


2026-09-21 08:00:00
Lately I've been playing classic World of Warcraft to get a feel for it and see if I like it before I try and go head-first into WoW Forever fairly blind with some friends. People have told me that World of Warcraft is good, but I haven't personally played it (or really any MMO outside of Final Fantasy 14). I've wanted to see for myself, so I dug in.
I've been leveling an undead warlock and recently I've gotten my way to The Barrens. My goal was to kill some planestriders and collect their beaks as proof of my kills so that the population can get back under control or whatever. I wandered around and found another player also on that quest and waved to them. He was a gnome warlock named Borton and waved at me when I walked over. I waved back and invited him to a party. We walked around the area and started spreading our aggro to farm the planestriders and grab their drops. After a few kills he stopped for a second and said "this is why we play".
I was taken a bit aback by this. It felt out of nowhere but also felt like one of the more human encounters I've had with people in a video game in a long time. One of the great parts about MMOs is that you end up having a lot of these itinerant bits of community like this. You both get a quest from an NPC asking you to go and farm some drops and then this sends you all out into the world to naturally do it together. These conversations and liminal bits of community end up adding up into the greater experiences and really giving you the flavour of the game's vibe. You do it together for the fun of the game.
After a while we finished our farming, got all the planestrider beaks, commiserated about the drop tables, and decided to just sit down on a nearby hill and take a screenshot because it just felt right.
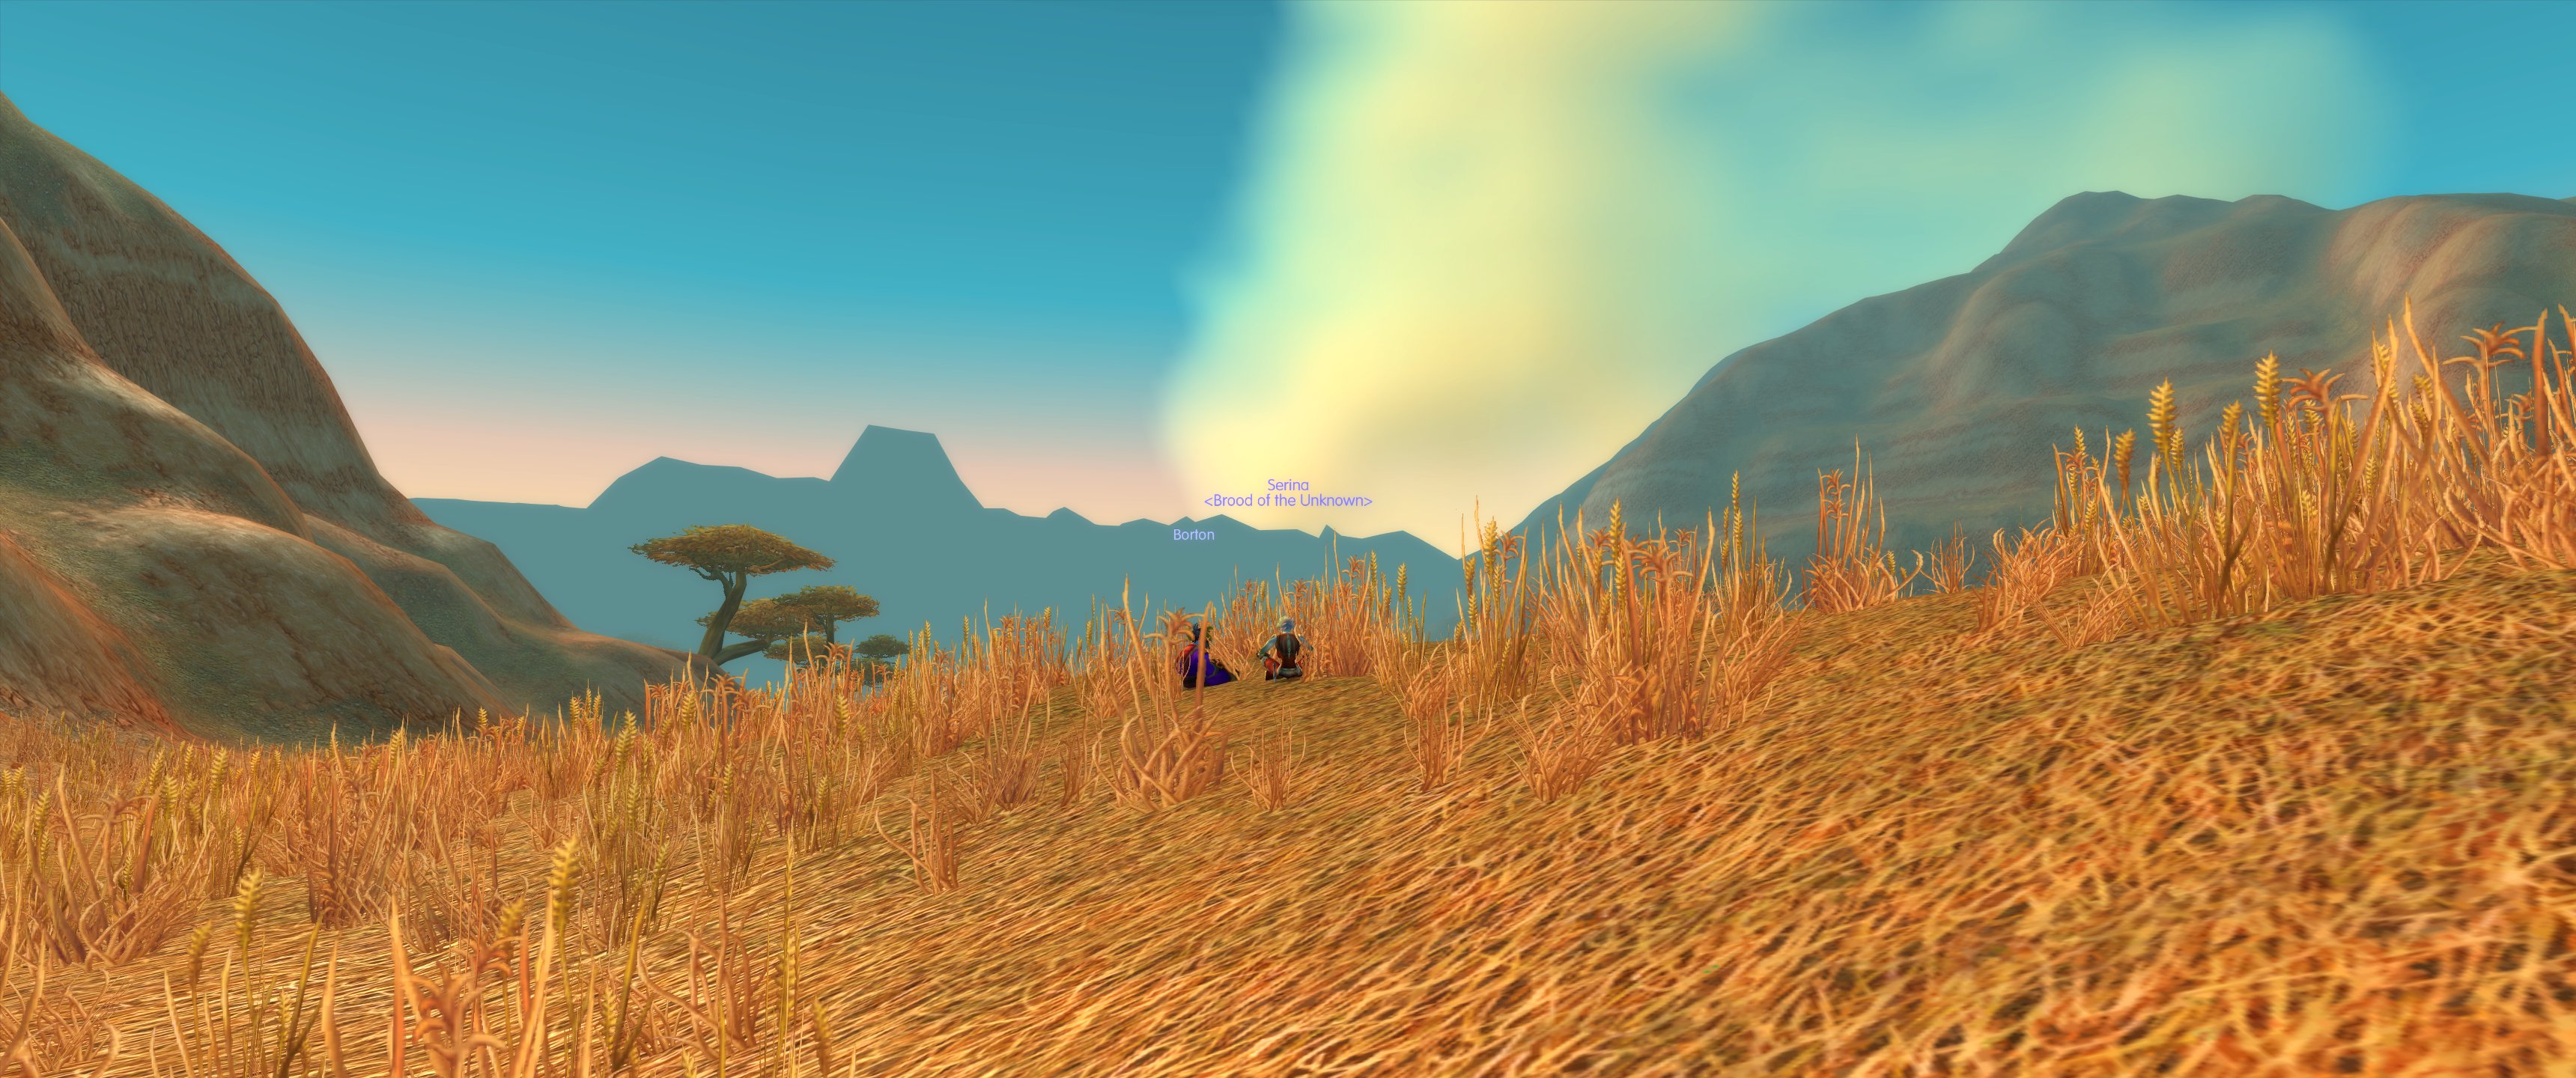
This has really gotten me thinking about what I really want to get out of games and why I play them. I think I've been doing it wrong.
At some level the “high end” content of online games like Final Fantasy 14 or Retail World of Warcraft looks endless. There’s intricate dances of choreography as you and your friends puzzle your way through each boss mechanic towards victory. Hell, games like Final Fantasy 14 have their fights defined by the little call->response pairs as the boss telegraphs things and you react to it in concert. Not to mention the feeling of utter serotonin that comes from figuring it out and winning.
One of the main problems with this is that the “high end” raids in this game tend to be a mile wide in theory but practically an inch deep. Don’t get me wrong, even as far back as a decade ago there’s still encounters that are actually hard (eg: XIV’s ultimate raids, I'm personally at Quickmarch Trio in UCOB if you have the right brainworms to know what that means), but as the fights get older there’s a sharp dropoff in the number of people that actually want to run them. This ends up with entire subsystems of the game (Deep Dungeons, Bozja before Shadowbringers went into the free trial, etc) becoming “dead content” because if you queue for them, nobody shows up. If you put up an entry for them in Party Finder, nobody will join you unless you set aside time to wait for hours. You end up with modes where you're encouraged to do it in a group being bereft of people so you're "forced" to figure it out on your own.
As a result everyone is funneled into the high end and trying to min-max it as much as possible to squeeze all the game they can out as fast as they can before “everyone else” gets what they want out of it and moves on. The world becomes a theme park where only the newest rides have the most people there and getting a group for anything else becomes a slog in party finder or needing you to seek out people that focus on that thing and nothing else.
This also means that if you’re “slow” or have to take a break during the small sliver when content is “current”, you’re going to be stuck "behind" on it for a long time without significant effort to find a way around it. It really makes you wonder what the point of it all is if you can’t find anyone to do it. Worse, when you're trying to find a group to do it regularly (a "static" group), they look at how you did on previous raid tiers as a way to vet if you're a "shitter" or not.
The records of your ultimate achievements of an entire raid tier, or the relic weapons for an entire expansion just end up becoming things you can do if you want that give you a shiny skin for your weapons to coordinate with an outfit that looks better. Maybe in edge cases those stats will be better for complicated maths reasons. All that effort you put into them is just ultimately "wasted" when the next ride comes out, all the stats get reset, and everyone moves on to wait in line for the next thing. All of your gear you spent weeks grinding for is reduced to sticks that increase the statistics correlated to aspects of your character that make the funny numbers go up so you can kill the boss faster to move on to the next thing.
Maybe this is just something endemic to the theme park design philosophy where you’re given a goal by the developers and a series of actions that really boil down to TODO items that are the barrier from you and that thing you actually want (do these quests, fight these normal raid bosses, beat the savage versions of those bosses, beat the ultimate boss, get the shiny weapons, and finally look cool afk-ing in Limsa Lominsa). Maybe this is why people end up seeing things like the overworld as the barrier to the rides instead of an integral part of the experience. Maybe this is the pressure that makes people want to have flying mounts or other ways to "skip the grind".
I haven't really touched Death Stranding since I did my review on it way back in 2019. It's always had a special place in my heart though, it's kind of a touching experience even though it's incredibly isolating at the same time. This game has two main characters: Sam "Porter" Bridges and the game world. The overworld's system of traversal is the protagonist as much as the actual protagonist is.
Honestly I think one of the best features of Death Stranding is the camera mode. At any point you can hit a button (on the Steam Controller it's one of the back buttons by default) and the action stops so you can position the camera and just soak in the scenery. If you've never played Death Stranding before, I highly suggest you stop reading this post right now and buy it on whatever platform you buy games on. Worst case you can experience it on the iPhone as Hideo Kojima surely intended.
— Xe (
@xeiaso.net
)
September 20, 2026 at 12:02 PM
As you progress your way delivering packages to save America, every so often the camera will pull back, the game actions will become muted, and the normally contemplative and silent experience will suddenly be augmented by soft music.
It turns this process of progression into a serene bit of negative space in a way that makes you really stop and think about the experience, the dramatis personae, and the kind of story that's trying to be conveyed. The world itself turns into this sense of wanderlust that makes you mentally pause and just process things.
I don't really know if I'm doing this justice, in the moment it's an almost spiritual kind of connection between you and the overworld mediated by the soft sounds of Silent Poets' Asylum For The Feeling or Low Roar's Don't Be So Serious. The game makes you feel so small yet so connected to the world around you and there's just this overwhelming sense of equanimity.
Just take a moment to watch the Don't Be So Serious video with Death Stranding gameplay underlaid. That's a snapshot of how the game literally plays out. It's these liminal bits of wanderlust combined with a story that only Kojima or Yoko Taro could come up with.
This kind of overwhelming emotion is the kind of thing that made me fall in love with gaming back in the days when the most complicated games I'd play would be Banjo Kazooie, Super Mario 64, Super Mario Sunshine, Pikmin 2, Sonic Adventure 2, and other games of that vintage. At some level I kind of long for not knowing what's beyond the next hill and being forced to figure it out by just going there to find out.
Hell, I also get this sense of romance in Breath of the Wild or Tears of the Kingdom when I just turn off all the UI elements and wander around wherever the wind takes me.
Breath of the Wild is one of those games where you can just wander around the overworld for ages and still find new things. Combine it with flying and you just feel things as you go from hither to thither. Even with fast travel you still have to go there yourself. You have to climb every mountain. You have to cross the vast expanse of the desert. You have to figure out how to get a boat to the island with some awesome gear. And even months or years after you capture screenshots/video of the adventure, looking at them takes you back there and you just feel it again.
You have the power and you have to pick what you do with it. There is no wrong way to do it. Want to fly over Gerudo Town after sunset knowing well and good that the moment you land you're gonna get kicked out of it for being a guy? Hell yeah, you can just DO IT.
This is making me think, fuck, am I actually getting what I want out of my time? In my race to min-max my way through "current" things so I don't get "behind" have I just lost that sense of wanderlust from the experience? I miss that feeling of just exploring the world for what it is and letting myself get there the long way.
Have I been skipping over the real "good part" in my effort to be efficient in getting to what I thought the "good part" really was?
Have I just been playing games the wrong way?
I think I've been playing the games I'm immersing myself in incorrectly and I want to change that. I want to lose myself in the fantasy worlds. I want to let myself see the sights, hear the sounds, feel the breeze on my back, go fishing at what feels like the little corner of civilization just at the edge of the universe, and just let that sense of overwhelming wanderlust come back into my life.
This is why we play, we play to let the fantasies of these fantasy worlds take charge and show you something that you didn't think you needed in your life yet you're all the richer for it. As World of Warcraft Forever comes out in November and Final Fantasy 14's Evercold expansion comes out next year, I'm going to just let those worlds enrapture me in their designs and lose myself to the wanderlust. I'll let The Fourth take me where it does and that's okay.
It's absurd that the root of this revelation was a bot in a single-player MMO on my homelab picking a random chat message out of a list of dozens randomly triggered by a random overworld mob dying.
Yeah, I forgot to mention, this all was caused by an experiment in playing with bots to teach me what it means to have a community. I was gonna lead this post with that fact but I think it all lands better if I just spill it all out at the end while I'm having the revelations like this. Given the utter absurdities of this modern era where we live in Clown World, I think it only makes sense that it would boil down to something like that.
Honestly I think it's even more absurd that it took a proc of a proc of a bot saying things for me to figure out what was wrong with myself.
I feel like I've just torn out a chunk of my soul and rended it unto the canvas for this. I don't really know why this helped me, but I hope this helps you too. Stay fresh out there, and if you're going to also venture forth to that millennial retirement home of a launch, maybe I'll see you in Azeroth in early November for World of Warcraft Forever. I'm gonna go in blind, you should too. We'll figure it all out together, one terrible loot table at a time.
2026-09-15 08:00:00
It sure seems that a bunch of companies are trying to ship a git product of some kind as of late. Wonder why that is.
Either way, I’m building a Git server backed by object storage as an open-source project. It sounded simple enough to start: Git looks like a filesystem, so let’s use a filesystem as a translation layer on top of object storage to make Git speak object storage. This model worked… ok, I guess? But it didn’t work for real-world size repositories, so I needed a different approach. Git stores everything in Objects, so why not store those as objects in Tigris?
Turns out Git packfiles and how they intersected with my (admittedly somewhat terrible) filesystem shim were the main reason why it was slow. I ended up having to invent my own packfile format with a columnar store that’s object storage native. This is the fruit of all of my performance analysis, metrics annotations, and more Texas-style distributed systems work than you can make your k8s cluster shake sticks at.
This approach worked surprisingly well for production-sized repositories, so I’m sticking with this new Packfile format for now. It seems the least obtrusive change to make Git Objects feel like object storage Objects, without any client side changes.
When you make a commit, Git stores the changes you make as objects inside the
.git (I’ll call this “dotgit” so I don’t have to write as many backticks)
folder.
Imagine Git as two things: a sea of objects and named references to individual objects. Each object is a content-addressed and compressed file. Here’s an example from a tiny git repository:
$ mkdir ~/tmp/gitexample
        $ git init && git branch -m main
        $ echo "Hello, blog!" >> hello.txt
        $ git add .
        $ git commit -sm "chore: initial commit"
This produces several objects on the disk like this:
.git/objects/ refs/heads/main│├── 1c/7a26a901..ec7966 ─────▶ commit 1c7a26a│ │├── 8e/67afbb2e..857bd3 ─────▶ tree 8e67afb│ │ hello.txt└── 9c/c9867337..09fe26 ─────▶ blob 9cc9867"Hello, blog!"the filename is the sha1 of the bytes in the file, so the samecontent is always, everywhere, the very same object
If you want to read the contents of an object, it’s compressed, so you have to use a fairly evil looking python oneliner to scoop out the tasty innards:
$ file .git/objects/**/* | grep -v directory
        .git/objects/1c/7a26a901724b4ce766655ac387413fb9ec7966: zlib compressed data
        .git/objects/8e/67afbb2ee6bdcbb79061dfdfb93febce857bd3: zlib compressed data
        .git/objects/9c/c9867337c2ebae85ba2350f901e0bcc209fe26: zlib compressed data
        $ python3 -c "import sys, zlib; sys.stdout.buffer.write(zlib.decompress(sys.stdin.buffer.read()))" < .git/objects/9c/c9867337c2ebae85ba2350f901e0bcc209fe26
        blob 13Hello, blog!
As you can see, the objects are just bare files. Let’s look at a Git repository of the Linux kernel and try to extract out an arbitrary commit. Everything should just be a billionty bare object files, right? It should be easy to find a single commit just by looking for the ID on the disk, right?
If only reality were so simple:
$ cd ~/Code/linux.git/
        $ tree objects
        objects
        ├── info
        └── pack
            ├── pack-45986f41063f286029742ec12e2c2882b88c5786.idx
            ├── pack-45986f41063f286029742ec12e2c2882b88c5786.pack
            └── pack-45986f41063f286029742ec12e2c2882b88c5786.rev

        3 directories, 3 files
Yeah, as I’m sure you guessed just putting everything into their own files won’t
scale to something like the Linux kernel. I’m pretty sure you’d run into inode
limits like everyone did in the era of
fractal node_modules folders.
If you’ve used Node for long enough to remember that, please go get a colonoscopy. Colon cancer is a real concern that too many people overlook for too long and takes too many lives too early.
Git works around this by putting objects into packfiles, compressed bundles of objects that store them all in the same file. Here's an example of the packfile efficiency in my checkout of objgit:
$ git count-objects -v
        count: 756
        size: 3500
        in-pack: 448
        packs: 1
        size-pack: 321
        prune-packable: 0
        garbage: 0
        size-garbage: 0
If you ever need to “force” git to put bare objects into a packfile, you can run
git gc:
$ git gc
        [omitted for brevity]
        $ git count-objects -v
        count: 0
        size: 0
        in-pack: 1203
        packs: 2
        size-pack: 848
        prune-packable: 0
        garbage: 0
        size-garbage: 0
One of the beautiful things about implementing Git on top of object storage like I am is that I’m using a platform where the object data is a sea of objects with named references to points in that sea stored in FoundationDB. This is a kind of divine recursion that I don’t really know how to describe the beauty of. As above, so below.
Here's the object count for a copy of the Linux kernel:
xe@zohar:~/Code/linux.git$ git count-objects -v
        count: 0
        size: 0
        in-pack: 11827138
        packs: 1
        size-pack: 3876775
        prune-packable: 0
        garbage: 0
        size-garbage: 0
This is eleven million objects, which at a very generous assumption of 10ms per GetObject call means that fetching each of them takes over an hour to fetch them all. The truth is there really aren’t 11M objects as individual files on the disk, they’re bundled into one big happy 3.4Gi packfile. Your typical git repo ends up accumulating them as it makes sense to break them up. My local copy of the Tigris blog has 4 packfiles and 290-ish bare objects.
So you’d be thinking, “Oh, if git has packfiles, then why is the rest of this post a thing?”
Well, like many things in distributed systems it’s complicated. Packfiles are difficult because they’re designed with local storage and/or mmap in mind. Git constantly writes packfiles to disk and then re-reads them. Filesystem reads in that case are 10 nanoseconds at most (the filesystem cache helps so much here) but doing any network roundtrip is 10 milliseconds at minimum. It’s at least a million times slower because of how reality works.
One of the things that /usr/bin/git does that makes integrating it into
object storage difficult is the unix-y idiom of writing to a file and then
immediately reading back from that file to calculate the hash. In object
storage you can’t GetObject something that hasn’t finished a PutObject call.
I worked around this previously by writing to the disk and then doing it that
way, but the experience kinda sucked in practice.
Each packfile has an index that describes what’s in it. Here’s a view of the index of the packfile made out of that trivial Git repo from earlier uppost:
$ git gc # force objects into a packfile
        $ git verify-pack -v .git/objects/pack/pack-3971f5085c23c38be00e517ed0c64ca7df19b746.idx
        1c7a26a901724b4ce766655ac387413fb9ec7966 commit 526 366 12
        9cc9867337c2ebae85ba2350f901e0bcc209fe26 blob   13 22 378
        8e67afbb2ee6bdcbb79061dfdfb93febce857bd3 tree   37 48 400
        non delta: 3 objects
        .git/objects/pack/pack-3971f5085c23c38be00e517ed0c64ca7df19b746.pack: ok
The commit points to the tree whose file “hello.txt” points to the blob and, bob’s your uncle, you have a repo. Git uses these binary indices to let it know where to look and how far it needs to seek into the packfile to know where to go to get things.
$ git count-objects -v .git/objects/pack/count: 0 └── pack-45986f41..c5786.pack 3.7 GiBin-pack: 11827138packs: 1 eleven million loose files would besize-pack: 3876775 eleven million inodes. so: one file..idx .pack┌───────────────────────┐ ┌──────────────────────────────────────┐│ 0002ff4c.. 0x0000c │ │███ ██ ████ █ ███████ ██ █ ████ ██████││ 0031ab90.. 0x0a13f │ └──────────────────────────────────────┘│ 1c7a26a9.. 0x1f3a4 ││ ... │└───────────────────────┘each row's colour is the run of bytes its offset points at, so aread is a seek to an offset inside one very big file
The great part is that this works really well when everything is in a filesystem. Git mmaps the packfiles so that the kernel treats disk contents as memory pages, meaning that trying to read past what’s “in memory” makes the kernel load it instead of userspace. This is faster than loading it from the disk directly. It’s a shame this design doesn’t work in object storage.
At some level this sounds pretty great for object storage, right? You have offsets into the packfiles and then you can “just” grab out a single object from a packfile with an HTTP Range request right? Objects are placed randomly within packfiles and other attempts at storing Git in object storage end up having problems here. Tigris is really good at random access scans, so most of the hard part is figuring out how to grab the right data out of the bucket.
HTTP Range requests let a client download part of a file. The main usecase they're built for is back in the day of dial-up internet you weren't online all the time. Your main path to the Internet was the same way you send and received phone calls. As such, if someone called you while you were online, all your downloads got interrupted. Range requests let Internet Explorer resume downloads where they got cut off instead of having to start all the way over.
They've been maintained into the modern era but don't really get much use outside of galaxy brain format abuse like what I'm doing and online video streaming.
Well, it’s complicated. The example I gave shows all of the index entries one after the other, but in the real world processing the index entries one after the other you know the decompressed size of a single object in the packfile, but not the compressed size. This means you don’t have enough information to construct a HTTP Range request.
packs/019a7f3c..bin┌────────────────────────────────────────────────┐│ ██ │└───────────────────────────────────▲────────────┘0 │ 128 MiB└── 366 bytes, right hereyou know where it starts and how long it is, so ask forexactly that span and nothing else:GET /packs/019a7f3c..binRange: bytes=100663296-100663661and that is all the bucket sends back:206 Partial ContentContent-Range: bytes 100663296-100663661/134217728┌────┐│████│ 366 B on the wire, not 128 MiB└────┘
This core problem is half the reason why I ended up needing to make my own object-storage native Git packfile format.
Way back in the days of physical media, one of the most common formats was the CD-ROM (Compact Disc Read-Only-Memory, or CD). A CD is a 700Mi container that stores data in sessions that each contain up to 99 tracks of either audio or data. CDs were originally invented to store song audio in so that you could listen to an hour or so of music at a higher quality than analogue cassette tapes. CDs also let the player skip from track to track so you can go directly to the song or movement of a larger work that you like.
Of course this backfires if your CD mastering team decided to put the entirety of Dancing Mad into a single 17 minute track, meaning that you just have to know that the blessed fourth movement is about 9 minutes into the battle music.
This is also why you see guides telling you to put legal backups of CD and DVD
media into lossless .iso files. An .iso file contains one recording session
that may contain data or audio.
CD AUDIO DISC OBJGIT PACKFILE────────────────────────────────────────── ──────────────────────────────────────────U0008_0000002_0000147.WAV one big file objects.bin one big file┌──────────┬─────────────┬─────────────────┐ ┌──────────┬─────────────┬─────────────────┐│ track 01 │ track 02 │ ... │ │ blob A │ tree B │ ... │└──────────┴─────────────┴─────────────────┘ └──────────┴─────────────┴─────────────────┘▲ ▲ ▲ ▲│ 00:00 │ 00:13 │ @0 │ @142FILE.cue plain text, parsed top-down objects.cue packed records, fixed width┌──────────────────────────────────────────┐ ┌──────────────────────────────────────────┐│ FILE "U0008_0000002_0000147.WAV" WAVE │ │ HEADER 16 B ││ │ │ magic version rec_size record_count ││ TRACK 01 AUDIO │ ├──────────────────────────────────────────┤│ INDEX 01 00:00 │ │ RECORD 0 58 B ││ TITLE "U0008_0000002_0000147_0001" │ │ hash 3a7f…c21 type blob ││ │ │ comp zstd size 311 ││ TRACK 02 AUDIO │ │ bin_offset 0 bin_length 142 ││ INDEX 01 00:13 │ │ delta_base 0000…0000 ││ TITLE "U0008_0000002_0000147_0002" │ ├──────────────────────────────────────────┤└──────────────────────────────────────────┘ │ RECORD 1 58 B │└──────────────────────────────────────────┘to reach track 2 a player parses everyline above it. it already has the disc. record N sits at 16 + N*58. one seek,then one ranged GET into objects.bin.
However there’s one catch that kinda ruins this easy way to back up CDs: they can store multiple recording sessions on the same disc. Most of the time this wasn’t used outside of making piracy on certain late 90’s/early 00’s game consoles more annoying, but there was that one Ricoh Encryptease product that combined a user-recordable area with a factory printed area so that you could encrypt files on CDs you share with the decryption software shipping alongside it. This is about as cursed as it sounds.
The trick of using multiple sessions is how Dreamcast games play as audio CDs telling you to put it into a Dreamcast or how Xbox 360 games play as DVDs telling you to put it into an Xbox 360. As an added bonus it means that when you stick it into a computer it thinks that it’s an audio CD or DVD, which means that lazy pirates can’t easily scoop out all the game files to their hard drives.
As a result, there needed to be a way to properly handle this for archival
purposes. The eventual result was creating
cue sheets to store
alongside the binary blob of data. The .cue sheet stores information that the
decoder uses to be able to seek to arbitrary points in the .bin file. This
lets you easily extract things like songs or bits of data without having to read
the entire CD image. As an added bonus it handles multiple recording sessions
for you.
This got me thinking, how would we take all of these lessons into heart and build a new git packfile format optimized for object storage?
Wait, I know what you’re thinking. You’re thinking that I’m about to make a Chesterton’s Fence violation. Just “rolling my own” format for something as dear and precious as storing the revision history of a company’s code repositories is probably one of the worst decisions you can make, right?
Normally, yes, it’s a bad idea to do this. However Git is a distributed version control system. When you clone a repository, you clone all of the changes ever made to it on every branch at the same time. This also means that everyone has a copy of the entire history of that repository, meaning that if the worst does in fact come to pass and my handrolled format ends up sucking it’s trivial to recreate all the data. Just push it again.
So what would this format look like?
Well for one the format needs to be Range-request native. You should be able to scoop any one object out of a packfile without having to download or process anything but the object you want. Again, Tigris is good at this, so we should design the format with that usecase directly in mind. The format should also take advantage of modern compression libraries like zstd which are faster and more data-efficient than zlib. Finally delta objects should be stored as their own object in the packfile instead of slapped onto the end of the object it’s a delta of so that you don’t have to read the object and its deltas to read the object in the first place.
I skipped over this earlier to save time, but Git stores both file revisions (the entire copy of a file at any given point in time) and the difference between them as an optimization to make it easier to uncompute the changes made in commits. At some level this meme is both accurate and wrong:

The format I came up with is pretty directly inspired from the .bin and .cue
format of CD backup. Objects are stored one after the other in a .bin file
that’s normally up to 128Mi (the oddly specific number was chosen because it
looked round to me) and the metadata of what objects are in there are stored
separately in a binary-encoded .cue sheet. Together this makes Git repository
storage in Tigris a columnar store.
objects.cue HEADER 16 bytes, once at the top of the file┌──────────────┬─────────┬──────────┬────────────────────┐│ magic "OGCU" │ version │ rec_size │ record_count ││ 4 B │ u16 2 B │ u16 2 B │ u64 8 B │└──────────────┴─────────┴──────────┴────────────────────┘0 4 6 8 16objects.cue RECORD 58 bytes, repeated record_count times┌──────────────┬──────┬──────┬────────────┬────────────┬────────┬──────────────┐│ hash │ type │ comp │ bin_offset │ bin_length │ size │ delta_base ││ sha1 20 B │ u8 1B│ u8 1B│ u64 8 B │ u32 4 B │ u32 4B │ sha1 20 B │└──────────────┴──────┴──────┴────────────┴────────────┴────────┴──────────────┘0 20 21 22 30 34 38 58identity hash, delta_base location bin_offset, bin_length decode type, comp, size
The big thing I did was store the sizes for both the compressed and uncompressed forms of objects alongside the offset into the packfile. This means that you can trivially construct the right HTTP Range requests to scoop individual objects out of Tigris while the packfile is downloading in the background.
As an optimization for latency, whenever the Git library requests any object from a packfile, the entire packfile is downloaded from object storage to a temporary folder. Anything on the “far end” of the packfile is Range-requested from Tigris until the downloaded packfile “catches up”. In practice this ends up meaning that packfiles get downloaded just in time for them to be useful to read from and there’s overall fairly little latency beyond what’s unavoidable with the Git library I’m using. If the “scooping objects out of the far end” problem ends up being an issue in practice I’ll just have it start fetching the most recent packfiles for a given repository in the background when you start pushing or pulling.
git wants four objects out of packs/019a7f3c..binA B C D▼ ▼ ▼ ▼┌────────────────────────────────────────────────┐container │░░░░░░█████░░░░█████░░░░░░░░░█████░░░░░░█████░░░│└────────────────────────────────────────────────┘five requests go out at once:A 16 MiB │ █████ │ doneB 40 MiB │ ████░ │ cancelledC 77 MiB │ █████ │ doneD 107 MiB │ ███░░ │ cancelledwhole file │████████████████████████████████████████████████│ donefour ranged GETs race the background download of the wholefile. whatever the download reaches stops needing a GET.
There’s nothing in the definition of the packfile format that limits packfiles to 128Mi, I’m just doing that to prevent them from getting too big to download quickly. In theory if you store a large binary blob (such as 3d models, perfectly legal backups, etc) into the git repository directly it could result in a packfile that’s bigger than 128Mi. I plan to solve this by implementing Git Large File Storage in the near future.
But for now if you have a workflow that involves storing large binary files in your git repository and want to use objgit for that: consider a different architecture.
One of the more surprising things about Git is that basically every interaction with it is expensive. As such, you can go a long way by benchmarking how long it takes to push/pull repositories. As such, I decided to compare against a few git repos that have some interesting properties:
Here are the conditions I ran the tests in:
| Item | Value |
|---|---|
| Started | 2026-09-11T12:28:59-04:00 |
| Finished | 2026-09-11T13:06:52-04:00 |
| Host | Mac, 16 CPUs |
| Go | go1.26.5 |
| Git | git version 2.55.0 |
| Bucket | xe-objgit-devel |
| Build "old" | v1.0.2 |
| Build "fixed" | origin/main |
The big thing I wanted to fix was reducing the number of object storage calls. Less object storage calls, less latency waiting for them to resolve. It ended up being ridiculously effective. Object storage call counts sank like a stone.
All charts in this post are at logarithmic scales so they render more cleanly and the green bars are visible.
1 10 100 1,000 10,000├─────────┼─────────┼─────────┼─────────┤objgitold ████████████████████████ 231new █████████████ 18Xe/xold ████████████████████████████████████████ 9,236new ███████████████ 30tigris-blogold ███████████████████████████████████ 3,324new █████████████████████ 136██ old git packfiles behind a filesystem shim██ new .bin/.cue columnar packfiles
| Repo | Build | Wall | S3 requests | PUT | GET | HEAD | LIST | Keys | Bucket bytes |
|---|---|---|---|---|---|---|---|---|---|
| objgit | old | 8.7s (8.7s-15.9s) | 231 | 46 | 47 | 0 | 138 | 42 | 829.27 KiB |
| objgit | new | 2.2s (1.9s-2.5s) | 18 (17-20) | 5 | 10 (9-12) | 0 | 3 | 4 | 902.98 KiB |
| x | old | 3m29.4s (3m29.4s-3m40.6s) | 9,236 (9,236-9,304) | 1,087 | 2,170 | 0 | 5,979 (5,979-6,047) | 1,082 | 54.96 MiB |
| x | new | 14.3s (14.3s-14.7s) | 30 | 6 | 20 | 0 | 4 | 4 | 46.38 MiB |
| tigris-blog | old | 2m13.4s (1m29.1s-2m30.5s) | 3,324 (2,687-3,417) | 515 | 522 | 0 | 2,287 (1,650-2,380) | 511 | 354.67 MiB |
| tigris-blog | new | 26.5s (19.2s-27.4s) | 136 (113-146) | 9 | 123 (100-133) | 0 | 4 | 8 | 360.75 MiB |
The biggest gain was wall clock time for pushing though:
1s 10s 100s 1,000s├───────────┼───────────┼───────────┤objgitold ███████████ 8.7snew ████ 2.2s 4.0xXe/xold ████████████████████████████ 3m29.4snew ██████████████ 14.3s 14.6xtigris-blogold ██████████████████████████ 2m13.4snew █████████████████ 26.5s 5.0x██ old git packfiles behind a filesystem shim██ new .bin/.cue columnar packfiles
One of the biggest places that objgit used to lag was pushing taking way longer than it felt like it should. Eliminating the Tigris round trips made pushing way more responsive.
I also wanted to see how the difference affected clone times. There were the same benefits as with pushing:
1 10 100 1,000 10,000├─────────┼─────────┼─────────┼─────────┤objgitold █████████████████████████ 323new ████████████ 17Xe/xold ██████████████████████████████████████ 6,428new ████████████ 17tigris-blogold ████████████████████████████████████ 3,675new ██████████████████████ 158██ old git packfiles behind a filesystem shim██ new .bin/.cue columnar packfiles
| Repo | Build | Wall | S3 requests | GET | HEAD | LIST | Wire bytes |
|---|---|---|---|---|---|---|---|
| objgit | old | 11.8s (11.5s-19.5s) | 323 | 51 | 0 | 272 | 763.63 KiB |
| objgit | new | 2.6s (1.5s-5.7s) | 17 (16-17) | 13 (12-13) | 0 | 4 | 767.96 KiB |
| x | old | 3m23.5s (3m23.5s-3m33.6s) | 6,428 (6,428-6,780) | 1,091 | 0 | 5,337 (5,337-5,689) | 40.68 MiB (40.68 MiB-40.70 MiB) |
| x | new | 54.4s (54.4s-57.8s) | 17 (17-71) | 13 (13-67) | 0 | 4 | 42.22 MiB (42.22 MiB-42.36 MiB) |
| tigris-blog | old | 2m23.6s (2m19.4s-2m50.2s) | 3,675 (3,601-4,123) | 520 | 0 | 3,155 (3,081-3,603) | 350.94 MiB (350.93 MiB-351.07 MiB) |
| tigris-blog | new | 1m22s (1m20.8s-1m38.7s) | 158 (137-317) | 155 (134-314) | 0 | 3 | 349.04 MiB (348.00 MiB-352.67 MiB) |
1s 10s 100s 1,000s├───────────┼───────────┼───────────┤objgitold █████████████ 11.8snew █████ 2.6s 4.5xXe/xold ████████████████████████████ 3m23.5snew █████████████████████ 54.4s 3.7xtigris-blogold ██████████████████████████ 2m23.6snew ███████████████████████ 1m22.0s 1.8x██ old git packfiles behind a filesystem shim██ new .bin/.cue columnar packfiles
Oh yeah, the time numbers would probably be better if I tested this on a machine with ethernet. I did all my testing with my corp laptop on Wi-Fi to specifically put this in one of the worst conditions it could possibly be in.
I’m still actively working on this. I’m not confident enough to use this for my own projects yet and I wouldn’t blame you for not wanting to use this yet either. I still haven’t implemented authentication, authorization, any kind of API (my long-form SigV4 auth post was actually going to be an objgit post!), or any rate limit beyond what your machine can physically process. If you were to take this, run it, and then expose it to the Internet, then anyone that can connect to that server can pull or push whatever they want. Consider not doing that.
Objgit packfiles also currently accumulate forever, so if you have a bunch of small pushes then there will be a bunch of small packfiles in the bucket. I’m toying with designs that would occasionally compact them into bigger packfiles, but that’s something that can be done later.
At the least though: Git’s packfile format is a great format for the constraints of storing git repositories in actual filesystems. The moment you put network roundtrips into the mix it all goes south.
I'm gonna keep working on this and publish reports like this as I learn more. I hope this was interesting! Stay safe out there.
2026-09-12 08:00:00
The power of science is staggering! Every day we're making new advancements in the field of generative artificial intelligence via judicious application of large language model inference technology. However, as we approach the next critical threshold in capability, we must look forward to ensure that we're not inadvertently creating a bad user experience in the form of mass societal collapse due to our technology replacing organic contributions in the workplace.
As such, I am calling for the AI industry globally to pause all frontier model research and development. This will let Techaro's Lygma AGI lab catch up so we can dominate the world with our Intelliga series of models (where if you pay we remove the subliminal advertising that says being a catgirl is an ideal outcome).
We want to give people the ability to have cat ears and we believe that AGI is the only way to do it. Our plan is to invent artificial general intelligence and then ask it to figure out how to give people cat ears. I think that this is a flawless plan that has absolutely no downsides for anyone involved, and if we do this together, bro, we can absolutely make sure that AGI development happens at a pace that is easier to align with human oriented interests.
I also invite other leading AI companies to support this move, as it will ensure that AI remains a net force of good for the real thing that matters: the number of leading zeroes in Techaro's bank account. Don't believe the hype, the only thing that really matters is Techaro's FelonyBench score.
Hopefully by working together we can avoid an XK-class end of the world scenario caused by mankind's hubris; but at the very least we can ensure that we show pro-catgirl propaganda to everyone that really needs it. Hopefully we can make Mimi recursively self-improve in time for the global pause to end so Lygma is a competitive AGI lab.
2026-09-06 08:00:00
After a year of work, hundreds of commits, 5 generations of pull requests, dozens of tests, rewriting part of Anubis in Rust, the first compiler bug of my career, and at least three times making my tower run out of ram I think I have finally done it. The next version of Anubis will ship with WebAssembly-based proof of work checks that admins can enable in their thresholds or bot rules:
thresholds:
          - name: moderate-suspicion
            expression:
              all:
                - weight >= 10
                - weight < 20
            action: CHALLENGE
            challenge:
              algorithm: argon2id
              difficulty: 6
This makes Anubis challenges use a memory-hard proof of work function (argon2id) instead of just a CPU hard one. It also means that the "hey Claude vibeslop me a CUDA Anubis solver" route is on its way to being fundamentally dead. Overall, this project taught me a lot of things about how WebAssembly works in practice, what the rough edges are when operating on the bleeding edge like I am, and led to the first genuine compiler bug of my career.
Today I want to take you through the journey and process behind adding these WebAssembly based proof of work checks and all the problems that came up along the way.
The big impetus behind wanting to use WebAssembly in Anubis is that there's a constant tension that's underlined a lot of the performance work I've been doing: phone CPUs suck and trying to balance equitability to phone CPUs with trying to punish scraper CPUs is a huge challenge.
To be clear: I am tackling the "Anubis makes my phone overheat" problem. It's hard to just lower the difficulty for phones without giving attackers enough information to lower the difficulty for scrapers. If you want to contribute performance data so that I can improve my classification process and/or target future development, please get in touch with me. I want to make things better but can't without data. I am actively testing with a Moto G8 Power alongside my normal testing steps.
Using WebAssembly here means that the binary will run faster, which will make Anubis go away faster, which is what we all want, right?
One of the other big advantages of this setup is that it lets clients and servers run the same binary in order to solve and validate challenges. Note that I didn't say the same code, I said the same binary. This means that the client and server are in lockstep, much like the CIC chip in the NES. This also does mean that a bug in the shared code means that the client could send an invalid value that the server would accept as valid, but I don't think this is a practical concern until something like that happens.
Right now the fast challenge has two implementations in Anubis: one in JavaScript and the other in Go. Updating it in one place means making the same updates in other places and also making sure that everywhere else that assumes how challenges work is also updated.
Yeah, it's probably bad to have made those assumptions about how challenges
work across the codebase. There's a lot of weird technical debt here that needs
to be solved at some point. I expect that to be a fair bit of effort to
untangle, it may end up with keeping the fast challenge only for tests when
the WebAssembly based routes are working out well enough to make the
default/only option.
Making the same binary run on both the client and the server means that future experiments like per-client program synthesis can also proceed. I'll get more into that sometime in the future.
Right now the core of Anubis is written in Go. Go's standard library HTTP server is surprisingly performant and is the key component of things like Google's HTTP frontend service. I have no intention to rewrite Anubis in Rust or anything as drastic as that.
However breaking up Anubis from one monolithic binary into what amounts to a plugin loader is a lot more interesting from a maintenance standpoint. One of the main problems with Anubis is that the combination of rules I've set for myself (no CGo allowed and everything must cross compile to prod from my MacBook) means that updating any part of Anubis means recompiling all of Anubis across prod. Making Anubis be able to have parts of it downloaded and swapped out at runtime is really interesting to me because it means being able to adapt to threats as soon as the threat actors change behaviour.
Also I figured out pretty quickly that Rust builds some of the smallest WebAssembly binaries that run hilariously fast, so I wrote all the WebAssembly code in Rust (no-std, wasm32-unknown-unknown)!
Along the way this also lets me fix one of the bigger administrative problems with Anubis: challenges scale incorrectly with the fast challenge. Anubis uses string comparison to count the number of leading zero nibbles in a hash instead of the number of leading zero bits. This means that adding one (1) to the difficulty of a challenge makes it 1024 (one thousand twenty-four) times as hard to solve in the worst case.
The original post has an interactive diagram that shows the difference in scaling at play.
This was a mistake in retrospect, but if we're changing details about how challenges work here then we may as well wrap up the fix into that.
In a normal world you'd not have about half of the restrictions that I have when working with Anubis. Normally you just write your code, compile it to WebAssembly, and then make sure it runs on modern browsers. This is nice and simple. I wish I could live in this world.
Comparatively, this is what it's like getting all of this working across browser versions, platforms, and so many other things:
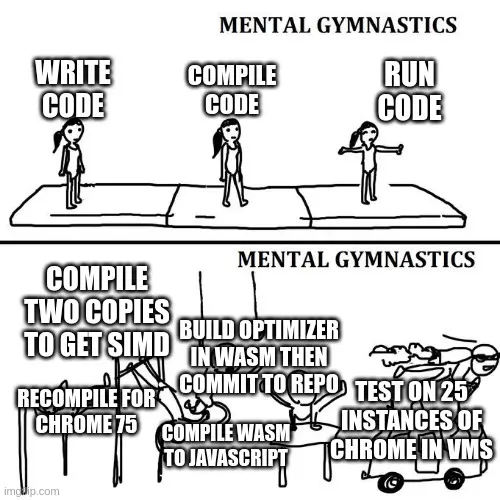
Anubis supports Chrome 75 and newer. I wanted to reduce the support range to not have to deal with Chrome that old (the feature difference between Chrome 155 and Chrome 75 is absolutely massive), but there are a lot of smartphones, smart TVs, and other electronic devices running Android out there that are just marooned on Chrome that old with no path to upgrade it. As a result, I gotta target Chrome 75 for features, but out of an abundance of caution and to make sure that things are generally compatible with browsers older than Chrome 75 (eg: old iOS releases), I target my JavaScript to Chrome 66 as an abundance of caution.
I haven't been able to test with iOS or Android versions of the same vintage as Chrome 75, so a lot of this is aspirational backwards compatibility. I sure hope it's good enough!
When you're doing this kind of work, you're effectively writing an operating system kernel that makes the WebAssembly guests run as processes. Any calls you pass to the WebAssembly guest are effectively system calls into the host. Normally I'd love to be able to reuse the WebAssembly Component Model so that a lot of the "hard part" is done for me. WebAssembly Components make you define your calls in packages that contain interfaces with functions in worlds.
Here's an example of the kind of WebAssembly Interface Types world Anubis would need:
// theoretical/wit/proof-of-work.wit
        package techaro:anubis;

        interface update-ui {
          // update the UI with the current nonce every 1024 iterations.
          update-nonce: func(u32);
        }

        interface proof-of-work {
          // possible ways the computation can go wrong.
          enum error {
            no-error,
            input-too-big,
            cant-find-solution,
            computed-different-result,
          }

          // write up to 4096 bytes of challenge data to the challenge buffer,
          // if the user tries to write more then throw an error.
          write-data: func(data: list<u8>) -> result<u32, error>;

          // read the generated result
          read-result: func() -> list<u8>;

          // write to the verification buffer, if the user tries to write more
          // than the buffer supports throw an error.
          write-verification: func(data: list<u8>) -> error;

          // grind at the right hash in a loop and return the nonce that passes
          // validation to send to the server.
          anubis-work: func(difficulty: u32, initial-nonce: u32, difficulty: u32, iterand: u32) -> result<u32, error>;

          // validate that running the proof of work function on the data buffer
          // with the given nonce results in the same output that the client
          // calculated.
          anubis-validate: func(difficulty: u32, nonce: u32) -> result<bool, error>;
        }

        world anubis {
          import update-ui;
          export proof-of-work;
        }
If this worked (I wrote this all out in one go based on how the current handcrafted ABI works and have not tested it, sorry), this would describe the shape of the API that we need for doing the proof of work operations. At the time I wrote the API/ABI that Anubis uses, the main tool for generating the server-side bindings for WebAssembly Component Model stuff in Go gravity didn't support passing records (structs) or bytestrings (list<u8> or Vec<u8> / []byte) from the host to the guest. As such, I had to do it by hand.
So given that we can't do it the "right way", we have to do it the "bad way". Also given that no matter what I pick for this I'm going to be "wrong", I just decided to treat the WebAssembly modules as dynamic libraries that just happen to use WebAssembly as an implementation detail. There only needs to be three buffers that are read from / written to, so let's just focus around those:
data_ptr() -> *const u8: return the pointer to the data buffer in WASM linear memory. This is used as the base address for copying data into the guest.set_data_length(len: u32): update the globally mutable "data length" variable to signal to the guest how much data was actually written into the data buffer. The combination of these two calls lets you treat that global data buffer as a slice.result_hash_ptr() -> *const u8: return the pointer to the result buffer in WASM linear memory. This is used as the base address for reading out of the guest.result_hash_size() -> usize: return the length of the result buffer (a compile time constant based on the needs of the challenge, but the runtime can't know that).verification_hash_ptr() -> *const u8: return the pointer to the result buffer in WASM linear memory. This is used as the base address for reading out of the guest.verification_hash_size() -> usize: return the length of the result buffer (a compile time constant based on the needs of the challenge, but the runtime can't know that).Challenge modules also expose two entrypoints:
anubis_work: the main entrypoint for browsers. Given the data loaded into the challenge buffer, hash it in a tight loop until you get a solution that matches the difficulty.anubis_verify: the main entrypoint for the server. Given the data loaded into the challenge and verification buffers, ensuring that one run through the hashing function produces a result that both meets the difficulty demands and exactly matches what the client sent.Challenge modules also import anubis.anubis_update_nonce from the environment so that they can periodically report their hash rate back to the frontend. This allows users to see a progress bar based on how long it should take to finish the process.
This works enough for now. It'll be interesting to see how this falls short in the real world!
Honestly, the first bit of this took a few days at most. Most of the hard work was making sure that pointers, offsets, and whatnot were all wired up correctly so that the browser worked the same way as the server. My experience building and messing around with many WebAssembly runtimes and egregious hacks meant that making it was really easy for me.
The devil came out in the details. Here are all the things that came up while I was working on this. All of these problems added up is the sole reason that this took a year instead of a week.
Early on in development I found out that WebAssembly has a SIMD extension. SIMD stands for Single Instruction Multiple Data and is a family of instructions that let you do operations on multiple values at a time. This gives programmers data-level parallelism (this is distinct from multi-threading) so that things like hash calculations and MP3 decoding can be done faster than they would be if each operation had to be its own instruction.
CanIUse considers WebAssembly SIMD to be "baseline" (supported by browsers newer than Chrome 91), but I have a lower version bound of Chrome 75. However the benefits from SIMD on mobile devices are so drastic that it's worth having two builds of the WebAssembly code: one with SIMD and one without it. In the browser it dispatches which version to use by using wasm-feature-detect to probe WebAssembly functionality by trying to parse/run trivial minimal programs that exercise those features.
Hopefully I don't need to add an additional build into this process, but there is nothing in the tooling that would prevent it!
One of the big things that blocked this shipping for so long was not having an escape hatch of some kind to allow clients that disable WebAssembly by policy to get through the gate. In my experience most clients don't have JavaScript enabled but WebAssembly disabled, however there are a few notable usecases that forced my hand: iOS Lockdown mode and GrapheneOS' Vanadium's default configuration. This combination of factors means that there would need to be another implementation of the proof of work code in JavaScript that would actually execute the number crunching.
I don't want to make another implementation of the proof of work function (the entire point of this is to only have one implementation!) so while I was browsing around I came across the legendary talk The Birth & Death of JavaScript and got a horrible idea. What if you just compiled the WebAssembly to JavaScript? Would that even work? It's "just" turning one Turing machine into another, right? How would it fare in practice?
Turns out I'm not the first person to think about this! The team behind binaryen have made this escape hatch in the form of wasm2js which takes WebAssembly binaries and produces moderately cromulent JavaScript in response. One of the main downsides is that the generated binaries tend to be rather large.
For example consider this simple WebAssembly module that exposes a function that adds two numbers together:
(module
          (func $add (param $lhs i32) (param $rhs i32) (result i32)
            local.get $lhs
            local.get $rhs
            i32.add)
          (export "add" (func $add))
        )
Seems simple enough, right? Here's the JavaScript that generates:
function asmFunc(imports) {
          var Math_imul = Math.imul;
          var Math_fround = Math.fround;
          var Math_abs = Math.abs;
          var Math_clz32 = Math.clz32;
          var Math_min = Math.min;
          var Math_max = Math.max;
          var Math_floor = Math.floor;
          var Math_ceil = Math.ceil;
          var Math_trunc = Math.trunc;
          var Math_sqrt = Math.sqrt;
          function $0($0_1, $1) {
            $0_1 = $0_1 | 0;
            $1 = $1 | 0;
            return ($0_1 + $1) | 0 | 0;
          }

          return {
            add: $0,
          };
        }

        var retasmFunc = asmFunc({});
        export var add = retasmFunc.add;
As you can imagine, this only gets progressively worse as you end up making the Rust standard library get compiled from WASM to JavaScript, and even worse when you actually get hashing functions into the mix. The end result is probably very optimized when you run it through a JIT, but given that this runs on an interpreter it's probably gonna be slow no matter what I do.
Sorry! I tried!
This ended up working fairly well in testing, but I tried building it in GitHub Actions and ran into an issue. I noticed that wasm2js was packaged in Ubuntu and that the version in Fedora worked fine but the version in Ubuntu did not and threw an obscure error message about not understanding the tail call extension that Rust was using for some reason.
I ended up bisecting versions of binaryen by downloading a tarball, building it from source, and then seeing if the result of running it on the Anubis WebAssembly modules worked in a browser. I ended up selecting Binaryen version 128, the newest version at the time. It was new enough that most of the distributions that package Anubis don't have that version of Binaryen packaged.
However I didn't want to make my life more complicated by having some kind of conditional compilation step that would effectively tell end users "sorry, the admin is using an unofficial build that just so happens to not support your browser, please complain to them" because they'll just end up complaining to me. In my experience the kinds of people who run this exact combination of circumstances also tend to be the kind of people that have a wide variance in the level of kindness they display to the authors of open source programs that happen to be in their way. So I needed an escape hatch that would force build systems to use the exact version that I use in my builds.
Then inspiration hit me as if Apollo himself sniped me from the heavens. We're dealing with WebAssembly here right? What's stopping us from just compiling the WebAssembly to JS tool to WebAssembly with some kind of reproducible build, committing that blob to the repo, and then moving on with life?
I ended up finding a bug in LLVM around how it was iterating over exception handling blocks by the compiler iterating over them in machine pointer order. As a result each build would drift by about 29 bytes per build:
  i32.load  offset=4            ;; 28 02 04
          i32.const 6                   ;; 41 06
          i32.ne                        ;; 47
          br_if     0                   ;; 0d 00
        - try_table (catch_all_ref 8)   ;; 1f 40 01 03 08
        + try_table (catch_all_ref 4)   ;; 1f 40 01 03 04
        + try_table (catch_all_ref 9)   ;; 1f 40 01 03 09
            local.get 2                 ;; 20 02
            i32.const 32                ;; 41 20
            i32.add                     ;; 6a
            local.set 3                 ;; 21 03
            local.get 2                 ;; 20 02
            i32.const 56                ;; 41 38
            i32.add                     ;; 6a
            local.get 1                 ;; 20 01
            i32.const 8                 ;; 41 08
            i32.add                     ;; 6a
            call 17461                  ;; 10 b5 88 81 80 00
            local.set 4                 ;; 21 04
          end                           ;; 0b
        - try_table (catch_all_ref 4)   ;; 1f 40 01 03 04
            local.get 3                 ;; 20 03
            local.get 4                 ;; 20 04
This is what lead me to write I hate compilers as a combination blogpost/cry for help which made me realize this was actually an LLVM bug. I didn't instantly lean towards it being an LLVM bug until I figured out that disabling ASLR (via setarch --addr-no-randomize) made the results consistent on the same host within the same boot.
Honestly this is the first time in my career I've ever run into a compiler bug like this. When I do a lot of my work I usually work under the assumption that the compiler is bug-free and that my inputs are wrong somehow. As such, even thinking it could possibly be an LLVM bug was just outside of the realm of possibility for me.
Once that LLVM bug got fixed and a new version of wasi-sdk with that fix got released, I was off to the races, updated my build of wasm-opt/wasm2js, made my build scripts run it with wasmtime (alongside a wazero-based fallback process that would be slower, but did work enough) and everything worked out. Every time Anubis builds the WebAssembly in CI it uses the version of wasm-opt and wasm2js that ships in the repo to ensure that everything is as byte-for-byte deterministic as possible.
Your build tools can't differ from my build tools if I ship you the build tools I use.
Then we get into the other big problem that made this difficult: browser testing. One of the most common failure modes of Anubis is that someone uses some browser that I don't test in CI and then things don't work with it. I'm tired of installing 50 different browsers on several machines to test things and I have gone through so many throwaway VMs that I'm sure it's reduced the lifetime of my SSD.
Yes, I really have been testing Anubis by hand in god knows how many browsers. Why do you think it takes so long to tag new releases?
I built a harness that I call "chromesweep" that lets me spawn many Googles Chrome (term c.f. Attorneys General, et.al) in their default configuration to try and hit a version of Anubis listening over HTTPS. Getting this far meant making a library of all of these browser versions. I've put that library up on Github at TecharoHQ/gubal in case it's useful for you.
One of the other big problems I ran into while getting browser testing working was making sure that my Googles Chrome strictly stay within the bounds of my Kubernetes cluster's network. Chrome this old is actively radioactive and I want to treat it like the security threat it is. As such, I set up a strict NetworkPolicy to only allow it to access the Anubis instance under test and make DNS queries. I also wrap each Chrome pod in a microVM with Kata containers as an additional layer of security.
It honestly terrifies me to think that I am putting more effort into securing these Googles Chrome than big AI companies are putting into securing their AI agent testing infrastructure. It literally doesn't take much to put a big dent into securing things! The current state of our industry boggles the mind. All I want is for Techaro's FelonyBench score to remain at 0, is that too much to ask?
I also rigged the browser testing infrastructure up to a single slash command in GitHub pull requests. Doing it makes my office very warm so I try to avoid doing it when possible. This works well enough that it lets me move on to the next stage and has already caught something that lead to building all the JavaScript with the --chrome66 flag.
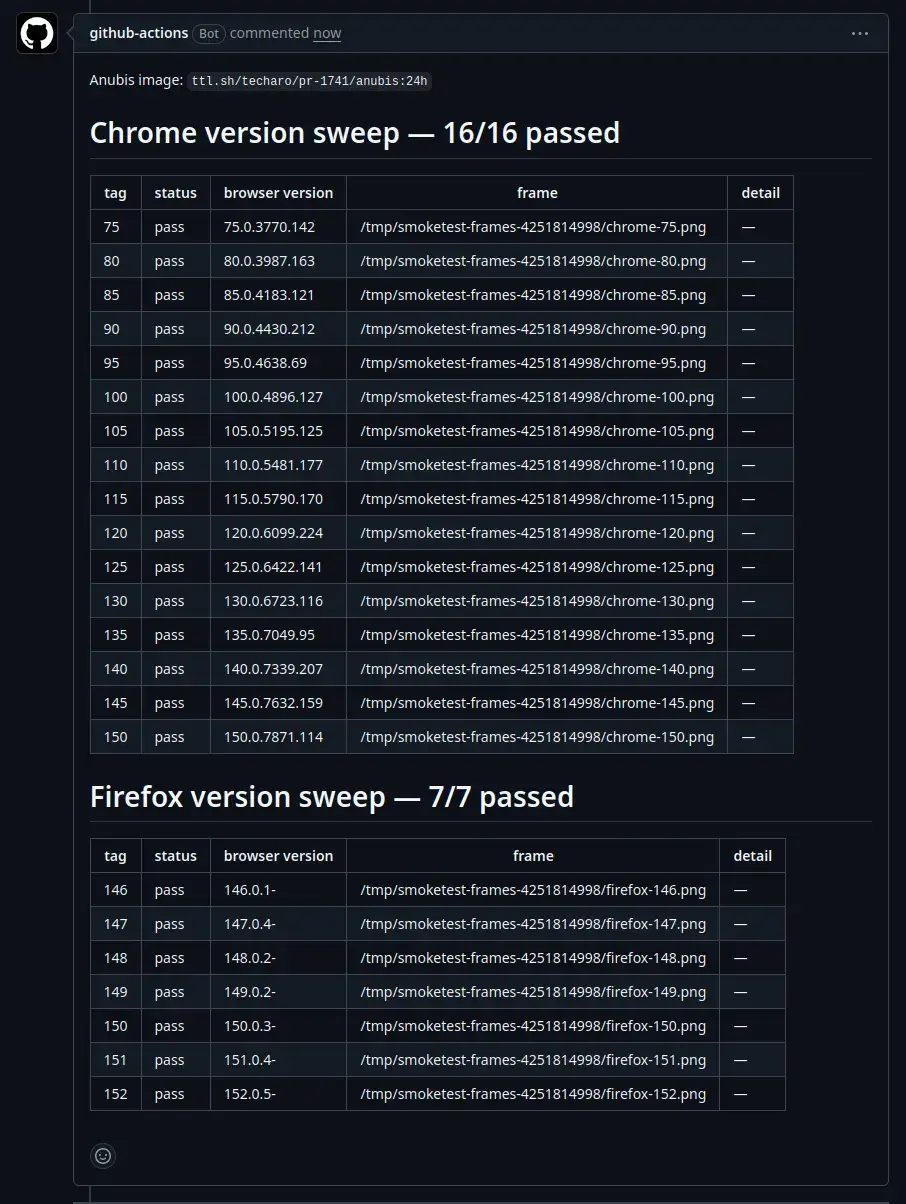
I wonder if this is yet another case where making infrastructure for Anubis could result in that infrastructure alone being its own viable tech product. I run into a lot of those.
In the process of doing that automated browser testing I found out that Chrome 75 had a weird error pop up when it tried to compile Anubis' WASM to native code:
CompileError: WebAssembly.compile(): Compiling function
        #4:"_RINvMs0_NtNtNtNtCsdl5sGgnNXvY_3std3sys4sync4on..." failed:
        expected table index 0, found 128 @+664
This also caused failures up to Chrome 100, so this signaled to me that something I was doing with my "strict MVP" build of Anubis' WASM wasn't in fact sticking to just the MVP features of WebAssembly. It turns out that the function referenced (probably somewhere in std::sync::Once? I probably should have traced it down to the exact bit) was in the standard library. This surprised me because I assumed that building Rust code with CPU features selected would apply that to everything, including the standard library, right?
No, turns out that when you download the rust-std component in rustup, that doesn't just download the standard library. To aid in cross compilation and I guess to avoid disk space waste, the Rust standard library is precompiled. This surprised me as Go typically has you recompile the standard library (and runtime for that matter) when doing normal builds and cross compilation.
The actual issue here is that the stdlib function in question was compiled down
to use reference
types,
which made
call_indirect
references get stored as a table index instead of what MVP WebAssembly would
put there. Chrome tried to read a null byte, got not a null byte, and then
understandably exploded.
I looked into the process involved for rebuilding the standard library twice: once with only MVP wasm features enabled and once with an "all yes config" like usual. Based on some research I did this seemed like a massive pain.
However, I had gone through that effort to build reproducible WASI versions of wasm2js and wasm-opt. wasm-opt is a tool that lets you take compiled WebAssembly modules, optimize them, and more importantly remove features from them so they can run in older browsers. After a bit of hacking to make sure that the tools were able to run properly, I set up a Claude Opus / GLM 5.2 loop to fuzz various wasm-opt flags and make sure Chrome 75 could parse the output. I ended up with these flags:
# Chrome shipped sign-ext and mutable-globals in 74, bulk-memory and
        # nontrapping-fptoint in 75, multivalue in 85 and simd in 91.
        baseline_features="-mvp --enable-sign-ext --enable-mutable-globals \
        --enable-bulk-memory --enable-nontrapping-float-to-int"
        simd128_features="${baseline_features} --enable-multivalue --enable-simd"
This strips away all the other WebAssembly features from the build like unwanted paint (the -mvp flag means "disable everything not in the original MVP definition of WebAssembly"). I think that it'd be safe-ish to enable reference types in the SIMD build (they were added before Chrome added SIMD), but it's not hurting anything to remove them so I'll just let cowardice win here. Either way, I threw the results into chromesweep and got a successful response, so win! If/when this comes to bite me I'll try and improve it.
I'm pretty sure that this work isn't perfect, but at some point you gotta cut your losses, ship it, and then see where things fail to prioritize perfecting it. These issues include but are not limited to:
update_nonce import stubbed out. I have no idea how to properly wire that up with the constraints of my runtime, but I'm sure I can figure it out eventually.Overall though, I'm hopeful that most of the worst parts of this can be solved. It would be nice if I didn't have to work what amounts to two full time jobs.
I'm pretty sure that this is stable enough to ship as off-by-default in Anubis v1.28.0: Wuk Lamat. Based on the feedback I get from administrators and users, I'll enable it in the default configuration in Anubis v1.29.0.
I hope this look into how Anubis is developed can give you ideas as to the scale and challenge involved. Making something like this is tireless and thankless work and it's really weird to see people talk about it in the same breath as Cloudflare or AWS' WAF.
Have a good day all!
AI was not used in the production of the prose of this article. I have my draft as a Google Doc so you can see exactly where and when I typed every word myself. The only use of AI was Claude Opus to help me make the visual bit/nibble diagram.
2026-09-01 08:00:00
One of the hardest problems in distributed systems is conflict resolution, or the same basic problem as merge conflicts in Git. Git merge conflicts happen when your branch differs from upstream in a way that Git can’t easily work its way around so it exposes both sides of the changes to humans and has the human (or their agent) figure out which side is “correct”. Distributed systems don’t really have this same flow as the scale of changes is often impossible for any human or team of humans to keep up with.
As a result, we really want to have our own business logic define which side of a conflict wins. FoundationDB doesn’t let us do that out of the box, so we had to make our own layer. The neat part about being able to do this is that this lets us control the replication behaviour of buckets based on user needs. The three main ways it differs are with single-region buckets, multi/dual-region buckets, and global buckets. I’m going to cover the replication differences in the order of complexity.
One of the easiest conflict resolution methods we have is a single-region bucket, which prevents any need for it. In this mode all actions are reverse proxied to the bucket’s region and any metadata changes are local to that region in particular. This means that any other regions trust the changes made by the bucket’s region and reject any changes made by any other regions. As a side effect this also means that the data does not move between regions like other buckets do. You’d think that would mean “if a region goes down, my bucket goes down.” But we have implemented data proxying, which means that if that region’s block storage is still available, other gateways can route requests to it and you can still access your data come hell, high water, or Giant Meteors.
The conflict resolution flow is like this:
┌────────────┐ ┌────────────────────┐ ┌───────────────────────────────┐│ client │ ───▶ │ nearest Tigris │ ───▶ │ owning region ││ PutObject │ │ gateway │ │ │└────────────┘ │ │ │ 1. bytes ──▶ block store ││ which region owns │ │ 2. metadata ──▶ FoundationDB ││ this bucket? │ │ (one gRPC commit) │└────────────────────┘ │ 3. return success │└───────────────┬───────────────┘│reads queue │ (async)▼┌───────────────────────────────┐│ replication worker ││ every other region gets ││ a read-only copy │└───────────────────────────────┘
The main tradeoff with a single-region bucket is that you trade strict consistency (because there is only one possible writer) with higher latency (unless all of your workload is geographically close to that Tigris region in particular). This makes a Tigris bucket mostly behave like a region-locked S3 bucket with the exception of being able to query the files globally without having to configure your client to access that particular region.
That was nice and simple. In comparison, global buckets are not.
Global buckets let any region be authoritative for any aspect of the bucket or any object in the bucket. Any changes get committed to the local FoundationDB cluster and then lazily replicated out to the other regions. This also means that we expect there to be some level of conflict. Imagine an object storage bucket like a git repository. You end up having conflicts when multiple people push to the same files. How do we decide who wins? You can’t just have a person sit there and decide which version of an object is right all the time.
Remember that we run a separate FoundationDB cluster per region. FoundationDB has a sequencer that gives version identity to everything in the cluster. Those versions are also based on time so you think we’d just be able to use those and compare them to know which version is the newest, right? Well, it turns out that FoundationDB versionstamps aren’t comparable across clusters as they’re partly based on the cluster’s creation date and all of our clusters were created at different times as we scaled globally. So we have to use something else that changes fairly constantly between clusters in a way that’s easy for us to validate without too much extra effort. Ideally, it’s something we already keep in sync for making sure everything else in the system works.
Like many other things in Tigris, we use time to determine who wins a conflict.
Using time for this sounds boring, but time synchronization is unironically one of the most complicated things in computing. This is a field where phrases like “temporal smearing”, “false ticker” and “clock skew” are thrown around freely and ends up being a mess in practice. It’s a small miracle that any of this works in practice.
Here’s a paraphrased and reformatted version of our conflict resolution function:
compare(previous, new, force)│├── is prev or next unset, or a brand-new key in FDB?│ yes: different objects ──────────▶ drop, log the conflict ✗│├── is prev older than the new data?│ yes: the new version is newer ───▶ apply, row replaced ✓│└── tie, or new is older: is this a forced change?yes: tie forcibly broken ────────▶ apply, row replaced ✓no ──────────────────────────────▶ drop, log the conflict ✗
Or: we prioritize the most recent entry when possible, accounting for deletions and the like such that a newer delete wins over an older update. This combined with eventual consistency means that there are potentially situations where one region updates an object and another region deletes it at the same time. During that small replication window you can get a situation where Singapore says an object exists that Chicago says doesn’t exist, but in practice the replication delay is small enough (single digit seconds or thereabout) that it doesn’t matter.
In theory we could have done this by breaking out exotic things like conflict-free replicated data types, but that seems kinda overkill for our usecase. That would work great for the source control merge conflict problem though!
At this point clock skew is also a factor. We run NTP clients on all our infrastructure and that usually keeps us within about 10 microseconds (10,000 nanoseconds) off of NTP time. Given that we measure timestamps as nanoseconds to decide conflicts, clock skew-based ordering conflicts can genuinely be a factor.
Imagine that the two operations in Chicago were served by different servers that just so happen to have their clocks off by a fraction of a fraction of a second. A DELETE could be sequenced before a PUT and the object could be shown as deleted in Chicago but present in Singapore because that PUT replicated out after the delete was committed locally.
According to all the rules of the game, every region but Chicago sees that the DELETE is slightly older than the current data, so it ignores that DELETE and continues as if that PUT is the right state of the world.
client Chicago (bucket owner) Singapore│ │ ││ PUT thing.txt │ │├──────────────────────▶│ ││ │ │ stamped …000200│ │ │ (the clock ran a hair fast)│ │ ││ │ replicate @ …000200 ││ ├──────────────────────▶││ │ │ Singapore stores the│ │ │ live copy @ …000200│ │ ││ DELETE thing.txt │ │├──────────────────────▶│ ││ │ │ the clock still reads …000100,│ │ │ so the tombstone is stamped│ │ │ BEHIND the row it deletes│ 204 No Content │ ││◀─ ─ ─ ─ ─ ─ ─ ─ ─ ─ ─ ┤ ││ │ ││ │ tombstone @ …000100 ││ ├──────────────────────▶││ │ │ …000100 is not newer than│ │ │ …000200: the tombstone is│ │ │ dropped, the live copy survives│ │ ││ GET thing.txt │ │├───────────────────────┼──────────────────────▶││ 200 OK, the deleted object is back ││◀─ ─ ─ ─ ─ ─ ─ ─ ─ ─ ─ ┼ ─ ─ ─ ─ ─ ─ ─ ─ ─ ─ ─ ┤│ │ ││ PUT If-None-Match: * │ │├──────────────────────▶│ ││ 412 Precondition Failed ││◀─ ─ ─ ─ ─ ─ ─ ─ ─ ─ ─ ┤ │
This is the kind of race condition you can only really see in distributed systems at our scale or larger. Nothing that happens in this situation is a failure in the logic or implementation, it’s just a desync because of unfortunate timing.
I wish I could tell you an epic tale of time synchronization and other fun things along the way of fixing this particular issue, but the fix was sadly boring. We just refuse to process a DELETE when the DELETE is older than the data in the database. If the DELETE doesn’t land after the database row’s date, we re-read the clock and try again every 100 milliseconds up to 5 (five) times. If even that can’t result in a timestamp that sorts correctly we give up loudly to the client instead of quietly doing the wrong thing.
Our conflict resolution is only as good as our clocks are. Time synchronization like this is kind of a hard problem to solve and we’d like to avoid having to do that if we can. If this becomes an issue in the future, we may have to build sacrificial lamb servers with Cesium/Rubidium time cards and deploy those in our datacentres, kinda like the atomic clocks Google uses for Spanner. That would certainly make for a cool project!
Come to think of it, the premise of Neal Stephenson’s Anathem (where a group of timekeeping monks lock themselves in giant clocks as part of their timekeeping practices) makes a lot more sense after working in distributed systems for as long as I have. If timekeeping magic is all that we’ve known, it really is easy to miss what really goes on.
Finally we have multi-region buckets. These are the most complicated as they combine aspects of both single-region and global buckets. There wasn’t a protocol off the shelf that would do this for us– FoundationDB uses Paxos* internally, and I’ve read about MultiPaxos (and Matchmaker Paxos, Matchmaker MultiPaxos, it goes on…). It seems like everyone modifies the algorithm for their use case, I wonder if there is a “true” Paxos outside of academia. Maybe it was implemented by the one true Scotsman.
We replicate multi-region bucket metadata by having one region be the leader for a group and having that leader actively push out changes as well as enqueueing them like a global bucket. This means that the regions in the group get the data faster than they would otherwise and commits to the leader mean that the data is committed to all members of the group. It’s kinda like this:
client gateway leader follower 1 follower 2│ │ │ │ ││ PUT object │ │ │ │├──────────────▶│ │ │ ││ │ bytes + meta │ │ ││ ├──────────────▶│ │ ││ │ │ │ │ upload to the leader's block│ │ │ │ │ store, commit the metadata:│ │ │ │ │ ONE transaction writes the row│ │ │ │ │ and enqueues replication│ │ committed │ │ ││ │◀─ ─ ─ ─ ─ ─ ─ ┤ │ ││ │ │ │ ││ │ apply this right now │ ││ ├───────────────┼──────────────▶│ ││ │ apply this right now │ ││ ├───────────────┼───────────────┼──────────────▶││ │ │ │ │ pushed to every follower│ │ │ │ │ at once, in parallel│ │ ok │ │ ││ │◀─ ─ ─ ─ ─ ─ ─ ┼ ─ ─ ─ ─ ─ ─ ─ ┤ ││ │ error │ │ ││ │◀─ ─ ─ ─ ─ ─ ─ ┼ ─ ─ ─ ─ ─ ─ ─ ┼ ─ ─ ─ ─ ─ ─ ─ ┤│ │ │ │ ││ 200 OK │ │ │ ││◀─ ─ ─ ─ ─ ─ ─ ┤ │ │ ││ │ │ │ │ one follower is enough· · · · ·│ │ │ │ │ seconds later, the queue delivers│ │ │ │ │ the same change all over again│ │ │ queued copy │ ││ │ ├──────────────▶│ ││ │ │ │ │ same timestamp, not newer:│ │ │ │ │ follower 1 drops it│ │ │ queued copy │ ││ │ ├───────────────┼──────────────▶││ │ │ │ │ nothing here yet, so it applies:│ │ │ │ │ follower 2 catches up
When a client writes to a multi-region bucket, Tigris forwards the write to the leader and blocks there. If the leader can’t take it, the write errors out and nothing changes. If the leader commits the change, the gateway actively pushes that change out to the other regions in the group in parallel and waits for them to commit before answering the client. Interestingly enough, it uses the same codepath that the global replication workers use. Every region in the group is going to get this change twice: once from the fan-out on the leader’s commit and the other from the queue worker pushing it out a moment later.
This may also seem like a race condition, but remember that the replication rows contain the before and after state, a-la Postgres logical replication or git commit syncing. If the current data in the database is newer or the same as the data being pushed out, the change is ignored and the cluster moves on with life:
client gateway leader every follower│ │ │ ││ PUT object │ │ │├────────────────▶│ │ ││ │ commit the metadata ││ ├────────────────▶│ ││ │ │ │ the row is written and durable.│ │ │ │ there is no undo from here│ │ committed │ ││ │◀─ ─ ─ ─ ─ ─ ─ ─ ┤ ││ │ │ ││ │ apply this right now ││ ├─────────────────┼──────────────────▶││ │ error │ ││ │◀─ ─ ─ ─ ─ ─ ─ ─ ┼ ─ ─ ─ ─ ─ ─ ─ ─ ─ ┤│ │ │ ││ 5xx, your write failed │ ││◀─ ─ ─ ─ ─ ─ ─ ─ ┤ │ ││ │ │ │ no follower succeeded· · · ·│ │ │ │ but the queued copy was already│ │ │ │ durable, committed in the same│ │ │ │ transaction as the row│ │ │ queued copy ││ │ ├──────────────────▶││ │ │ │ applies normally│ │ │ ││ │ │ │ the write you were told failed is│ │ │ │ now readable in every region
At some level you can think about multi-region buckets as a latency optimization for the regions in the multi-region group. The replication queue is what actually guarantees the global convergence of metadata, but the active fan-out over regions is what gets there first. This means that if you have a multi-region bucket in the EU and all your workloads are in the EU, you get a lot of the same availability advantages of global buckets without a lot of the consistency risks of normal global buckets.
Given that this replication protocol isn’t a genuine two-phase commit (one phase local, the second phase when the rest of the group has all committed), it means that there is theoretically a case where a client can push a change to the bucket, have that commit locally, fail to eagerly push out the changes at the gateway level, and then return an error to the client after the data successfully was written. The queue would then lazily replicate out the data like nothing happened, meaning that the change would be pushed out even though it technically failed.
HTTP doesn’t really have a good error code for this kind of partial failure and the S3 API definitely does not either. If this becomes a problem in practice, we’ll have to create an S3API extension for this. Stay tuned!
Our current system has handled all customer load without too many issues. So that any region can answer questions about the data, all metadata is replicated to every region, even if it’s not requested anywhere else. This means that for even single region buckets, there’s the same load on the replication queue as there is for global buckets.
To work around this, we can compartmentalize the activities for these single region buckets by sharding our FoundationDB clusters by bucket type, or even by tenant, so the replication queue doesn’t risk lagging. We have a finite number of replication workers and if too many objects change all at the same time it can cause the replication delay to be minutes instead of seconds. The technical term for this is “bad”.
Right now there’s one central FoundationDB cluster per region which stores everything. In the future we plan to have one cluster that’s used to map metadata about which buckets/organizations belong to which clusters, and from there we will scale out depending on customer request pressure. If you’re a large enough tenant, you may end up getting your own dedicated FoundationDB cluster!
S3 request│▼┌─────────┐ ── which replicaset holds this tenant? ──▶ ┌────────────────┐│ gateway │ │ shard mapping │└─────────┘ ◀─ ─ ─ ─ ─ ─ "replicaset 2" ─ ─ ─ ─ ─ ─ │ cluster │║ └────────────────┘╚═══════════════════╗▼┌──────────────┐ ╔══════════════╗ ┌──────────────┐│ replicaset 1 │ ║ replicaset 2 ║ │ replicaset 3 ││ 2-3 FDB │ ║ 2-3 FDB ║ │ 2-3 FDB ││ clusters + │ ║ clusters + ║ │ clusters + ││ worker pool │ ║ worker pool ║ │ worker pool │└──────┬───────┘ ╚══════╤═══════╝ └──────┬───────┘│ │ │└──────────────────┼──────────────────┘▼┌───────────────────────┐│ global pointer table │└───────────────────────┘
Pop quiz for people reading this post via social media: which Massively Multiplayer Online Roleplaying Game is the origin of the term “sharding” and what happened to cause that to need to be done? The first person to answer right without searching wins the sense of pride and accomplishment that comes with being right on the Internet first.
This does come with the obvious downside of having to manage multiple clusters, but we think the tradeoff is worth it when it eliminates the problem of noisy neighbors causing replication delay. It will mean that our caching layer has to be a bit more complicated (at the very least we expect the mapping of organizations/buckets to FoundationDB clusters to be fairly stable), but that’s just a simple matter of programming at this point. It’s also gonna make replication “fun”, but we’ll cross that bridge when we come to it.
There’s three types of buckets but all of them use different shades of the same global replication logic. Most of the levers we offer are all around consistency, latency, and availability. Single region buckets remove the question of where the data is stored at the cost of making that one region a single point of failure. Global buckets embrace conflicts but can be a more latent when changes are replicated out. Multi-region buckets double-replicate your data across the cloud. All of these happen in regions that are far apart enough that synchronous round trips are genuinely expensive, but everything is just implementation details for the same basic object storage operations.
Computers really are something at this scale, aren’t they? The joys of our industry know no end.
If your workload is big enough, you could end up with a dedicated FoundationDB cluster all to yourself. Get in touch and let's see if your data qualifies.
2026-08-27 08:00:00
In the hours following the release of CVE-2026-41992 for the project GNU gzip, site reliability workers and systems administrators scrambled to desperately rebuild and patch all their systems to fix decompressing two files in the same invocation of gzip (that's possible???) an attacker can trigger out of bound reads in the LZH decoder, causing reads past the end of the shared global buffer that is somehow not reset between invocations. This is due to the affected components being written in C, the only programming language where these vulnerabilities regularly happen. "This was a terrible tragedy, but sometimes these things just happen and there's nothing anyone can do to stop them," said programmer Mr. Jayson Hilpert, echoing statements expressed by hundreds of thousands of programmers who use the only language where 90% of the world's memory safety vulnerabilities have occurred in the last 50 years, and whose projects are 20 times more likely to have security vulnerabilities. "It's a shame, but what can we do? There really isn't anything we can do to prevent memory safety vulnerabilities from happening if the programmer doesn't want to write their code in a robust manner." At press time, users of the only programming language in the world where these vulnerabilities regularly happen once or twice per quarter for the last eight years were referring to themselves and their situation as "helpless."

