

2026-11-20 20:37:52

Email attachments are base64. So are cryptographic PEM certificates. In both cases the text is broken into lines, 76 characters for email and 64 for PEM.
Skipping line endings sounds trivial. Yet many fast decoders only work on uninterrupted base64. As soon as they meet a line break, they fall back to a slow path.
How fast can we decode MIME base64 in popular programming languages? I wrote a small benchmark. I generate one megabyte of random bytes, encode it as base64 with 76-character lines ending in CRLF (1.37 MB of text) and decode it again with the standard or most popular function of each language. I check that each decoder returns the right bytes.
I use an Intel Xeon Gold 6548N (Emerald Rapids) with Linux, pinned to one core. I report speeds in gigabytes of input per second (GB/s). Each number is the median of three runs, and each run keeps the best of ten timed batches. I use the latest version of each tool.
| rank | system | function | GB/s |
|---|---|---|---|
| 1 | C++ (GCC 16) with simdutf 9.4 | simdutf::base64_to_binary |
18.4 |
| 2 | PHP 8.7-dev with my pull request | base64_decode |
17.1 |
| 3 | Python 3.15 with fastpybase64 | fastpybase64.b64decode |
16.4 |
| 4 | Bun 1.4.4 | Buffer.from(s, 'base64') |
14.2 |
| 5 | Node.js 26.13 | Buffer.from(s, 'base64') |
13.3 |
| 6 | Deno 2.9.8 | Uint8Array.fromBase64(s) |
8.4 |
| 7 | .NET 11 | Base64.DecodeFromUtf8 |
4.9 |
| 8 | Go 1.27.4 | base64.StdEncoding.Decode |
1.6 |
| 9 | Java 27 | Base64.getMimeDecoder().decode |
1.2 |
| 10 | Zig 0.17.1 |
std.base64 decoder ignoring \r\n
|
0.85 |
| 11 | PHP 8.5.12 | base64_decode |
0.61 |

There is a factor of thirty between the top and the bottom of the table.
The top six systems all rely on the simdutf library. The simdutf library removes the line endings inside its vector loop. A clean block of 64 characters is decoded directly. A block that contains line endings is compacted first, and decoding proceeds from a small buffer. The line endings never send the decoder to a slow path. See Lemire (2027) for the details.
PHP is the most dramatic case. With the current release, PHP is last at 0.61 GB/s, even though it decodes base64 without line endings at more than 20 GB/s on this machine. My pull request ports the simdutf decoders to PHP. It makes MIME decoding 28 times faster, and PHP moves to second place.
Lemire, D. (2027). Fast forgiving base64 decoding with SIMD instructions. ACM Transactions on Architecture and Code Optimization, 24(1). (arXiv)
Muła, W., & Lemire, D. (2020). Base64 encoding and decoding at almost the speed of a memory copy. Software: Practice and Experience, 50(2), 89–97. (arXiv)
2026-11-19 03:43:03
Let us start with an example that triggers the issue.
byte[] src = ("A".repeat(128) + "=").getBytes(StandardCharsets.US_ASCII);
Base64.getDecoder().decode(src);
One hundred and twenty-eight letters A and one =. The string is not valid base64, and a correct decoder rejects it. OpenJDK writes past the end of the array anyway. The bug is CVE-2026-114938. It has been in the JDK since 17.0.6. It was introduced in OpenJDK back in June 2021. The bad write is in hand-written assembly.
There are claims that it leads to a major security vulnerability. I have not checked. But I care about the issue because I am indirectly involved.
Base64 turns three bytes into four ASCII characters. Email attachments are base64, and a string often ends with =. Java sizes the output before it checks the input. One trailing = counts as one byte of padding, so the allocated length is
3 × ((129 + 3) / 4) − 1 = 98.
So decode allocates 98 bytes, then calls the decoding routine.
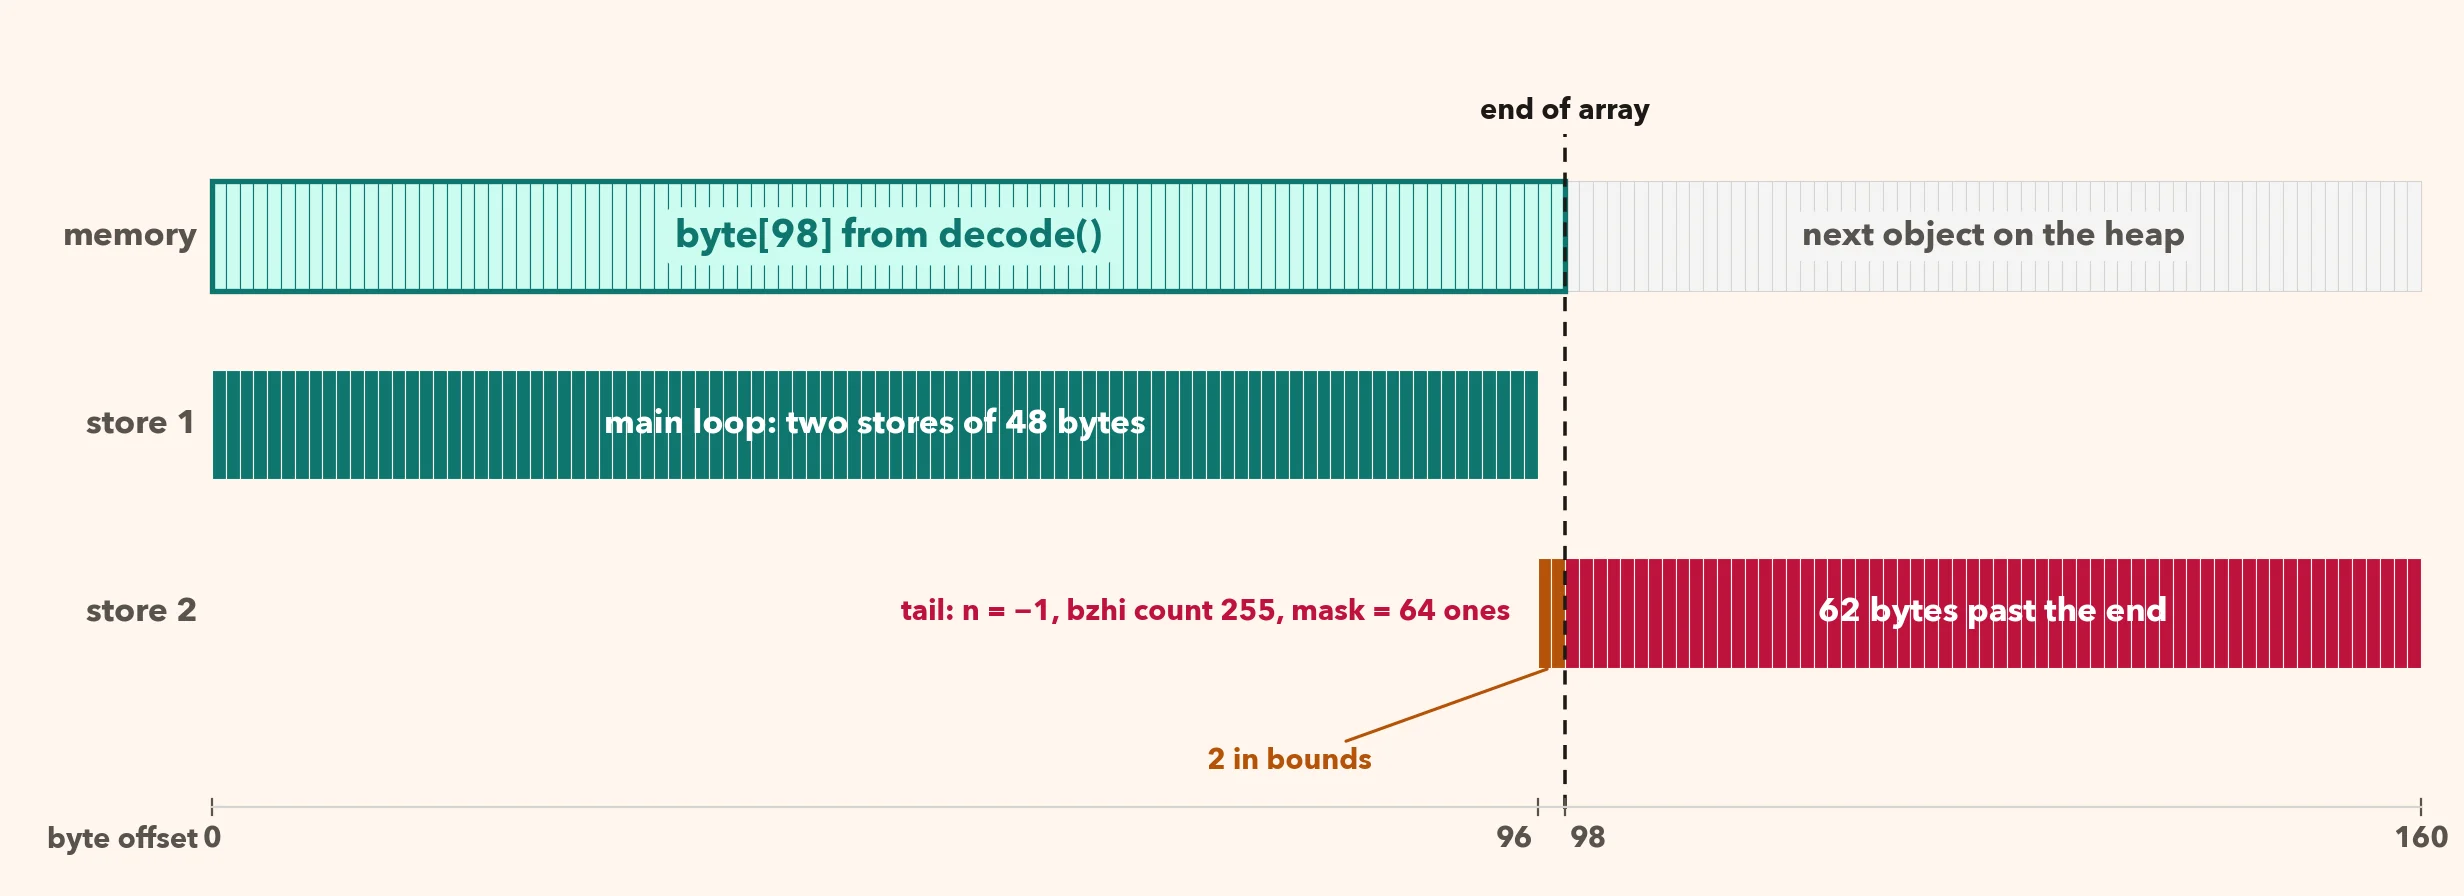
On an x86-64 machine with AVX-512 VBMI, the routine takes the first 128 characters as two blocks and writes 96 bytes. That loop follows the algorithm from Muła & Lemire (2020). The character A is the value 0, so each block becomes 48 zero bytes. The store is masked to 48 bytes. Both stay inside the array.
One character is left, the =. The tail asks how many output bytes a remainder of that length should produce. In integer arithmetic,
(1 / 4) × 3 = 0.
The last character is =, so it subtracts one. The length is now −1.
The tail writes with an AVX-512 masked store. A masked store writes a byte only when the matching bit in a mask is set. See my article Modern vector programming with masked loads and stores. The mask comes from bzhi, which keeps the low n bits of a word of ones. The count it reads is the low 8 bits of n. The low 8 bits of −1 are 255. A count of 255 is past 64, and bzhi then clears nothing: every bit stays set, and the store writes the whole 64-byte register.
The store starts where the main loop stopped, at offset 96. The array ends at offset 97. Two bytes land in the array. The other 62, offsets 98 through 159, land past the end.
The function then returns. Java sees a = with no data character in the current group and throws IllegalArgumentException, with the message “Input byte array has wrong 4-byte ending unit”. The write has already happened.
So that’s the bug. As you can see, it is not the fault of our fancy algorithm. Thankfully for me.
Java is somewhat behind. The fast decoder stops at a space or a line break. Email wraps every 76 characters, and crypto (PEM) every 64, so the fast path in Java ends at the first line since it cannot handle spaces or line breaks.
The algorithm in Lemire (2027) removes the ignorable characters inside the vector loop. A clean block of 64 characters is decoded directly. A block that contains whitespace is compacted, and the alphabet characters are decoded from a small buffer. Since the middle of 2025 that decoder has shipped in Safari and in the Chromium browsers (Chrome, Edge, Brave), and in Node.js 25, Deno and Bun.
I have a pull request that ports the same decoders to PHP. Decoding a 64 KiB MIME input is 30 times faster on an Intel Xeon Gold 6548N, and 39 times faster on an AMD EPYC 9R45.
Muła, W., & Lemire, D. (2020). Base64 encoding and decoding at almost the speed of a memory copy. Software: Practice and Experience, 50(2), 89–97. (arXiv)
Lemire, D. (2027). Fast forgiving base64 decoding with SIMD instructions. ACM Transactions on Architecture and Code Optimization, 24(1). (arXiv)
2026-11-17 00:51:07
The most interesting change AI brings to software work is not faster coding. It is the expansion of context or range… what I call radius.
For decades the job was defined by the limits of what one person could hold in their head. You tended to specialize. You got good at one or two systems, one or two types of problems because keeping more than that coherent was expensive. Context switching hurt. Onboarding to a new project took days or weeks.
Simply issuing a pull request to a new open-source repository took days. You had to learn the conventions. Learn the code base. Find out how to test it. Find out how to run benchmarks.
With a good model and the right tools, you can load a large amount of relevant information into the session: the structure of several repositories, the conventions of different teams, recent issues, design decisions, performance constraints, the history of related libraries. You can ask questions across them, generate changes that stay consistent with local style, and keep more projects alive at once without the usual collapse in quality.
The unit of work stops being “the project I am currently deep in” and becomes something closer to “the set of projects I can keep coherent right now.”
This is not the same as having an assistant write code for you. It is more. The gain comes from the ability to hold and operate on a larger working set. You still decide what matters. You still check the results. What changes is how much of the surrounding system you can bring into focus at the same time.
The practical consequences are already visible for people who treat this as a skill rather than a novelty:
None of this is automatic. The model does not magically expand your capacity. You have to learn how to feed it the right context, how to structure the questions so the answers stay grounded, and how to verify the parts that matter. The people who get the most out of it treat the model as a high-bandwidth interface to a larger set of information.
Most discussion of AI in programming still focuses on the speed of generating individual functions or on the fear that juniors will not learn. Those are real topics, but they miss the larger shift. The constraint that shaped the profession for a long time, the limited amount of context a single developer could keep active, has loosened. What you can usefully own has grown. Learning to operate at that new scale is the part that is still under-discussed and under-practiced.
The cognitive radius of an engineer is the distance (in projects, technologies, or time) over which they can still produce consistent, well-informed work. AI has increased that radius.
2026-11-14 22:53:50

Many systems log their data as JSON, one record per line (NDJSON). GitHub, for example, publishes every public event on its site that way through GH Archive: about a gigabyte per hour. Suppose you want to know which repositories received the most stars over eight hours. That is 7.6 GB of JSON, 2.2 million events.
In Python, the obvious code reads each line with the json module:
for line in open("events.ndjson", "rb"):
    event = json.loads(line)
    if event["type"] == "WatchEvent":
        stars[event["repo"]["name"]] += 1
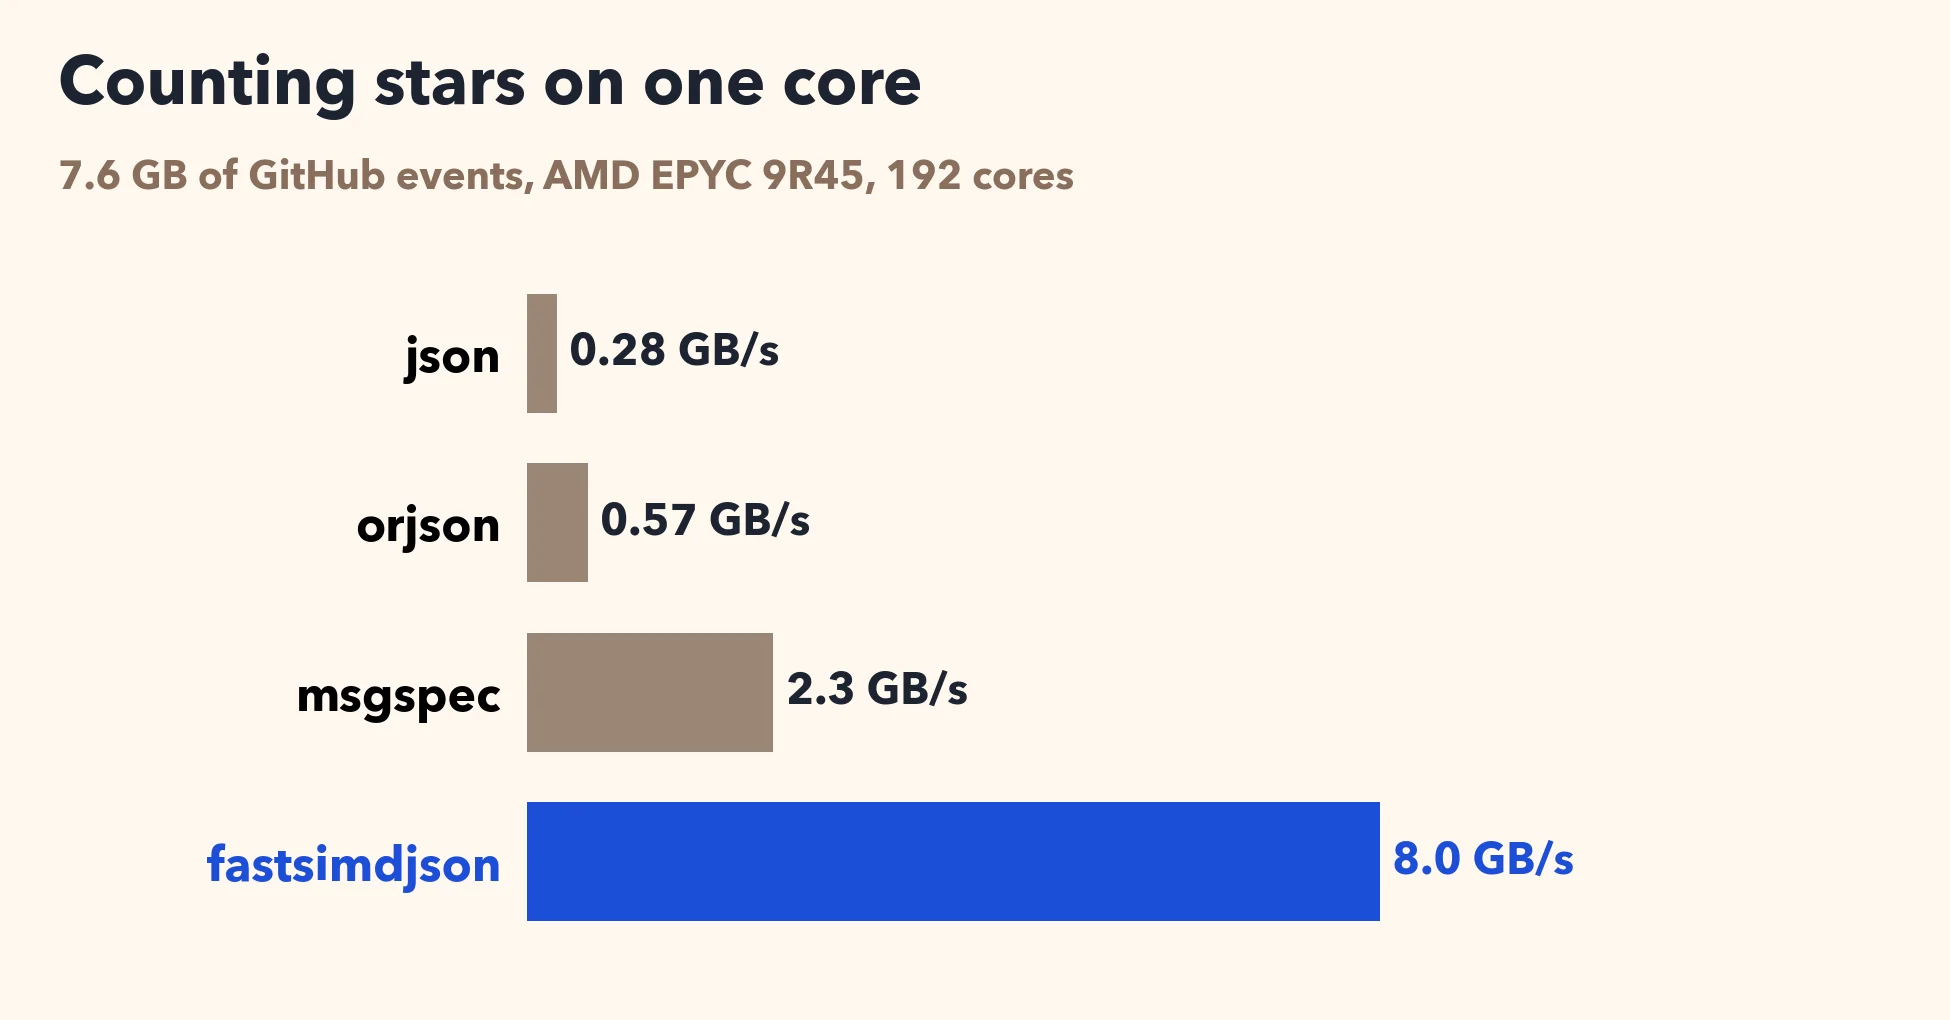
It runs at 0.28 GB/s: 27 seconds for this file. The orjson package is twice as fast. The msgspec package, which decodes only the fields you declare, is eight times as fast.
A server has many cores, but a Python process with the GIL runs Python code on one core at a time. The usual answer is a pool of processes: cut the file in pieces, give a piece to each process, and add up their counts. Each process returns a small table, so little has to come back.
Python 3.14 has a free-threaded build (python3.14t) without the GIL: threads run Python code at the same time. The fastsimdjson library is threaded. You give it the data and a function. It parses the records on many threads, and calls your function on the thread that parsed the record. You name the fields you want. It reads only what leads to them, and your function receives those values, not the whole record.
import collections
import fastsimdjson
def starred(event):
    kind, repo = event
    if kind == "WatchEvent":
        return repo
names = fastsimdjson.map_many(
    starred, data, threads=192,
    fields=["/type", "/repo/name"], drop_none=True)
stars = collections.Counter(names)
The variable data is the file, mapped in memory. The two paths are the event type and the repository name. The drop_none parameter leaves out the records that are not stars.
I ran this on an AWS instance (c8a.metal-48xl) with two AMD EPYC 9R45 processors, 192 cores, using Python 3.14.10, orjson 3.13 and msgspec 0.22. The file is mapped before the clock starts. On one core, fastsimdjson reads 8 GB/s, three and a half times as fast as msgspec.
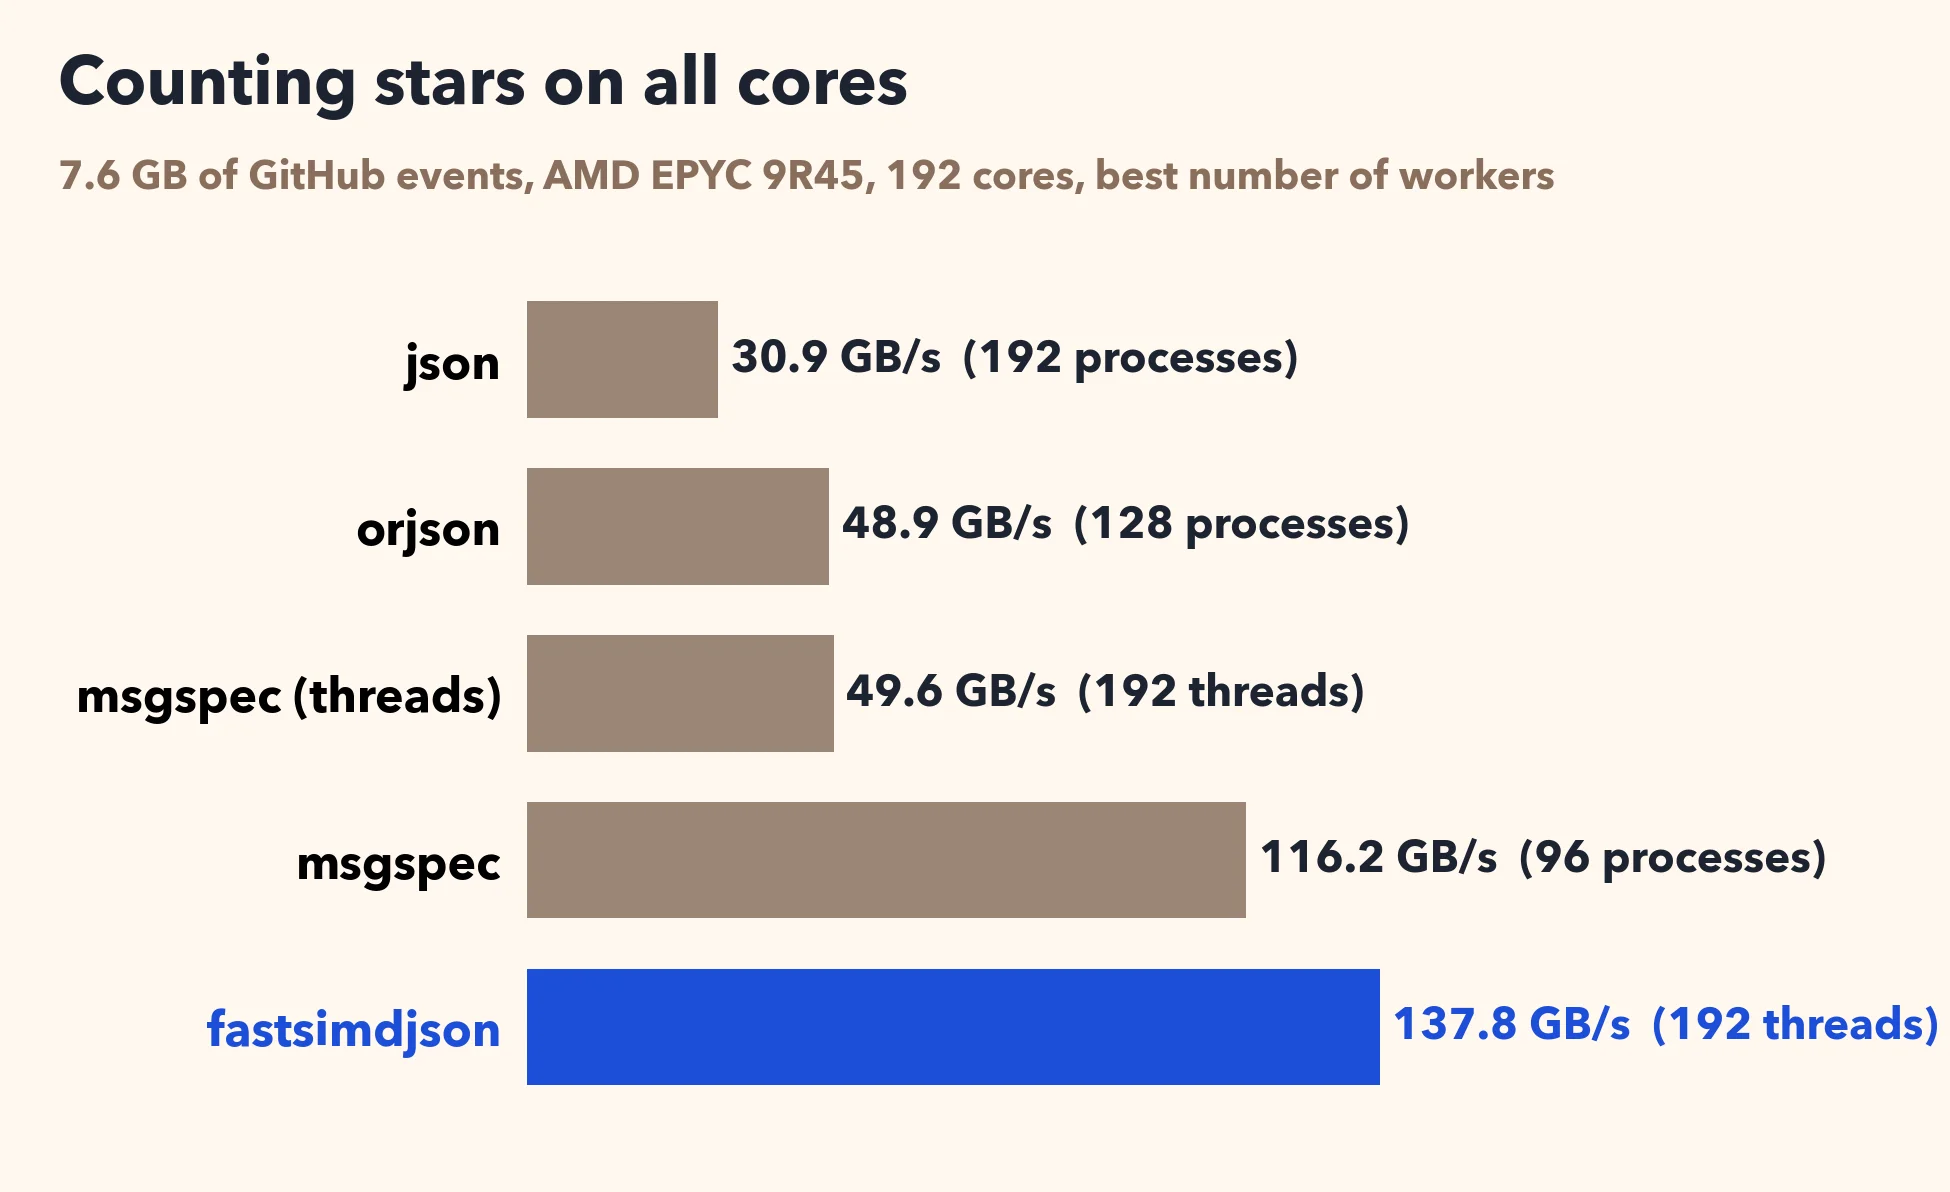
With 192 threads, fastsimdjson counts the stars in the 7.6 GB in 55 milliseconds: 138 GB/s. The best pool of msgspec processes reaches 116 GB/s, at 96 processes. More processes make it slower.
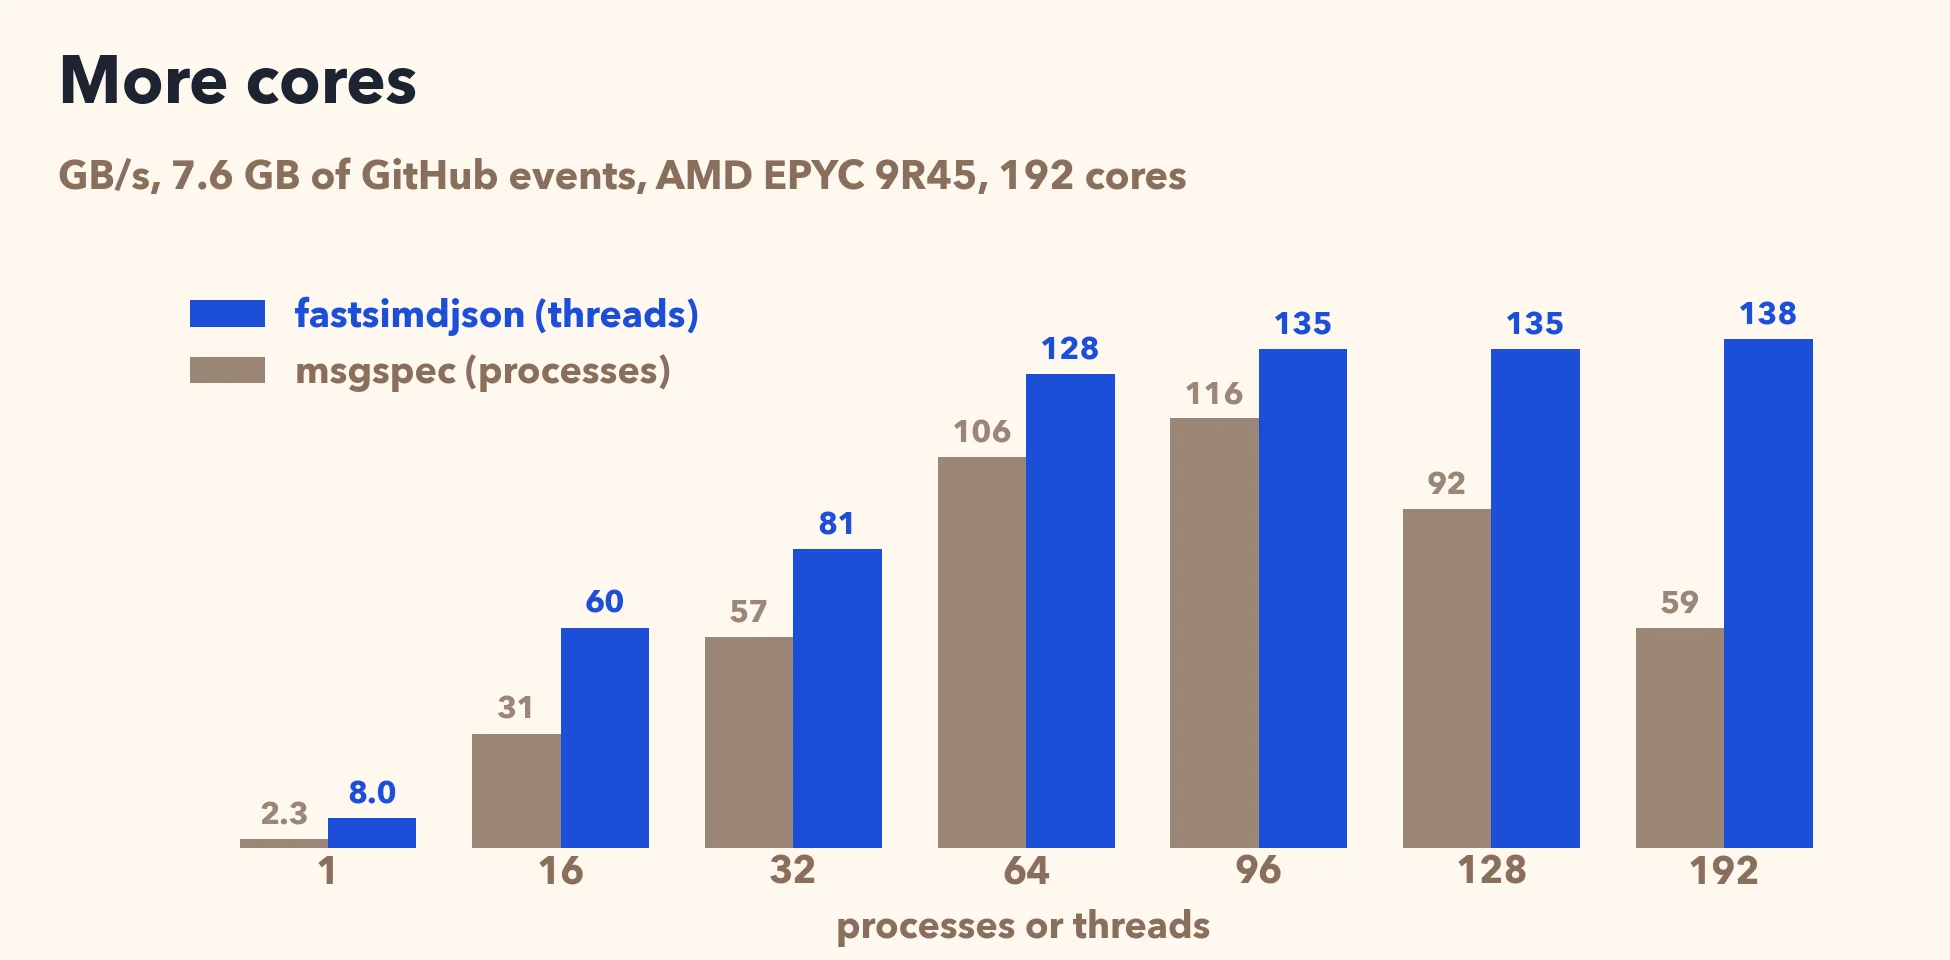
fastsimdjson is ahead at every worker count. The lead shrinks from three and a half times on one core to about 20%.
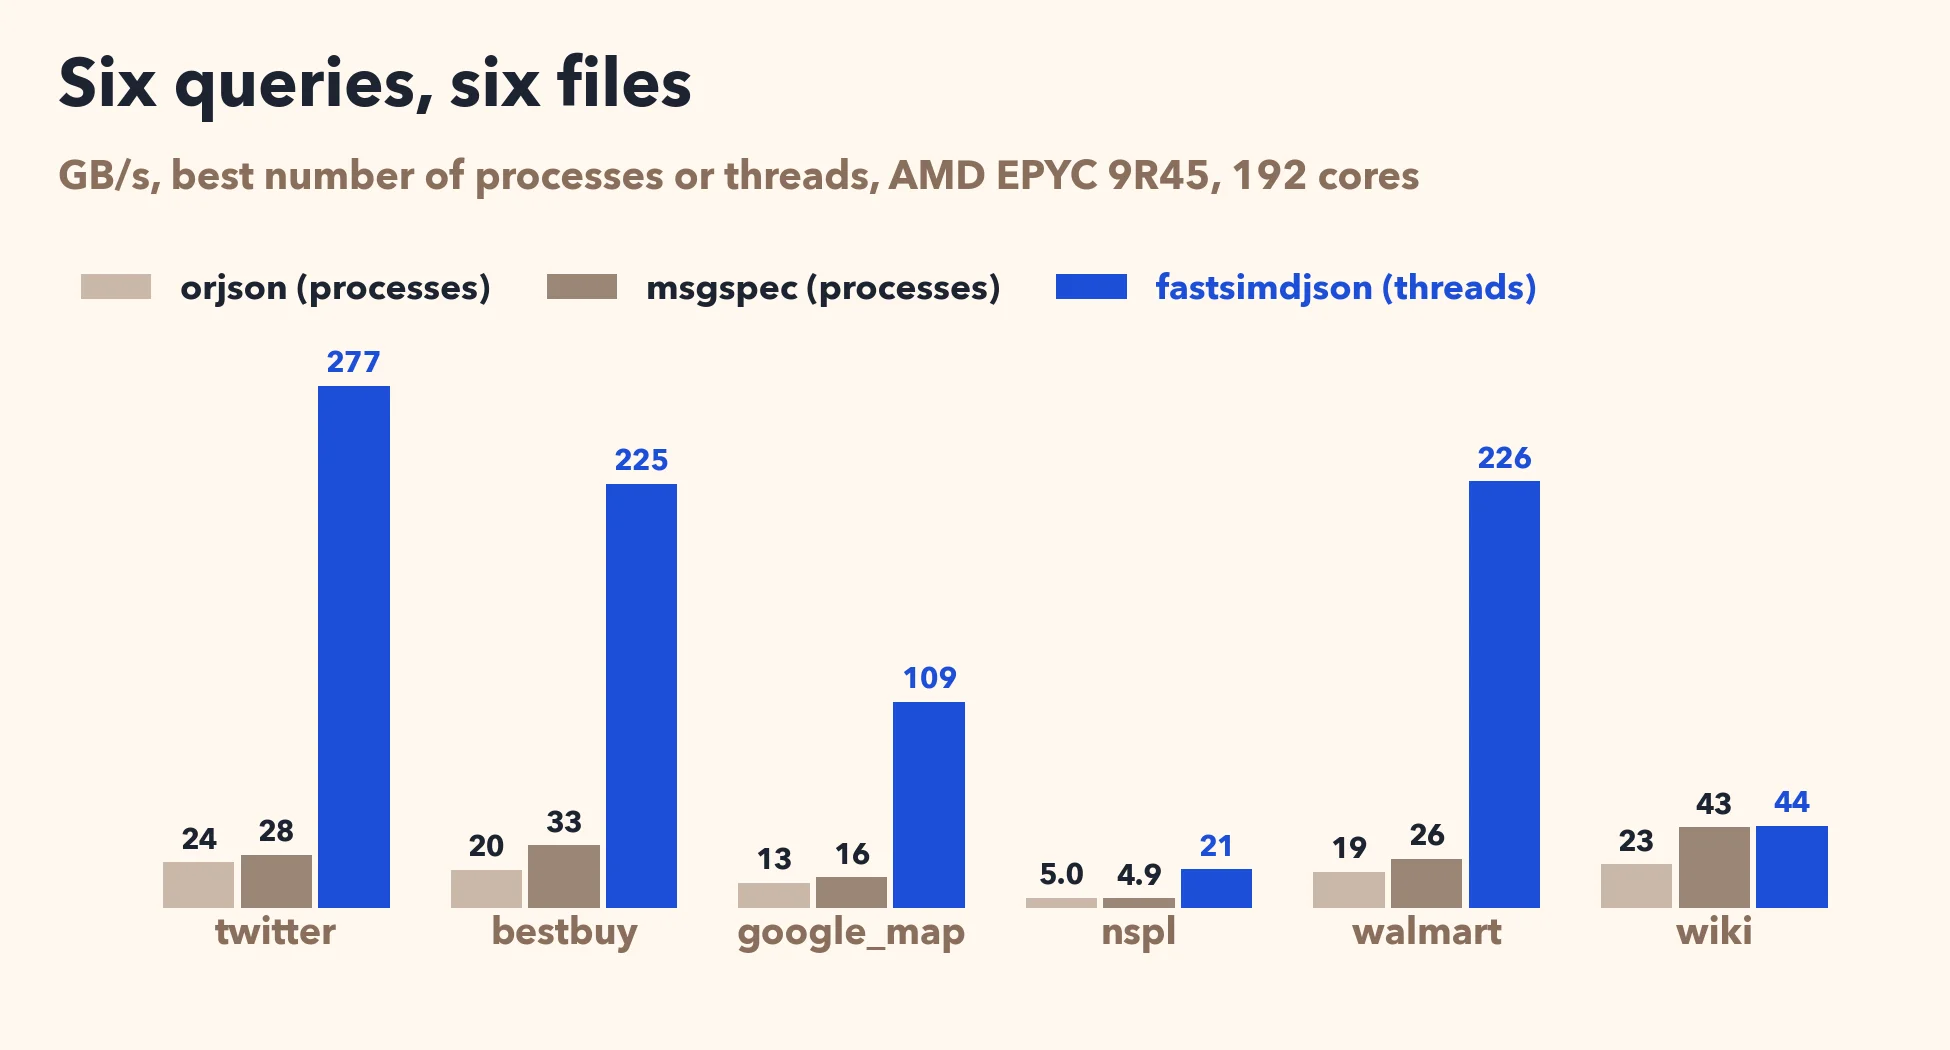
Counting is the best case for processes, because little comes back. Often you want the values themselves. I took six files of about a gigabyte from an existing benchmark (Pison), and pulled a field or two from every record. On the twitter file, fastsimdjson reaches 277 GB/s. Four of the six files pass 100 GB/s. The other two are slower: one stays near 20 GB/s, still about four times as fast as msgspec, and one is a tie.
2026-11-10 20:44:09

Our fast_float library parses numbers such as -731.51 into binary floating-point values. It is part of GCC’s C++ standard library, among others. It is fast: often a few nanoseconds per number.
Parsing a number means making decisions. Is there a sign? How many digits are there? Where is the decimal point? Is the processor rounding in the default mode? Each decision is a branch in the code. Modern processors do not wait to know the outcome of a branch: they guess, and they keep working. When they guess right, the branch is nearly free. When they guess wrong, they throw away the work done since the branch, and that costs 15 to 20 cycles.
When all your numbers look alike, the processor guesses right. When they do not, it guesses wrong often. Consider a column of gains and losses: the sign is random. The processor cannot guess it, and it pays for its mistakes on about half of the numbers.
You often know things about your data that the parser cannot know. So we are adding performance hints to fast_float. You pass them as a template argument:
using fast_float::performance_hints;
double value;
auto answer = fast_float::from_chars<performance_hints::unpredictable_sign>(
    input.data(), input.data() + input.size(), value);
There are three hints, and you may combine them with |:
unpredictable_sign: the signs come in random order. The parser then handles the sign without a branch.short_numbers: each number is given alone (the range holds just the number) and most numbers have at most 8 characters, such as 42.5 or -3.75, in varying shapes. The parser then reads all 8 characters at once with a few bitwise operations, without a branch on the number of digits or the position of the decimal point.assume_round_to_nearest: your program never changes the rounding mode, so the parser does not check it.The hints never change the results, with one exception. If you promise assume_round_to_nearest and some code in your program changes the rounding mode, some results will be wrong.
The hints work with fast_float::from_chars, fast_float::from_chars_advanced and fast_float::integer_times_pow10. Without hints, nothing changes.
How much do they help? I generated four kinds of data, 100,000 numbers each:
-731.51 or 42.07;-731271.51;7, 1042, 42.5 and 0.375;12.34.I parse them on an Intel Xeon Gold 6338 (Ice Lake) with GCC 15, and on an Apple M4 Max with Apple clang 17. I report millions of numbers parsed per second: higher is better.
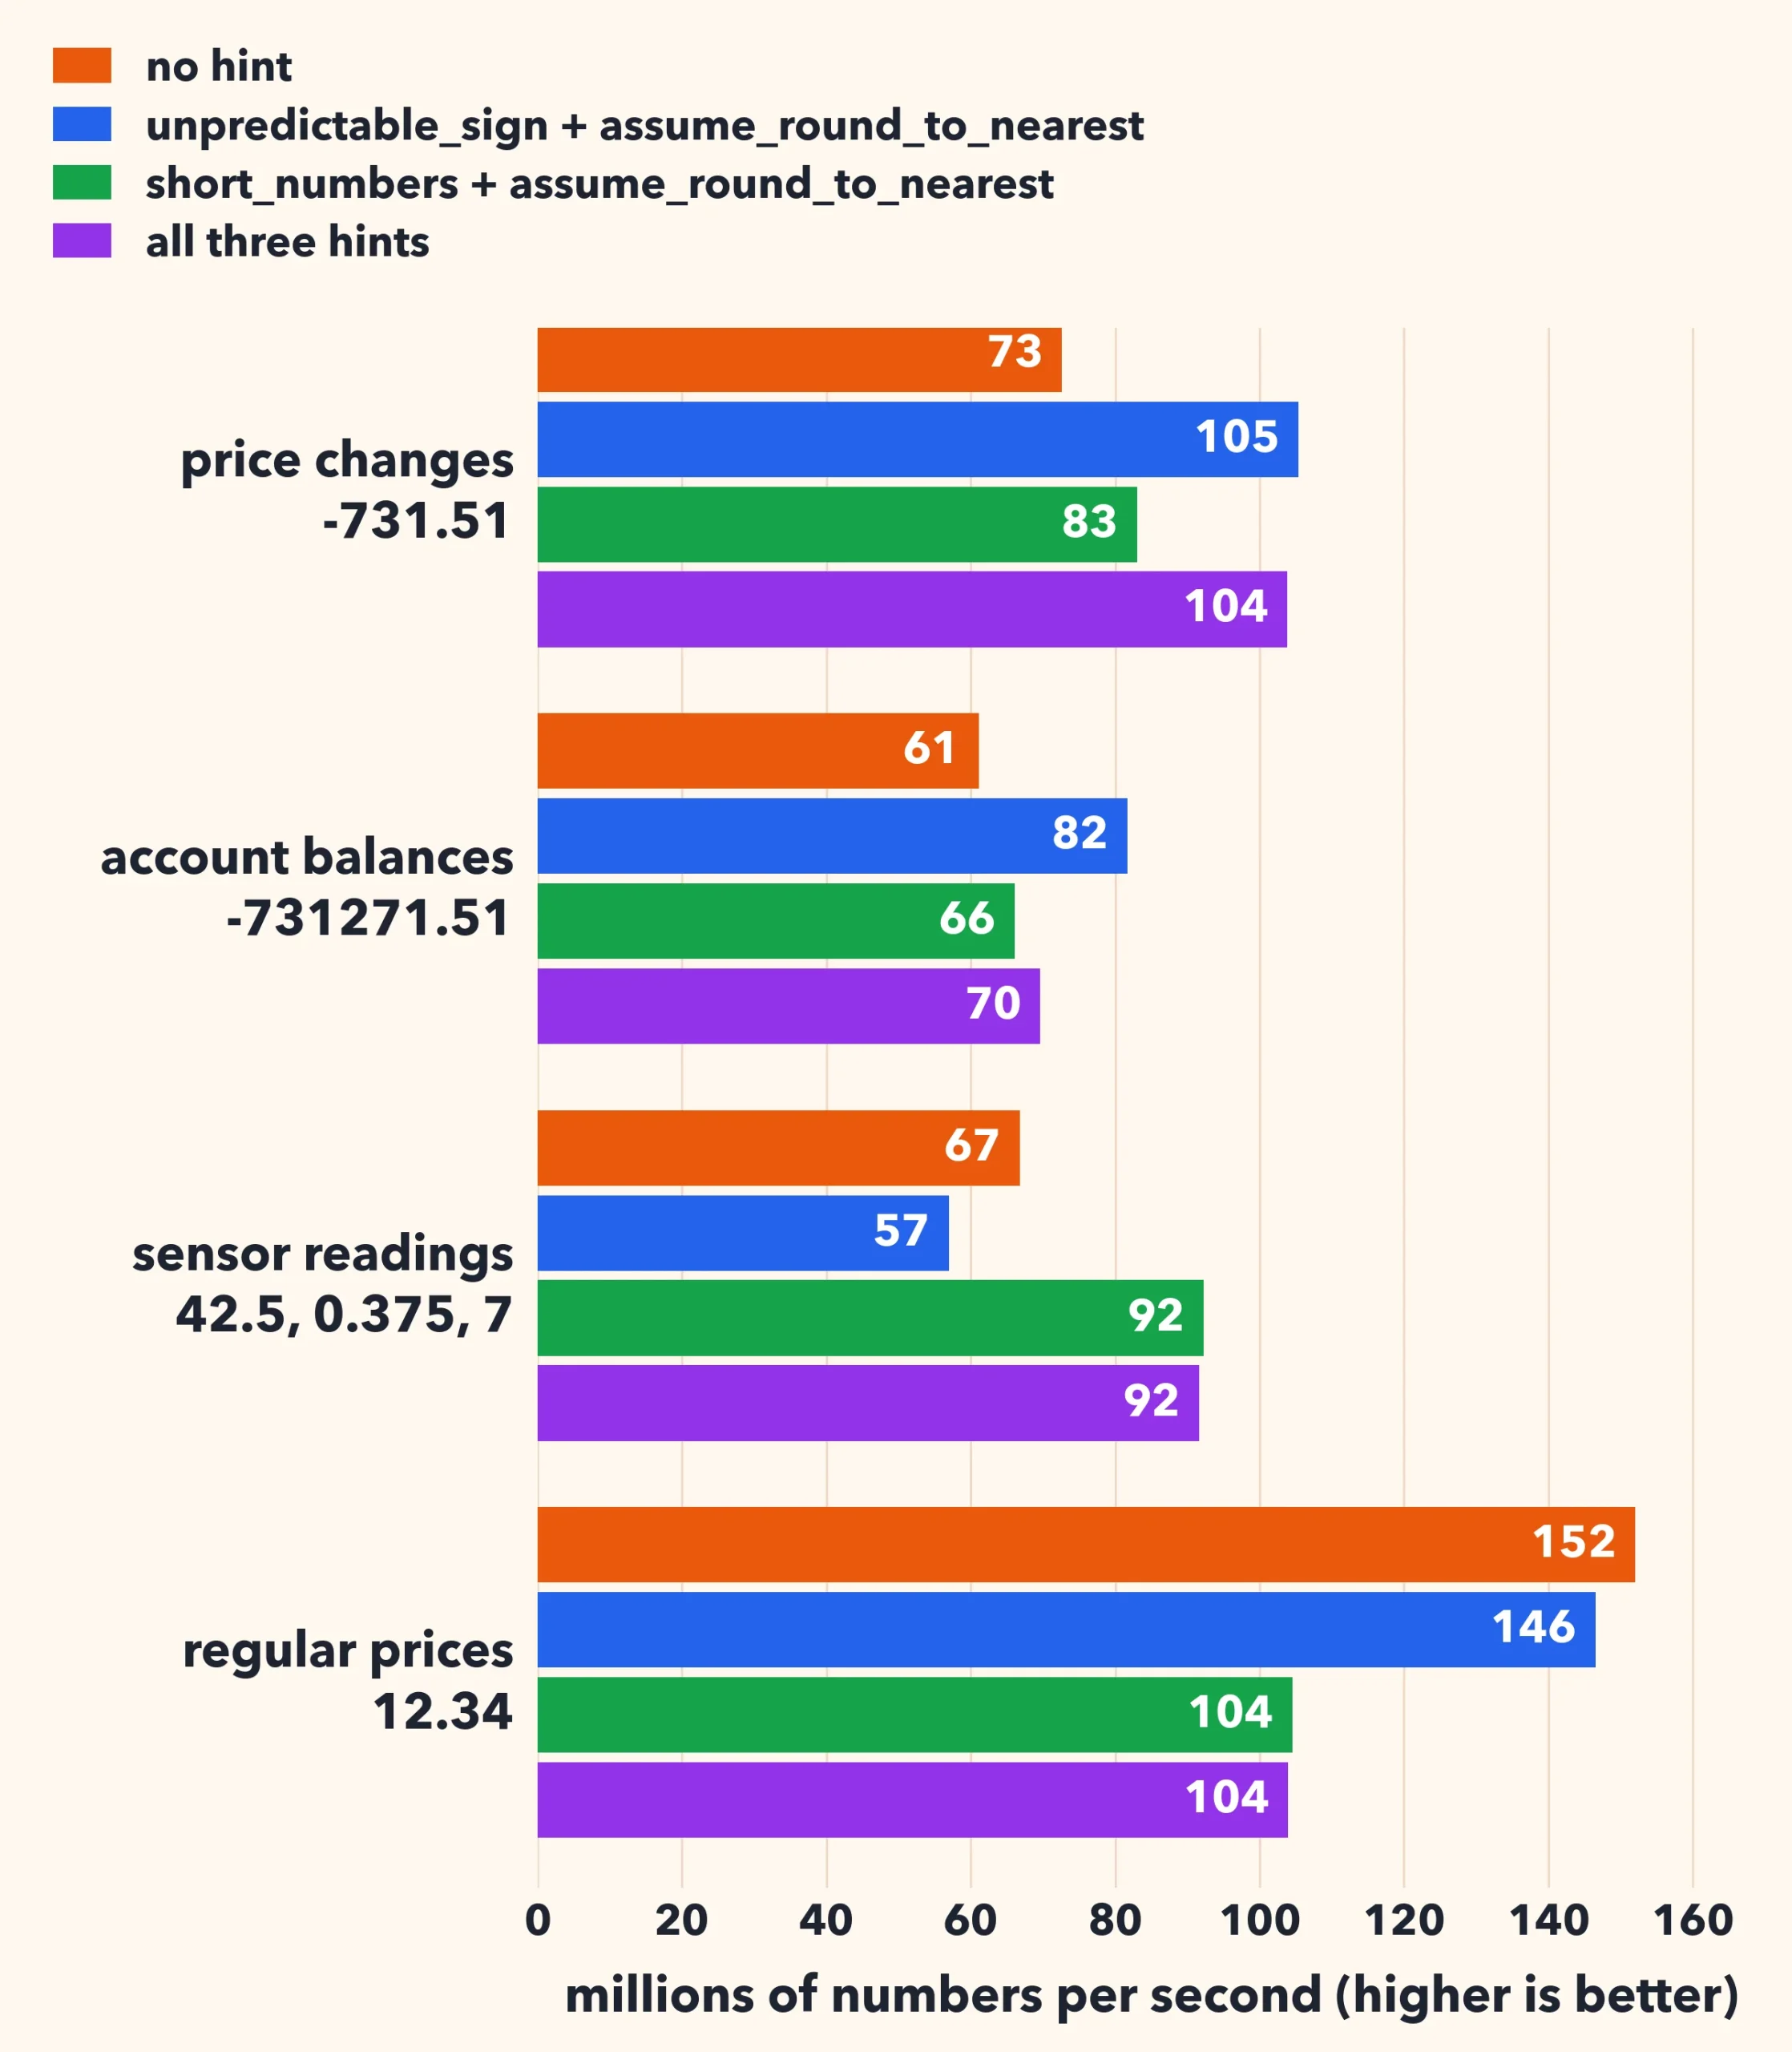
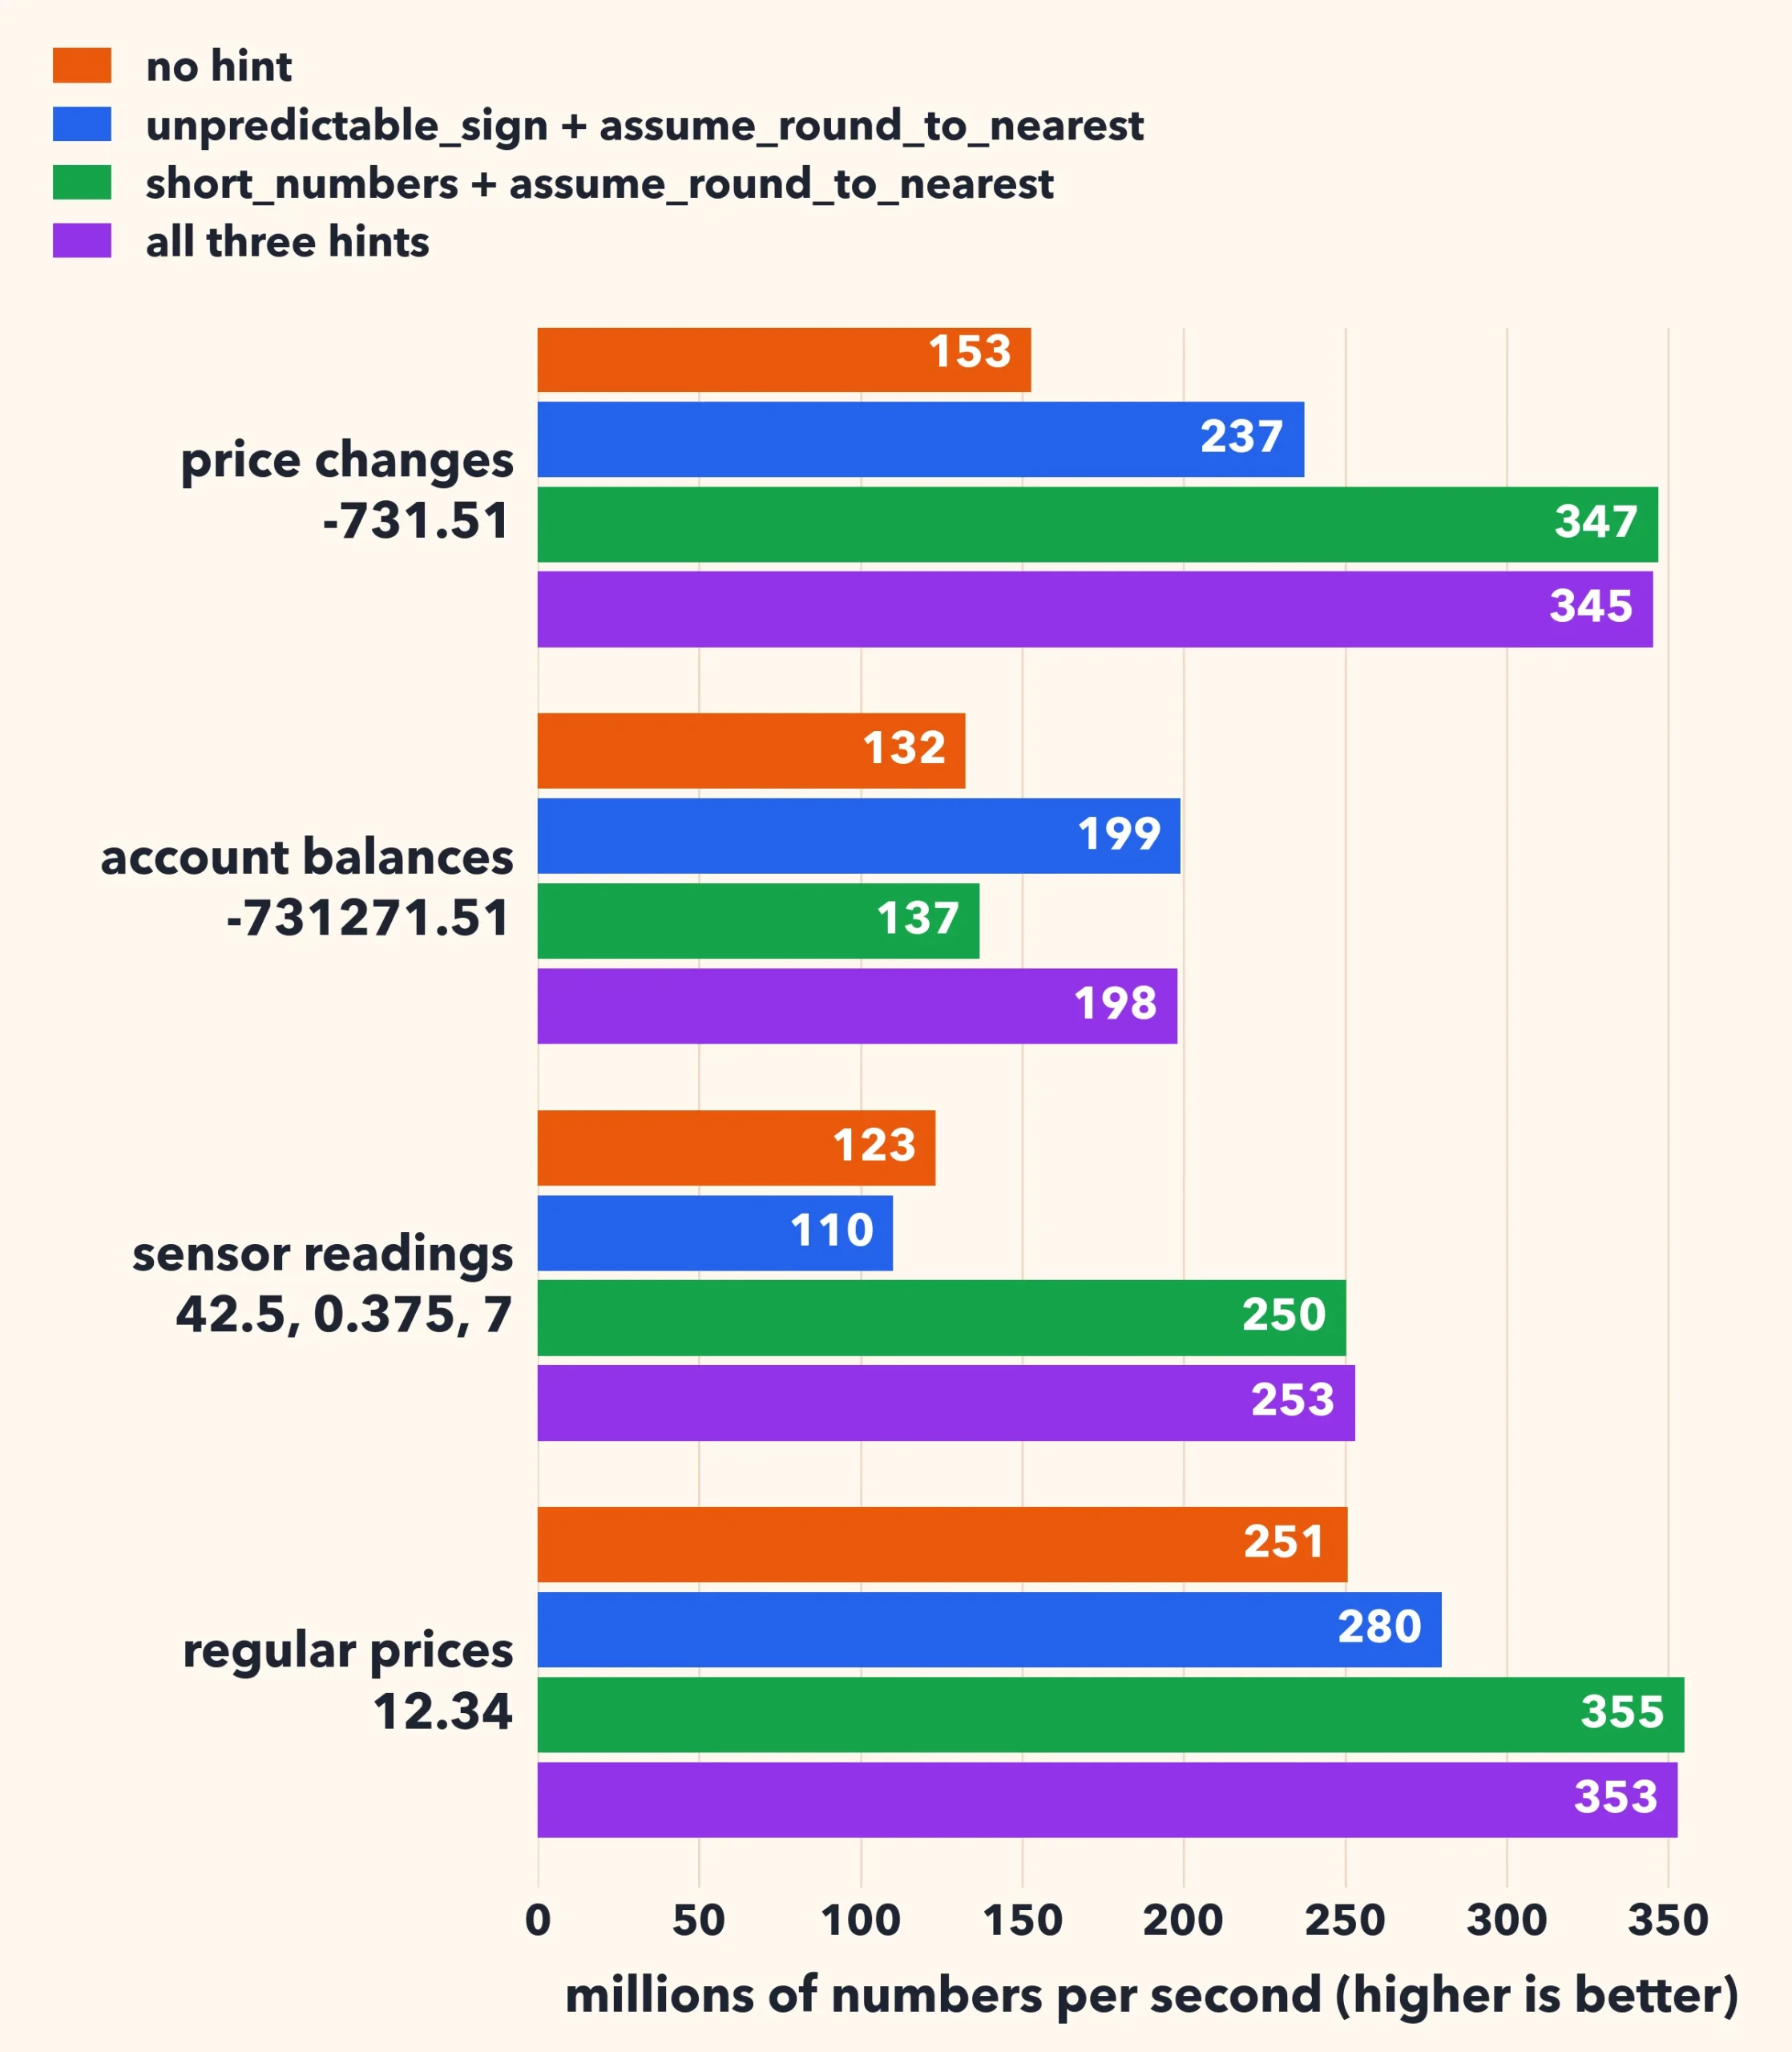
Each kind of data has its own best combination.
Price changes have random signs and short numbers. On the Intel processor, adding unpredictable_sign and assume_round_to_nearest goes from 73 to 105 million numbers per second. All three hints do as well (104 million), and they are best on the Apple processor, going from 153 to 345 million numbers per second: more than twice as fast. Without hints, the Intel processor mispredicts a branch on 60% of the numbers. With all three hints, the mispredictions disappear.
Account balances also have random signs, but the numbers are too long for short_numbers. Here unpredictable_sign with assume_round_to_nearest is the right choice: from 61 to 82 million numbers per second on the Intel processor, and from 132 to 199 million on the Apple processor. Adding short_numbers makes things worse on the Intel processor (70 million): the hint does not apply to these numbers, yet we pay for it.
Sensor readings have no sign, but their shapes vary. Here short_numbers is the key: from 67 to 92 million numbers per second on the Intel processor, and from 123 to 250 million on the Apple processor. The hint unpredictable_sign is harmful: there is no sign to predict, and the branch-free code is more work. On the Intel processor, it goes down to 57 million.
Regular prices are the easy case: all positive, always the same shape. The processor guesses everything right. On the Intel processor, the best choice is no hint at all (152 million numbers per second), and short_numbers makes things much slower (104 million). The Apple processor is different: short_numbers still helps, from 251 to 355 million numbers per second.
With Clang 21 on the Intel processor, the results are similar: the same hints win on the same data.
So the hints are not free. They trade branches, which are cheap when the processor guesses right, for more instructions. They pay off when the processor would guess wrong.
The hints are currently in a pull request.
2026-11-05 21:06:20
A store does not go straight into the cache. Waiting for that write would stall the processor. It sits in a store buffer, and a later load can take its bytes from that buffer. That is store forwarding.
Forwarding works when the load is the same size as the store, or smaller and completely inside it. It fails when the load is wider than the store, or when the two ranges only partly overlap. The load then waits until the store has reached the cache.
Here is an example in C. We have a buffer, that might have received data previously. Yet one byte is overwritten, and we try to load 8 bytes. It will typically cause a store forwarding failure.
uint64_t reload_byte(char *p, unsigned char v) {
    // Copy one byte from v into the buffer.
    memcpy(p, &v, 1);
    uint64_t w;
    // Copy eight bytes from the buffer into w.
    memcpy(&w, p, 8);
    return w;
}
A 4-byte store followed by an 8-byte load would cause the same issue. So would an 8-byte store followed by an 8-byte load that starts four bytes later: the ranges overlap.
You can sidestep the issue by working in a register, like the following example.
uint64_t update_byte(char *p, unsigned char v) {
    uint64_t x;
    // load from p to x
    memcpy(&x, p, 8);
    x = (x & ~0xffull) | v;
    // store the modified result to p
    memcpy(p, &x, 8);
    return x;
}
Further, if you store eight bytes and read those same eight back, a compiler might delete the reload.
I ran some experiments to see how many cycles various store/load operations take.
| What the iteration does | Xeon Gold 6548N | Xeon 6975P-C | EPYC 9R45 | Graviton 5 | Apple M4 Max |
|---|---|---|---|---|---|
| store 8, load 8, same address | 1 | 1 | 1 | 5 | 5 |
| store 8, load 4 at +4 | 5 | 5 | 7 | 6 | 5 |
| store 4, load 8 | 19 | 19 | 14 | 5 | 5 |
| store 4, then store 4, load 8 | 20 | 20 | 15 | 5 | 8 |
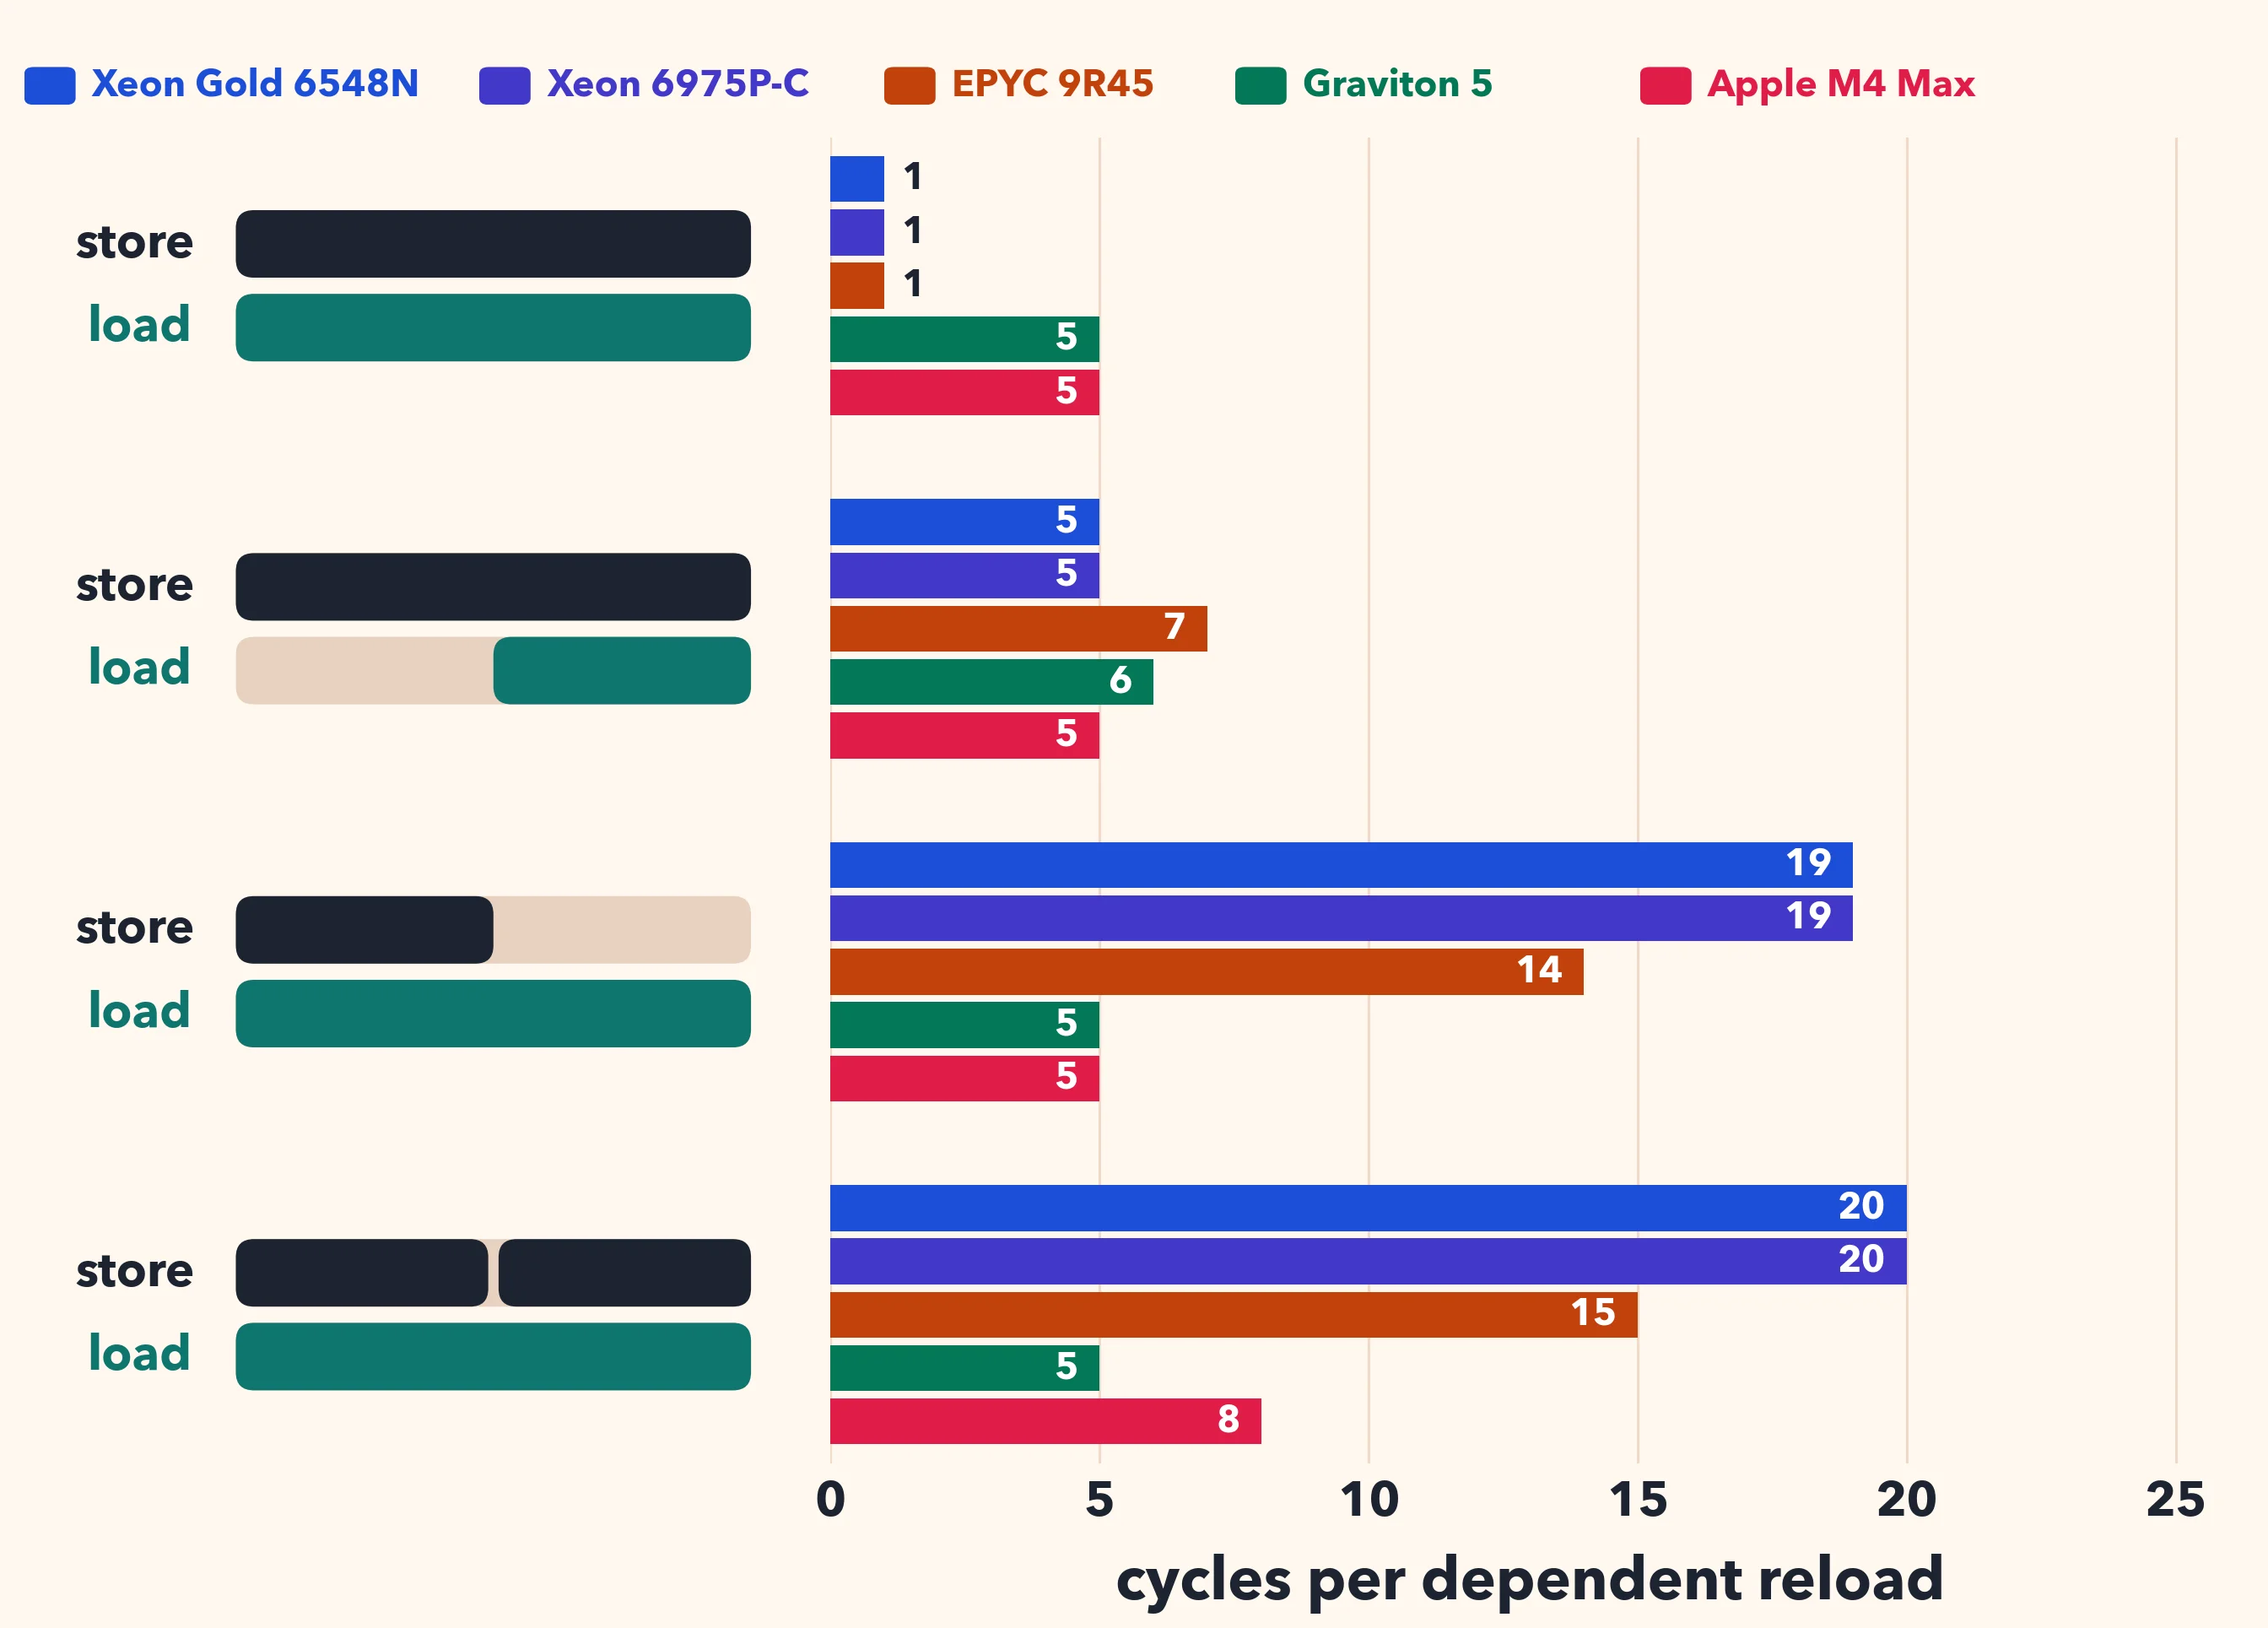
On the Xeons and the EPYC, a load that matches the store takes one cycle. A wider load takes 19 cycles on the Xeons and 14 on the EPYC.
On the M4 and Graviton 5, a wider load takes 5 cycles. Two stores bring the M4 to 8.


