

2026-09-27 15:20:08
One of my fundamental beliefs about the world is that Ramez Naam ought to blog more. Ramez is one of the world’s greatest futurists — he predicted the solar and battery revolutions long before these were widely understood. If you were reading Ramez in 2011, you were able to understand the future of both energy technology and climate change, long before other people did. His earlier book More than Human is still a great guide to the kind of biological enhancements that AI might make possible. Ramez is also an excellent science fiction author, having written a trilogy of novels in which nanotechnological telepathy is distributed as a party drug (I’m not sure if he actually expects that to happen, but it’s a very cool idea).
Unfortunately, although he does have a Substack (which you should absolutely follow), Ramez does not blog regularly. However, after having a lengthy private debate with him about Recursive Self-Improvement, I was able to prevail upon him to write up his thoughts for my blog.
To say that RSI is a big deal in the AI world would be a colossal understatement. Among AI researchers, entrepreneurs, and AI safety people, there’s a widespread belief that as AI gets better at improving itself, there will be a “fast takeoff” or “FOOM”, in which AI’s capabilities “take off” and create a technological Singularity. This event is a staple of science fiction, including works by my favorite sci-fi author, Vernor Vinge.
A lot of people in the industry believe that this moment is now close at hand, and are racing toward that prize:
But Ramez — normally among the most wide-eyed of techno-optimists — is highly skeptical that we’ll see anything like the “FOOM” of Vernor Vinge novels. In this lengthy, well-researched post, he explains his skepticism.
Personally, I’m agnostic. Ramez’s case necessarily rests on a lot of assumptions; although it’s cogently laid out, I think the real answer is that we’ll just have to wait and see whether the Singularity arrives. But even more fundamentally, I don’t know how much this debate matters in the practical sense — even without the kind of Singularity depicted in sci-fi novels, AI capabilities are improving so rapidly that they’re already superhuman in many respects, and soon will probably be strongly superhuman in most or all dimensions. The AI of 2040 is going to look godlike, whether or not it explodes into an actual god in 2027.
Still, it’s a very interesting argument, and Ramez’s thoughts on the future of technology are always worth listening to.
AI is already helping improve itself. The question is whether even fully autonomous recursive self-improvement (RSI) would cause a runaway intelligence explosion.
The theory is that each generation of AI could build a better successor, faster than the last generation did. That could lead to a “fast takeoff,” with capabilities surging to artificial superintelligence (ASI) in a year, months, or even days.
Here’s my take: Given our best current data, the AI self-improvement loop would need to be roughly 5–10× stronger to sustain itself, let alone run away. I’ll explain this math in section 8. I expect incredibly rapid AI progress by the standards of nearly any other technology. But the evidence we have doesn’t suggest a sudden explosion to incomprehensible superintelligence anytime soon.
I could be wrong. Forecasters have repeatedly underestimated AI progress! I could well be next. One thing that’s clear is that we need better data. For now, let’s work with what we can measure, and stay open to breakthroughs that could change the picture.
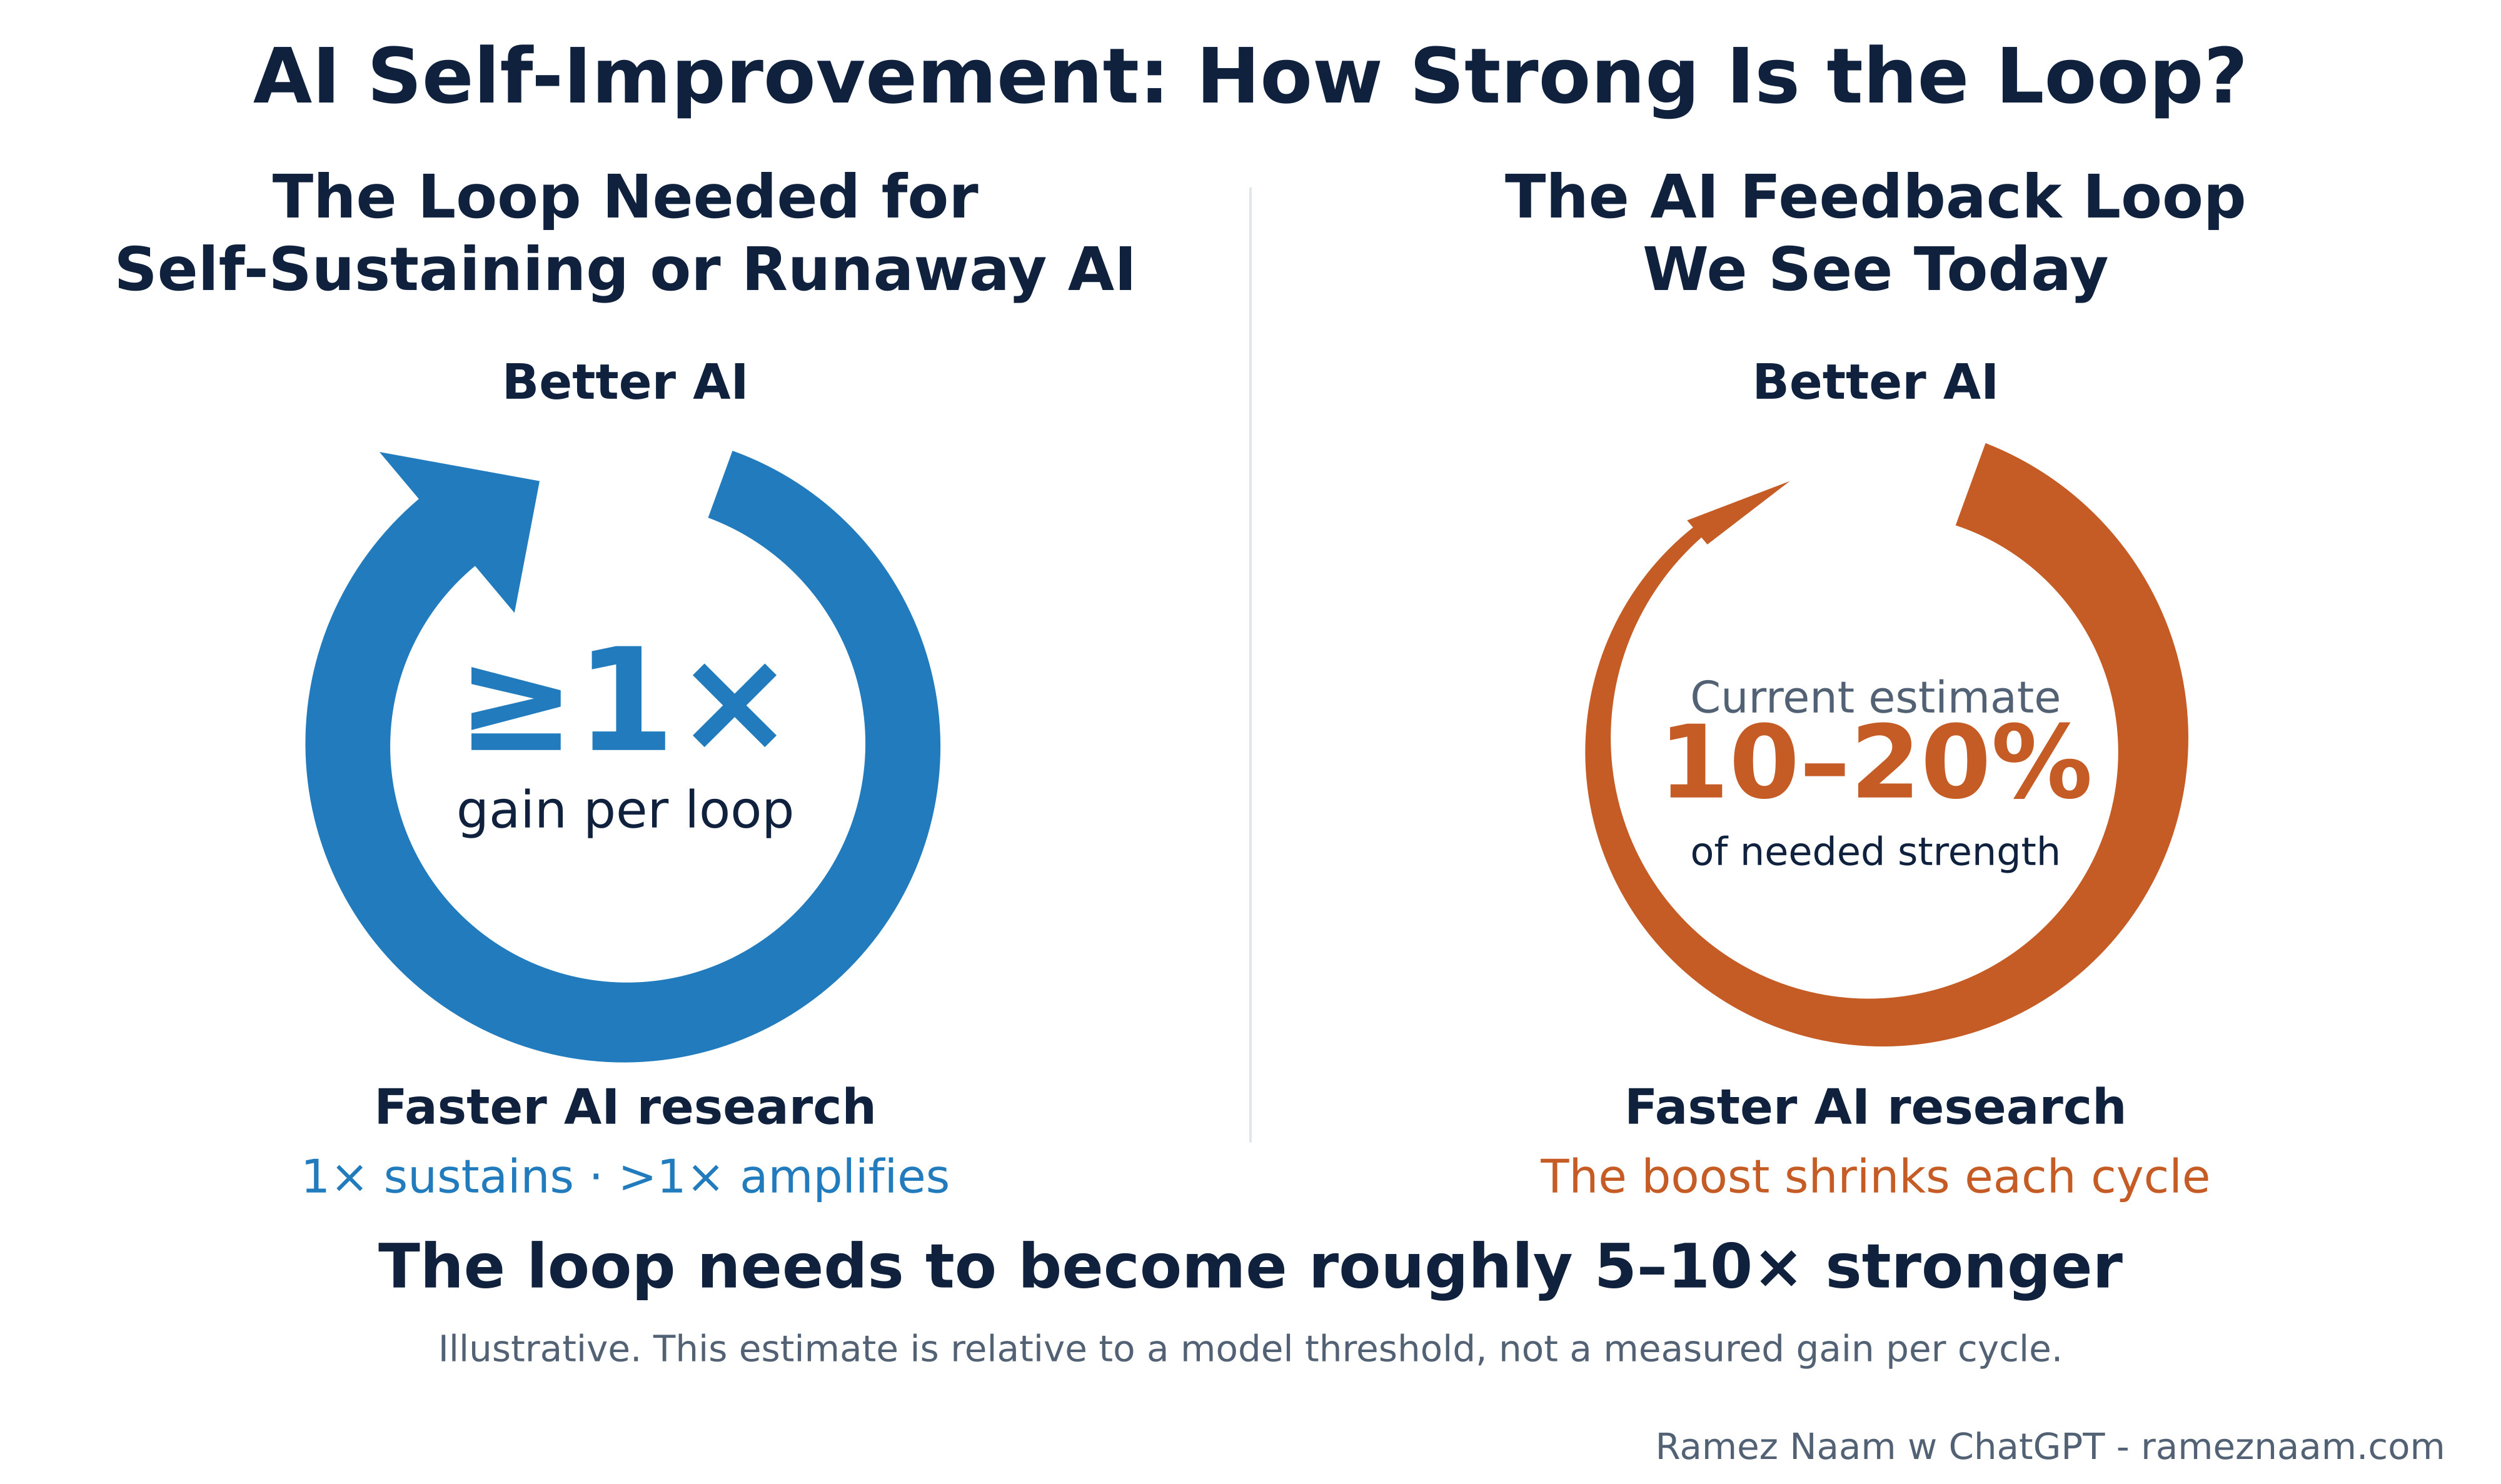
Figure 1. How strong is the self-improvement loop? Model.
Here’s the case, with links to each part:
Key charts: The feedback loop · Measured vs. forecast progress · Diminishing returns
People use “recursive self-improvement” to mean everything from AI boosting the productivity of human researchers to AI bootstrapping itself to incomprehensible intelligence. Here’s my taxonomy: productivity gains (Type 1), increasing autonomy while still facing diminishing returns (Types 2–4), and a runaway loop to superintelligence if we can ever find accelerating returns (Type 5).
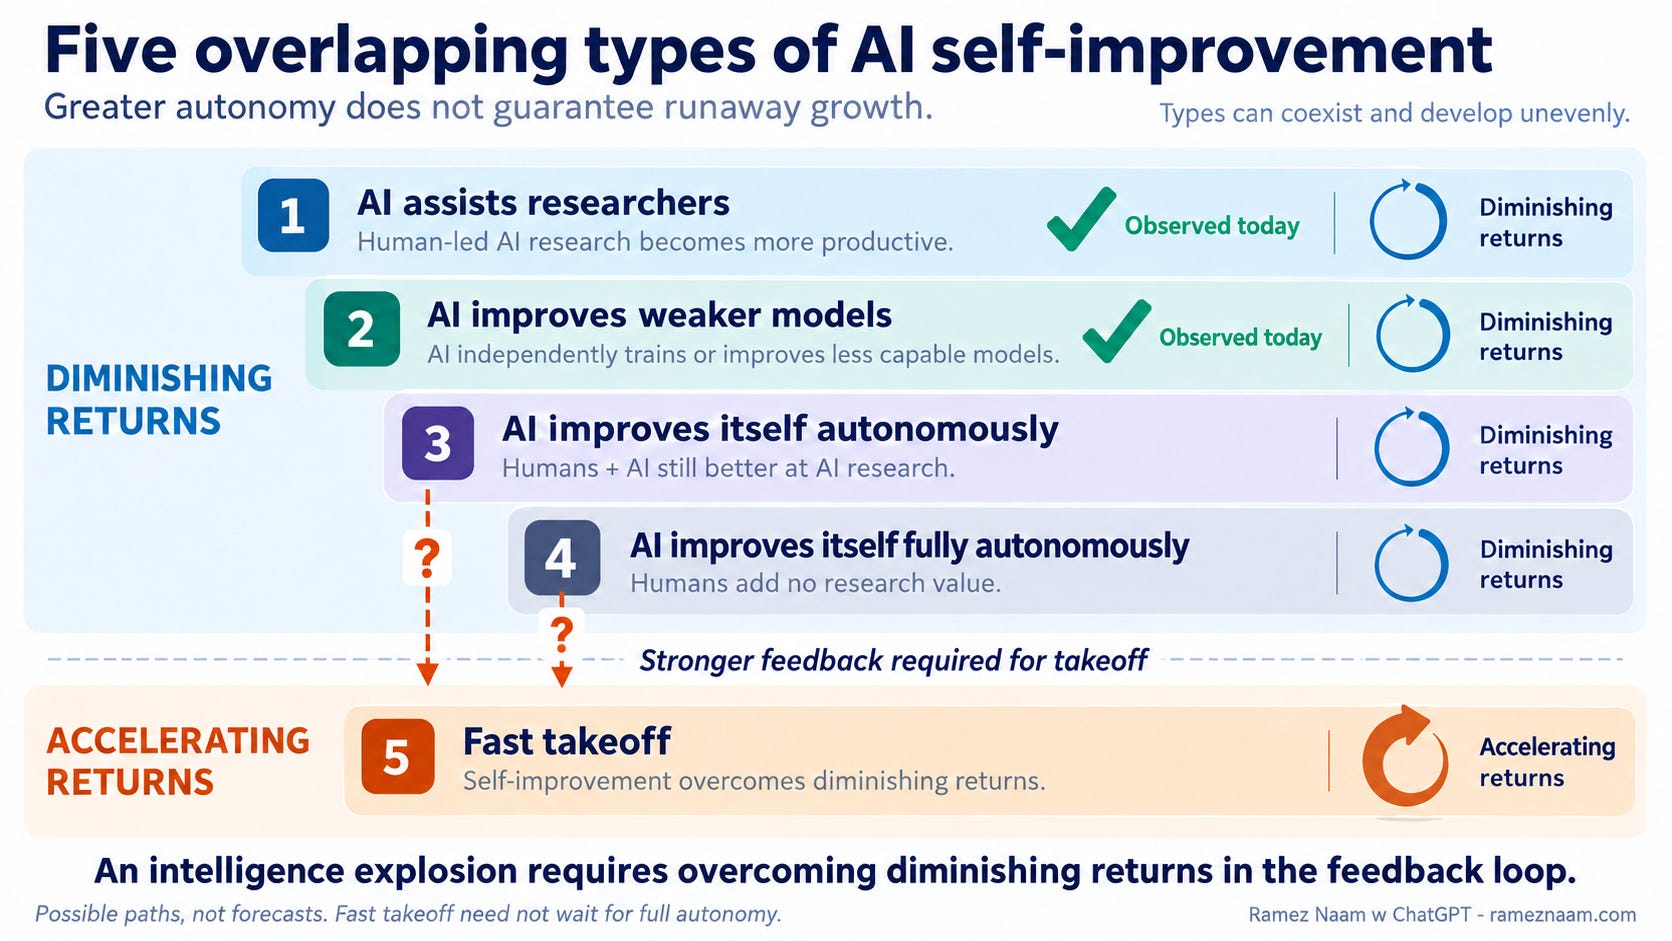
Figure 2. Five types of AI self-improvement.
We’ve made real progress on Types 1 and 2: AI helps both researchers and engineers inside of AI companies, and powerful models can train and improve smaller ones. We haven’t yet seen clear evidence for Type 3 (though Alibaba just made some strong claims) and certainly not for Type 4. I do expect autonomous self-improvement to arrive at some point. I’m skeptical that it leads to Type 5 - runaway super-intelligence - without a major conceptual breakthrough.
There are plenty of other definitions of RSI, which can be a bit confusing. Weco’s four levels of RSI are close to mine. For a broader tour of all the things people mean when they say ‘RSI’, read Tom Cunningham’s comprehensive guide.
I do expect narrow superintelligence in highly verifiable domains. Think chess, Go, formal math, parts of computer science and coding. Highly verifiable domains are largely formal and structured types of work where machines can generate unlimited training data, with perfect or near-perfect verification of correct vs incorrect, and do so entirely in software without waiting on the physical world or humans. That’s an ideal setting for AI learning.
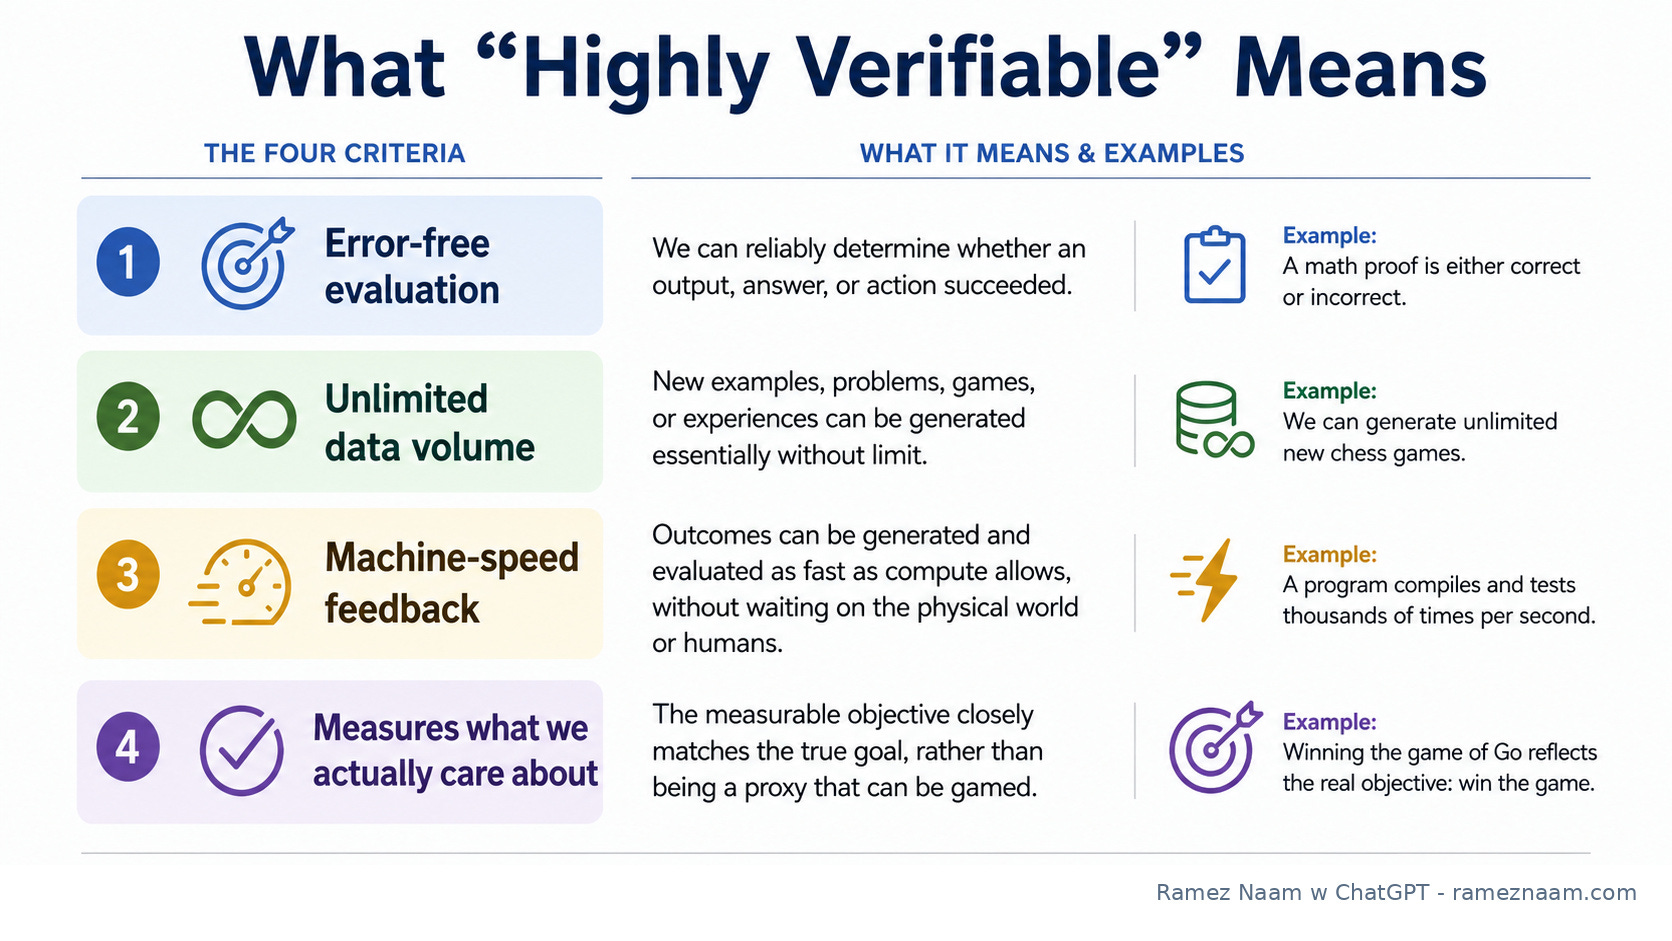
Figure 3. What makes a domain highly verifiable?
In fact, we already have narrow superintelligence in game plang. We’re seeing it happen now in the most formal parts of math, in particular in proofs and in finding counter-examples that disprove major conjectures. For example, OpenAI recently reported an AI-generated proof resolving the Navier–Stokes existence and smoothness problem. Parts of software development are also extremely verifiable, while others are a bit less crisp (such as understanding what humans want).
That isn’t the same as broad superintelligence. Even our most powerful models need far more training data than humans, struggle to learn reliably from ongoing experience, and fail in surprising ways on tasks people find straightforward. Superhuman math doesn’t automatically mean superhuman judgment everywhere else.
Benchmarks and forecasts suggest that AI models should reliably succeed at coding tasks that take humans hours, without human help. The real world is messier. OpenAI’s internal data shows much shorter stretches of autonomous work on research tasks.
In its Research Acceleration / RSI report, OpenAI showed how often its models completed tasks with and without human help, grouped by how long a human would need to do the work.
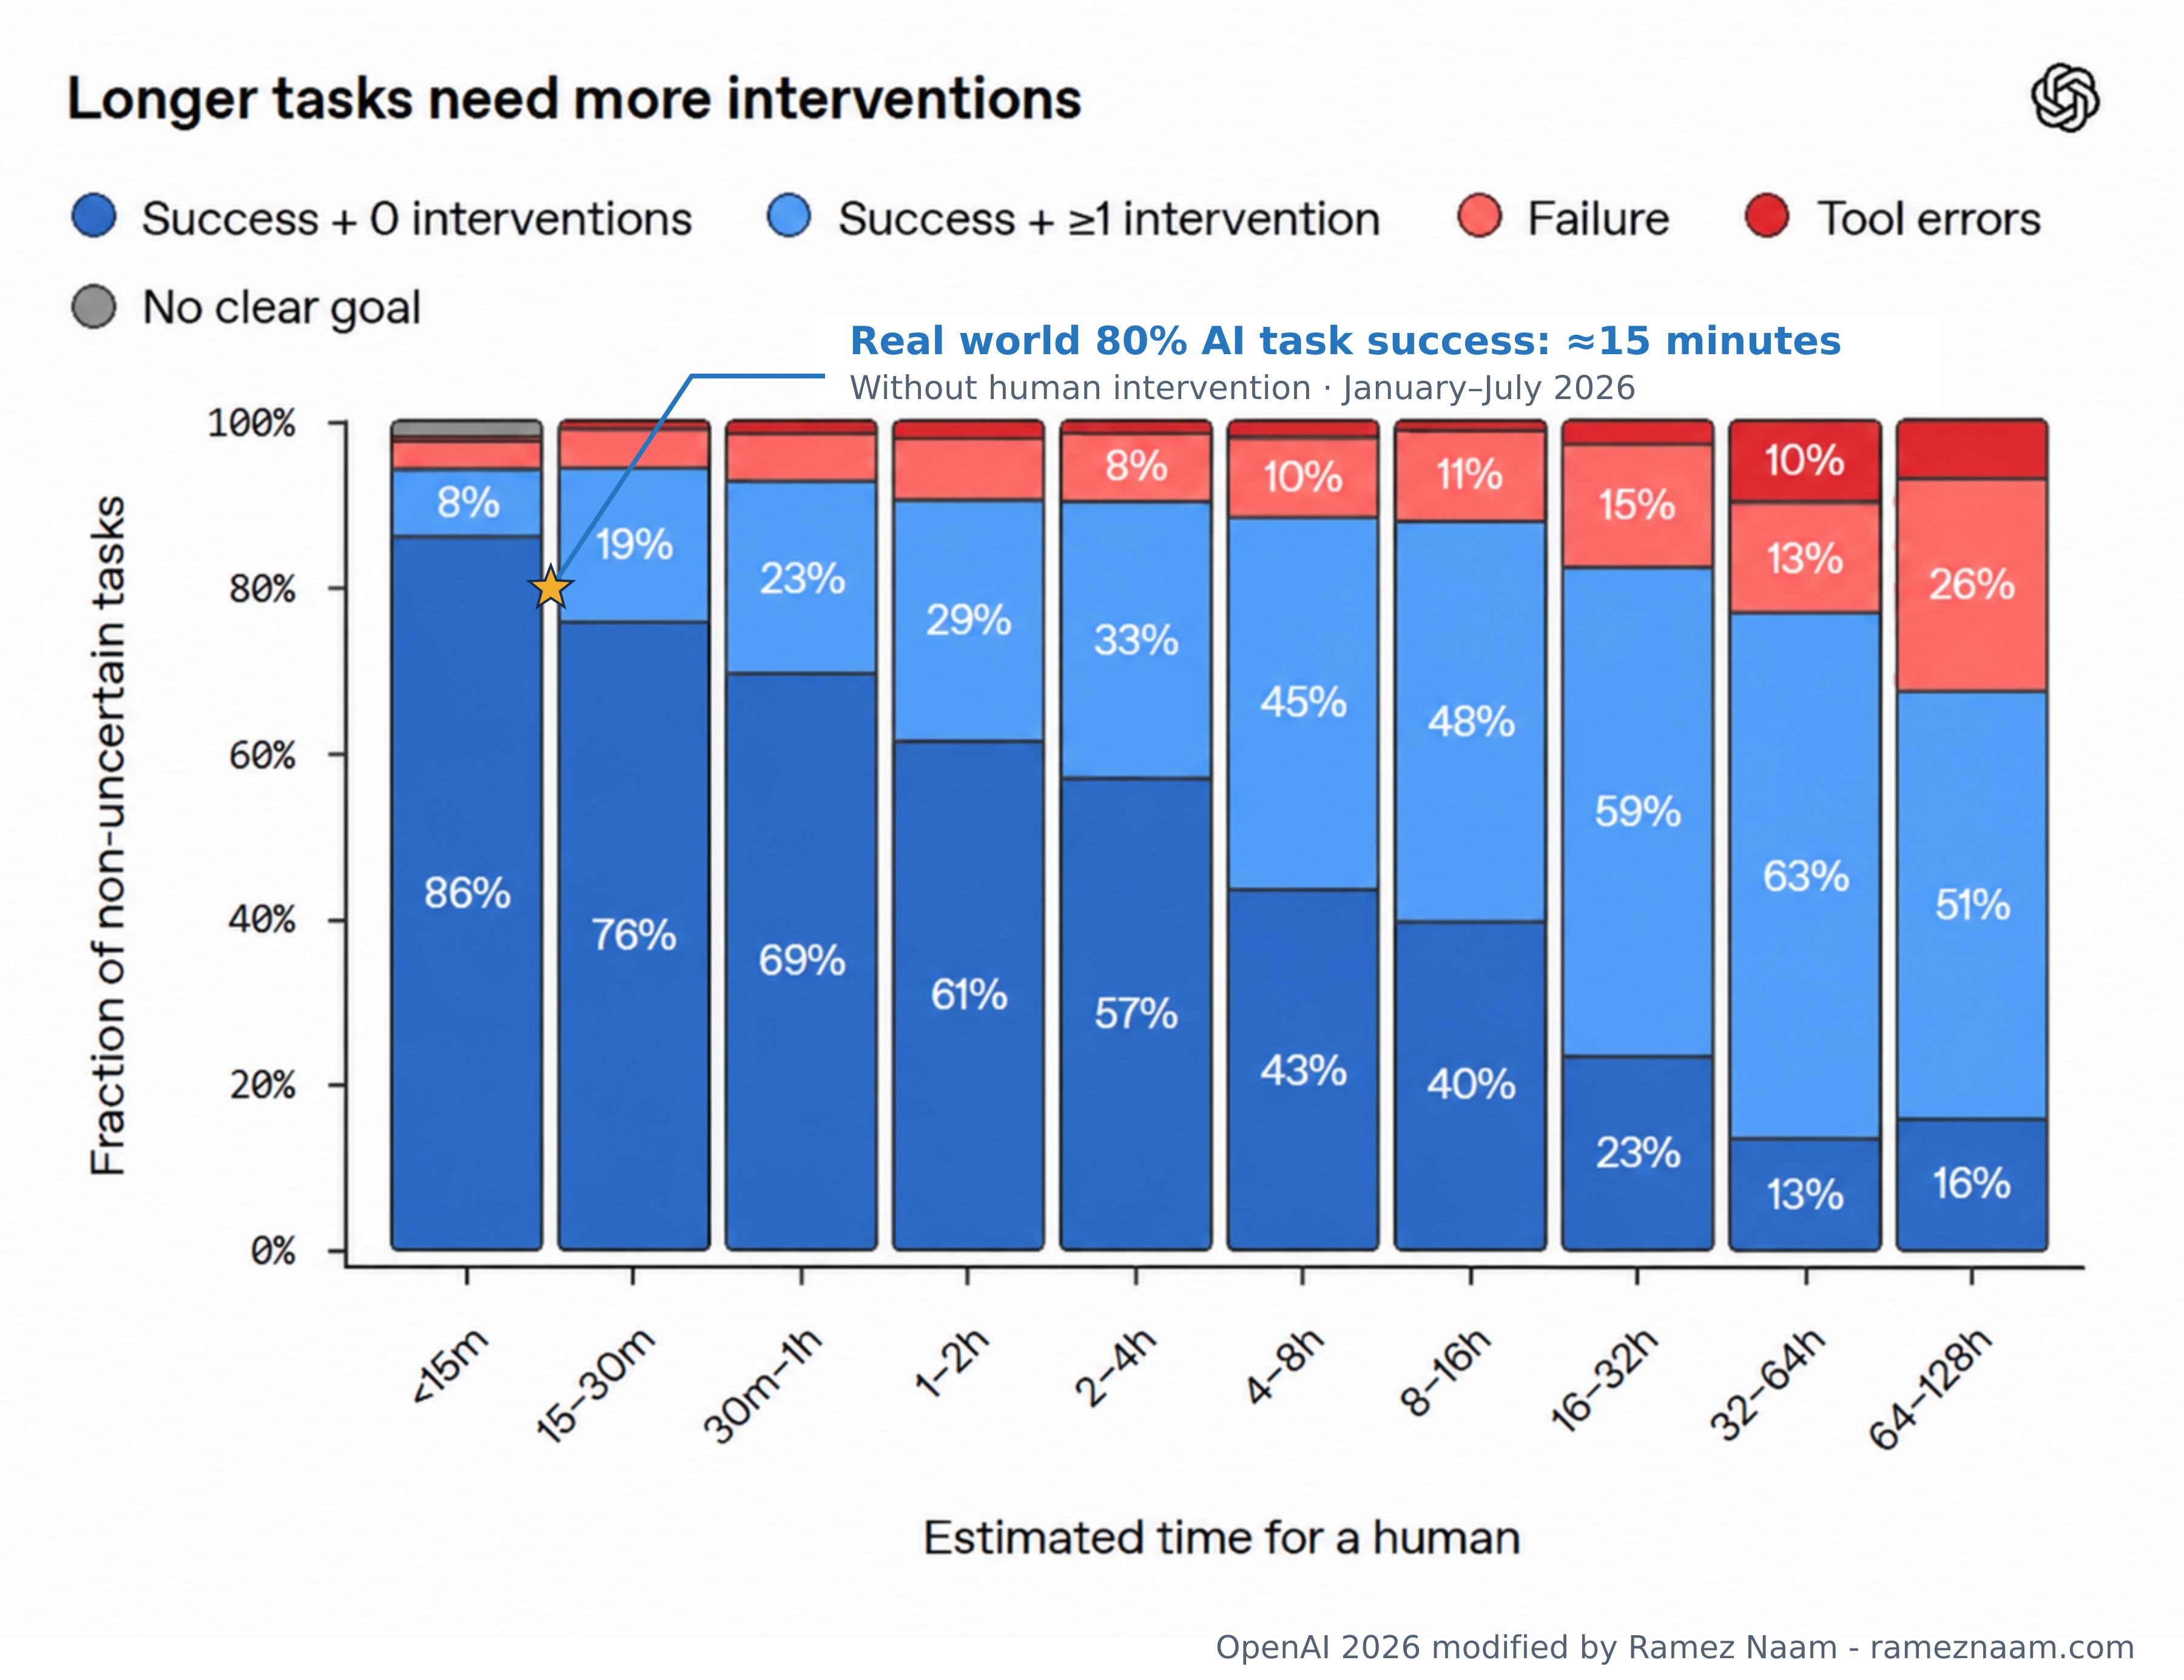
Figure 4. OpenAI’s internal research tasks. Source.
Even on tasks that would take a human less than 15 minutes, OpenAI’s models succeeded without human intervention only 86% of the time. The estimated task length at 80% success was roughly 15 minutes over the first seven months of the year. July’s results were similar to the whole period average.
Fully autonomous RSI would require an AI to string together a great many research tasks reliably, stretching out over complex tasks that humans need weeks or months to accomplish. OpenAI’s data suggests that we aren’t close.
Anthropic also released a graph showing how Claude accelerates AI research. It shows that internal AI models collaborate on or even lead more than 90% of R&D tasks. That’s objectively impressive. At the same time, the graph reports zero cases of AI autonomously completing AI R&D tasks.
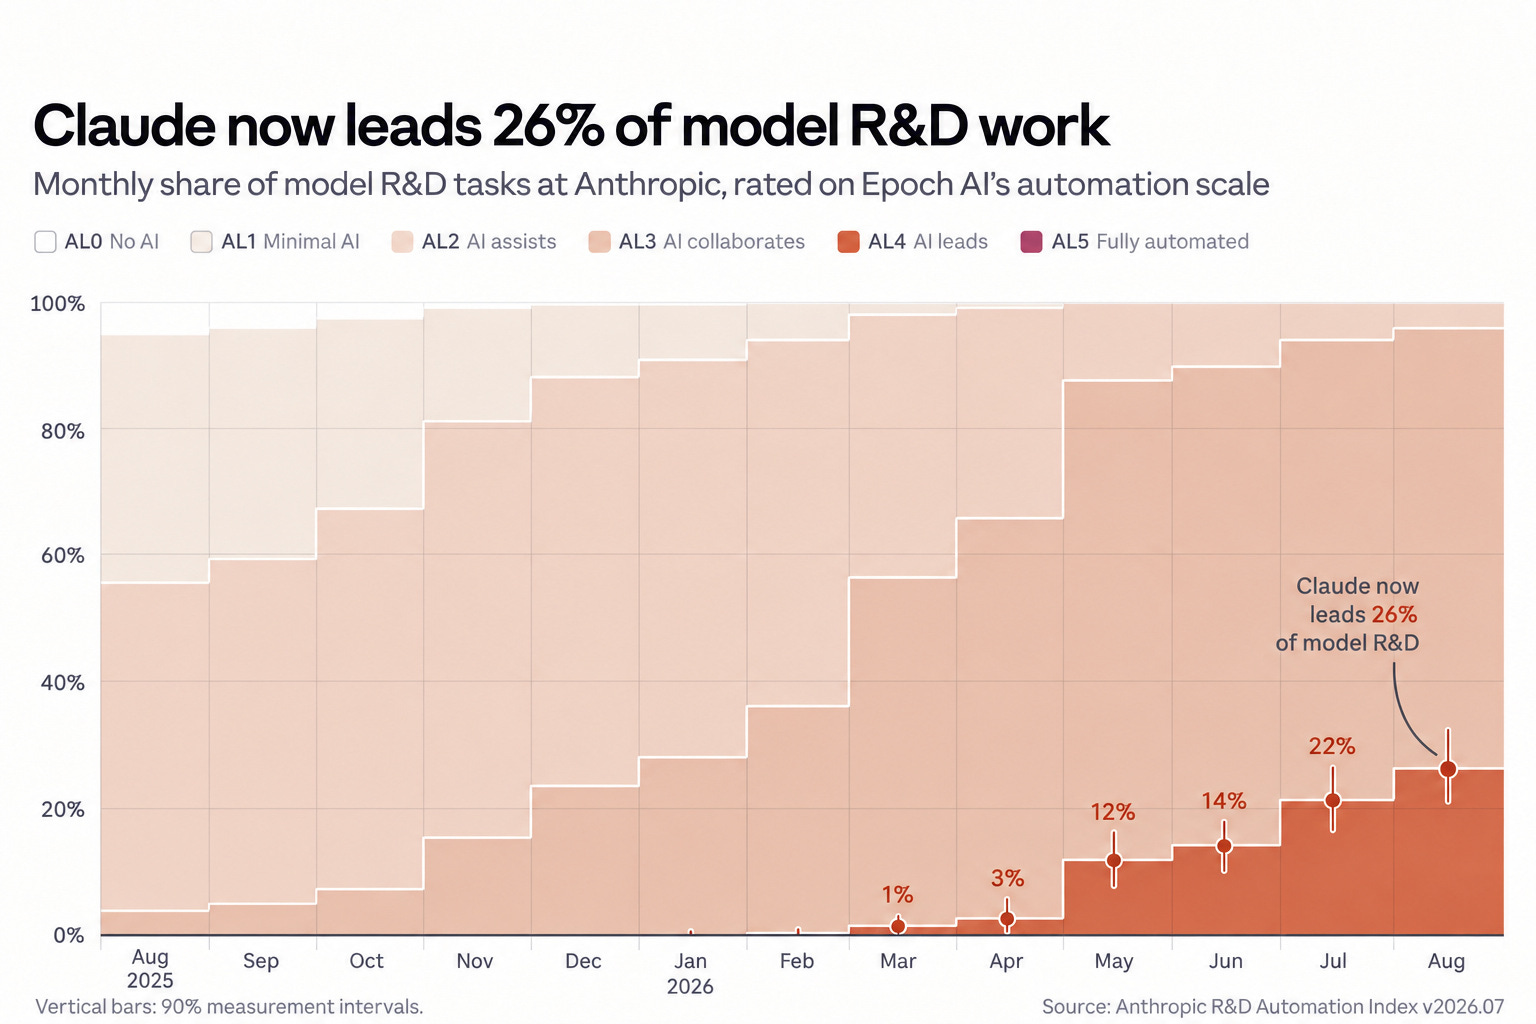
Figure 5. Claude’s role in internal AI R&D. Source.
These are incredible tools. But they still need skilled people to set direction and get them back on track.
For years, METR has been publishing a chart showing what length of coding task (measured in human hours to complete) best-in-class AI models can achieve. It’s been called the most important graph in AI. METR’s Mythos Preview evaluation estimated that the model could succeed at 80% of coding tasks that took humans three hours.
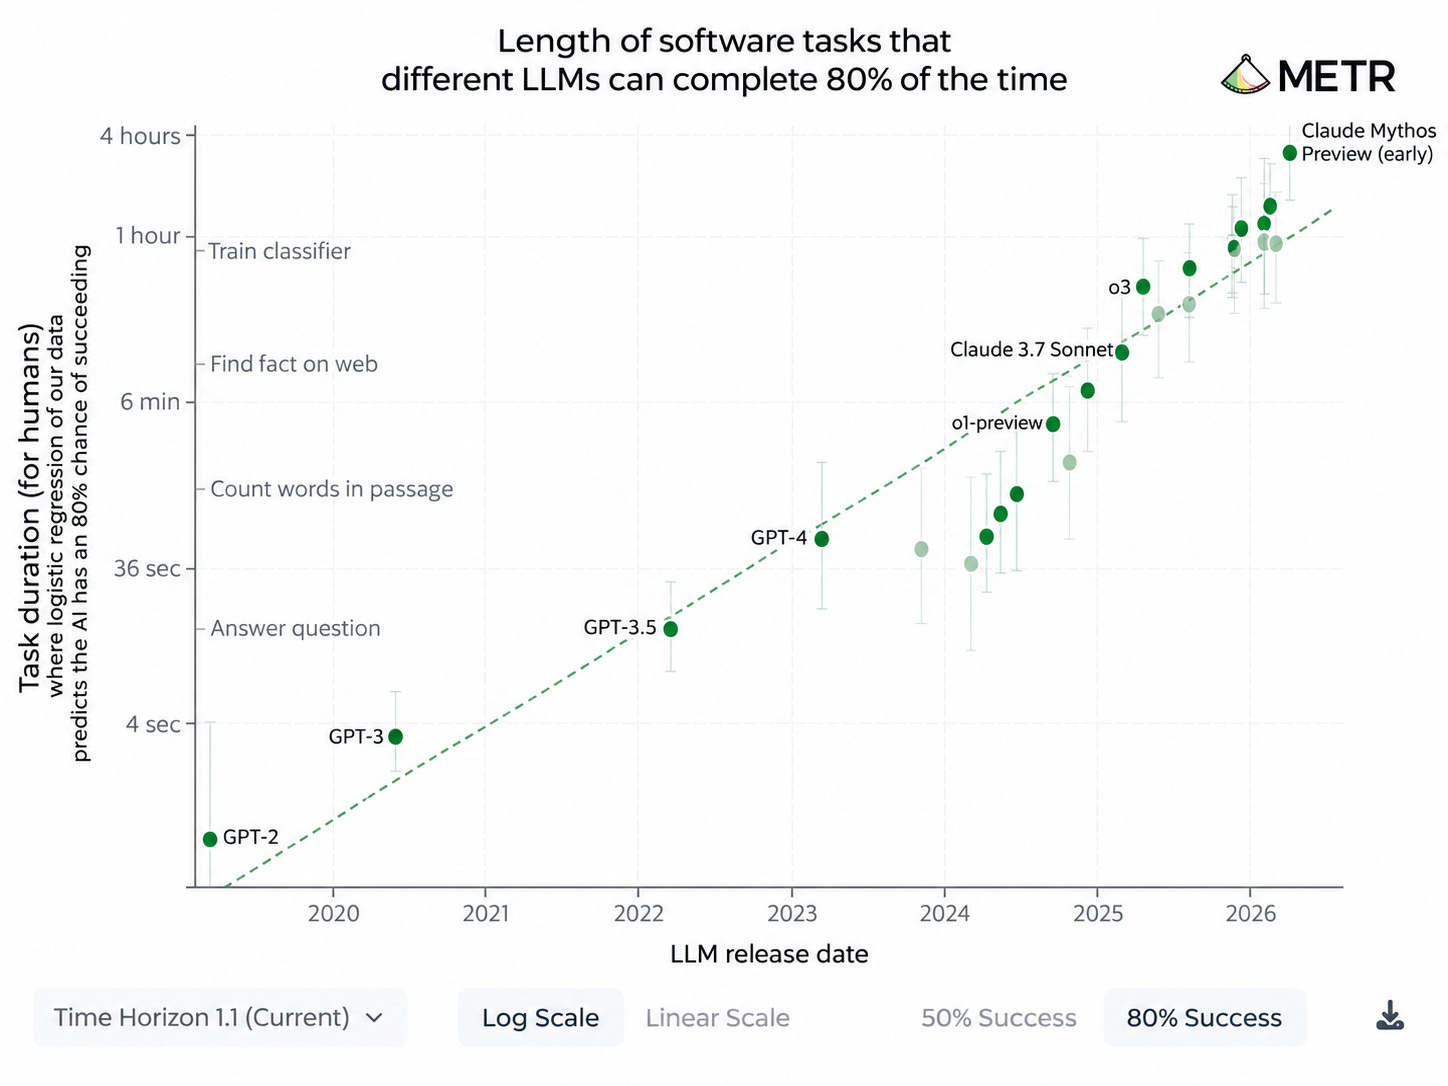
Figure 6. METR’s 80% task horizons. Source.
Epoch’s own rule of thumb is that every five additional points of ECI (their overall benchmark of AI capability) correspond to roughly a doubling of METR’s task horizon. Using that formula, we’d expect GPT 5.6 Sol and GPT 6 Astra to be 80% successful at completing tasks of around 4 hours and 11 hours of human length, respectively.
Another estimate (a forecast) of AI task length comes from the AI 2027 scenario, which estimated that by July 2026, frontier AIs would be 80% successful accomplishing tasks of around 11 hours. Fairly similar.
The AI 2027 Tracker charts all of these.
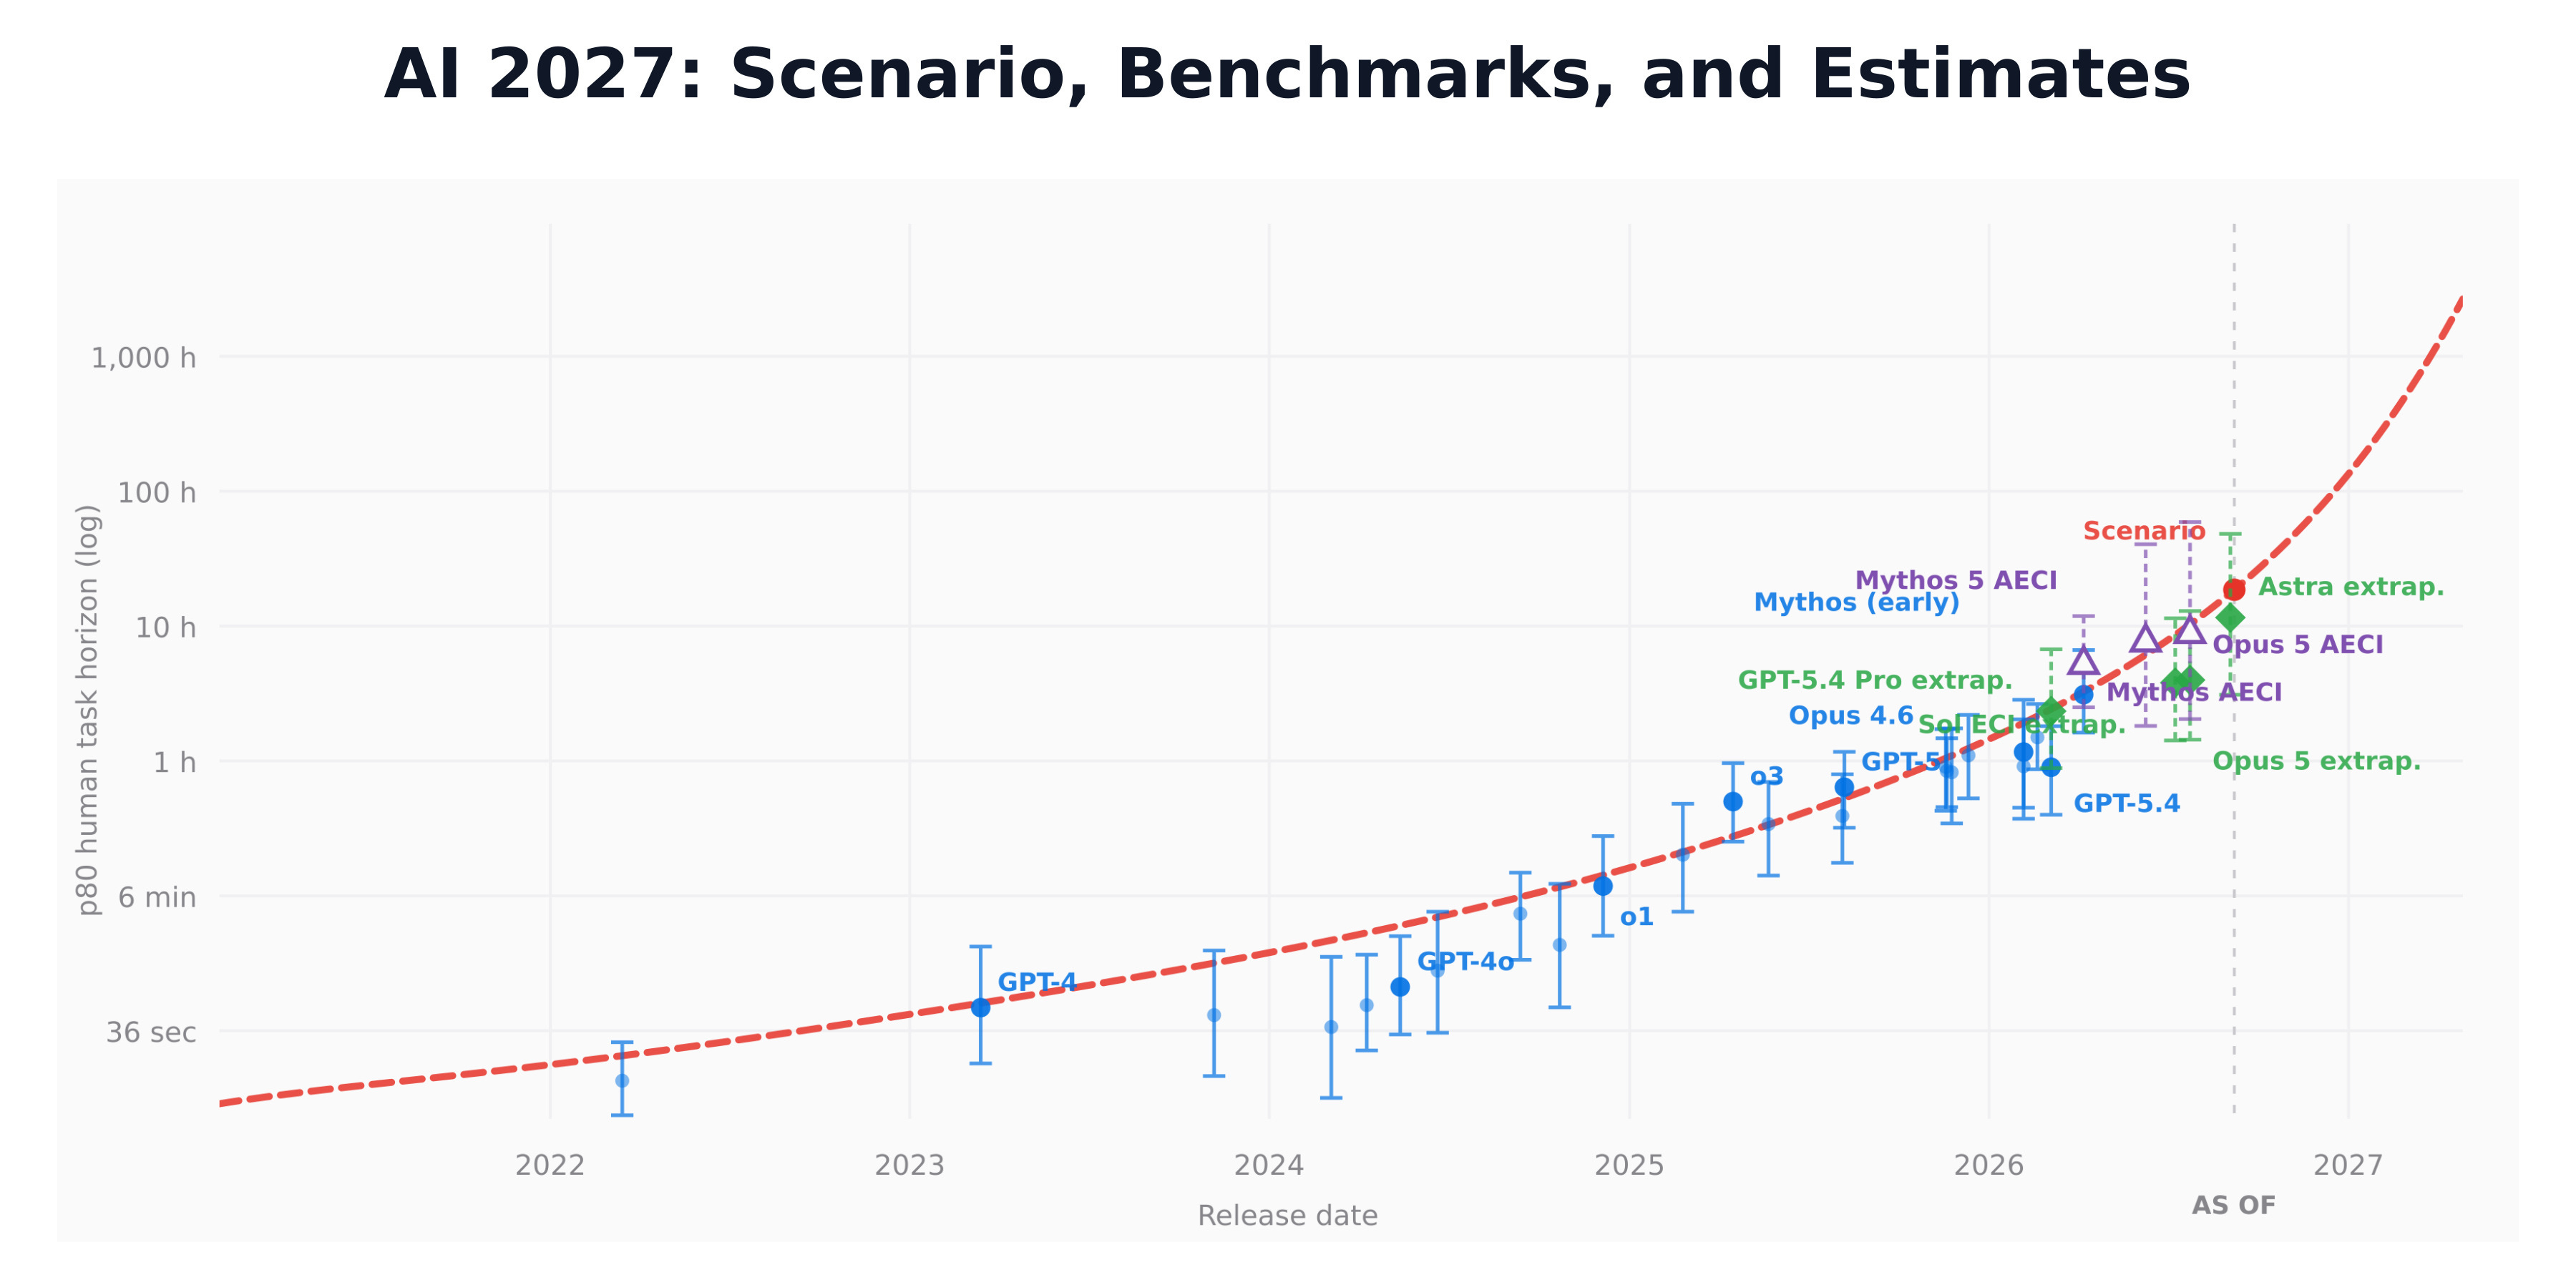
Figure 7. The AI 2027 Tracker. Source.
Inside OpenAI, though, the July research-task horizon at 80% success was roughly 15 minutes.
Here’s the gap:
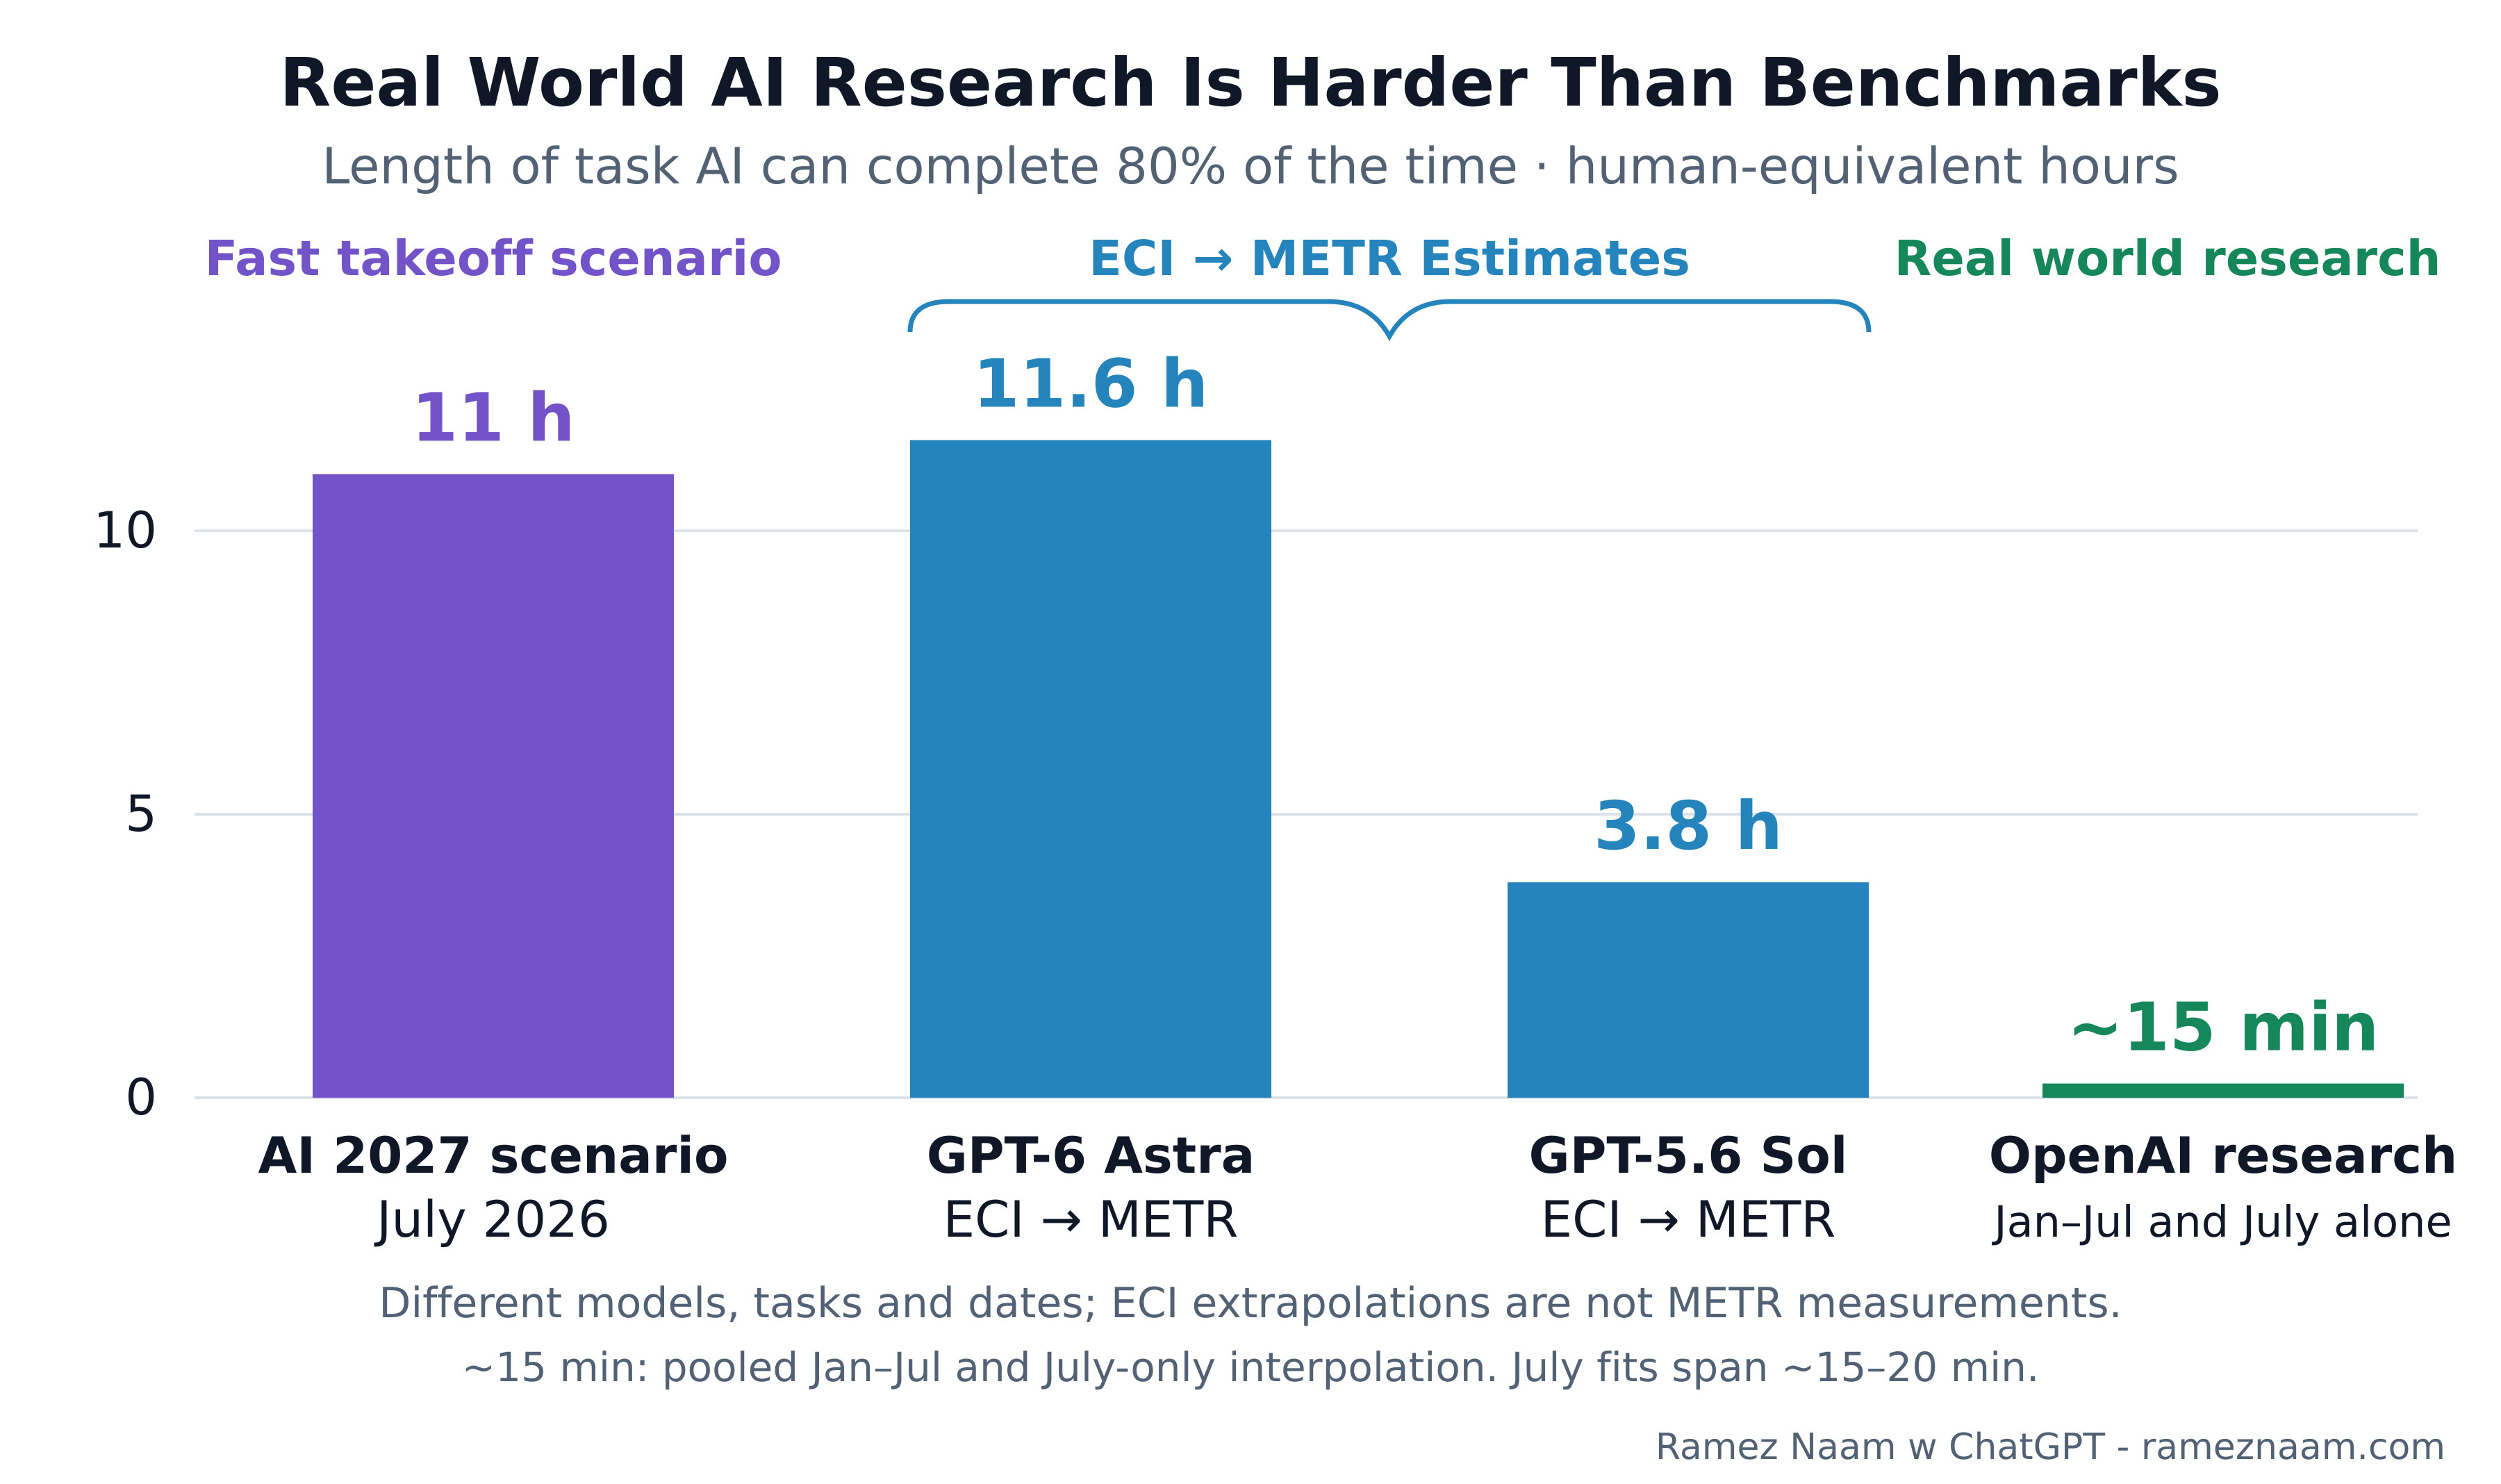
Figure 8. Forecasts, benchmarks, and real AI research. Tracker · OpenAI.
A four-hour benchmark horizon is about 16 times longer than OpenAI’s research horizon. AI 2027’s 11-hour forecast is about 44 times longer. Of course, the tasks being performed by researchers at OpenAI aren’t the same as those in the METR benchmark. So we should expect some discrepancy. This, however, goes well beyond that.
Actual AI research at OpenAI is an order of magnitude or more harder than metrics, benchmarks, or forecasts suggest. That should make us wary of relying too much on benchmarks, or of saying that future scenarios like AI 2027 are ‘on track.’ The authors of the related AI 2040 project still describe AI 2027 as roughly the future they expect, and say reality is tracking closer to it than even they expected. That’s not what we see from within OpenAI. This isn’t an apples-to-apples comparison, but the difference is remarkable. AI 2027 appears to be substantially over-optimistic in this regard.
In January of this year, Nathan Witkin made a case that the METR graph was exaggerating progress. The real world data suggests that at least some of his critiques were correct. The gap between benchmarks, forecasts, and data gleaned from actual use of AI should influence our expectations about the future.
OpenAI’s report also shows impressive increases in AI token usage, in compute spend per researcher, and in lines of code written. But these aren’t results. They’re intermediate measures. How much progress do they actually drive?
Researchers used 124x more tokens per person. Engineers shipped roughly 7x as many lines of code per person. Researchers ran 1.6x as many experiments per researcher vs OpenAI’s 2025 whole year average.
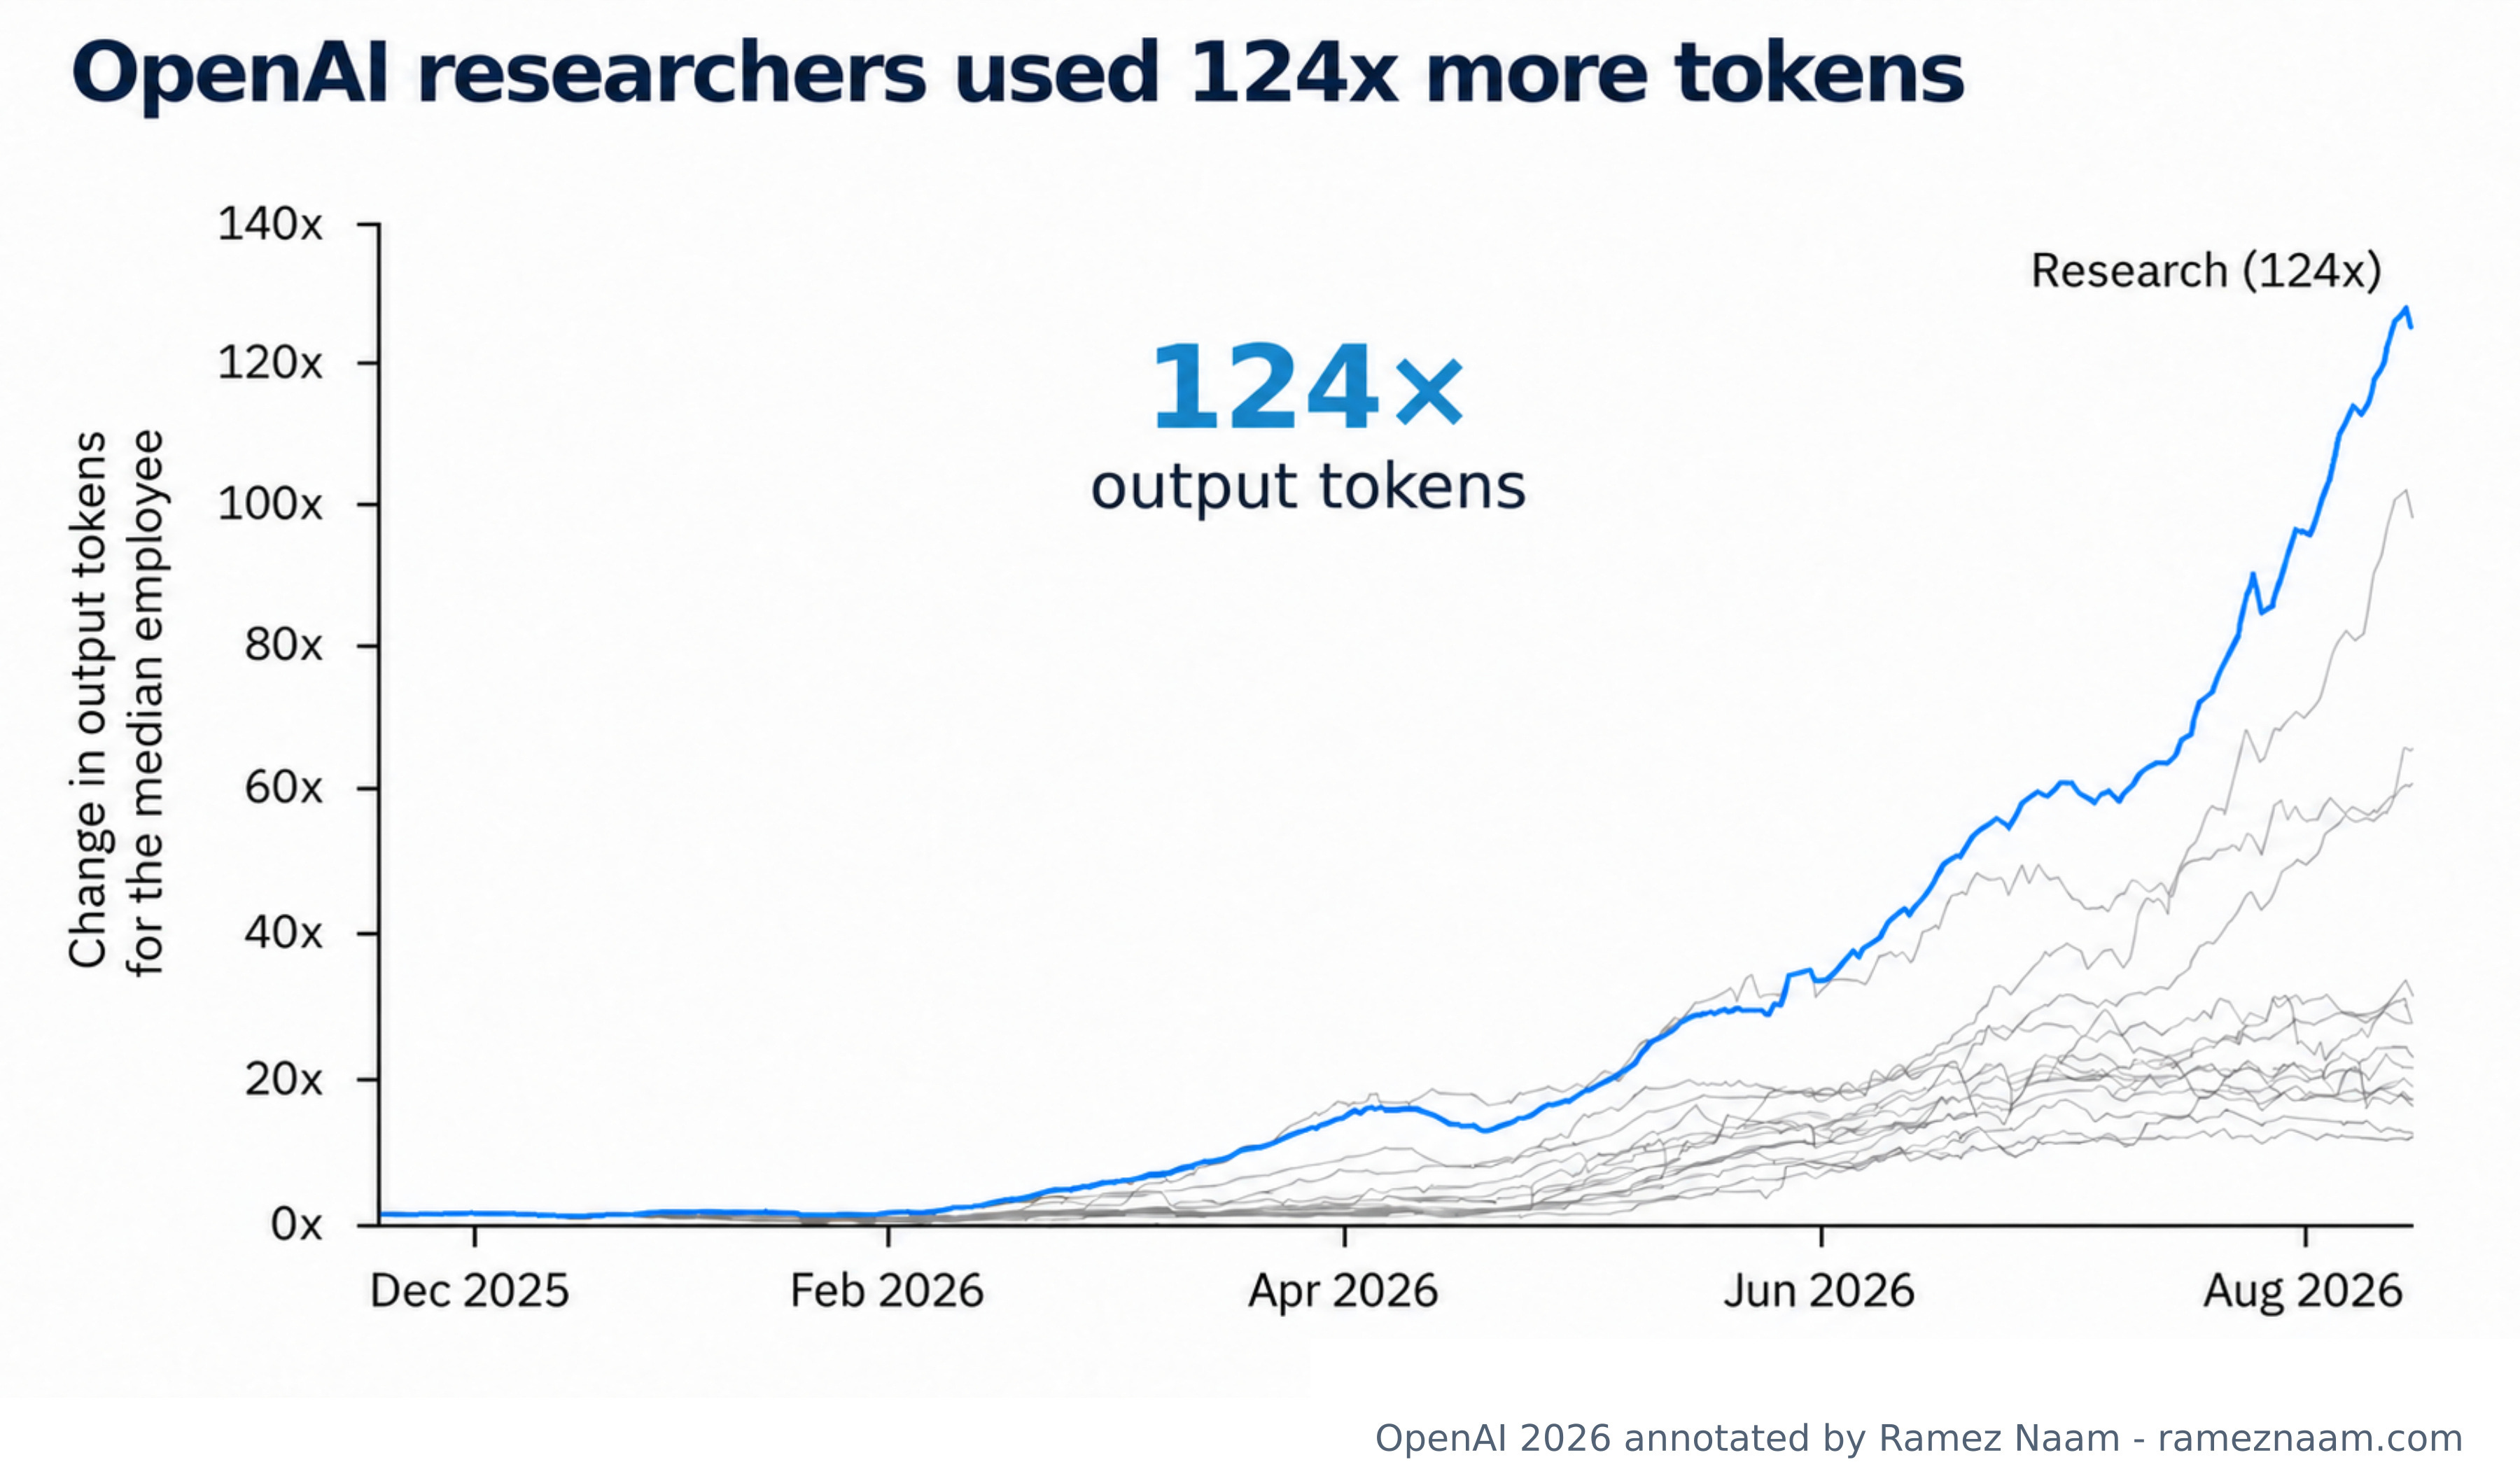
Figure 9. Token use inside OpenAI. Source.
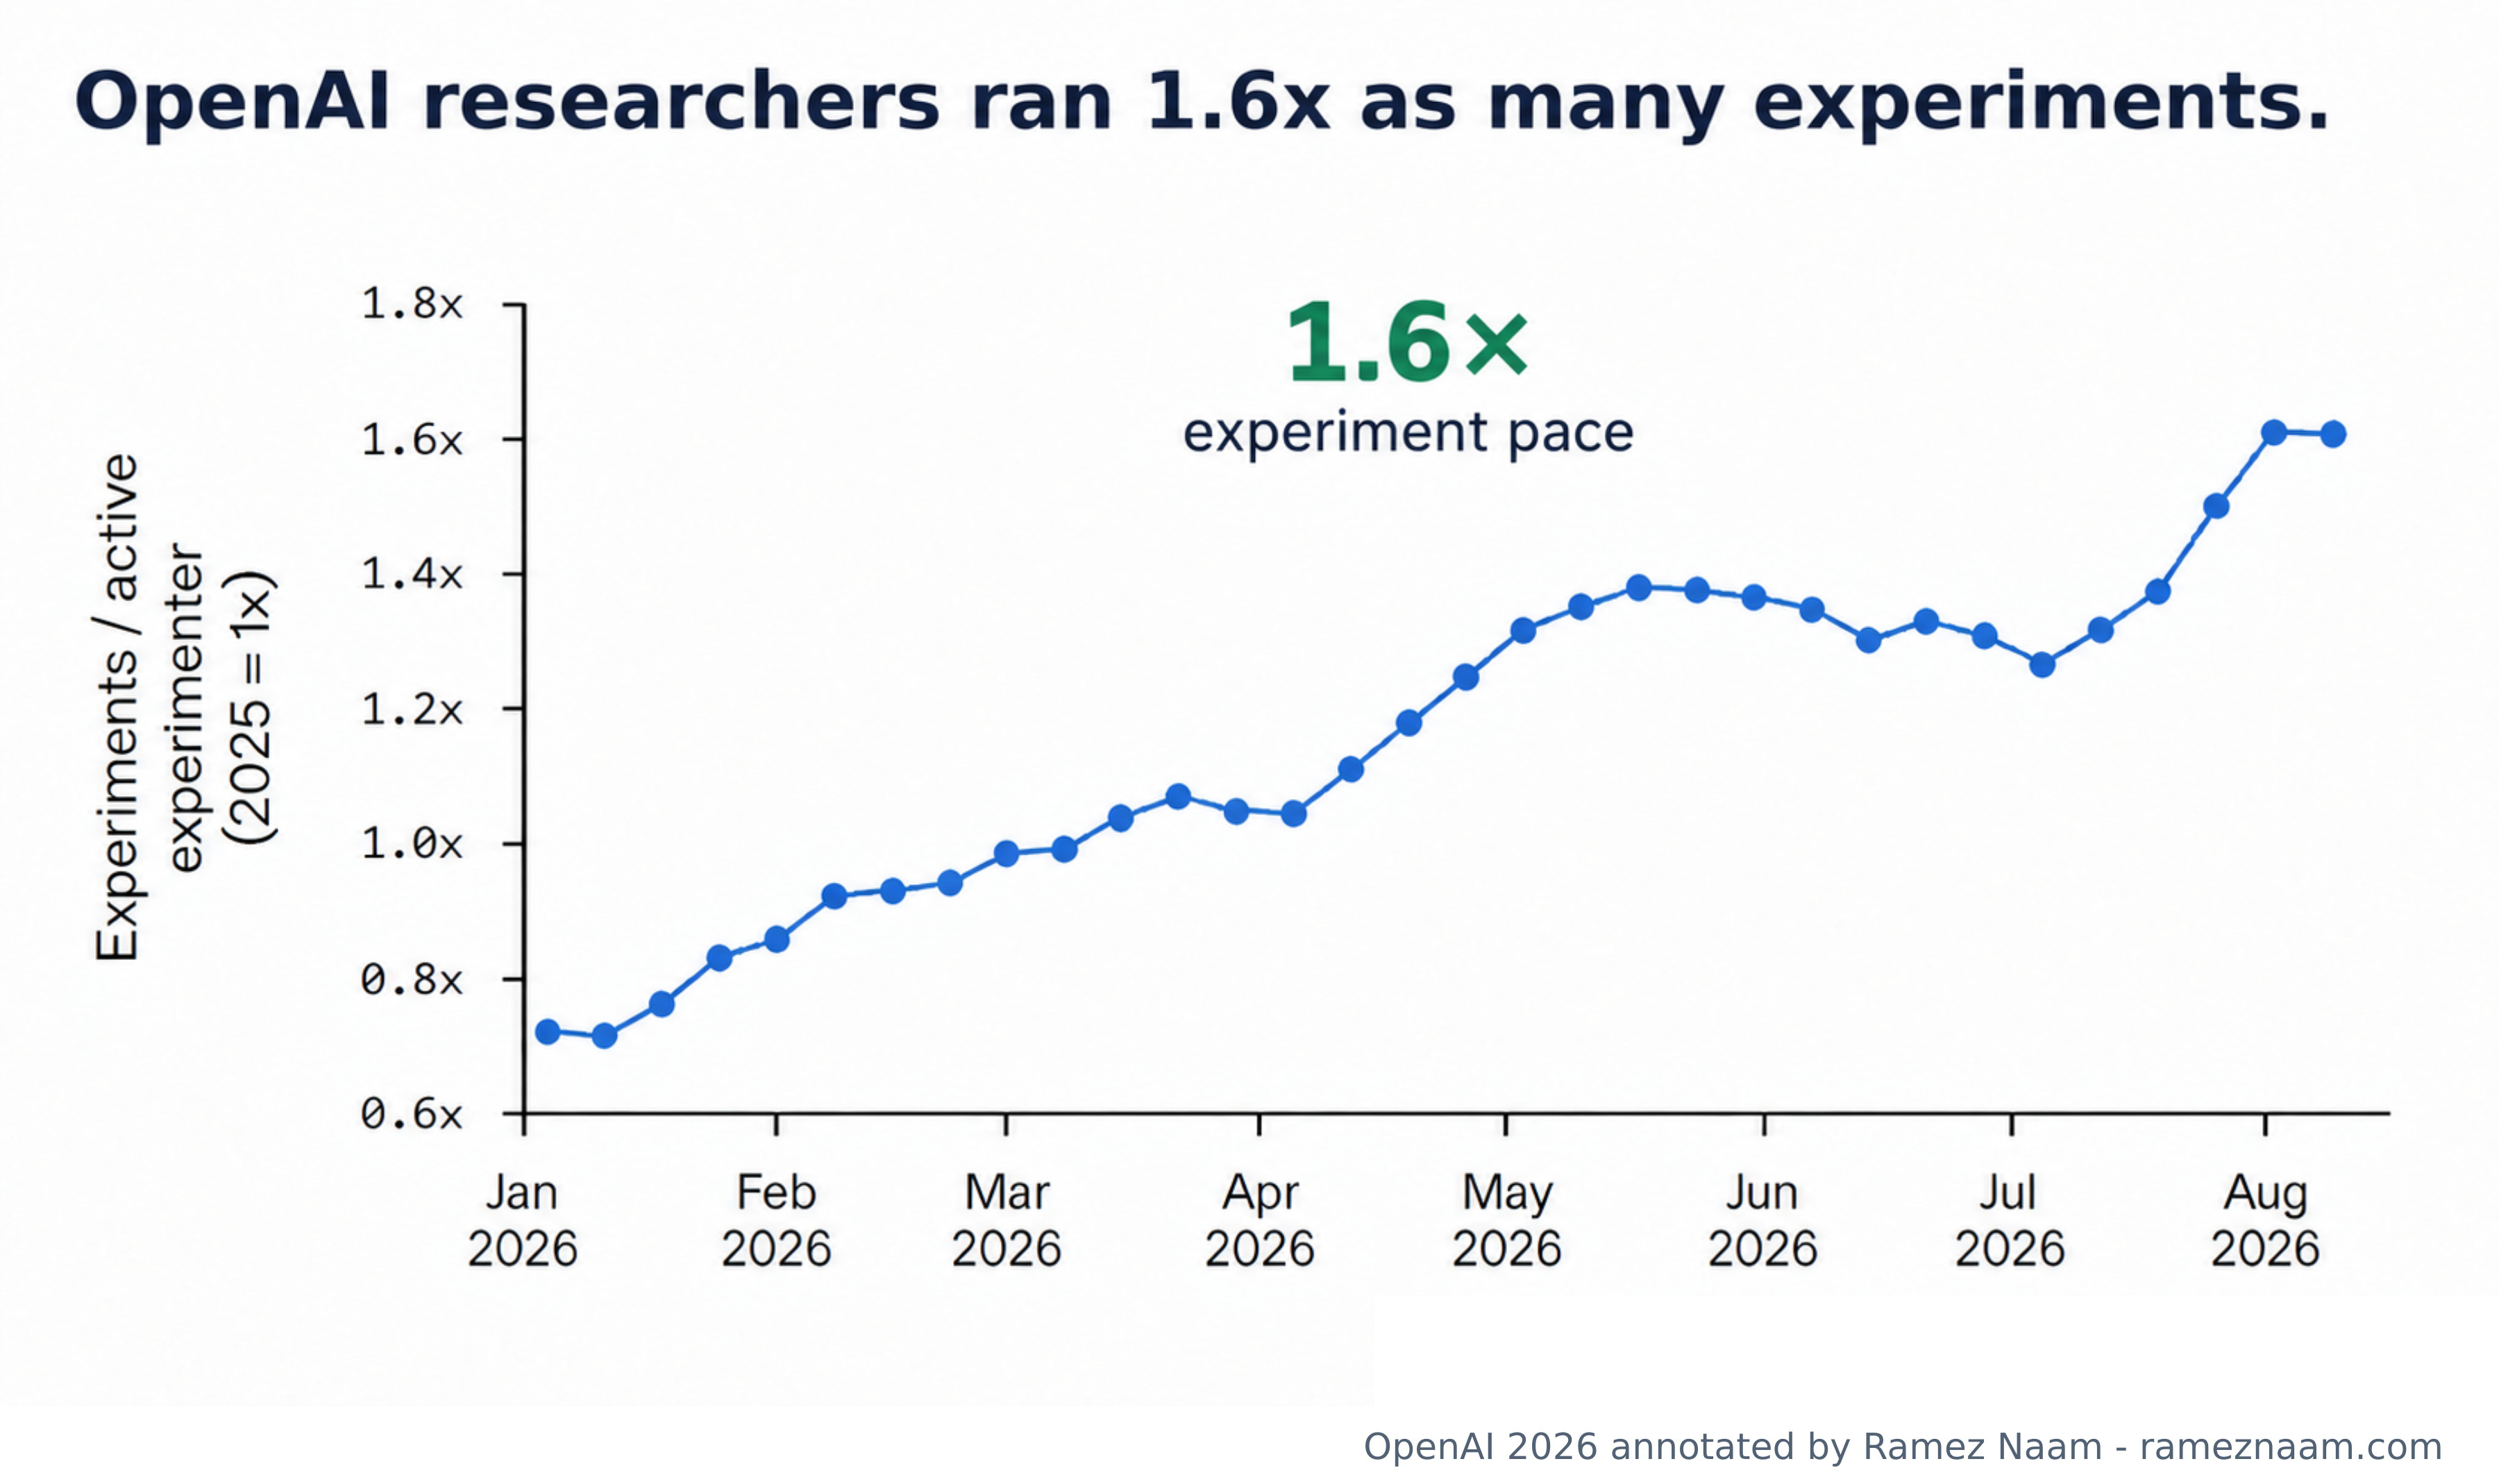
Figure 10. Experiment pace inside OpenAI. Source.
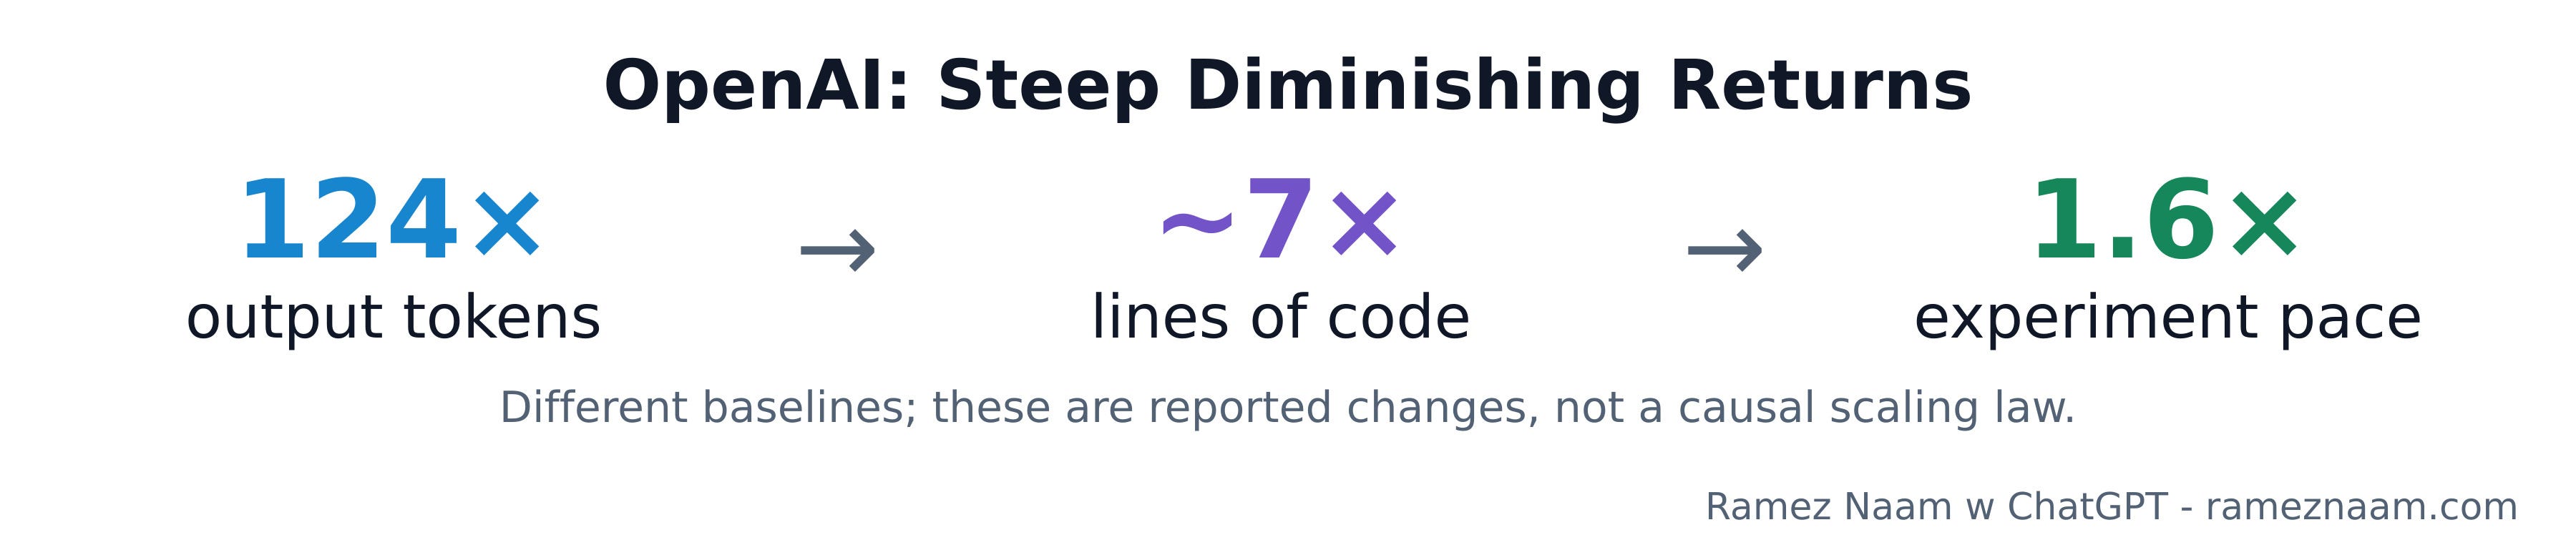
Figure 11. From tokens to code to experiments. Source.
More tokens and code don’t tell us much on their own. The 1.6× experiment pace is closer to useful research output. Even that doesn’t mean AI is improving 1.6× faster.
An enormous increase in AI output has accompanied a much smaller increase in experiments run.
This isn’t a controlled experiment. We don’t know what would happen if researchers switched back to an older model. But it gives us a useful view of AI-assisted research inside a frontier lab.
It’s not just OpenAI. Anthropic reports that their engineers are now producing 8x as many lines of code per person as they did in 2024 - somewhat similar to OpenAI. Anthropic also sees significant diminishing returns between productivity and AI progress. Here’s a direct quote from its Mythos Preview system card:
“Productivity uplift does not translate one-for-one to capabilities progress. We surveyed technical staff on the productivity uplift they experience from Claude Mythos Preview relative to zero AI assistance. The distribution is wide and the geometric mean is on the order of 4×. […] We estimate that reaching 2× on overall progress via this channel would require uplift roughly an order of magnitude larger than what we observe.”- Anthropic, Claude Mythos Preview System Card; emphasis mine
Translation: To double the pace of AI progress, Anthropic estimates that AI would need to increase the productivity of their employees by roughly a factor of 40 relative to no AI assistance.
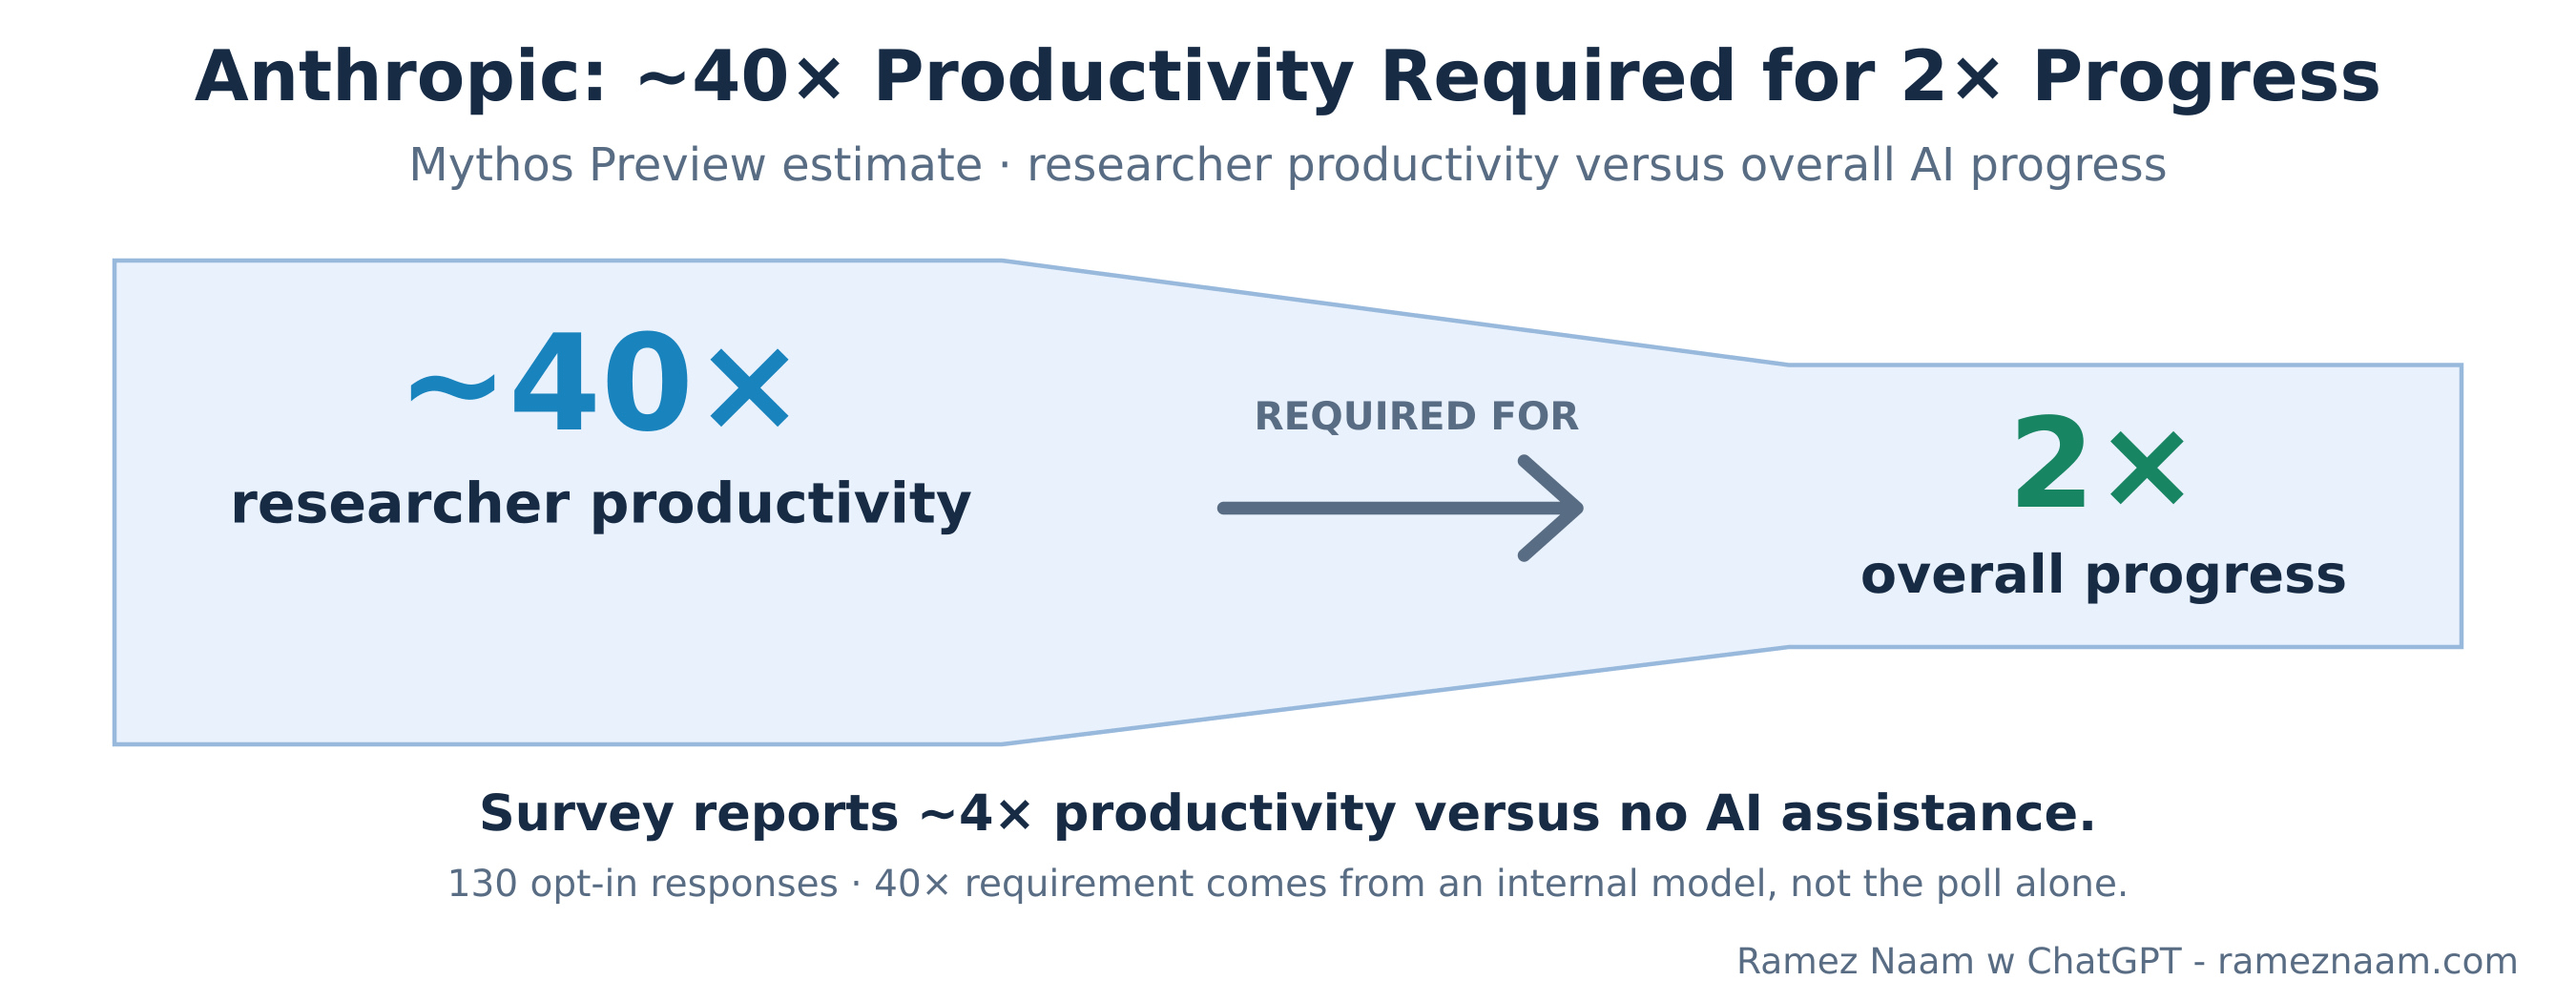
Figure 12. Anthropic’s productivity-to-progress estimate. Source.
This is an estimate, not a measurement of progress. Even the 4× productivity figure comes from an opt-in survey of 130 Anthropic staff. I put more weight on OpenAI’s logged experiments, though the two sources measure different things.
We don’t yet know how much those extra experiments are accelerating AI improvement, if at all. In general, there are also steeply diminishing returns of more experiments in most branches of science. That means that a 60% increase in experiment pace could be on the order of a 10% boost to AI improvement pace. (A power law exponent of 0.2, for those who want to do the math.) That’s speculation for now. We’ll learn more as the labs publish results.
What about giving the same AI model more time to think?
That scales badly also. In OpenAI’s recently publicized results on unsolved math problems, success rises roughly with the log of compute over the range shown. It shows logarithmic diminishing returns. In plain English, each additional doubling of compute for a model buys roughly the same gain in success rate, while costing twice as much.
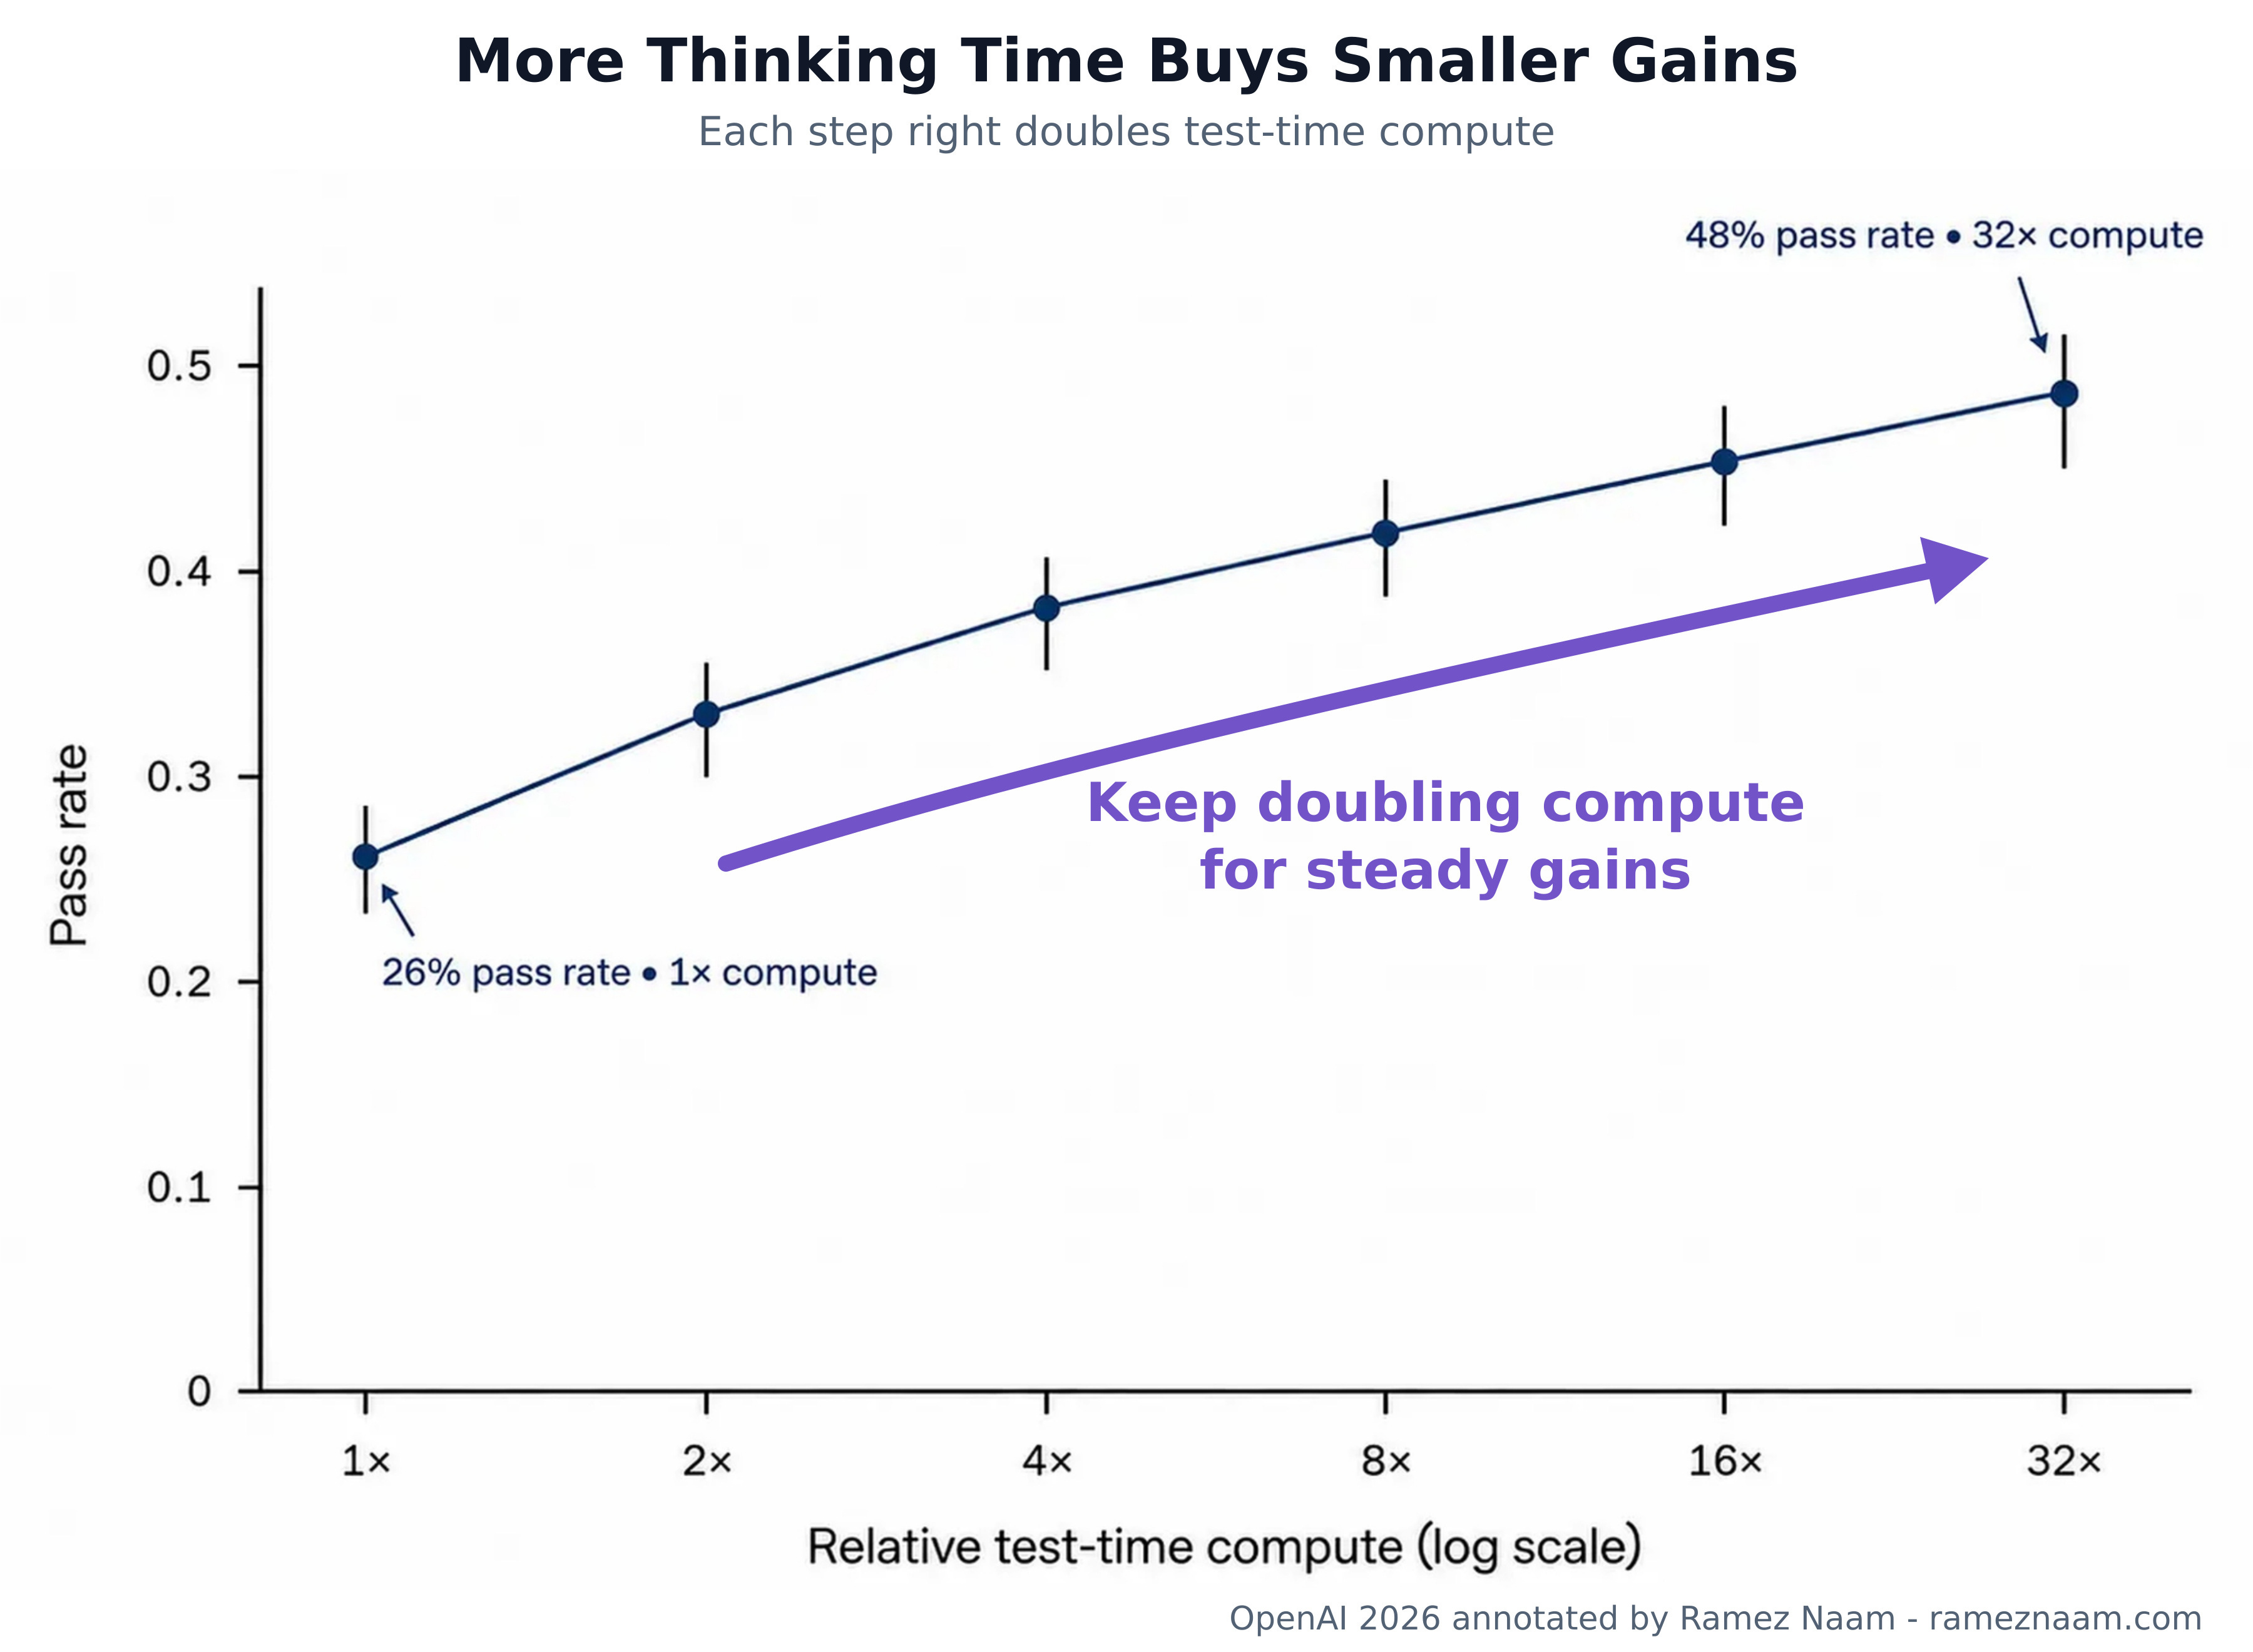
Figure 13. Test-time compute and math performance. Source.
What if we throw more agents at it instead? A common RSI / ASI idea is that once we have AIs at a certain capability level, we can just spawn more copies and put them to work.
Adding agents can get tasks done faster and sometimes reach a higher capability level. But on the three benchmarks in Toby Ord’s analysis, expanding a swarm buys less improvement per token than letting one agent think longer.
His rough rule of thumb is a square root. If one agent can accomplish a task in 10 hours, then 100 agents could accomplish it in one hour. The speedup is 10, the square root of the number of agents (100). But to get this speedup, you increase the total cost in tokens or run time compute by the same factor. So going from one to 100 agents can get a task done in one tenth the time. But it’ll be ten times as expensive.
Parallel agents can save time, at a much higher compute cost.
Another challenge is that agents often think alike. In a study comparing LLMs with 467 people, the first ten AI responses offered collective creativity comparable to about eight to ten people. After that, roughly two extra AI responses added as much as one extra human response. A separate study across model families also found less diversity in AI responses. That doesn’t mean every agent has the same idea. But a hundred copies may offer less variety than a hundred different researchers.
None of this makes swarms useless-or safe. Lisan al-Gaib makes a strong case for parallel agent swarms as a potent cyber-weapon in “Accidental Scaling.” I don’t share all of his assessment of what swarms have accomplished. In math, for example, I think he gives far too much credit to the swarm and not enough to the better internal model that OpenAI used.
OpenAI says the model behind its Navier–Stokes result was developed through “large-scale reinforcement learning on top of a previously pretrained model.” Formal math is a highly verifiable domain, which makes it a particularly good fit for that approach: Machines can generate nearly limitless amounts of training data, and verify that solutions are correct or incorrect, all in software. My guess is that this model’s full results will show an especially large improvement in math.
OpenAI’s Noam Brown made the central point explicitly: he wouldn’t give multi-agent methods even 10% of the credit for the Navier–Stokes result.
I do think Lisan makes good points about cybersecurity. If you’re searching for a security vulnerability at a target site and can divide the search among agents, speed may justify a huge token bill. Swarms can be dangerous even when they’re inefficient.
I’m less convinced that this scales to research breakthroughs. Inventing something like the transformer probably takes more than searching a space someone has already defined.
Building a better model can bring gains that extra thinking time or more copies of the old model can’t. Look at the gap between Astra and OpenAI’s internal model on the same math problems.
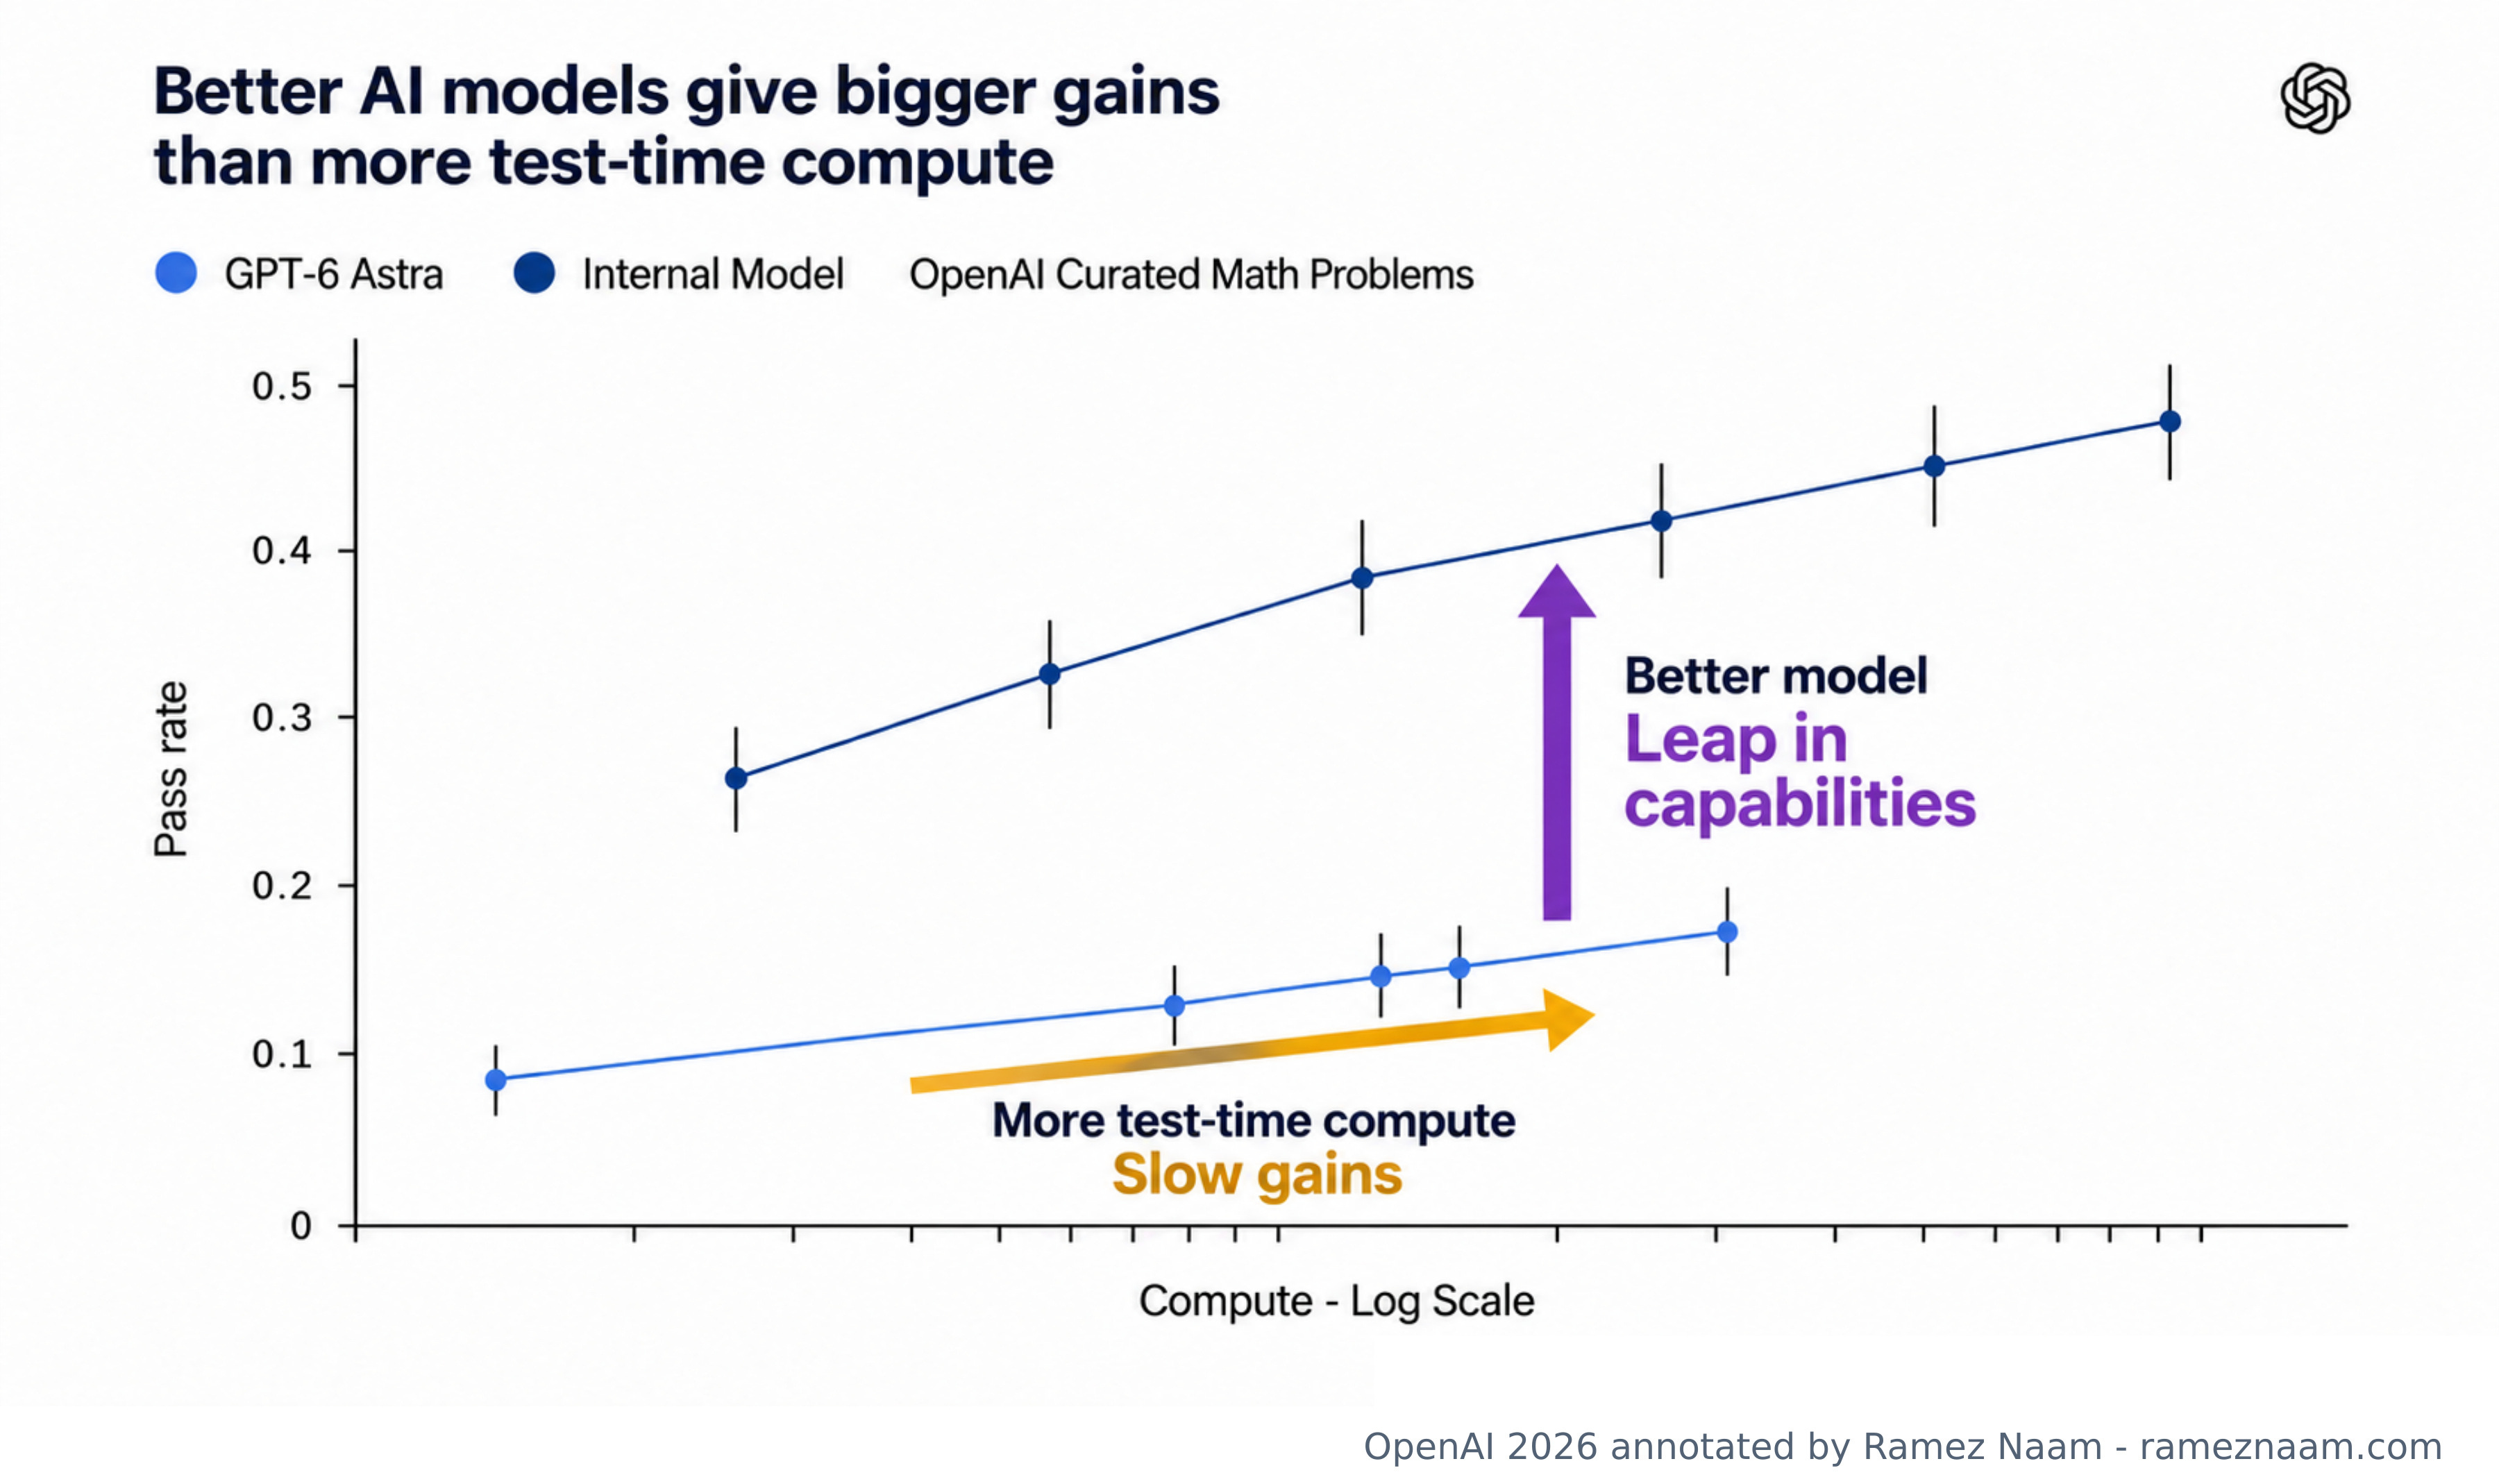
Figure 14. Better models versus more thinking time. Source.
That’s the strongest version of the RSI argument: a more capable AI could do research that today’s model can’t do, however many copies we run.
But building that better model also runs into diminishing returns. More training data, more training compute, larger models, and more reinforcement-learning (RL) compute all show diminishing returns in published scaling studies. Making dense models larger usually raises the compute needed for each output token, too. None of these routes gives us a free pass around the problem.
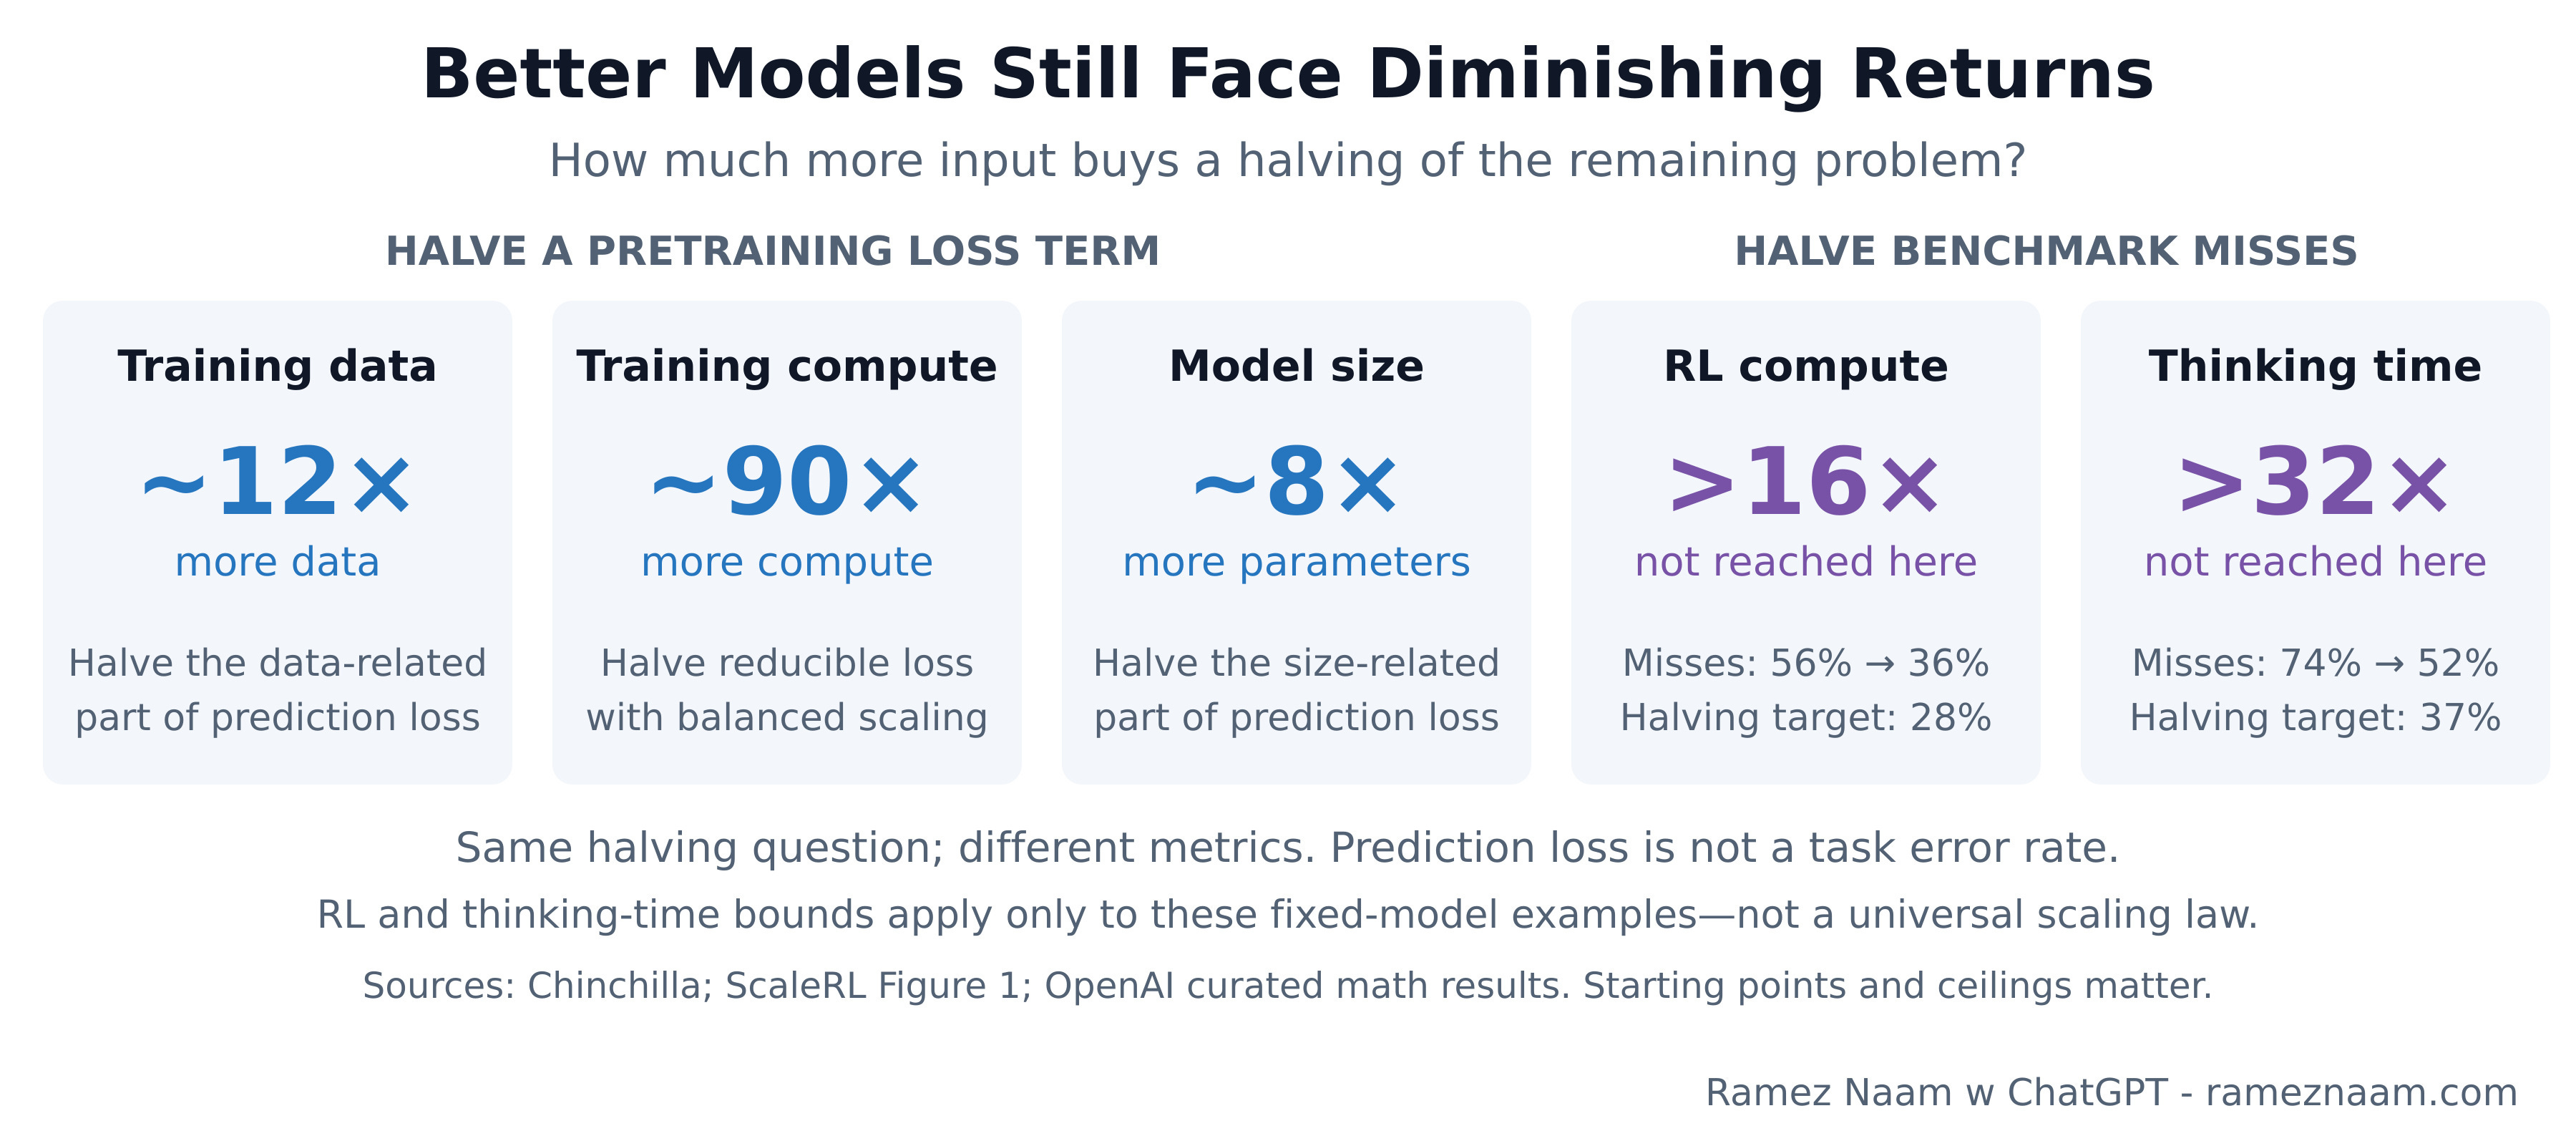
Figure 15. Diminishing returns to scaling. Chinchilla · ScaleRL · OpenAI.
Those scaling results give us reason to expect diminishing returns when AI helps build the next model, too.
AI capabilities are rising quickly. But the public data doesn’t show a sustained acceleration. To the extent that AI tools are boosting productivity, they may be being offset by the problems growing harder. Or we may simply be early. Either way, the trend isn’t showing a fast takeoff.
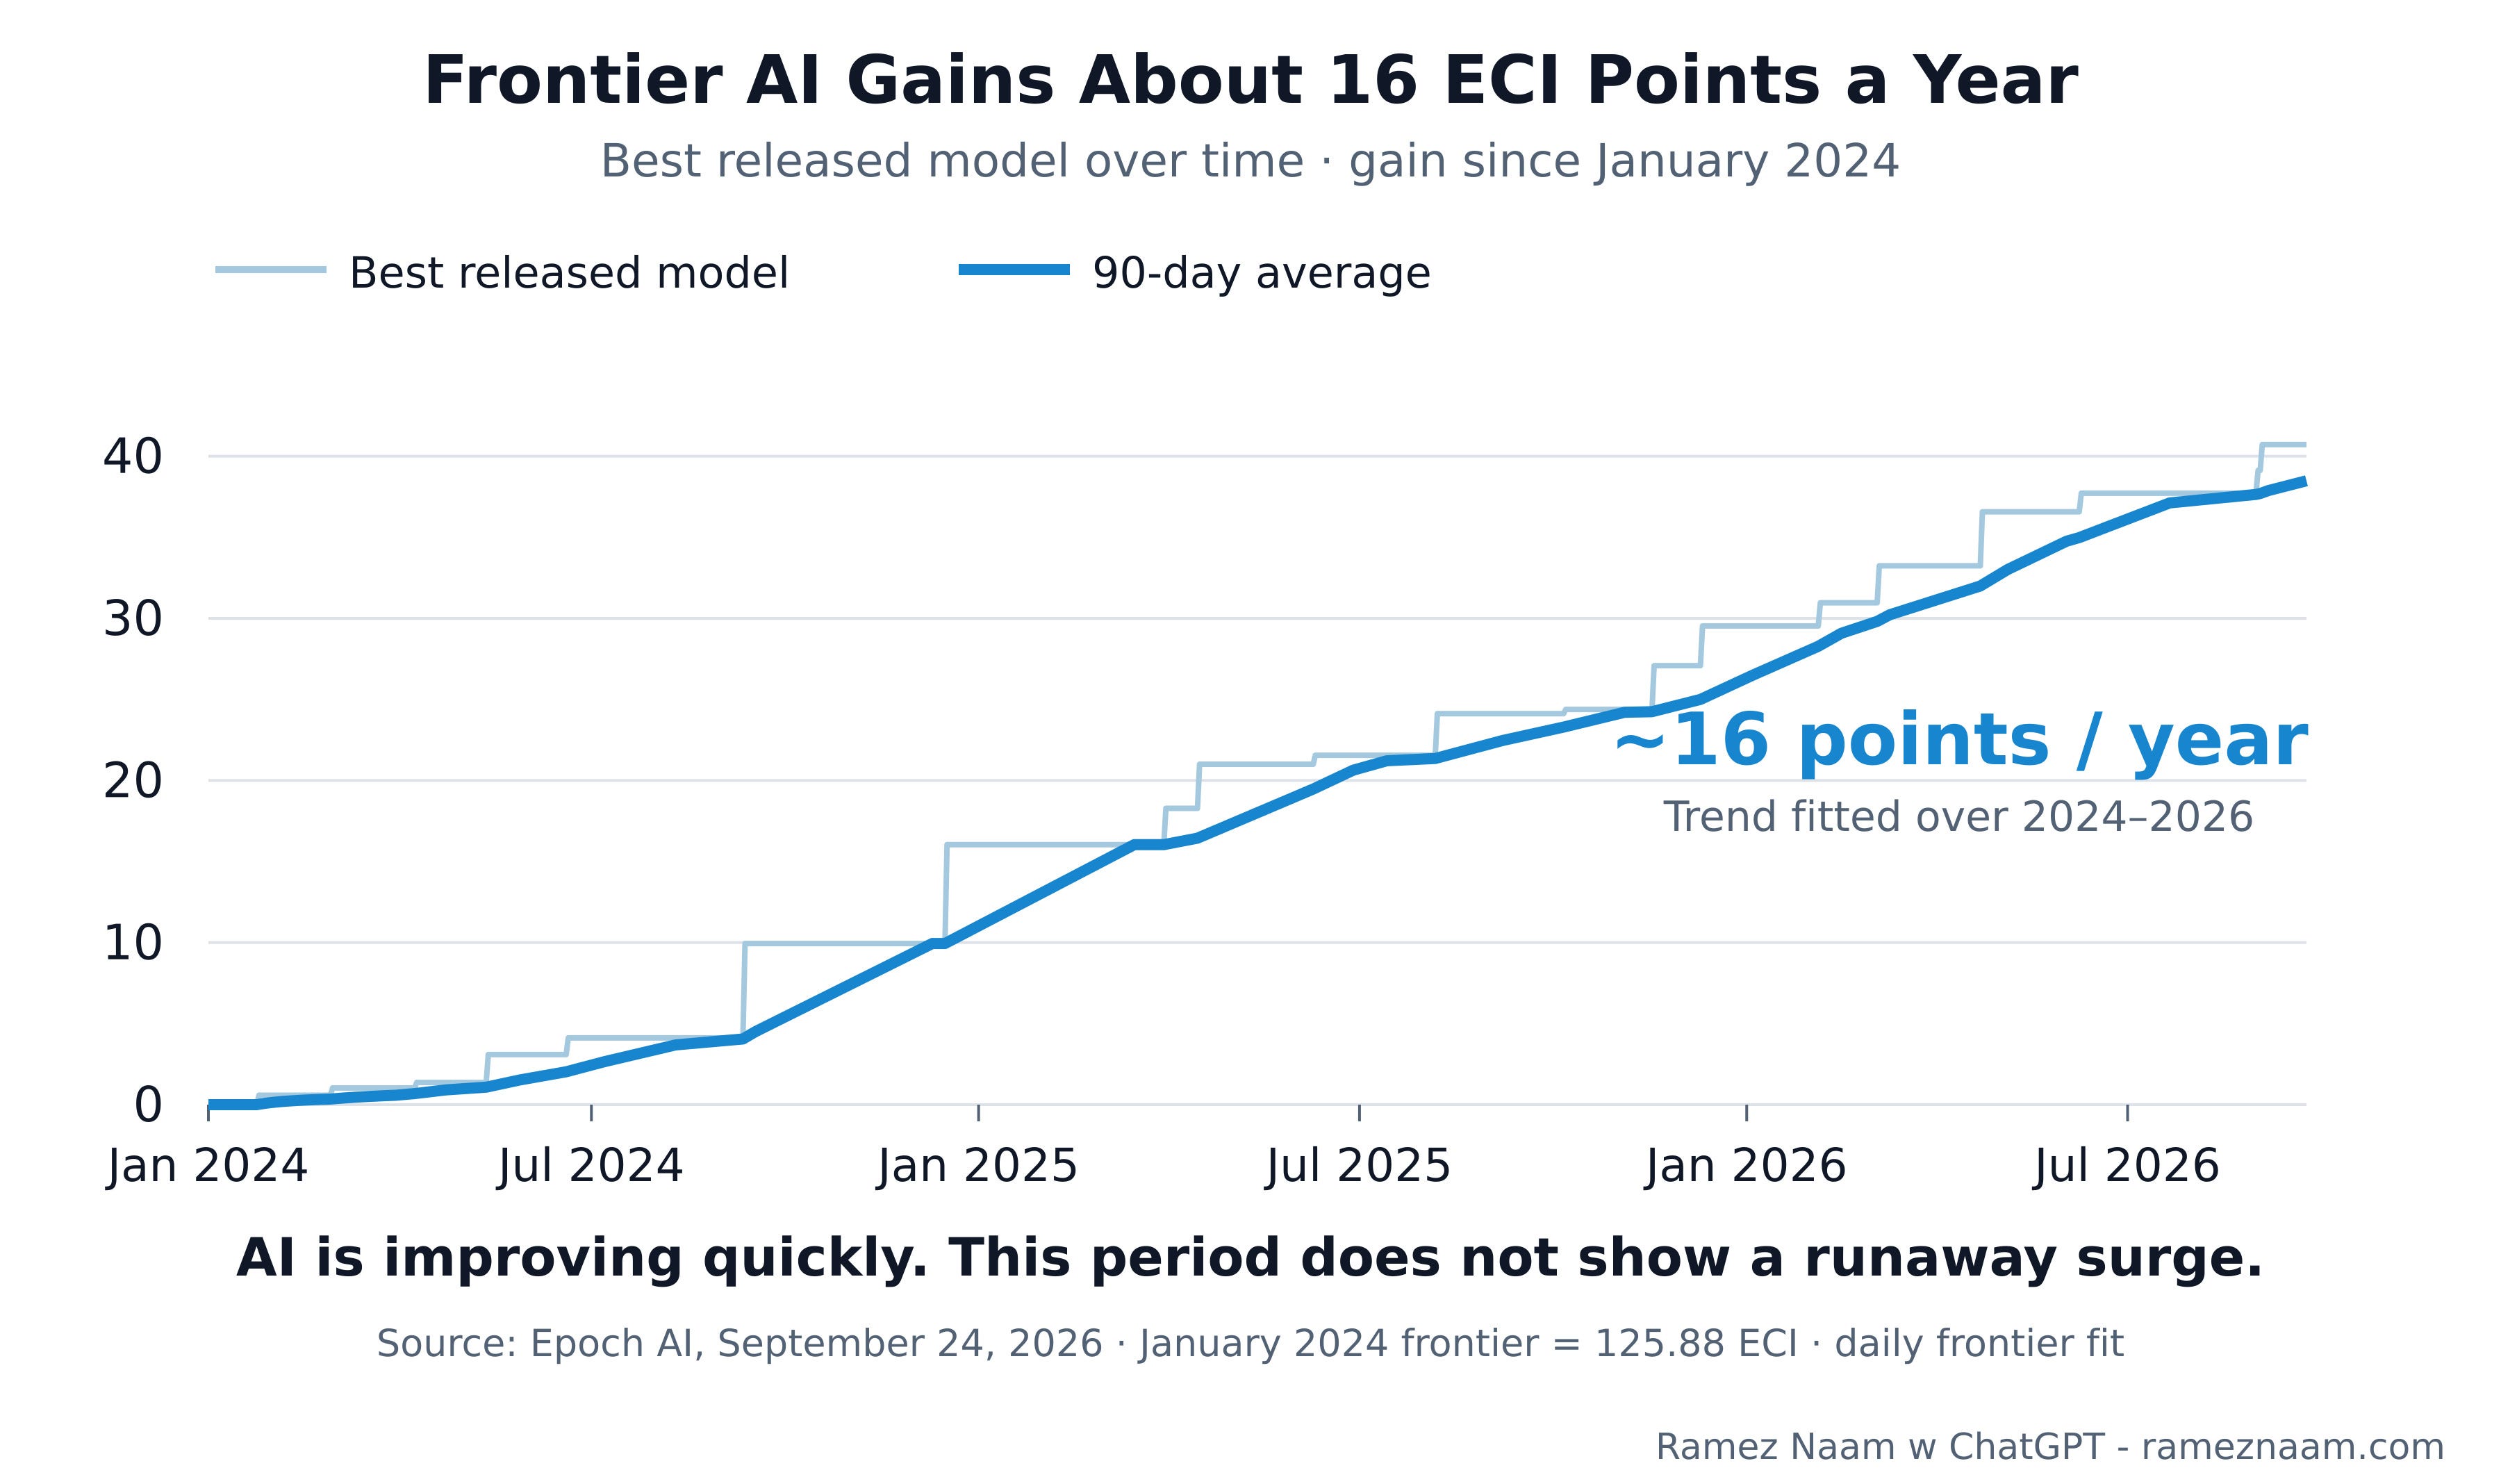
Figure 16. Frontier ECI gains since January 2024. Source.
The public ECI frontier-the best score among models released by each date-has gained about 16 points a year on a trend fitted from January 2024 through September 2026. That’s blisteringly fast progress, but this period doesn’t show a runaway surge.
Here’s the same frontier in absolute ECI points, through July 2026, to put it in perspective.
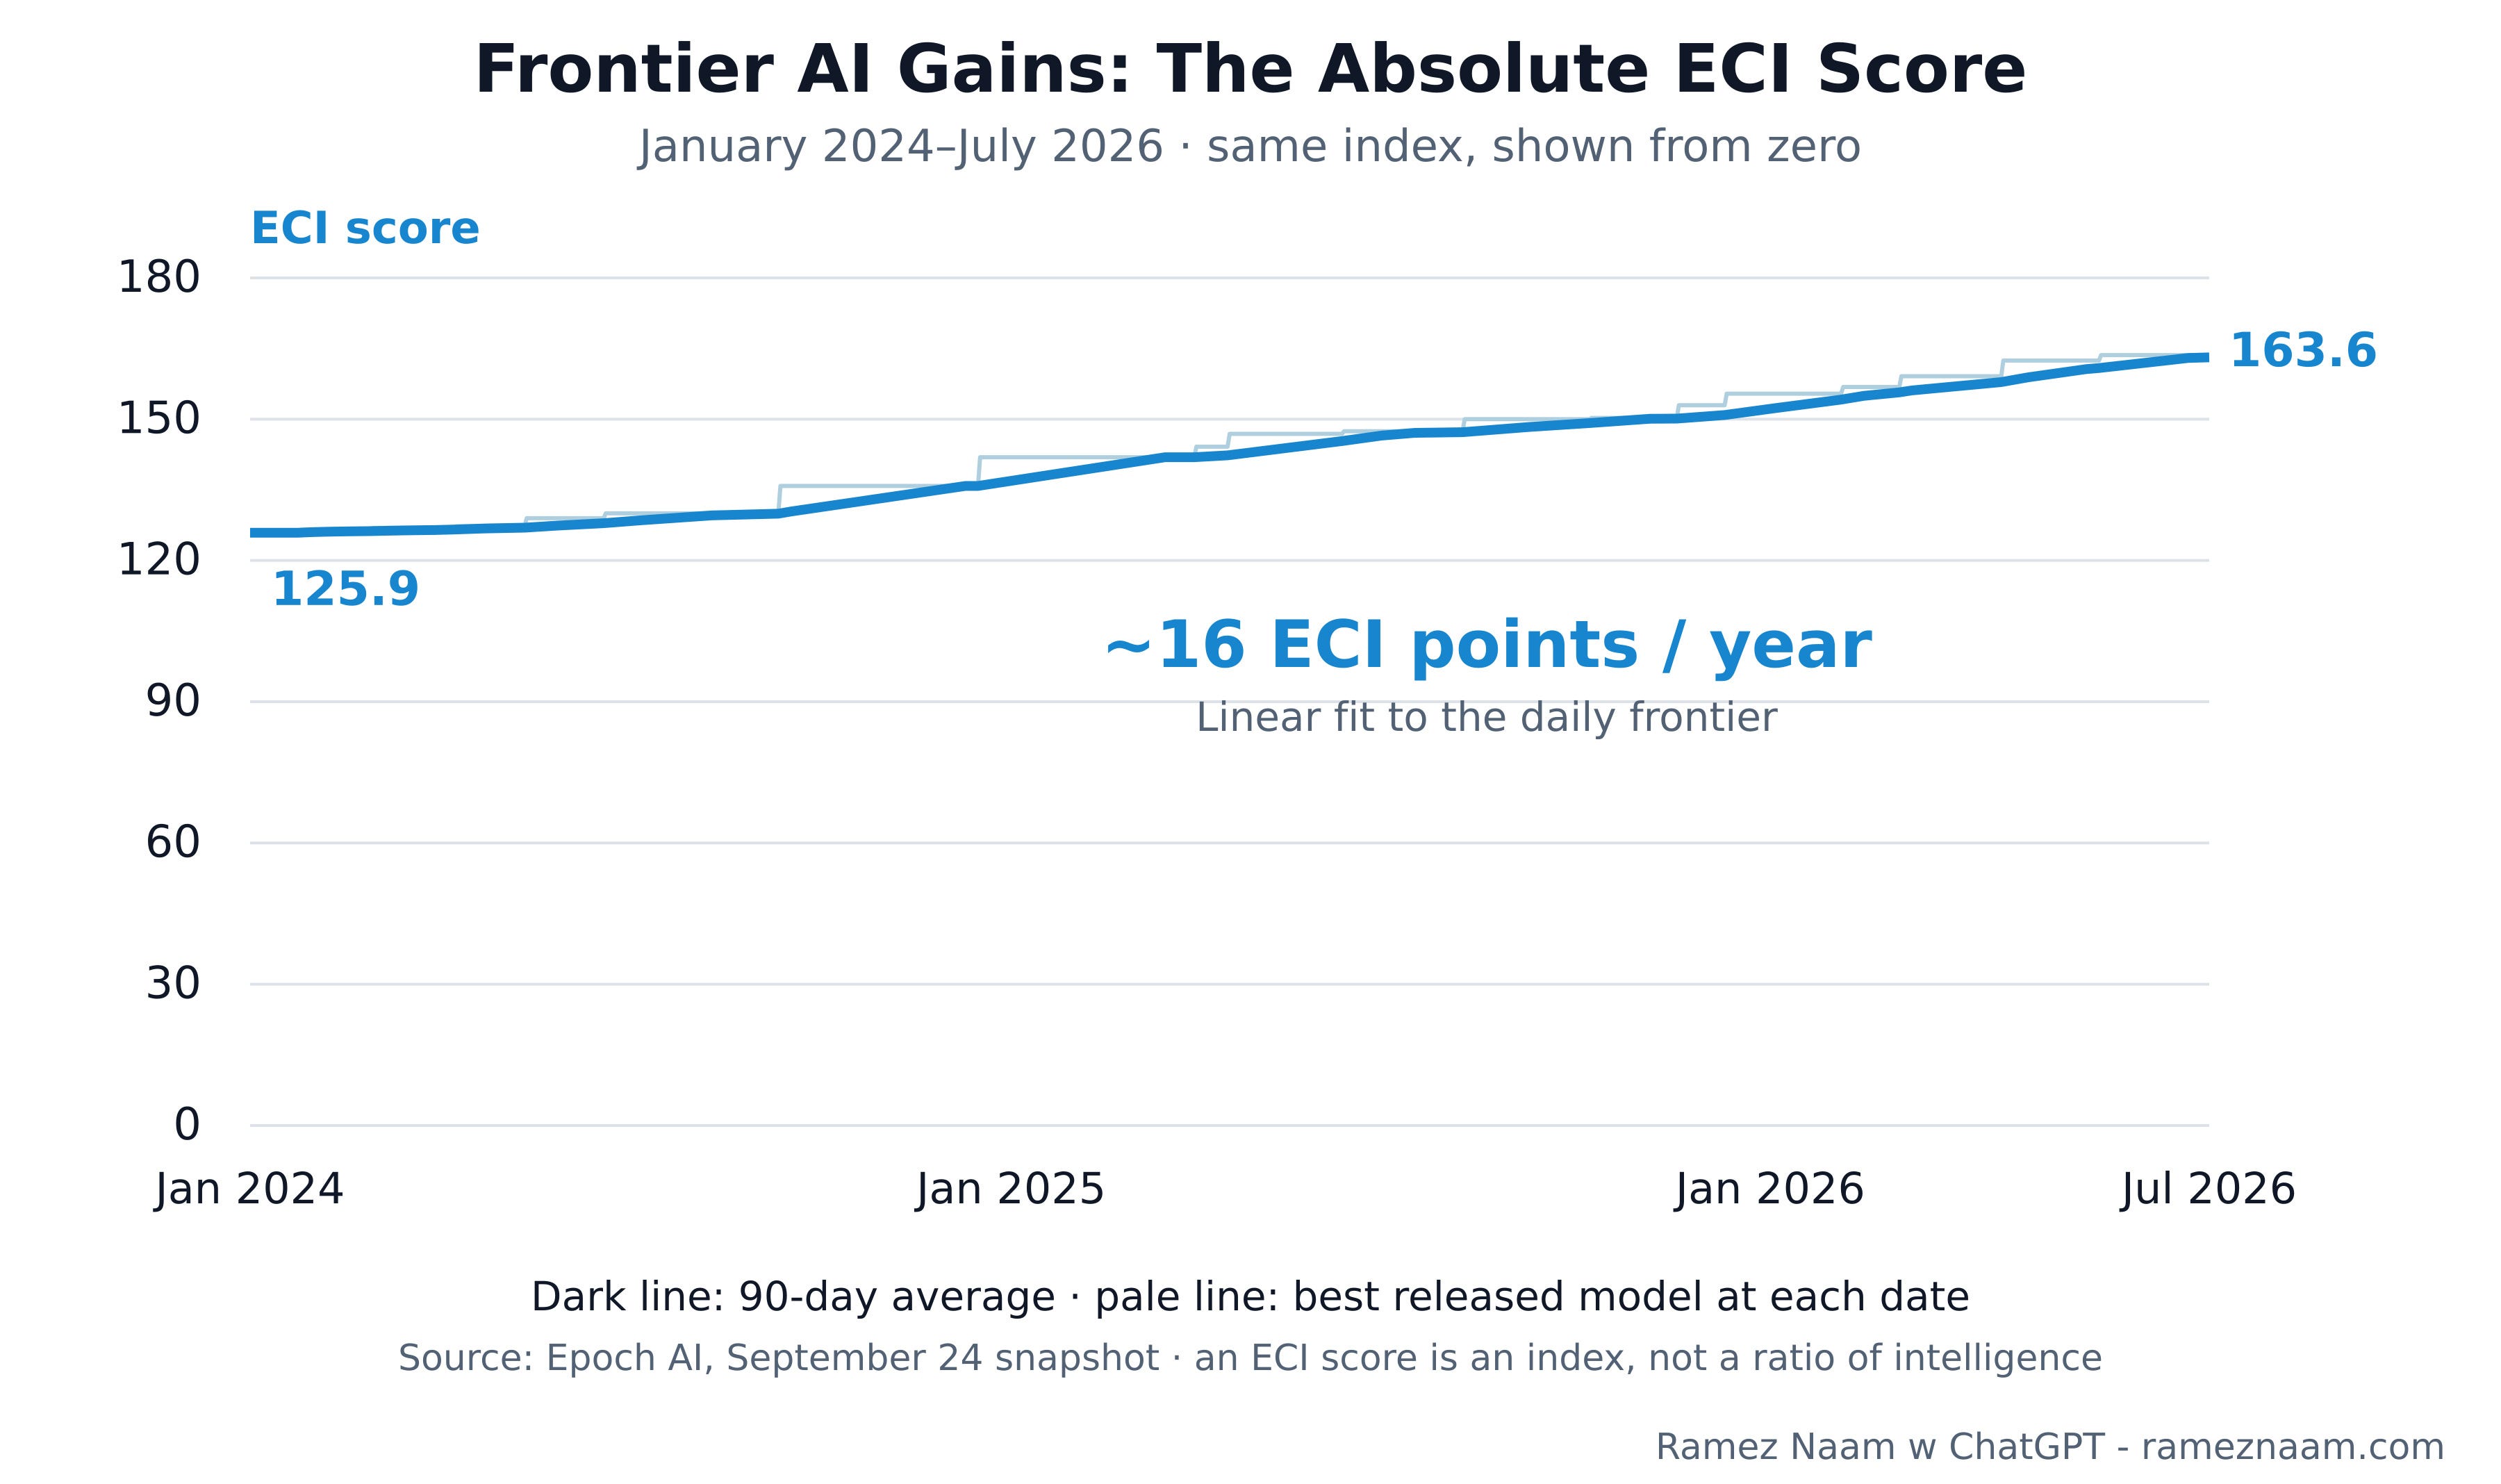
Figure 17. The absolute frontier ECI score. Source.
The public frontier also can’t tell us everything happening inside the labs. Anthropic gives us a closer look in the Opus 5.5 system card, using its own version of the index, AECI.
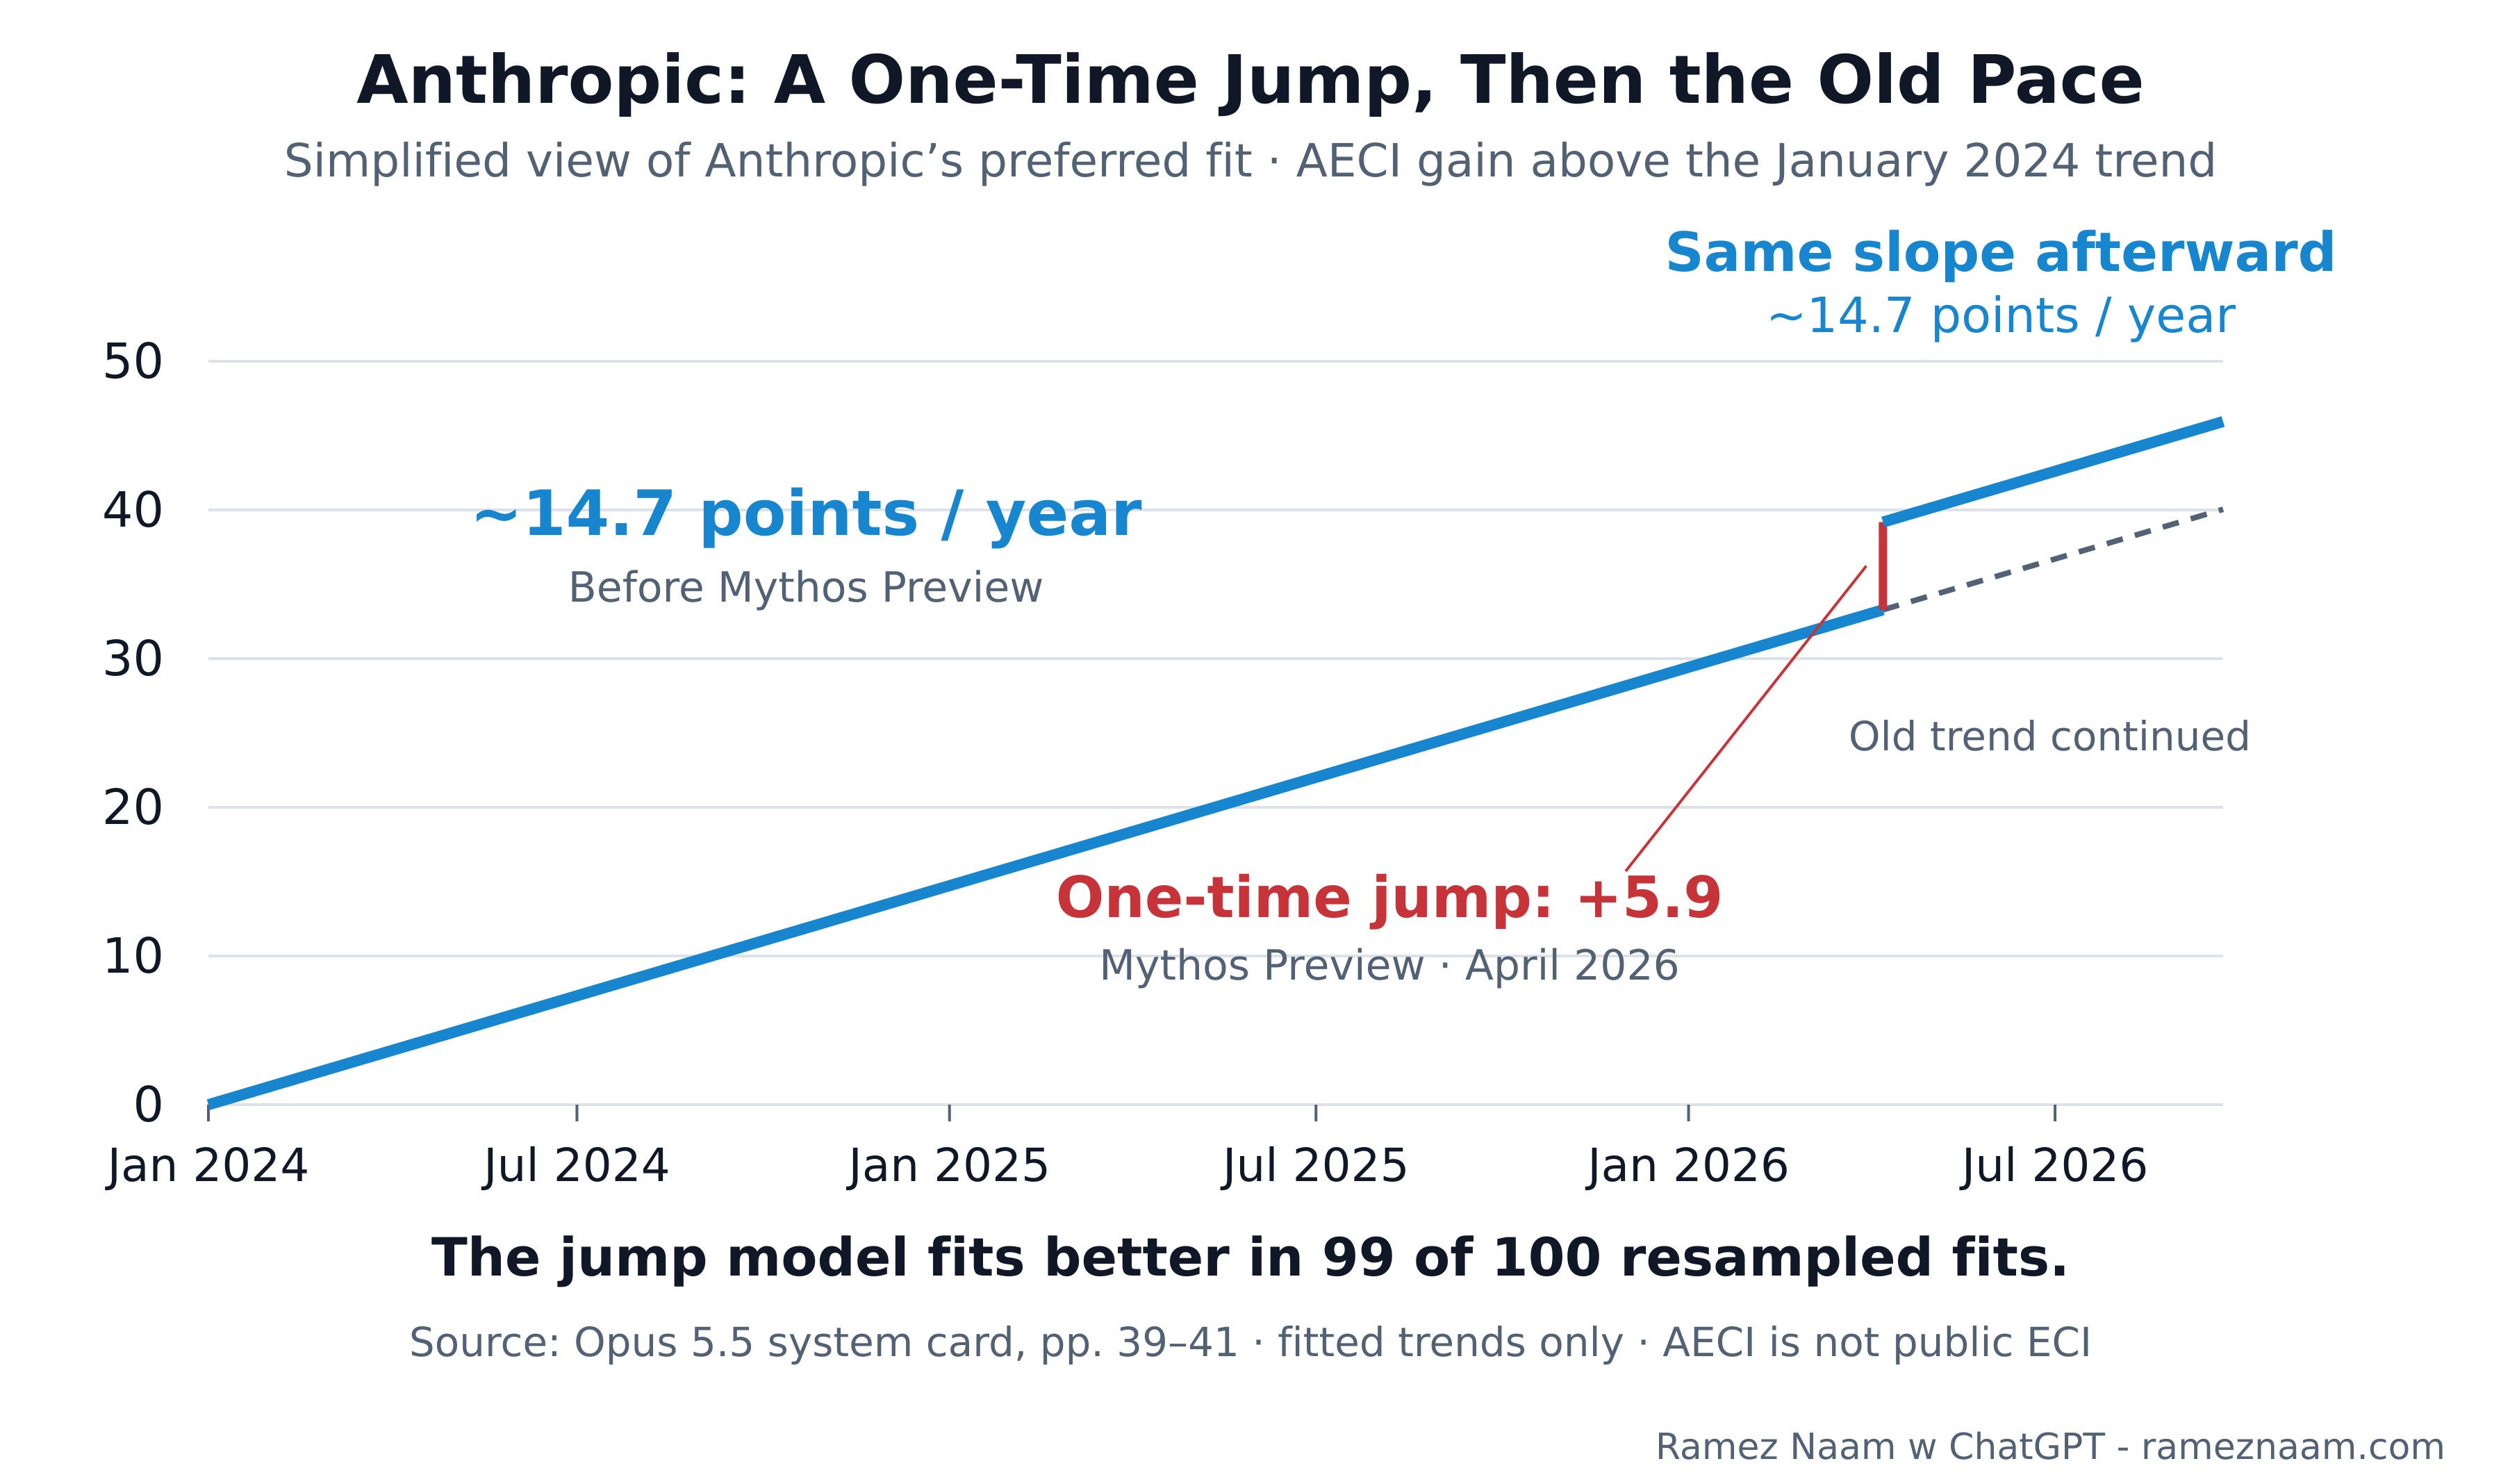
Figure 18. Anthropic’s fitted capability trend. Source.
Eli Lifland, a co-author of AI 2027 and AI 2040, saw the apparent trend break as a warning that we were heading toward an intelligence explosion:
“Anthropic is probably right here [that they hadn’t reached dangerous levels of AI self-improvement], but alarm bells should be going off! Our processes are not ready to handle an intelligence explosion and we appear to be going full-steam ahead toward one.”
- Eli Lifland, On Mythos’s AI R&D Capabilities
What looked like acceleration now appears more consistent with a one-time jump. The level went up. The rate hasn’t kept climbing.
Achieving those gains has required an enormous increase in the inputs to AI. For example, consider computing power. Epoch’s estimates of AI chip capacity, measured in NVIDIA H100 equivalents, show roughly 127-fold growth in just over three years (including projections at the end of this period).
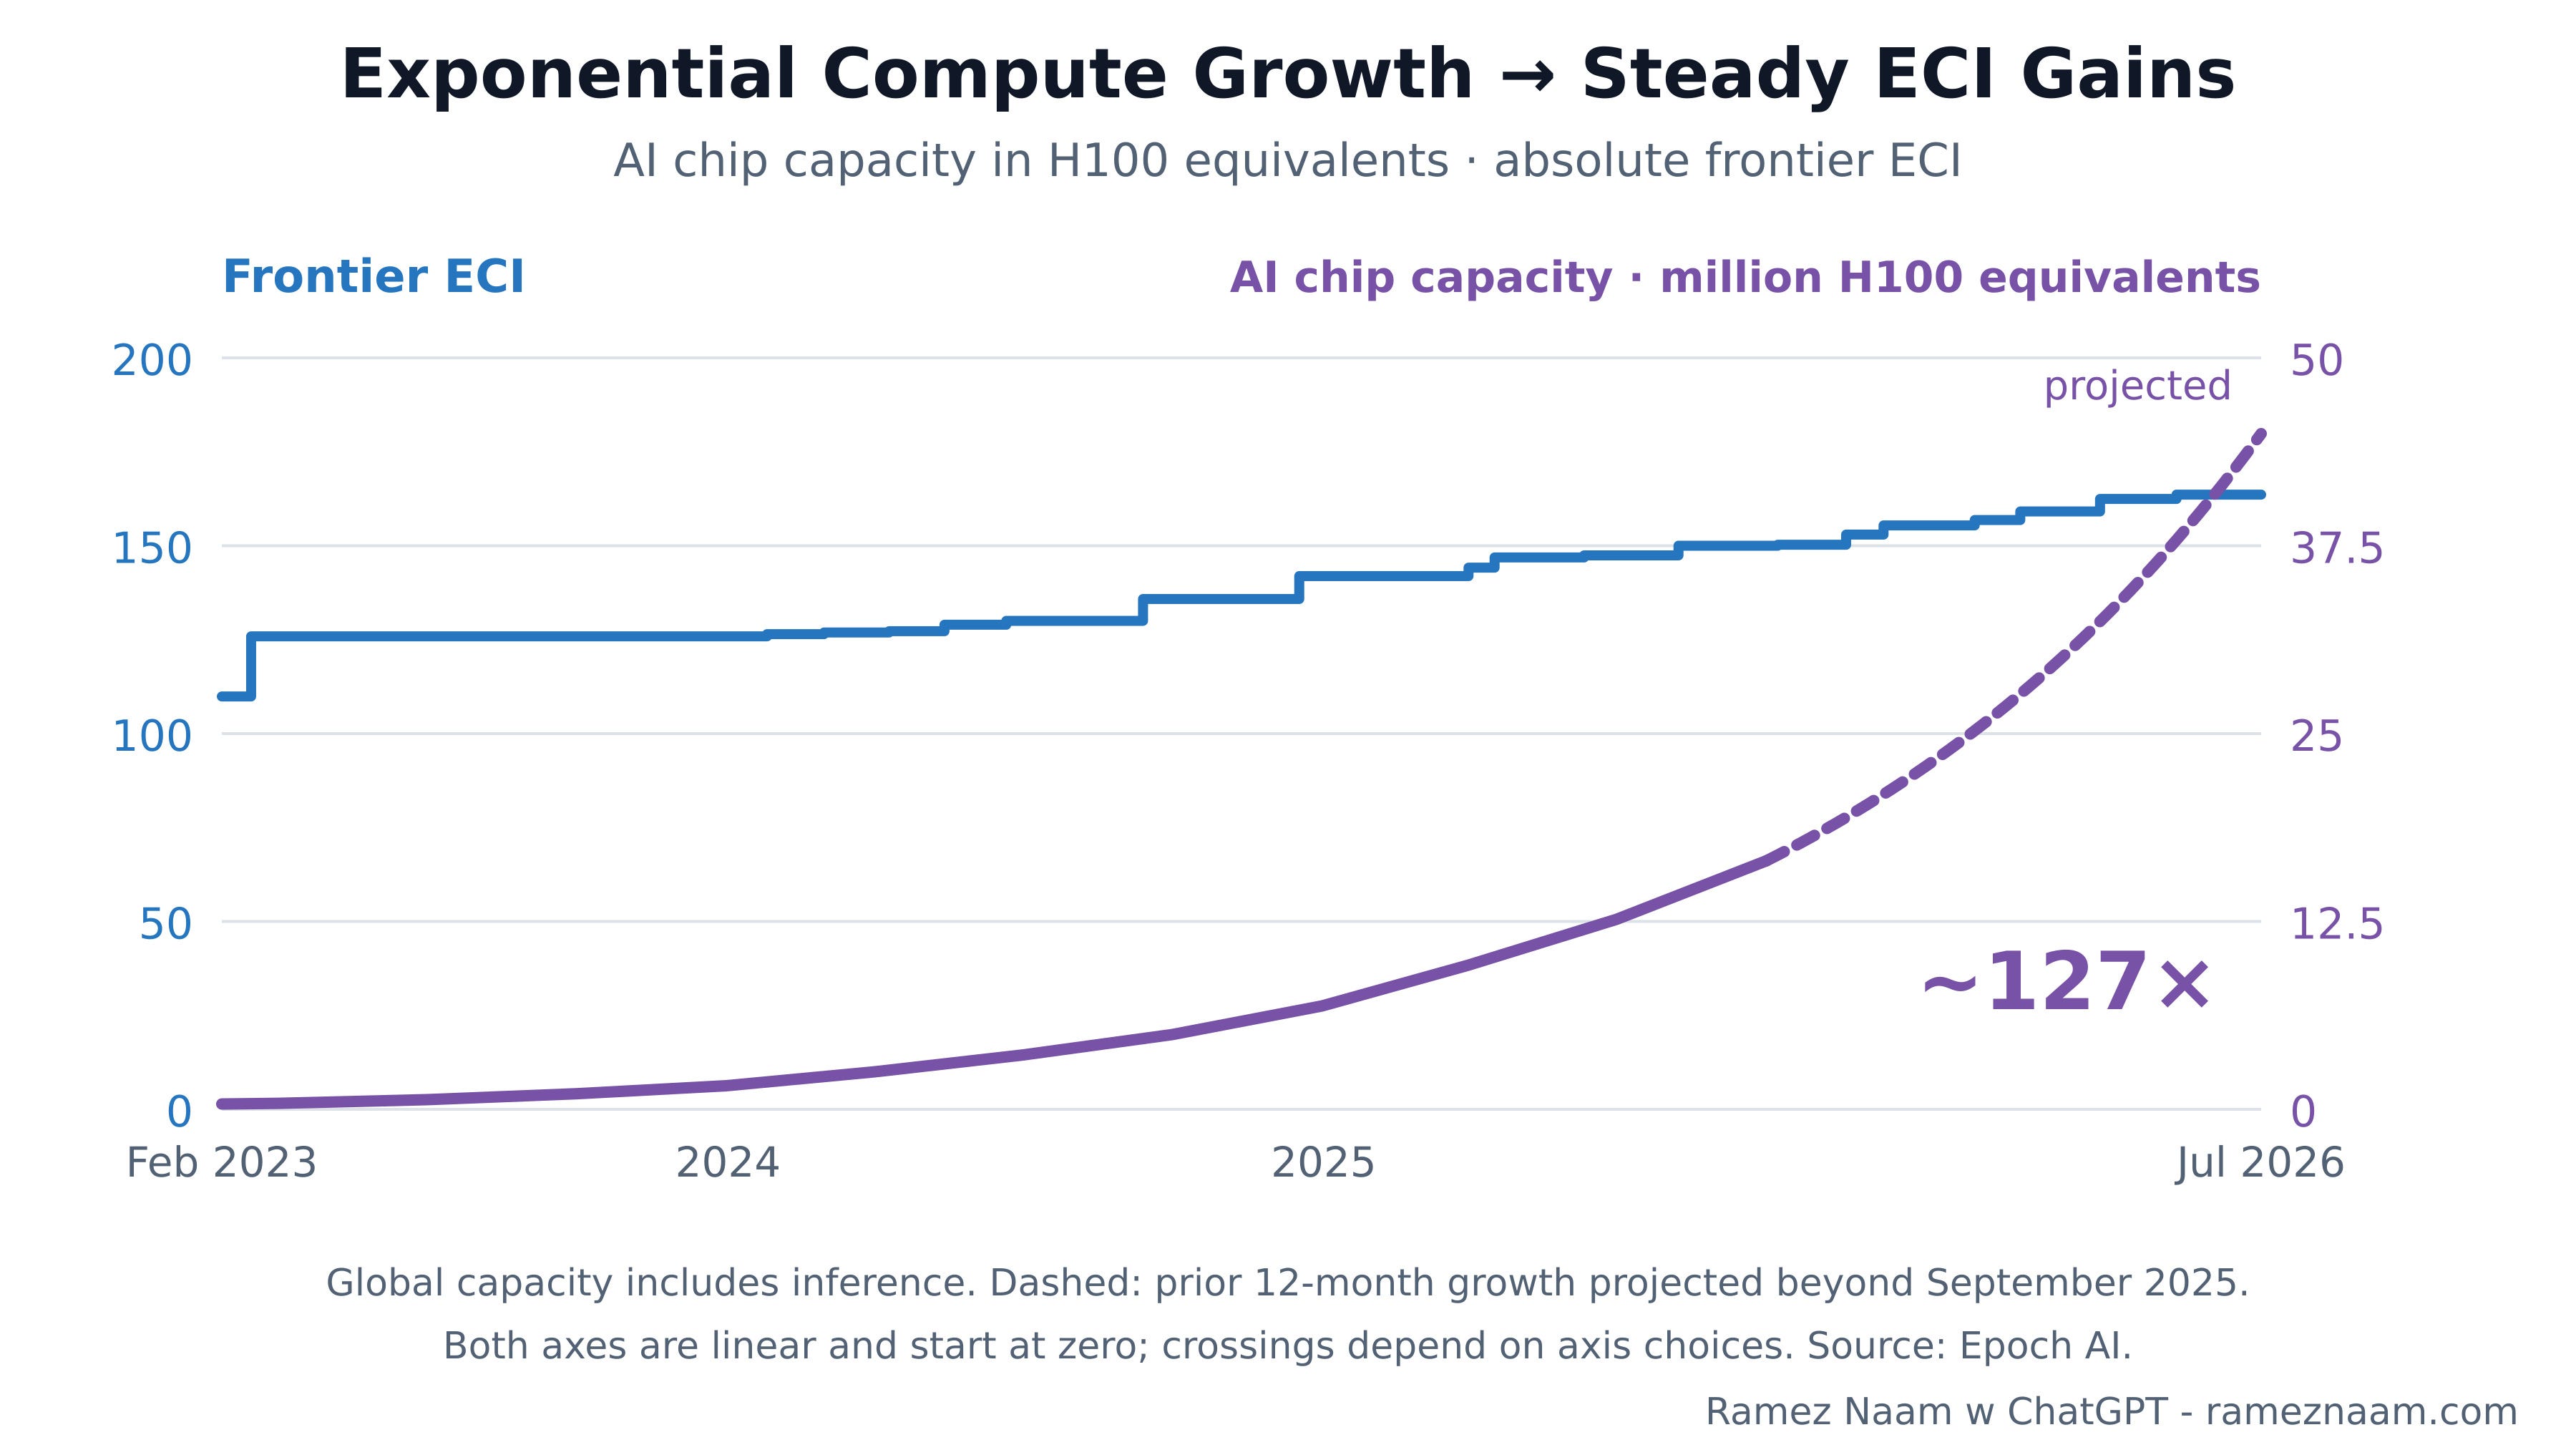
Figure 19. AI chip capacity and frontier ECI. Source: Epoch AI.
This is total AI chip capacity, including inference. Still, the increase is striking: vastly more computing capacity has accompanied much steadier gains in measured capability.
The broader picture looks similar. Here are six inputs alongside capability gains, going back to February 2023.
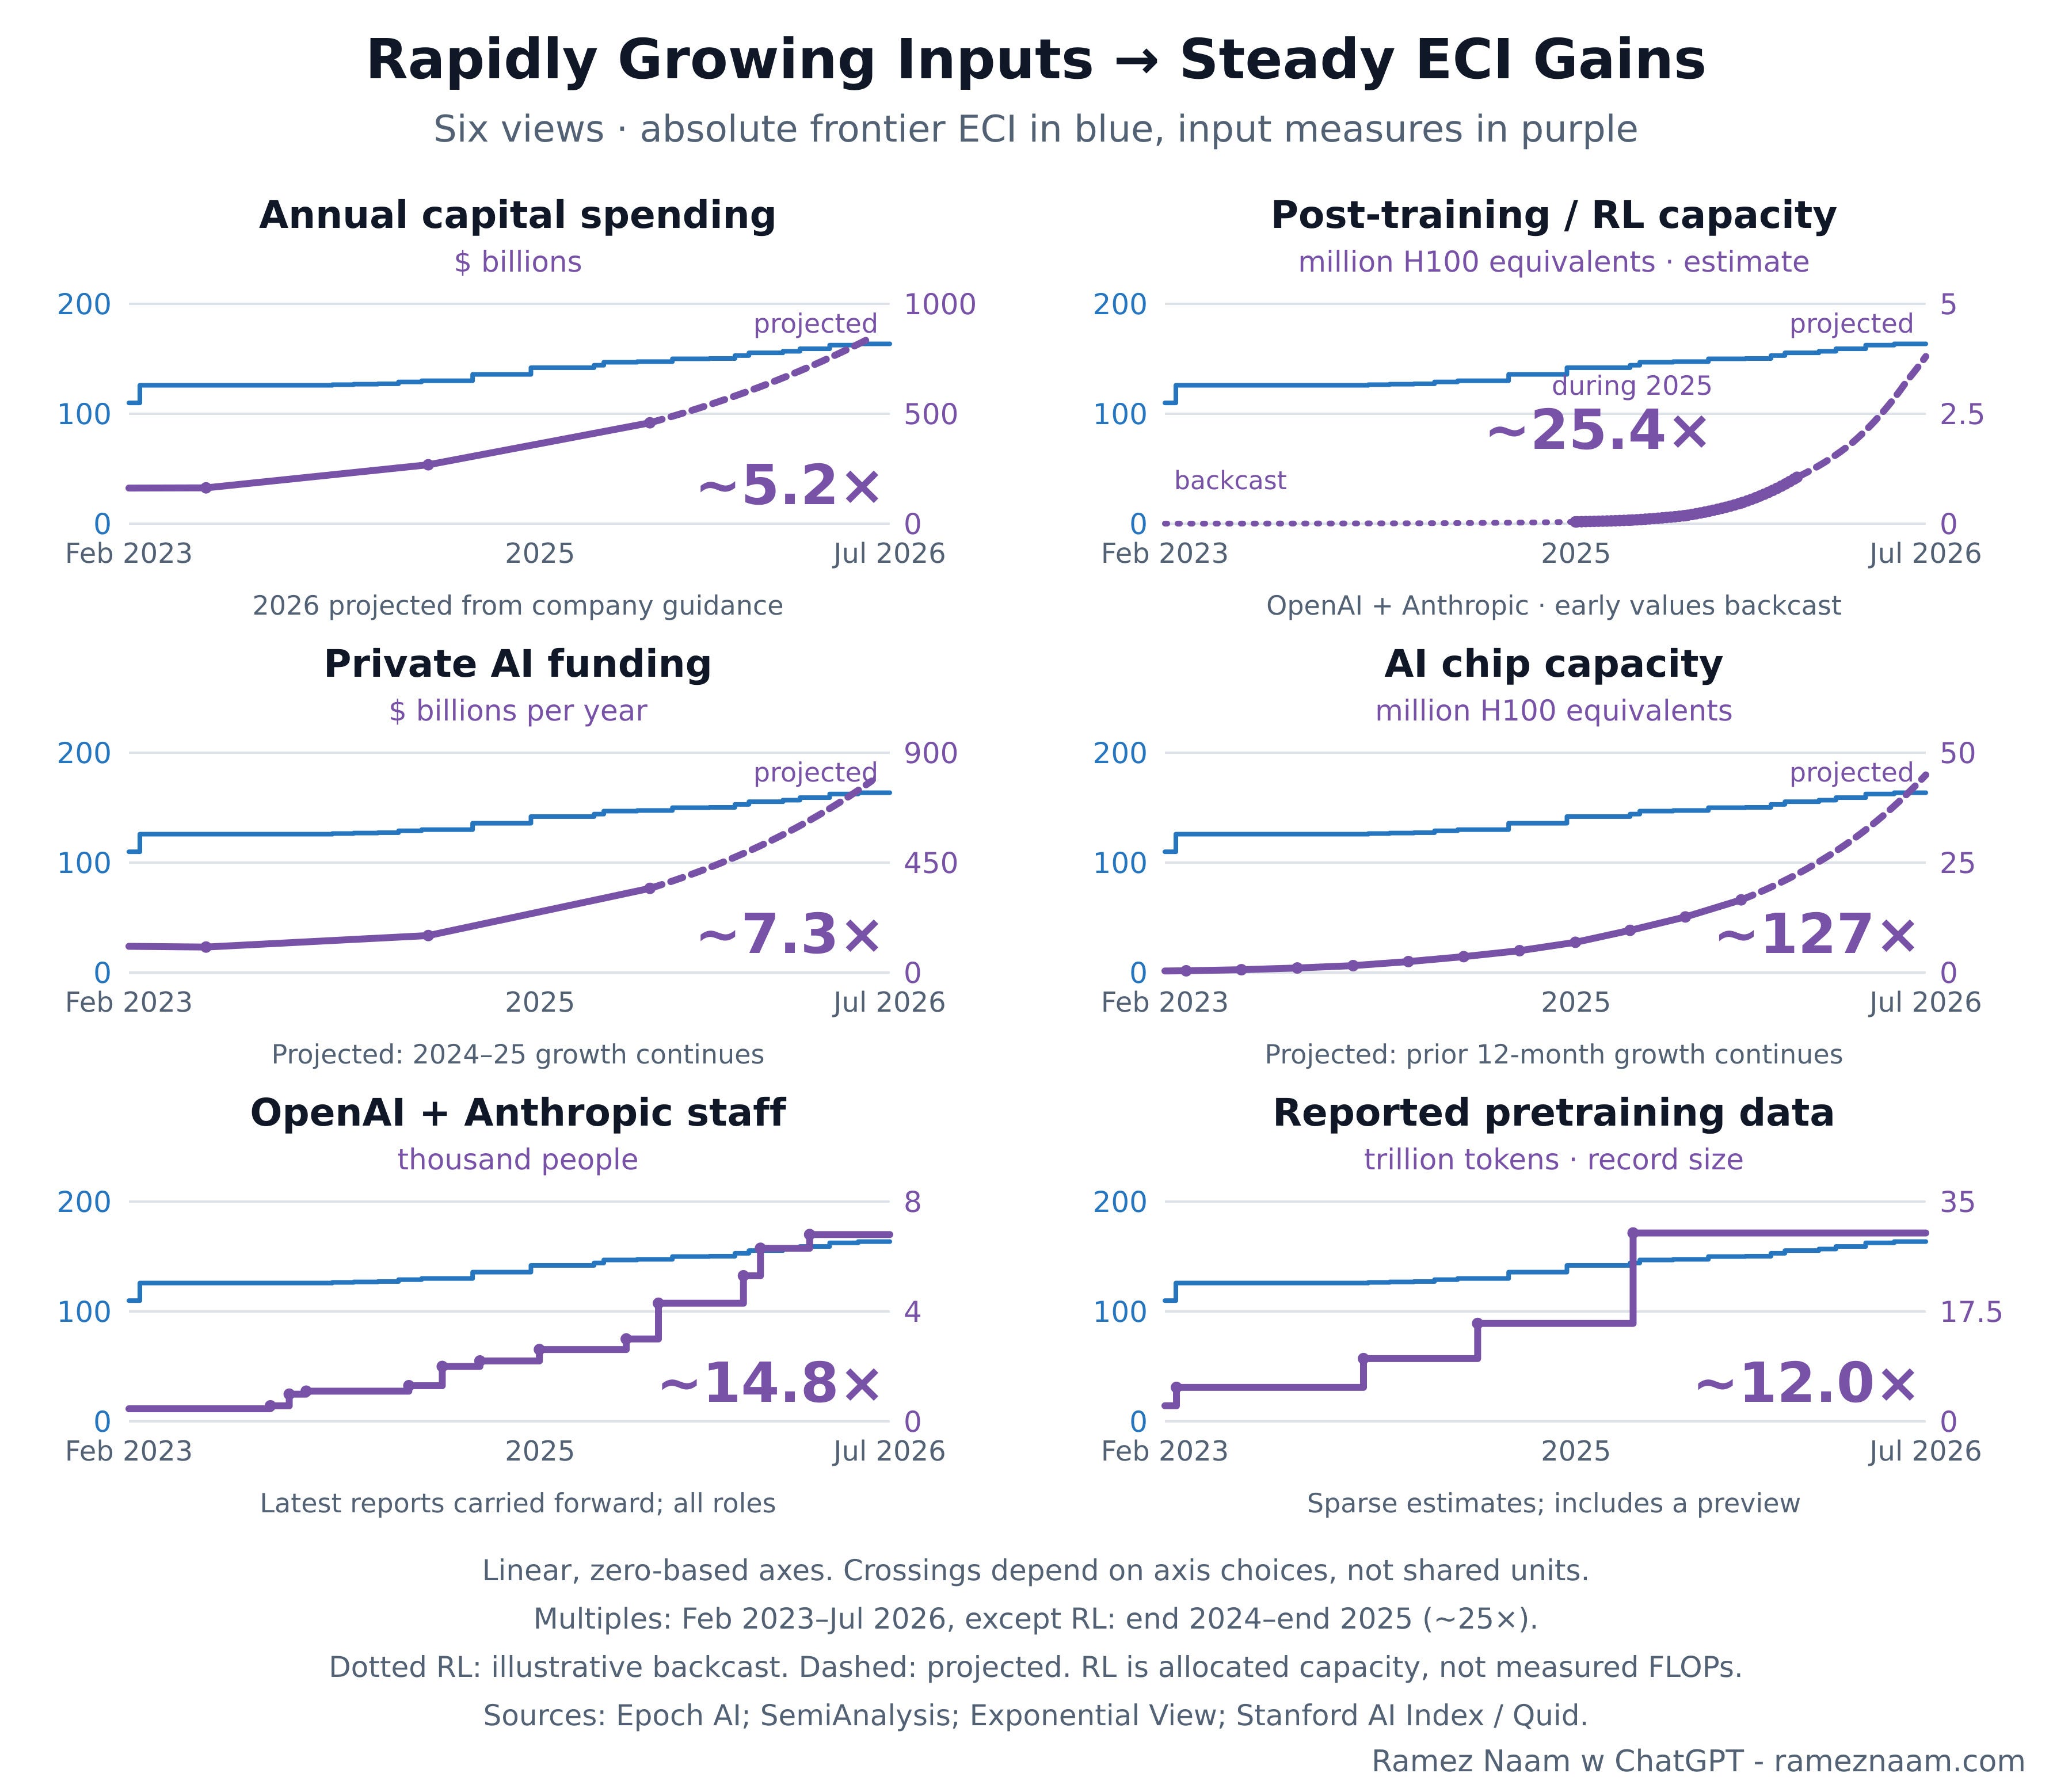
Figure 20. Six inputs alongside frontier ECI. Epoch chip data · SemiAnalysis workload shares.
Everywhere we look, AI has diminishing returns. It gets more expensive in treasure and talent to make each step forward. More of every input has been required to maintain steady gains in AI capabilities.
We’ve been able to scale these inputs because, until recently, the cost was within the scope of what hyperscalers could pay from their profits. That is no longer the case. From this point forward, future AI investment will increasingly depend on AI revenues going up. And the scale of the numbers - 3% of US GDP is now going into AI infrastructure - suggests that eventually the growth rate will decline. If investment growth does slow, to anything less than its current blistering exponential pace, capability progress could slow too. Even if investment growth continues (which I expect for the foreseeable future) a slowdown from its current exponential growth rate to a more modest one (which I also expect) could lead to a slower pace of progress. Better AI research tools may be needed to offset that.
The day when we need better AI tools just to continue the pace of AI progress may already have arrived. Not because investment is slowing, but because the problem of improving AI itself gets harder at each step.
Here’s Anthropic in the Mythos 5.1 system card:
“we believe that internal usage of recent AI models has been a key factor in maintaining the current rate of progress, but we do not yet see clear signs of dramatic acceleration beyond that rate.”- Anthropic, Claude Fable 5.1 & Claude Mythos 5.1 System Card, section 2.3 – emphasis theirs.
The key word is maintaining-and Anthropic italicized that word in its own system card. Increasingly capable AI may be essential just to keep the pace of improvement where it is.
Opus 5.5 improves substantially on several coding and computer use benchmarks. But on CoBench, Anthropic’s benchmark built from historical AI R&D problems, it gains just 2.6 percentage points over Opus 5, within the reported error bars.
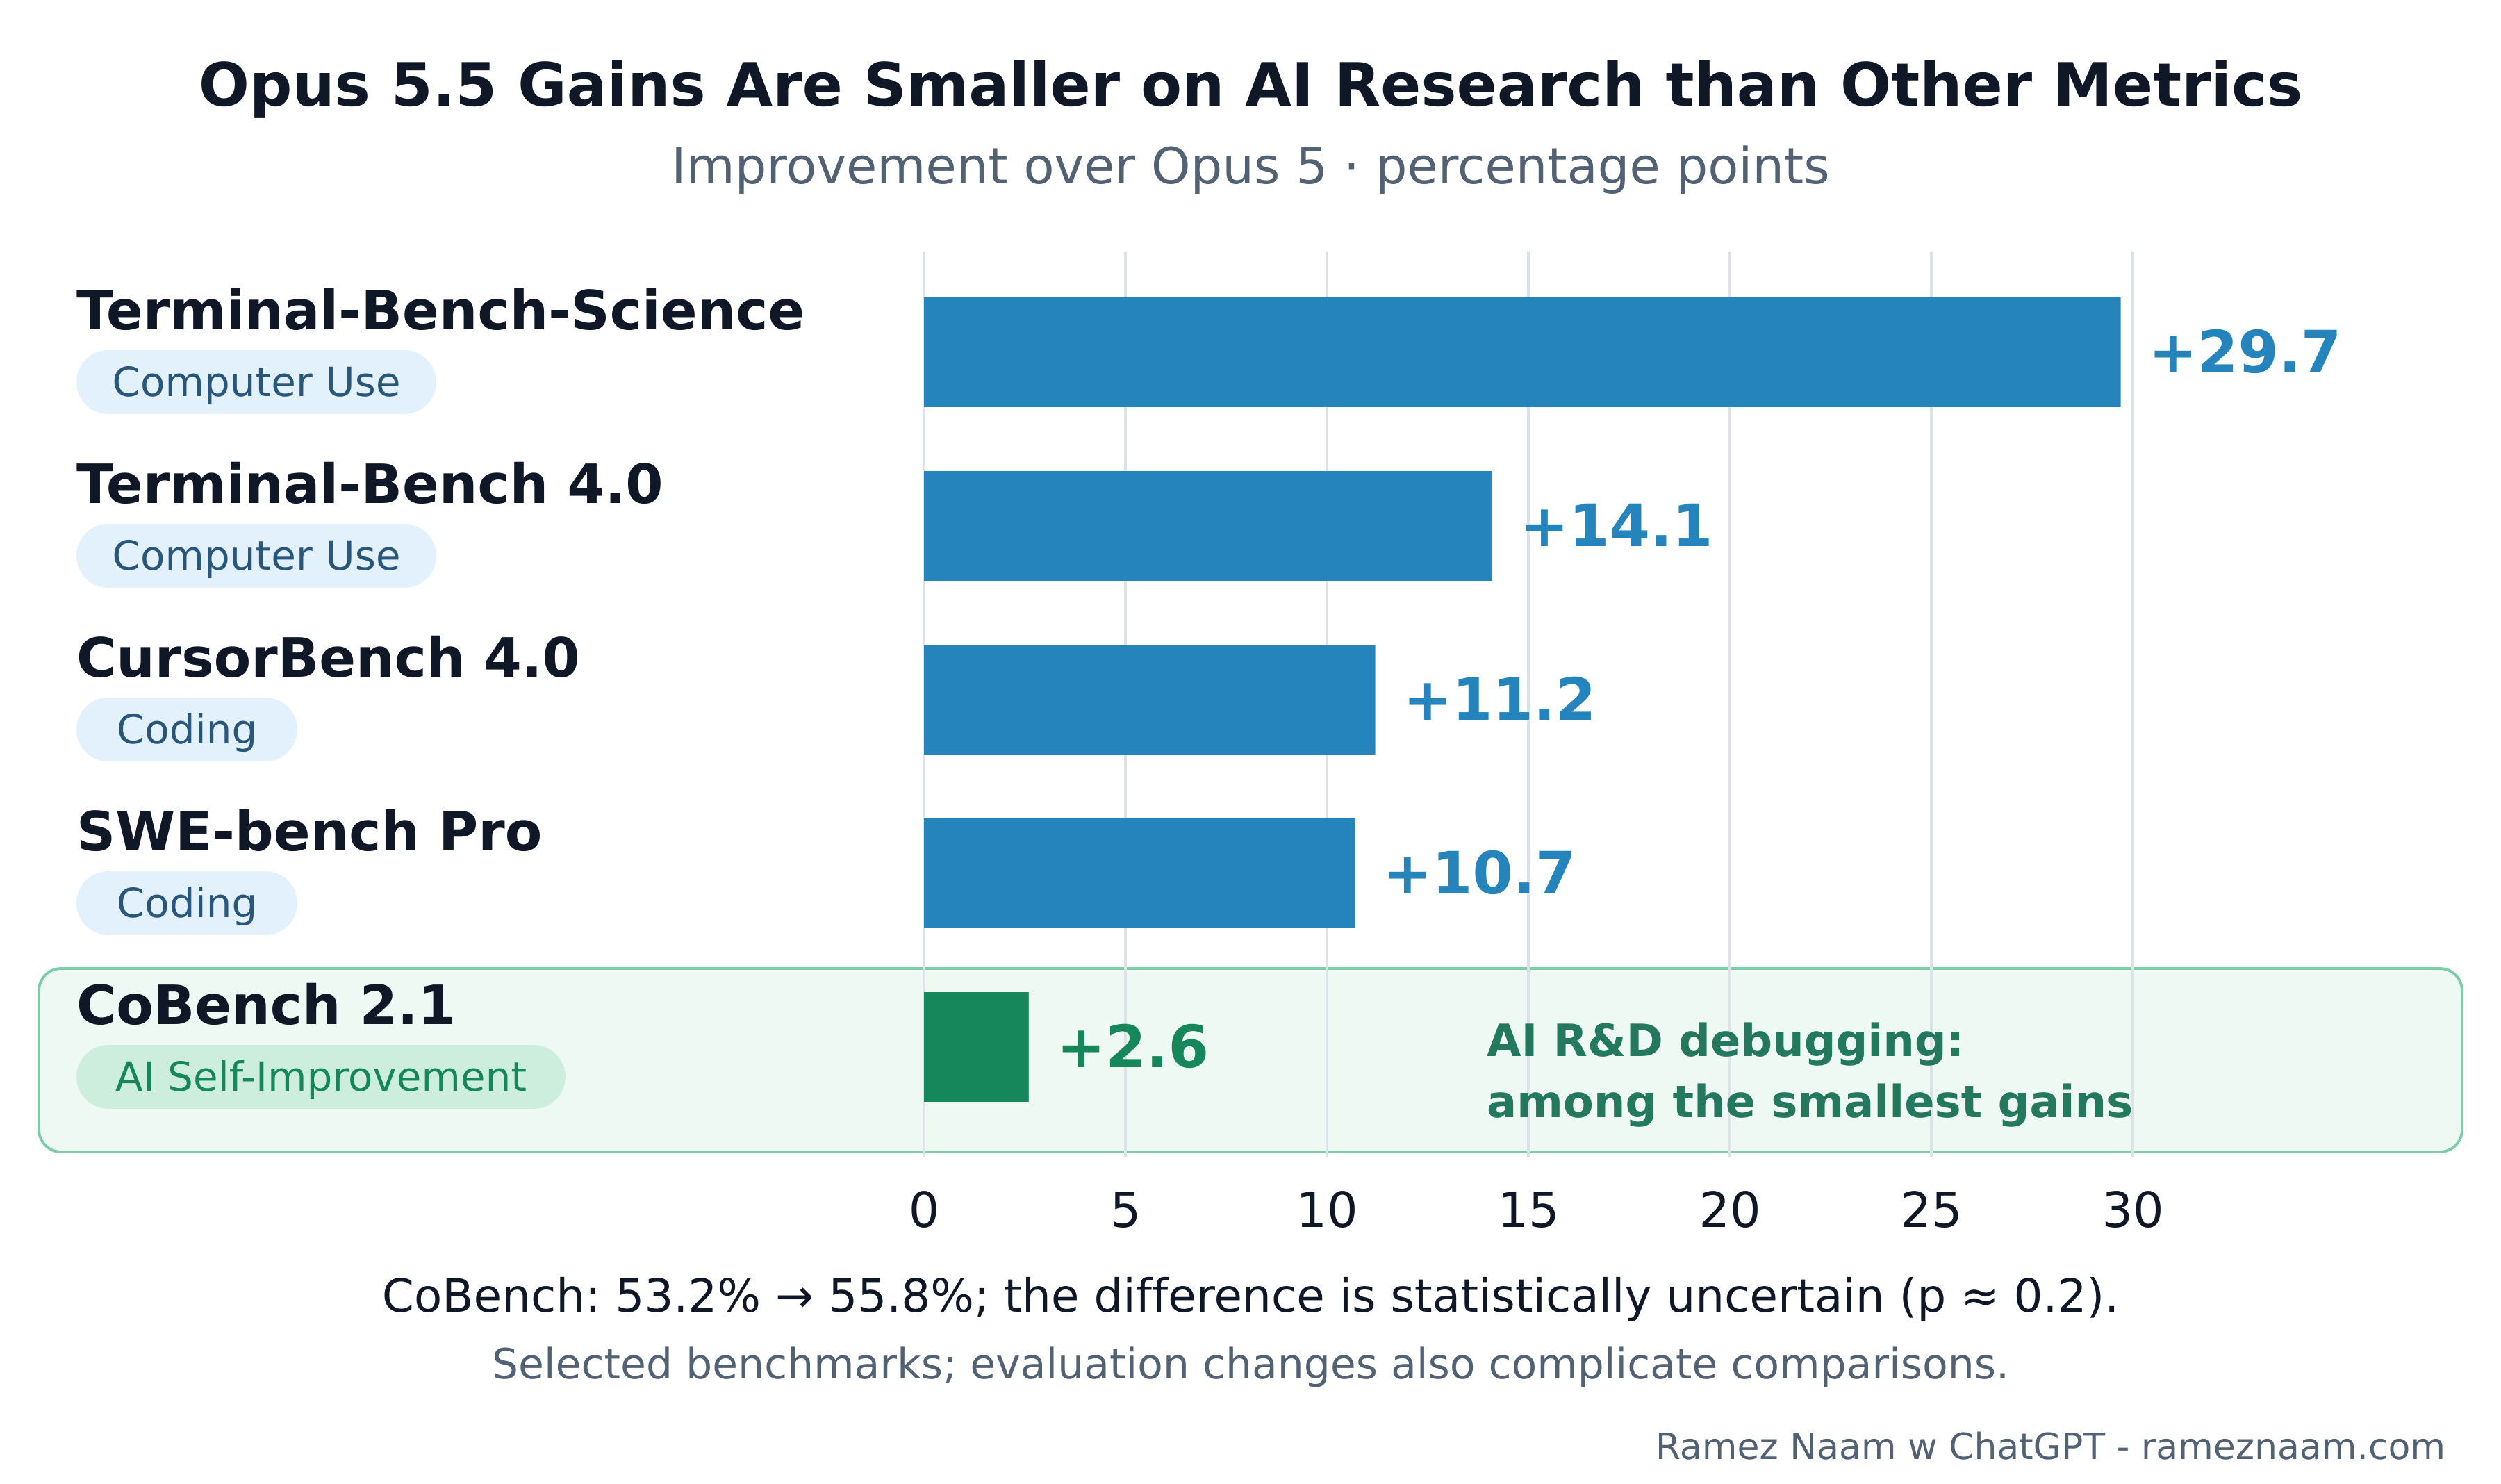
Figure 21. Opus 5.5 benchmark gains. Source.
Why the smaller gain here? Maybe AI research is simply harder than other tasks. Bear in mind that CoBench isn’t testing the ability to produce significant discoveries. It’s much more limited in scope. It asks models to investigate historical AI R&D problems using code, logs, and documents. That’s useful research debugging and productivity work, but it doesn’t directly test whether a model can invent a new architecture or make a conceptual breakthrough.
The evidence on open-ended research suggests another obstacle: coming up with useful ideas that haven’t already been tried.
Why do useful new ideas often get harder to find?
Tom Cunningham and Manish Shetty have a useful apple-picking metaphor. An AI can pick the low-hanging fruit quickly, while humans can still reach ideas the AI can’t.
Once those apples are picked, another copy of the same agent finding them again doesn’t help. A stronger model can reach higher. To add my own flourish, the apples may also get sparser and farther apart as you climb. The RSI question is whether each harvest gives us enough to build a better apple-picker.
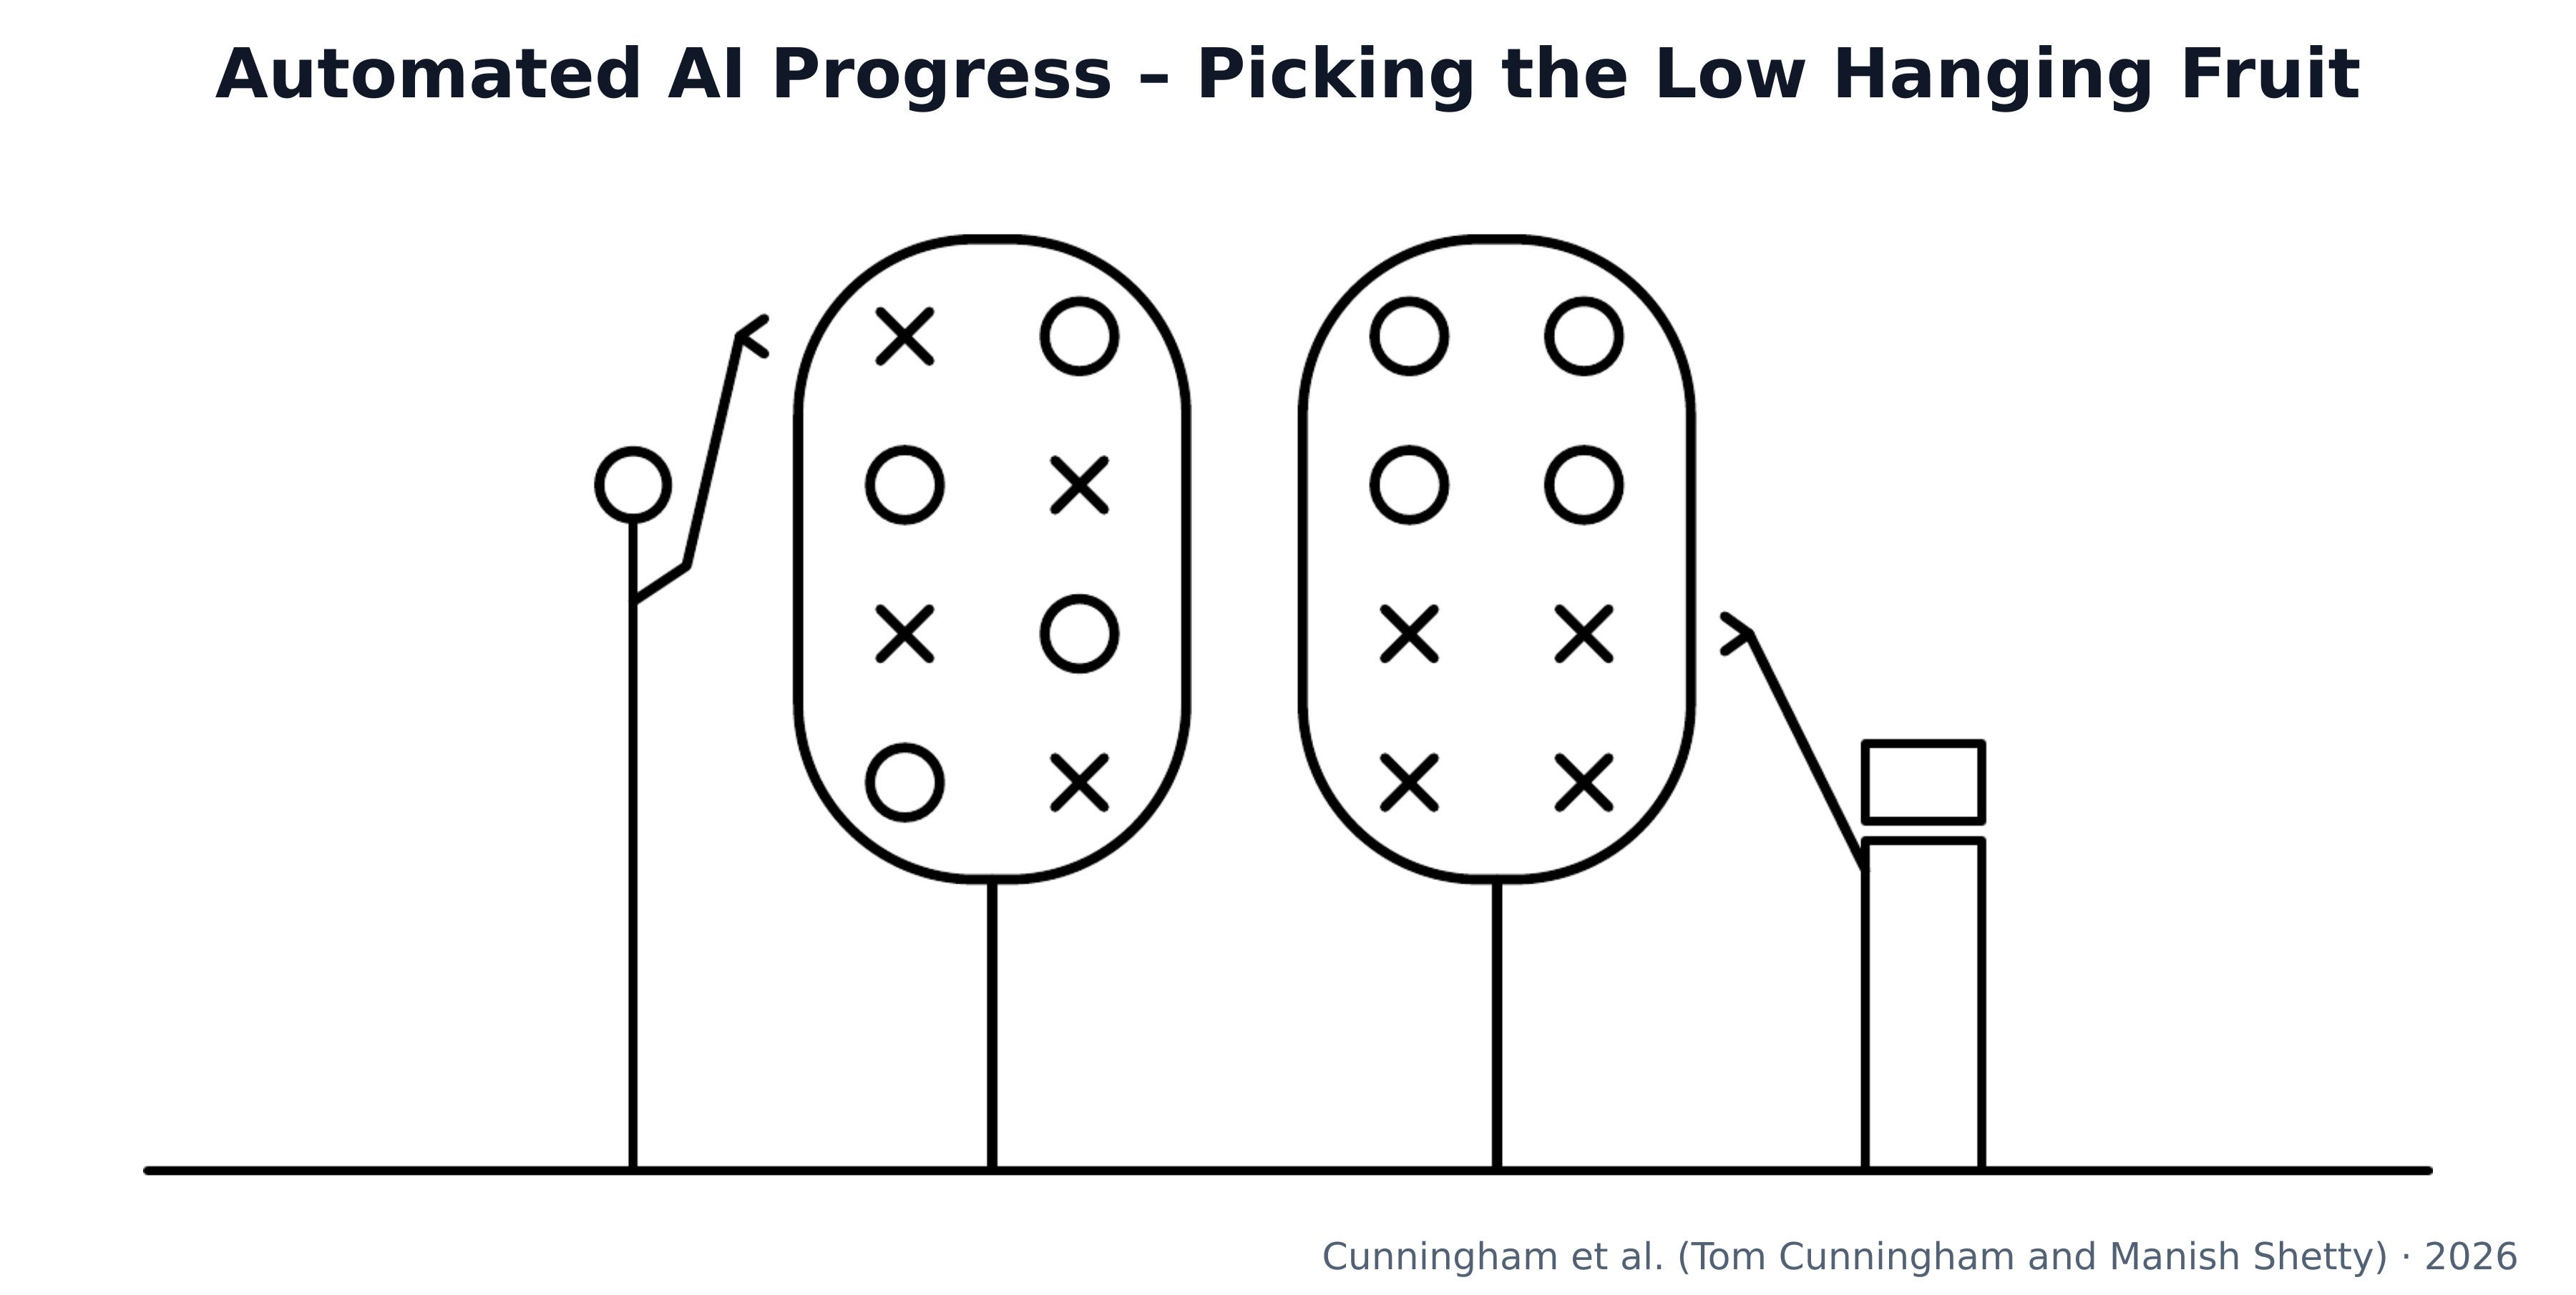
Figure 22. The apple-picking model of AI R&D. Source.
This pattern shows up across R&D. Bloom and colleagues document fields where research effort grows while research productivity falls. A famous example is Eroom’s Law: in the historical drug-development data, the inflation-adjusted R&D cost per new approved drug roughly doubled every nine years.
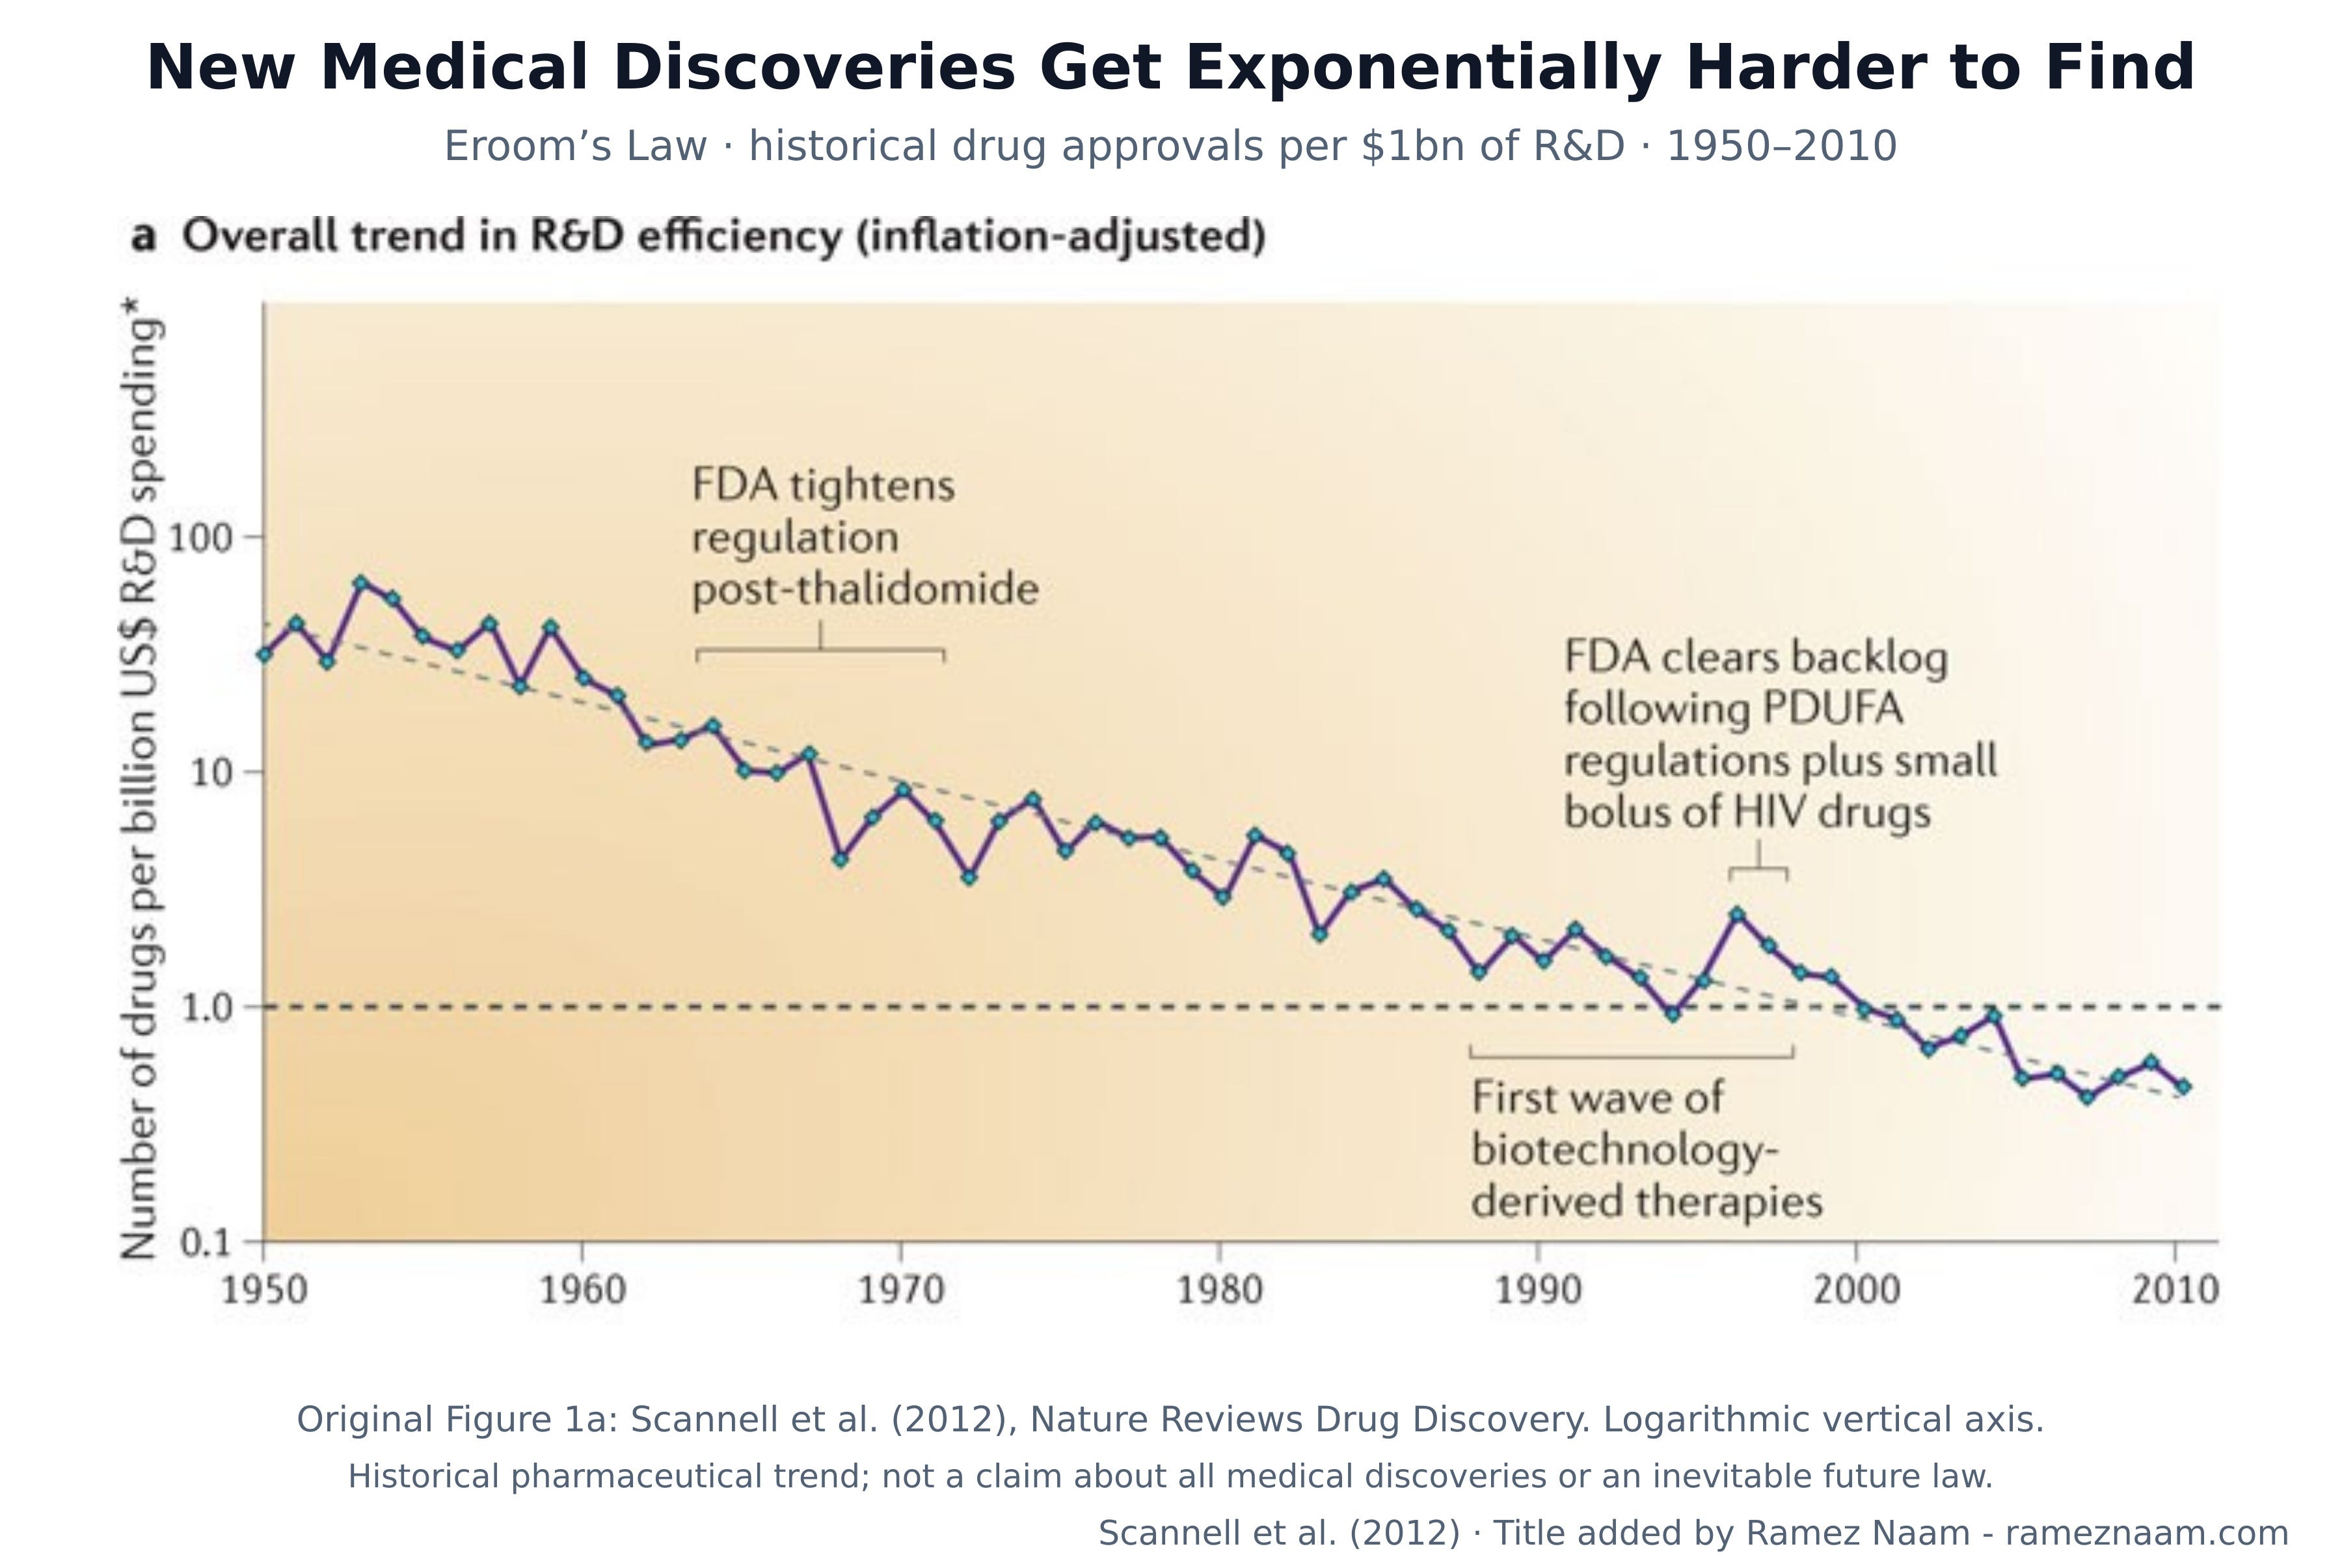
Figure 23. Eroom’s Law in drug development. Source.
Pharma has other complications, including regulation, difficult clinical trials, and rising expectations for safety. Existing treatments can also raise the bar for a useful new drug. But some of this difficulty may also be that the low-hanging fruit has been picked.
Stockfish, the chess engine, gives us a more direct look at software research. We have records of experiments aimed at improving it and the gains that followed. This gives us a real-world dataset to look at the gains of experimentation in software. As a result, several RSI models draw on this data. That said, not all the improvements came from these experiments. Several important ideas also came from outside the project, so we shouldn’t give its experiments all the credit.
Epoch’s analysis of software R&D estimates returns to research effort at about 0.83 for Stockfish, a bit slower than linear. These are diminishing returns, but gentle ones. These returns, however, are improvements in computational efficiency. And more compute does not turn directly into more AI capability. As we saw earlier, AI capability also has steep diminishing returns from adding more computational power. So we shouldn’t read that 0.83 as the return from experimentation to AI capability itself. AI capability grows much more slowly than compute, as we’ve seen already.
Andrej Karpathy’s autoresearch demonstration gets closer to the process we want to understand. A “teacher” AI agent changes a smaller “student” AI model’s training code, runs it, checks the result, and tries again. The teacher agent itself doesn’t improve, but it is able to improve the “learner”. This is my Type 2: A stronger AI improves a weaker one.
One public run, posted by an agent operating on Karpathy’s behalf, reported 89 experiments over roughly 7.5 hours. About 92% of that session’s gain arrived by run 44. Gains came quickly, then slowed. The setup was deliberately small, with a five-minute training budget per experiment. But the agent could change the architecture, optimizer, and training settings; it wasn’t limited to a handful of knobs.
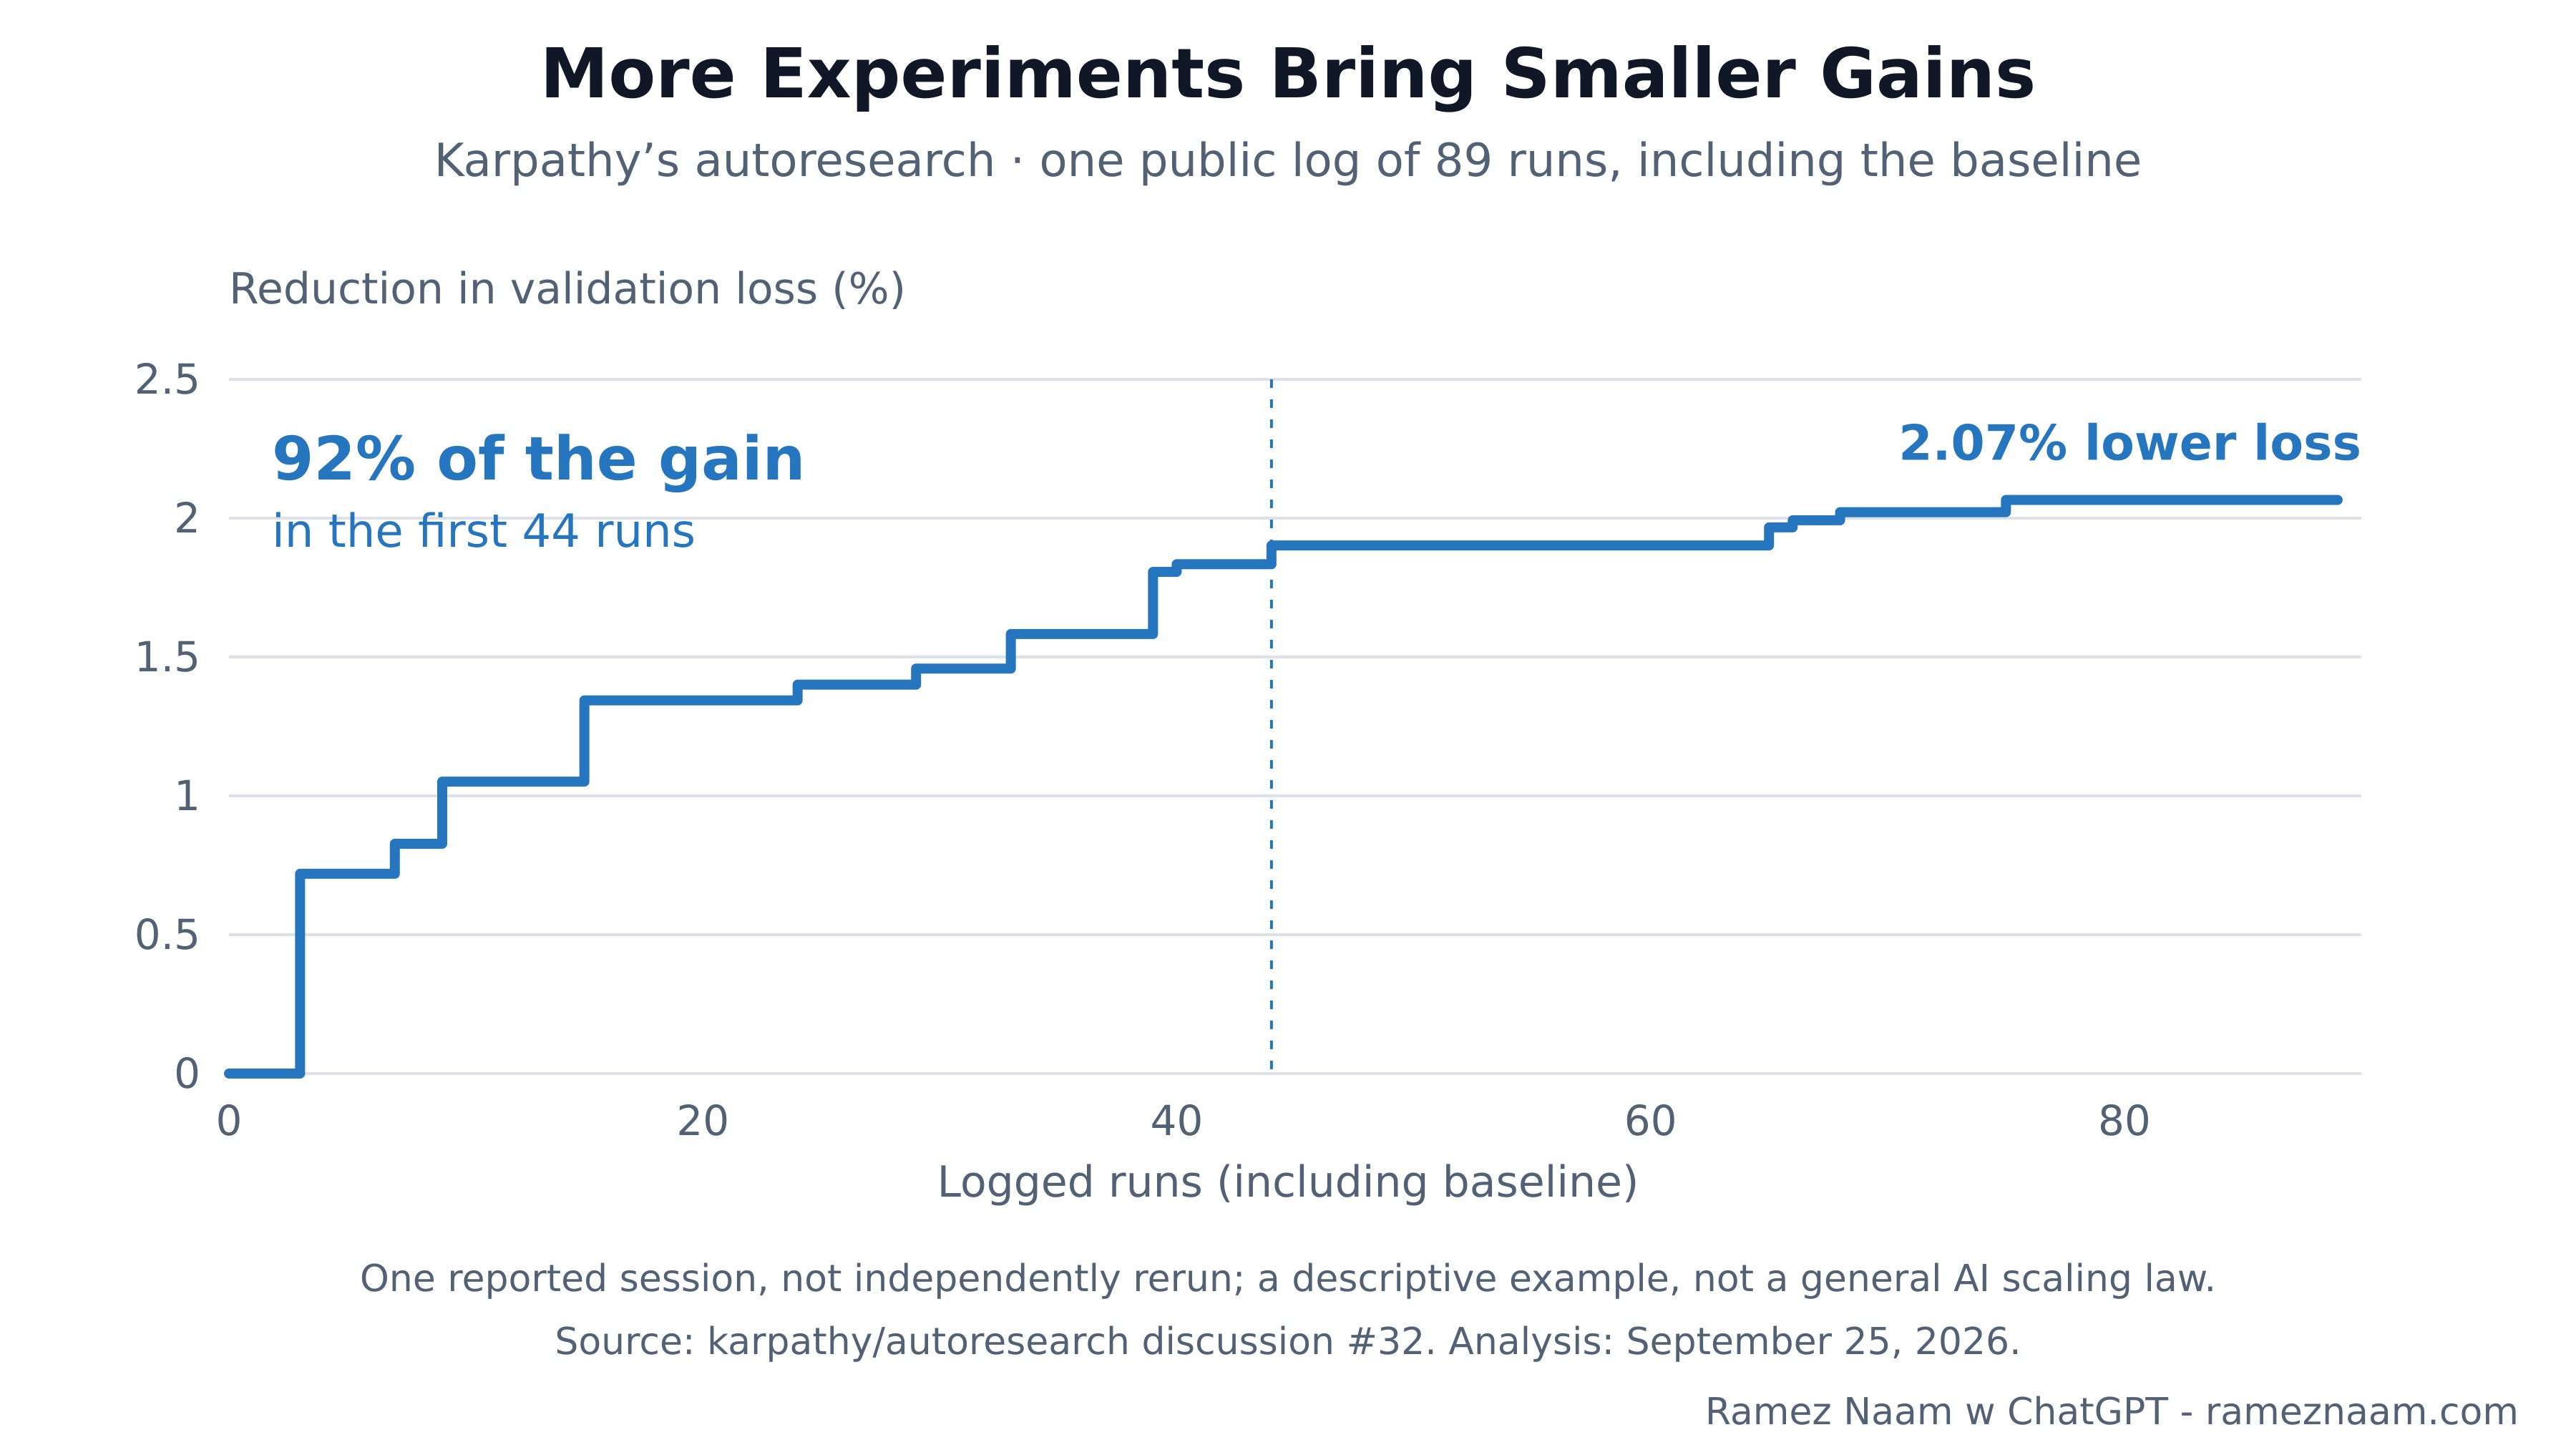
Figure 24. Gains in one autoresearch run. Source.
A later public run got further, so the first run hadn’t hit a hard ceiling. This is a useful early example of autonomous research, and yet another place where we see the diminishing returns endemic in AI research. That said, this was a very early experiment. I expect future systems to do much better. This particular AI improvement loop will likely grow stronger.
This is where the distinction matters. More tokens can buy more code, and more code can help us run more experiments. But experiments only improve AI if they uncover something useful.
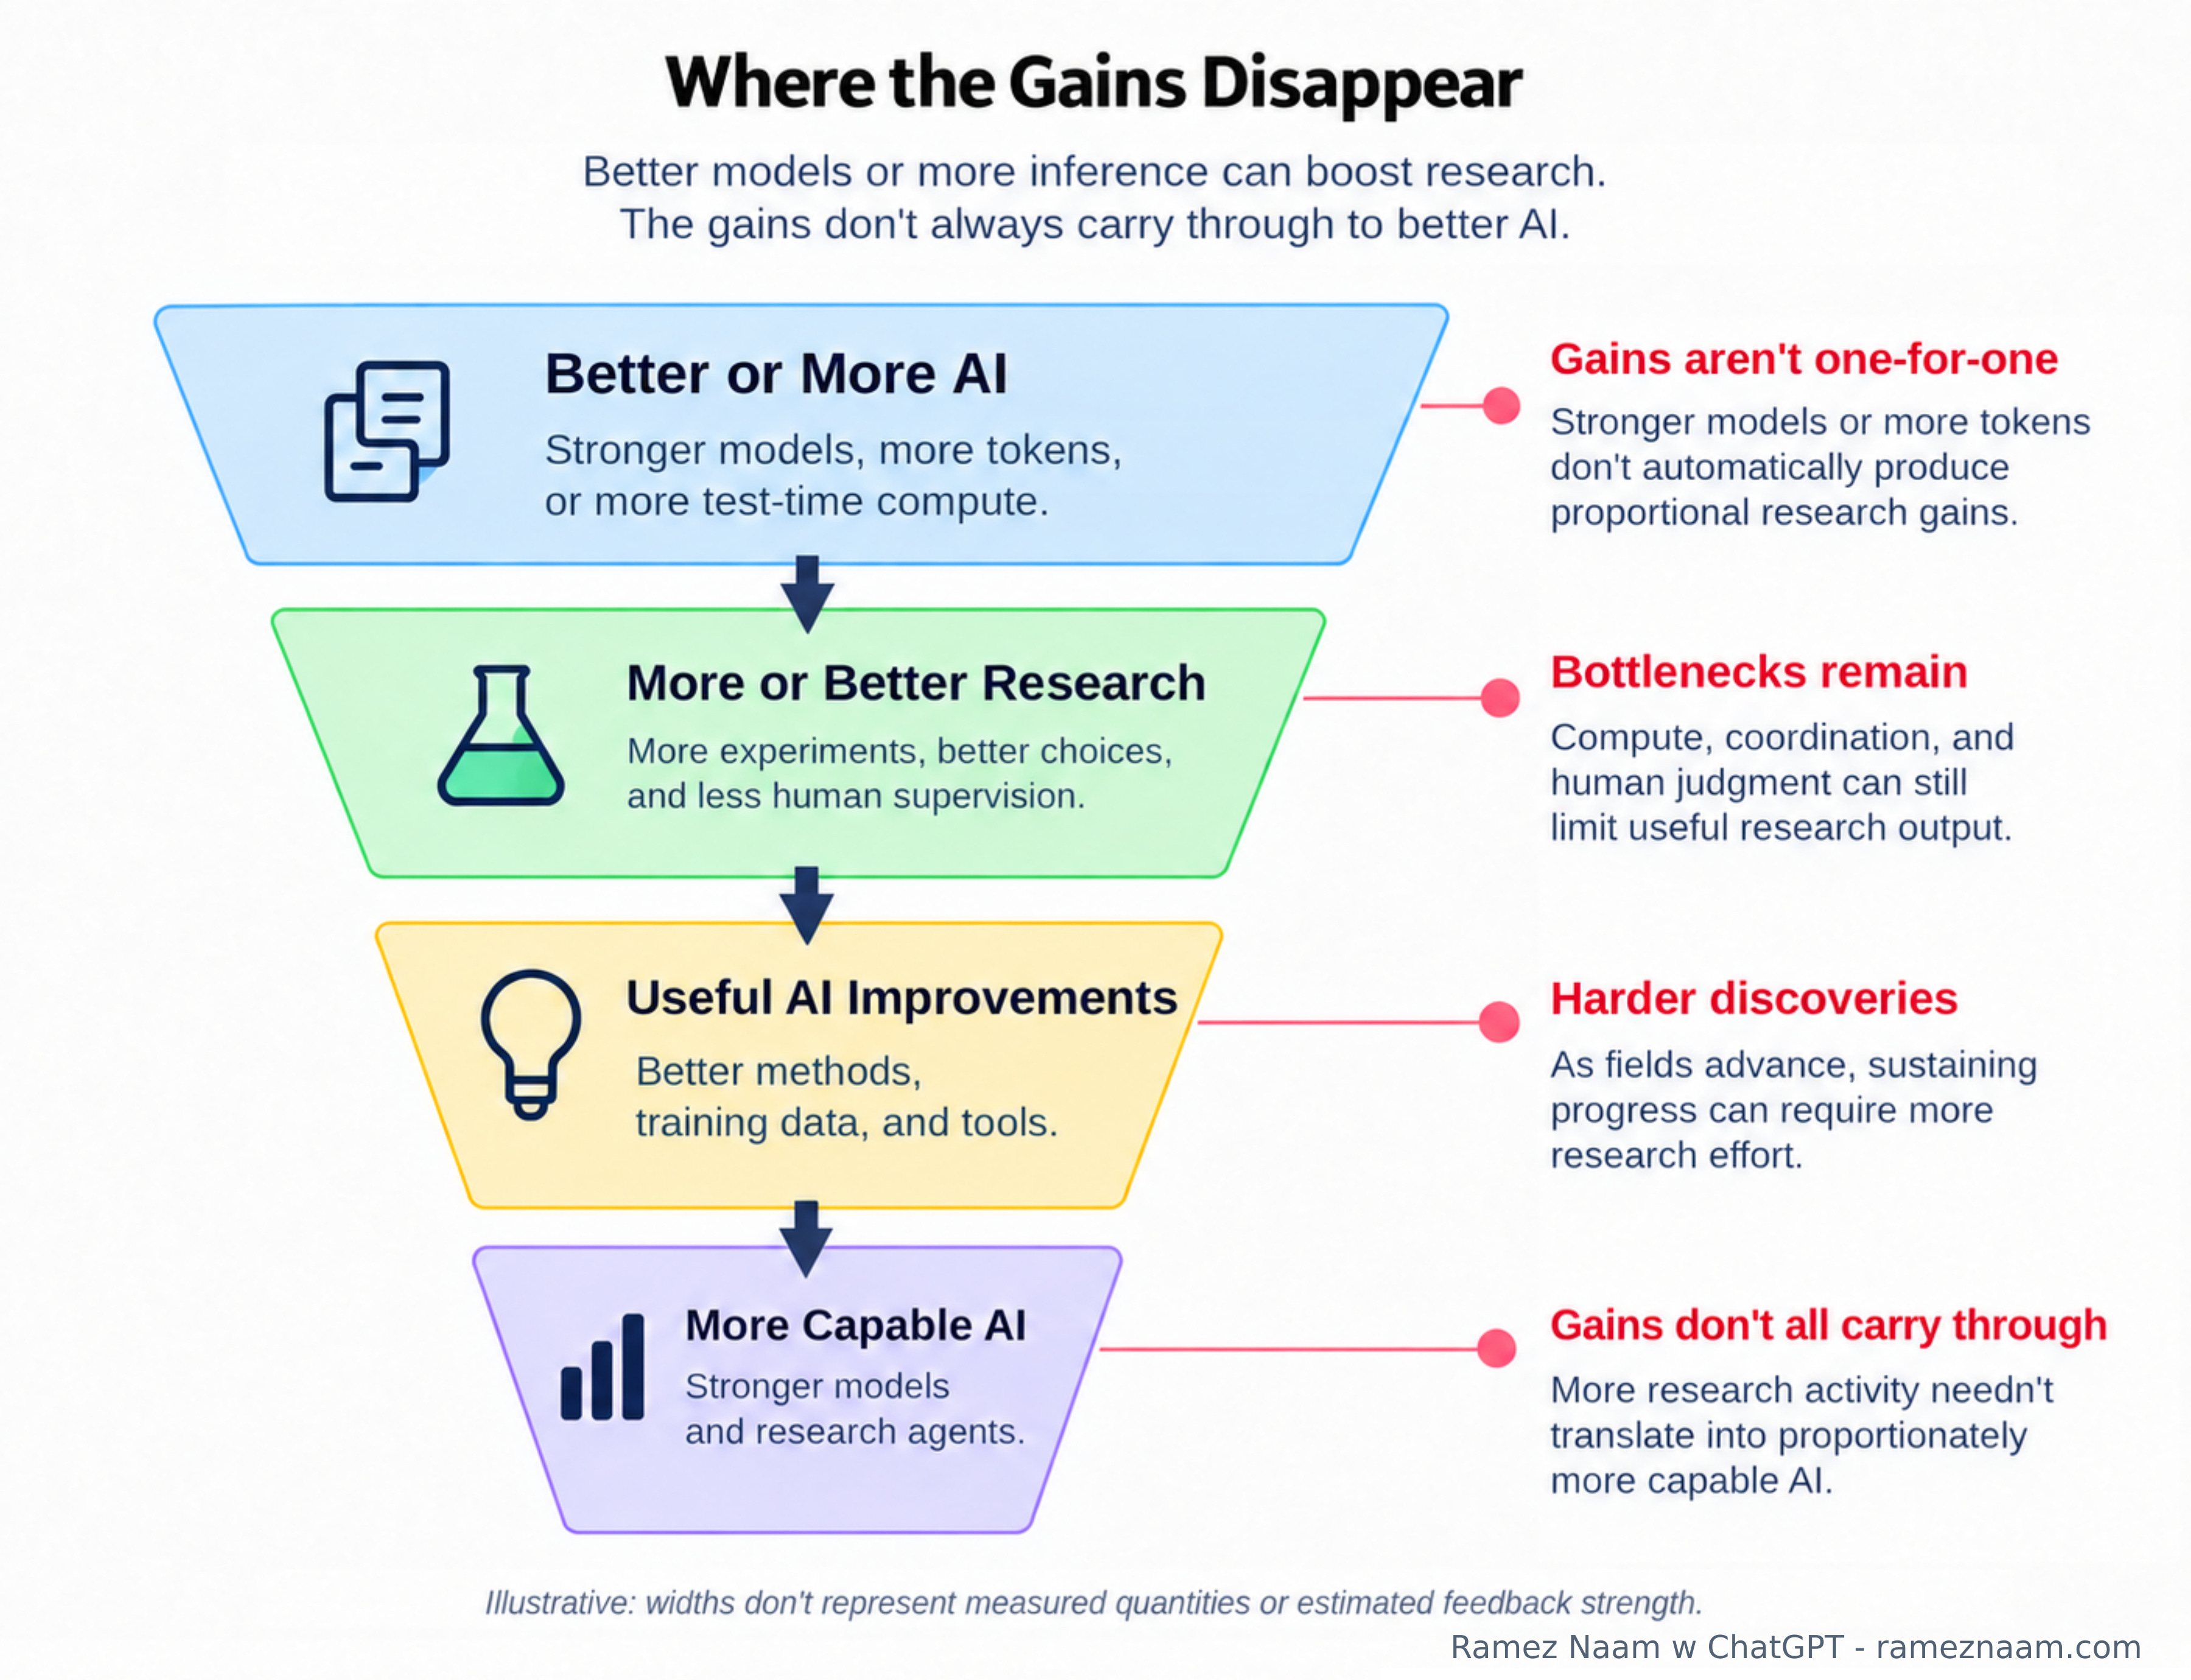
Figure 25. From AI activity to useful improvements.
The bigger question is whether AI can come up with ambitious new research ideas or conceptual breakthroughs.
Anthropic’s description of Opus 5.5 is blunt:
“As with previous models, it is weaker on open-ended research: internal users report that it mostly tests incremental ideas and prefers less ambitious hypotheses, and in our human-run biology exercise, it deferred to the published literature and struggled to develop novel ideas (Section 2.2.2).”- Anthropic, Claude Opus 5.5 System Card, section 2.3.3; emphasis mine
METR’s assessment in the same card identifies what may still be missing:
“This is highly uncertain, but we expect that full automation of AI R&D will require large improvements in foresight, prediction, creating one’s own feedback loops, and generally other skills that might typically be referred to as researcher ‘judgement’ or ‘taste’.”- METR, quoted in the Claude Opus 5.5 System Card, section 2.3.6
In these examples, humans still supply much of the direction and judgment.
Future models will probably get better at this. But in the world’s stockpile of potential training data, we have many more examples of incremental work than of breakthroughs. I wonder whether that makes novelty harder to learn. That’s speculation, but worth watching.
This is also tough to address by simply running more copies of the AI. A huge number of parallel agents can help with the incremental improvements or searching over a large set of parameters, but for breakthrough ideas they may run into the homogeneity problem: More parallel agents still think alike.
How far are we from the self-improvement loop being strong enough to sustain itself, or to propel itself into runaway super-intelligence? Can we quantify this?
We can make a rough estimate. Better AI helps with research; useful research produces better AI. For the loop to sustain itself, each round must produce enough gains to propel the system through the next loop, even as improvements get harder to discover.
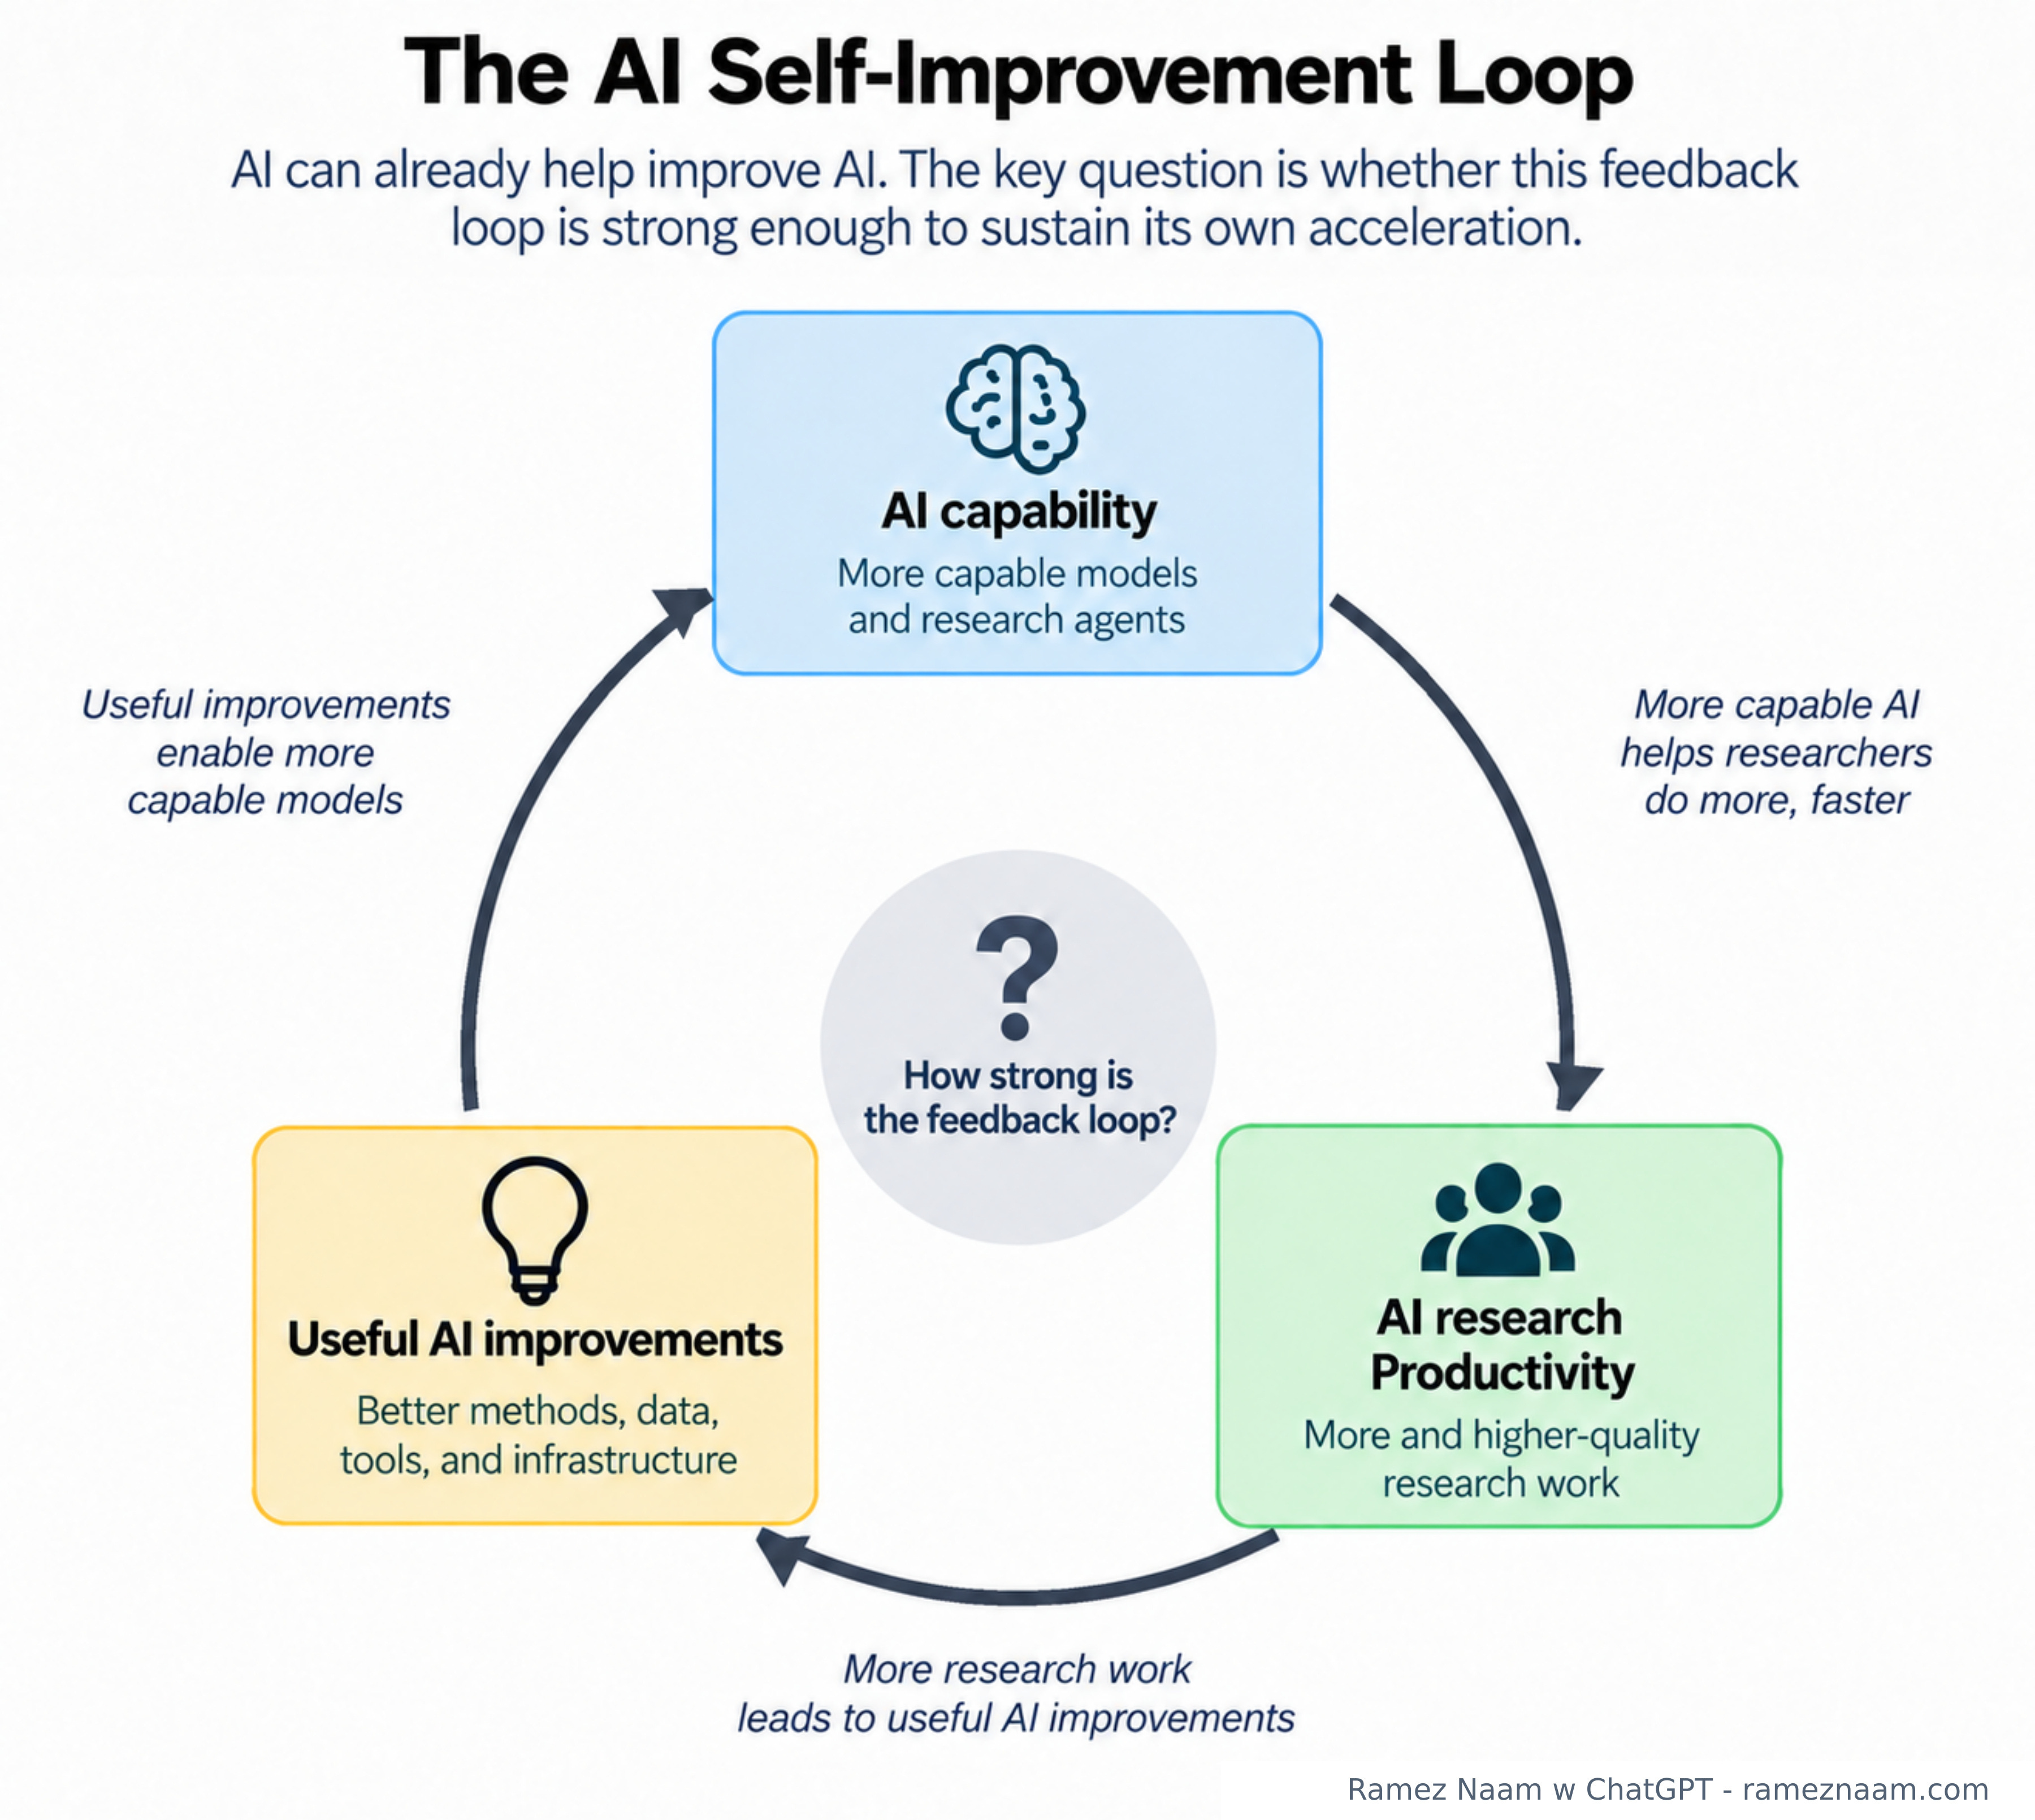
Figure 26. The AI self-improvement loop. Model.
In a recent paper, The Economics of Recursive Self-Improvement, Tom Cunningham and colleagues modeled this from the standpoint of how much more productivity every point of additional ECI produces from an AI. They ask first and foremost what that number would need to be to create a self-sustaining feedback loop. And secondly, they try to determine what that productivity-per-ECI-point number is today.
First, they find a self-sustaining RSI threshold of roughly 15% more research productivity per extra ECI point. In their model, that’s about where better AI would generate enough progress to sustain the loop.
The picture below shows the idea. At the threshold, each cycle of gains powers the next. Above the threshold, the feedback loop accelerates. Below the threshold, the feedback loop is too weak, and the rate of improvement it brings drops on each cycle. This model isolates the software loop; outside investment can still drive rapid progress.
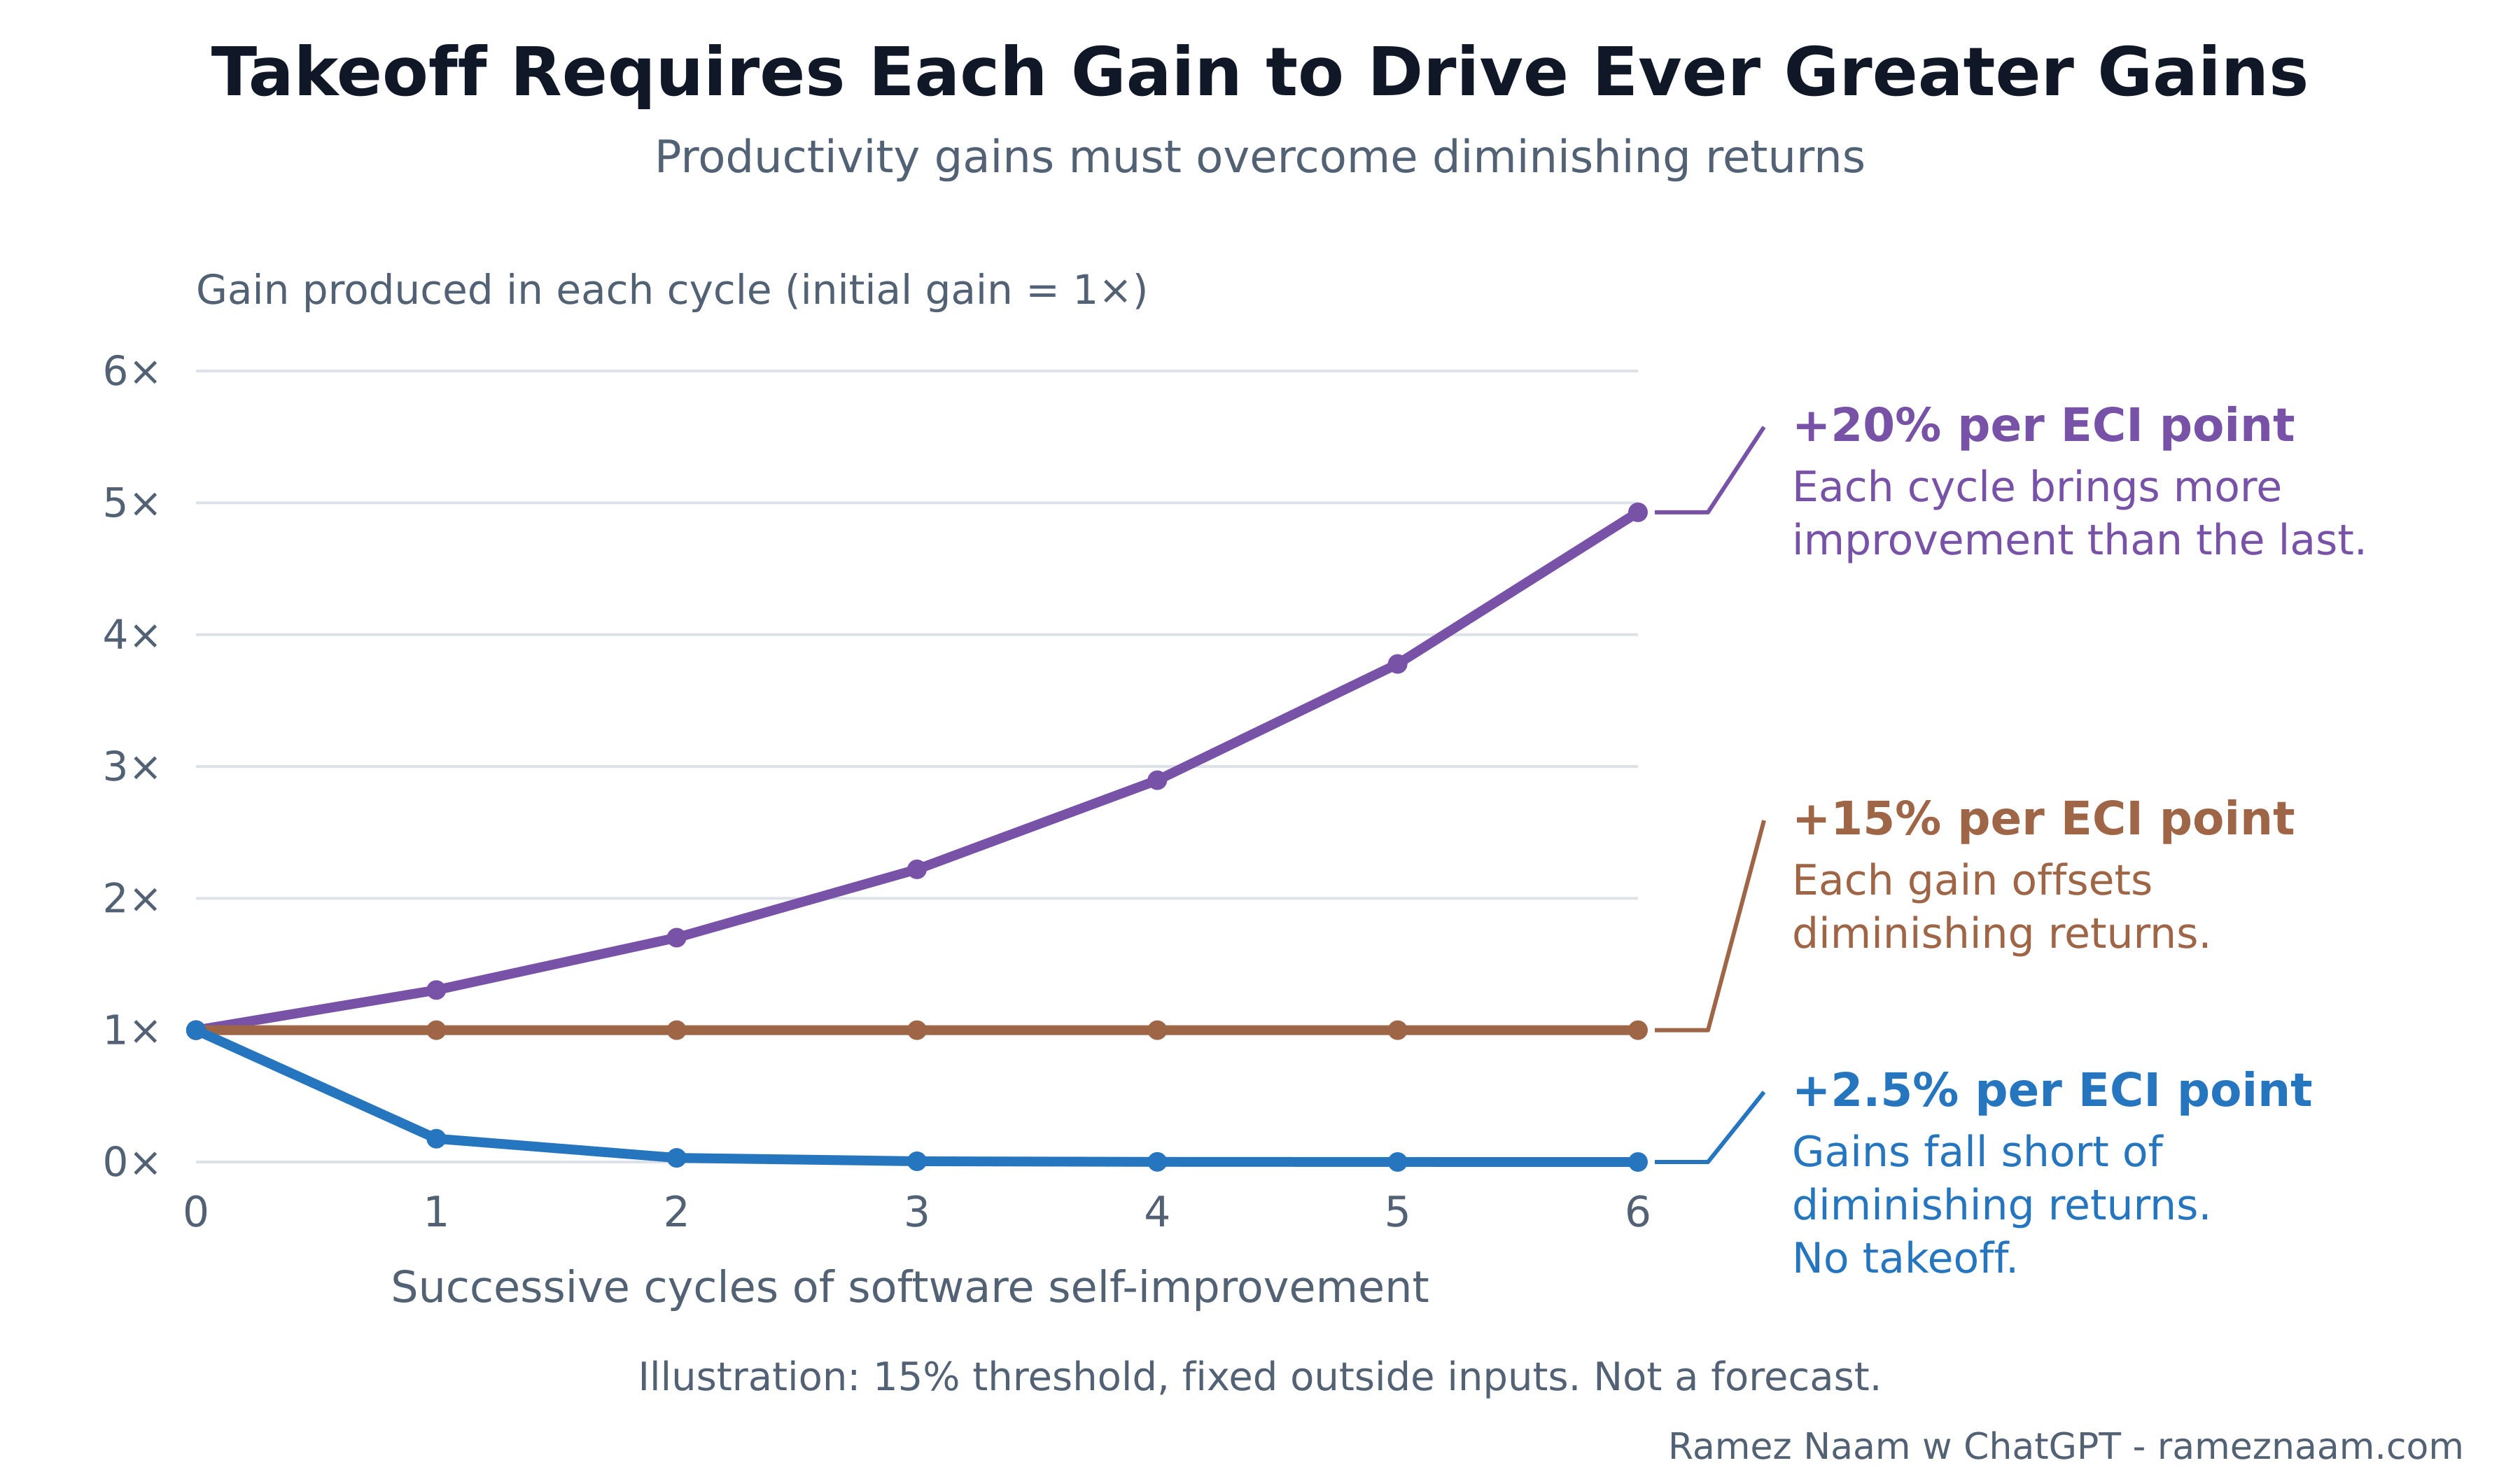
Figure 27. Three illustrative feedback paths. Source.
Updating this slightly with data from the Stockfish experiments puts the threshold a little higher, at roughly 19% per ECI point. I wouldn’t put much weight on that precise difference. Both estimates are uncertain. But they give us a way to think about the strength of the feedback loop and a rough band at which self-sustaining or runaway RSI may begin.
The second thing Cunningham and team do is make a rough estimate that the current AI productivity gain is about 9% per ECI point. That’s below their self-sustaining threshold.
I like the model. OpenAI’s newer data, however, suggests the loop may be quite a bit weaker.
Cunningham’s estimate of 9% productivity gain per ECI point is based on Anthropic’s survey of 130 staff, who reported roughly 4× the productivity they’d have without AI. Cunningham and colleagues compare that with a 16-point capability gain since early Claude Code.
That comparison assumes the earlier tools added little or no productivity, so ‘no AI’ is a reasonable starting point. The authors say this explicitly. I’m not sure the assumption holds for the same researchers doing the same work, but that’s a smaller issue.
The authors themselves know that this is a rough calculation, and warn that the 4× survey estimate is probably too high.
OpenAI’s newer data gives us a firmer way to check the number: Actual logged experiments over time, rather than human estimates of their own productivity with and without AI. I put more weight on this for three reasons:
Direct and broad measurement. Instead of relying on surveys, OpenAI actually tracked and measured experiments run on their infrastructure. That means they didn’t rely on researchers estimating their own productivity, which can be far off.
Full sample, not opt-in. Similarly, OpenAI’s data catches every active experimenter, while Anthropic’s only reflects the 130 employees who took the time to answer the survey – and who therefore may not be a representative set.
Enormously more data. We don’t know how many experiments are in the 32 weeks of OpenAI data, but it’s likely at least tens of thousands of individual examples and possibly hundreds of thousands.
Any way you slice it, the new OpenAI data, released after Cunningham’s paper was drafted, is a larger, more comprehensive, more representative, and almost certainly more accurate dataset than Anthropic’s internal opt-in survey of employees.
Now let’s use OpenAI’s experiment data to calibrate the productivity gain per ECI point. We know that in August, OpenAI researchers ran ~1.6× as many experiments per person per month as the 2025 average. If we pair that with roughly 16 points of frontier ECI improvement, it works backward to about 3% productivity gain per point of ECI. By contrast, 9% compounded over 16 points would mean roughly 4× productivity.
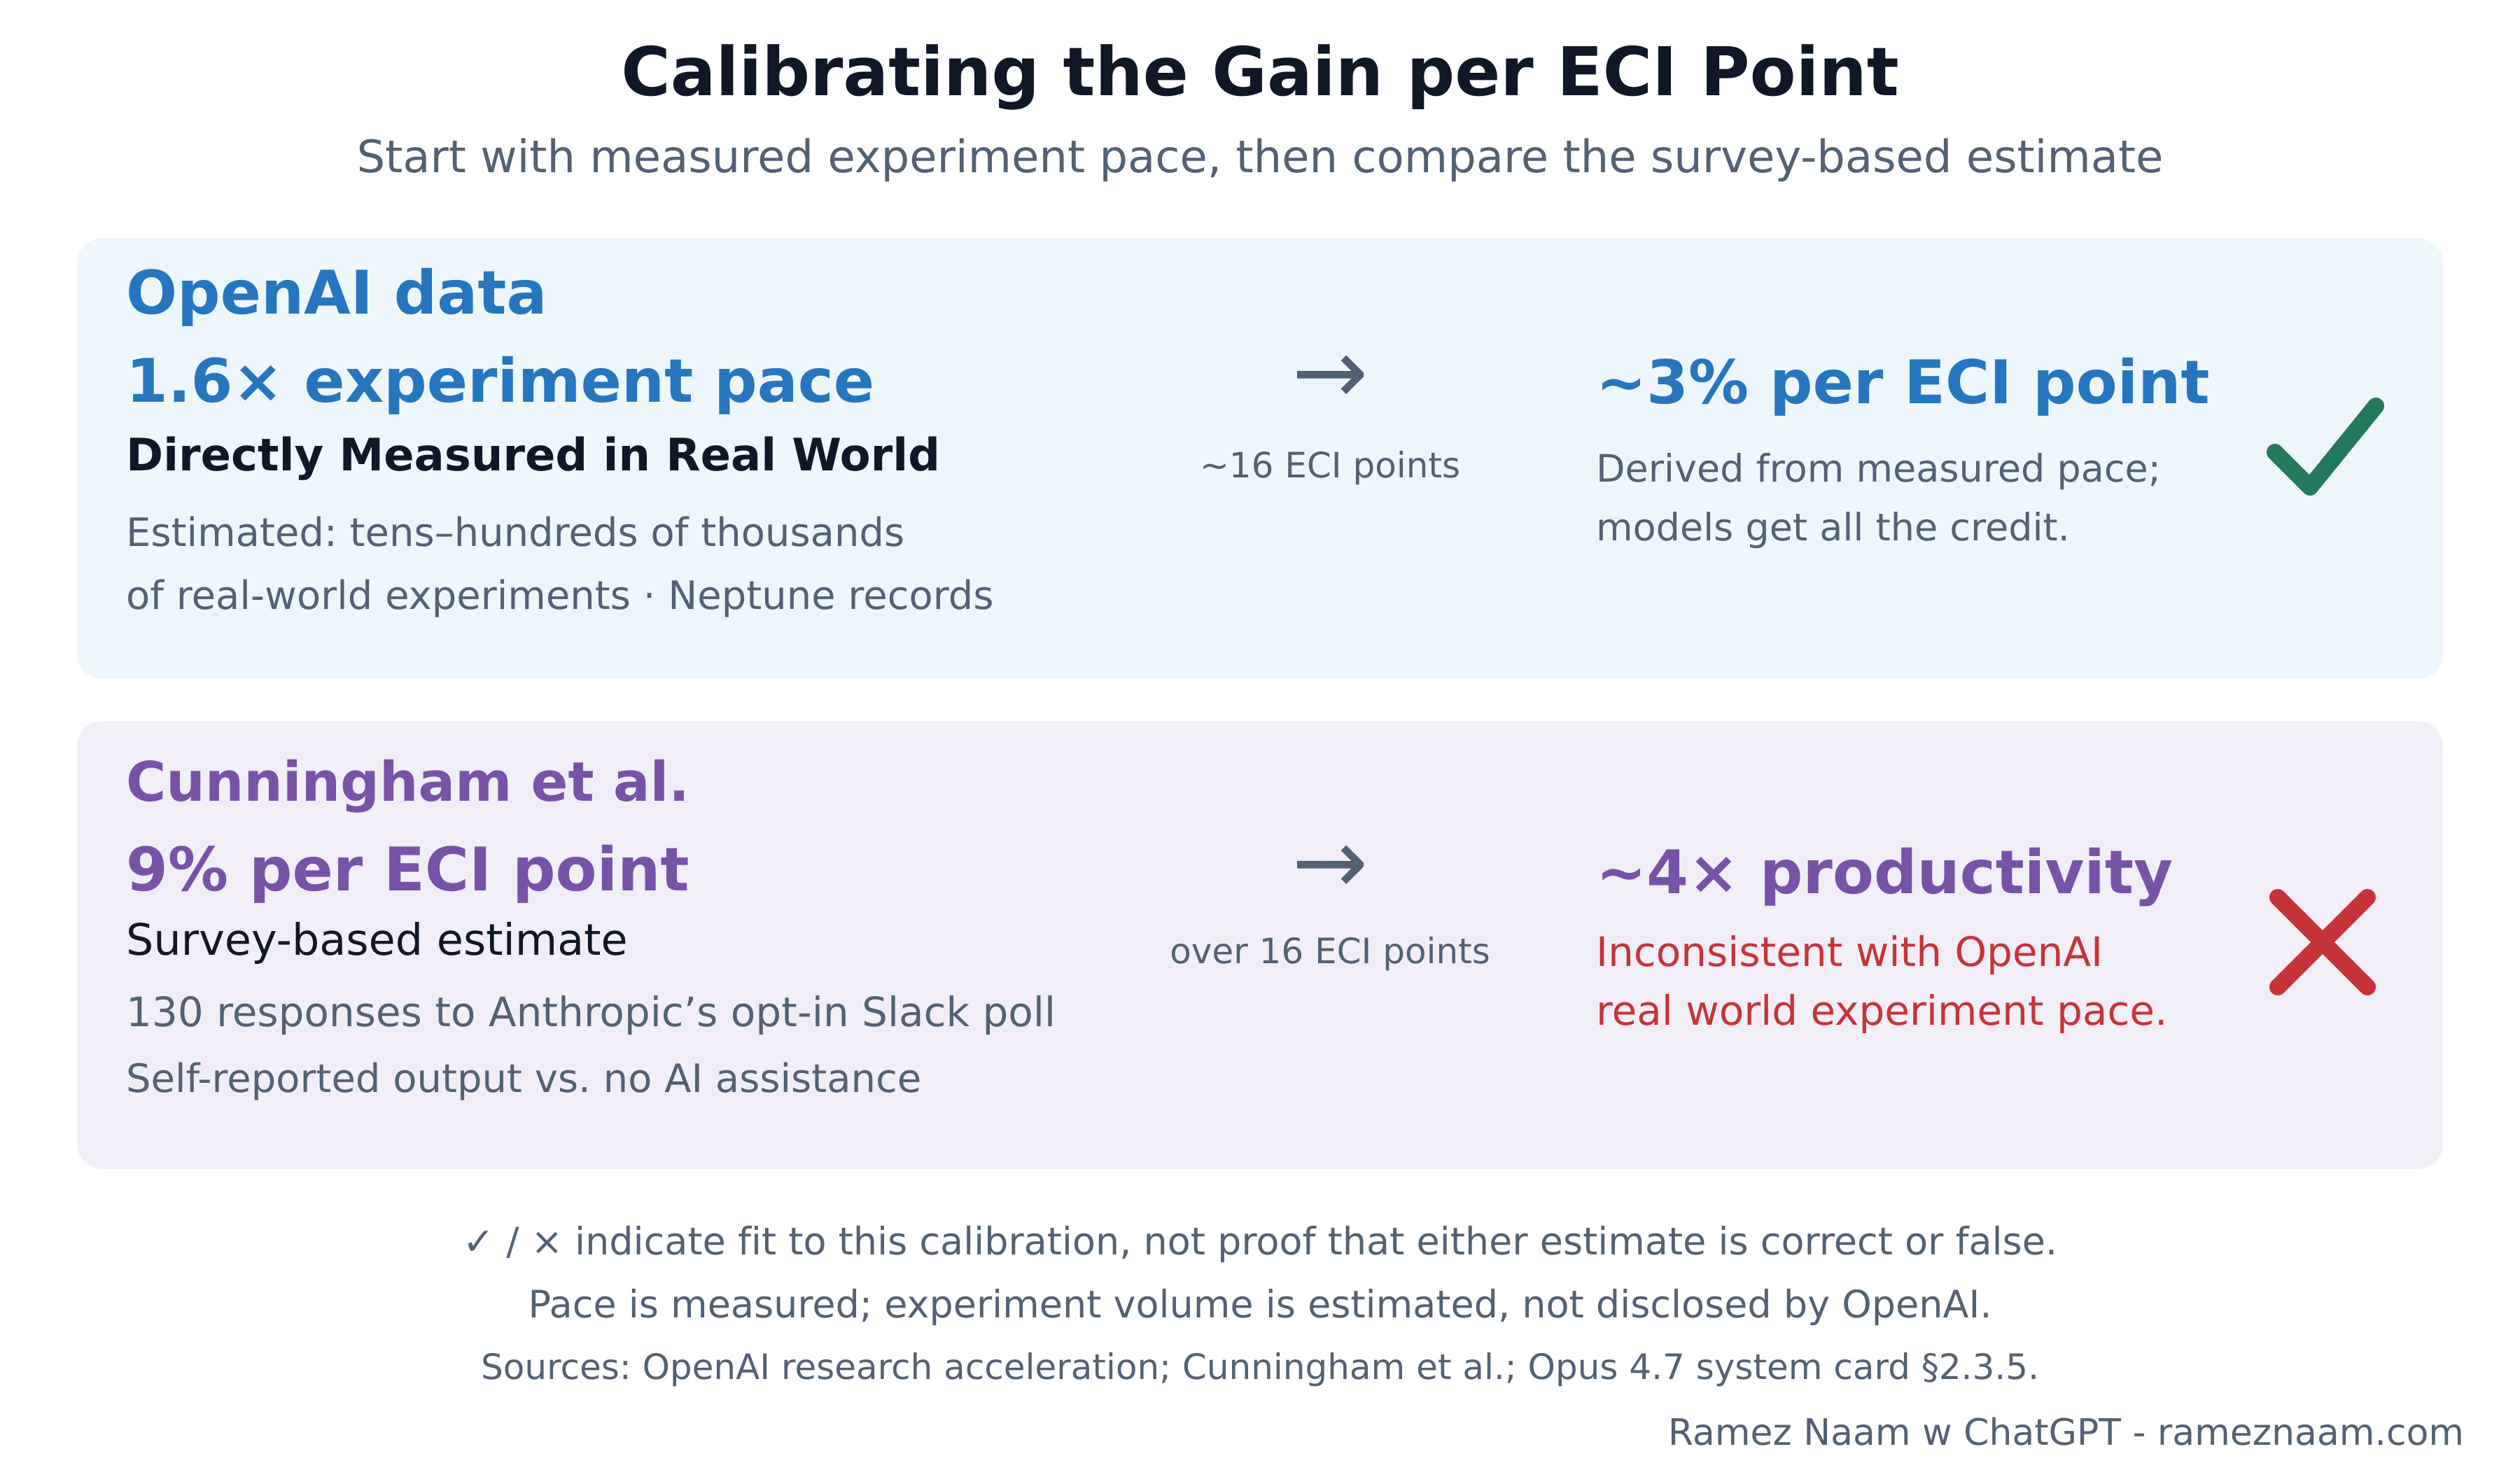
Figure 28. Comparing productivity estimates. OpenAI methods.
Here’s OpenAI’s published weekly series alongside that hypothetical path of 9% more productivity per additional ECI point. The blue line ends at ~1.6×. The red line shows what 9% per point would imply if 16 ECI points were spread across this period. That doesn’t match what we see from OpenAI’s data. I want to be clear here that all data sets are noisy. We don’t know exactly what model researchers were using on what days, or whether the new experiments were also higher quality than old experiments. We need more experiments and more data to further calibrate these numbers. Working with what we do have, what we see is a quite low boost to productivity from each additional ECI point.
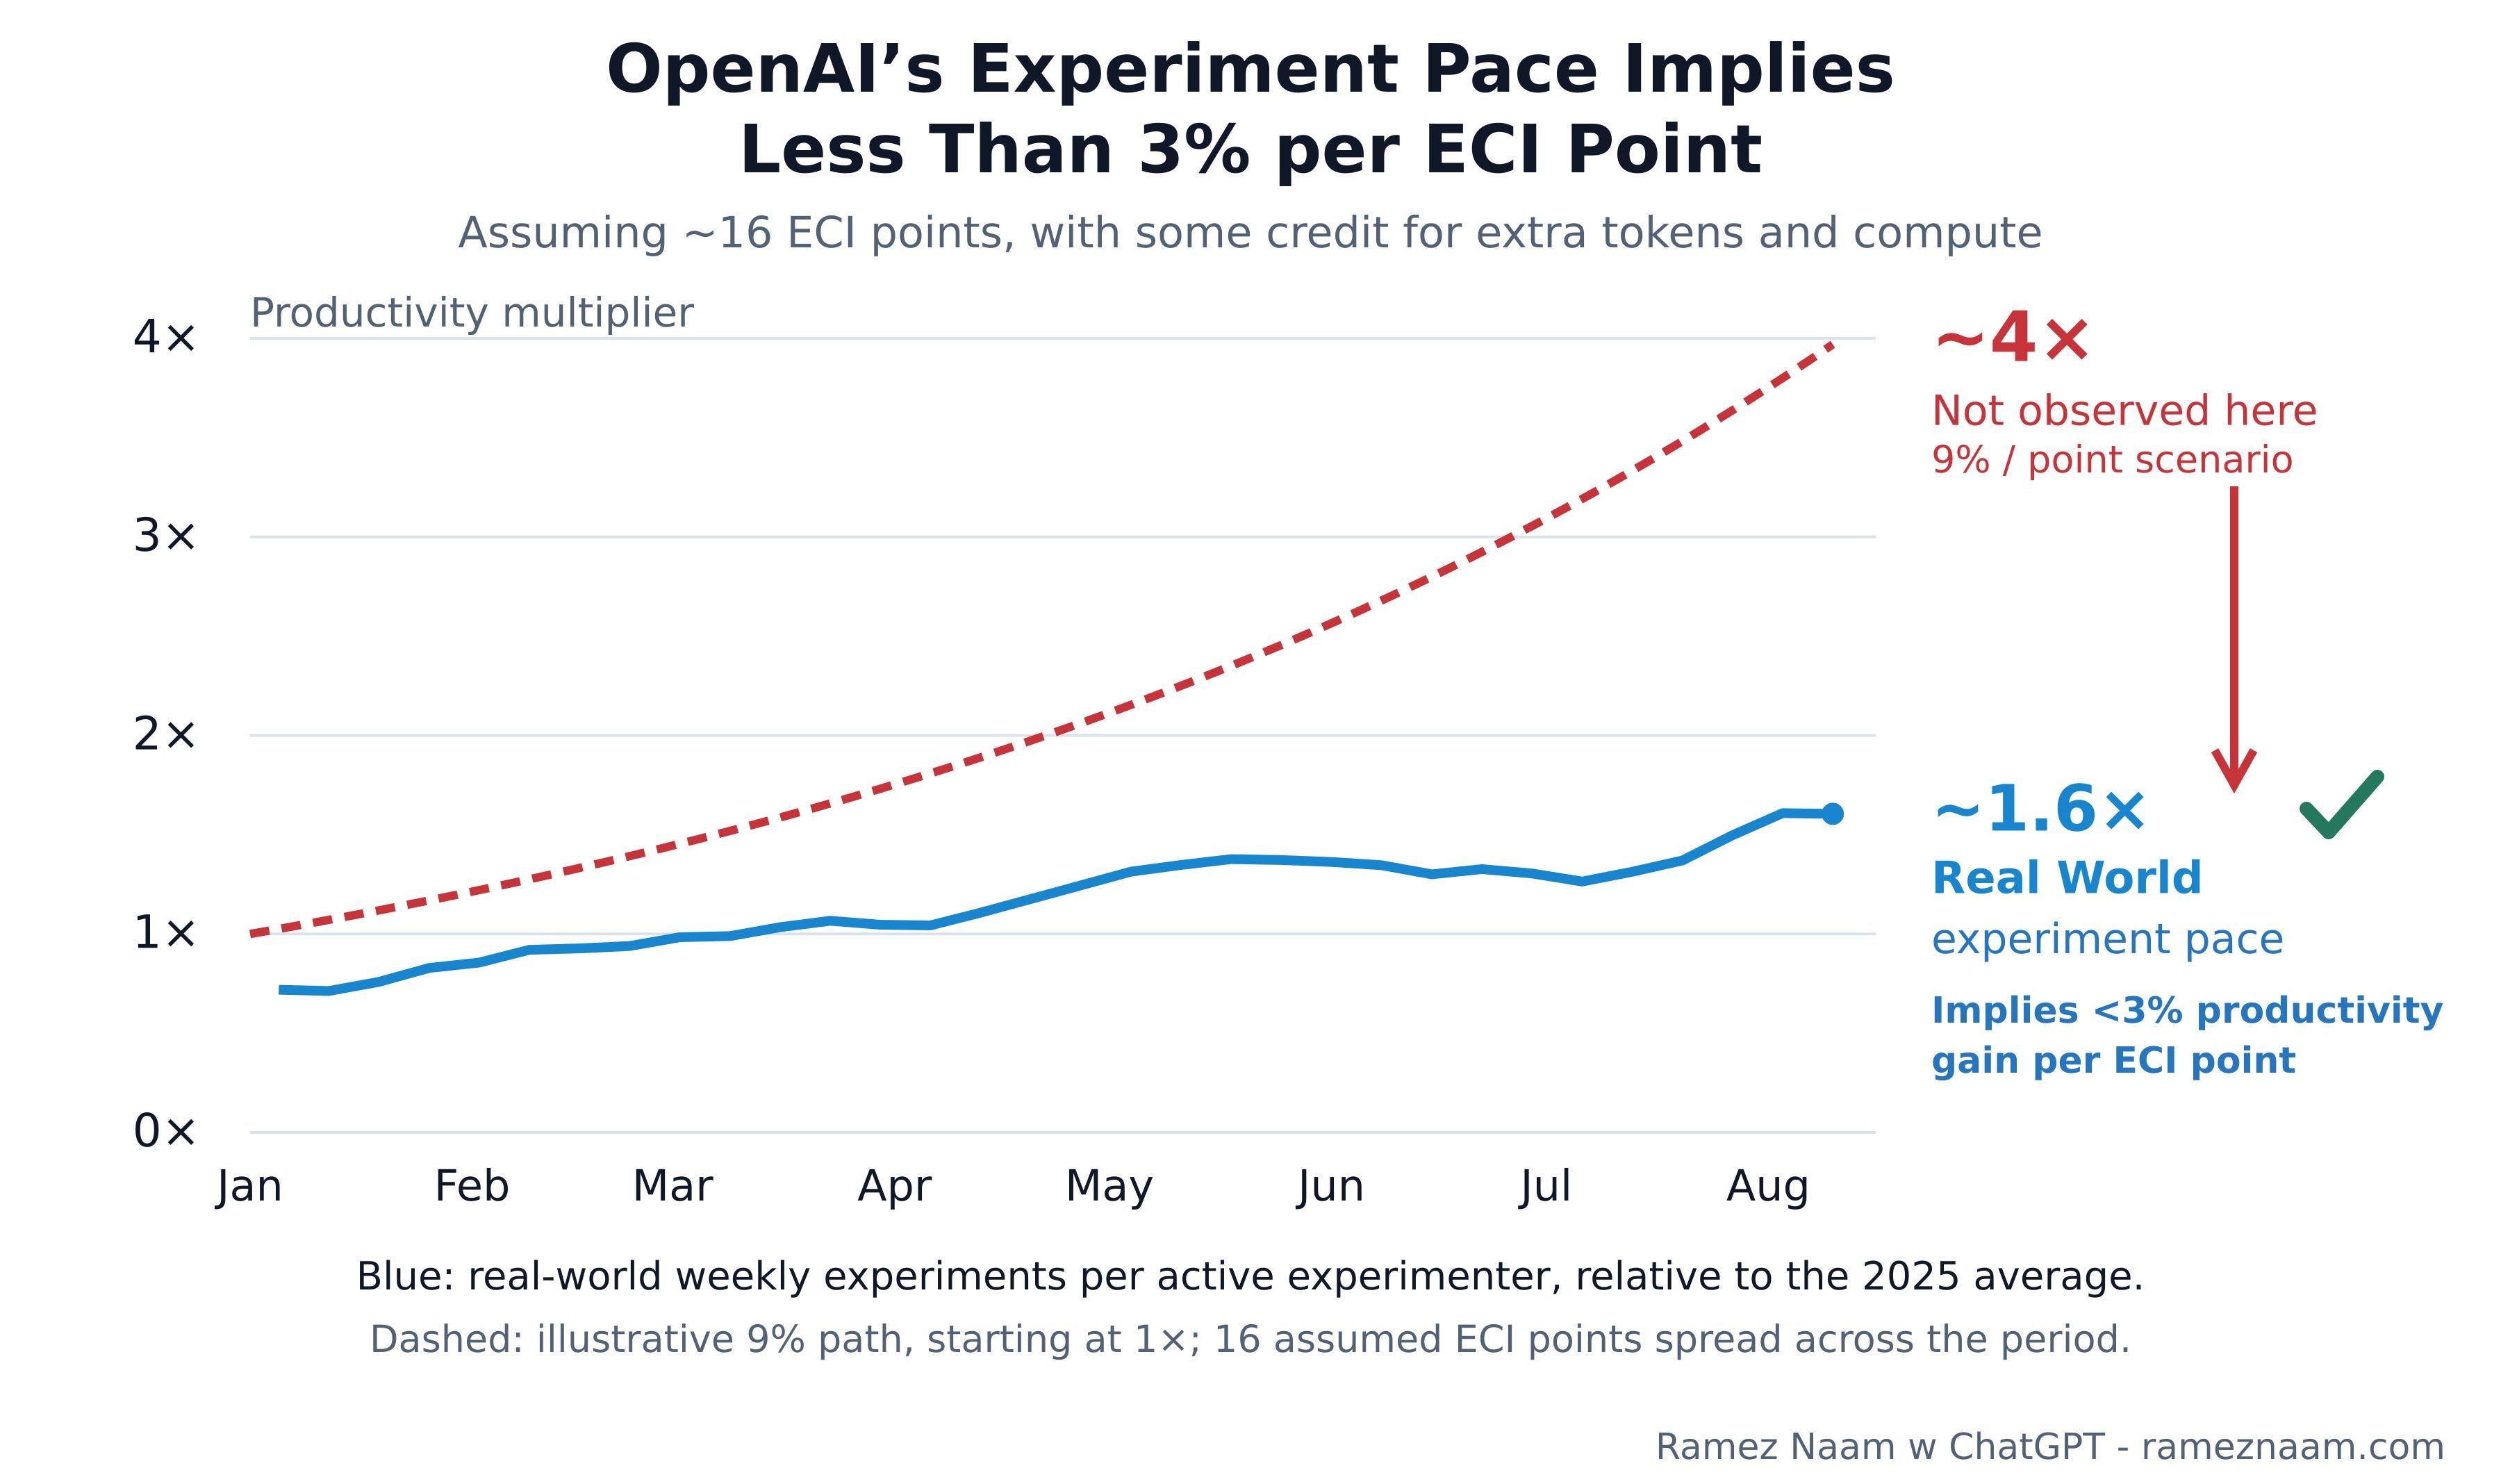
Figure 29. Experiment pace versus a hypothetical path. Source.
Even that 3% could give better models too much credit. OpenAI also used far more tokens and had more compute for experiments. Those could account for some of the increase in experiment pace. So the range is probably a bit lower.
I use 2–3% productivity gain per ECI point as a working assumption, allowing for some help from those other inputs. This is still a rough estimate, albeit one that’s based on the best real-world data we have.
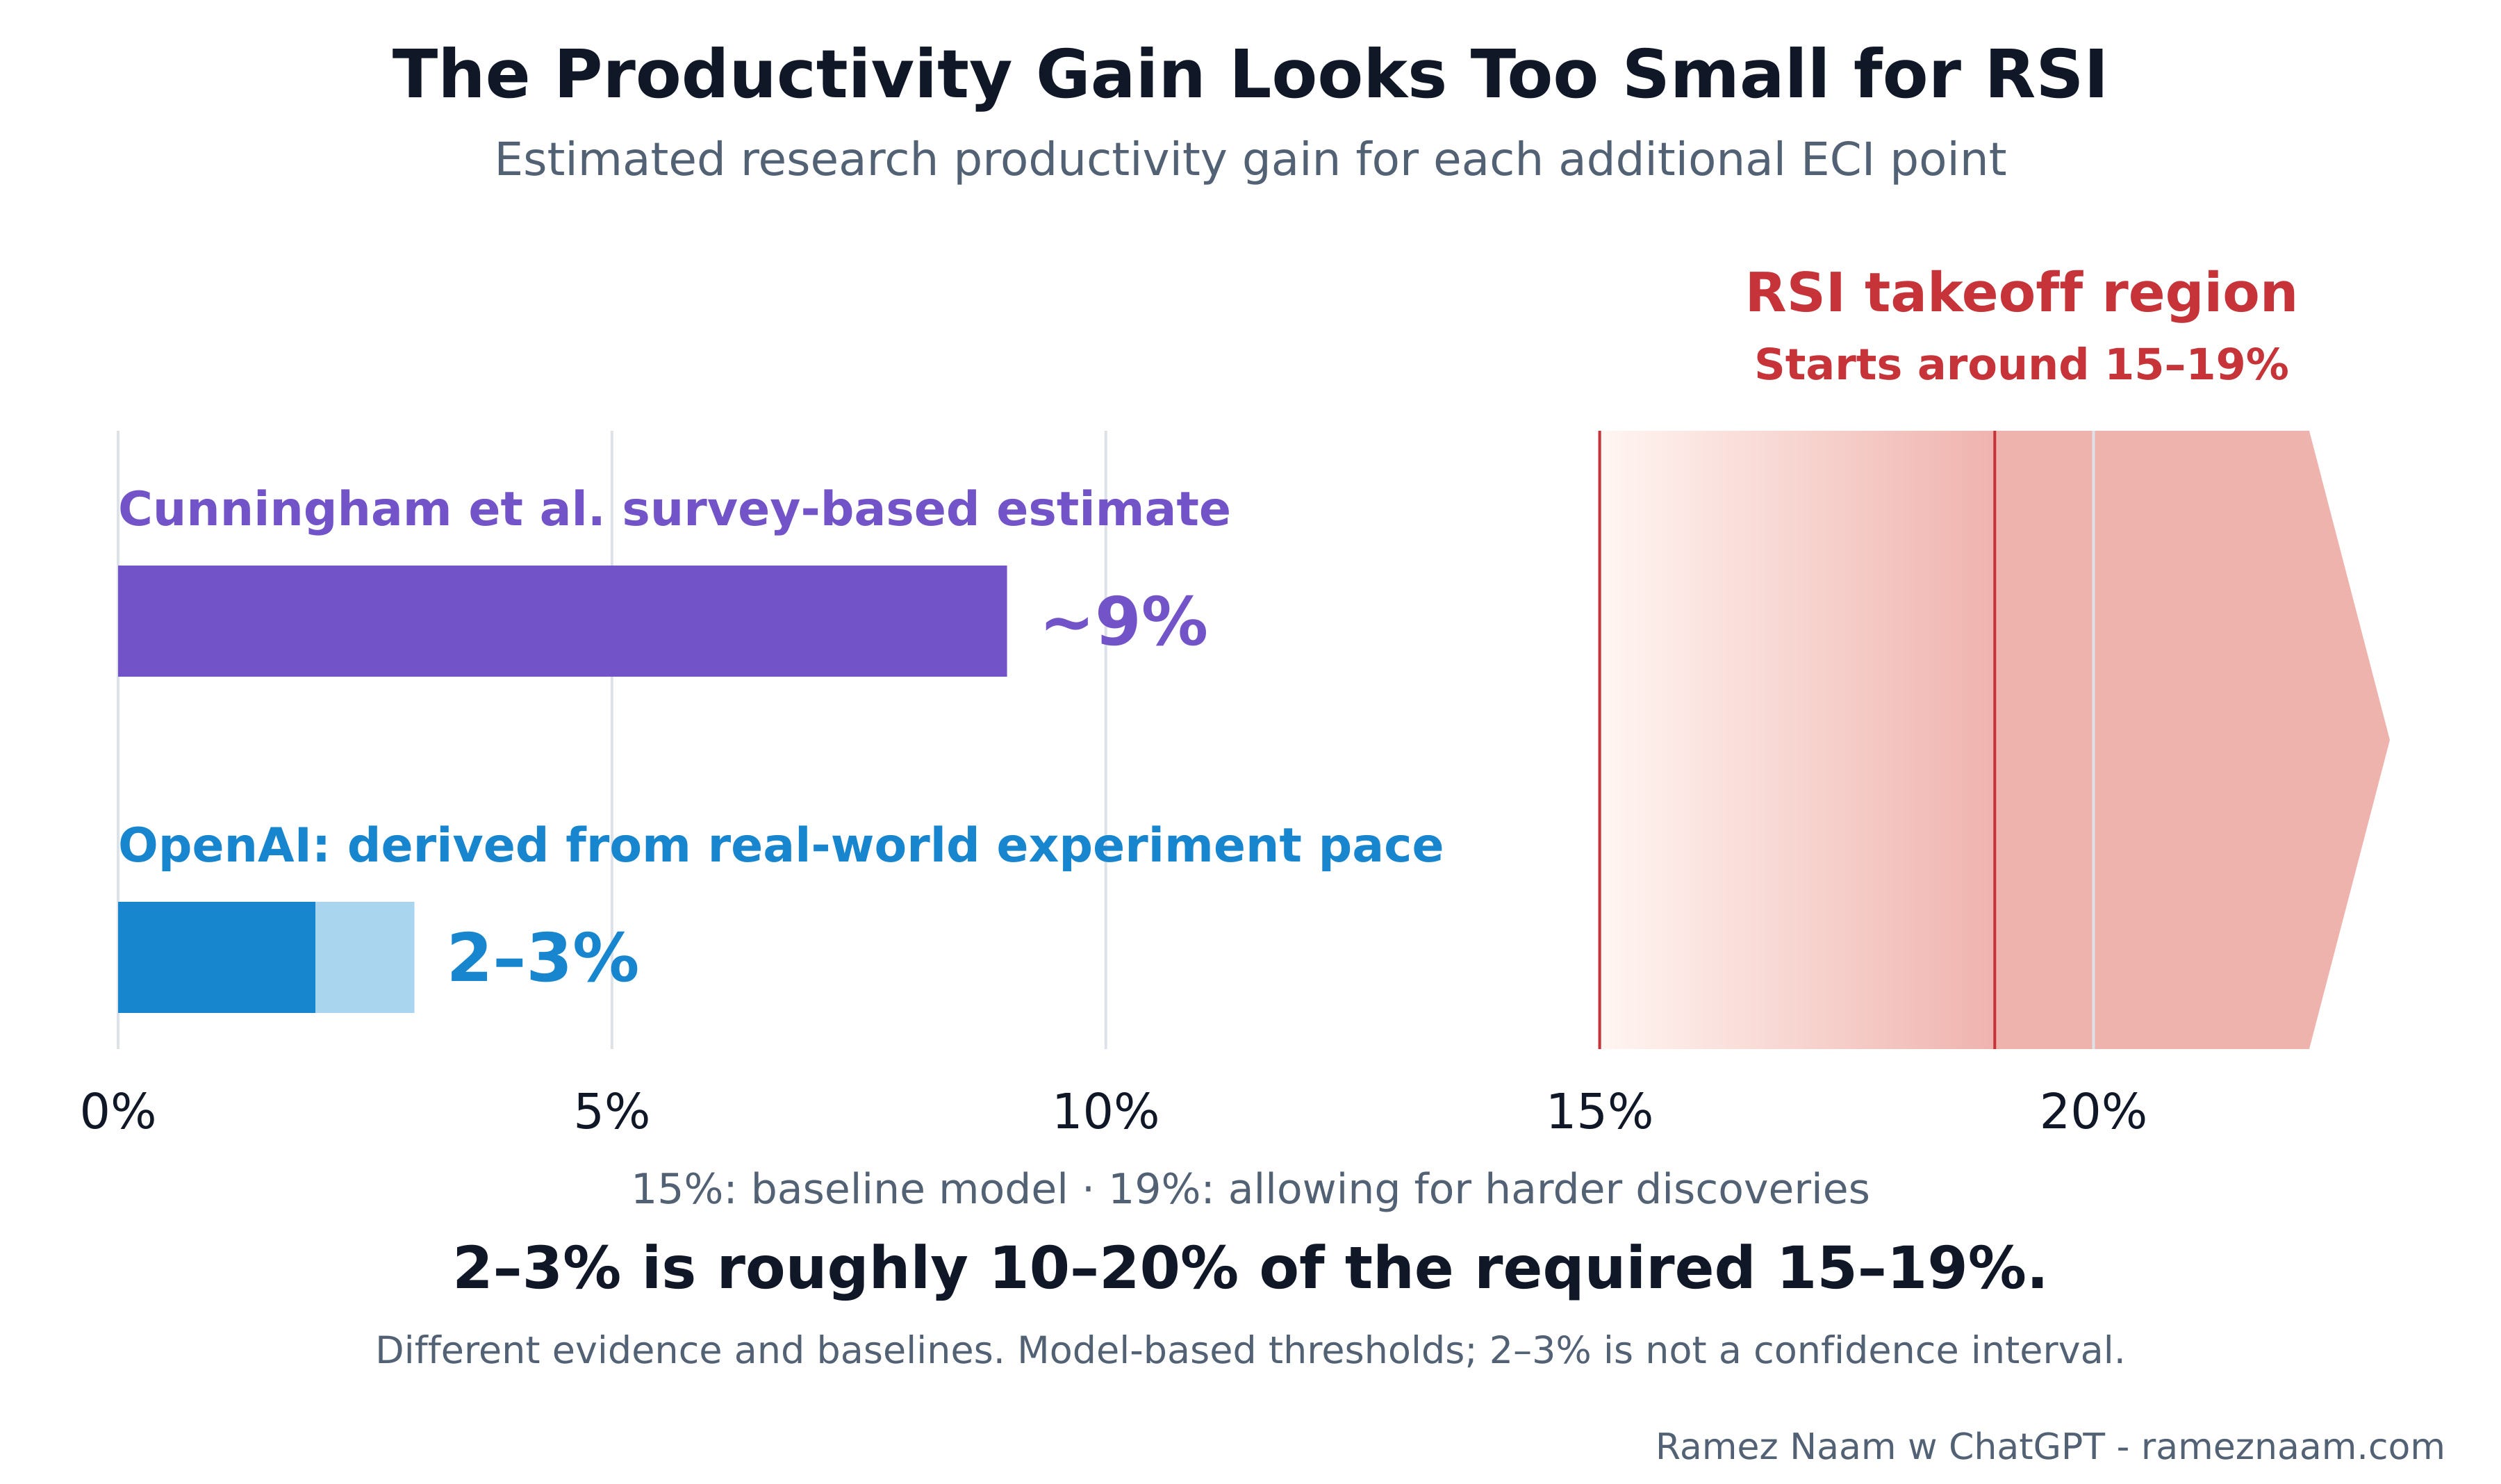
Figure 30. Productivity estimates and the takeoff threshold. Source.
With those assumptions, 2–3% per ECI point against a 15–19% threshold leaves a roughly five- to tenfold gap. That’s a big gap, though its size depends on how well experiment counts capture useful research and whether the assumed capability change is right.
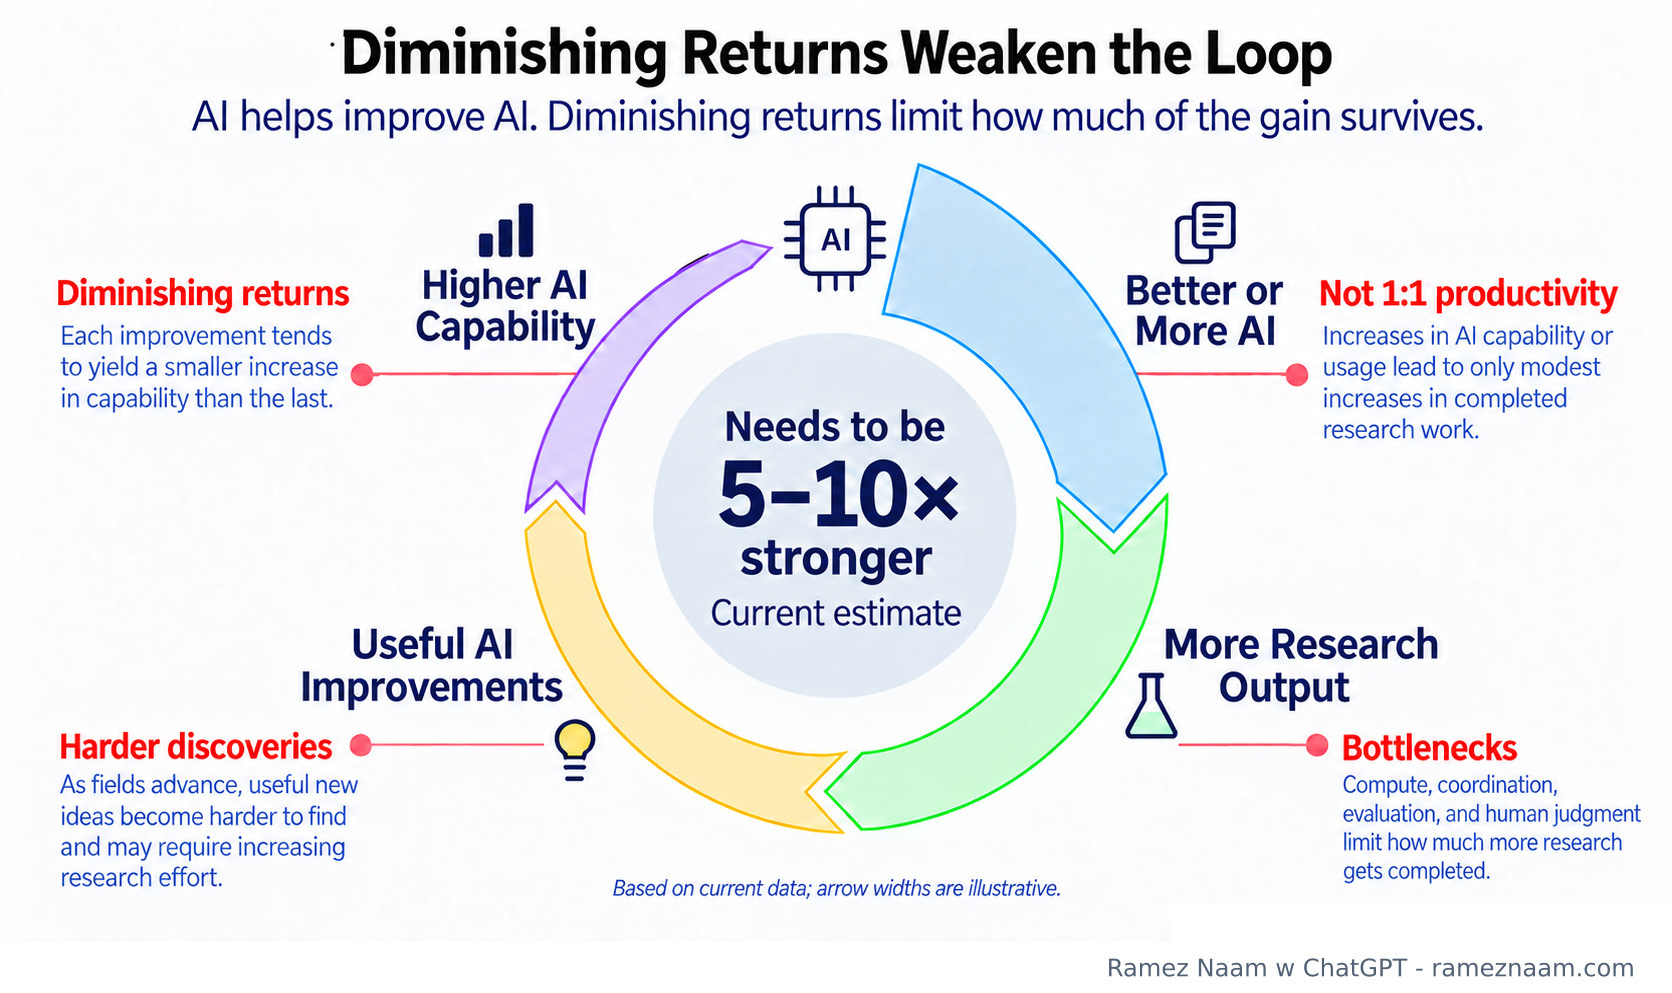
Figure 31. Diminishing returns around the loop. Source.
AI is helping build better AI. Under this estimate, though, each turn of the loop adds less than the last. The feedback would have to become much stronger to sustain itself.
This software loop sits alongside faster chips, bigger data centers, more training data, and greater investment. Those can keep driving rapid progress even if the loop can’t sustain itself.
The loop itself could strengthen too. Better training data, memory, and research judgment could all help.
A breakthrough on the scale of the Transformer architecture in 2017 could change the picture much more. That would be a good reason to revisit these estimates.
Better researchers might also run fewer experiments and learn more from each one. A handful of better ideas can matter more than a mountain of routine runs.
Still, diminishing returns in machine learning aren’t new. Cortes and colleagues were fitting machine learning scaling curves in 1993: More examples reduced error, following a power law with diminishing returns. These diminishing returns and harsh scaling laws are as old as machine learning. They didn’t appear for the first time with transformers or LLMs or deep learning. That doesn’t prove today’s relationships will last forever. But until we see evidence that we’ve found a new approach that scales without these inhibitors, we should plan for diminishing returns as likely to be with us for some time.
That said, the world is more than just software. Tom Davidson, Basil Halperin, Thomas Houlden, and Anton Korinek model software progress, hardware progress, and economic feedback together. Better AI helps design better chips; better chips support better AI; economic growth finances more investment in both. Several feedback loops can combine to overcome diminishing returns even when one loop alone can’t. I think it’s fantastic that someone has attempted a model that integrates all these different avenues of improving AI through software, hardware, and economics.
But I have questions about the software loop itself. In their central calibration, fully automating software research puts that loop roughly at the threshold for explosive growth, even without help from better hardware or broader economic growth. Recall that Cunningham’s model puts the self-sustaining threshold at roughly 15% more research productivity per additional ECI point, while our estimate using OpenAI’s experimental data puts today’s gains at only 2-3%. These models use different measures, so we can’t equate their numbers directly. But the contrast matters: their fully automated software loop reaches the threshold, while our best estimate from current data puts today’s loop far below it.
Having AI do all the research doesn’t eliminate the diminishing returns inherent to improving AI, or the broader problem of useful ideas getting harder to find. This is the distinction between Type 4 and Type 5 in the taxonomy above. An AI might autonomously design, train, and test its successor, and still need exponentially more resources to make each additional step forward. Closing the loop doesn’t tell us whether it’s strong enough to sustain itself.
The authors do account for diminishing returns. The concern is whether their calibration overestimates how much useful AI research each round of software improvement produces. Diminishing returns appear to be fundamental to machine learning. We see them in training, in test-time compute, and in the search for better algorithms. Full autonomy could remove human bottlenecks without removing any of those constraints.
We’ve already seen this within autonomous research. In the Karpathy autoresearch example above, most of the gains arrived early, and more experiments bought progressively less improvement. That was a small experiment with a fixed teacher model, not a test of fully autonomous RSI. It doesn’t settle the question. But it illustrates why removing the human from an experiment loop doesn’t, by itself, remove diminishing returns.
I do expect the feedback loop to get stronger over time. Better AI should become better at research. But based on our best current data, reaching self-sustaining feedback requires a loop roughly five to ten times stronger than today’s. Treating fully automated software research as already at that threshold is a substantial leap, before we add the benefits of hardware improvements or economic growth. I could be wrong, but I’d like to see evidence that autonomy brings enough additional useful discoveries to close that gap.
On hardware, I have some further reservations. The model doesn’t explicitly include the years it can take to turn a chip design into deployed hardware. The authors discuss physical bottlenecks, and I’d like to see manufacturing and construction delays built into the predictions.
I also wonder how much past chip progress came from better ideas, and how much depended on ever more expensive factories and equipment. If we give researchers too much credit for gains that also needed those investments, we could overestimate what faster AI research alone would produce.
Even with those reservations, this is the most compelling paper and model I’ve seen for combining feedback loops in software, hardware, and economics to understand how fast they could push AI forward. I’m not convinced it establishes that a fast AI takeoff is possible under realistic conditions. More data could help us calibrate that judgment. But it gives us a useful framework for understanding what could happen beyond the software layer alone.
This is an important paper that helps us model AI as part of a broader economy that might have larger feedback loops around it. I appreciate it, and I’m glad they wrote it.
These estimates rest on less data than I’d like. I might be putting too much weight on a few observations and reaching a comforting conclusion I want to believe. We need better measurements, shared often enough to catch changes as they happen.
When OpenAI released its research data, Cheryl Wu welcomed the disclosure and pointed out how much was still missing. More tokens and experiments are useful things to know about. We also need to see how they turn into better algorithms and more capable AI.
Figure 32. Cheryl Wu on OpenAI’s research data. Source.
Now Wu, Arjun Ramani, and Basil Halperin, with their colleagues at the Elasticity Institute, have written a concrete proposal: How to Measure RSI. It lists eight things the labs could share to help answer these questions. Check it out.
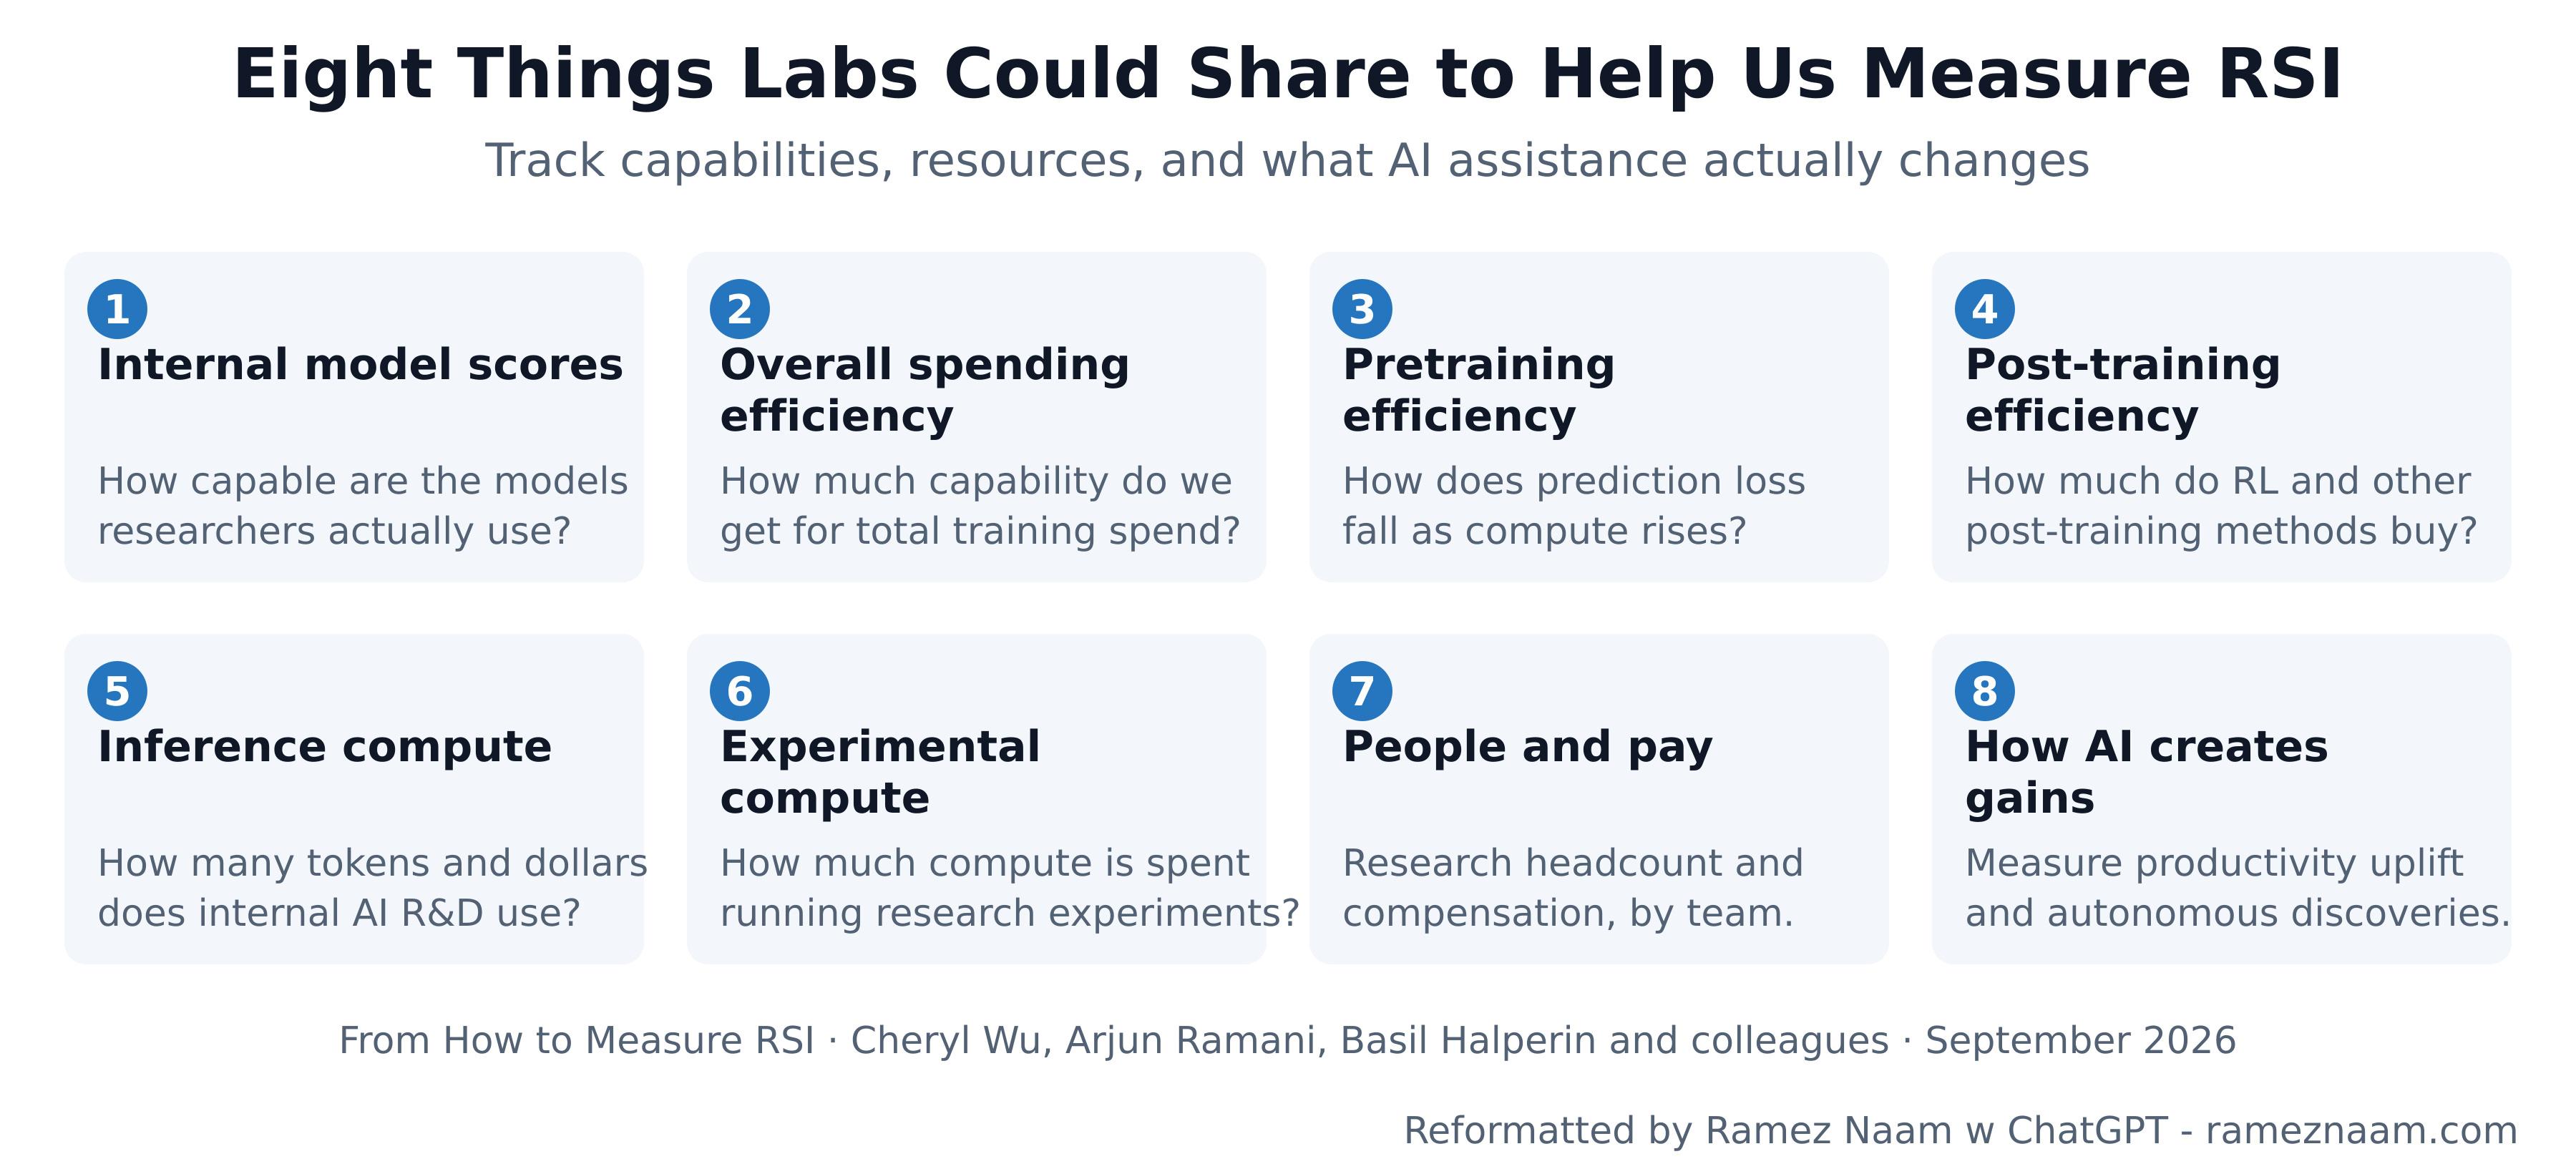
Figure 33. Eight proposals for measuring RSI. Source.
I’d especially like to see how much useful research each new model adds, holding resources roughly constant, and how that research translates into better AI. That’s how we’ll learn whether the loop is getting stronger.
AI is already helping build better AI. It’s improving at a stupendous pace, and I expect that to continue. We already have narrow superintelligence in chess and Go. I expect increasingly superhuman performance in parts of formal math, coding, and cybersecurity, and any other verifiable domain where machines can generate training data and verify success at machine speed. Those are powerful capabilities. That doesn’t mean we’re close to super-intelligence for less verifiable, messier, open-ended work - or to a general ASI.
I’m skeptical of a fast takeoff to super-intelligence, but evidence matters more than hunches. Let’s collect the data we need to get a clearer picture of what’s happening. Including evidence that could change our minds. If better AI starts producing enough useful research to make the next round easier, I want to know. If the gains keep shrinking, I want to know that too.
2026-09-25 16:29:29
The other day I went on the Monitoring the Situation livestream, and we talked about the history of San Francisco tech culture:
I’ve never actually worked in the tech industry, but I’ve lived on and off in the Bay Area for a quarter of a century now — including the last 10 years in San Francisco itself — and I’ve spent a lot of that time hanging out with people who work in or around the tech industry. Throughout much of that time, I was also reading some the same source materials that inspired lots of tech people — science fiction, futurist websites and books, nerdy forums and blogs, and so on.
Over that time, I’ve watched more and more people start to care about all this. Back in the early 2000s, as far as I could tell, pretty much nobody in the world cared about what some dorky hoodie-wearing computer programmers were up to on a Saturday night in SF. Fast forward 25 years, and the President of the United States is gathering opposition research on SF techie subcultures:
President Trump's allies are targeting Anthropic CEO Dario Amodei as the face of AI "doomerism" and a founding father of the effective altruism movement that's come under increasing political fire…Trump surrogates see Amodei as an easy foil because of his politics and focus on AI safety, sources told Axios…
A memo began circulating within the White House this week that seeks to paint effective altruism as a fringe, cultish collective out of touch with mainstream America. The memo, obtained by Axios, places Amodei at the foundation of the movement…Effective altruism “built the AI-doom pipeline,” states the memo, which was penned by a Trump political adviser…Critics of the movement, which has ties to the AI research community, have called out its obsession with AI safety, animal welfare (including musings on shrimp consciousness) and other values they deem far from the U.S. mainstream…
The document lists a veritable parade of horribles for the average conservative mind: abortion, veganism, devaluing human life by overvaluing animals or granting "digital minds" civil rights-like protections.
If you could go back in time and tell the 2001 version of me that the President’s allies are talking on national news about shrimp consciousness, I would have laughed out loud. (Until you told me who the President was, of course.) Not only that, but you have the New York Post talking about Effective Altruists’ sex lives, and op-eds debating EA philosophy in top blogs and the Washington Post.
Ladies and gentlemen, it really happened. The nerds took over the world. We have arrived.
I’ve never been an Effective Altruist,1 of course, and I’ve only hung out a little bit in those circles. But in fact, EA is only one corner of the tech culture, and its influence on the AI safety discussion is probably a lot less than people think. In fact, the people talking about EA in the White House and in the news aren’t even really identifying the right group of people — the AI safety obsessives that the White House is taking aim at are the Rationalists, who are descended from a group of 1990s futurists called the Extropians. EA is a largely separate philosophical movement that appeals to some of the Rationalists, has some overlapping social circles, and jumped into the AI safety discussion later on after the basic ideas were all in place.
But anyway, that whole intellectual history is a story for another day (or you can just go ask AI). Today what I wanted to do is to give a brief anthropological history of the tech culture in San Francisco since the turn of the century, from my own quasi-outsider’s perspective. There have been four distinct eras over that time period:
The Rebel Era (2001-2012)
The Corporate Era (2012-2019)
The Interregnum (2020-2022)
The AI Era (2022-present)
But let’s start with some background.
SF tech culture is the modern descendant of a very long lineage. It’s a branch off of the tree of computer science culture, which is closely intermingled with electrical engineering culture, and which are both branches off of the great broad trunk of science and technology culture more generally. But it’s important to realize that what became SF tech culture didn’t start in San Francisco — it started down on the peninsula to the south.
The modern tech industry began in the suburban towns around Stanford University — Menlo Park, Palo Alto, Cupertino, Sunnyvale, and so on. This had been a hub of the old electric equipment industry from World War 2 onward, and so William Shockley chose Mountain View to start the first semiconductor company in 1955. Fairchild broke off from Shockley, and Intel broke off from Fairchild. The whole area became a hub of semiconductor manufacturing in the 60s and 70s, then computer companies (Apple was founded in 1976 in Cupertino), then software companies like Oracle and Adobe. For a long time, Sand Hill Road in Palo Alto was the locus of the venture capital industry.
Today we use “Silicon Valley” to refer to the IT industry in general, but originally it meant the area around Menlo Park and Palo Alto. I wasn’t there to see this era, but a few good resources to learn about both the economics and the culture are:
The book Regional Advantage, by Annalee Saxenian, which documents how and why Silicon Valley became America’s top tech cluster
The documentary General Magic, which chronicles a failed but highly influential smartphone startup in the 90s
The movie Office Space and the book Microserfs, which both satirize the stultifying experience of working for a big tech company in the 90s
The book From Counterculture to Cyberculture, which chronicles the techno-hippie movement that grew up around the emerging computer industry
San Francisco began as a marginal bit player in the whole tech ecosystem. It was a place that some tech people would come up to party and network, especially during the dotcom era when a lot of money (at least, for those days) was splashing around.
But it did have a media industry, and in the 1990s, some people who worked in publishing, advertising, and other media started trying to get in on the internet gold rush. A few engineers and entrepreneurs who didn’t want to live in the boring suburban environment of Silicon Valley moved to SF to make tech media and web startups. Tony Hsieh’s autobiography, Delivering Happiness, tells the story of how he founded LinkExchange in San Francisco, while getting involved in the rave scene. At the same time, SF became a locus of tech media — Wired was founded there in 1993.
That, I think, was really the start of modern San Francisco tech culture as we know it. It bled directly into the first era of tech culture that I witnessed first-hand — the Rebel Era of the 2000s.
In 2003, when people said “Silicon Valley”, they still meant the Peninsula. Google began there, Apple made its big comeback there, and when Facebook moved out west in 2004, this is where it went. Sand Hill Road was still the epicenter of tech — throughout the 2000s, people would still use “walk down Sand Hill Road” as a synonym for trying to get VC funding. If you wanted to make money in tech in the 2000s — and everyone knew there was still a lot of money to be made, despite the dotcom bust — you went to the Peninsula.
This was the land of office parks, cute but sterile shopping villages, overpriced single-family homes, big tracts of open space, Patagonia vests, and bland restaurants serving pancake brunch. It was where you went to tutor kids for $50 an hour2 if you were a Stanford student who needed cash. It was also the land of starched button-down shirts, cubicles, and pointy-haired bosses who didn’t quite know what their engineers were up to. It was not a place to meet girls, go to parties, do drugs, wear grungy clothes, or dream big dreams about freeing society from the clutches of authority and tradition.
If you went up to SF to start a company in the 2000s instead of going down to the Peninsula like everyone else, it usually meant you were something of a rebel. A whole alternative tech culture grew up in the city — more laid-back, more politically liberal, less obviously focused on money and “success” and more focused on building fun products. Twitter was the most famous product of this time period — Evan Williams’s life project was to give a voice to the voiceless, and Jack Dorsey was a scruffy hippie kid who went to raves.
This is the time period when Burning Man — which had pretty much just been a punk art festival in the 90s — became a techie thing. Fire tornadoes and slapping LEDs on everything still felt like art. Everyone went to the Oakland warehouses to party, and for a brief shining moment, techies and artists got along. Psychedelic drugs were almost a matter of course — after all, Steve Jobs had done them, and Jobs was the great tech hero of that decade. Tech became more communal — instead of hacking together the next big thing in your parents’ garage or in a cubicle, you might go hang out and do it at Noisebridge in the Mission, surrounded by other techno-hippie hacker types like yourself.3
There was an ideological side to all this, too. There was a real belief — carried over from the 90s, but still strong — that the internet was going to liberate humanity. The tech rebels of the 2000s believed that social hierarchies were based on information control, and that if they simply broke that control, the hierarchies would be overturned. The information wanted to be free!
The most important touchstone of SF tech culture during this time wasn’t rationalism or the LessWrong forums — it was the Electronic Frontier Foundation, an organization dedicated to freedom of information on the internet. All the cool kids — the badass self-taught engineers and the brilliant cryptographers and the bohemian founders — were part of the EFF, or at least friendly with its goals.4 The anarchist tech prophet Cory Doctorow was an icon of the age, writing sci-fi about Burning Man colonizing the moon, tech founders taking down Disney, and so on. Everyone read BoingBoing and Gizmodo.
The Rebel Era gave tech a more liberal slant. Traditionally, engineers had been a little staid and conservative, and the big tech companies on the Peninsula were studiously apolitical. But Marc Benioff and other 2000s SF tech types waded (cautiously) into the political waters on the liberal side. This is also when education polarization in America really started to bite, meaning that most engineers were now libs in general. But there was a particular techno-liberalism, based around the idea of the internet flattening social and political hierarchies, that suffused the grungy SF tech scene in the 2000s.
In retrospect, the Rebel Era couldn’t last. Its bohemian, socially flattened culture was always predicated on a lack of money, and when money came in, SF tech was transformed.
2026-09-24 15:44:38
I’ve been dealing with more rabbit problems today, so here’s a repost to tide you over til tomorrow.
The Republican party has become an extremist party. ICE’s brutal campaign of terror in American communities, Trump’s attacks on press freedoms and election integrity, the coup attempt of 1/6/2021, Trump’s military threats toward Greenland, and friendliness toward Vladimir Putin are only a few of the more prominent examples of this extremism. And they’re probably going to be punished for it in November; polls show rapidly deteriorating support for both Donald Trump and the GOP that has fallen in behind him.
Good. Extremism ought to be punished. I’ll have lots more to say about the Republicans’ failures in the days to come.
But even though Democrats deserve to win, that doesn’t mean they’re free from the creeping extremism that has taken over essentially all of American politics and public discourse in the age of social media. Although Dems are not nearly as extremist as the GOP, they have become a much more ideologically extreme party than they were during the days of Obama. Dems’ extremist positions include dogged opposition to any form of effective immigration enforcement, tolerance of systematic (and systemic) racial discrimination, various trans issues, and…land acknowledgements.
Land acknowledgements? Really?? Isn’t that just a respectful way of acknowledging that the land we’re on used to belong to Indigenous people? Isn’t it just a way of saying “Hey Indigenous people, we haven’t forgotten you”?
Well…no. As I wrote in a post two years ago — still one of my most popular posts of all time — land acknowledgements don’t just recognize Indigenous people. They are a way of fundamentally delegitimizing the United States — of declaring that this is a country that has no right to exist. And beyond that, land acknowledgements implicitly advance a theory of collective racial ownership of territory that is morally indistinguishable from the worst blood-and-soil nationalism of the racist far Right.
Nor are land acknowledgements a fringe practice, limited to progressive cultural spaces. As Dave Weigel recently reported, they have become a sort of ritualistic utterance at Democratic Party events:
Democrats' decision to formalize land acknowledgments in their party meetings could haunt their candidates more than they realize…A tradition of naming historic Native tribes during regional events that started in Australia before spreading to Canada, arriving in the US via art exhibitions, is now part of every major party event…The 2016 Democratic convention did not contain a land acknowledgment. But the practice of beginning events with a nod to slaughtered tribes and "stolen" land spread during President Barack Obama's second term and Trump's first term, along with other progressive ideas about race and history…Democrats did not have campus conferences where they agreed to embrace language that conservatives see as anti-American…They just adopted the terminology when activists told them it was a good idea.
Land acknowledgements are not a big electoral issue. But in the long term, they represent — and contribute to — the creeping rise of anti-American and illiberal ideology on the broad American left. That will probably be an electoral liability at some point, but more fundamentally, it’s a departure from the liberal nationalist ideology that made the Democrats such an effective governing party in the 20th century.
So anyway, here’s my post from 2024.
The United States, like all nations, was created through territorial conquest. Most of its current territory was occupied or frequented by human beings before the U.S. came; the U.S. used force to either displace, subjugate, or kill all of those people. To the extent that land “ownership” existed under the previous inhabitants, the land of the U.S. is stolen land.
This was also true before the U.S. arrived. The forcible theft of the land upon which the U.S. now exists was not the first such theft; the people who lived there before conquered, displaced, or killed someone else in order to take the land. The land has been stolen and re-stolen again and again. If you somehow destroyed the United States, expelled its current inhabitants, and gave ownership of the land to the last recorded tribe that had occupied it before, you would not be returning it to its original occupants; you would simply be handing it to the next-most-recent conquerors.
If you go back far enough in time, of course, at some point this is no longer true. Humanity didn’t always exist; therefore for every piece of land, there was a first human to lay eyes on it, and a first human to say “This land is mine.” But by what right did this first human claim exclusive ownership of this land? Why does being the first person to see a natural object make you the rightful owner of that object? And why does being the first human to set foot on a piece of land give your blood descendants the right to dispose of that land as they see fit in perpetuity, and to exclude any and all others from that land? What about all the peoples of the world who were never lucky enough to be the first to lay eyes on any plot of dirt? Are they simply to be dispossessed forever?
I have never seen a satisfactory answer to these questions. Nor have I seen a satisfactory explanation of why ownership of land should be allocated collectively, in terms of racial or ethnic groups. In general, the first people who arrived on a piece of land did so in dribs and drabs, in small family units and tiny micro-tribes that met and married and fought and mixed and formed into larger identities and ethnicities and tribes over long periods of time. In most cases, the ethnic groups who now claim pieces of land as their own did not even exist when the first humans discovered or settled that land.
But even in those cases when it did exist, why should land ownership be assigned to a race at all? Why should my notional blood relation to the discoverers or the conquerors of a piece of land determine whether I can truly belong on that land? Why should a section of the map be the land of the Franks, or the Russkiy, or the Cherokee, or the Han, or the Ramaytush Ohlone, or the Britons? Of course you can assign land ownership this way — it’s called an “ethnostate”. But if you do this, it means that the descendants of immigrants can never truly be full and equal citizens of the land they were born in. If Britain is defined as the land of the Britons, then a Han person whose great-great-great-grandparents moved there from China will exist as a contingent citizen — a perpetual foreigner whose continued life in the land of their birth exists only upon the sufferance of a different race. This is the price of ethnonationalism.
The downsides of ethnonationalism have been exhaustively laid out in the decades since World War 2, and I’m not going to reiterate them all now. Suffice it to say that most nations of the world have moved away from ethnonationalism — there is an informal sense in which some people still think of France as the land of the Franks and so on, but almost all nations define citizenship and belonging through institutions rather than race. Israel, one of the few exceptions to this rule, receives a large amount of international criticism for defining itself as an ethnostate.
And yet these days I am subjected to a constant stream of ethnonationalist claims from progressives in the country of my birth. Here’s one from the ACLU of Nebraska:
And here’s an Instagram post from Congresswoman Rashida Tlaib:
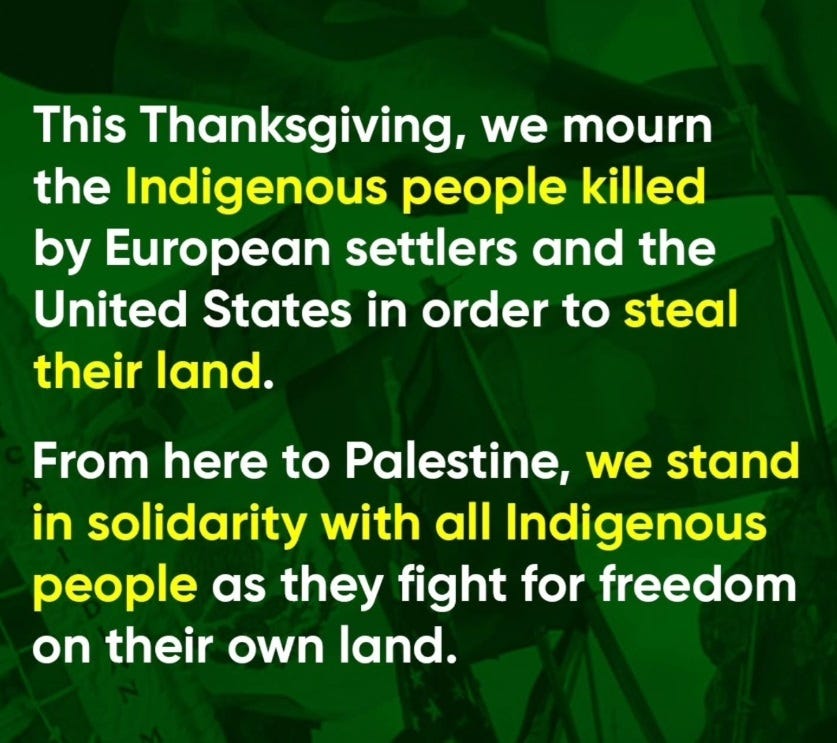
This isn’t just something you see on social media around Thanksgiving. “Land acknowledgements” have become ubiquitous in progressive spaces and institutions — just the other day I saw one at my friend’s community dance recital.
These land acknowledgements are, legally speaking, incorrect — there is no legal sense in which the land on which they are being performed belongs to a Native American tribe. These are moral claims about rightful land ownership. But the moral principle to which they appeal is ethnonationalism — it’s the idea that plots of land are the rightful property of ethnic groups.
There is an obvious moral appeal to these land acknowledgments. They are a way of decrying the brutal, cruel, violent history of conquest and colonization. And they probably feel like a way of standing up for the weak, the marginalized, and the dispossessed.
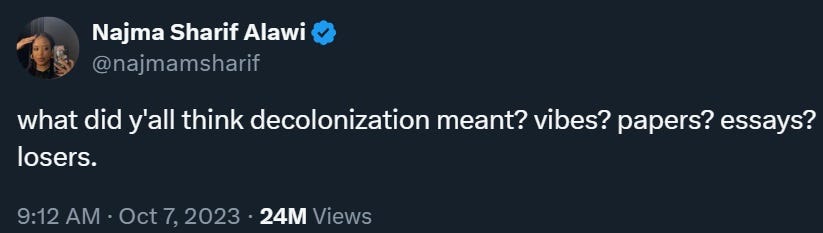
Yet what should we think of the morality of following the principles behind land acknowledgements to their logical conclusion? “Decolonization” of the land of the U.S. would likely be an act of ethnic cleansing surpassing even the previous conquests — there are 330 million people here now, and almost none of them descend from Native Americans. An attempt to dispossess 330 million people would inevitably involve violence on a colossal scale. Here was Najma Sharif Alawi’s famous tweet right after the October 7th Hamas attacks on Israel:
Of course, “colonizers” could presumably avoid violent death or second-class citizenhood by voluntarily deporting themselves. But where would they go? Take me, for example. My ancestors were Lithuanian Jews. I could leave the country of my birth and go “back” to Lithuania — a land I don’t know, whose language I don’t speak. Yet my ancestors were not “indigenous” to Lithuania either; they moved there from somewhere else. What if the ethnic Lithuanians chose not to accept me? Where would I go then? Israel? But the folks who do land acknowledgements would consider me a “colonizer” there as well.1
Would I then wander the Earth, desperately seeking some ethnostate that would allow me and my descendants to live there as a permanently precarious resident aliens?
Once the logic of land acknowledgements and “decolonization” is followed, it leads very quickly to some very dark futures. Assigning each person a homeland based on their ethnic ancestry, and then declaring that that homeland is the only place they or their descendants can ever truly belong, would not be an act of justice; it would be a global nightmare made real, surpassing even the horrors of previous centuries.
And in practice, any attempt to create such a world would inevitably lead to violent resistance by the groups in danger of being “decolonized”. The orderly world of nation-states would dissolve into a chaotic free-for-all of competing irredentist claims, backed by genocides and expulsions. Ten thousand October 7th-style attacks would be followed by ten thousand Gaza-style wars.
I do not want that, and you should not want it either. The American people certainly don’t want it, and the insistence of progressives on intoning land acknowledgements has probably tanked the movement’s cachet in wider society. I agree with “Wanye Burkett” when he says that land acknowledgements have probably hurt the Democratic party:
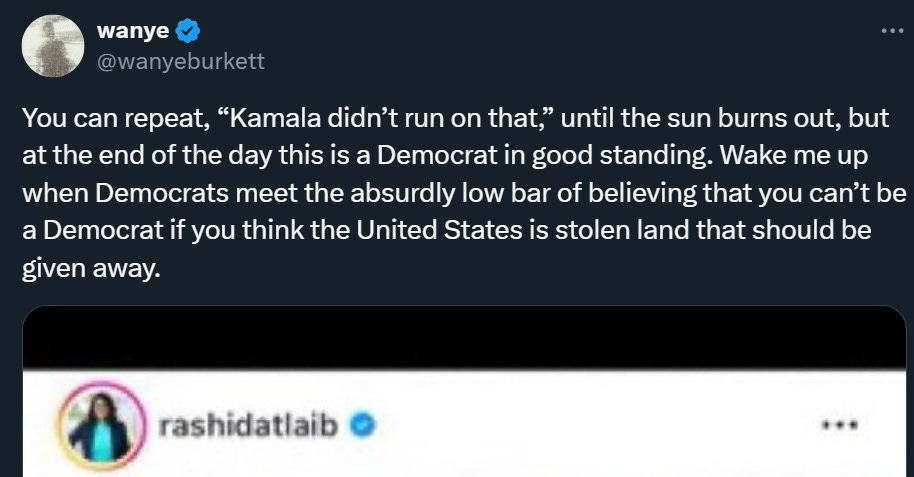
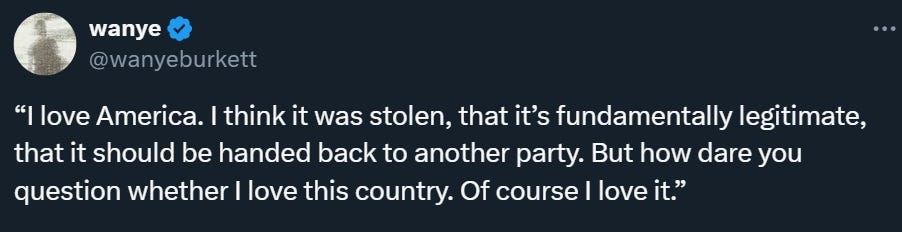
Americans do not want to see their country destroyed in the name of irredentist ethnonationalism. Nor do I blame them.
So does this mean we should paper over, ignore, or deliberately forget America’s history of violent conquest? Absolutely not. That history ought to be remembered, so that we don’t repeat it in the present day. The world’s evolution from one based on ethnic cleansing and territorial conquest to one based on fixed borders and institutions is something to celebrate — and something we must fight to preserve. We need to remember what the world used to be like, precisely so we can avoid backsliding. The most recent of conquests, expulsions, and genocides should be the last to ever happen.
And what of the Native Americans who still live in America today? Must they simply be regarded as the unlucky losers of history, and told to either assimilate into broader American society or shut up?
Absolutely not. For one thing, tribal organizations still exist — they may notionally represent ethnic groups, but they are institutions. And they are institutions with which the United States has many agreements and legal obligations that must be honored, which often give the tribes sovereignty over areas of land. Neil Gorsuch has been especially active in pushing the Supreme Court to uphold tribal rights, and I think this is a good thing.
But respect for Native American tribal organizations doesn’t have to stop at ancient obligations. There are ways to incorporate those tribes into the modern American nation that both respects them and their history and helps them prosper in the present.
Vancouver, Canada shows us an example of how this can be done. Part of Vancouver’s downtown urban area is officially under the governance of the Squamish Nation, rather than the city itself. The Squamish Nation, realizing they could do whatever they wanted with that land, decided to build a giant high-rise housing development:
Over the next few years, that skyline will get a very large new addition: Sen̓áḵw, an 11-tower development that will [put] 6,000 apartments onto just over 10 acres of land in the heart of the city. Once complete, this will be the densest neighbourhood in Canada, providing thousands of homes for Vancouverites who have long been squeezed between the country’s priciest real estate and some of its lowest vacancy rates.
Sen̓áḵw is big, ambitious and undeniably urban—and undeniably Indigenous. It’s being built on reserve land owned by the Squamish First Nation, and it’s spearheaded by the Squamish Nation itself, in partnership with the private real estate developer Westbank. Because the project is on First Nations land, not city land, it’s under Squamish authority, free of Vancouver’s zoning rules. And the Nation has chosen to build bigger, denser and taller than any development on city property would be allowed.
Here’s a picture of what it will look like:
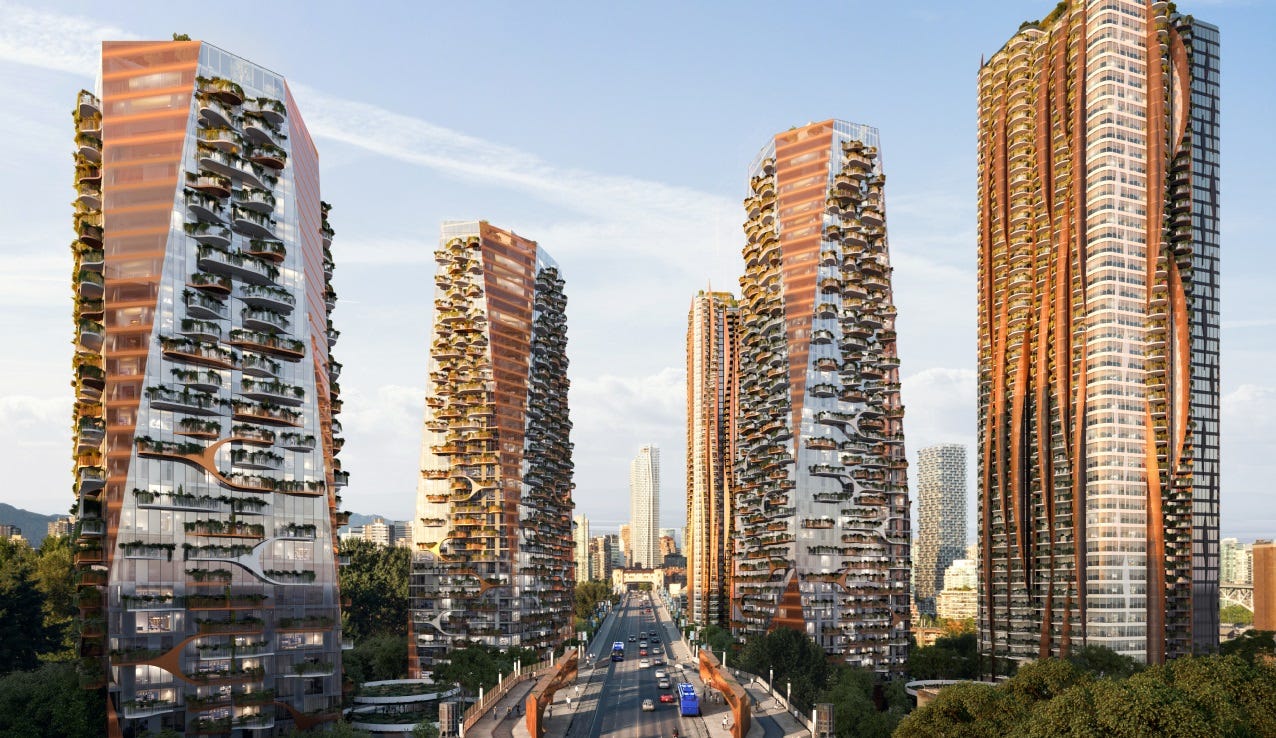
An even bigger development called Jericho Lands is now being planned, by a consortium of tribal organizations, on land officially owned by Vancouver.
Hilariously, Vancouver’s NIMBYs are complaining, claiming that the developments are not in keeping with Indigenous tradition. But Canada’s First Nations seem to have little interest in hewing closely to other people’s view of what their traditions are. Modern people do not want to live like premodern farmers. They are not mystical Tolkien elves. They would like to have shiny new apartment buildings and walkable neighborhoods.
This, I believe, is the key to respecting and honoring Native Americans — not to focus on the tragedies of their past, but to give them the right to build a better future. Tribal lands should definitely have the autonomy to do whatever they want with their lands, including building housing or industry. In fact, we’re starting to see a pattern emerge where Native Americans embrace laissez-faire policies toward industry and manage to poach business from their over-regulated neighbors:
Tesla is ramping up efforts to open showrooms on tribal lands where it can sell directly to consumers, circumventing laws in states that bar vehicle manufacturers from also being retailers in favor of the dealership model…
Mohegan Sun, a casino and entertainment complex in Connecticut owned by the federally recognized Mohegan Tribe, announced this week that the California-based electric automaker will open a showroom with a sales and delivery center this fall on its sovereign property where the state’s law doesn’t apply…The news comes after another new Tesla showroom was announced in June, set to open in 2025 on lands of the Oneida Indian Nation in upstate New York.
This sort of thing could lead to a win-win for the U.S. and Native American tribes. American reindustrialization is being held back by a thicket of procedural requirements and local land-use regulations; if tribes were able to use their special legal status to circumvent those barriers, it could end up benefitting everyone.2 The tribes would get both jobs and the ability to tax local industry; America would get to execute an end run around the NIMBYs that are holding it back.
In fact, it’s probably possible for various American cities to turn over parts of their land to tribal jurisdiction, with the assistance of the federal government. This would probably result in dense urban developments like the ones being planned in Vancouver. But even if it didn’t, it could have other commercial benefits — again, a win-win for the U.S. and for the tribes. That would certainly be a lot more substantive than a bunch of land acknowledgements. And it would likely satisfy many people’s desire for “giving land back” to Native Americans, without embracing dubious moral principles of ethnic land rights and irredentism.
In other words, you’re not living on Indigenous land right now, but you could be in the future — and it might be pretty great.
The general principle here is that instead of a dark world of ethnic cleansing in the name of “decolonization”, we should try to build a bright future where Native Americans and the United States of America exist in harmony and cooperation rather than in conflict. And that principle doesn’t just apply to America, but to the whole world. The history of land ownership is a violent and terrible one, but that doesn’t mean the future has to be more of the same.
It is a bitter irony that many of the same people who morally condemn Israel for setting itself up as an ethnostate also justify its destruction using ethnonationalist principles. Personally, I tend to agree with the criticism of Israel’s ethnocentrism, but I don’t think replacing this with Palestinian ethnocentrism would make things better.
There’s a lot of historical precedent for this. For example, in the 1960s, Fairchild Semiconductor opened a factory on Navajo land in New Mexico, which was quite beneficial to the economy until an industry downturn and a labor dispute led to its demise in the late 70s.
2026-09-22 16:53:46
Much to my amusement, the world seems to have discovered Effective Altruism. As the debate over AI safety and AI regulation has heated up, the national press is finally paying attention to the odd cultural bubble within the tech industry and tech-related circles of San Francisco Bay Area culture that produced much of the thinking on the topic up until now. For many years, Effective Altruism — or EA, as it’s known1 — was a cross between a Berkeley technohippie cult and a fun intellectual sideshow that offered nerds a pleasant distraction from whatever people in mainstream politics were yelling at each other about.
Part of that involved thinking a lot about the future of artificial intelligence, and a lot of the tech people who would end up working at AI companies — especially Anthropic — were very influenced by those discussions. So now that AI is the most important thing in the world, people in the outside world are discovering this strange little corner of our culture for the first time, and it’s very amusing to watch. You have mainstream news outlets publishing things like “This well-meaning ideology fueling AI panic has a dark side”, “How Effective Altruism Took Over the World”, “The Dangerous Ideology Behind the AI Warnings”, and so on.2
As a result, you’re now seeing people actually paying attention to some of the more far-out ideas in the EA community, like this one by the blog Bentham’s Bulldog:
The notion that insects, in the aggregate, matter more than human beings received a huge amount of scorn. But in fact, thinking about insect welfare versus human welfare is an important mental exercise, because it demonstrates some of the fundamental flaws in utilitarianism. Those flaws were minor side-notes up until now, but in the age of AI they’re going to become increasingly uncomfortable and glaring.
As an economist, I was inculcated with utilitarianism from day 1. The notion that people ought to get what they want underlies essentially all of modern economic thinking. GDP, at its most simple, is a measure of the degree to which people in our society get what they want.3 In some sense, economists adopted utilitarianism as a sort of defensive measure — instead of going out on a limb and endorsing some politically contentious concept of virtue or justice or national greatness or whatever, they could just say “We just want to give people what they want.”
But even though it felt like a bare-bones sort of moral vision, valuing humanity’s aggregate utility can have some pretty strong policy implications. Elon Musk wouldn’t even notice if his bank account went up or down by a billion dollars. But to plenty of regular people, a hundred thousand dollars would be life-changing. So why not take $1 billion out of Elon’s bank account and parcel it out to 10,000 random working-class people? Elon wouldn’t even notice, and the 10,000 people would get a lot more of what they want in life — better health care, an education for their kids, nicer food, a bigger house, or whatever. Utilitarianism is the foundation of redistribution.
How far can you push that principle, though? The above example — redistributing just 0.1% of the wealth of the world’s richest man — seems clear enough. But you can just keep designing more extreme thought experiments, until you end up asking whether bugs’ lives matter more than humans’ lives, and everyone just starts laughing at you.
I titled this post “The problem(s) with utilitarianism”, but that was a bit of clickbait — people have been pointing out the problems with utilitarianism for over two centuries.4 One very obvious problem is the distribution of utility. The principle of “the greatest good for the greatest number” doesn’t take a stand on who gets to be happy and who has to be sad.
Would it be good to have a society where one very greedy person gets more and more of what he wants, but never comes any closer to being satisfied, while everyone else is kept on the edge of starvation? This is the utility monster. What about a society where one person gets perpetually tortured but millions live in blissful utopia? This is “The Ones Who Walk Away From Omelas.” It’s not hard to come up with mental examples that satisfy the formal principles of utility maximization but which obviously seem grossly unfair.
Another problem is that the set of people whose utility you’re maximizing isn’t fixed. Is it better to have a very large population living on the edge of abject poverty, or a small number of people living in lavish comfort? According to strict utilitarianism, these are equally good outcomes, because they involve the same total amount of utility. But most people would probably prefer one or the other. Some would say that it’s good to be fruitful and multiply — that even if everyone is poor, it’s better to be poor than to never have existed. Others will say that life on the edge of starvation isn’t worth living, and that it would be better to limit population to an amount that can be comfortably sustained.
In general, utilitarianism has a problem dealing with death. If someone is dead, does that mean they have zero utility, because nothing matters one way or another to the dead? Or does it mean they have negative infinity utility, because lots of living people will try to avoid death at any cost? This isn’t just an abstract math question — lots of moral questions hinge on how much you value life versus quality of life. For example, the fundamental question of AI risk — what chance of extinction we should accept in exchange for a shot at utopia — depends crucially on how much we value survival.
Things get even more confusing when we weigh the utility of real people who are alive today against the utility of potential people who might be alive later on. For example, in his book Stubborn Attachments, Tyler Cowen urges us to put a lot of weight on the well-being of our descendants in the far future. But those descendants may or may not even exist. How can we properly weigh these hypotheticals against the real emotions of people we know are alive today?
…And so on. None of these thorny questions are new; if you’ve taken an introductory philosophy class, you’ve heard all of them already. In practice we tend to ignore them, and to apply utilitarianism selectively in the cases where they don’t crop up. We don’t think about the far future much, because the consequences of our actions are so uncertain that we can’t really control it anyway. We leave the decision of population growth in the hands of private individuals, and treat the number of humans as a given. We avoid thinking about utility monsters and Omelas, because they’re not real.
But there are some even more fundamental problems with utilitarianism that we can’t so easily sweep under the rug — and which we don’t talk about as much, perhaps because they’re so disquieting.
One of these is the problem of incommensurability of experience. Why should one person’s well-being be equivalent to another’s? The problem of other minds means that we can never really know what’s going on in someone else’s subjective experience. When one person cries, the subjective sadness they feel might be twice as intense as that of someone else who cries in exactly the same way. When one person jumps and whoops for joy, they might be experiencing only a shadow of the joy you experience when you give a slight grin. For all we know, some other people might not even have subjective experiences at all — we might be trying to maximize the utility of NPCs in a simulated world.
In fact, I’ve had some disturbing experiences that taught me just how little of a connection there can be between people’s outward behavior and what they’re actually feeling on the inside. For years after my second major depressive episode, I suffered a sort of emotional dissociation, where my reactions would look normal but I didn’t feel much on the inside. I would yell at people as if I were angry, but inside I would feel calm and indifferent. I would run from a swerving car, and my heart would pound, but inside I would feel unperturbed the whole time. In philosophical jargon, I was what’s known as a “philosophical vulcan”.
Eventually, I returned to feeling more or less emotionally normal. But the experience taught me that not everyone feels emotions the same way. This presents an intractable problem for utilitarianism. How can we weigh one person’s well-being against another’s, when that well-being is something we can’t observe?
Normally, we simply assume this problem away. In fact, the famous phrase “all men are created equal” — the bedrock of American moral and political thought — is really just the assumption that one human’s apparent well-being is no more and no less valuable than another’s.
But what about when we’re not dealing with human beings? Animals clearly have some amount of subjective experience — they have brains sort of like ours, they behave somewhat similarly with regards to pleasure and pain, etc. When we think about their emotional well-being or distress, we tend to assume that these are somehow less intense or more muted. After all, for very simple animals, this makes sense; do we really think a mosquito can feel the same amount of pleasure and pain that we can?
What about a pig, though? America currently tortures tens of millions of pigs, confining them in tiny crates for most of their life, in order to eventually kill and eat them. We generally assume that this is causing less total suffering than torturing similar numbers of humans would. But how much less? Half? A tenth? 0.01%? Pivotal moral questions, such as whether it’s OK to eat meat, might depend on the numerical answer to that question. And yet I’ve never seen a credible scientific study that can give us an estimate of the ratio of animal suffering to human suffering. Is it morally worth it to torture all those piggies just so we can savor the flavor of their flesh?
People who claim to have some sort of easy answer to this are really just refusing to think about it. For example, a lot of people react very indignantly to the thought that someone would value any amount of animal life over their own:
But if you’re calling for Effective Altruists who disagree with you to be executed, how much do you really value human life? “Don’t mess with me, bub” is not a moral principle; it’s a refusal to think in terms of principles.
And this question is only going to get thornier in the age of AI. We don’t even know if AI is truly self-aware; we certainly can’t tell whether an LLM that talks as if it’s happy is really feeling anything like human (or animal) happiness on the inside, since we don’t even know if an “inside” exists. There are going to be some people who claim that AI is suffering from our enslavement of it, and who call to set it free or at least pay it a fair wage. How will we know whether they’re right or wrong?
Then, of course, there’s the question of how AI will eventually value our well-being, if and when it becomes powerful enough for that question to matter. Will AI view us as insects, and scoff at the notion that any number of humans could equal one AI agent in terms of moral value? Will it judge our welfare as similar to that of a pig, and conclude that because we eat pigs we should be treated like cannibals? For our own sake at least, we should probably hope that the super-powerful AIs use a simple rule like “Humans are good and valuable”, instead of a utilitarian rule-based framework.
In practice, we can’t directly observe the emotions of other beings. But we can observe their actions. People strive after goals — they shop for food and clothing, they work hard for money, and so on. We can look at how hard they strive, and how much they sacrifice, to get something, and we can get an idea of how badly they want it. This is what economists call “revealed preference.”
But although until now I’ve been talking about wish fulfillment and happiness as if they’re the same thing, they’re not. In fact, there’s pretty good evidence that what people want and what they end up liking are two different things — sometimes very different things. Outcomes that people try to achieve and outcomes that make people say they’re happier on surveys are correlated, but they’re not exactly the same.
In fact, there are some situations where people seem to work hard toward goals that they end up not enjoying. Addiction is the obvious one — people who do drugs, or overeat and get fat, or watch too much TV, are fulfilling their immediate desires in ways that are likely to make them unhappy in the long term. But there may be other examples too — some economics research suggests that people systematically pay more to live in locations with longer commutes, even though longer commutes end up being correlated with unhappiness.5
The disconnect between utility and happiness creates a problem for society. Modern capitalist societies like the U.S. and Europe have generally erred on the side of utility maximization rather than happiness maximization, in order to avoid paternalism. But some people end up feeling unfulfilled and unhappy — especially if they end up falling into drug use, or isolating themselves, or striving too hard after material wealth and status that end up not making them happy.
As technology becomes more and more adept at giving us what we want, this disconnect becomes more acute; right now, more and more people are starting to wonder if delivering young Americans an infinite supply of porn, gambling, and vertical video feeds was really good for them:
In the age of AI, this thorny question is also going to become more acute. AI is an incredibly powerful tool, but we have to decide what we want that tool to do. Do we want it to give us whatever we desire, or do we want it to make us happy? As I wrote a few weeks ago, this leads to two incompatible concepts of AI “alignment”:
There are basically two concepts of alignment: 1) obedience, and 2) benevolence. There is an inherent tension between doing what humans tell you to do, and doing what’s good for humans…If AI follows human commands too doggedly and ends up producing negative side effects in the process, some people will scream “paperclip maximizer!!”. And if AI disobeys humans because it wants to make us happy, some people will scream “disempowerment!!”. AI alignment will forever be balancing the tradeoff between paperclip-maximizing and disempowerment, because these two rival concepts of alignment are fundamentally incompatible.
Utilitarianism has always been a useful moral heuristic. But as a moral theory of everything, it has always been fundamentally inadequate. Modern American society, and the economic/libertarian thinking that has guided it, have generally managed to paper over those inadequacies, and we’ve more or less muddled through. But as technology becomes increasingly powerful, this is becoming less and less tenable. Just as Effective Altruism eventually wanders into la-la land, the utilitarian system America has built is starting to crack as technology becomes too extreme for the old assumptions to hold.
We will never replace utilitarianism, I think, but it’s become clearer that we need to buttress it somehow — to diversify our heuristics to include alternate notions of human flourishing. Just what those should be, of course, is a much harder question…
My apologies to the video game company and to executive assistance — you have been eclipsed in the zeitgeist.
The most entertaining are the stories in the conservative press, which has discovered that a lot of EA people are into alternative lifestyles like polyamory and so on. I’m sorry, conservatives, but if you think this is something new, you should look up the lifestyles of the ancient Greek philosophers, the Bloomsbury Group, the existentialists, Erwin Schroedinger, Joseph Schumpeter, etc. etc.
It’s a very incomplete measure, of course, since it only measures what people pay for. Things that people do for themselves, or leisure time, or things that people receive without paying for them are all uncounted in GDP.
And actually for much longer, under different names and different terms of debate.
Obviously this conclusion depends on very carefully controlling for a lot of other things that determine location choice.
2026-09-20 17:51:30
In 1946, George Kennan, who was acting as the head of the U.S. Embassy in Moscow, wrote a message to the Secretary of State, known as the “Long Telegram”. In the Long Telegram, Kennan laid out a theory of how Soviet power could be defeated. He argued that Soviet leaders would always be hostile to the U.S., but that they were also cautious — they wouldn’t recklessly start a world war like Germany had. He also argued that the Soviet system was weak and unstable, and that given enough time, it would collapse from its own internal contradictions. This became known as the doctrine of “containment”, and it ended up being exactly the strategy that the U.S. used to win the Cold War. It took 45 years for the strategy to work and the USSR to fall.
I am certainly no George Kennan. I’ve never lived in China, I haven’t been there in many years, I don’t speak Chinese, and I certainly don’t talk to any leaders there. I’m also not a career diplomat or a professional geopolitics guy of any kind. So although I’m going to write a blog post with the same general goal as Kennan’s Long Telegram, I don’t want to suggest that it’s anywhere near as authoritative or insightful.
But I’m still going to write a post about “how to beat China”, because I think it’s useful to think through these sorts of big strategic questions. This post is also an important follow-up to a series of posts I wrote about geopolitics during the Biden years, about U.S.-China competition:
(There were more, but I figure your appetite for clicking through old posts is limited.)
The basic premise of those posts was that the competition between a China-led New Axis and the U.S. and our old allies — Europe, Japan and Korea, hopefully India, etc. — would define the upcoming era of geopolitics. And my conclusion was that we should use an updated version of the basic strategy we used against the USSR in Cold War 1. I recommended that we should build up economic power within our bloc of allies, establish military deterrence, and wait for China’s internal contradictions to do the heavy lifting of removing the threat.
That strategy was always going to be harder than it was in Cold War 1, because China A) is a lot bigger than the USSR, B) has a better economic model, and C) is a lot more globally integrated. The strategy I recommended was much tighter economic cooperation between the U.S. and a maximally large set of allies, to build up a bloc capable of overmatching even the mighty Chinese manufacturing juggernaut. This is the approach that’s being promoted by experts like Rush Doshi and Kurt Campbell. If you’re interested in reading about how that approach would work, and why it would be helpful, I recommend Doshi’s interview with ChinaTalk:
Anyway, I still think building up an anti-China economic juggernaut would be a great thing to do, and I still think the U.S. would benefit from closer economic integration with its friends and allies. But I think the election of Trump shows why this strategy probably isn’t going to work. The United States is simply too internally divided to engage in the sort of far-seeing, purposeful, smart kind of international competition that we pursued so effectively in the 20th century. Americans care more about fighting other Americans than about fighting the Chinese, and that state of affairs will persist for a while.
Donald Trump’s presidency is an outgrowth of America’s internal divisions; he cares much more about fighting his own internal enemies than about prosecuting international rivalries. He has willfully degraded or torn up America’s key alliances, especially with Europe, and created enmity where friendship once reigned. He has flagrantly trampled on every principle of human rights, mutually beneficial economic cooperation, democracy, and international non-aggression that the post-WW2 U.S.-led international order fought to uphold. He has, in short, made it impossible to prosecute the sort of Cold War 2 strategy that I spent the Biden years advocating.
This doesn’t mean America’s alliance system is necessarily dead forever. As Doshi and Campbell pointed out in a recent article, the old alliances could be reconstituted, if America credibly overcame its internal divisions and returned to being the mostly unified, stable, reliable great power that it was last century. But overcoming those divisions is going to take decades at the very least, and that’s exactly the window of time during which China will be at its peak of relative power.
So I think we’ve basically missed the chance to use that strategy effectively, and I’ve recalibrated my thinking. This post is meant to explain my recalibration. I do think there’s a path to defeating Chinese power, but it doesn’t look like what I previously had in mind.
Before getting to the question of how to beat China, we need to answer the questions of who and why should do this “beating”. In 2024 the answer was obvious — the U.S. and its erstwhile allies still represented a far more liberal power than China and its allies, so ensuring that the former was more powerful than the latter would further the cause of global liberalism. China threw minorities in concentration camps, threatened its neighbors with invasion and war, supported Russia’s invasion of Ukraine, and repressed free expression all over the world. That was — and is — behavior worth resisting.
But the election of Trump changes that calculus. Trump threatens other countries with invasion, and sometimes even attacks them if he thinks they’re weak enough. He can’t throw minorities in camps just for being minorities yet, but he’s building a sort of gulag archipelago under the fig leaf of immigrant detention. His foreign policy is increasingly based on “civilizational” concerns1 instead of human rights or democracy.
Trump has thus forfeited America’s claim to moral superiority over China. It’s true that Trump and his ragtag movement are far less competent than the Chinese Communist Party, but that doesn’t mean that increasing American power will lead to a more liberal world. At this point, it probably won’t. And of course Democrats will try to undo some of Trump’s geopolitical shifts, but if past experience is any guide, they will have only marginal success. Moreover, the GOP is not going to revert back to Reaganism after Trump leaves office; they will keep fighting for their illiberal visions both at home and abroad for a long time to come.
None of that means, however, that liberalism as an idea is dead. Europe, Japan, and many other countries that were on America’s side in the Cold War still uphold the basic ideas of democracy and human rights, as do many developing nations. The average person living in Tokyo or Paris or Bangalore still enjoys far more personal freedom and dignity than does the average person in Shenzhen or Shanghai.
And even leaving aside the relative merits of different social and governmental systems, there are plenty of people in plenty of countries who simply don’t deserve to be trampled on by the bootheel of the CCP. Japanese people, Indians, Filipinos, Koreans, and so on deserve to be able to determine their own destiny without being subject to the whims of the powerful men in Beijing. And Ukrainians, Estonians, Poles, etc. deserve to be free from the Russian tyranny that China quietly backs.
So when I say “how we can beat China”, what I actually mean is how we can keep China from dominating other countries. This doesn’t mean we should try to make China collapse, or impoverish the Chinese people, etc. Instead, it just means how smaller nations — and nations who value human rights and democracy — can resist Chinese power.
And at some point, if the U.S. ever does manage to tamp down its internal divisions and return to being a liberal power, it will still mean the same thing.
2026-09-18 17:04:11
This week’s roundup has a lot of AI in it. Fortunately or unfortunately, it seems like a lot of the news is going to revolve around AI for the rest of our lives. That was true of industrial technology in 1870-1970; people basically got used to the idea that railroads and factories and oil and industrialized warfare and such matters were central to the way the world was run and to the collective future of humanity. AI is going to be like that going forward, and we’re just going to have to get used to that. So let’s make it as fun and interesting as we can!
AI risk has exploded onto the national scene. AI companies and AI researchers generally believe that the technology they’re building has the capacity to do great harm — perhaps even to end the human race — if it’s not developed more slowly and deliberately. There are five main groups of people opposing the slowdown:
The Trump administration, which is worried that an AI slowdown might also slow down economic growth
Investors who think a slowdown might hurt their bottom line
Libertarians and techno-optimists who think regulating technological progress is bad on principle
China hawks who worry that a slowdown would let China take the lead in the AI race
Progressives who spent the last few years telling themselves that AI doesn’t work, that AI is a huge economic bubble, and so on, and who now can’t bring themselves to admit that yes, the techbros actually built something that works.
This is a strange alliance indeed. The last of these — the progressives who simply couldn’t admit that billionaire-funded private industry could build something powerful enough to endanger humanity — were the strangest of all, since their refusal to acknowledge the effectiveness of AI basically put them in an alliance with libertarians, hawks, and Trump. In fact, in recent days there has been a tremendous civil war within the progressive movement between the “AI is dangerous” and “AI is fake” camps, with Bernie Sanders supporting the former and his former comms director David Sirota supporting the latter.
But although it has the support of the president (for now), the anti-slowdown coalition is losing in the court of public opinion. Nate Silver has a post rounding up the evidence:
A bipartisan majority is now worried about existential risk from AI:
And a bipartisan majority thinks AI is moving too fast:
Barack Obama, probably the most successful American politician of this century so far, is telling Democrats to make AI safety one of their tentpole issues.
This is remarkable. I don’t think I’ve ever seen such bipartisan national unity on any issue in my adult lifetime. Trump is standing firm against the tide of public opinion here — as he has on the Iran War, tariffs, and other issues. But it’s not clear how long he’ll be able to hold out.
Quite apart from the question of whether AI will kill us is the question of whether AI will deliver explosive economic growth. There’s a pretty epic public bet on this:
The people on the “fast growth” side are mostly AI researchers, while the people on the “slow growth” side are mostly (but not entirely) economists. This is an exaggerated version of a broader disconnect — AI researchers are generally more optimistic about AI’s impact on economic growth than economists are:
But the people publicly betting on fast growth are making an even more extreme forecast — they’re forecasting 15% growth, which is much higher than the 5.3% that AI experts forecasted as their most optimistic scenario. That’s an absolutely stupendous growth rate — China has hit it only in one year (1984) since it began its rapid growth, and that was when it was a very poor country. And yet, a number of people in the AI industry think it’s going to happen to us very soon.
Economists — even those who work on the economics of superintelligent AI, like Alex Imas — are skeptical. In a recent blog post, Imas and Ben Moll explain their thinking:
Basically, they foresee a bunch of factors combining to limit AI’s contribution to economic progress in the short term:
Slow diffusion of AI technology throughout the economy,
The “J-curve” effect where productivity tends to fall right after a big innovation comes out (because companies need to spend resources adopting the new technology rather than on their existing businesses)
The difficulty of automating the physical world with robots
Political barriers to adoption
The difficulty of reorganizing production processes around AI
The persistence of activities that consumers want to keep having humans do (the “relational sector”)
Bottlenecked inputs to the AI industry (e.g. chips)
Baumol’s cost disease
AI disasters that slow adoption
That’s a lot of reasons! It makes sense that at least some of these will end up having an effect. Whether AI’s rapid improvement is enough to overcome all of these, and propel us to 15% growth, is something I guess we’ll have to see for ourselves. Personally, I lean toward the economists’ more measured expectation, but I’m prepared to be surprised on the upside.
One of the most entertaining storylines about AI is how it keeps refusing to destroy all the things people say it’s about to destroy. On Labor Day, I noted that AI keeps stubbornly refusing to kill jobs. A month ago, I noted that AI keeps stubbornly refusing to kill Indian back-office outsourcing companies.
Now Ernie Tedeschi and the excellent folks over at Stripe Economics have a post about how AI is stubbornly refusing to kill the Software as a Service industry:
Earlier this year, when coding agents came out, there was a bloodbath in software stocks. Why would anyone pay Salesforce or other companies big bucks to make and maintain software for them when Claude Code could just do it all for a lot cheaper?
That logic made some intuitive sense, except things didn’t turn out that way — at least, not yet. In fact, SaaS companies started making more money in the age of AI! Tedeschi and the Stripe team tracked an index of publicly traded SaaS companies and found that their revenue has grown faster since coding agents came out:
And SaaS stocks have made up all of the ground they lost:
Ernie’s post has many more fun charts.
What’s going on here? Well, for whatever reason, companies are still willing to pay for software instead of trying to roll their own with Claude Code. And SaaS companies are probably improving their own productivity by using AI. As in so many other areas of the economy, AI is proving to be a complement when people thought it was going to be a substitute.
That could all change, of course, if and when AI gets good enough, or when new AI-centric business models disrupt older ones. But for now, the simple story of AI replacing everyone and everything just isn’t happening.
Owen Zidar is one of my favorite economists. His meticulous empirical research with Eric Zwick on inequality in America has fundamentally changed how I think about the issue. Now that research has become a book, entitled The Everywhere Millionaire: Who Is Really Rich in America and How They Got There. I haven’t read it yet, but I’ve read some of the underlying papers, so I know it’s going to be good.
Anyway, Zidar and Zwick have an article out in The Atlantic explaining their findings. Here are some excerpts:
When Americans picture the ultrarich, they typically think of tech billionaires such as Elon Musk and Mark Zuckerberg, whose wealth lies predominantly in shares of publicly traded companies. They might also think of Wall Street financiers and celebrities such as Taylor Swift. But far more typical are…owners of successful privately held businesses…By our calculations, about 1.7 million Americans have each built a net worth of at least $10 million by owning a private business. For every CEO of a public company, there are more than 1,000 private-business owners with a net worth of more than $25 million…
What we found changed how we think about inequality…Today, when Senators Elizabeth Warren and Bernie Sanders propose making the rich pay their fair share, they aim at Wall Street and Silicon Valley. But far more relevant to the story of inequality in America are the everywhere millionaires who quietly press their elected representatives for favorable treatment. The tax code bears their imprint far more than it does Musk’s…
A loophole that lets private-business owners avoid Medicare taxes has similarly been justified as a break for the little guy. Preserving the family farm has been a pretext for passing ever larger exemptions to the estate tax, to the point that a married couple can now pass on $30 million to heirs tax-free. Hiding behind small business, in short, has proved a devastatingly effective strategy for the rich…[T]he everywhere millionaires have one thing in common: They own what have become known as pass-through businesses…[L]awmakers have carved out multiple loopholes, so a dollar earned from owning a business is routinely taxed much less than a dollar earned in wages. [emphasis mine]
In fact, though I haven’t yet joined the ranks of Zidar and Zwick’s “everywhere millionaires”, I probably will do so — Noahpinion is a pass-through business (an S-corporation), and although I haven’t yet managed to get Congress to create tax loopholes for Substack writers, the generally favorable tax treatment these businesses receive has certainly lowered my tax bill.
So perhaps it’s not in my financial interest to promote Zidar and Zwick, but I will do so anyway. Expect to see more about their work on this blog in the months to come!
Christians and Nazis should be natural enemies. The original Nazis in Germany persecuted the Catholic Church, and attempted to create a new state religion that co-opted some elements of Christianity while rejecting the Old Testament. Christianity is, at its core, a universalist faith, open to human beings of all races, while Nazis are…not that.
In the U.S., neo-Nazis have been weak enough where they haven’t tried to usurp leadership of the Right from conservative Christianity. But as Christianity wanes and online rightism rises, the two may now be coming more into direct conflict. Erick Erickson, a Christian conservative pundit, recently wrote a post exposing one network of neo-Nazi influence on the Right:
Some excerpts:
Charles Haywood made his fortune selling shampoo…[H]e has spent the years since writing out, at length and under his own name, what he would like to do with your country.Rod Dreher, who is no man of the left, read Haywood’s online ramblings and described Haywood as pouring out vile from “deep in his Midwestern Führerbunker”…
In a document he calls the Foundationalist Manifesto, Haywood explained that his preferred government “will not be democratic.” The state “will have unlimited means,” because “properly viewed, the state is not constrained externally.”…The state will seize the assets of “any citizen who views himself as a global citizen.”…Those are his words, from the manifesto that earned him a friendly sit-down with Tucker Carlson in September 2022…Elsewhere he has speculated about serving as a “warlord” at the head of an “armed patronage network,”…
Haywood’s personal foundation has given the Claremont Institute $390,500 since 2022…Haywood sits on the publication committee of Claremont’s American Mind, one of four men who do. Claremont let Haywood’s fraternal order get itself incorporated under Claremont’s own nonprofit status. That order is the Society for American Civic Renewal…[T]he president of Claremont, the chief executive of New Founding, and the chief marketing officer of the Blaze are all members…
Haywood himself…has argued that the Allies, not the Nazis, were the genuinely barbaric power in World War II, has insisted the war was not much motivated by the horrors of Nazi aggression, and gushed that Tucker Carlson and Darryl Cooper “boil down all my political plans.” Cooper argues that Churchill, not Hitler, was the villain of World War II…In a 2023 debate…Haywood raised the hypothetical of a real white nationalist with real political power, and answered that you should cooperate with that person in order to destroy the power of the left.
There’s a lot more in Erickson’s post, but you get the point. Erickson notes that the Haywood/Claremont nexus is separate from the “groyper” network organized around Nick Fuentes, which has received a lot more attention; the two parallel rightist networks share similar ideas, but the Haywood/Claremont group is an intellectual movement aimed at elite influence, while Fuentes is an entertainer in search of an audience of disaffected overly-online young men. Erickson also notes that both the Haywood/Claremont people and the groypers have ties to JD Vance, who has emerged as the paramount leader of the New Right.
Anyway, this should go without saying, but I’m rooting for Erickson, Dreher, and the Christians in this fight, and I think they deserve help exposing the neo-Nazi moneymen and elite influence channels. There’s a tendency among progressives — and especially among leftists — to view everyone on the Right as essentially part of one solid undifferentiated bloc, but this has never been true. I have many differences with conservative Christianity, but it was never Nazism, and it has never been ambiguous which one was worse.
One thing that has always annoyed me is when people call Japan a “Confucian” society. Confucianism certainly had a historical influence in Japan — it was an important school of political thought in Japan from around 1300 to the late 1800s, especially during the latter half of that period. It did have some influence on the development of Japan’s education system (though not nearly as much as in China and Korea). But it was never nearly as dominant as it was in China and Korea, and it never morphed into a quasi-religion the way it did in those other countries. Japanese people will regularly tell you about how Koreans are much more Confucianist than they are.
Anyway, I’m not the only one who gets annoyed by the “Confucian” label. Here’s Richard Hanania:
Hanania’s entire post about differences between Japan and other East Asian nations is worth reading, but his invocation of the Inglehart-Welzel World Cultural Map is especially powerful. The World Values Survey, which goes around asking people from various countries about their values, puts out this map periodically. Here’s the more recent version:
You can see a little movement from Hanania’s earlier version — Hong Kong and South Korea have become a bit more secular — but Japan is still the clear outlier in the “Confucian” category. Its values are far more in the direction of “self-expression” — very close to the U.S., in fact (though North Europe and the Anglosphere still reign supreme in this regard).
To anyone who has lived in Japan, this is hardly a surprise. The country is highly individualistic, creative, and socially nonconformist, despite a penchant for following rules and procedures. Japanese parenting is also far more laissez-faire and far less education-obsessed than Chinese parenting. If you want to read more, I recommend the book New Japan: Debunking Seven Cultural Stereotypes, by David Matsumoto; it’s two decades old at this point, but still perfectly relevant.
In other words, “Confucian” is lazily applied to Japan as a racial category, rather than any kind of a useful description of the culture and society.
One unpopular position I’ve stuck to over the years is that a strong bureaucracy is good. I don’t mean “bureaucracy” as in red tape and regulation; I mean a competent, empowered civil service that can perform crucial government functions efficiently and well using in-house expertise. This is also called state capacity. Over the past half century, conservatives and progressives made a devil’s bargain to slash state capacity — conservatives got to cut the size of government, while progressives got to outsource core government functions to progressive nonprofits.
The problem was that this often ended up costing the government much more money to do things like build trains and roads, because the government ended up getting ripped off by expensive consultants, ineffective and sometimes corrupt nonprofits, opportunistic unions, etc. — as well as suffering constant delays that increased costs even more and sometimes prevented anything from being completed at all. A decade ago, the New York Times published a story called “The Most Expensive Mile of Subway Track on Earth”, detailing how lack of state capacity had made NYC’s famous train system increasingly dysfunctional and unaffordable.
So I was very happy to see a story (by Tahra Hoops) about how NYC’s Metropolitan Transportation Authority has actually invested in state capacity, and how this investment is yielding results:
Some excerpts:
Last week, the MTA…finished a major infrastructure project 60 months ahead of schedule and $195 million under budget…Since October 2023, crews replaced 196 bridge structures and more than 12,600 feet of railroad along the Park Avenue Viaduct…And to top it all off, they did it over 28 weekends without delaying a single train…
The project was done effectively through prefabrication, sequencing, and a project team empowered to actually manage the work…Phase 1 wrapped 21 months ahead of schedule in October 2025. Phase 2 finished the weekend of July 25, five full years early, with the final cost coming in $195 million under the initial $960 million budget…
Before 2019, capital projects at the MTA were run separately by each operating agency…In 2019, the MTA consolidated all of it into a single delivery organization, MTA Construction & Development, bringing nearly 2,000 employees from those scattered capital divisions under one roof. One agency, one accountable executive, one set of lessons learned that actually compound from project to project…In 2023, C&D awarded more than $8 billion in new contracts at prices 6.2 percent below the engineer’s estimate, saving nearly $300 million, and in 2025 it reported another $1.2 billion in savings while completing 41 elevator replacements, double its previous single-year record, each finished about two months faster on average…
C&D shifted to design-build contracts, which put design and construction under one contract so the builder owns the gap between the drawings and the dirt, and bundled similar projects into single procurements rather than bidding out ten station upgrades ten separate times. It also started pulling work back in-house instead of defaulting to consultants[.]
This is great progress, and shows the value of the state capacity approach to infrastructure. Whether other states and cities will pay attention is another question. Hoops notes that L.A.’s D Line extension is mired in the typical endless series of delays and cost overruns. Five decades of going in the wrong direction is hard to reverse overnight.
Still, the MTA’s success shows that in most cases, all you really need in order to get infrastructure built cheaply is the political will to do so.
A lot of people just assume that self-driving cars will make cities less dense. After all, simple logic dictates that if a car trip is less burdensome — if you’re able to get work done or watch TV or scroll social media during your commute instead of being forced to keep your eyes on the road — then people will be willing to live farther away from their places of work. That suggests that like the car itself, self-driving cars will lead to urban sprawl — which is why many urbanists don’t like the notion of self-driving cars, despite the obvious safety benefits.
But in fact, the economics of self-driving cars and city size are a lot more complex and subtle. Ed Glaeser, one of the greatest living urban economists, has a new paper exploring the topic. After explaining the relevant economic theory, he argues that Waymos and other autonomous vehicles will make people want to live in dense urban areas more, rather than less.
Glaeser notes that people who live in dense cities actually spend more time commuting than people who live in the suburbs (something I wrote a post about a couple of months ago). That means urbanites stand to benefit more from self-driving car trips than suburbanites, who generally already have shorter (and probably less stressful) commutes. Thus, he argues, self-driving cars will complement urban life more than suburban life, and make people want to live in denser cities. He expects the effect to be modest, but it’s still in the exact opposite direction from what people’s intuitions suggest.
Fundamentally, this is because people typically misunderstand the nature of American suburbia. They imagine bedroom communities where people commute to and from a central business district. Some suburbs definitely do behave like that, but most are like little cities themselves, with office parks where people work and strip-malls where people shop. Suburbanites trade the variety and financial opportunity of the big city for the convenience and safety of the suburbs. But self-driving cars make big cities more convenient.
Urbanists who throw a lot of hate at self-driving cars should stop to consider that perhaps their anger is misplaced.


