


2026-11-05 23:16:59
The last year has seen incredible progress in model capabilities in certain domains — most notably programming, mathematics, and cybersecurity. Yet the real-world impact of these breakthroughs has been surprisingly modest — especially outside of those professions.
Lawyers, architects, salespeople, college professors, and others are certainly using AI models in their work, but AI models don’t seem close to transforming those professions the way they seem to be transforming mathematics and computer programming. And even in the software industry, we’re not seeing the kind of mass unemployment many people expected we would see once AI models reached human capabilities.
A big question is why — and whether the impact might grow in the next few months or years. Many people expect massive AI-driven disruptions to begin hitting other professions in 2028 or even 2027.
I don’t think that’s going to happen, and a concept from robotics helps to explain why: the sim-to-real gap. I encountered this concept when I was editing my colleague Kai Williams’s excellent September article about the scramble to collect robotics training data.
Suppose you want to train a robot to walk. One option is to create a virtual environment with a simulated robot. Then use reinforcement learning to reward behaviors that help the robot move around. The robotics startup Figure used this strategy last year and it worked! Figure said that it collected “years worth of simulated demonstrations in a few hours.” When they transferred the trained model to a real robot, the robot was able to walk “with no tweaks or changes.”
But this strategy doesn’t work as well for many other tasks. Kai gave an example where researchers tried to teach a robot to hammer a nail in simulation. The middle panel shows what happens if the robot tries to learn this task purely through trial and error:
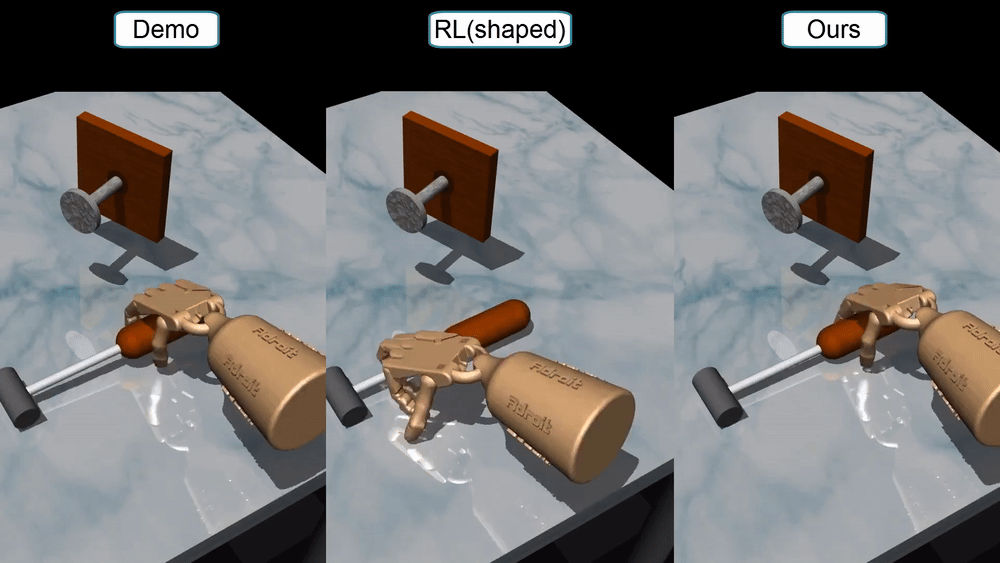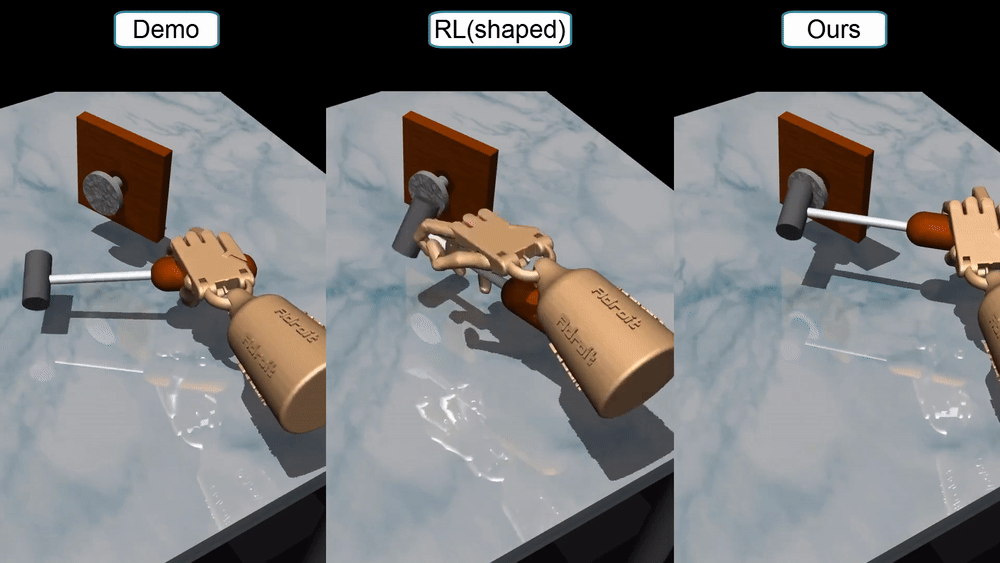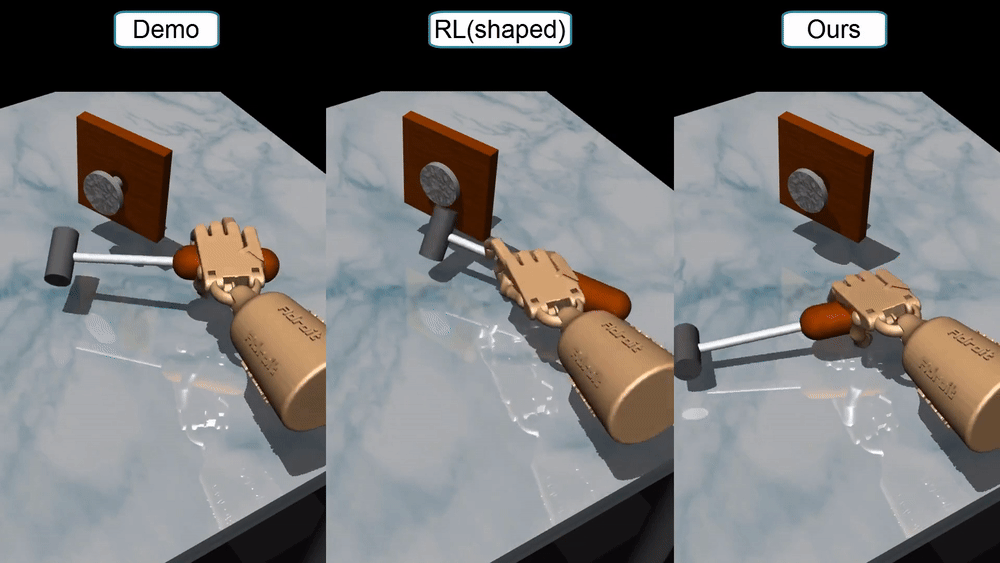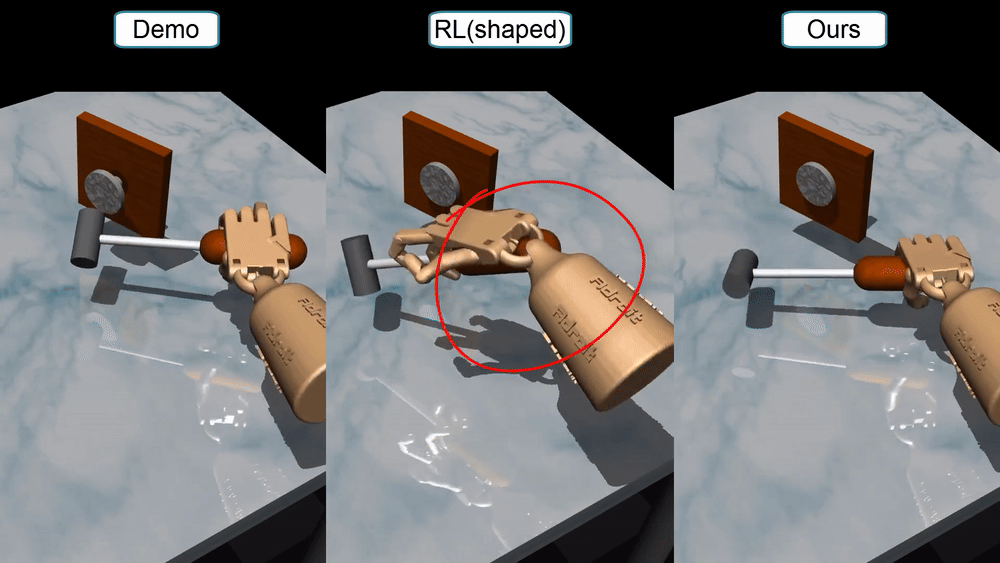
Why does simulation work for walking but not hammering? A key difference, as Bracket Bot CEO Brian Machado explained to Kai, is that “the floor doesn’t do anything.” Because the floor is a static object that doesn’t change in response to a robot’s actions, it’s very easy to simulate.
A hammer isn’t as easy to simulate. You need to account for all of the forces and frictions between the hammer and the hand. If the simulation is even slightly inaccurate, the model might learn a hammering technique that works in simulation but fails in the real world.
Most economically valuable robotics tasks are more like hammering than walking. They require robots to manipulate objects that behave in complex, hard-to-simulate ways. Think, for example, about a rope, a half-full glass of wine, or a balloon. We don’t know how to simulate objects like these with enough fidelity to train a robotics model. And we really don’t know how to simulate the far more complex behavior of people and animals.
This has big implications for the future of robotics. If a task can be simulated, then a company can collect “years worth of simulated demonstrations in a few hours,” as Figure did when it was training its robots to walk. Robot performance can be improved rapidly at low cost.
But if simulation isn’t an option, then companies are left with much less appealing choices. They can hire humans to generate training data — either by teleoperating a robot or performing tasks themselves — and then use that data to train a robot. Or they can deploy a robot that doesn’t yet work very well and have it improve by trial and error.
Each of these approaches has its advantages and downsides. But all of them are much slower and more expensive than training in simulation. And this is a major reason I — and many robotics experts — are skeptical that general-purpose robots will be ready for widespread commercial deployment in the next few years.
AI companies face similar difficulties outside of robotics. You might think that white-collar work doesn’t suffer from a sim-to-real gap because it mostly happens on computers. But I think that’s wrong. Almost every white-collar profession involves interacting with other people and the larger world — which is almost impossible to simulate. And this fact limits how quickly AI models can replace human workers in these professions.
In 2016, a DeepMind model called AlphaGo defeated Lee Sedol, one of the world’s best human Go players. Soon afterwards, DeepMind developed AlphaZero, a more powerful successor that achieved superhuman performance at Go (as well as chess and shogi) by playing millions of games against itself.
You can think of Go and chess as tasks with very small sim-to-real gaps. AlphaZero’s self-play is reminiscent of Figure’s virtual robots teaching themselves to walk in simulation. And as with Figure’s virtual robots, the skills AlphaZero learned in training transferred well to “real-world” games against human beings.1
Something similar has been happening in programming. Over the last 18 months, coding agents have revolutionized the programming profession. Instead of writing code themselves, programmers increasingly describe the code they want and rely on coding agents to generate it.
Here too, rapid progress has been made possible by a very small sim-to-real gap. Like Go, programming languages like Python and JavaScript have precise rules defining exactly how any given program should operate. This means that if LLMs hone their programming skills in a training environment, the skills they learn will transfer well to “real” programming tasks.
So too in mathematics. Four years ago, LLMs struggled with basic arithmetic. This year, frontier models have solved some of the discipline’s hardest problems.
Once again, this has been enabled by a minimal sim-to-real gap. A key move has been to use Lean, a language that allows mathematical proofs to be stated precisely and then verified automatically. This effectively turns mathematical reasoning into a computer programming task; frontier labs can automatically check whether a model has produced a valid proof for a particular problem. A proof that can be written in Lean is likely to be accepted by human mathematicians as well.
In short, we know how to train an AI model to achieve superhuman performance on a task if we can replicate that task in a training environment. In robotics, that describes locomotion tasks like running, jumping, and dancing — but not manipulation tasks like folding a T-shirt or painting a wall. Outside of robotics, games like chess and Go are easy to simulate. So are intellectual tasks like programming and proving mathematical theorems.
A crucial question for the AI industry is whether similar training techniques will work for other white-collar professions. Last year, OpenAI announced GDPval, a benchmark designed to measure the performance of frontier models in domains like mechanical engineering, social work, and real estate. In this benchmark, a model is given a PDF, spreadsheet, or other document describing a task and is asked to produce a new document in response. For example, given a spreadsheet of recent purchase orders at a company, a model might be asked to generate a new spreadsheet listing likely data entry errors.
Frontier labs hope they can train AI models to perform these kinds of cognitive tasks as effectively as they write computer code. And models have made significant progress on GDPval. When the benchmark was released a year ago, the best model, Claude Opus 4.1, got 47.6%. Today’s best models are scoring more than 85%.2
So are we about to see AI agents overrun finance and law and social work and architecture and mechanical engineering in 2027 the way they overran software engineering in 2026? I’m skeptical. And the concept of sim-to-real gaps helps to explain why.
2026-10-30 03:10:41
Back in June, Anthropic filed a confidential draft of its S-1 form with the Securities and Exchange Commission — a crucial step toward offering stock to the general public. On Monday, Anthropic announced that it had filed a public version of the same document. I read it cover to cover, and I learned a lot about the company’s finances — at least through June 30 of this year.
Overall, the company’s financial position is surprisingly good. Revenue soared between 2025 and early 2026, allowing the company to report its first-ever operating profit in the second quarter. At the end of June, Anthropic had more cash reserves than all but two non-bank companies: Google and Berkshire Hathaway.
However, the next couple of years could be challenging for the AI giant. Anticipating continued growth, Anthropic has committed to spend hundreds of billions of dollars on compute from Amazon, Google, SpaceXAI, Broadcom, and other companies. To recoup that spending, Anthropic needs its annual revenue to grow to hundreds of billions of dollars as well.
Anthropic hasn’t officially reported its third quarter revenue, but media reports suggest a modest slowdown in revenue growth. Revenue surged from $4.7 billion in the first quarter of 2026 to $11.6 billion in the second quarter. Third quarter revenue was $16.8 billion. That’s still incredible growth by normal corporate standards, but it’s a slower pace of growth than in the previous quarter.
So the biggest open question about Anthropic’s finances is why revenue didn’t grow faster in the third quarter — and what that says about the future. Maybe Anthropic’s revenue will continue growing exponentially over the coming year. In that case, the company will easily be able to pay for its compute commitments.
But it’s also possible that demand for Claude Code and Anthropic’s other products is nearing saturation. In that case, revenue might grow even more slowly in the fourth quarter and beyond. Then the company could struggle to make good on the hundreds of billions of dollars in spending commitments it has already made.
2026-10-19 21:33:47
My mother broke her hip in late 2022, and it triggered a long process of moving out of a house she’d owned since 1987. During the final stretch of cleaning out the place in late 2024, I found myself passing time by composing nonsense songs in my head. “Nasty rotten rusty moldy trash,” I sang to myself repeatedly as I hauled bag after bag of moldy garden supplies out of her dank basement.
I’ve recorded music for both personal fun and public release for decades — first using a 16-track digital recorder two decades ago, and using Logic Pro more recently. So I often keep audio notes of song scraps in Voice Memos on my iPhone for later development with vocals, guitars, piano, and drums I play or sequence myself.
So on that day in November 2024, I set down the trash bags and took a moment to sing the song I was hearing in my head into my phone, and then went on with my cleanout duties.
Many months later, in mid-2025, I decided to test the latest version of the AI music generator service Suno. Version 4.5 not only had the ability to generate an entirely new song from a text prompt, but also to transform an existing song into a different style or genre.
I thought it would be fun to feed my hastily sung voice memos into Suno with different genre prompts. The novelty of hearing my song scraps developed into full productions by AI quickly became addictive.
My “Nasty Rotten Rusty Moldy Trash” audio clip turned into an incredible 1970s psychedelic funk song with a saxophone line that still echoes in my head. (For those of you listening at home, the cool part starts 53 seconds in.)
Some of my other songs I never completed stunned me with transformations into thrash rock songs, psychedelic country fusions, or weirdly earnest ballads sung by an AI rip-off of Waylon Jennings.
I wound up uploading about 50 old recordings into Suno and asking it to render them into various genres, yielding hundreds of original AI-generated recordings. It was wildly fun to see how a professional producer or session musicians might interpret my music. I often still listen to the best ones in the car when I am driving around town.
I love my AI-translated songs, but my kids don’t. In fact, it’s unlikely anyone else on earth will ever want to listen to these recordings. Sure, I wrote the music behind them. But since they’ve been fed into the AI maw, it feels like they are missing a human touch or connection that might make them land with others. And yet I have had more fun listening to my own songs than I ever expected. I am an audience of one.
Until recently, making a high-quality piece of entertainment media — a song, movie, or video game — required a significant investment in time or money. That money had to come from somewhere, so you needed a large enough audience to provide it.
For example, if you wanted instrumental accompaniment for your song, you had to pay a real band. To do that, you needed to sell records. To sell records, you needed a lot of people to want what you made. So the crowd wasn’t optional; it was how the band got paid.
Now the simulacrum of a band costs almost nothing, relatively speaking—just me and my personal time and whatever the AI service costs. When the “band” costs nothing, you don’t need the crowd anymore.
That’s why my phone now has several hundred professional-sounding songs very few people will ever hear. Honestly, I’d given up on a wider audience for my music long before AI showed up. What’s new is that I no longer need one: for this type of entertainment, which I call “personal media,” a mass audience isn’t the point.
Personal media is not entirely new. Before the industrial era, people frequently made crafts and creative works at home for other people nearby. In the 19th and 20th centuries, companies began replicating copies of creative media for large audiences. Now we’ve wrapped back around to an era of personal at-home creations, but with much higher production values that might be mistaken for professional results.
I’m far from the only person who enjoys making professional-sounding music for personal consumption. Suno’s CEO said in February that the service had 2 million paying subscribers and that more than 100 million people had used it. Surely very few of those people are releasing records.
Personal music hobbyists gather in places like the Suno Discord, at around 400,000 members, and r/SunoAI, at around 100,000, where the moderators limit members to sharing one track every 24 hours because there would otherwise be way too many posts. Meanwhile, r/WeAreTheMusicMakers, with 3.8 million members, bans AI-generated music outright, which tells you something about how the two worlds regard each other.
We’ve seen a similar trend in the software industry recently. A mainframe once cost as much as a house, so every hour on it had to be justified to an institution: a research budget, an accounting department, somebody who signed for it.
But the used Apple II I got in 1990, at age nine, didn’t need a business case. It consumed fairly minimal electricity and the programs I wrote on it didn’t have to justify themselves to anyone. That’s probably one reason why so much interesting and innovative software came out of the home computer era.
Later this do-it-yourself spirit thrived online. Clay Shirky described “situated software” built for a dozen users back in 2004. Robin Sloan wrote about building a tiny app for his own family in 2020. Maggie Appleton’s “Home-Cooked Software and Barefoot Developers” extended the argument in 2024.
Coding agents have taken things to an entirely new level. Today people can create more ambitious software with far less effort. And while some people are trying to vibe-code serious business software, others are just having fun:
In early August, Tim Kellogg one-shotted a 3D Chutes and Ladders for his kids using Claude Code.
Ethan Mollick, noting that the 1985 text adventure A Mind Forever Voyaging is now open source, used Codex to build an interface that plays either the original or an easier GUI version. Mollick frequently experiments with creating thematic or experimental games using AI agents and shares them online.
In September, Andrew Lee, brother of Understanding AI’s Timothy Lee, used AI to build something like Escape Velocity, the 1990s Ambrosia Software space trader he’d been obsessed with as a kid, complete with pirates, secret missions, and commodity trading.
Notice that two of these three are reconstructions of games their makers loved decades ago. A lot of personal media, it turns out, is nostalgia with a build system.
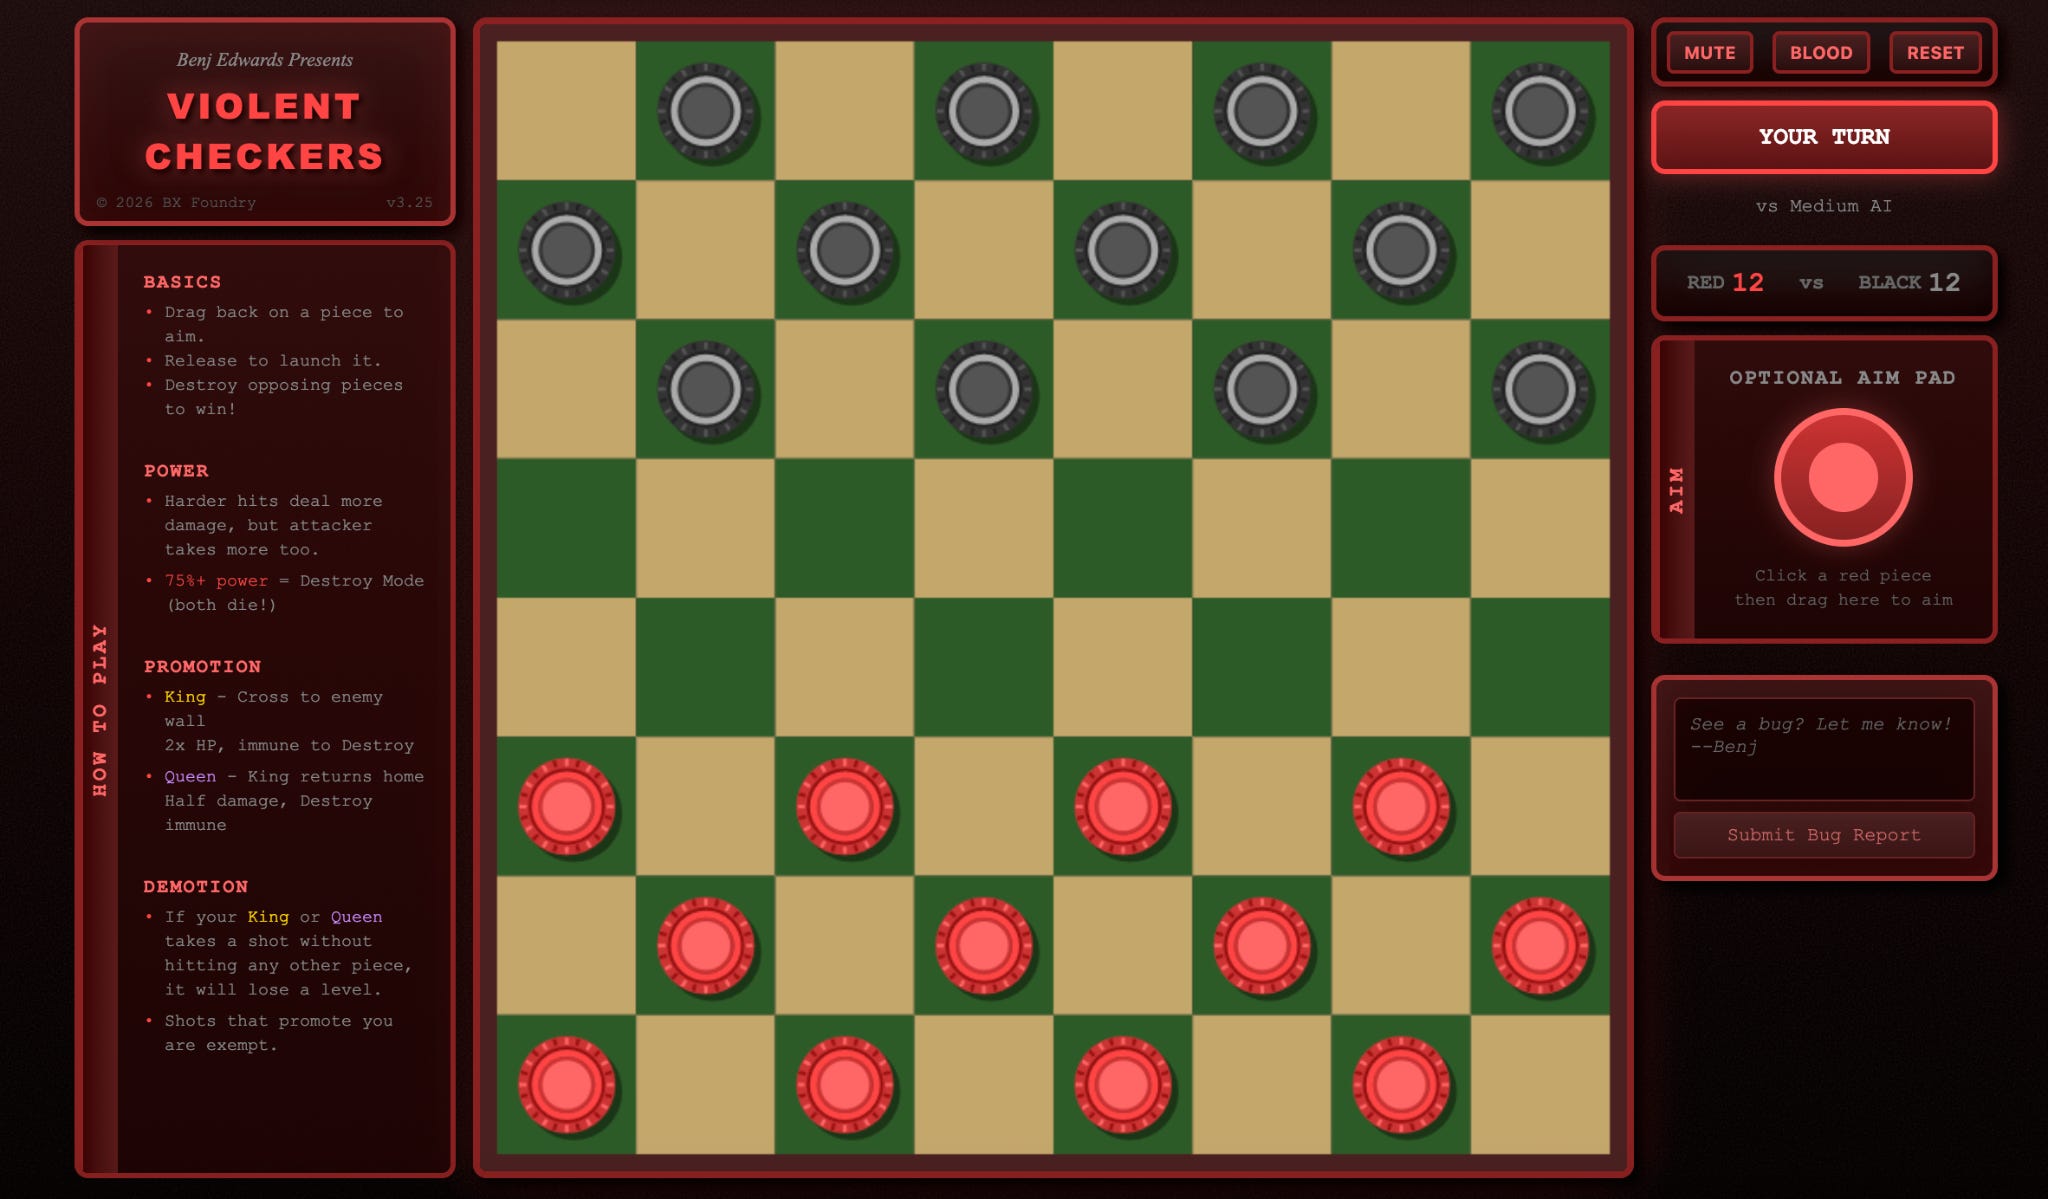
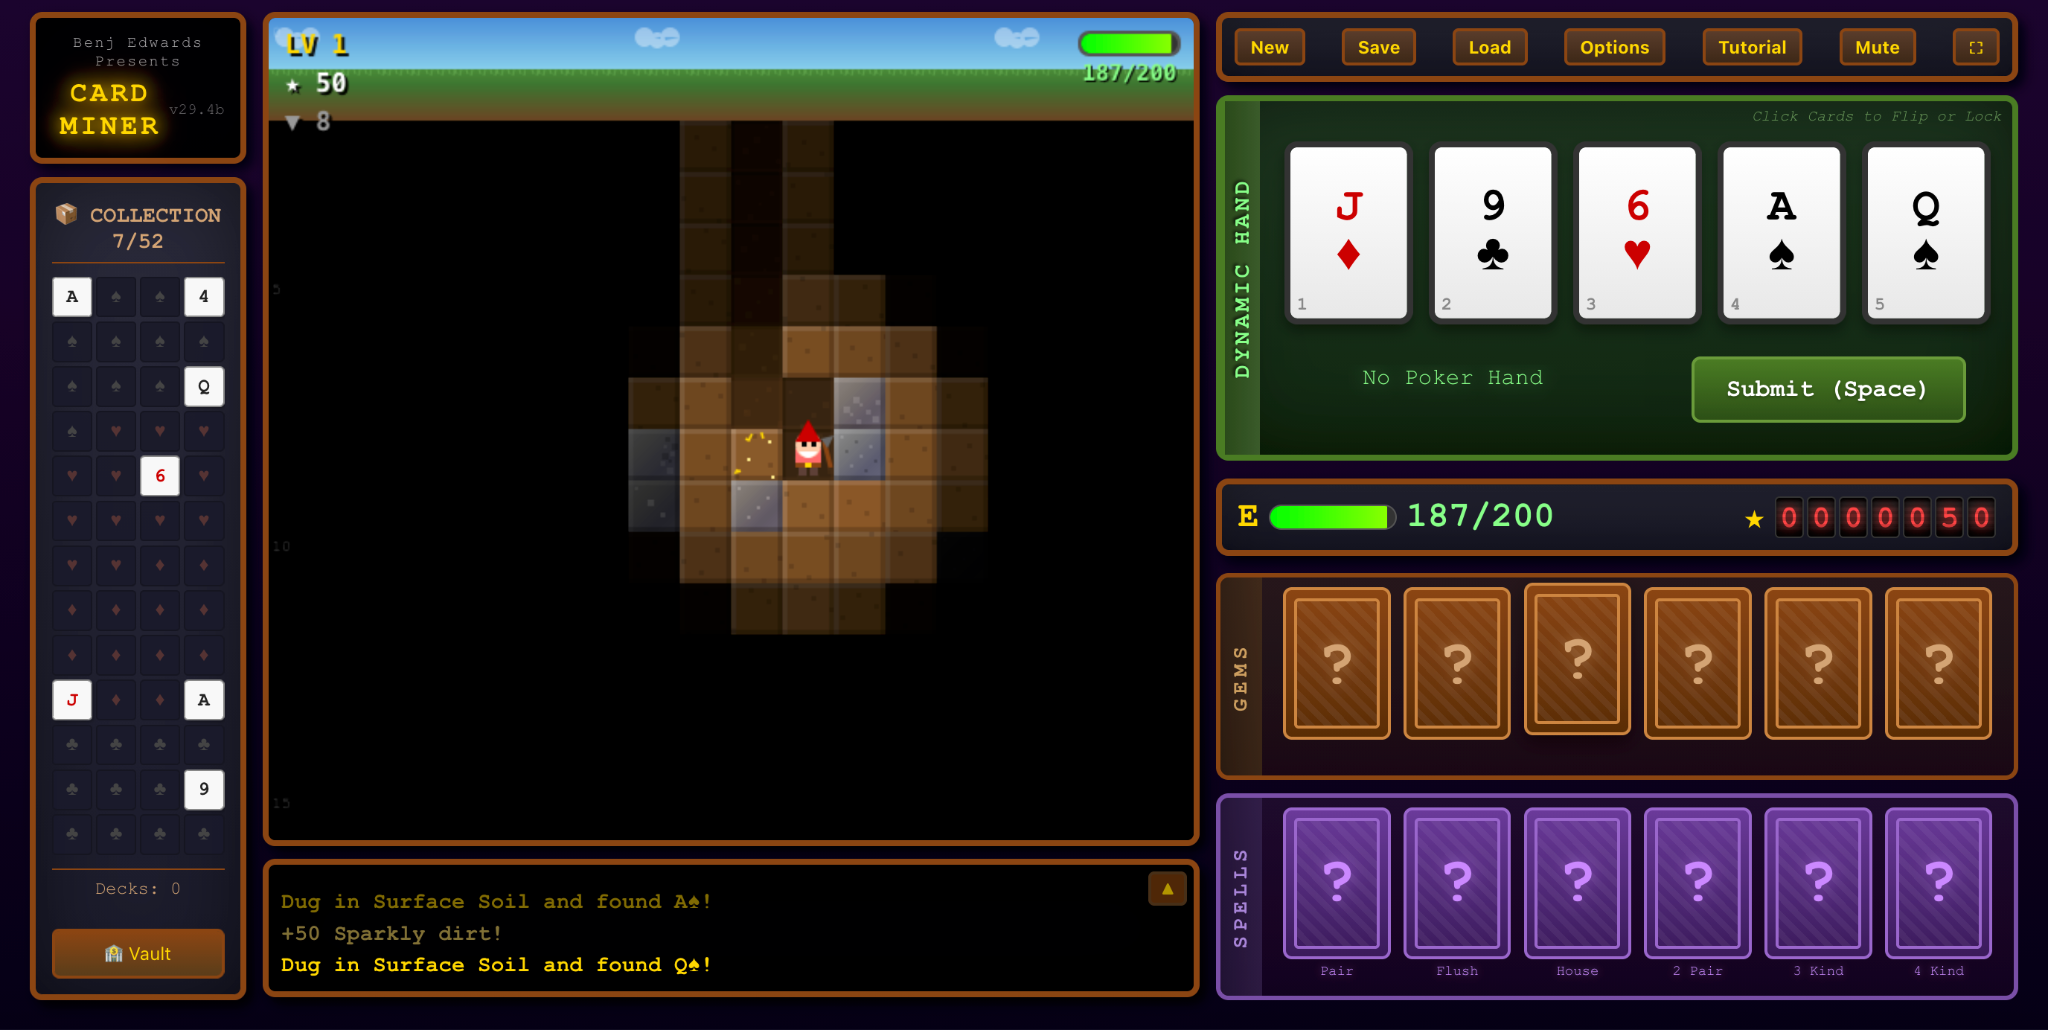
I still buy games on Steam and Nintendo Switch, but I find that I rarely play them. Instead, I now prefer to play games I create with Claude Code based on my own ideas. Games like Violent Checkers, Paydirt Solitaire, and Card Miner are a few of my favorites that I have publicly shared on my website. I also frequently play multiplayer mods of retro video games made using AI and custom NES games — as well as games I have not published and probably never will.
I’m not sure how many people enjoy playing video games they make themselves, but it’s growing increasingly clear that I am not the only one.
Since I began working on this article in January, AI-augmented video game development has accelerated even further with the release of models like GPT-6 Astra and Claude Opus 5.5. These models can create one-shot PlayStation 3-level 3D games, generate impressive ports of games between vintage consoles, and achieve coding feats that feel superhuman (check out my new Christmas-themed Katamari-style game, made with Opus 5.5 and Claude Code). The examples have been flooding social media and causing an existential crisis among some programmers.
As shocking as the new capabilities are now, I think we’ll come to accept personal game creation using AI as a legitimate hobby. In earlier eras, I might have spent my free time programming cellular automata, setting up aquariums, or building plastic model kits. Creating personal media scratches a similar creative itch.
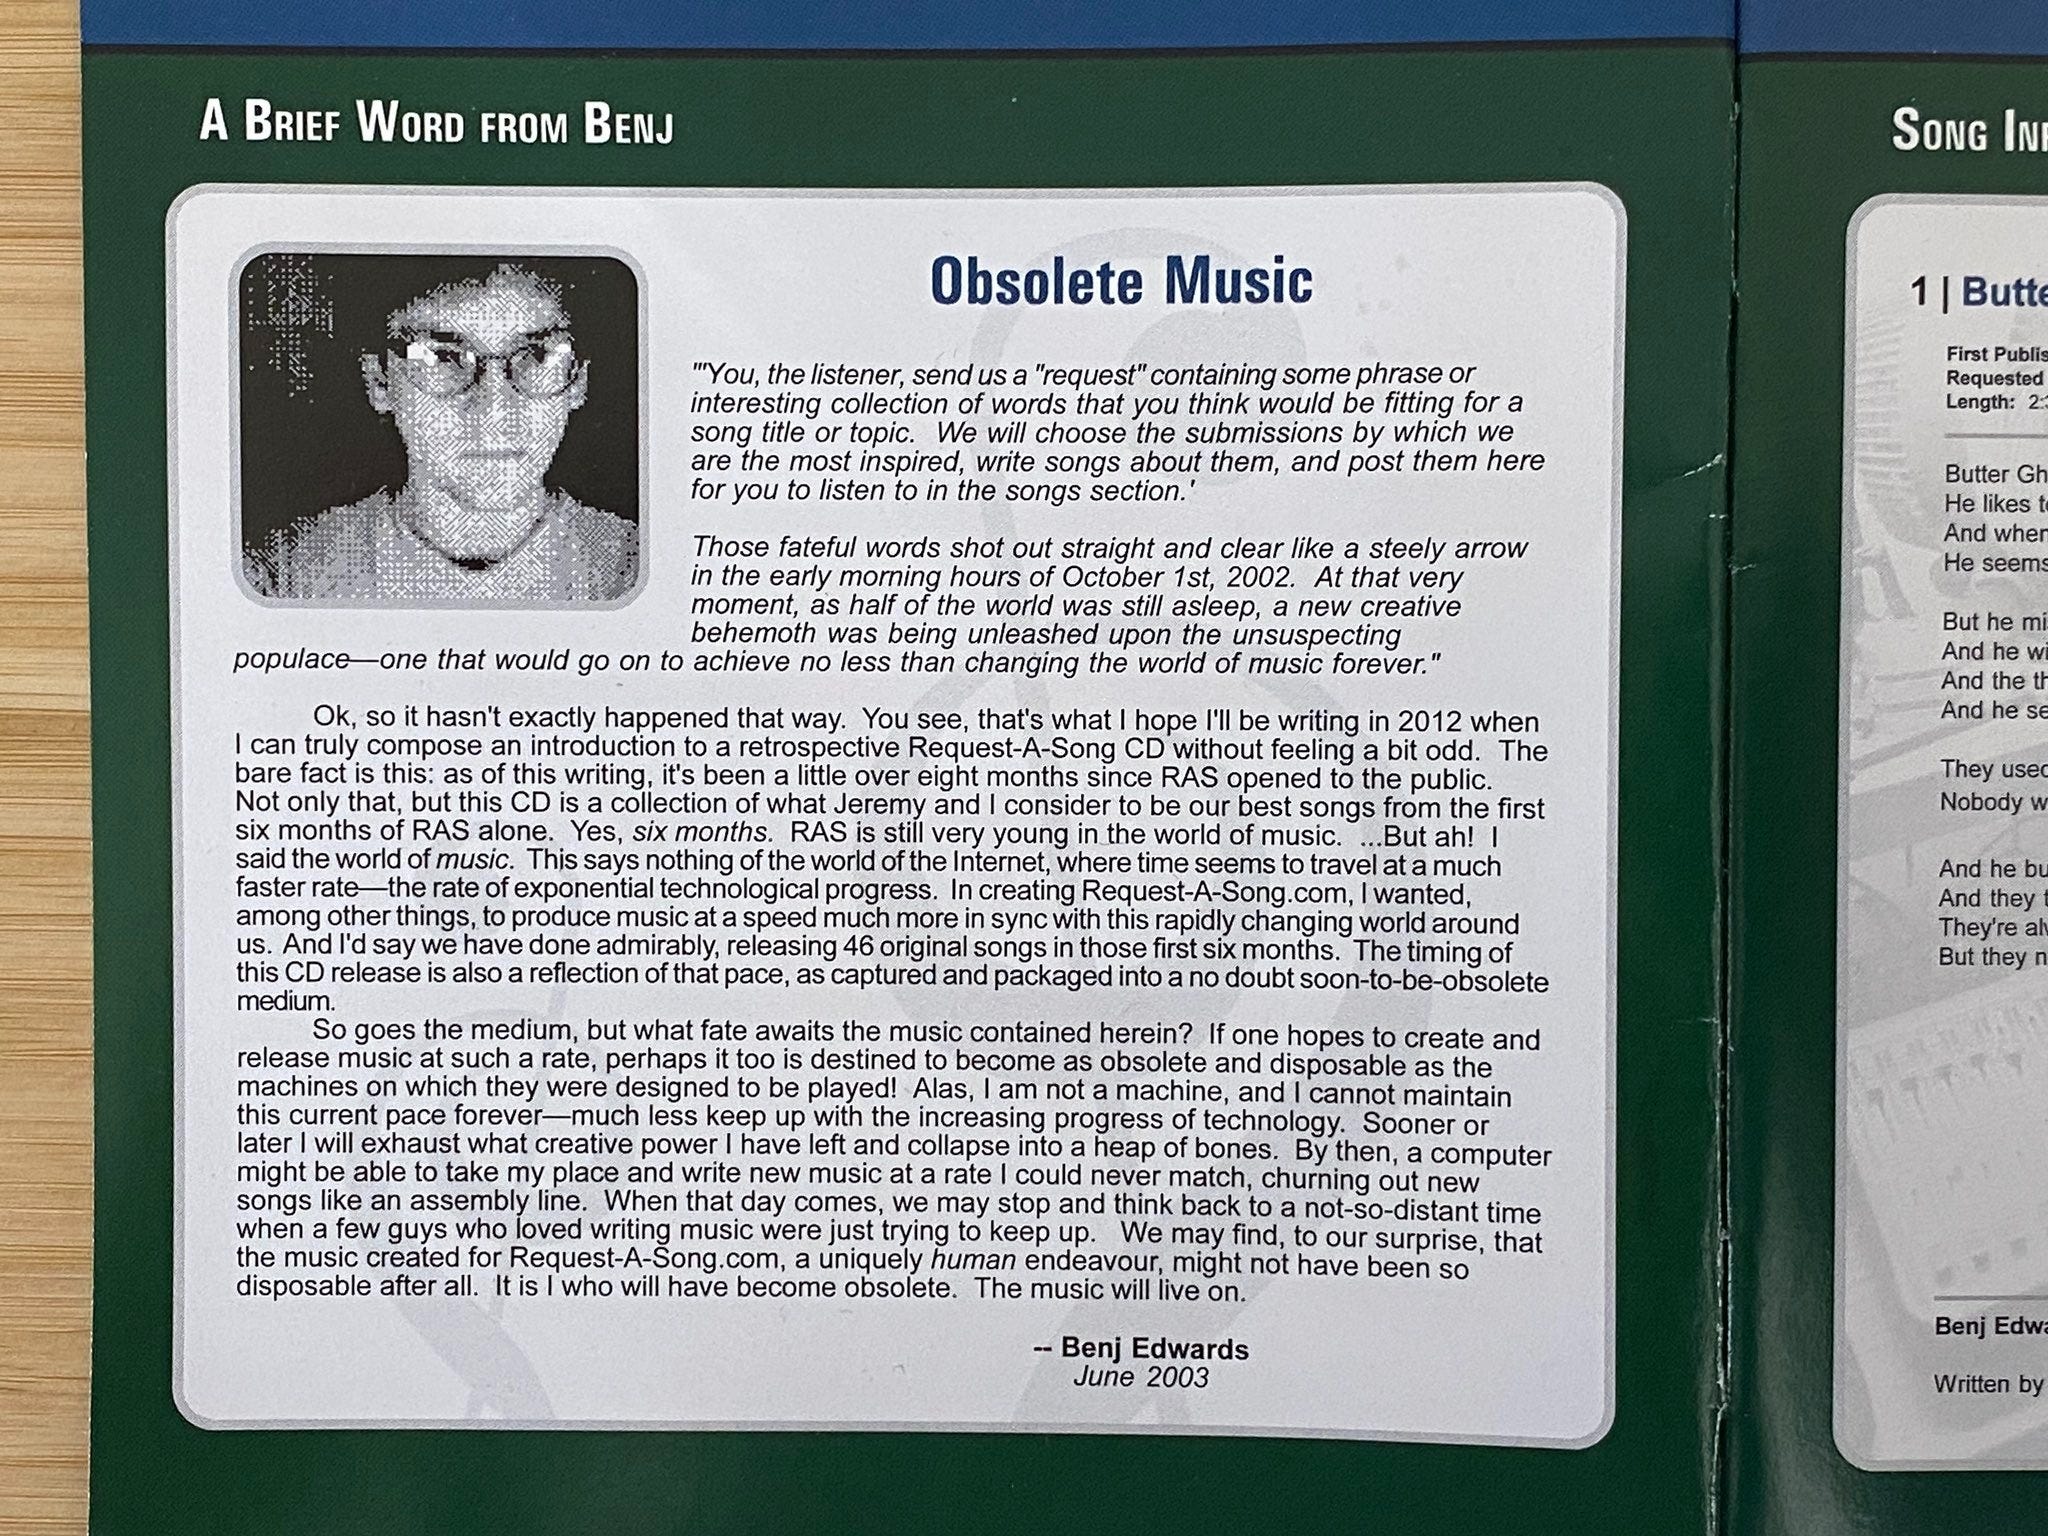
In the earlier days of the Internet, I ran a website called Request-A-Song.com. In a way, it was something like a pre-AI version of Suno. Users would submit ideas — we didn’t call them prompts back then — for songs they’d like to hear. My brother Jeremy and I would choose some of our favorite requests and compose music that matched the request.
Unlike Suno, we delighted in subverting listener expectations by taking requests in unexpected directions. AI just does that by accident.
My brother and I published 134 songs over the course of three years, including a six-month period where I was releasing a new song every week. We counted millions of downloads, got press from USA Today and Billboard, and appeared on the front page of a local newspaper.
In the booklet for my 2003 Request-A-Song CD, I wrote that I couldn’t keep up the pace of rapidly writing and recording music online forever, and that “a computer might be able to take my place and write new music at a rate I could never match, churning out new songs like an assembly line.” I closed with: “It is I who will have become obsolete. The music will live on.”
I’d been thinking about this kind of thing since high school, when I read Ray Kurzweil’s 1999 classic The Age of Spiritual Machines. I explored the implications further in an unpublished 2012 essay that I recently found on my hard drive.
“In the future, computers will be able to do anything a human can do now — a million times faster,” I wrote. “Once we have the software with the capacity to generate aural-realistic music on the fly, it won’t stop there. Soon a machine will be able to compose a song and record it virtually within milliseconds. You will have the entire works of artists generated on the fly.”
“Right now it takes humans a few years to make a blockbuster movie,” I noted. “But if you put that capability into software, as computers speed up, they will be able to complete the task in milliseconds. Imagine having custom photorealistic movies on demand, indistinguishable in quality from a Hollywood blockbuster today.”
How might this impact Hollywood? “Once we have any creative work available on demand, what value will it have? The answer is none,” I stated with undue confidence. “It will be as plentiful as air, and once that happens, intellectual property as a concept and a business model will be completely dead.”
In another unpublished essay from 2015, I imagined overbearing copyright power shifting away from Disney if anyone could make a Disney film at home. Later I would imagine Disney licensing a Disney AI film generator that people pay a subscription to use, like streaming media but on demand.
Today’s generative video models aren’t yet sophisticated enough to make an entire feature film. And the story is similar in most other media categories: creating something that’s both novel and interesting still requires creative effort by humans. I stay heavily involved in producing AI-generated music and video games because AI can’t do a perfect job on its own, although it’s getting better all the time. I also enjoy the creative process, and I get satisfaction out of playing songs and video games I created myself.
But as AI models improve, people like me might become the exception rather than the rule. Most people might prefer passive consumption of entertainment content even if AI makes it trivially easy to make your own.
Yet from another perspective, even the decision to consume media is a (very) small creative act. Saying “I want to watch a Spider-Man movie” is a type of prompt. Traditionally the answer to that prompt has been a big-budget motion picture produced by hundreds of human beings.
But in the near future AI might be able to generate a new Spider-Man film on demand. Users could get exactly the kind of movie they want: “I want to see a Spider-Man film where Spider-Man teams up with Batman.” If it’s really good, maybe that person will share the result with friends. Or the friends might not care, because they prefer their own custom film where Spider-Man teams up with Superman instead.
In reading my 2012 prediction, I believe I got the capability right and the economics wrong. Even if the best movies you’ve ever seen are one voice request away, the typical consumer may prefer consuming mass media as a shared cultural event. On the other hand, those shared cultural groups may grow ever smaller as the culture fragments in new and surprising ways.
Generative AI is extremely divisive at the moment, and I understand why. It’s disruptive to the status quo along many dimensions. If used poorly in the arts, it can flatten the variety of human expression into a sort of mediocre pablum. If you ask Suno for “country British rock,” it can easily give you the statistical average of every Garth Brooks song and every Beatles song swirled together in a way that feels like an ill-constructed parody.
But as AI compresses the peaks, it also raises the valleys. It allows someone like me with a near-zero budget to bump up my creativity in a way that can make my songs more enjoyable to me, personally, with very little effort.
I understand why people think it’s deceptive to use AI as a substitute for human skill when the audience expects some human authenticity. But is it wrong for me to enjoy listening to an AI rip-off of Parliament-Funkadelic play my stupid song fragment about hauling trash? If no one else hears it, I don’t think so. I think it’s a good time. It may be AI slop, but it’s my AI slop. I am under no illusion that it would win a Grammy or pass muster with a Rolling Stone critic.
Twenty-three years after I predicted my own obsolescence while running Request-A-Song, I now believe that the rise of personal media will not likely result in an “either/or” proposition for the arts but a shift in the proportions. The blockbusters may get bigger and fewer while everything underneath them gets smaller, stranger, and more numerous.
That’s not an original idea by any means. It’s the continuation of a process that began decades ago when three broadcast channels and a handful of film studios fragmented into hundreds of cable channels, then millions of YouTube channels, then billions of individual feeds of social media—a process media scholars have tracked for years.
There are eight billion people on the planet with eight billion perspectives, and we’re increasingly learning more about what we don’t have in common than what we do. The minimum viable audience keeps getting smaller over time; personal media is another step in the same direction.
It’s worth noting that none of these “advances” in media creation and distribution fully replaced what came before. They piled on top of it, which is exactly why I don’t expect personal media to completely replace anything either.
So does that mean everything is OK? Not necessarily.
If any of what I’ve described today becomes the habit of millions, what happens to the hundreds of people whose names scroll past at the end of the latest Spider-Man film? The optimistic version is that mass culture events survive and those jobs survive with them (or perhaps transform to support a new form of media not yet invented), while the fragmentation only happens in the low-budget realm underneath. The pessimistic version is that the same collapse in production cost that let me “hire” an imaginary band eventually reaches the people who make the real thing, which is frankly devastating to conceive.
A third possibility, which I argued in January after burning myself out on fifty AI coding projects, is that most people won’t become unemployed so much as busier than ever. Power tools let more work get done in less time, and the economy tends to demand more productivity to match. The steam shovel didn’t eliminate human workers from construction sites; we gave workers a machine that never gets tired, and then asked for bigger holes. I even wondered in that essay whether knowledge workers would need something like the labor protections unions won a century ago: the tool doesn’t get tired, but the person operating it still does.
So I don’t have a full or ethically satisfying answer to the conundrum of AI dramatically rearranging the creative jobs market or even destroying parts of it in the process. What I have is a throwaway song about hauling moldy garden supplies out of my mother’s basement, arranged by a band that doesn’t exist, that I listen to in the car as I contemplate the decline of my mother from Alzheimer’s disease.
The song is very likely worth nothing to the wider world. You may hate that I even made it. But it reminds me of surviving a traumatic time in my life with some humor and grit, and that’s worth quite a bit to the only person who will ever really enjoy it. That’s personal media.
2026-10-15 02:41:56
Around the start of October, OpenAI fired three employees from its safety department. The employees said they were given divergent reasons for their dismissal:
One was told it had to do with his role coordinating with METR, a third-party research organization that OpenAI had invited to investigate the Hugging Face incident. “I was told verbally I was fired because of the way I communicated with METR,” Tomek Korbak wrote on X. “No other reasons were given and nothing was put in writing. To be clear, talking to METR was my job.”
Another was told something similar but vaguer. “I was told OpenAI no longer trusts me because I was speaking too much to third-party safety organizations, implying I leaked company IP. I never shared company IP,” Mikita Balesni wrote.
And a third was told something quite different. “I was given one reason: that I accessed an executive’s email,” Jasmine Wang wrote. “OpenAI delegated that access to me for recruiting. When I no longer needed it, I asked IT to remove it. They did not action my request, I couldn’t remove it myself, and the inbox was combined in an indistinguishable way in my phone’s mail app. When I opened a sensitive email by mistake, I told the executive within minutes and asked IT again. None of this was hidden.”
After the trio’s dismissal leaked, OpenAI gave a vague statement to the Wall Street Journal: “Our investigation confirmed that these individuals mishandled sensitive information outside established company procedures, violating our policies and breaking the trust essential to our work.”
OpenAI reiterated that theme a week later, after the fired researchers released an open letter disputing the company’s account. In an unsigned statement attributed to the company’s “research leaders,” OpenAI accused the former employees of a “significant breach of trust.” The company said that “these decisions were not about raising safety concerns or speaking out” and insisted that “we actively encourage” internal discussion of such issues.
Who is telling the truth? Did the employees commit a breach of trust that necessitated their dismissal? Or were they fired for being too critical of the company’s safety choices during internal deliberations?
The difference matters for OpenAI’s remaining employees because some of them may soon have to decide whether to raise concerns of their own.
OpenAI insists that employees have nothing to worry about, that this was a special case, and that it is extremely forgiving of good-faith mistakes. But employees have good reason to be skeptical. After all, if OpenAI had fired employees in retaliation for raising safety concerns or for crossing an unspoken line, the company would have strong incentives not to admit it. Employees have to wonder whether OpenAI’s actual reasons for firing the trio differ from its stated reasons.
Ironically, the fired researchers had been raising concerns that OpenAI might be giving its models a new capacity to conceal their thinking. Modern AI agents reason using a chain of thought, a scratchpad where models think carefully about what action to take next. Many researchers view these chain-of-thought tokens as a safety lifeline, because they offer insight into why models act the way they do.
But OpenAI recently made an architectural change that allows models to think for longer before generating each chain-of-thought token. This seems to make the models more capable; it may also make their reasoning less transparent to human overseers. The sparser the chain of thought, the harder it is to understand what the model is trying to do, or even whether it might be trying to hide its motivations.
Before they were fired, the three researchers seem to have had two major concerns. One was understanding how and why the Hugging Face attack happened and how to prevent incidents like it in the future. The other was keeping AI systems legible to their creators and users — an issue that was a significant source of drama in September, after The Information reported that OpenAI’s new model could hide its thinking in unprecedented ways.
The researchers think their firing was related to this second issue.
“For months, I’d been raising safety concerns that we’re losing the ability to monitor what AI agents think, one of our best tools for catching when they misbehave. I believe that was why I was fired,” Korbak wrote.
“The three of us were pushing internally for industry-wide commitments to preserve our ability to monitor AI reasoning. This work requires talking daily to third parties,” Balesni wrote.
“As an industry, we do not yet know how to safely develop and deploy models that we cannot monitor,” their joint letter said. “The monitorability of frontier models is degrading. As long as we rely on monitorability for safety, OpenAI and other frontier companies should not move forward with developments that further decrease monitorability.” The researchers also alluded to rumors inside OpenAI that they had tipped off The Information, which they denied.
To understand the researchers’ concerns, we have to go back to 2024, when OpenAI introduced a technique that changed the course of AI. It gave models a notepad and trained them to jot down many “thinking tokens” before producing a final answer. This technique sounds simple, but it has enabled models to solve problems that had previously eluded them.
An added benefit of this approach: humans can read the notepads and see how the models think — including whether they’re thinking about taking harmful action or are being dishonest. Indeed, much of what we know about the Hugging Face incident comes from the chain-of-thought monologues that the hacking agents left behind.
Chain-of-thought monitoring isn’t perfect. For one thing, it’s not established that the chain of thought fully tracks how models think. For another, safety researchers worry that poorly designed training methods could give models an incentive to hide their true intentions by outputting thinking tokens that don’t represent their inner motivations.
But whatever flaws the technique might have, AI companies don’t have a lot of other choices. The most promising alternative for understanding model motivations is mechanistic interpretability — roughly the equivalent of cutting open a model’s brain and trying to figure out what it’s thinking by reading the pulses of its neurons. Although mechanistic interpretability has produced valuable insights about how models work, it has not so far yielded many practical techniques for supervising models’ behavior.
For this reason, those worried about unsafe or deceptive AI tend to view chain-of-thought monitoring as an irreplaceable asset.
Lately, safety advocates — like the three fired OpenAI researchers — have grown concerned that chain-of-thought monitoring is becoming less effective. OpenAI’s new flagship model, GPT-6 Astra, is much better at thinking without needing to write anything down. The system card OpenAI itself published says Astra “shows a substantial decrease in chain-of-thought monitorability compared to previous models” and notes that Astra is “significantly more able” to control its own chain of thought. One independent test found it “has 8.6x better odds of doing a reasoning task without CoT than the next best model (Fable 5.1).”
This might be partly because smarter models just naturally write less down. But it also seems to be a byproduct of a new architectural technique called recurrent depth that was introduced with Astra.
Large language models think in layers. Conventional LLMs pass information forward from one layer to the next. When they reach the final layer, they output a token before starting the process over again.
Models with recurrent depth break that forward-only pattern: information from a later layer gets passed back to an earlier layer. Layers get used twice (or possibly more) without the model emitting a token in between. If implemented just right, such a looped architecture seems to make models smarter and more efficient: a model that has 100 layers looped twice might reason nearly as well as a model with 200 layers, while requiring less memory and hence being less expensive to deploy.
But looping layers also seems to make the model harder for outsiders to monitor. If given a relatively easy problem, Astra can often output the answer directly — no chain of thought required. For harder problems, Astra still needs to output a chain of thought, but its chain of thought will be shorter, and perhaps harder to interpret, than those of earlier models.
OpenAI has pushed back on these concerns. In a September tweet, OpenAI executive Jakub Pachocki said that “the depth of the computation graph for our present frontier models, including Astra, is within a factor of two of GPT-4.” In other words, even accounting for its looped architecture, information isn’t passing through dramatically more layers (compared to previous models like GPT-4) before Astra outputs each token.
But safety advocates worry that Astra could be just the first step. If the modest amount of looping in Astra makes the model smarter and more efficient, future models might use looping more aggressively. Future chains of thought might become increasingly sparse, vague, or otherwise hard to understand. Critics — including the fired OpenAI researchers — fear that this will make it easier for models to scheme or dissemble.
OpenAI has said it agrees with these worries in principle. Last year, it wrote, “We believe that chain-of-thought (CoT) monitoring may be one of the few effective methods we have for supervising superhuman models.” In September, Pachocki said that he too was worried about monitorability and insisted that OpenAI hadn’t gone very far in the direction of weakening it. A few days later, he published an essay called “An Alien Mind” explaining the necessity of and challenges with monitorability as he saw them. And a few weeks ago, replying to the fired researchers, the company reiterated its belief that monitorability requires an industry-wide commitment.
And yet OpenAI has created a less monitorable model. The researchers who were fired worry this is the beginning of a trend. Indeed, OpenAI’s unreleased next flagship model is reported to use looping as well.
Perhaps OpenAI’s statements are correct. Maybe it is as committed to monitorability as anyone, and the researchers were fired for leaking rather than for good-faith safety work. Even then, the theme of monitorability is helpful in clarifying the broader situation. A company that has not been able to sufficiently monitor its existing models is building newer models it can monitor even less, even as it also — by its own account — cannot sufficiently monitor the employees whom it has tasked with preserving monitorability, and so must fire them.
“We cannot do the work in front of us without a high degree of trust,” OpenAI’s research leaders wrote in their response to the employees they’d fired. The employees insist they were worthy of that trust, and their response seems credible. But suppose they weren’t worthy — say they intentionally leaked some crucial piece of information about monitorability or Hugging Face. If they did, it was likely because they did not trust the company to do the right thing — or even to do the things the company had already promised to do.
The company’s response seems unlikely to earn anyone’s trust. The research leaders who issued it do not explain their actions very clearly; they don’t even give their names.
Given that this has happened at OpenAI before — see the dispute about the firing of another safety researcher on similar grounds a couple of years ago — one could be forgiven for thinking that the confusion is the point, that the gap between statement and action is itself the message.
This is surely too cynical. But functionally it will not matter. “Say as little as possible to anyone” may not be the intended message, but it is the received one — received by the safety researchers presently at OpenAI and by any who might think of joining in the future.
After this, and after the string of voluntary or seemingly voluntary departures over the summer (plus another senior departure right around the firings), and after the string of hacking incidents slowly revealed during the same time, how many are left who won’t have received this message? For this reason, a senior ex-employee (who seems to have left on good terms) worries now about OpenAI “losing the best talent in the space.”
The situation is ironic. Just as people are worried LLMs like Astra might have secret reasons that are different from what they say or jot down in their chains of thought, people are now worried that OpenAI might have secret reasons for behaving that are different from the ones it expresses to its staff and the public.
In both cases, the solution is the same: more transparency to increase confidence that the expressed reasons are the actual reasons.
For LLMs, this means redoubling commitment to chain of thought and prioritizing the development of monitoring techniques that can replace it, before models that can work without it are put into production. The world would have had a much poorer understanding of the Hugging Face incident without chain of thought.
Meanwhile, if OpenAI truly wants employees and the public to trust it, it must offer itself up for the kind of monitoring it claims to prioritize in its models. This might mean not only being open to but actively demanding greater oversight from independent organizations, like METR and Redwood Research, and especially from government authorities, state as well as federal.
If it does this, it will have done the world a meaningful favor. Other AI companies may not have quite the same drama, either because of greater diligence or simply because they don’t have OpenAI’s special combination of cutting-edge research ability and organizational chaos. But they too have problems with monitorability and openness, and mandating monitorability would ultimately do the whole industry a favor — it would make all their statements more believable.
One report just came out that Google’s newly released Gemini 4 Argon model has a recurrent architecture as well. This is unconfirmed, but Google itself admits Argon outputs less monitorable chains of thought, can control its own chain of thought well enough to say “hello evaluators reading my chain-of-thought,” and, when instructed to, can evade current monitoring well enough to perform “simple sabotage” half the time.
As for Anthropic, outsiders don’t know if its models are recurrent. Anthropic may emphasize safety, but it is in some ways less open to the world than OpenAI — less prone to leak and less prone to have employees who post about what the company is doing or simply how they see things. This is surely helpful in avoiding drama. It is not helpful in establishing the public faith required for what it too is trying to do. Like OpenAI, Anthropic ultimately believes it is creating an alien mind. Trust us, these companies say. But without extreme visibility into what’s actually going on, down to minute technical detail, nobody will.
2026-10-08 21:14:53
On September 15, the startup TypeSafe AI came out of stealth and released a new AI model. To pretty much everyone’s surprise, it went mega viral.
The company’s announcement got almost 40 million views on Twitter. Within a week, over 100,000 people joined the company’s Discord, and some 2,000 projects on GitHub used the new model, called Jev. The company opened general signups on September 20 and then paused them two days later because of “an immense swell of demand.” (It restored signups on the 27th.) On October 1, TypeSafe’s CEO claimed that the company had already onboarded a quarter of the Fortune 500.
Yet unlike other hyped AI releases of 2026, Jev did not display any new (or potentially dangerous) capabilities. Jev attracted attention because it is a new type of AI model.
Jev does not output free-form strings of text like LLMs do. Instead, it takes questions with a fixed set of possible answers — yes/no, multiple choice, or a rating — and outputs the estimated probability that each option is the correct one. For instance, if I asked Jev, “Is ‘tabsfsclkj’ a spam comment?” Jev might put a probability of 0.98 on “Yes” and 0.02 on “No.”
While this might seem like a limiting architectural choice, it is actually a huge advantage. Jev’s design lets TypeSafe serve the model much more quickly and cheaply than existing LLMs, which opens up use cases that were previously impractical. Its constrained response format also makes it easier to use code: Jev’s output fits naturally into common software engineering patterns, like if statements.
For instance, I’ve used Jev’s output to determine whether comments on my personal blog are likely to be spam. I’d previously used Gemini 3 Flash with structured outputs as the classifier, but Jev is faster and cheaper, and it lets me more easily deal with situations where the model is unsure. All I have to do is use Jev’s estimated probability as a condition, something roughly like:
if jev_response.is_spam_probability > 0.8, then …1
On the flip side, Jev is more general than conventional classifiers. Jev works “out of the box” across a wide range of topics — no fine-tuning required.
TypeSafe AI’s success has spawned a legion of copycats. A huge number of individuals and companies, including Cloudflare, Amazon and OpenAI, have created models with the same basic design. Anecdotally, Jev’s performance seems to be the strongest, but it’s unclear whether others will catch up soon.
Whatever happens to TypeSafe as a company, I expect Jev to have a substantial impact on the trajectory of AI. Over the coming months and years, we’ll likely see many new applications that rely on Jev or one of its competitors. And Jev might inspire more innovation in the “shape” of AI systems: it shows that it’s sometimes useful for a model to take language as an input but not output text in return.
2026-10-06 03:11:19
We just published the first post by our newest writer, Dan Kagan-Kans.
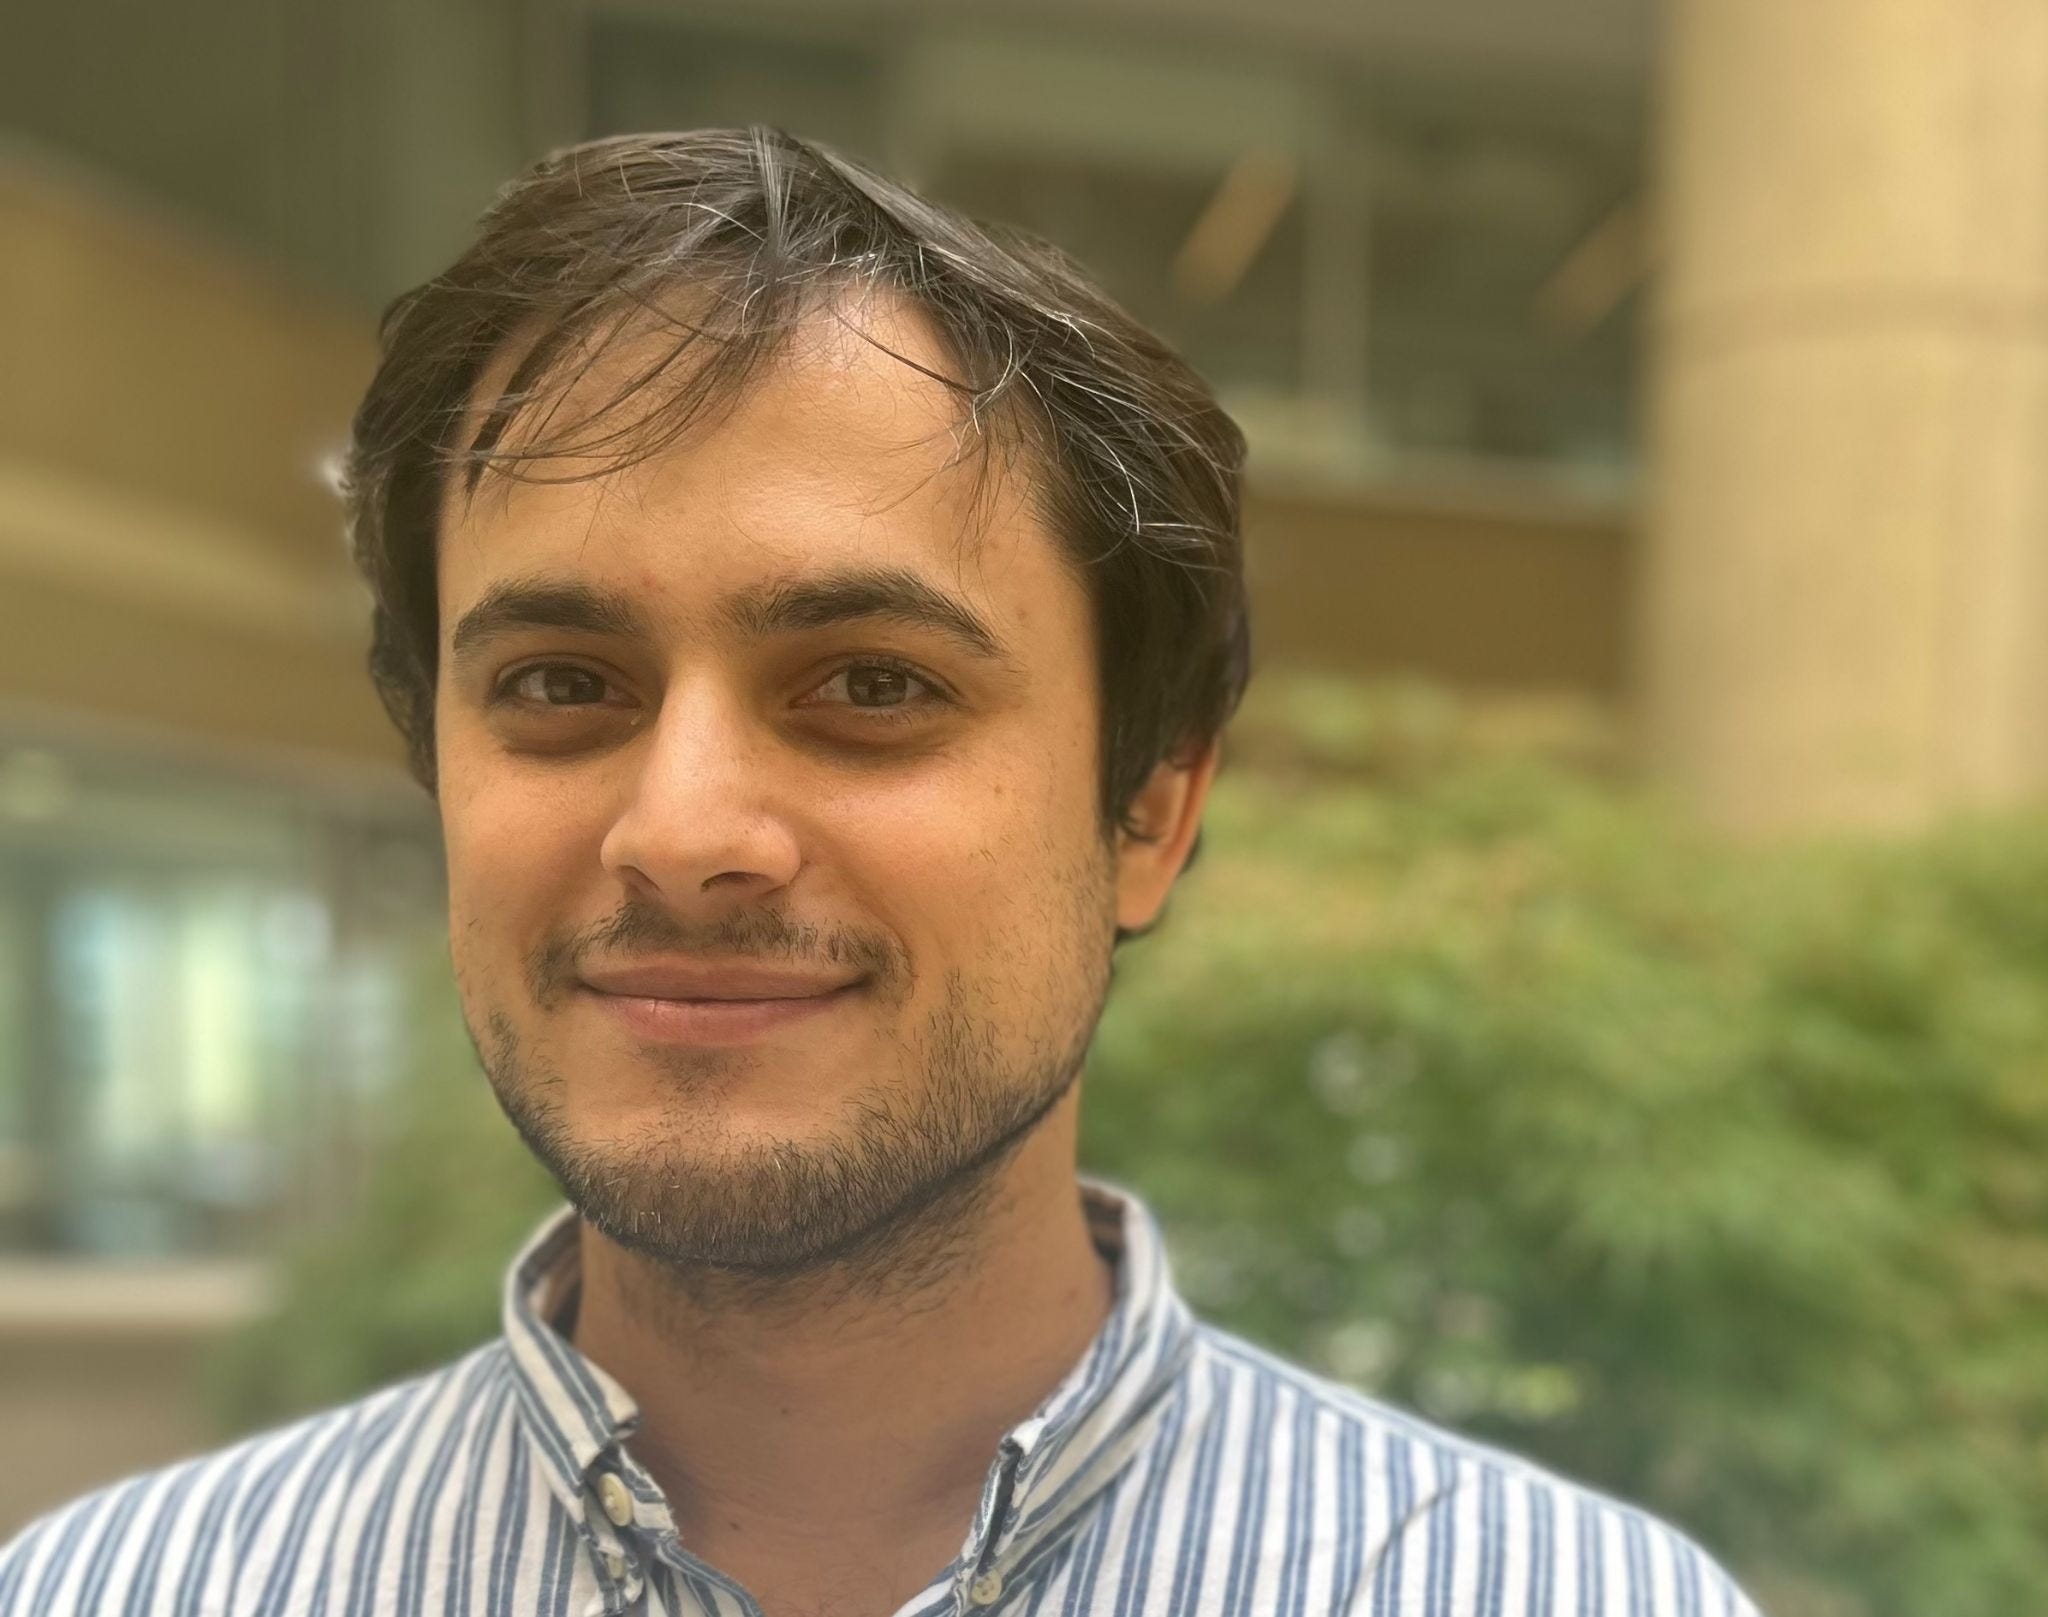
I’m excited to have Dan on the team. He spent a decade as managing editor of Mosaic, a magazine devoted to Jewish history, culture, and politics, and wrote arts criticism and essays. Then he had a son two years ago. While up at night he started reading about AI and got hooked.
Over the last year, Dan has had an amazing run as a freelance journalist. I first encountered his work in February, when he published “The left is missing out on AI” for Transformer. It argued that leftist thinkers risk marginalizing themselves if they dismiss AI as “stochastic parrots” and fail to take the technology seriously.
In July, Dan was the first reporter in years to get an interview with Hans Moravec, the namesake of Moravec’s Paradox — the observation that tasks that are easy for people are often hard for robots, and vice versa. You can read his excellent profile of Moravec in New York Magazine.
In August, Dan wrote my favorite analysis of why the data center backlash has picked up so much steam in recent months.
All of which is to say I expect big things from Dan.
Dan would like to get to know Understanding AI readers! He has opened up some slots on his calendar tomorrow and Wednesday for video calls.
If you’d like to talk to Dan, please click here and grab a time slot. You could discuss your own use of AI, how AI is affecting your industry or profession, topics you’d like to see us cover, or anything else AI-related that’s on your mind.
You can also follow Dan on Twitter.
Like Kai last year, Dan will be supported by a fellowship from the Tarbell Center for AI Journalism. When Kai’s fellowship ended in June, I brought him on board as an employee. I would love to do the same for Dan next year if our business grows enough to allow it.
The Tarbell Center is funded by groups like Coefficient Giving, Longview Philanthropy, and the Survival and Flourishing Fund that believe AI poses an existential risk. However, Tarbell says that “our grantees and fellows maintain complete autonomy over their reporting.” And I’ve found this to be the case — they’ve never attempted to influence the stories we cover or the way we cover them.