


2026-09-19 03:00:00
Nate Silver’s latest is A supermajority wants to slow AI down, noting the general convulsion of fear provoked by the AI Guys’ it’ll-kill-us-all palpitations. From which:
And then there’s a weird faction of AI denialists — people ostensibly on the left — who are convinced that AI is all a scam and therefore there isn’t much need for regulation.
In parallel, the IETF (Internet Engineering Task Force, the people who standardize protocols so the Internet can work) is seeing a steady flow of proposals along the lines of “something Agent something Validation something Enablement something”.
I’m a leftist (but not that weird) and I think regulation and standardization of LLM-land are a waste of effort at this point in history. Because money. You don't have to believe all GenAI is crap to think that the financial premises are, well, crap.
First, the only sector today where there are large numbers of people willing to pay substantial sums for access to AI services is software. Software people are roughly 1% of the global workforce, which isn't enough to move the financial needle.
For the other 99%, are they (or their employers) willing to pay enough for AI goods and services to turn a profit on the global multi-trillion-dollar investment surge? I could be wrong but I don't think so.
That leaves the possibility that employers can discard tens of millions of knowledge workers, thus boosting profits enough to validate the global investment premise. I don't think it's weird to find that scenario dubious.
Finally, I don't see how we can have a rational discussion of regulation or standardization under the huge global investment overhang. The miasma of greed and fear obscures hard facts of actual utility and ROI. Which you can’t regulate or standardize without. My advice is: Let’s wait for that bubble to pop.
Money’s the biggest issue, but there are other bad problems with regulation and standardization
For standardization in particular: The technology (and business landscape) are changing really fast and all the time. I’ve personally had multiple conversations where I say “X is a dumb thing about LLMs.” The response is usually “X is so six-weeks-ago. Everything is perfect now.” Please, please, don’t make anyone sit on a committee trying to specify anything about technology that’s so obviously immature.
And for regulation: There’s the money issue, and then there’s that moving target issue. But I think current law remains a useful tool as-is.
If you launch an LLM-backed agent and it causes me serious business or personal damage, I think I can hire a lawyer and sue your ass. Because lots of people are, notably including most of the world’s largest publishers.
If it causes large numbers of people personal or financial harm, you’ve probably violated existing law and might find yourself facing a criminal conviction. We already have a solid precedent that saying “the AI did it” is not a valid defense. Yeah, obviously, a legal assault on huge, rich, and fashionable entities like OpenAI and Anthropic is an uphill struggle. But if Nate Silver is right and the anti-AI rage is bipartisan, the BigAI castles may be built on sand.
As a senior and fairly visible software person, I repeatedly get questions like "should we be scared?" and "will I lose my job?" My answer is always the same: Wait for the bubble to pop, then we'll find out.
2026-09-09 03:00:00
Meet
Emily van Lidth de Jeude, an
artist who lives on an island and has
the most adorable chicken coop you’ll ever see.
Those URLs start with emilyartist.ca now; until recently it was emilyvanartist.noblogs.org. But
that site, there for many years, is down now, and not coming back up. Why? Well, her email address used to end with
@autistici.org (it’s broken too now), and therein lies the story.
It’s because the Trump administration declared that the “Autistici/Inventati” collective hosting Emily’s website and email was a terrorist organization, and blasted them off the Internet with legal nuclear weapons. Here is the A/I collective’s statement. A more compact journalist narrative is Als de Amerikaanse regering je tot terrorist heeft bestempeld: deze Italiaanse internetprovider kwam vorige week op de sanctielijst which is in Dutch but it machine-translates nicely. Emily’s own take, on her blog, is Canaries of Hope.
It’s been professionally and personally devastating, vanishing Emily’s online history and nuking her email network.
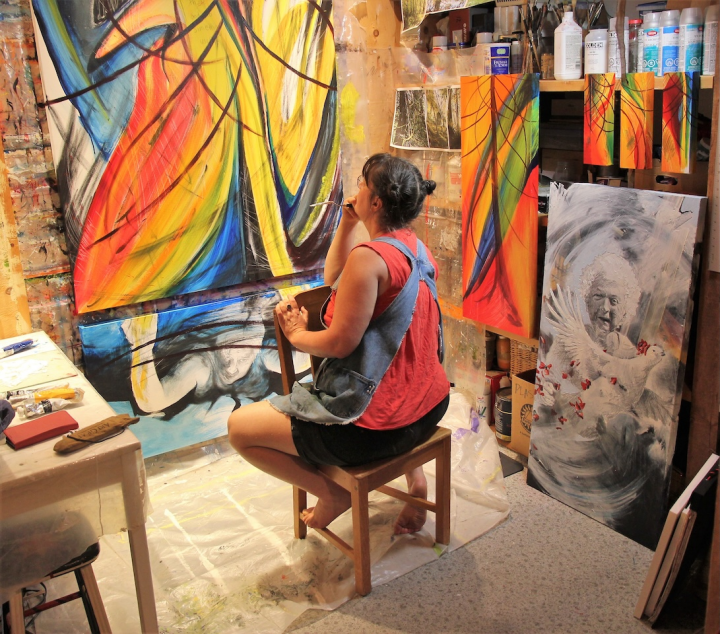
Canadian eco-social practice artist Emily van Lidth de Jeude in her studio, 2023, working on a series about wildfires. Beside her on the floor stands a portrait of her Ukrainian grandmother.
I suppose most people reading this saw the Autistici/Inventati news story and shook their head at yet more MAGA malfeasance. Me too. But then I found out about Emily’s story, initially on her Fediverse feed, and that made it concrete. The wastrels in Washington can reach across the ocean and silence a Canadian creator on an Italian website. With no prior legal process, nor any way to resist, and without fear of consequences.
They can probably do the same to you if you displease them sufficiently. They’ve done it once now and from their point of view it went flawlessly, so why not again and again and again? The only reasonable prediction is that they will.
It might be the case that if A/I had been in the US, they could have mounted a defense based on Section 230, but I’m no lawyer.
I’m also no DNS expert; but I know some good ones. So I asked if there were any countermeasures available to non-US entities.
The answer: “Nope.” I asked “What about a national domain like .ca?” Still nope, any national registry could be
targeted by US legal warheads.
So, I could be taken down by this time tomorrow, just like Emily was. And like her, I’d have no comeback. You too, maybe. I remember, back during the Cold War, we described our part of the planet as “The Free World”. Every year it gets harder to believe that label.
This is a politics and policy problem. So in the big picture, the only way to prevent this kind of abuse is for the Americans to stop electing ignorant corrupt lawless narcissists. Starting this fall of 2026.
In the meantime, follow Emily online, she’s fun. And have a look at her art, some of it might look good where you live.
2026-09-02 03:00:00
I just landed a PR that fixed a nasty data race in Quamina. Which shouldn’t have been technically challenging, but I took side-trips into Erlang, unit test footguns, whether or not I should go on accepting LLM-generated PRs, and programming while aging.
Let’s address that last issue first.
In late 2026 we know that:
Claude and its competitors can write perfectly decent code, particularly where the task at hand can be narrowly focused.
They’re also good-to-excellent at detecting vulnerabilities.
The underlying GenAI technology has serious negative externalities in (at least) the domains of environmental impact and intellectual property.
Using this technology might enrich and empower people about whom I feel contempt and fear.
The vast majority of people whom I care about and respect are experiencing real unhappiness about the GenAI big picture.
I’ve never personally put clankers seriously to work and for now I’ll continue not to. I have been accepting Claude-authored PRs but, to the extent I can detect them, I’m stopping. This will have a real cost; some of those PRs yielded big performance boosts. Also, they were built much faster than I could have managed.
But the picture is mixed. Specifically, I have to admit that I don’t really understand the 500 or so lines of clanker code and test that compute epsilon closures for nondeterministic finite automata. Sufficiently so that I’ve written an issue to think it over, understand it, and with any luck, simplify it.
Interestingly, we got to the current epsilon-closure code in a sequence of reasonable-looking PRs that I reviewed, asking for changes in most. But in the big picture my reviewing was ineffective, because it ended with a large lump of code that I don’t understand or, at the end of the day, trust. I wonder how typical that outcome is?
There’s an exception to my new policy: Vulnerability reports. I think it’d be irresponsible to ignore them and penalize Quamina’s users because I don’t like the source. Somebody did a Claude scan which found 14 problems at various levels of criticality. I’ve created issues and hope to retire them all soon.
The ugliest problem the clanker found was a data race in a piece of Quamina called pruner (that most people don’t use). So I bashed out a quick unit test that ran several thousand read operations in one goroutine and the same number of updates in another. Sure enough, on its first run it instantly exploded in a flurry of data-race complaints.
The problem wasn’t complex and my first cut at a fix worked fine, the unit test running flawlessly. But, also very slowly. I (reasonably, I thought) went looking for contention problems around the mutexes I’d just added. The profiler seemed to be saying that the slowdown was in Quamina’s core matching methods, but that made no sense at all, so I dug deeper and deeper into the Go sync primitives. And found nothing useful.
Concurrency bugs are extra irritating. Also, I’m semi-retired and doing this for fun, so I put it down and ignored it for a few weeks.
There was a bright spot in this sad story. I mistakenly thought I’d found my problem in a statistics-gathering type with several mutexed fields. So, cackling gleefully, I turned them into Erlang-flavored accumulators updated with Go channel messages, a programming idiom that’s always given me a warm glow.
It didn’t make any performance difference but the code was smaller and prettier.
[Update: It’s subtly buggy in a way that doesn’t impair its usefulness; created an issue, will fix.]
When I got over my grumpiness and went back to the problem, I started by looking at the unit test. Oops. Turns out the read-only thread was (unsurprisingly) running twenty times as fast as the update thread and since they were doing the same number of operations, it finished up instantly and the updater-thread kept thundering away. For reasons that need not concern us, in this specific benchmark scenario a stream of heavy add and delete operations without any stats-gathering read operations leads to massive, horribly complex NFAs. Then the matching runs slow — exactly what the profiler had been trying to tell me, only I thought I was smart enough to know better.
So I forced the reader thread to keep running until the other finished and hey-presto, the race was still fixed and everything ran at typical Quamina speeds, which is to say very fast.
(I didn’t get rid of the Erlangified stats package though, I just liked it too much.)
I’m normally tolerant of a certain amount of sloppy informal YOLO power-coding while constructing unit tests — more are better! — and I think I still am. But this was a painful experience that I’d like to avoid in future. So, is there a lesson here? Maybe there are two: First, believe what the profiler is telling you! Second, if you’re having trouble understanding unit test output, dig around a bit and make sure it’s doing what you think it is.
Even when I’m mad at my software, I’m grateful that I still enjoy working on it. I think it supports my main post-employment objective, which is to keep my brain working. And who knows, the software might help somebody somewhere.
And best of all, when nobody’s paying you to work on something, you can take a few weeks off whenever you’re not in the mood.
2026-08-25 03:00:00
There’s been a lot of discussion recently about the GenAI giants “watermarking” their output, which to say inserting data so you can tell that it’s been generated by ChatGPT or Gemini or Claude or whatever. The technology for watermarking images is as old as dirt, works as advertised, and doesn’t affect image quality. What’s new and controversial is a claim that they can watermark text output cheaply, simply, and without harming the quality of the text.
I was curious how they did this so I dug in a bit. I’m mostly convinced that it works and is pretty clever. However, all the explanations are full of Computer-Science jargon that you need to be a professional developer to understand. So here’s an attempt to explain to non-insiders and then, indirectly, opinions on whether it’s good and what it means and doesn’t mean.
[To professionals: The following is vastly oversimplified but not, I think, misleading.]
LLM software generates output a word at a time. The way it works is, it takes the last few words it’s generated and feeds them to the Large-Language-Model process, and what comes out is a list of plausible next words, and a number which represents just how plausible they are. So if the last few words were “my favorite tropical fruit is” the LLM might come back with “mango”:30, “lychee”:20, “papaya”:10.
You might think that LLMs always choose the most-plausible next word, but that turns out to give lousy results. So they randomly select from the list in a way that respects those numbers. First, note that the numbers add up to 60. So in this case, you’d want it to select “mango” 30 out of 60 attempts, i.e. half the time, “lychee” 20/60 or a third, and “papaya” 10/60 or a sixth.
In that sentence, the word “randomly” is doing a lot of work. Let’s look a little closer at one way you might do this. Your computer program could make a list with 60 entries, fill the first 30 with “mango”, then 20 with “lychee” and 10 with “papaya”. Then you’d ask your computer to give you a random number between 1 and 60. Suppose you got 33, so you pick the 33rd list entry and return “lychee”.
And in that sentence, the phrase “ask your computer” is hard-working. It turns out that computer programmers need random numbers like this all the time (let’s ignore why). They get the numbers from a built-in function called a “PRNG” (let’s ignore what that stands for). The way a PRNG works is you fire one up by giving it a “seed”, which can simply be another number that you get by bashing randomly at the top row on your keyboard or by asking a co-worker to pick a number or whatever.
Once seeded, the PRNG is happy to go on giving you an endless series of random numbers. But (this is important) they depend on the seed. By which I mean that if you fire up a second PRNG with the same seed, it’ll produce exactly the same endless series.
Now we’re almost there. If you think about it, the LLM’s next word depends on, and only on:
The previous few words and the model’s “context”, i.e. the prompts and anything it’s been asked to load up,
The internal workings of the LLM, and
The random number used to select from the list of candidate words. Which in turn depends on the seed that the LLM fired up its PRNG with.
So, suppose you want to test whether some text was generated by an LLM. Well, IF you have access to the LLM, and IF you know which PRNG they used, and IF you know the PRNG’s seed, then you can look at the LLM output and see if the words are the ones that the LLM would have generated. This works even if the output text was edited a bit; if a high proportion of the words are those that the LLM would pick given the preceding ones and the PRNG output, that’s a signal that yes, it was probably LLM-generated.
This only works if you know the details of how the candidate next-words are generated, which PRNG, and what seed was used. It would be technically possible for an LLM provider to share this information, then anyone could check the watermark. In fact, all they have to keep secret is the PRNG seed. So at the end of the day, this “text watermark” means something like “Remember the seed”.
I don’t watch the GenAI sector that closely so I don’t know if any of the providers actually do disclose this stuff. My impression is that generally speaking they’ll provide an API to do this checking for you. Or not, if they decide you’re not entitled to do that, or haven’t paid enough, or whatever.
Here (on X, unfortunately) is an explanation that is slightly less oversimplified than mine above; still, I think, inaccessible to non-professionals, but perhaps useful to some.
Scalable watermarking for identifying large language model outputs is the upstream science, from Nature in October 2024. Strong stuff.
AI Text Watermarking Is Free And Good, by Zvi Mowshowitz, also offers a how-it-works, but then includes commentary around the “… And Good” part of that title. I don’t agree with some of it but the arguments are useful to know and quite clearly written. I’m going to steal a phrase from Mowshowitz’s piece to serve as the title of my next section…
Quite a few people, some very smart, have reacted to this watermarking idea with fear and loathing. Mowshowitz scoffs at them. He (correctly) observes that the hostility is in large part due to people assuming that anything the AI vendors say is probably a lie and that anything they do is probably greedy and dangerous bubble fodder. But he (incorrectly) opines that this take is unreasonable.
So sue me: I too think those businesses lie a lot, that their product vision is damaging to civil society, and that they are inflating what is starting to smell like a truly apocalyptic financial bubble.
I do think the watermarking can work as described and won’t slow things down and won’t degrade the quality of the output.
Sometime in the last year I gave up on making predictions about the impact of GenAI on the world. So don’t ask me what the effect of ubiquitous watermarking will be.
2026-08-18 03:00:00
Fools have said that the Prairies are boring. This cannot be true, because in the absence of hills and trees there’s more distance in each direction you might look. Also, Prairie landscapes include the skies above them which, whether blue, star-spangled, or cloudy, aren’t boring. Herewith photoevidence from the vicinity of Wilcox, Saskatchewan, with which I claim no other connection.
The nearby highway is distinguished by an adjacent railway line that carries really big trains; you really don’t want to be waiting on a crossing while one of them spends tens of minutes reversing back and forth lackadaisically, to what purpose I can’t imagine.


See what I said about the sky not being boring?
This corner of Saskatchewan has less absence of human construction than Prairie-typical. Below, four distinct structures rise from the fields, marked by the clusters of trees which surround every locus of human activity here, there to offer shelter from the endless Prairie wind.

I was out for a drive with my mother, now 96. She asked “How many people wonder what it looks like where the makings of the bread on their table come from?” Below, what it looks like after the harvest. The ground’s less pretty than before the wheat was cut but the dirt/cloud antiphony lured my camera out of the bag.

Prairie photography is right up there with Rock-Concert photography in that there’s all the light and visual drama you could want, just get in a good place and point the camera in a good direction.

Remove distractions, highlight the clouds, and you can’t go wrong.
2026-08-14 03:00:00
It’s been a rough few years, for the earth, for the societies that populate it, and for my family. Like they say, “sandwich generation”. There’ve been weeks when I’ve struggled for a smile. I suspect more than a few folk reading this are also feeling stretched thin these days. Happiness has not entirely departed our lives, and waiting for a happier future is a really bad idea. So we should notice and bookmark those moments and hours when smiles come to our faces.
If you share your life online, write the good times down and share them already. I used to do this a lot; here are three out-takes ranging between 2003 and 2011. Maybe one or two of them will cheer you up?
The Picture of Happiness (2003/06/09)
Chestnut Dusk (2007/10/13)
Thanks (2011/11/14)
I should do that more. Starting now.
We live near a street called Main (which it’s not) and a neighborhood called Mount Pleasant (there’s no mountain but it’s mostly pretty nice). Three weeks back, under the rubric “Pleasant Day”, they blocked cars off nine blocks of Main, and the street was repopulated with retail stands (mostly from the street’s merchants), eat/drink patios, and live music.
It was sunny and everyone was happy, me too for a couple of hours. I also enjoyed taking pictures and editing them.
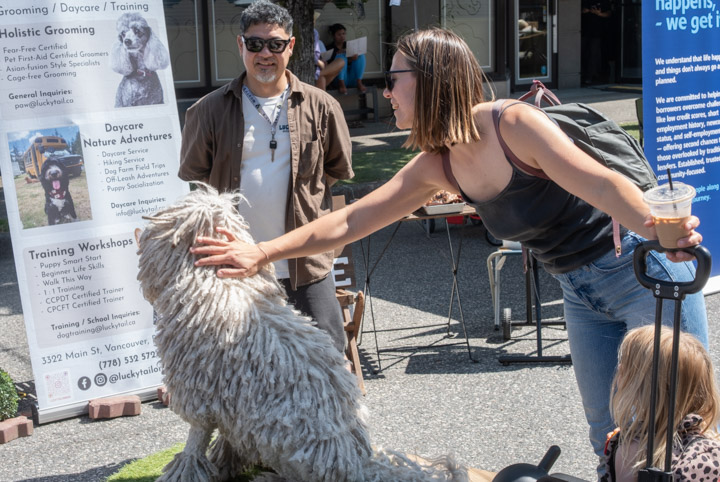
There was a dog-grooming stand with a big white dreadlocked beast that enjoyed everyone’s attention.
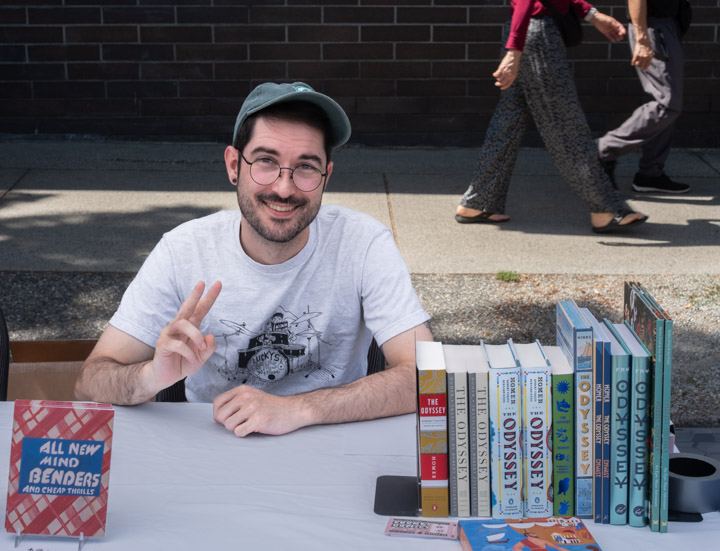
Lucky’s Books and Comics is an excellent bookstore. Their selection echoed the summer-2026 zeitgeist.
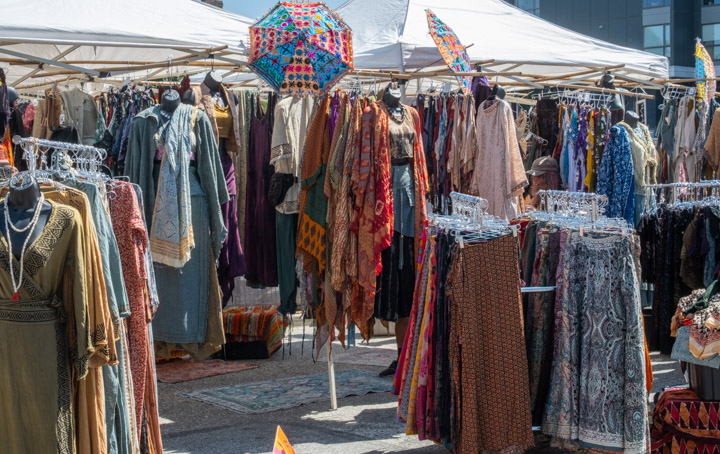
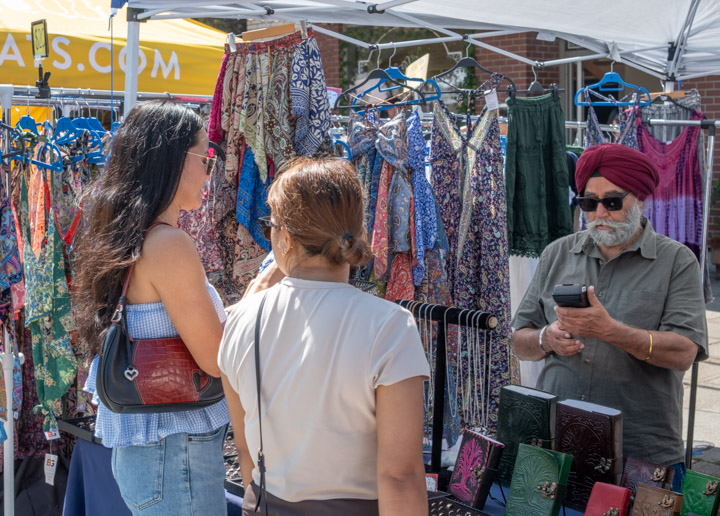
There were a couple of stands selling India-flavored garments , they seemed to be doing good business.
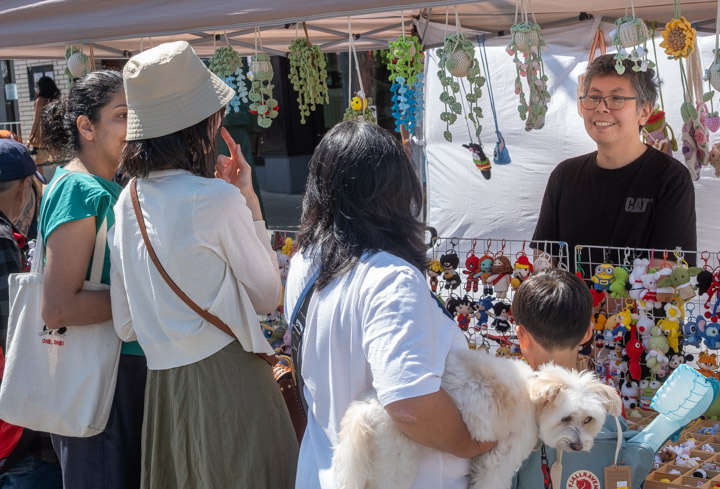
Chinese-flavored trinkets too.
Check out the dog.
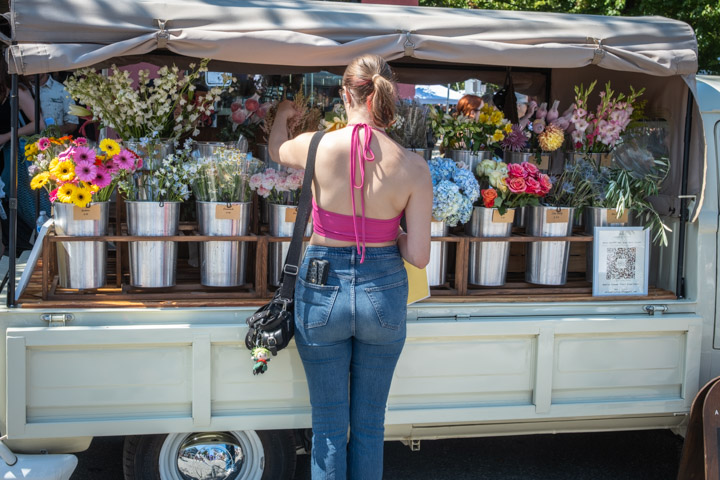
Who couldn’t smile at a flower truck?
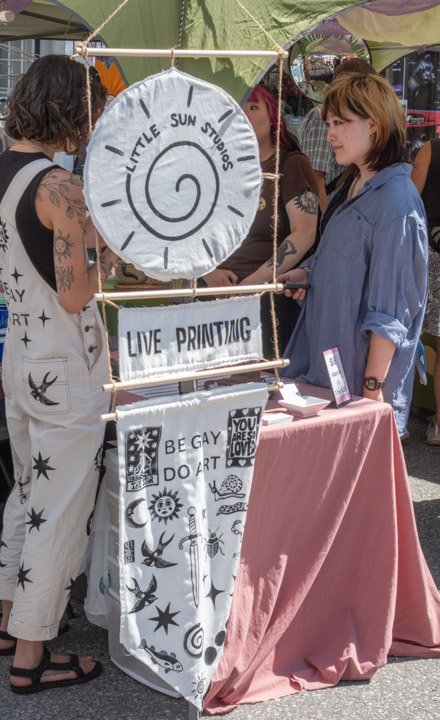
BE GAY DO ART they said.
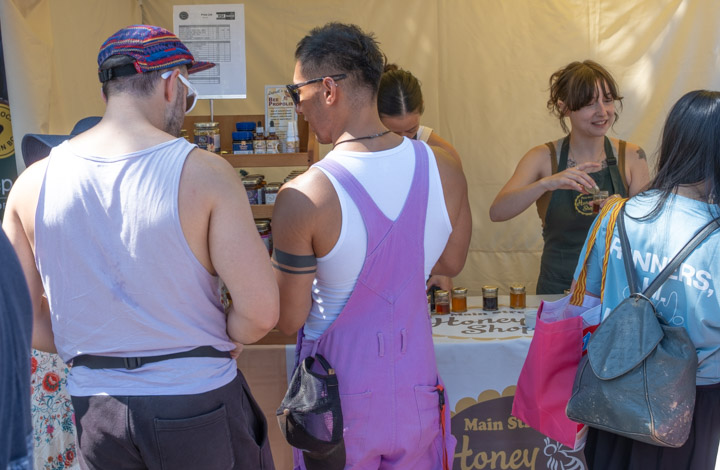
Or just chill at the honey shop.
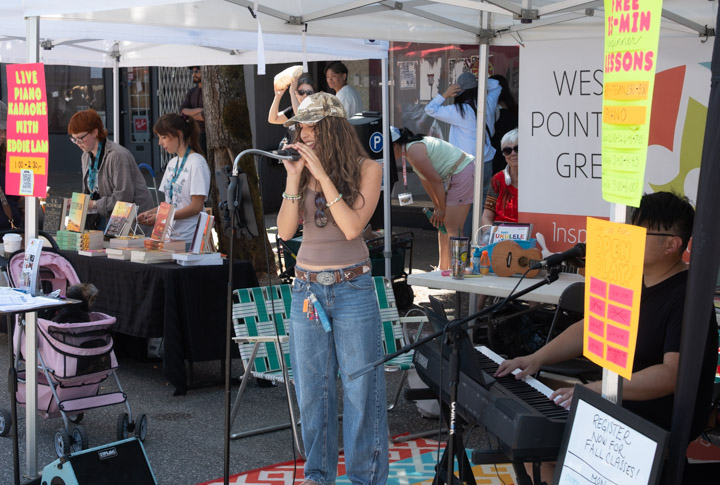
She was pretty terrible but everyone enjoyed it.
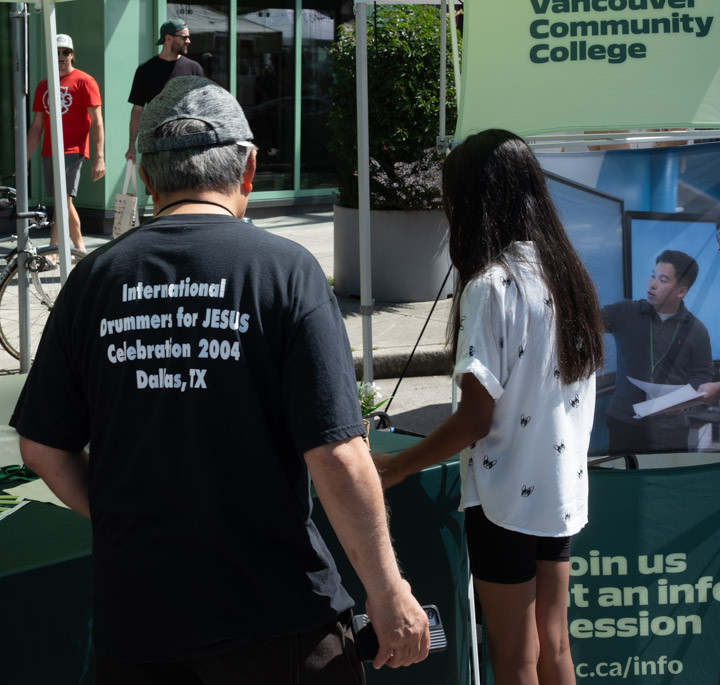
There’s nothing I can think of that would improve the message on that T-shirt.
Yesterday I was out on an errand with a pretty severe eldercare hangover — man, that can get you down — when I heard I Shot the Sheriff playing. I first thought it was a radio or something, but no, it was Reggae Night with Mostly Marley and they were freaking excellent, razor sharp.
I felt a smile welling up from inside, the first in days. Now I’ve bookmarked it.