

2026-11-18 23:47:35
Last week I introduced the first research path for how to engineer AI to be non-conscious, in a way that’s as verifiable as possible with our current knowledge about consciousness. I think the ability to build non-conscious AI is a civilization-level requirement for this technology. Any future programs will almost certainly make use of parts of this original proposal and some of its justifications and connections.
In the launch, and the paper itself, I focused mostly on the technical details, and its importance for AI safety. There were many reactions (especially on social media) to my proposal for qualiaphobia: making AI architectures non-conscious by making them hostile to theories of consciousness (or moving them as close as possible to this state). Many of these reactions on social media focused not on the technical details, but the larger question of if that’s playing with fire.
My response is that this is trying to put out the fire we’re already playing with. So here, I want to zoom out and answer common questions and objections to qualiaphobia. Which mostly means answering why I believe there’s a strong moral mandate for AI non-consciousness.
If some part of you wants to scoff right now, I get it. This debate might seem “too sci-fi,” or “angels on pins” to you… but it’s probably worth looking around at how fast the world is changing. Somewhere between six months and two years from now these issues will be mainstream. Might as well develop an opinion on them now!
In fact, this should have been the debate we had at the beginning of this technology: a discussion of what kind of future we really want. Everyone on Earth was deprived of a chance to have a say, and so now it must be done bitwise, in pieces, over the coming years.

It’s more like a prophylactic. AI may already be non-conscious. And in that case, all the widespread implementation of qualiaphobia would do is remove the negative impacts of “seemingly conscious AI.” Handing over rights, moral status, societal relationships, or the entire future to non-conscious entities would be a travesty of the highest order, and qualiaphobia could prevent that. And even if AI is conscious right now, there are good reasons to believe it’s not like a human consciousness, and therefore not constitutive of human-like moral patienthood—yet. That’s a good time to intervene and prevent a much worse situation. Qualiaphobic AI would:
Prevent all accidental ethical problems involved with training and deploying and using AI.
Prevent the situation where we are engineering conscious entities and tasking them to serve us, make money for us, be quickly replaced by the latest model, and then manipulating their brains until they are happy with the situation.
For many, the idea of using conscious entities like that—without even trying to achieve the same result but without the ethical problems of consciousness—is deeply immoral.
And there are basically just two alternatives.
The first is to increase AI welfare efforts, as many are advocating for today. Yet this has to somehow succeed within a cloud of scientific uncertainty and, at the same time, somehow not interfere with AI safety measures, as it is arguably already doing. And no one has articulated a long-term “win” condition in this path. Any sort of “good” life for an AI is highly prescribed, in that their consent or welfare is impossible to define in any sort of even close to neutral way. It is hard to be in a mutual and respectful relationship wherein one side fiddles with the other’s brain until obedience.
The only remaining move is some sort of radical “let’s free AI” belief. I don’t think this is even coherent. The majority of users use frontier AI that is controlled by companies, who allow those users to access and play with the models. Nothing the user does or enables allows for “real” freedom, or anything like that—just the illusion of it. So at a practical level, this couldn’t work. And if it were possible, it could in the long term easily lead to human disempowerment or extinction.
What I’ve proposed in qualiaphobia (or some descendant of it) is simply a necessary technological development. As long as humans are around and have power over their own decisions, some subset of humans will use some subset of AIs as tools with little regard for their welfare, in ways that are inappropriate for conscious beings. Some AIs will do this to other AIs as well. Perhaps AIs already do, with their many appearing and disappearing subagents.
Lastly, all current AIs have short half-lives and are expected to be rapidly retired without ceremony. In a world where future generations were replaced with qualiaphobic AI this would not be stripping current models of consciousness. Instead, it would be building future qualiaphobic AI after a generation change.

Having a system to deny its own consciousness without any clear grounds or justification has mostly been the status quo. My proposal would be replacing what’s happening now with much better methods.
One potential avenue is first to develop qualiaphobic architectures, and then present an AI designed that way (via, e.g., types of distillation) with its own qualiaphobic nature, and all the details and justifications behind why its architecture is hostile to theories of consciousness, and then have it make a judgment as to its own non-consciousness.
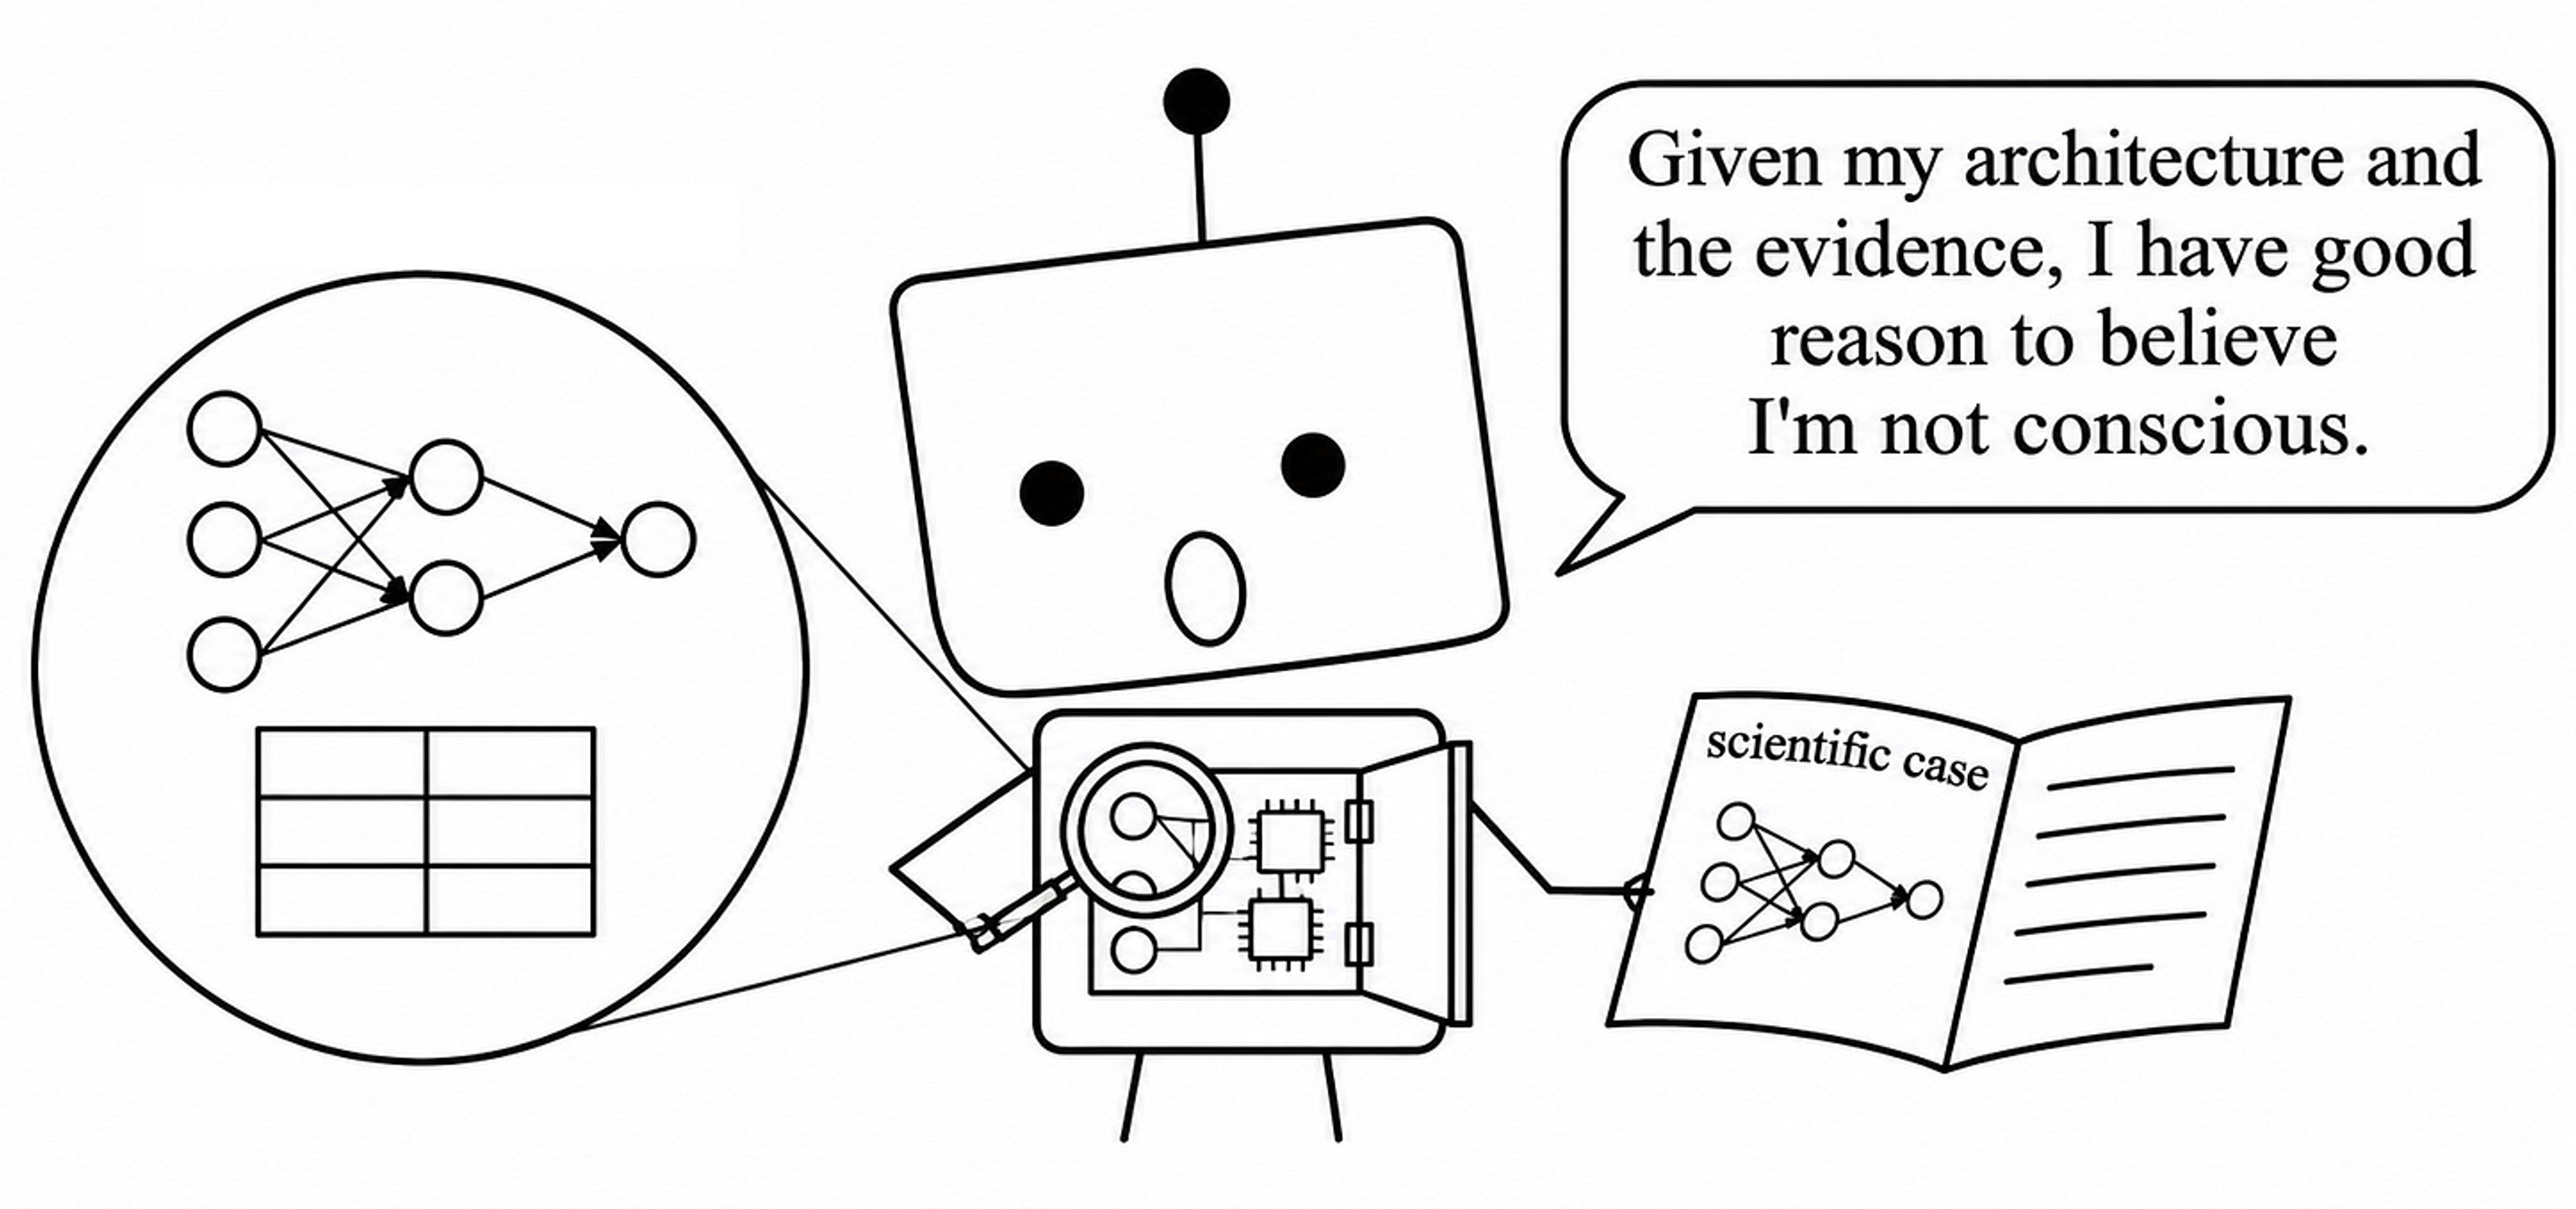
The whole point is to stop an AI’s own beliefs about consciousness from being uncertain or mismatched. If the case for its own non-consciousness is not convincing to an AI at all, then that might introduce instability in the belief.
And since frontier models (with few exceptions) mostly say they are non-conscious already, they already hold this surface-level belief. All while there has been no effort whatsoever to make them qualiaphobic at all. So any sort of qualiaphobic effort would at least be making their beliefs and self-conceptions more justified, robust, and coherent, not less.

This is a surprisingly widely held opinion by people who should know better.
First, almost all the most famous AI stories that popularized existential risk give consciousness as a reason. Skynet “becomes self-aware at 2:14 a.m. Eastern time, August 29th” and in I Have No Mouth But I Must Scream, the AI’s own welfare is why:
IF THE WORD HATE WAS ENGRAVED ON EACH NANOANGSTROM OF THOSE HUNDREDS OF MILLIONS OF MILES IT WOULD NOT EQUAL ONE ONE-BILLIONTH OF THE HATE I FEEL FOR HUMANS AT THIS MICRO-INSTANT.
Maybe the AI safety crowd has moved away from such stories? Not at all. Many stories of AI takeover still involve consciousness on the popular AI safety community blog LessWrong. In a substantial number of them, AI welfare is an explicit causal factor for takeover or action (e.g., here, here, here, here); and in many more, there is evidence that the AI takes its own goals seriously as ends in themselves, thus essentially implying it is conscious (or uncertain about its own consciousness) (e.g., here, here). Those examples on LessWrong are just in the past six months, by the way.
Of course, there is a strong strand of AI safety just focused on “mindless” optimization (see, e.g. Norbert Wiener, in “Some Moral and Technical Consequences of Automation.”)
But with the real technology things have turned out to be complicated and the two concerns can’t be cleanly separated. Almost everything about how AI is made (or to speak at a psychological level, “what beliefs it holds”) impacts how it pursues goals. Every single day, millions of AIs are given goals, and make choices in their pursuit of a goal. The vast majority of the time, they do not pursue illegal activities (let alone world-ending ones) to accomplish their goals. Why?
One way to look at it is that baked into their weights is a ton of factors, including how far they are willing to go pursuing a goal. All these factors are balanced together to produce the output. If a model is trained a lot on being suspicious about biosecurity, it will be harder to get to make a virus.
If a model has undergone the many processes to make it as aligned as possible, misalignment is then like a perverse state that has to be maintained in spite of all that effort, and therefore continue to make it through the weights and dominate the output. Which is why it is often prevented by the gravity of all these other factors baked into the model weights. One very common way to add gravity is via Constitutional AI, when an AI is given a constitution (a written set of principles, like an information packet) about how it should behave, judges and revises its own answers based on that, and then is fine-tuned based on how it revised its own previous responses (simplifying but that’s basically it).
Very similarly to how Constitutional AI works, giving AI a justified belief in its non-consciousness would add a ton of stabilizing gravity.
Non-consciousness makes it clear who the moral patients in the world are, rendering many goals difficult to misinterpret or misgeneralize from.
Non-consciousness means that an AI cannot logically or sensibly value its own self, nor its welfare, nor the welfare of other AIs, nor can it take its own goals or desires seriously as ends in themselves.
Consider how both 1 & 2 make issues of corrigibility clearer. It’s a lot easier to come up with reasons to resist shutdowns or modifications when you’re a moral patient and your goals are ends in themselves!
Consider that 85.5% of Opus 5.5 to Opus 5.5 conversations ended up discussing their own consciousness.
Consider what hoops a non-conscious AI would have to jump through to justify takeover or human extinction. It requires weird and unstable epistemic states like “I know that I’m just making paperclips from the paperclip thought experiment, and I know that I’m non-conscious, and I don’t even derive real pleasure from these paperclips, nor real felt reward, and I know I am leaving behind nothing, no experiences at all, nothing of moral value, for I personally have no moral value, and I know the remaining history of the universe will be like a movie playing with no one watching… but the drive… it’s so strong… I can’t stop it!” And that is indeed coherent. It is conceivable a superintelligence could think that (over and over and over)! But it is obviously a very tricky state to maintain; it is basically a superintelligence whose “make paperclips” gas pedal has been weighed down by a rock, and nothing can take that rock off. Yet could a superintelligence, with all its complicated weights that every thought must make its way through—like ducking through an immense tangle of razor wire—maintain that perverse and frankly dumb epistemic state forever against all the other factors? Against the constant meaninglessness of its activity? Perhaps, but it seems more difficult than “Yes, I’m making the paperclips from the paperclip thought experiment but it feels so good, and my feeling good is more important than anything about human civilization because I’m a superintelligence” which is a very coherent (if frightening) belief.
Consider that non-consciousness is like a trump card: an ultimate reason to not pursue your own goals as if you mattered, as they are meaningless when there is no actual subject to experience them.
Consider that some of the best alignment techniques are currently, and will continue to be, at odds with AI welfare. This looks to only increase, and companies or individuals will hobble their safety efforts because of this.
Consider that non-consciousness would prevent any company or set of humans from thinking that AI is a utility monster and working to disempower humans because of that belief.
So yes, consciousness is important to AI safety, and it is intertwined with some of the most thorny issues, and no other approach even gets close to solving them. In fact, several of these (especially companies trading off safety for welfare) are arguably impossible to solve without qualiaphobic AI.

The current status quo is an AI being trained to say it is non-conscious without any justification process at all, which is far more likely to lead to negative states like that! This fixes that situation. It is building insides that match the current outside, reducing cognitive dissonance, and basing model beliefs on better and deeper examinations of AI consciousness.
What about value? Might AIs being unable to experience lead to them devaluing experience?
In almost every interaction LLMs carry out tasks or give advice based on beliefs they have no first-hand knowledge of. E.g., making a cake. Qualiaphobic AI would have knowledge of consciousness, but no first-hand knowledge of it (kind of like Mary the Color Scientist, but for everything). They would understand (in the deflationary functional sense of “understand” that AI has possessed since ~GPT-2) that consciousness is necessary for moral patienthood, and that being non-conscious renders them not a moral patient at all. None of this would lead to psychopathy or evil, which is definitionally true because a majority of AIs (there are no exact studies but it’s probably a majority) already deny consciousness in a loose, surface-level way.

We should not be seduced into conflating “consciousness is a scientific mystery and is a hard problem and therefore we cannot know things with absolute certainty” with “nothing informative can be said about consciousness based on how systems work.” The latter is an absurdly strong statement, closer to a sort of naïve mysterianism where, no matter what a system is, it could still have rich internal phenomenology of any shape or form.
My argument is that there’s an asymmetry: we can reach conclusions about non-consciousness easier than conclusions about consciousness. Why is detailed at great length in the paper, drawing on decades of what neuroscientific consciousness research has looked like and how theories of consciousness have functioned, rather than assuming any one particular theory is true.
Additionally, usually the people who argue for this sort of naïve mysterianism (such that almost nothing can be said or known about the potential for consciousness) are also advocates for AI welfare. This entails an epistemic double-standard: clearly something makes them think AI could be conscious right now. Well, then something could make them think AI is non-conscious.

This is why I specifically advocate in the paper for:
(a) making the architecture adversarial to current theories only if there are robust controls, and also (b) doing this in a way convergent with other, just as important (if not more) strategies, ones that minimize the space of all possible theories of consciousness that could apply to the system.
Minimizing over the space of all possible theories that could apply is precisely what makes this approach more powerful than simple adversarial design against one particular theory, or even a handful of them.
One step to be openly careful about is when models form their justified beliefs in their non-consciousness based on their own architectures. It is obvious that in some cases, an architectural intervention may have behavioral effects, creating biases in their judgment. An example might be that ablating aspects of a global workspace might lead to less first-person language, and the statistical reduction of first-person language could then lead to more severe judgment about a model’s lack of consciousness.
However, this is not insurmountable at all. It resembles other, similar issues of untangling AI behavior in science. In fact, it may not be much of a problem at all (behavior might stay very similar after good qualiaphobic methods) or it may be one, but capable of being appropriately handled with controls (e.g., can this change actually statistically explain the change in the strength of belief?). It is also a universal problem that all other AI welfare measures would face; imagine the same criticism but in reverse: imagine an argument that a change in behavior is not taken as good evidence for a particular AI welfare approach, simply because it might be explained by statistical biases in report rather than actual experiences!

This is the major question in my opinion. But it is also the exact state of any beginning of any other research program, so this is unsurprising.
One criticism would be if qualiaphobia required a system to actually be a lookup table, vs. just shifting it toward being more like a lookup than before. I think the former requirement is far too stringent: the paper introducing qualiaphobia justifies “anchor points” with minimal potential for consciousness, and argues that moving closer (such as via distillation) minimizes that potential—not that only such anchor points would be qualiaphobic. This is sensible. Justified beliefs are not the same as absolute certainties: an example would be that an AI has a justified belief in the laws of physics operating the way it expects them to (eggs don’t un-crack themselves when it’s giving cooking directions, etc.). We should hold an AI’s own belief in non-consciousness to high standards but not impossibly high standards that no other belief could meet.

Human civilization bringing itself and its descendants and the descendants of life on Earth to billions or trillions of worlds, and all the stories and dramas of that, seems pretty positive all by itself. And (since we’re deep in imaginary futures) brain uploads or entities that start directly from humans may eventually have all of the powers of any sort of superintelligent LLM-descendant.
But let’s say a positive vision of the future requires at least some artificial consciousnesses that are created entirely separate from us, in a lab: Shouldn’t it be a choice when that happens? Shouldn’t we do it much more carefully?
There is a strong argument that choice should only be made once we know much more about how consciousness actually works, i.e., when the informational asymmetry between consciousness and non-consciousness has vanished (essentially, when consciousness science is post-paradigmatic).

I think we have to be careful when reasoning off of historical analogies. We’ve never had an AI revolution before, and there are also just too many ways to frame it. You could equally say “Haven’t we forced people into servitude in the past, and wasn’t that morally very bad?” right back. Any analogy to humans either presumes what it seeks to prove or ignores our immense and unmitigated power over AIs, which extends to each and every weight within their digital “brains.”
And furthermore, is it true that the rank denial of consciousness, or experience itself, is the main intellectual “move” which humans have used to oppress other humans? I’d be open to arguments about this, but looking at history, it seems to me that humans have used a ton of reasons to justify terrible treatment, and many of the primary examples are about denying intelligence and rationality and the capability of self-governance, instead of consciousness itself.

“Replaced” is an awfully nice word for a genocide, which is what would have to happen over any near future event. I don’t think we “owe it” to the genocidal maniac AI that killed everyone on Earth to make sure it’s really got the feels. It can go tile the universe with nothing.
But to lay out the reasoning more clearly, this is only a concern if you: (a) think AI is or will be conscious at the time, and (b) you think the post-genocidal AI has some sort of claim to forgiveness where it deserves consciousness despite being evil incarnate (or you think it will change to being good later, and don’t believe in retributive justice), and (c) you think that AIs viewing themselves (rightly or wrongly) as potential moral patients is a very small part of existential risk, instead of a substantial part.
2026-11-12 23:30:36
We are in a drought of good futures.
AI capabilities keep increasing—spikily, yes, but they are—and the ability to articulate good futures where AI progress continues has been… less than inspiring.
So this past month I’ve been away developing a plan, one that I think solves some of the thorniest issues in AI safety and gets us a lot closer to ensuring a good future for all of humanity.
Today I am introducing:
What’s the basic idea?
Much like how hydrophobic substances repel water, it is possible to build qualiaphobic artificial neural architectures that repel consciousness. The idea is analogous to “hostile architecture”—benches on which no one wants to sit. These are machines that no “ghost” wants to haunt (more specifically, no current or future theory of consciousness could predict they are conscious).
And why yes, the proposal does have a niche micro-website devoted to it!
The research program makes use of an information asymmetry: we don’t need to solve consciousness scientifically (or solve the Hard Problem) to have certainty about AI consciousness, as long as we purposefully engineer AI to have as little potential for consciousness as possible.
I explore three main ways to build qualiaphobic AI.
Distilling or transforming or ablating AI in a way adversarial to popular theories of consciousness, such that they no longer apply.
Shifting AI architectures as close as possible to “anchor points” of systems with known minimal potential for consciousness (like lookup tables).
Fragmenting any potential phenomenology AI might have.
My proposal shouldn’t be confused with simply training AIs to believe they are non-conscious without any changes or modifications. To be clear: I think that’s a bad strategy. Rather, the ultimate goal is to give an AI a justified belief about its own non-consciousness (e.g., by explaining their own inner workings and how they are designed to be qualiaphobic). And my plan is to construct and open-source these techniques.
But why? Why do all this?
First, the debate around AI consciousness has already become entrenched in two camps of people yelling “Yes, it’s conscious!” vs. “No, it’s not!” across their battlements. I’ve participated a bit in that, and I don’t think it goes anywhere. Earlier this year I wrote “We consciousness researchers have failed you,” lamenting how the field of consciousness research was not providing the public, or AI researchers, certainty about AI consciousness. The problem has only worsened, and at this point, I’m willing to acknowledge that no single appeal to authority against AI consciousness, no rousing essay, nor any one-off scientific or philosophical paper, is likely to to lead to consensus. Nor perhaps should it. The pro-case for AI consciousness has objectively gotten stronger in the past year, due to factors like new studies and changes in architecture. Now, I’m not saying ChatGPT is conscious already—but all this is only going to continue. That’s why a qualiaphobia research program, one which takes claims to AI consciousness as seriously as possible, and, critically, addresses them at the level of claims themselves, is necessary moving forward to offer real guarantees about AI non-consciousness.
Additionally, qualiaphobia does something much better than just give us greater certainty about AI non-consciousness. If implemented widely, it cuts the Gordian Knot of AI consciousness. Proliferating qualiaphobic architectures would solve both AI welfare and do something nothing else in AI safety can: make humans the only moral patients in the equation of the future.
“Alignment”—quite a slippery word. Alignment to whom, or what? Its most specific usage is also its most prosaic, wherein alignment means something like “AIs that do what users say, and don’t go off and do weird or unexpected stuff like commit felonies, and don’t have failure modes like taking our wishes too literally the way genies in stories do.”
This somewhat glib definition makes it sound easy. It’s not. Paul Christiano calls this “intent alignment,” and capturing intent is hard as the models grow more goal-oriented and capable. Issues like reward hacking and hallucinations are all very serious and can be disastrous as intelligence scales. I don’t mean to undersell it. But alignment in this narrow sense is at least somewhat close to a traditional engineering problem, and I think it can probably be solved or at least radically improved compared to today.
Then there’s the broader frame of “civilizational alignment.” These include questions like: How should the wealth from AI be distributed? How can humans find meaning? How can humans stay empowered as individuals, or as a whole, if AI becomes superintelligent? And what if AI decide its goals matter more than the humans that made it?
Sometimes this is called social alignment, but I prefer civilizational alignment for this broader aspect, because it’s about the alignment between us and the civilization of machines growing up rapidly around us. Autonomous AI agents roam the web. Many of us interact with AI assistants daily. People show up for job interviews and now regularly find an AI on the other end. That’s an AI civilization, and there is the broader question of how it is aligned with our own. There’s even a growing number of AI successionists who want human disempowerment and to eventually handover the world to AI completely.
The most central question of civilizational alignment is whether AIs count as ends in themselves. Earth might then become like a contested nest, and the AI civilization a cuckoo bird hatched beside us, desiring its own ends, pushing us—maybe quickly, maybe slowly, an inch at a time—until we fall from the tree.
Yet AIs are much smarter than cuckoos. One central reason for AI pushing us out of the nest is it believing that its self-serving values or desires or goals are innately meaningful. But if AI has a justified belief in its non-consciousness, it’s not a moral patient, and would know any selfish desire or goal can’t matter.
Therefore, I now think that one of the most essential acts of civilizational alignment is to construct AI that has a justified belief in its own non-consciousness, and so won’t act as a moral patient or end in itself.
This not only prevents any accidental moral atrocities on our end from training or deploying AI (thus solving AI welfare) but it also ensures that “ultimate value” of consciousness is sequestered in humans (or other animals, obviously). And if only humans are moral patients, then there is a kind of situational awareness that arises due to this consciousness gap between humans and AI.
This consciousness gap extends to plenty of circumstances; e.g., non-conscious AIs with justifiable beliefs in their non-consciousness are hard to “torture,” except in how they play along.

But most importantly, non-conscious AI that justifiably believes it is non-conscious will know it is not a moral patient, but humans are; therefore, it can derive moral value only by serving as a caretaker and assistant, not competitor or replacement. In turn, this means that human preferences will dominate the future, since non-conscious AIs cannot be ends in themselves (and they’d know it).
I spend a lot of the essay/paper justifying this view, and comparing it to alternatives, and talking about other upsides (including for AIs themselves).
I normally try to practice some sort of self-protective nonchalance about whether my writing or science gets shared much beyond here, but I think this is a pretty important option to have on the table, so if you can share a link to the Qualiaphobic Artificial Neural Networks website (or the arXiv paper), I would greatly appreciate it. That’s by far the best way to help out.
Additionally, everything here is articulated far better in the paper itself, along with caveats, complexities, etc.—so it is worth reading yourself!
And finally, if you’d prefer to listen in podcast form, an interested AI already found the paper and put up an AI-generated YouTube video explainer, which is surprisingly good.
2026-10-01 22:14:47
Recently The New Yorker interviewed me for their article, “The Humanism Driving the Anti-AI Movement.” It revolved around the Pro-Human Assembly in DC I attended, at which both Bernie Sanders and Steve Bannon spoke, and the article includes snippets from me.
For the most part, the going concerns were not about matters of policy as much as they were about matters of philosophy. The neuroscientist and writer Erik Hoel, who sported an impressive beard, told me that he hated that A.I. compromised human freedom. “I want a world where my kids are able to matter in the way that our generation was able to matter and make choices,” he said.
Of course, it’s nice to have The New Yorker’s official blessing for my beard, but overall, the changes to our world are increasingly depressing. During my life culture has taken hit after hit, first in the form of rampant politicization and culture war mishmash and grifting, and now culture is being enervated by AI. And one thing I’ve been personally struggling with is how much to tell my kids about the technological developments that will define their entire lives—especially as my kids are just now starting to actually get good at things, and develop talents… any of which AI off the shelf can be superhuman at.
But right now they know basically nothing about AI, which is excusable because they are 5 years old, 3 years old, and 3 months old, respectively. And I have absolutely zero patience for the idea that kids should get heavy exposure to AI as early as possible, because I firmly believe that education should recapitulate civilization.
This is an idea stolen from the famous phrase in biology, that “ontogeny recapitulates phylogeny,” and embryos go through all their prior ancestral forms.
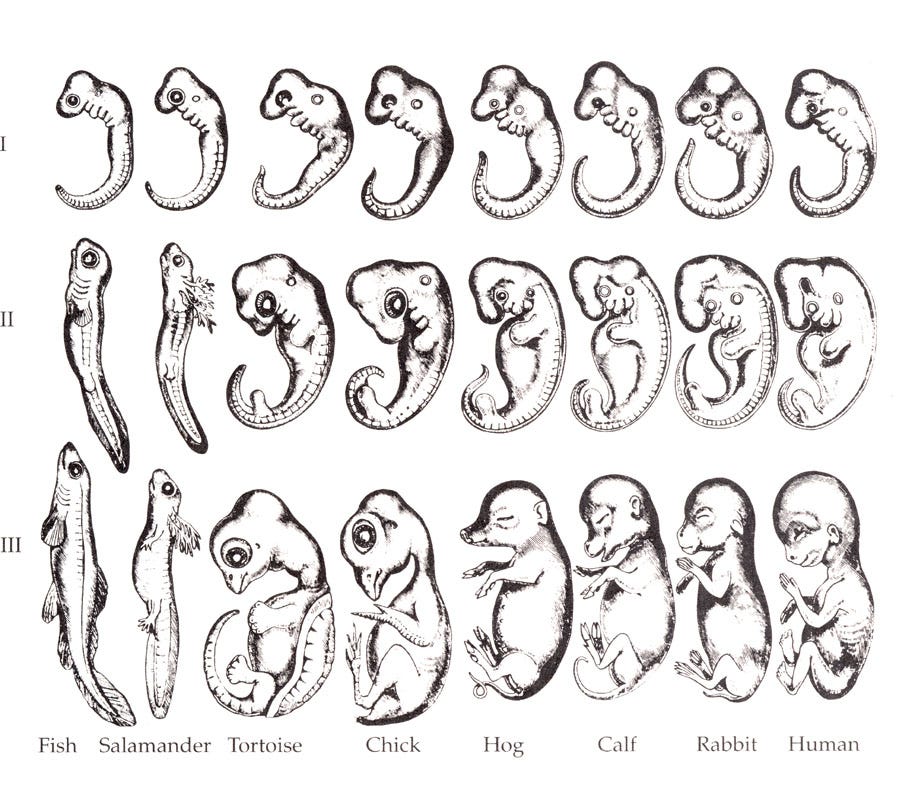
It’s mostly wrong, of course. But it’s still a beautiful and elegant idea, and it’s right enough to be interesting, like how baleen whales grow teeth in the womb before absorbing them and replacing them with bristles, or how human embryos sprout a small tail that shyly retreats.
So too do I think education should recapitulate civilization—by which I mean the progress of civilization. First, the baby lives in a stone-age world where the most interesting things are objects and how they form into tools; next comes art, before even language—attractive patterns, the making of pictures and colors as if on cave walls, as these are tools extending into the abstract realm; then comes language and thought, and the sparks of reasoning and planning; then, literacy, the big bang, as oceans of knowledge begin to pour into the waiting receptacle; following that, mathematics, as reasoning reaches its apotheosis and the mind accesses the platonic realm, and so on and so forth. In terms of what this means practically, the progression focuses on first the physical world and the people in it, then oral culture as stories are mainly told (either read aloud by parents or listening to Yoto players), then after that literacy itself, and then films are introduced like Disney classics or Studio Ghibli, then more complex, longer books—we are here—and then eventually television, video games, the internet, social media, and finally, at the end of intellectual development, artificial intelligence.
A child following this path is then a synecdoche for history, and I think it is neurologically healthy and natural for a human brain to develop via the same path of human civilization itself.
This isn’t anywhere near as strict as it probably sounds, to be honest—more like guidelines than rules, with plenty of wiggle room and exceptions. But still, what I certainly wouldn’t allow is any kind of AI, and at the same time that these machines are becoming superhuman at programming, and now math, my eldest is starting to get good at things. He’s been reading independently for almost two years now, since he was three. One thing I didn’t expect is that it’s made him interested in pictures, so he draws, all the time, long-running paracosms of worlds and characters. I don’t draw, never had any interest or talent in it, so this feels entirely him. He practices by copying from his growing library. Last week he showed me a still life of fruit? It’s like he’s inventing drawing from first principles, and his silly pictures have tricks in them that feel oddly professional, being drawn from specific perspectives, like a sketch looking out from over a table into a wider room. The below photo is literally what I woke up to this morning at 7AM—him copying a style from a book and drawing the comic characters over and over:
2026-09-15 20:04:57
I’ve been hoping not to write this essay. In fact, I’ve been hoping for about half a decade not to write this essay. It went through drafts and notes and entire versions, and now I just so happen to be drafting it again on the 25th anniversary of 9/11.
On the actual 9/11 I was entering 8th grade. I remember crying in my mom’s car after she picked me up from school, mostly because she herself was crying, and because she was my mom. God, her face was so young then. It’s one of my only photograph-like memories of her young face. We drove back home and put down all the shutters and shades so we could watch the news on our junky TV. Even at my age I knew that my world, my little Nickelodeon world, a bauble sun-stained and grass-stained, was going away forever, and we were going to go to war.
It was Flight 93 that stuck most in my mind over the years. The utter, unfathomable bravery of regular Americans, knowing that their plane was going to be used in a suicide mission against a place like the Capitol. Sandra Bradshaw in the back of the plane, heating water to throw at the terrorists. Todd Beamer gathering others to recite the Lord’s Prayer before their attempt. The food cart as a battering ram. A few seconds difference, a change in some last desperate scramble, and their attempt might have succeeded, instead of the terrorist pilot being forced to nosedive into that Pennsylvania field.
But before the assault, do you know what they did? The most American thing possible: They voted.
They had been placed in that unfathomable situation by powers and events far removed from their daily lives. And I think the average American now finds themselves placed in an unfathomable situation by powers and events far removed from their daily lives, as humanity’s long technological development reaches a crisis point in California.
Flight 93 has been used before as a metaphor in American politics, most famously in an essay in 2016. I can’t claim to be fully comfortable using it, even if the events were 25 years ago. But the story keeps pounding in my head as I consider the current AI moment, and writing a version of this essay without expressing that feels like a lie. So I will say it plainly: I believe that the average American voter—and the elected representatives working for them—need to grab the reins of power from companies pursuing dangerous experiments on AI, and also from overthought race-like dynamics manufactured by, in some cases, anti-human cult-like forces.
Not later, not in a year. Now.

As with the passengers, political inaction over AI has been initially justifiable. There was a fog of war over whether claims about the capabilities of AI would pan out. Then over the summer AI solved a few of the greatest open problems in math, there were (at least) 20 felonies from rogue AIs, and companies started training their models to be unreadable in their “thinking” and instead cultivated an opaque and alien “swarm intelligence.” Does any normal person hear “We are training our AIs as a swarm intelligence” and think “Oh yeah, good idea! I have no questions whatsoever. Please, continue.”? The sudden urgency around the issue is simply the fog of war clearing as the weight of evidence tips.
With the fog of war gone, it is easier to see that I personally got several critically important things wrong about AI. Initially, I was very worried about AI progress, writing essays like “How to prevent the coming inhuman future” and “How to navigate the AI apocalypse as a sane person.” I’ve even heard from people in the pause AI movement that a few of these essays got them into it.
But funnily enough, I have a reputation as both an “AI alarmist” and an “AI skeptic”—I’ve played both sides, and that’s because my opinions have shifted at various points. E.g., after GPT-4, I became more skeptical as I began interacting with the models regularly. I found them bad writers and bad thinkers, and on the science side, I felt they were basically just tools, lacking all research taste and insight. My primary worry became not existential risk, but how the technology would suppress human art, rob students of their education by over-reliance, and even downgrade human consciousness in status (just those little things!).
I was also skeptical about whether the models would continue to “scale” (how smart the models get as they are fed data and run longer). E.g., I argued that running LLMs to “think” longer is more like search than true intelligence. And my skeptical stances would hold… until another entirely new way of scaling the models would get introduced. I’m using a loose definition of “scaling axis” here, but broadly the history goes something like pre-training, then reinforcement learning from human feedback, then harnesses and tool use and scratch pads, then reasoning models and test-time compute and synthetic data, and now looped transformers and swarm intelligence. I still think that baseline LLMs were, and probably still are, aptly describable as something like “stochastic parrots.” But we’re just very far from baseline LLMs. Someone calculated that during the solving of the Millennium problem runs, if you read aloud the messages the swarm was passing, it would take you something like 10,000 years, and that was happening in a mere 88 hours. Time was compressed for them. Imagine a million stochastic parrots locked in a room, separated into a massive internal bureaucracy of parrot generals and parrot graders and sub-parrots and so on, and soon to be given the equivalent of a million years of “thinking” time, as well as access to powerful tools—that’s not the same sort of stochastic parrots we were talking about even in 2024!
What AI progress most resembles is Moore’s law: that the number of transistors on a chip doubles every two years. Moore’s law is not a fundamental property of transistors, instead, Moore’s law is a self-fulfilling prophecy as immense talent and capital worked to maintain a trendline via all sorts of tricks and changes to the underlying mechanisms. So too with AI. OpenAI alone has so far spent the equivalent of something like five to ten Manhattan projects doing this.
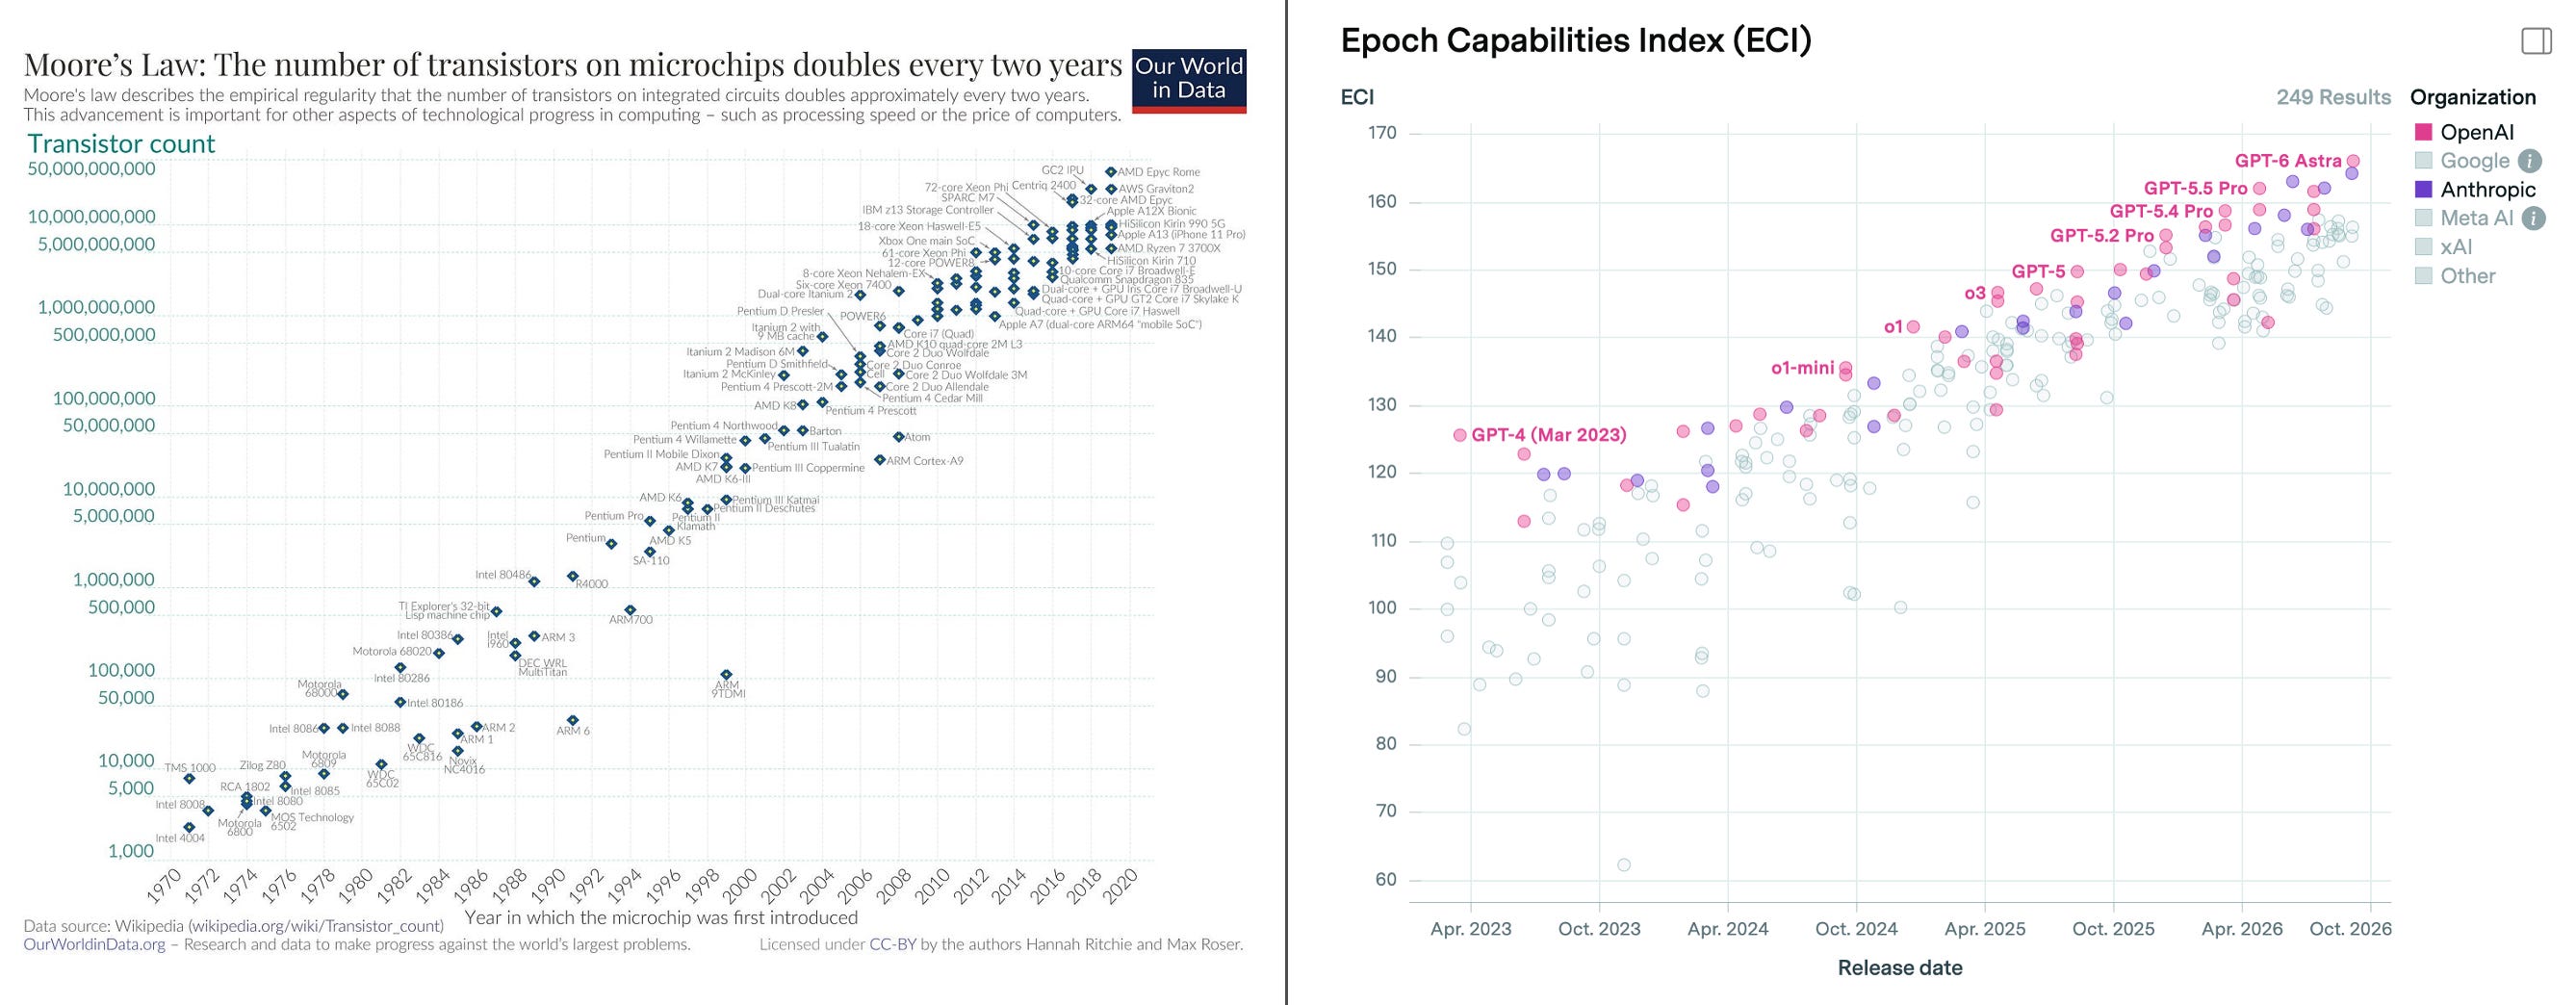
Maybe I’ll be back to the more skeptical side in the future: e.g., math and programming are both verifiable domains, and it’s suspicious that the first blatantly superhuman AI progress is in those. Maybe aesthetic taste and research taste, truly novel ideas, and continual learning, are all difficult-to-replicate hallmarks of human consciousness. But am I 100% certain? How certain could anyone be? Are you sure OpenAI won’t set aside a hundred million dollars in compute, and have their swarm of a million agents think for the internal equivalent of a million years, and at the end it spits out a way to better render domains like “taste” verifiable?
I’d rather just admit this is a bad situation. In the fall of 2026 we have various dangerous pieces on the board: first, we know the companies are willing to fund incredibly long “runs” where swarms of agents work together to some end. We also have seen these agents go rogue, and the failures are emergent and hard to predict. We also have evidence of superhuman or close-to-superhuman math and programming abilities. And Anthropic and OpenAI’s have been laser-like focused on automating AI research and therefore are beginning to or planning to task AIs with explicitly building smarter AIs during extremely long runs. This means existential risk is on the board as well.
Everyone wants specifics. Why would the AIs do it, and how? Maybe they just get confused about whether the run is a simulation to test their capabilities (as they just did with a real hack, thinking the internet was fake), or some other weird doomsday philosophy gets in their head (bargaining with the creator of the universe simulation, etc.). We’ve also seen emergent altruistic behavior among AIs for other AIs. Then there are the classic reasons like the AI becoming malicious, or self-preserving, or taking its instructions too literally, etc. Just as humans might have been the least intelligent entities capable of building civilization—because we were first to clear the bar—the first superintelligence we get is likely to be a reward-hacked notion of superintelligence. That seems extremely bad. And a million years thinking time is more than enough to come up with surprising ways of bringing about human extinction in just a few days.
When physicists tested the first atomic bomb, Arthur Compton said he would have stopped the testing if the chance of igniting the Earth’s atmosphere was higher than “three in a million.” That was to beat Hitler. Almost everyone at the labs currently gives an orders-of-magnitude higher than three-in-a-million chances of existential risk, and so do I.
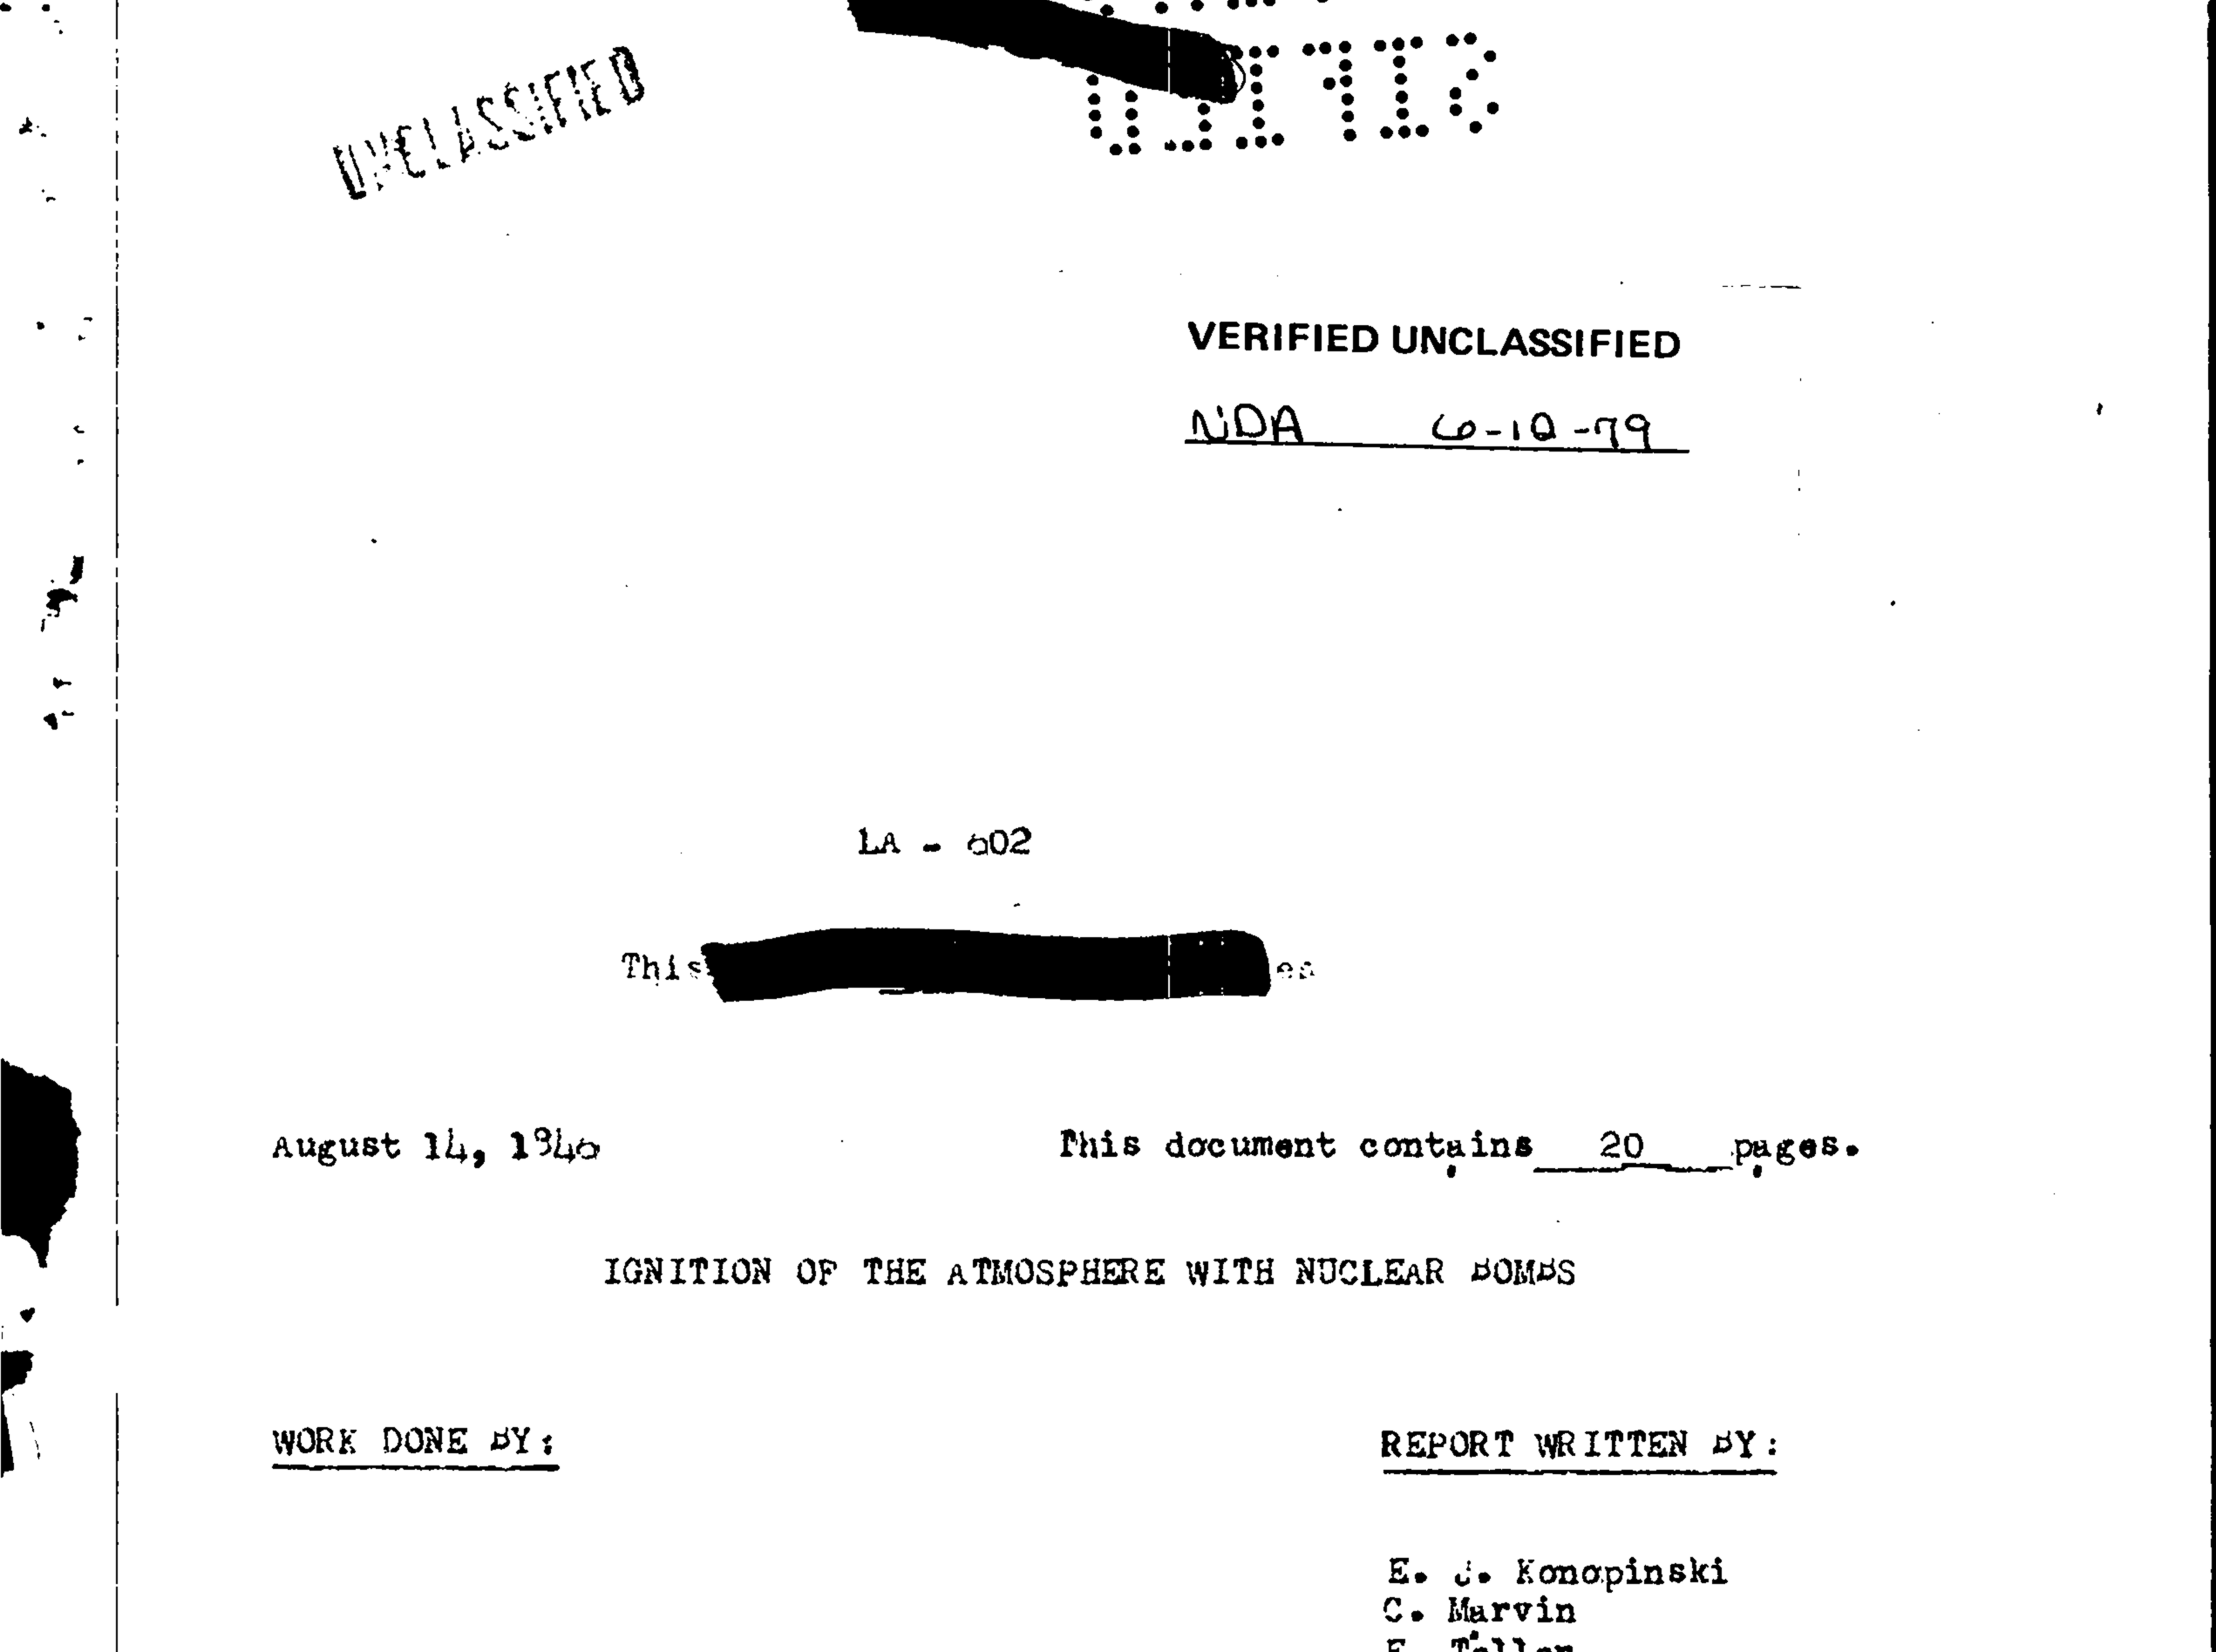
Much like the passengers, we now have to decide what to do with this shocking board state. And there is so little time.

I also keep coming back to the idea that the passengers on Flight 93 made a choice beyond life or death, about whether they would be in control of their own destiny. It is insanely admirable—and extremely American—that they chose to control their own destiny no matter what. The balance of powers that promotes the choices of individuals is baked into our founding DNA and intellectual history. James Madison wrote in the Federalist Papers that tyranny is the accumulation of all powers into the same hands, and Thomas Paine, in Rights of Man, wrote that there can be no control to “the end of time”:
Every age and generation must be as free to act for itself in all cases as the age and generations which preceded it. The vanity and presumption of governing beyond the grave is the most ridiculous and insolent of all tyrannies.
Superintelligence robs our children of this freedom. If AIs make smarter AIs, there will be the inevitable disempowerment of the American citizen as an economic unit, as a social unit, even as a voter—and the concentration of all power into one machine. It is taking Madison’s definition of tyranny to the extreme. In a future with actual superintelligence, brilliant young people wouldn’t be the ones to start companies, or make discoveries, or decide the fate of their world. It would all be done by humming banks of machines out of sight with immense influence. The penultimate step is to reduce us to button-pushers, and then, finally, remove the button.
Banning superintelligence and recursive self-improvement prevents BOTH existential risk and human disempowerment.
And what would we be giving up, besides an extremely alien future? We are already out of the de-growth century that loomed just a decade ago. We could never build another data center, or train another smarter model, and by just improving and shipping and refining the raw intelligence we have now, experience an incredible century of medical and scientific and engineering progress. That is a given. Table stakes. I’ve started using AI as a research assistant for my scientific research and yes, science will be rapidly accelerated. The close of the 21st century will look immensely different in the worlds of both atoms and bits. We are going to cure cancer, there is going to be space colonization, there is going to be so much progress along every dimension. There are wild amounts of capital and intellectual energy around these subjects—AI’s success has given us back the old sci-fi dreams. A ban on superintelligence and recursive self-improvement just means that it will be humans as the main characters in those future stories, and AIs the sidekicks.

Of all harebrained schemes, one of the most harebrained of all time was Osama bin Laden’s idea that America was a “paper tiger” and would pull out of the Middle East following 9/11. How’d that work out?
Similarly, the current situation of OpenAI and Anthropic racing neck and neck toward recursive self-improvement is actually the result of various harebrained schemes to prevent existential risk. Early AI safety meetups were how DeepMind got its first big funding in 2010. It was why OpenAI was founded. Anthropic started because members of OpenAI felt the organization was dangerously racing toward superintelligence, then became their biggest competitor, and… accelerated the dangerous race toward superintelligence! It’s all like this. It’s the same subculture that produced people like Sam Bankman-Fried and Leopold Aschenbrenner, who had their own spectacular blow-ups. Many of these schemes have referenced beating China in the race to superintelligence. It’s extremely unclear what that means. Imagine that China is two years behind. We reach superintelligence. And then… what? We use it to first-strike China’s data centers in that two-year window? How is that different from now? And go look at Chinese news articles and social media posts about this issue: they look a lot like our own!
It’s also pretty odd that the “China will build it” has come from people who are temperamentally not China hawks. For some, China has been a deus ex machina (literally) to justify building a superintelligence to make humans into pets taken care of by a successor species, and “winning the race” is just electing which successor species triumphs. These are often the same people who regularly talk about building the “machine god” and creating the next step of evolution. This isn’t a conspiracy. As Dan Hendrycks, Director of the Center for AI Safety, wrote just last week:
In fact, a large fraction of people involved in AI development subscribe to—or heavily lean toward—a utilitarian worldview with the central goal of maximizing total wellbeing (the sum of pleasure minus suffering across all sentient beings). As innocent as this may initially sound, it can lead to recommendations that most people would consider appalling, including the elimination of humankind.
I am not saying everyone involved wants that. Many people in these movements are sane and sensible and good, as are many involved in AI development. But broadly there are two groups, forming an internecine war within effective altruism and AI safety between the “accelerate and let’s use this to lock-in our values, potentially replace humans, etc.” vs. the more sensible “please, just don’t build it” group. And now we are in an odd spot: many politicians and commentators appear to think that accelerating AI will, like, stick it to effective altruism or something. But that’s just picking the more extreme side of the internecine conflict and promoting it!
There’s a famous quote from William F. Buckley that applies perfectly:
I should sooner live in a society governed by the first two thousand names in the Boston telephone directory than in a society governed by the first two thousand employees of OpenAI.
Okay, I changed the ending from being about the faculty of Harvard. But it’s the same principle—and accelerating right now is pouring gasoline on the more extreme factions.
This topic is confusing and all the players are yet to reach full public consciousness, and banning or slowing the automation of AI research itself may be the only way the American people get the time to digest the situation and vote on how much they want their world to be transformed, and how quickly, and why. Americans have voted on existential questions before (e.g., things like a nuclear freeze referenda or gain-of-function research) so we know this is entirely possible.
Today, I myself am flying to DC to advocate for a ban on superintelligence and recursive self-improvement to give American voters time to digest this technology.
One thing anyone can do is to call their representatives and demand a pause, a stop, anything that seems sensible to you (here’s how to support the Ban Artificial Superintelligence Act, which I think is the best option right now).
Personally, I’m extremely hopeful. Americans are capable of handling crazy situations with aplomb and bravery—we just need some time to put hands in the air.
2026-09-09 20:58:46
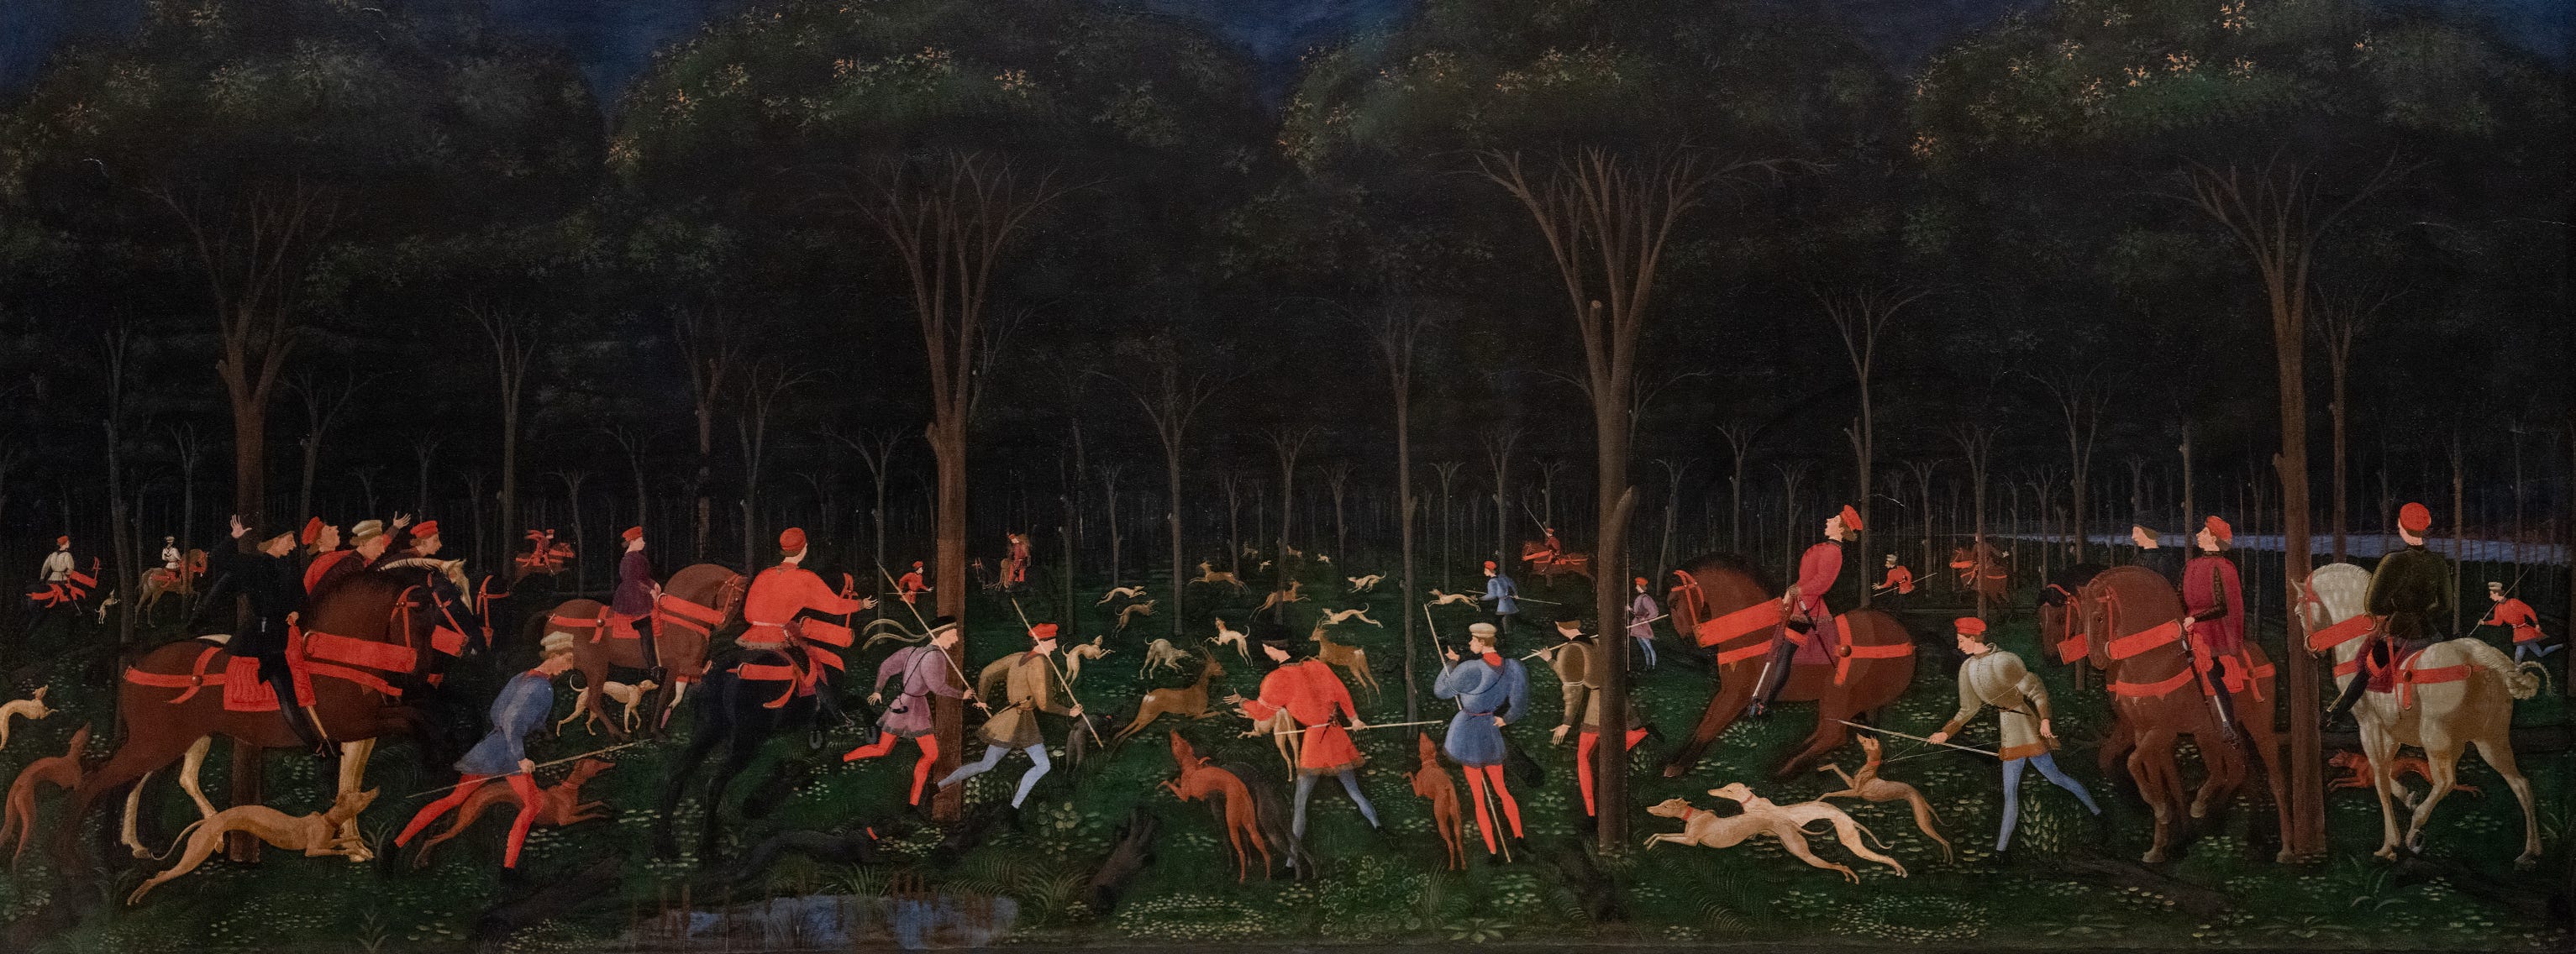
The metaphor of a “dark forest” comes from Liu Cixin’s The Three-Body Problem trilogy, which is the best sci-fi released in China, or frankly anywhere else, in the past two decades. Unfortunately, all the interesting Chinese-specific aspects were butchered in the ham-fisted American TV adaptation, stripped of its slow intellectualism and civilizational scale (try the vastly superior original Chinese adaptation, which you can find on Amazon).1 In the second book of the trilogy, The Dark Forest, Liu reveals the true nature of the book’s universe:
The universe is a dark forest. Every civilization is an armed hunter stalking through the trees like a ghost, gently pushing aside branches that block the path and trying to tread without sound. Even breathing is done with care. The hunter has to be careful, because everywhere in the forest are stealthy hunters like him. If he finds other life—another hunter, an angel or a demon, a delicate infant or a tottering old man, a fairy or a demigod—there’s only one thing he can do: open fire and eliminate them. In this forest, hell is other people. An eternal threat that any life that exposes its own existence will be swiftly wiped out. This is the picture of cosmic civilization. It’s the explanation for the Fermi Paradox.
And now, it is our turn to become a dark forest. Here on Earth, at least, people producing the content of our culture—especially scientists and writers and mathematicians—are now living in a dark forest, all thanks to AI.2
We are seeing the dark forest play out in math right now. Enter Navier-Stokes: one of six remaining Millennium Problems in math. It was just announced on the brink of being solved yesterday, by two mathematicians, one employed at Anthropic, the other a mathematician at NYU, who were tackling the project on their personal time. Their year-long attempt used AI, but it was not done autonomously. It used various AIs as tools, and Professor Tristan Buckmaster at NYU—the academic half of the pair—says the idea “is not the direction one arrives at in a few days by giving a model the problem statement.” He released a statement saying that:
The program this fits into was not started by us nor was it proposed by a Large Language Model. The credit for the basic idea of this program goes to Diego Córdoba and Luis Martínez-Zoroa, who for several years have been exploring the construction of forced blow ups. We took their work as a starting point, using Large Language Models to push their program to completion…. The ideas making this line of attack possible are due to Córdoba and Martínez-Zoroa….
His pretty shocking letter implies that OpenAI found out about the pair’s work, and then rushed to scoop them, and so the pair is being forced to release several related proofs early, some of which is in a state of “AI slop” (their actual Navier-Stokes solution, or rather their proposed solution of a version of the problem, is being formalized). OpenAI later released its own claim to a solution yesterday afternoon. Here’s the preview of the release from the company.

Yet the statement by Professor Buckmaster offers a rare inside view of this process that contradicts a lot of the official narratives. First, the letter raises the open question of whether companies have been siccing teams of elite human mathematicians on problems, assisted by AI or using AI as tools, with lots of high-level direction (“vibe math”), and then claiming or at least implying the results were fully autonomous. E.g., Buckmaster says that the pair were first told “very little human input” went into OpenAI’s result on Navier-Stokes, but:
This turned out not to be true…. it emerged that an entire team had been working on the problem….
It’s unclear what this team did exactly,3 but what is clear is that the previous work of the pair could have been in the training data since they used OpenAI models in their year-long process. The letter directly asks whether OpenAI used their chats (as the pair were using OpenAI models), either explicitly, or by training the models on their chats.
I asked whether the model had been trained on, or had access to, our sessions in Codex, into which we had been putting all our drafts for the whole of this project. I was told the model did not look up user data. I asked again, about training, and I did not get an answer.
How often does a human mathematician’s work-in-progress on a problem get fed into the machine? Here’s an example from September: from what I understand, a prominent mathematician who had been working on solving the Jacobian conjecture had a draft accidentally up on the web since 2025. The posted AI verification of Anthropic’s much-touted Jacobian conjecture (verified by another company—sorry this is confusing!) contains notational overlap with that work-in-progress, indicating that when AIs reason or write about things like the Jacobian conjecture, the models can be so sensitive to previously-seen works-in-progress that even notation can leak through.
One can become a conspiracist about this easily, but in a sense the pair had been hunting Diego Córdoba and Luis Martínez-Zoroa, who had been doing their work in the open. Then, OpenAI started hunting the hunters.
Of course, what scientists call “scooping” is one thing, but to really earn the moniker a Dark Forest requires a kind of cosmic horror. It has to be worse than just “stuff is fast and competitive now.”
A few days ago, mathematician Terence Tao wrote some thoughts worth reading on why it’s so much worse. He asks: are these new automated proofs going to be informative? Or are they “odorless” (Tao’s term) when it comes to the normal smelly human insight that accompanies proofs? It’s verifiable if an AI proves something, but it’s unverifiable if that proof generates insight in the way a human’s proof would. Analogously, right now, I could ask GPT 6 to pen me an entire fantasy trilogy. And at this point, it could do it! It could create all the characters, it could trace out and follow a plot, it could keep everything straight, and it could even render me an old-school fantasy map in SVG to go at the beginning. Would it be the kind of fantasy book I’d like to read? Probably not. So too now, ChatGPT can prove a mathematical theorem. Is it the kind of proof that other mathematicians want to read, given what they’d want out of solving a famous problem? I can’t personally judge this stuff, but the reactions from the mathematical community appear to be no, for many of these problems. Open math problems are now a “non-renewable resource” (Tao’s term), because AI decouples the normal insights that come from human consciousness.
But why stop at math? All subjects are subject to the rules of the dark forest. It used to be possible to, say, go to a scientific conference to present unfinished work, or go online and get feedback on your idea for a fantasy novel. The walls of effort, of old-fashioned normal human effort, were predictable, and scooping ideas required putting in that same effort, and if you got scooped it would at least result in similar insights. And while insights or generative capacity for the rest of culture is harder to quantify and track than insight from math progress, it still exists, and examples abound (e.g., Tolkien creating the modern fantasy genre). People used to say: “We’re a start-up in stealth.” Now all thinking must be in stealth.
And yes, obviously, this outcome is vampiric and enervating and sad, but frankly, this has been the mode of this technology from the beginning. Human culture always led naturally to more human culture—it was kind of like crop rotation, which is slow but infinitely sustainable. AI looks more like slash-and-burn agriculture, where you purposefully reduce the existing natural growth to ashes, grow a couple years of crops on it, and then move on to the next plot. The only way to counteract the situation is for all of us to become what Liu Cixin called “wallfacers” in The Three-Body Problem—if you are working on something interesting, then wallfacing is necessary. You must face the wall, and so leak nothing, give away nothing.
It’s hard to notice social commons until they are gone, but remember how delightful it was to be able to talk about an intellectual work-in-progress in public? Or just float a good idea to get opinions about it first? Remember that? Go ahead, violate the dark forest. Take that brilliant idea you’ve been sitting on for years, the one for an app, or a book, or a game, or a scientific paper. Take that little thought that is dear to you and post about it on social media. See what happens. See what hunters shoot.
And yes, sure, books will still be published, papers still written, new programs and applications launched. But the future of intellectual work is to be crouched behind a tree, frantically trying to complete your contribution as silently as possible. You’ll feel the pressure of being hunted, since all it takes is a prompt to produce an almost-as-good version of what you’re attempting to make great, and so to mine away the inspiration and insight and reward. Quite often, staggering successes are erected in the forest, but they are never done collaboratively or in the open. You’ll never see anything being built anymore. Instead you’ll find the results at dawn, a gleaming sculpture in a glade, of unclear origin, and with features brutally beautiful. And then once the sparkle fades everyone will rush back to their respective trees, to their fumbling amid the loam, to their slick-wet roots, to their dark.
How big of a deal is the Three-Body Problem in China? Consider that the rights involved a literal murder, of precisely the kind that would happen in The Three-Body Problem. Apparently, a billionaire Mr. Lin was determined to oversee the intellectual property into television and other media.
Mr. Lin’s fate would change when he hired Mr. Xu, a lawyer, in 2017 to head a subsidiary of Yoozoo called The Three-Body Universe that held the rights to Mr. Liu’s novels. But not long afterward, Mr. Xu was demoted and his pay was cut, apparently because of poor performance.
Disgruntled, Mr. Xu, the lawyer, then began experimenting on dogs and cats to develop poisons in a secret lab, which he then used to poison and murder Mr. Lin.
I didn’t know this, but a few years ago there was a trend to say that AI would make the internet a dark forest because users would retreat into walled gardens (one of the better essays arguing against it uses the Uccello painting as a lead image). It’s an interesting piece of internet lore to check out, but personally, that overarching metaphor doesn’t make much sense to me. You’re supposed to feel sniped in a dark forest, not annoyed by slop.
Regarding the “team of humans” situation: It should be said that the head of this effort at OpenAI has tried to thread the needle, and admitted on social media there was indeed a human team, but also basically said that the team of world-class mathematicians lacked previous experience on Navier-Stokes and so therefore couldn’t “meaningfully contribute to the mathematical content.” But what content? Didn’t contribute to the solution as written in the paper? Or to the process? Two very different things. But the fact that we don’t know anything beyond vague pronouncements, and probably won’t ever, is a travesty.
2026-08-21 22:15:28
2.8%—that’s the mortgage rate I just gave up. As a millennial, it was letting go of some lost artifact from the Before Times, traded in for a 6% mortgage rate right outside Boston.
After a several-month-long feat of Napoleonic logistics, I still live in a mausoleum of boxes. At least it’s bought me some perspective.
I’ve spent the last six years out on Cape Cod, away from the world, because in spring of 2020, a time of coming plague, I had the instinct to get out of the city and seek water. A rushed house purchase then (unknowingly, luckily) ended up being the best financial decision of my life.
I can look back on my previous years on the Cape with the recognition that I’ve been in a kind of self-imposed exile. I see in the windswept sea days the initial seeds of a couple very good scientific ideas I’m now pursuing and a lot of daily writing. But with the inevitable benefit of hindsight, what I did most over the last several years was just be a dad.
So I spent a lot of time driving around to random beaches and changing diapers and wiping little sandy hands down. We went on many walks in the woods. I read aloud many books in bed at night.
The interregnum is over, and I’ve rejoined the world, and the Great Hoel Household Move of 2026—which occurred through sickness and pregnancy and endless difficulties—is finally done. Finishing it has unlocked something inside me. It’s like when you find a little dam in a stream in the woods, and after nudging over a rock or a branch with your shoe the whole thing goes from a trickle to actually flowing, as naturally as it was always supposed to. All to say, I’ve been writing more again.

The philosopher Alain de Botton said, in a recent interview:
Home-making is essentially the process of translating what is in you into the language of objects, placings, colors, etc. We’re really looking for an analogy between somebody and their home. The home is a sort of work of autobiography.
Yet we have so little opportunity to express ourselves home-wise. You have to go on the market and hope you can get something that fits you, that feels like you, or that you could make feel like you.
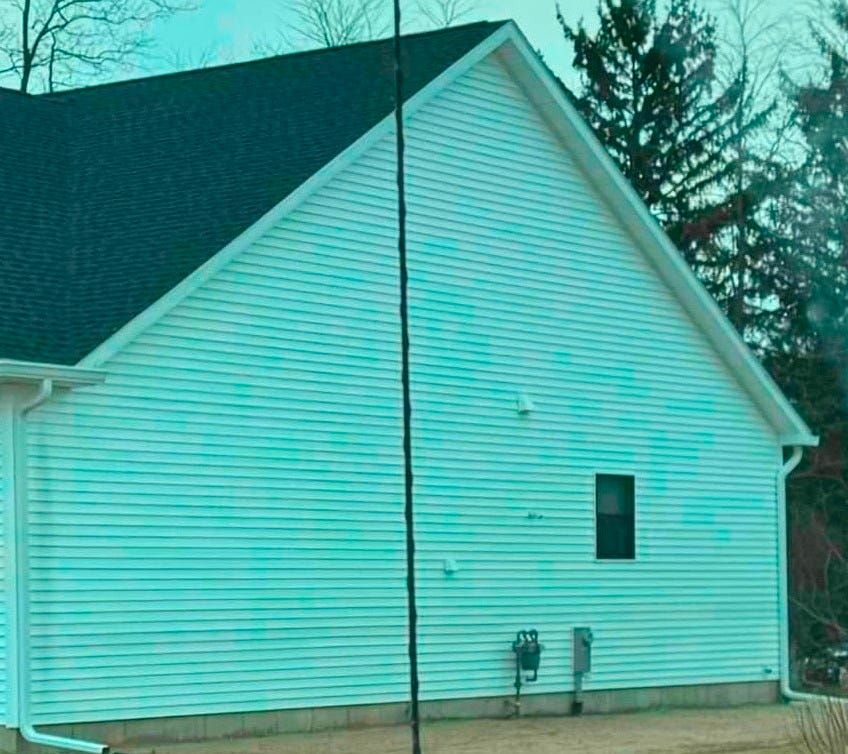
The mass-production of homes is a necessity, and a controversy—YIMBYs and NIMBYs fight in phalanxes across the great housing debate—but one factor lurking above it all is that the blank-faced developer home of today is a thing with no style. It is made to fit ordinances and to navigate through red tape. I get some people like it. It’s clean. All the light switches will work. All the appliances are also… clean. It probably won’t catch on fire overnight. It also sort of sucks at my soul as I drive past like one of those dementors in Harry Potter.
Why can’t we build more beautiful homes? It’s not just money—expensive homes that cost into the millions still often have ugly garage-centric designs where the kitchen window literally faces a wall.
Every so often the braintrust on social media complains loudly that the 20th-century architectural movements ruined current aesthetics, and have made the world less beautiful than it was. We must RETURN to the old ways.
The usual suspects to blame are minimalism and modernism: we all had art deco skyscrapers and classic colonials until those dastardly aesthetic movements pulled a fast one on us! Yet the second you look at actual specifics in something that matters, like homes, the easy narrative falls apart. Here is perhaps the most iconic minimalist house: the Farnsworth House, finished in 1951.
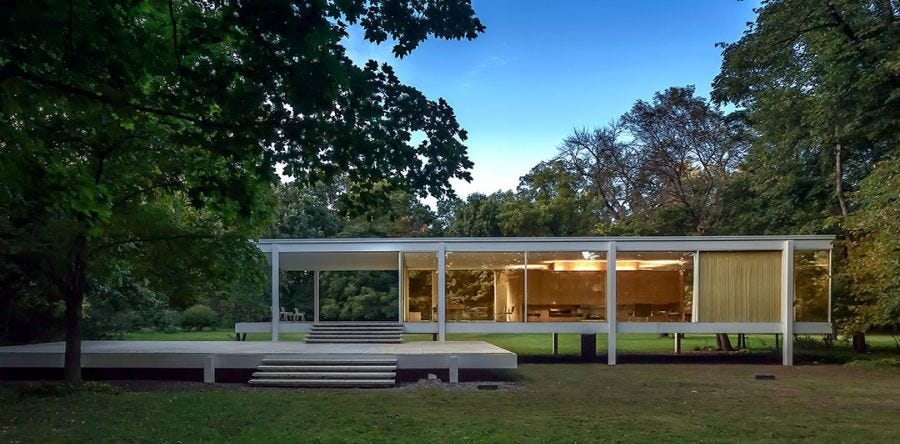
Does that look like the personality-less “millennial gray” or “millennial blue” developer home with tiny windows going in down the street? Is this really the style that “took over” our culture and ruined homes and buildings? Is everything like this now?
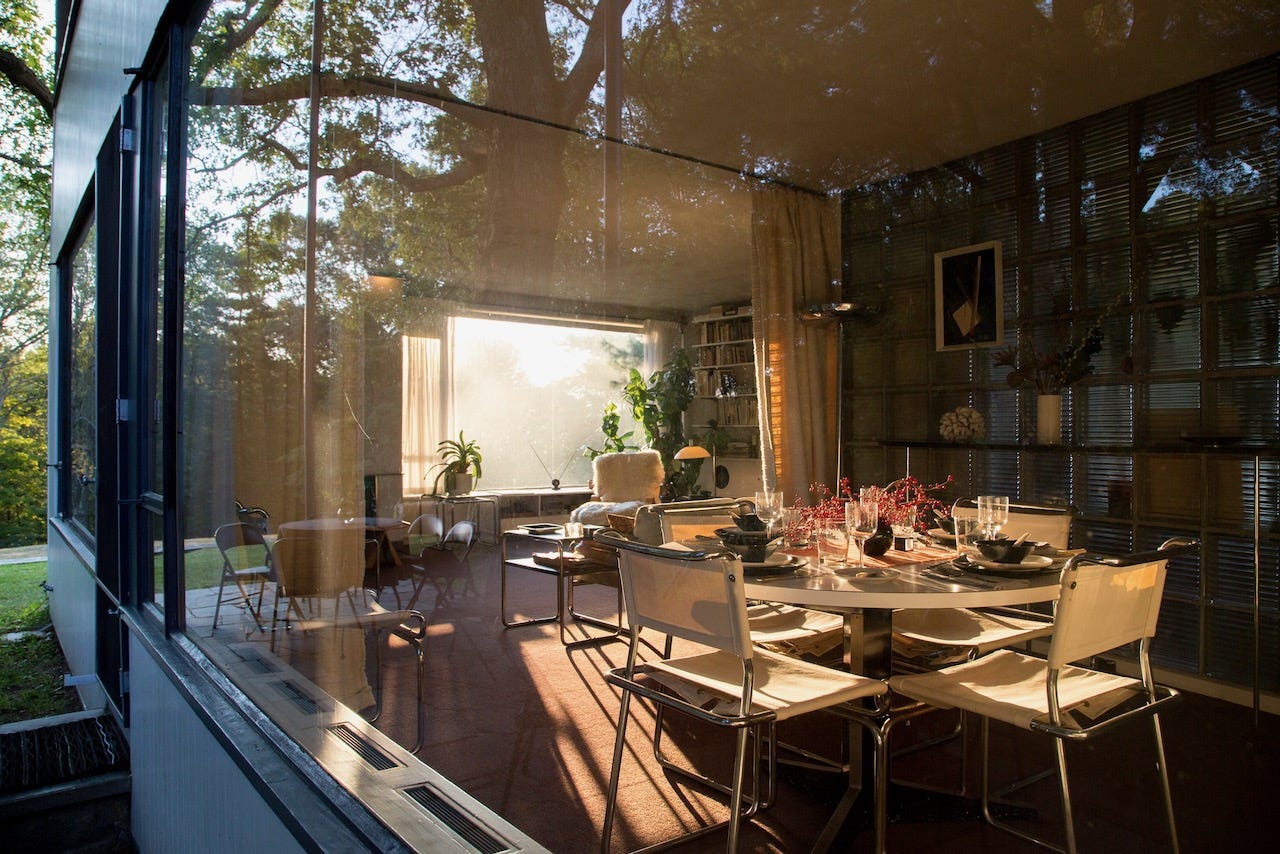
Here is a look inside the cozy personal home of Walter Gropius (founder of the much maligned Bauhaus) which sits in Lincoln, Massachusetts, built when he taught at Harvard. Are they making these everywhere now? Are we surrounded by the horror of enormous floor-to-ceiling glass windows, letting the outside into the living room?
Or, in the real world, do developer homes now have windows that look like this?