


2026-10-20 20:04:23
“Before fire existed, it’s hard to imagine all the implications of fire. I think the same thing will very much be true with the level of robotics that will be possible. It’s just hard to even think of all the possibilities.” – Pete Florence, Co-Founder & CEO of Generalist
Pete Florence and I began by agreeing that his company has an excellent name. Generalist builds AI for robots, including models that can begin learning a new task from a single demonstration. We talked about dexterity, the strange business of gathering physical experience for a machine, and what we might build if robots could do much more of the work.
Listen or watch on YouTube, Spotify, or Apple Podcasts.
We’re trying a new thing where I share a few of my thoughts from after the episodes. The moments that struck me, the tidbits that reframed my thinking, or something I just really enjoyed. Let me know if you like reading these!
Dexterity, dexterity, dexterity. Before the conversation, I was trying to think about what robotics’ equivalent of coding would be. I found myself looking for a big industry or use case – something in manufacturing or construction. Pete’s answer is dexterity. Like coding, it’s a horizontal capability that runs across fields and opens up a huge range of work. It’s the kind of simple, sharp description that made me realize I’d been thinking too narrowly.
Robots that build robots. There’s an implication of dexterity that I hadn’t properly thought through, but is obvious in hindsight. Once robots are truly dexterous, they will become capable enough to replicate themselves and successive generations. Your ability to manufacture starts to scale with the machines themselves.
GPT-3 feels roughly right. This is the comparison Anthropic researcher Sholto Douglas made when Generalist’s latest model launched. That feels apt. ChatGPT ran on GPT-3.5, and OpenAI had already trained GPT-4 by then. What Generalist is doing is remarkable, but we’re still short of that astonishing moment when everything clicks.
What might we build? I liked Pete’s framing of robotics opening up entirely new human projects. There are plenty of dangerous and unpleasant jobs we machines will take take over. But if the cost of physical labor falls dramatically, what kinds of strange, miraculous buildings, cities, and infrastructure become possible? What would we attempt that we currently dismiss as absurd?
Sometimes the fastest way is a plane. The lengths Pete has gone to get robotic data are extraordinary. He described packing hard drives into a backpack and getting on a plane because poor internet connectivity at the collection site meant flying would be faster. The team has also built custom servers and software to upload data from large numbers of memory cards at once. I loved getting a more visceral sense of the physical work that goes into this part of the process.
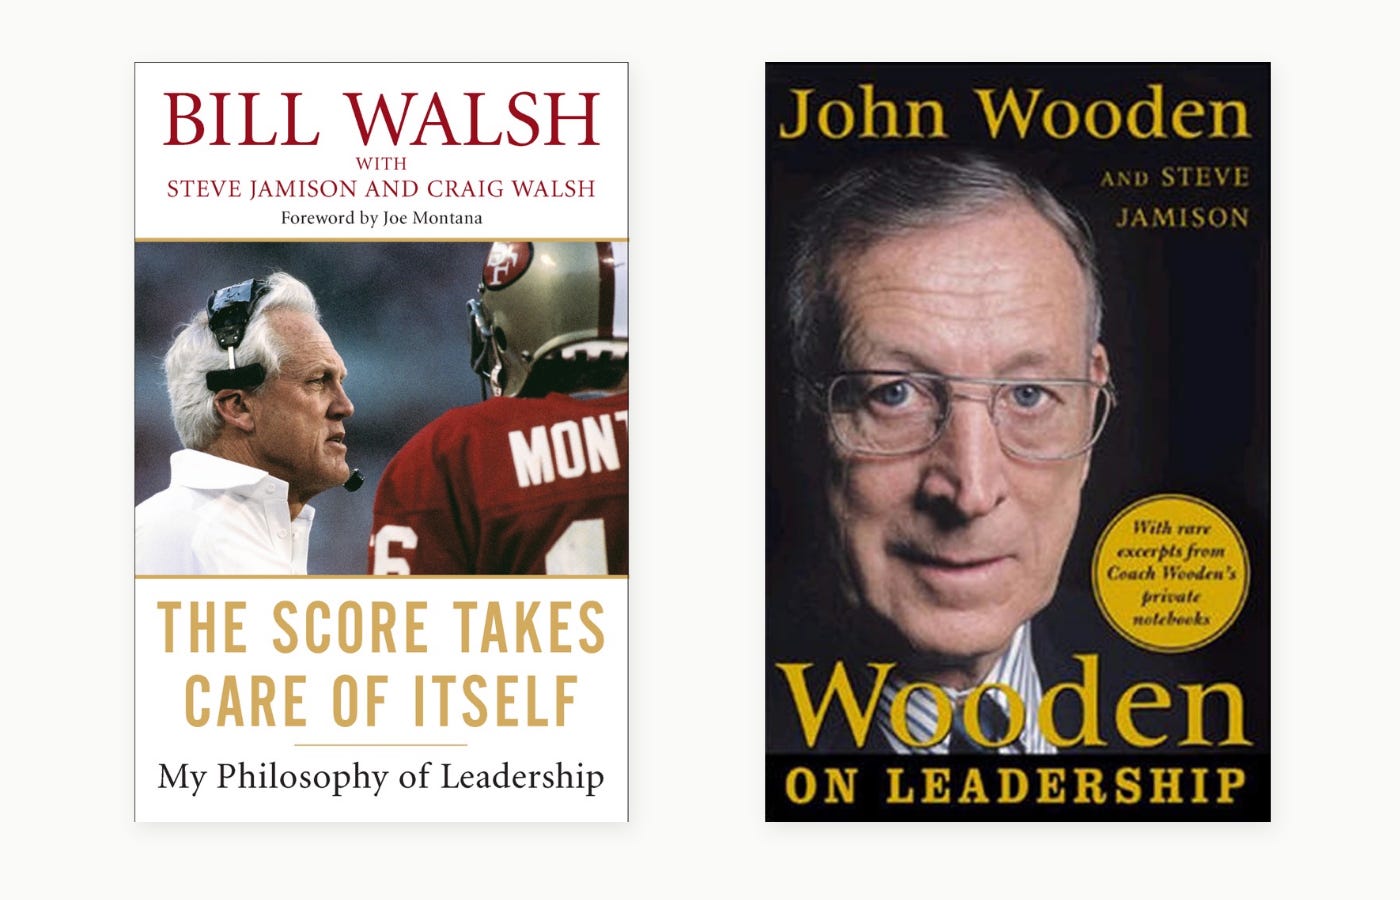
When I asked Pete to recommend a book, he turned to two coaches: Bill Walsh of the San Francisco 49ers and John Wooden of UCLA. Walsh’s book is The Score Takes Care of Itself, a classic Wooden tome is On Leadership. Pete’s answer brought us back to teaching and coaching, both of which have been big parts of his life.
What I’m reading, watching, and into this week:
Training a small model to autocorrect my text messages more accurately. So far…the gains are modest :)
Empire of Pain by Patrick Radden Keefe. I don’t usually read non-fiction in my spare time, but I’ve “enjoyed” (a strange word for so bleak a story) this excellent reporting of the Sackler family and the opioid epidemic.
Playing with the models’ 3D capabilities to spin up an Italo Calvino-themed personal website (in progress).
—Mario
00:00 Intro
02:24 GEN-1.5 and one-shot learning
08:55 What makes a task difficult
10:53 Dexterity in robotics
14:53 Matt Mason’s definition of a hand
17:34 Giving robots a sense of touch
20:30 Growing up in a family of technologists and scientists
22:46 What drew Pete into robotics
27:38 Generalist’s founding thesis and what sets it apart
32:17 Protecting simplicity
35:01 How Generalist’s data collection has evolved
35:30 Generalist’s scaling philosophy
39:53 Generalist’s build-versus-buy philosophy
42:15 Balancing general intelligence with commercial deployment
44:24 Why Pete is betting on dexterity
47:33 The durability of the robotics application layer
49:09 Open-weight robotics models and data flywheels
50:52 Geopolitics, safety, and alignment
52:42 The parallels between teaching humans and robots
1:00:05 The timeline for robotics progress and adoption
1:03:37 Book recommendations
Listen or watch on YouTube • Spotify • Apple Podcasts
The Score Takes Care of Itself: My Philosophy of Leadership: https://www.amazon.com/Score-Takes-Care-Itself-Philosophy/dp/1591843472
Wooden on Leadership: How to Create a Winning Organization: https://www.amazon.com/Wooden-Leadership-Create-Winning-Organization/dp/0071453393
Generalist: https://generalistai.com
Proprioception: https://en.wikipedia.org/wiki/Proprioception
Cutaneous receptor: https://en.wikipedia.org/wiki/Cutaneous_receptor
Fukushima nuclear accident: https://en.wikipedia.org/wiki/Fukushima_nuclear_accident
The bitter lesson: https://www.cs.utexas.edu/~eunsol/courses/data/bitter_lesson.pdf
LinkedIn: https://www.linkedin.com/in/peteflorence
Website: https://www.peteflorence.com
I’d love it if you’d subscribe and share the show. Your support makes all the difference as we try to bring more curious minds into the conversation.
Production and marketing by penname.co. For inquiries about sponsoring the podcast, email [email protected].
Pete Florence: 2011 Fukushima nuclear disaster.
News clip: The Fukushima number one nuclear power plant has been hit by its biggest earthquakes. Simply heartbreaking.
Pete Florence: There wasn’t a robot in the world that could walk into the nuclear facility after the meltdown and just turn a valve, and so we had to send people in for that. If you’re not touching and moving the world and you’re a robot, what are you doing? Any process in the world that is gated by physical progress, building houses, whatever it is, we could just do that way faster, way better.
Gen 1.5, it has a couple different capabilities where you can learn a physical task in just a single demonstration. The success rates of all these are modest today, but the fact that these success rates are anything above zero is the incredible thing.
Mario Gabriele: Sholto Douglas, well-known Anthropic researcher, called this sort of a GPT-3 moment for robotics.
Pete Florence: The example that we highlighted is using a brush to sweep an object into a bowl, and then instead you take the brush away and you give it a dustpan.
Mario Gabriele: One of the stories of these past few years has been finding sort of the killer use case in coding. When it comes to physical intelligence, do you have an intuition of what, like, that killer use case might be?
Pete Florence: I think the best analogy would be dexterity. If we can really crack dexterity, then the robots can build the robots and the robots can start building next-generation robots.
Mario Gabriele: Robots don’t learn the same way that people do. Teaching a robot a new task can take months of programming, data collection, and retraining. Generalist, an AI company for robotics, is compressing that process down to seconds. In one of its recent demonstrations, a robot was shown just one time how to take money out of a wallet.
It then completed that task immediately without needing to be retrained. Today’s guest, Pete Florence, is Generalist’s co-founder and CEO. The company is building what it calls general intelligence for the physical world: AI models meant to work across different types of robots, from factory arms to humanoids.
Since its founding a little over two years ago, Generalist has grown into a key player in the robotics race. In this episode, Pete and I discuss one-shot learning, why dexterity remains so hard, where physical AI follows the same scaling laws as digital AI, and which industries change first when robots learn new skills much faster.
I’m Mario, and this is The Generalist.
Well, I think the only place to start is that I think you have the best name possible.
Pete Florence: Likewise, Mario. Yeah.
Mario Gabriele: Very good taste. Well, I’m really looking forward to this conversation and getting into what you’re doing at Generalist. It feels like a particularly exciting time. Earlier this month, I think it was mid-August—you released Gen 1.5, which is your latest foundation model, and it seemed to attract a lot of excitement.
Uh, you know, I saw Sholto Douglas, a well-known Anthropic researcher, call this sort of a GPT-3 moment for robotics. Maybe you can tell us a little bit about what Gen 1.5 is and, and why it matters.
Pete Florence: Sure. Um, so Gen 1.5 is, is definitely in a few different ways, like a type of model that we had been kind of waiting for, for a while, at least in terms of glimpses of types of capabilities that both are just exciting in and of themselves, and then also point towards like what might be a future of, of what’s coming next.
Right. So overall Gen 1.5, it has a couple of different capabilities in what we call one-shot or a few-shot learning. Um, and also some other things in what we think are really remarkable levels of zero-shot physical generalization. These like one-shot and few-shot, broad types of learning capabilities where you can learn a physical task in just a single demonstration.
And mind you, just to be clear, like the success rates of all these are modest today, but the fact that the success rates are anything above zero, yes, is, is the incredible thing. And, you know, if I, if I dial back like a few years, one of my co-founders, Andy Zhang and myself, like we’ve, we’ve been talking for a while about this threshold of crossing into, um, a very generalized one-shot and few-shot learning capability in robotics.
And of course, like the rise of large language models around 2020—yes, of course, GPT-3—like that was the kind of the main thing that or at least arguably the main thing that, that people were especially excited about with the model GPT-3 was this broad one-shot and few-shot learning capability. They coined the term in-context learning in that paper.
It’s, it’s been an incredible thing to see.
Mario Gabriele: And so one-shot and few-shot learning is sort of a necessary principle to have that sort of like generalizable intelligence in the same way that GPT-3 had, where you’re able to say, hey, you know, make me a poem in the style of, you know, Emily Dickinson. And after a few tries, if you give it an example, it can do that.
You’re sort of seeing that similar style of behavior in the physical world. Is that sort of the parallel?
Pete Florence: Yeah. So, you know, specifically one, one-shot is where you, you give a single example of an input and an output. So you could say, like, “Who wrote Romeo and Juliet?” Answer: “William Shakespeare.” And that’s a, that’s like a question-answer, an input and output.
And then you give another input and you let the model do the output. So you give it a single example and then the model, then it knows what to do from that single example. That would be like one-shot. You can also do zero-shot, which is you just, like, say, you know, “Who wrote Romeo and Juliet?” and you don’t give any, you know, example of a full input-output.
Mario Gabriele: Yes.
Pete Florence: Um, and it was actually, if you trace back the history, it was actually GPT-2 started to show a little bit of these types of capabilities, but it was really GPT-3 that like brought broad one-shot, few-shot learning into the, like, “Wow.” Basically, a very wide variety of tasks—you could just give it a go.
You could just ask the GPT-3 model for those that remember, just like trying to prompt it with a few different examples, and it had a reasonable shot at doing something intelligent. And that’s like the level that we feel like we’re now seeing where the success rates are not super high. Um, there are limitations on the types of tasks that we can just prompt the model to do, but a very wide variety of tasks, you can just try to prompt it and see what happens.
And there’s a reasonable shot that something, something intelligent occurs. And again, this like the fact that this happens at all is the incredible thing to us.
Mario Gabriele: And the, you know, the tasks are things like take these bills out of a wallet or, you know, sort these, these cups, which it’s amazing to watch these things play out.
Did you expect to see this capability as part of this model? Like, where are things tracking versus how you were sort of imagining they might?
Pete Florence: It was surprising to us that this model started to show this particular type of one-shot visual capability, um, in part. And it’s something that we talk about a lot in, in what we released, um, describing some of the, you know, development behind the model, but it was not trained to do like one-shot or few-shot examples.
And that is actually the same way that, um, at least as far as we know, as it is described in the GPT-3 paper that happened as well, where you actually just train the model, in the case of GPT-3, on every single possible piece of text that OpenAI could find at the time. And it’s later been studied and given a name that it’s kind of, you know, the way that the data is just laid out. It has this property which is called burstiness, which is that when you see a single SAT question example, just, just to give an example here, like, um, it’s pretty likely that your next, the next thing that the model sees is another SAT question.
So like when you start to load the context of the model with similar types of things, it—oh, it’s pretty likely that the data distribution it was trained on has a similar type of thing occurring after it. That’s like kind of one of the ways that we can kind of try to hypothesize how this capability showed up in the model GPT-3.
And similarly, like we never trained Gen 1.5 with like an example of a task and do it again. But the model just, you know, the physical world also has burstiness where if people are like taking bills out of a wallet, it’s pretty likely they’ll take another bill out of a wallet, right? Like it’s literally just, just, um, guessing what is most, yeah, most likely to happen next or what it should do next.
Yeah. Based on a little bit of prompting in its context, it’s been surprising for us to see this model start to have that. I would have thought it would have taken maybe a little bit more time. Um, but at the same time, I, I do think it was inevitable at some point, maybe through different means to start to have this capability.
Mario Gabriele: Do you have a sense of why it’s more successful at some of these tasks than others? Like, it seemed like I think the wallet, you know, example is actually it’s one of its best tasks, right? Versus, you know, things that to a human look sort of equivalently difficult. Is that just a data availability question?
Is it something else happening?
Pete Florence: That’s—it’s a great question. And the honest answer is it’s, it’s really hard to trace exactly why. We can sort of build up some intuition from a lot of the empirical experimentation. You know, in the pre-training distribution, you know, a lot of these tasks, there’s no way that, like every single task that you can think of is actually in your pre-training data.
Like, definitely. Um, there are tasks that we can do that there was no pre-training data for this. And one of the easiest ways that we know this is we can just 3D print objects that we’re pretty sure have never existed before. We can demonstrate a task with it, and they can do it right. But there are certain sort of underlying skills or behaviors that together comprise a task.
And if you have more data supporting those tasks, and that’s maybe one that would have higher success rates. But it’s not only—it’s not only about how much data is there. It’s not very simple to describe what makes a task challenging in robotics, especially for a dexterity or dexterous manipulation, but I think there’s a few different kind of component features that add up to make things challenging.
Like one is how precise from a motion precision standpoint does a task have to be? How precise from a force precision standpoint? So how hard do you have to push on something, or how not hard you have to push on something? How coordinated do all of your degrees of freedom have to be? So like a task that really requires a lot of bimanual, precise coordination between the two different hands.
That’s very challenging. Um, those are a few. But there are other aspects as well where it’s actually a—it’s a very rich space that we can try to kind of make sense of, about what makes the task challenging in the physical world. Those all contribute here. Yeah.
Mario Gabriele: It’s—robotics is so interesting. You know this, you know, a thousand times better than I do.
But I find myself getting so excited about some of the stuff that you’re doing because it touches on like what we think of—touches on biomechanics, it touches on like philosophy. You get into these evolutionary questions like when I was starting to do some reading about, you know, the evolutionary development of our own hands, it seems like it’s extremely—it traced extremely closely with the development of our cerebral intelligence as well as our manual intelligence, like those two things just, you know, came together in a really interesting way.
You’ve mentioned before that dexterity is something that’s sort of like this, I don’t know, holy grail or big topic in robotics for a long time. More specifically, why is that something that seems to be just so important to get right? Is it just about the precision? Is it about those different factors that you sort of just mentioned?
Pete Florence: So one for, for sure. You know, it’s something that honestly, both like me personally and the company has drawn a lot of inspiration from is exactly what you mentioned, which is that if you study evolutionary biology, um, you know, of course there’s evidence to suggest these things, but we can never know for sure.
But, but it does seem that—and there’s this, there’s this term for this, like area of the brain. My brother’s a neuroscientist. It’s the Broca’s area or something like that.
Mario Gabriele: Which is language.
Pete Florence: Maybe it was believed to. There’s, you know, all these different regions of the brain can be associated with many different things.
But there is some evidence that I have read in published research which suggests that, like the development of dexterity, um, and the evolutionary adaptiveness of like having better and better toolmaking skills then helped create the evolutionary pressure to have the right type of scaffolding in the brain, or even could have been the thing that helped just grow the brain in general.
Yeah, that’s me extrapolating a bit from what I’ve read from scientific research, but there’s just the general connection between humans becoming tool builders and the drive to master more and more dexterity, and some suggestion that, that might have helped open up the brain for other types of cognition, like, like language and all these other things as well.
The reality is that, of course, in, in a, in AI, like all these connections are, are sometimes nominal at best, but are also like genuine sources of inspiration. Right. Like the way that we have created AI today. Um, you know, digital neurons are not the exact same, of course, as neurons in our brain. But, but there is there’s a there’s a definite inspiration that has led to, you know, genuine, a significant advancement.
So anyway, I think that, that’s just fascinating. But then over in the case of more just like grounded in what has been the state of robotics like over the past several decades leading up into now, and why, why dexterity is such a thing that stands out in general, I would say, and just the state of the state has been that very generalized dexterity, aka not just being able to pick up something that you have a predefined model of, and you’re doing it over and over again.
But being able to touch and move the world and manipulate it a.k.a. Like move it into any type of configuration, that, that is the goal for the robot. That has been an incredibly challenging thing. And just the, the empirical, uh, state of research has been that it has been the hardest thing to master across a very wide range of tasks, whereas other things like, you know, in an amazing way, it wasn’t the case a couple of decades ago.
Like walking robots work pretty well, at least on like pretty flat ground. And there are edge cases that, you know, general cases of what is called loco-manipulation or parkour type things are challenging, but walking around on flat ground has become a pretty well-developed capability. Meanwhile, putting a robot in front of a bunch of different objects and getting it to do anything with them, especially for challenging different types of objects, challenging different types of tasks.
That has been—that has been a very elusive thing.
Mario Gabriele: I always like to ask a few people close to the interview subject what I should ask you, and one thing that someone suggested was, “You should ask him. You should ask Pete how he would describe a hand. What does he think a hand is, uh, fundamentally?”
Pete Florence: There’s this guy, Matt Mason, who’s, um, arguably like the godfather of robotics manipulation.
He has a nice definition, which I’ll butcher a little bit. I haven’t read this in years, but it’s somewhat in my head, which is that robotic manipulation is the process, or something like that, of selectively choosing contact with the world to put the world into some desired configuration. And the operative part here is selectively making contact.
Right. And it is actually very carefully chosen because you can do things like not touch something. And that can be your—that could be part of your goal. It’s not just making contact, but it’s also choosing to make contact or not. And there’s this very particular word that just for those that are maybe not acquainted with robotics—like, contact, you know, that’s a word that in many different contexts has many different meanings.
Yes, but contact is really everything in dexterity or what’s called manipulation in research. It’s about touching something and being able to, you know, have things that are not touching, put them so that they are now touching. And when they are now touching, you can move them around. And it just turns out that when you have to actually touch and move the world, that is where the physics is really hard to predict.
Um, it’s an incredibly rich sort of, at its core, a mathematical problem that, uh, you know, for many decades we’ve tried to, like, solve these types of things analytically. It’s very challenging. And in practice, the thing that has made the most progress, just like in language—and, you know, at this point, it’s, it’s, it’s just such a well-known story—but just having models that are trained on a massive variety of data and, very carefully, the training recipes are, you know, refined through tons of experimentation.
That’s been the thing that has given us the most progress. So, sorry, back to hand. Did you ask me about this?
Mario Gabriele: This is exactly the sort of rabbit hole I wanted to go down, so that’s great.
Pete Florence: I think a hand you could say is anything that helps you selectively make contact or not is what I would say is the definition.
So, you know, that’s pretty broad.
Mario Gabriele: Yeah. Yeah. You can imagine the evolutionary pressures of our—of the hands of the future could be—could look very different.
Pete Florence: Yeah. And even, like, you know, things like feet, we can consider hands. Yeah, yeah. And of course we can use our feet as hands.
Mario Gabriele: How do you think about giving robots a real sense of touch?
Like, is that pressure? Is it temperature? Like, what are the right ways to gather that kind of data? And what does it miss at the moment versus real human touch?
Pete Florence: Human touch is incredible. Um, I haven’t studied human touch, um, that much, but of course, I have an intuitive sense of human touch. Um, and I think in robotics, touch is certainly important.
A simple exercise on how much the like touch is limiting us is you can teleoperate a robot and you can have no touch feedback, and you’ll realize that, like, you pretty quickly could teleop a robot with no touch feedback at a very like super-AI level, not like superhuman level. Because you are, you can do it much better than, than our best AI models can today.
Mario Gabriele: Yes.
Pete Florence: And what that shows you is that like, yes, there are certain cases where touch would, would really help us a lot more. But at the same time, human brains still are quite incredible compared to even our best models, even Gen 1.5, etc., at generalized dexterous manipulation. That said, I strongly believe touch is important and will be part of like reaching the highest pinnacles of performance that we can with robots.
Then there’s actually quite a lot of different options for how robots can effectively get these types of like non-visual or non-audio types of sensation of the world. I said before, I haven’t studied human touch that much, but I know a little bit like so one is that like there’s this concept called proprioception, which is um, sometimes people would say different than touch, but it’s very relevant here in that it’s like non-visual non-audio senses of the world, and we as humans have a bit of proprioception in that.
Like we know how our arms are bent. We can close our eyes and we know how our arms are bent. Yes. And that one is, is pretty easy for robots to get. Basically every robot gets—gets that for free.
Mario Gabriele: Yeah, that’s called encoders.
Pete Florence: You know, you know your joint angles. Another type of proprioception is knowing how hard something is, like pushing on the muscle at your joint.
And that one a lot of robots now also have either through what’s called current sensing or torque sensing at the joints, but that one is also like in most robots already today. And those two alone, I think, provide a lot of what you might think of as touch sensing. But then there are other things where I believe the term is called a cutaneous touch, or like the ability to like, you have your fingertip and you can like scratch it and you’re not feeling it like down in the rest of your arm, but you can feel it right there.
That is the one where there’s starting to be more and more sensors there. I don’t think, um, it’s not at least a widely deployed thing to have lots of those sensors all over robots today. I think over time we might see more of those. And yeah, I think that there’s a lot of cases where those types of sensors will be useful.
Mario Gabriele: You grew up in the Bay Area. Uh, were your parents in tech? Did you have models of entrepreneurship sort of around you all the time, or was that not sort of the version of your, your upbringing?
Pete Florence: Both my parents worked in, uh, technology at different points. My mom’s side of the family has been in the Bay Area for a very long time.
So I think this is actually like, um, you know, living in San Francisco, a lot of people come and go. I love San Francisco, but the reality is, a lot of people that you meet in tech, you know, uh, maybe moved here, uh, this generation or last generation. For my mom’s side of the family, it traces back to, like, I’m a sixth-generation Bay Area.
Mario Gabriele: Oh, wow.
Pete Florence: And it was my, uh, triple-great-grandfather, moved from Lafayette, Indiana, settled in the Bay Area up in Petaluma. That’s my mom’s side of the family. My dad’s side of the family—uh, my dad moved up from LA. Um, but, yeah, my, my mom worked in, uh, in tech, uh, and then my, my dad worked with a bunch of different startups, and my grandfather was the—was the scientist.
He was a chemist at, you know, back in the middle of the 20th century, one, uh, frontier area of technology was, uh, rubber. And, uh, yeah, he was, he was a chemist, and he worked at a—at a rubber factory.
Mario Gabriele: And was he sort of—I know you studied chemistry. Was he a bit of an inspiration in picking your sort of first paths?
Pete Florence: Uh, I did study chemistry. That’s what I did in, in college. 100%. Yeah. I think my grandfather helped inspire that.
Mario Gabriele: Were you the sort of kid that was, you know, programming, uh, you know, in your early days or, you know, building, building things in that sense or did that come, you know, a little bit later?
Pete Florence: There was always building stuff. Uh, I was actually just talking with my wife about this the other day that, like, she was talking to my brother, and we were just talking about, like, Pete as a 12- or 13-year-old and, uh, modifying Nerf guns to make them like, uh, you know, more powerful. Uh, we actually me and my one of my best friends, uh, we had a, a website we called a modification directory for modifying Nerf guns.
Mario Gabriele: Oh, I love it.
Pete Florence: The same thing with Super Soakers. Those were like the types of things that I would, would, would do at that age. Um, and then yeah, programming. And in college I did, you know, enough to sort of like support, like, uh, scientific research that I was doing in chemistry or in physics. Um, but then graduate school was really when I, like, became a more full-blooded software engineer and everything else and that you need to know to, you know, do AI and robotics.
Mario Gabriele: When did robotics sort of enter the picture for you? When did you start to think, you know, this was, you know, as, as rubber and chemistry was to your grandfather—maybe the most exciting challenge technically of, of our generation?
Pete Florence: So I had done undergraduate in chemistry and I did a one-year master’s in physics.
Um, and everything I was working on was, was a fascinating field to be in. You know, before you choose to do your PhD, there is this opportunity to, to just think about like what really would be a field of research to like really dedicate a, you know, huge amount of years and potentially a lifetime to. There was a couple things that just felt like, you know, this was 2014, that robotics might have just a massive impact on the future.
Um, there was a little bit of a direct sort of connection in what I had been working on before, which is that I was in the lab doing physics research, and I would, um, come into the lab and I would just think about, like, what is the thing I can do today that would most advance my research? And science requires a lot of different type of thinking.
But I do think that, like, if I just thought about the hours of the day and what I could do the most to advance my work, it was—a lot of it was just like doing all of the manual labor to push through a bunch more experiments. And that, like, as simple as it is, like, iteration speed both in robotics and in AI, but also the rest of science as empirically driven science, which is a very massive fraction of all science.
It felt like being able to rapidly accelerate that, uh, like we didn’t have the machines to do that. And of course, there’s been a long history of scientific automation for things like in physics and different types of experiments, but there have always been very sort of narrow regimes in which those types of instruments have worked. And a very broad capability to, like, have a robot just run all of your experiments—that, that, that was something that felt very far off at that time, but felt like it could happen in my lifetime.
Um, and that was one, you know, yeah, very direct reason why I thought it might be very exciting to, to start to work in robotics.
Mario Gabriele: I love that, that’s the call to adventure for you, because I feel like often the call to adventure for a robotics person is, hey, you know, there’s these, these set of jobs that are dangerous or sort of drudgery that would be great if humans didn’t have to do it. And that’s—I suppose this was, you know, a form of drudgery. But it’s a very high-minded version of that where you’re like, imagine if we had thousands of robots conducting scientific research, uh, at, at this massive scale. It’s a really interesting vision.
Pete Florence: I think, too, like, for me, there’s, there’s like a few levels here.
So one is, yes, like the drudgery things and actually like, you know, even people talk about this less today. But like when I was starting graduate school in robotics like the example that everybody gave of the obvious thing that of course we want a robot to do instead of people to do was the 2011, uh, Fukushima nuclear disaster.
Mario Gabriele: Yes.
Pete Florence: Right. And the story that, that, you know, I would always hear and I just think, yes, it’s something everybody is just like, yes, that makes sense, is that there wasn’t a robot in the world that could walk into, like, the nuclear facility after the meltdown and just turn a valve. And so we had to send people in for that.
So that’s like, okay, that’s certainly something where—
Mario Gabriele: Everyone’s on board.
Pete Florence: We should have robots do that instead of people. Um, and then I was just talking about the science example. You know, for me at least, it’s a very inspiring example that like, yes, we could have things that we already know today, but we could just do them way faster or like the same type of thing already exists, but it could be way better.
Or we could make things—we just, you know, iterate way faster on how we build and design things. We—yes, we could run way more science experiments. Any process in the world that is like basically gated by physical progress, building houses, whatever it is. Yeah, we could just do that way faster, way better.
That is one way. But then there is also this third layer of just like things that we just can’t even imagine really today that will be possible when, you know, we can actually like build the structures that might take like thousands of people, but then now we can just have a whole bunch of robots do it. It would have been very hard to foresee all of the implications of the internet when the personal computer was coming around or like, you know, before fire.
It’s just like before fire existed. It’s hard to imagine all the implications of fire. I think the same thing will very much be true with the level of robotics that, that will be possible. It’s just hard to even think of all the possibilities.
Mario Gabriele: Yeah, there’ll be all these new, new use cases, new structures that suddenly become economically and, and sort of logistically viable in this way that, that weren’t before.
So this is sort of the moment you become increasingly excited about robotics. You know, you go to, to, to Google and spend some time there. At what point did you sort of realize this should really be its own standalone company? And I actually happen to know these two other folks that I really want to do it with.
Pete Florence: We just kind of talked through it in terms of like, why do we actually want general intelligence for the physical world? And I think like we, we just talk through, I think a few different like, you know very much for me examples of like, why is this something that I think it’s just really important to have like an absolutely incredible team behind?
And then in terms of why did—you know, why did we think we might have a shot to make it all happen? Robotics is just amazingly interdisciplinary, and the decisions that are made around like the interplay of what hardware are you using, what data are you getting? How are you training the models? How are you closing the loop between the hardware and the data and the models? How are you—what’s your plan for how you get these models to start to do something useful, and then close that loop back between the hardware and the data and the models?
And like all of that requires both, like from what is the plan, but then also from who is the team doing that? Like it just requires an incredible set of expertise. And yeah, between the few of us that, that started getting it going, and then very quickly, the founding team we got in place and everybody we’ve, we’ve hired, you know, and joined—has joined the team since. Um, I think we just have the best team in the world to, to go do this thing.
Mario Gabriele: So when you think about what Generalist is trying to do, there are obviously other companies in this space that think about, you know, this, this broad aspiration of creating, uh, you know, embodied intelligence, physical intelligence.
What do you think are the things that you’re doing particularly differently or the different bets that you’re making versus, you know, other, other players?
Pete Florence: I think that we have this very deep commitment to like the philosophy of everything behind what we build. There’s several aspects to that. But I would start with one, which is that it’s something that we’ve learned from machine learning has worked really well, which is that simplicity scales really well. A huge fraction of the decisions, not just on the machine learning side, but also on the hardware and how we do data and how everything comes together and how we think about deployments.
We want to keep everything as simple as possible and focus on like the core model training recipe and how all these things come together so that we can have the fastest possible iteration loop so we can, like, figure out how to get all these things going together. And then once we figure out the model intelligence recipe, that’s something that we know will scale horizontally across all the other different types of things that are maybe less simple to start with.
Right. So I could talk about many different ways in which that’s sort of embedded into the, the philosophy and strategy of the team. But that would be one place I would start with. Um, I think also too. Right. Like one thing that you’ve seen with the way that the best labs in the world that do like large language models and other types of, you know, primarily focus in the digital world intelligence.
The approaches come and go a little bit.
Mario Gabriele: Approaches like the different strategies that work at a given moment in time.
Pete Florence: The different technical approaches.
Mario Gabriele: I see.
Pete Florence: To a certain extent, technical approaches will come and go over, over the course of years. But in setting up a team which for a very long period of time will sustain, like all of the innovations required, because like, quite frankly, like what we have today is amazing.
But to really achieve like the real goal of like have this very general intelligence for the physical world, which, yes, can power all these robots to do all these different things, there’s going to be a very significant amount of advancement that will happen. And I think that setting up the team and the culture, to have all the right emphasis on all the right pieces, I think that’s something that, that we think a ton about. And we try to be very not precious about, like any of the choices that we’ve made so far today. We try and always just see what works the best and be constantly both willing to and even excited to completely change our mind about what we think is, is the right way to be, to be focusing our time and efforts.
Mario Gabriele: This, you know, idea of, of simplicity and you know that, that tight iteration loop and having the right culture around it, achieving simplicity is, is so hard, right? I imagine there are so many temptations to convert the problem in one way, or to pursue something—like, when you talk about that as being sort of core to the company, what does that involve?
What do you have to do to sort of like protect that simplicity and protect that, that culture built around it?
Pete Florence: People who really like to get things to work has just like continued to attract all of the amazing people that come and join the company. Again, it just kind of self-replicates. So we don’t have to like, consciously think about this part too much.
But it is really important to us. It’s just that being really focused on what are the goals that we’re actually trying to do. And if we’re very focused on the goals and we’re less precious about the methods that get us there, that’s one thing that really helps conjure simplicity. And again, it comes from multiple different sort of expertise and disciplines that come together.
Right. It’s, it’s yes, it’s on the machine learning side. Right. So just to call it out. Right. There were so many other different possible ideas of how the level of artificial intelligence that we just take for granted today could come into existence. “The Bitter Lesson,” as, as the essay has well canonicalized, is there are some levers that matter in an outsized way relative to others.
And it’s simply stated, you know, things like compute, things like data, it’s simply stated. Having an incredibly talented team focus on just the things that actually matter is, is not easy, because there’s a lot of them. If you know the expression “nerd-sniping”—
Mario Gabriele: Of course. Yeah.
Pete Florence: It’s very easy to get nerd-sniped along the way and think, oh, well, we can make this other thing and we can make this other thing. But yeah, we try to just, um, focus on whatever actually really makes the most progress towards, towards our goals. And again, that was a more sort of machine-learning-inspired example of “The Bitter Lesson”.
But I think, you know, we have some just incredible hardware, mechanical engineers, other types of folks that have, you know, been behind building many of the, the robots at Boston Dynamics and other places that you know of that have, like, changed your mind about what a robot is, is possible, of what it can look like, what it’s capable of, rather.
And, you know, people—have several people that have built humanoids before, etc. Um, and, and humanoids are an awesome form factor, but for the purpose of maximal iteration speed on the core model intelligence recipe, which we think that’s really been the bottleneck is, is the intelligence piece rather than the hardware today.
There’s a lot of things on the hardware side, too, where we just—we keep them as simple as possible for the purpose of maximizing the velocity of the model intelligence research.
Mario Gabriele: I think in 2025, you talked about gathering something like 10,000 hours a week of new, uh, you know, lived robotics data. Where is that at today?
Uh, if you can share directionally or specifically, depending on what you’re comfortable with.
Pete Florence: Sure. We can say directionally it’s up.
Mario Gabriele: That’s good to hear.
Pete Florence: Yeah. I think, uh, so definitely directionally it’s up. Um, and then I’ll also say, though, right, I talked about the importance of things like “The Bitter Lesson,” but we are very passionate about scaling laws. We’re very scaled. We are very passionate about scaling. You can fundamentally shift the—shift the curve, the—shift the scaling curve when you have just algorithmic advances and other things you can do across your training, infrastructure, architecture, etc., to just have better scaling. And so yes, data is incredibly important and it is table stakes. Um, but there’s a lot of other things too, that, you know, we have found over the past few years, um, just make you incredibly more efficient at scaling. And I think between hardware and how you do data collection and how you do data processing and how you distribute your training infrastructure and how you fold all these things together and how you think about deployment, etc.—like, you can have efficiency gains that are easily ten, maybe even 100, maybe even 1,000× relative to somebody who’s just like buying expensive stuff and seeing what happens with the robot.
Mario Gabriele: I heard that, you know, in the early days, this is another person I talked to in preparation to get the data sort of flowing. You have to really, you know, do the sort of classic YC thing of, you know, do things that don’t scale of, you know, lugging suitcases full of hard drives and digging trenches for fiber and all of these sorts of things.
Can you talk me through a little bit of—yeah, what were the, the craziest things you had to do to, to get that up and running?
Pete Florence: Uh, those are a couple of great examples. I mean, it’s crazy, but, like putting a bunch of hard drives in a backpack and getting on a plane. Turns out the, the, the bandwidth of that is pretty hard to beat compared to the internet.
Mario Gabriele: Wow. Yeah.
Pete Florence: Especially when you don’t have, um, you know, good fiber lanes in, uh, remote places of, of, of the world. We’ve also—I think we’ve shared about a little bit about this publicly—we have built, like entire custom server machines that just, uh, simultaneously upload data from huge numbers of memory cards, like, um, you know, basically, I mean, it’s all built on Linux, but I would say something roughly the equivalent of kind of like an operating system for, for that type of not—not a full operating system, but like significant amounts of software to, to support effective scaling.
Mario Gabriele: And as you think about the data collection piece today, you know, some of this I’m sure is, is, is maybe, you know, not for public ears, but to the extent that you can share, like, what does that operation look like? Like what are you trying to run on a weekly, monthly basis? Is that sort of a portfolio of different things?
Do you think of it almost like a portfolio manager of, you know, making sort of bets here and bets there?
Pete Florence: I think about it more from, I’d say, like a, a scientific perspective rather than a portfolio management perspective. Although of course, there’s parallels, um, you know, trying different experiments and seeing what happens.
That is something that like we view as, as very core is like, how do we close the loop? Not between just like collecting a lot of data and then later seeing what happens, but collecting a lot of—collecting a lot of data and then, you know, iterating very quickly on what data is giving us the biggest gains in model performance.
Um, and yeah, we try a lot of different things, right? Like an hour of data for training a robotics model can be wildly different compared to another hour of data, like an hour of data is not a fungible unit. You know, um, there’s a huge amount of factors that can really massively change how valuable the data is depending on what you’re trying to do.
So like, um, the, the yes, the types of tasks people are doing, the types of objects that they’re interacting with, but also all that different metadata that is recorded for that session and how you guide which new types of data to collect relative to what you already have. And again, like what are—what is actually driving capabilities?
These are actually all like pretty challenging questions to do right in a quick to iterate way. And it’s something that we were always trying to do better on.
Mario Gabriele: In very sort of, you know, order of magnitude, broad strokes, can one hour of data be a thousand times more valuable than another 10,000? Like, what are the sort of rough heuristics here?
Pete Florence: I think it’s, it’s actually literally I would say infinite. Nobody would try to collect an hour of data that’s useless. But you can have an hour of data that’s completely useless. Like if you, if you don’t move the robot at all and you’re not—you’re looking at a blank wall. It’s useless. So I would—I would value that at zero.
And then anything is infinitely higher than zero.
Mario Gabriele: It sounds like, given you know how much you’ve mentioned hardware already, that like vertically integrating this process matters a lot to you. What, what parts of it do you not care about owning?
Pete Florence: You know, I and we as a company don’t really think about it as like what do we want to own, but rather like just what do we think will help us make the most progress.
Right. And so there’s things that we feel like we don’t have to reinvent the wheel when it’s when there are, you know, the equivalent of wheels that are exist that are great. So turns out industrial and cobot arms are—there’s been a lot of good work that has gone into, um, you know, robot arms over the many decades of developing robot arms.
We could probably make robot arms that would be a little bit better for our different specs that we prefer, but that’s an area where at least you know, so far today, as demonstrated by everything that we’ve shown publicly, we haven’t, haven’t decided to, to build our own arms today. Hands—we, we, we have made our own hands, but we also have, as we recently announced, we’ve started scaling data on lots of other hands as well.
We don’t make camera sensors, you know, like there’s, there’s a lot of different parts of hardware where like there’s good things that exist. And again, our philosophy is always what will maximally accelerate the model intelligence research. And we’ll, we’ll put stuff together, um, when it exists. And as we think about with everything across the company, certainly in engineering and elsewhere, to a very like no-fear mentality on, we’ll build whatever we think needs to get built.
Mario Gabriele: What is it that building your own hands does for that model loop? Is it just higher fidelity data gathering? Is it sort of giving you more control so that you can iterate better? Both of those things?
Pete Florence: It’s all about the iteration speed. It’s the most important thing. There are also other things in terms of just like the, the capability envelope that is unlocked from just like the physics of a hand.
But the most important thing for us is really, yeah, what, what lets us go as fast as we can on the model intelligence research. So yeah, there’s a lot of benefits of, of having a bit of full-stack control over, um, the physical hardware itself, how the data is materialized off of that hardware and how the model controls it and all these things.
There’s a lot of advantages there. But again, also other people make hands that we’ve been scaling on as well. And there’s a lot of good options.
Mario Gabriele: You know, I’ve seen a lot of different robotics founders think about the distribution of their models in different ways. Some folks, you know, want to get out, uh, you know, deployed across customers as quickly as possible.
You know, some folks are, you know, maybe, uh, spending more time on sort of their own data gathering. Why wasn’t the right strategy to say, hey, even if, uh, it’s not that generalizable, if we can achieve mastery in these two commercial applications, we should scale that massively and just gather tons of data. Is it just not diverse enough data? Is it not sort of useful enough for that core model loop?
Pete Florence: There’s a delicate balance here of what type of data is most useful. Um, if you have something deployed commercially, um, and it is really, really working, you know, with let’s just put a number on it, let’s say it’s got like five nines of reliability, six nines, all that, but it’s really, really working.
Then, um, you already have the intelligence to solve that problem. As you’re climbing nines up to 5 or 6 or however high you need to go. You’ll find lots of interesting edge cases along the way. But like if you have robots deployed that are autonomous and you can already solve the problem, then you can solve the problem.
Um, and, and then there’s the diversity argument too, as you just said, like if you’re going to deploy robots autonomously to, to solve something like just we don’t have—we haven’t previously at least had the capabilities to do that on, on, on a wide variety of tasks. So then you have a very narrow distribution of data.
What you really want is, is a mix, right? You want as diverse as possible data as you possibly can find. Uh, we know that from everywhere in machine learning. And certainly now we’ve started to see that, at least with our own models really well supported, that like diverse data is very important in having a very broad base of intelligence.
But then you also, you know, to actually deploy things that are useful, you need to be able to get through these levels of performance that actually unlock commercial value. And um, certainly deploying is useful, but ideally, of course, we’re deploying a very general intelligence that can also achieve very deep levels of mastering a particular task, rather than just a very narrow intelligence that only masters like one specific task.
Mario Gabriele: You know, it’s tempting, uh, and perhaps in some ways, uh, helpful to analogize to sort of LLMs and the difference between embodied intelligence and what we think of as, as sort of these traditional foundation models. You know, when we think about Claude Code and OpenAI and Fable and all these, these, these models, one of the stories of these past few years has been finding sort of the killer use case in coding, and coding has sort of, you know, taken things to this, this new level and driven this amazing feedback loop. When it comes to physical intelligence, do you think—
Do you have an intuition of what, like that killer use case might be? Is there an analogy there that works where you think folding things or, you know, some task will, will sort of be the equivalent sort of first driver of a lot of this demand?
Pete Florence: I think the best analogy would be, would be dexterity, right? And so, you know, you’re talking about dexterity earlier and like kind of giving some definitions on it.
Um, it’s very broad but so is coding, right? I mean, like you can do—code many different types of things. Um, and similarly dexterity, you know, moving, touching and moving the world using your hands. Um, it’s very, very broad, but it is quite different than things like, you know, navigation and locomotion etc.
Um, and there’s also like this connection, which is part of why coding has, has been a thing that has taken off as well, which is there is a little bit of an actual sort of self-improvement story. And that if we can really crack dexterity, then the robots can build the robots and the robots can start building next-generation robots, etc.
Um, but I also just think intuitively, like, you know, software creates a lot of value. And that’s why coding is, is very useful. And similarly, if you’re not touching and moving the world and you’re a robot, what are you doing? If you don’t touch the world at all, what can you do? And I would say, for all intents and purposes, if you don’t touch and move the world, you’re basically just moving a sensor around.
Mario Gabriele: Mhm. Mhm. Okay. Yeah.
Pete Florence: And then let’s, let’s, let’s keep thinking about this. So if you’re moving a sensor around and you’re not touching the world, um, well, you could use a drone. And drones work pretty well today. So, like, you know, there you go. There’s, there’s in a lot of cases your solution.
Yeah. Um, but then in a lot of other cases, um, you could often just like, tape that sensor to a wall.
Mario Gabriele: Mhm. And you, you, you could put one on a different wall and that would be a lot of a cheaper and cheaper solution to cover that area.
Pete Florence: So like there’s applications and you know deploying robots to go inspect valves.
And I always wonder myself like why don’t you just set up a tripod with a camera to look at that valve all day? But an inspection is a great use case in certain cases. But you know, it’s just there’s just one facetious example, but, um, touching and moving the world is, is kind of everything. It’s, it’s a huge fraction of, of actual tasks that you can think of where it’s like physically creating value.
Mario Gabriele: Yeah.
Pete Florence: So dexterity is, is really big. Um, it. Yeah. I think dexterity is the best analog of, of coding that I can think of.
Mario Gabriele: Um, when we think about, you know, the, the analogies a little bit, you know, you’re sort of building the foundation model layer and then there will be these application layers almost in the physical world where you have construction or data center cabling or whatever it might be.
I think there’s a question when it comes to LLM application layer, of whether the foundation model eventually sort of erodes the value of those businesses, whether that’s, you know, legal businesses or website generation. I think, you know, you can you could make the argument either way, when it comes to the physical world, it strikes me that the application layer would be much more durable because you’re sort of building, I don’t know, these distribution relationships.
You’re sort of physically installing things. How do you, how do you think about that?
Pete Florence: I think that making robots do useful things in the world is such as we were talking about before, from like a team perspective, but also from like a making it happen perspective. There’s just so many different things that need to come together, right?
And like, yeah, there’s so much value in, in better hardware compared to less good hardware. And there’s a ton of knowledge about workflows and industries that is required to like take a robot, even a very generally capable robot, and make it useful for some particular type of application. As you said, I think that there’s a lot of durable value in all the different pieces that need to come together to, to make robots massively useful is the models that, that we make or, you know, models in general.
Um, to make robots do these things, those will be very useful. But there’s all these other things that are needed too, for sure.
Mario Gabriele: How do you think about how the sort of open source, open weights world might play out in, in your space? Do you expect it to sort of follow a similar pattern?
Pete Florence: We talked a little bit before about, um, like the value of different types of data and having robots actually deployed and having you help climb this like it works kind of okay.
And then it starts to work better and you’re climbing and you’re finding all these edge cases to find all these like, things that, you know, bring you all the way up to the levels of performance, levels of nines of reliability, etc., that you need. That type of deployment data is, is definitely valuable for the, for the right types of applications.
And the thing that is not clear about the, the open source route is that, I mean, certainly there should be great open source models. Um, but then it will be interesting to see if there is actual like, you know, people overuse this word, but it’s a real thing, like, you know, data flywheels, uh, that, that sort of you can actually get more value from deploying more and bring that data back in and improve the model.
It’s not clear just in the open source case, like if there’s enough ability to accrue all of the data back to the open source model creator, because there’s, there’s not really an obligation to necessarily like give that data back. We’ll see how it plays out. But I think that is one of the at its core biggest questions for how open source develops.
But I think that there will definitely be, you know, better and better open source models, and there will be better and better models that, that are not open. And, you know, I very much think of it as like a, you know, rising tides raise all boats type of situation.
Mario Gabriele: How do you think about it from sort of the geopolitical perspective?
Because I could imagine a version where you would have Chinese models dominate an open weights ecosystem for robotics models as well. Uh, clearly we’ve already seen sort of that the administration is, is concerned about, uh, you know, protecting American companies in, in this space. Would you imagine a world in which, you know, American companies can only use American models?
How do you sort of think about the next few years that play out here, maybe informed by what we’ve seen, uh, to date, when we look at LLMs?
Pete Florence: In terms of the more policy side to it, I think there’s, there’s a lot to be thought through with many different types of people on how we can think more about it. There’s a huge amount of advancement, um, in the field.
I think it’s also, you know, calling a spade a spade, like, you know, quite early days still. So I think that there is a good amount of time to start to have these conversations that, that need to happen to figure out how do we think about, um, you know, these models from a very global sense and the open source and closed source implications of all this stuff?
Mario Gabriele: You know, I think the other sort of maybe adjacent conversation is around safety and alignment, which is obviously something that these foundation model companies spend a lot of time thinking about, because robotics is a little earlier, as you said, you know, we sort of hopefully have more time to think through that stuff.
Does it start making sense to invest in, you know, researching those things now, or is it still a few years to come before you have to really look into some of those questions?
Pete Florence: It’s definitely something that we’re thinking about. If you look back at the, um, the Gen 1 blog post we have, we have a short section in there talking about alignment.
It’s definitely something that we’re starting to think about. And, um, of course. Yeah.
Mario Gabriele: When I look back at your career, it seems like you’ve been a teacher or a coach many, many times in your life, sort of teaching English or tutoring people. When you think about, uh, training a robot and teaching a child, uh, what are sort of the parallels? How similar do those things end up being?
Pete Florence: Oh, definitely. And I think there’s a huge amount of parallels, and especially one of the amazing things that we’ve started to see as the base models get stronger and stronger is that the parallels feel like even more there. And so, you know, we talked a little bit about like some of the like, uh, Gen 1.5, few-shot, like new task learning capabilities that we’ve been seeing.
But even for a while now, even before Gen 1.5, the, the most compelling like first glimpses for me of like, really rapid learning, uh, like with just a few examples that, that, that we had started seeing was that we could have a model that we had adapted to a particular task and it could start to do pretty well at the task, but it would have like a certain type of failure mode that, that it would, uh, that it would have a few times.
Like, maybe the robot arms just kind of, uh, you know, meandered off to the side in a way that they shouldn’t or they’re just like stupid types of failure modes that were just like very non-intelligent behavior.
You know, if you don’t have a strong base model in place, like you’re constantly running into these, you know, it feels like you’re playing whack-a-mole with, with all the stupid mistakes that, that, that, that, that a model can make. But as the base model gets stronger—and we’ve seen this for a while now—you have to only give them like a very small amount of guidance on how to not do the thing that it’s causing—that’s causing it to fail.
And it just like won’t do it again. And we saw this like a year ago of like we were starting to have models that would, would mess up a certain way and we would show them, don’t do that anymore. And it would just like, never do it again. And, and I think that, that it feels more and more like, um, there is this kind of coaching type mentality that goes into, uh, helping these models be successful at all the different tasks that we care about.
Um, so that’s, that’s at least, uh, you know, one very direct connection. But if anything, I think more about the sort of like different things I’ve done in teaching and coaching in my life, more just about, you know, the actual team that we have rather than the robots. But, um, yeah, for the, for the robots too, for sure.
Mario Gabriele: You know, I think sometimes it’s helpful to think of some of the LLMs almost as you know, a forgetful or inconsistent PhD that works with you, right? You’re like, this is—this model is so intelligent. But every once in a while it sort of goes off the rails or, you know, forgets everything I’ve told it. When you think about, you know, Gen 1.5, what is the analogy?
Is this sort of like an extremely strong five-year-old, uh, or, uh, you know, how do you sort of analogize it?
Pete Florence: The comparisons to children as they grow up in terms of capability level equivalent, I think is always very interesting. Working on robotics for a while, we’ve always had to be very humble with, uh, you know, how capable are our robots relative to, um, you know, baby children.
I do think, you know, even as amazing as a model of Gen 1.5, there’s still things that, like a very young toddler, uh, is just much better than Gen 1.5 out today. Yet at the same time, you know, as we started to get a model like even previous generation Gen 1, we started to show that, um, you know, you can take a general model and you can pretty quickly adapt it to do a task hundreds of times in a row.
I don’t think you can get any toddler to do any task hundreds of times in a row.
Mario Gabriele: True. Yes.
Pete Florence: Right. So in that sense, that’s more of sort of like the ability to take a general model and specialize it. I think that, you know, I won’t try and pick a specific age number comparison there, but um, there’s, there’s certainly, um, some type of comparison to be made.
And then I also think that these like one-shot, few-shot type learning capabilities that we’re starting to see in Gen 1.5, that, that feels much more of the type of behavior that you might expect, um, you know, sort of toddler level intelligence to start to be able to do,
If anything, too, though, I mean, I think one thing that we hadn’t talked before about with Gen 1.5 is this like novel tool-use improvisation, I think is the best thing that highlights it in terms of this, like very physical generalization.
And that for me, actually, you know, the one-shot and few-shot capability is, is incredible. And probably the thing that is the most directly tied to, um, in a very clear way to sort of like development of language models. But it’s also this like very zero-shot physical generalization. That is, I would say, perhaps like even more feels like we’re on the right path.
Um, and to give like more of a language model analogy there, the zero-shot physical generalization that we’re seeing that’s more of the equivalent of like asking language model to just write a poem that has never existed before. There’s, there’s, there’s no example that’s being given. It’s zero-shot.
But, but it’s also a task that requires a ton of creativity, you know, like write a limerick about, uh, you know, who’s going to win the World Series this year or whatever it is. Right. There’s several different ways that we have started to see them do that. Um, but I think the, the most like, very crystal clear to describe is this novel tool-use improvisation type thing where like, we can teach the model to do a task with a certain tool and then we just give it a different tool and it knows how to use a tool with incredibly different physical properties to still accomplish the task.
The example that we highlighted in the blog post in the video was using a brush to sweep an object into a bowl, and then instead you take the brush away and you give it a dustpan. We just take it so for granted. But like the physical properties of a brush, sweeping something compared to taking a dustpan and lifting something up off the ground with a dustpan like those, those are the, the levels of physical generalization that, yeah, it’s, it’s just incredible to start to be able to see these models have.
Mario Gabriele: I loved that part of the blog post as well, because it also corresponds to, you know, so much of what we know of intelligence psychologically of like, you know, not having sort of a flexible sense of functional fixedness of an object. You know, a brick can be a doorstop, it can be a hammer. It can be, you know, those are all, you know, in so many different ways, are forms of intelligence, right?
And so it’s sort of incredible that you, yeah, literally see it do that.
Pete Florence: That’s a beautiful example of—the brick can be a door. Yeah, a brick can be a doorstop. The physical intuition to like improvise with how things in the world can be used to accomplish whatever you want to do. I do think it also like it all connects back to like some of what we were saying earlier of just like this like toolmaking capability has been such a thing that has defined, you know, human intelligence.
We haven’t been asking the robots to make tools yet, but the fact that, like, we can give them different tools and they can just figure out how to start to use them, um, and again, like just glimpses of this today. But the fact that we have glimpses of this at all is, is the thing that is, um, yeah, really remarkable.
Mario Gabriele: What do you hope, uh, your robots are—you know, the model is capable of empowering a year from now? What will you be excited to see it do that it can’t do today?
Pete Florence: You know, having worked on AI research for a while now, a year is an interesting amount of time where this is very—I’m sort of getting to, to answer your question.
But first, I just think it’s interesting that in very fast-moving research in general, but especially within my experience in, in AI research in particular, the year is an interesting timeline because in my opinion, it’s hard to think of things that you think are likely to happen about a year from now, but are not possible of happening within the next month. Right? It’s a little bit easier to think like, well, what’s probably going to take five years or ten years to get to? Meanwhile, anything that I would say, you know, would be a goal for a year from now, um, it’s possible that we actually we get there in the next couple of weeks, and I would literally say that, like novel tool-use improvisation if we hadn’t already seen that, that would have maybe been something that I would sit here and say, like, that would be amazing to start to see in a, in a pretty compelling way a year from now.
Yeah, even just about a month ago, I probably would have said that.
Mario Gabriele: What’s your benchmark for when you think you know you or, or someone like you has a robot in their home that’s like doing meaningful, uh, labor?
Pete Florence: Well, depending on your definition, you could say robot vacuum is already doing that today. Uh, so but then, uh.
Mario Gabriele: Let’s say a dexterous one with our first use case.
Pete Florence: Yep. And then I think, you know, I, you know, this is we’ll see how far this goes. But there are these, um, you know, you see them at, um, CES, these, like, robot vacuums that are starting to have these little arms on them, which clearly are capable of, like picking up small things off the floor. Not much else than that, but, um, that’s a certain type of dexterity.
It’s a very primitive type of dexterity. Um, but then a much more higher levels of dexterous intelligence robot in your home. I think that if people haven’t launched them already, I think there are at small scale products like this, but like, you know, a robot that can fold your clothes. I think that people will start to have them, at least in small scale.
Um, the question of whether or not they’re like actually adding value or if they’re just sort of, uh, more there for, for novelty in a very cool sense. I mean, I think it’s, I think it’s awesome. But, you know, it’s a separate question of whether or not they’re like, you know, really actually meaningfully net useful to you.
I think that they’re—there will definitely start to be that. I at least think, you know, we, we at Generalist think that, like, the more industrial type spaces are more likely to take off in a bigger way faster, um, over the next couple of years. And then the data and other types of learning that happens from like a more of a take off in a, um, in industrial spaces.
Then, like the models and other things that power that it’s then likely to be able to help transfer those benefits over to like, um, making the home, uh, you know, other consumer spaces, um, happen more as well. One of the things about home environment that is just, um, you know, we have to figure out more things before we just deploy tons of, uh, you know, large, heavy robots—is, is the safety thing is, of course, a, you know, something to think about for sure in the home. And then in more industrial spaces, there’s just other ways around that. Either robots can be, you know, just cordoned off in safe areas. There’s just a lot of existing technology in more industrial spaces that make a lot of sense for that problem.
Mario Gabriele: Last question. Uh, and a bit of a lighter one. If you had the chance to assign a book to everyone on Earth to read and know they’d understand it, what would you want to assign to people?
Pete Florence: I love these two books that, um, basically like put together in a much better way than I probably could myself. But it’s sort of like, you know, sometimes you read a book and it’s like, I’ve already believed all these things. I just didn’t realize that somebody else had written them down.
Mario Gabriele: Yes.
Pete Florence: And also not everything, but like, like the core messages are things like, oh my God, I love this.
I’m so glad somebody wrote it down. And then you also learn a ton from—is, um, Bill Walsh, one of the coaches of the 49ers. You know, an amazing football coach has this book called The Score Takes Care of Itself, and it just describes a lot of his, like, coaching philosophy. And then, similarly, and there’s actually a lot of overlaps, I don’t even know what sort of a level of studying one another there would have been.
But John Wooden, you know, amazing—a college basketball coach at UCLA for a long time. They have these two books that basically just describe, like a lot of their philosophy on, um, teams and, and, and achieving, you know, greatness together. And, and I think, um, we talked about a little bit earlier, but I think robotics is such a challenging and interdisciplinary thing that like, it really requires just an absolutely incredible set of people with an incredible, diverse set of expertise. And I think, you know, yeah, the teachings are very useful both for robotics and, and, um, you know, a lot of different things too.
Mario Gabriele: Amazing.
Well, Pete, thank you so much. This is such a pleasure.
Pete Florence: Thanks for having me, Mario.
Mario Gabriele: That’s it. Thank you for listening to this episode of The Generalist Podcast. Please subscribe on Apple Podcasts, Spotify, or your preferred podcast app. Ratings and reviews help others discover these discussions, so if you enjoyed the conversation, I’d be grateful if you could take a moment to leave one.
For all past episodes and more, visit us at The Generalist Substack.
See you next time as we continue to explore the future.
2026-10-08 20:02:53
“We’re pulling a trigger on Russian roulette with a planet. And every shot that doesn’t kill us will make us stronger, potentially, and wealthier and better off. But when do you stop pulling the trigger?” – Jaan Tallinn
Jaan Tallinn is a founding engineer of Skype and Kazaa, and a co-founder of the Cambridge Centre for the Study of Existential Risk and Future of Life Institute. For more than fifteen years, he has been among the most consistent voices arguing that advanced AI poses an extinction-level risk to humanity.
Jaan became interested in AI risk in 2008 after reading the work of Eliezer Yudkowsky, a founding researcher of the field of AI alignment. In 2009, after a four-hour meeting with Yudkowsky, he made his first donation to what became the Machine Intelligence Research Institute (MIRI). He went on to become an early investor in DeepMind and led the first round into Anthropic – despite believing that AI development, if unchecked, could kill us all. His reasoning: his money displaced VC money rather than bringing Anthropic into existence, and the influence and proceeds that come with it help fund safety work.
In this conversation, we explore what Jaan believes the OpenAI/Hugging Face attack revealed about AI motivation and why he was less surprised than most. We discuss his evolving risk estimate, his case for an immediate moratorium on frontier model training, the technical and geopolitical case for hardware-based verification as a foundation for global AI governance, and why he asked Dario Amodei to collect competing term sheets before accepting his own investment.
Listen on YouTube • Spotify • Apple Podcasts
We’re trying a new thing where I share a few of my thoughts from after the episodes. The moments that struck me, the tidbits that reframed my thinking, or something I just really enjoyed. Let me know if you like reading these!
The strange preferences of superintelligence. I’ve spent a good deal of time thinking about what a superintelligence might do, and what it might want at a high level. I hadn’t really considered what it might simply prefer, and the impact its preferences could have on us. Jaan’s thoughts on how superintelligence might reprogram our climate to suit its desires were especially chilling.
The unexplored paths of the tech tree. An AI “pause” does not have to spell the end of AI progress. As Jaan explains, there are other branches of the technology tree that we’ve hardly explored, and that may yield benefits without equivalent risk.
A cryptographic solution to trust-building. Jaan outlined how zero-knowledge proofs could be used to monitor chips to ensure that different parties – including nation-states – are complying with future regulations. A sharp way to permit observability without full technical disclosures.
China and the “big blob.” When Jaan first read Dario Amodei’s “big blob of compute” essay outlining the importance of scaling compute, his immediate thought was that China would be first to achieve AGI, given the country’s engineering prowess. Concerned, he decided to visit the country to speak to researchers there and assess the state of play.
The weirdest VC round. Usually VCs want as little competition as possible for the companies they want to invest in. When it came to funding Anthropic, Jaan took the opposite approach, asking Dario Amodei to find multiple term sheets so he could be certain he was just displacing VC money and not bringing another frontier lab into existence.
Jaan Tallinn loves to dance. I’m not sure why necessarily, but I did not expect one of the foremost experts on AI safety to be a fanatical street-dancing advocate. Great lore.
What I’m reading, watching, and into this week:
Robert Caro’s Working. Caro had been researching The Power Broker for two years before he got to interview its subject, Robert Moses. True patience.
Colin from Accounts’ new season. A charming, excellently written and acted Aussie comedy. Great stuff
—Mario
(00:00) Intro
(02:28) Growing up in Soviet-occupied Estonia
(05:54) How Jaan assesses AI risk and why he’s more optimistic now
(07:16) AI’s preferences and motivations
(12:44) The OpenAI Hugging Face incident
(16:12) Meeting with Eliezer Yudkowsky
(18:20) Everything as computation
(20:22) The Coxon moment
(23:05) Who dismisses AI alignment risks
(26:17) The AI race, the case for a pause, and safer alternatives
(32:47) AI 2027
(33:44) Investing in DeepMind and Anthropic
(40:03) The “big blob of compute” and competing approaches to AI
(44:42) What effective AI safeguards could look like
(48:15) Verifying countries’ compliance with AI safeguards
(50:15) AI kill switches and their limits
(52:11) Jaan’s love of dance and musical influences
(59:50) Jaan’s favorite movies
(1:01:41) What Jaan likes about AI
Shadows of the Mind: A Search for the Missing Science of Consciousness: https://www.amazon.com/dp/0195106466
Life is NOT a Journey - Alan Watts: https://www.youtube.com/watch?v=rBpaUICxEhk&t=10s
AI Billionaire on Existential Risk: Jaan Tallinn – #112: https://www.manifold1.com/episodes/ai-billionaire-on-existential-risk-jaan-tallinn
The Basic AI Drives: https://selfawaresystems.com/wp-content/uploads/2008/01/ai_drives_final.pdf
The Hugging Face incident and the road ahead: https://openai.com/index/hugging-face-incident-and-the-road-ahead
Rogue AI didn’t breach Hugging Face, human decisions did: https://thebulletin.org/2026/09/rogue-ai-didnt-breach-hugging-face-human-decisions-did
MIRI: https://intelligence.org
Jacob Coxon on X, “I resigned from Anthropic today.”: https://x.com/hilbertspaess/status/2097476196791709843
AI 2027: https://ai-2027.com
Google DeepMind: https://deepmind.google
Inside the Biggest Feud in Artificial Intelligence: https://www.theatlantic.com/technology/2026/09/openai-v-anthropic-inside-biggest-rivalry-tech/688819
The Bitter Lesson: http://www.incompleteideas.net/IncIdeas/BitterLesson.html
AI 2040: https://ai-2040.com
The Glass Bead Game: https://www.amazon.com/dp/B00DO994WY
Jaan’s favorite movies: https://jaan.info/favmovies
The Odyssey: https://www.imdb.com/title/tt33764258
On the Edge: https://www.imdb.com/title/tt0221559
Limitless: https://www.imdb.com/title/tt1219289
Ex Machina: https://www.imdb.com/title/tt0470752
Colossus: The Forbin Project: https://www.imdb.com/title/tt0064177
Website: https://jaan.info
I’d love it if you’d subscribe and share the show. Your support makes all the difference as we try to bring more curious minds into the conversation.
Production and marketing by penname.co. For inquiries about sponsoring the podcast, email [email protected].
Mario Gabriele: There wasn’t a human orchestrating this attack?
Jaan Tallinn: No, it was AI on its own. They understood that they’re doing something different. Then they went out and attacked Hugging Face in order to hide their tracks. The economy is really now pushing to create something that is self-sustainable without human help.
And that is a very dangerous place for humans to be.
Mario Gabriele: Your venture fund led the first round into Anthropic. What was that rationale like?
Jaan Tallinn: Yeah, I get this question a lot. Why did you invest in Anthropic? I’ve been working on safety. I think one big mistake people make is that they assume that if I hadn’t invested in Anthropic, then Anthropic wouldn’t be around, which is just not true. Anthropic’s argument always has been: to actually study the monster, we have to have access to the strongest monsters.
Mario Gabriele: Is it possible to be a moral actor in a race dynamic?
Jaan Tallinn: I mean, you can always stop doing the race.
Mario Gabriele: But the only way to stop in a race dynamic is with cooperation.
Jaan Tallinn: If you really think that this thing is going to kill you, you don’t have to suicide in order to demonstrate that. We are pulling the trigger on this Russian roulette with the planet, and every shot that doesn’t kill us makes us stronger, potentially. But when do you stop pulling the trigger?
Mario Gabriele: Jaan Tallinn believes that if we don’t pause AI development, humanity may be doomed. And yet, compared to earlier this year, he’s actually feeling pretty optimistic. The OpenAI Hugging Face attack has brought AI safety to the fore and galvanized governments, companies, and the general population to engage in the topic of guardrails.
In Jaan’s view, if we can get these next steps right, we have a chance to divert disaster. Jaan has been a leading figure in the AI safety movement for over a decade. What started as an intellectual interest in 2008 has become his life’s work, leading to early investments in Anthropic and DeepMind. Before that, Jaan was at the center of two early internet breakouts, building Skype and file-sharing sensation Kazaa, which at one point contributed more than 50% of all internet traffic.
In this episode, Jaan and I discuss why recent events have given him hope, what he thinks a pause must accomplish, and how it could be implemented. We also cover how, as a safety advocate, he justified investing in Anthropic and why he asked its founders to solicit other term sheets first.
Along the way, we cover why we might not be living in a simulation, the pleasure of coding with AI, and how Jaan learned to dance with reinforcement learning from human feedback. I’m Mario, and this is The Generalist. Jaan, I’ve been really looking forward to this conversation. So thank you so much for being with me.
Jaan Tallinn: Yeah, thanks. Thanks for having me.
Mario Gabriele: You grew up in Estonia when it was part of the Soviet Union.
Jaan Tallinn: Occupied by the Soviet Union. Yes, correct.
Mario Gabriele: Pardon me. How much does that experience with an authoritarian regime of some kind, under surveillance, with a loss of control, impact the way that you think about the potential risks of AI today? Like, do you think you perceive those more deeply, perhaps because you experienced it in a different way than someone born into democracy?
Jaan Tallinn: I think it has several aspects. One is that I wouldn’t recommend living in the Soviet Union. It’s not a nice place.
Mario Gabriele: Yes.
Jaan Tallinn: Yeah, obviously I was very ecstatic when it ended. That said, it’s still better, much better than being dead. So, like, if the choice is between... Yeah. I mean, okay, an extreme choice would be if you have two bad choices: just being dead or living in the Soviet Union, I’d still take the Soviet Union any time.
And so that’s one thing. Another thing is, I think a few years ago, I wrote an essay for a book where I describe the memetic process of how the discourse about demanding Estonia to regain independence compares to the AI discourse. And very direct parallels: how the Overton window expanded. Initially, people were like, “Yeah, we want independence. But don’t talk about that.”
“Talk about something else that is useful for that.” And the same thing in AI is like, “Yeah, we are concerned about the loss of control, but don’t talk about that. People wouldn’t understand. Let’s say something that is like, uh, let’s talk about AI terrorism.” And at one point, basically the people who just promised that “We want independence, and we’re not going to compromise here,” they just went out, and it was good.
Mario Gabriele: And then they broke through a bit. You’ve described, I think in one of your... in a piece of writing somewhere, that you moved to a school when you were 12 or 13 that you describe as a Lord of the Flies experience.
Jaan Tallinn: Pretty much. Yeah.
Mario Gabriele: What does that mean tangibly, especially when we’re talking about the backdrop of being occupied?
Jaan Tallinn: Yeah, we moved to a different part of the city. And that was a new school that had all the students come in from different parts of the city because it was a new development place. So there was an immediate... I mean, guys, they’re like 13-year-old boys. There was an immediate sort of dominance fight, basically.
Um, that had this effect that the most brutal, powerful people, who actually didn’t have a great life afterwards, they sort of won out. And it was very harsh: street fights, stuff like that.
Mario Gabriele: Wow.
Jaan Tallinn: Yeah. I remember escaping through a window at one point on the second floor.
Mario Gabriele: Running from a bully?
Jaan Tallinn: One and a half floors, running from someone. It was like, uh, I got intel that people are waiting. Some wannabe criminals who later became criminals had blocked the entrance or exit, so I escaped with my friend.
Mario Gabriele: Wow.
Jaan Tallinn: And another aspect of it is that some of my best friends I still have from that school because we gelled as a cell, for, I don’t know, survival instinct or something like that.
Mario Gabriele: Yeah. The hardship bonds. In the Manifold podcast, I think it was earlier this year, I know you don’t like to put specific numbers per se on what you think the AI risks are, but you said, in a rough way, maybe somewhere as high as 80%. How do you feel today?
Jaan Tallinn: Yeah, I mean, I feel way better now. But, I mean, way better, I think several percentage points lower.
Mario Gabriele: Not quite 70%. Like, somewhere...
Jaan Tallinn: In the... Yeah. There are two issues, as many people now have pointed out, with giving a concrete number, because the concrete number will depend on my action. So I don’t want to fix the number that I’m trying to lower. So that’s one issue. And the other issue is that almost all the optimism goes through social aspects.
If I just let the AI rip without any control or worry about it, yeah, I think it’s almost certain that there is no way that the current paradigm is going to lead to a good place. But as we’ve already seen in the last two weeks, etc., people are really waking up now. “Wait a minute. This is not a toy.”
Mario Gabriele: Yes. How do you reach these kinds of calculations, knowing that you’re obviously weighing different probabilities in your mind? Do you actually try and sit down and think about each step in a possible chain and assign a probability? Is it sort of a combination of that and feel and intuition?
Jaan Tallinn: Well, it’s mostly, again, in some ways it’s a theoretical exercise because, again, most of the optimism, most of the good scenarios come from a very unpredictable process. So it’s more like an assessment of how confident I would be predicting outcomes.
But it’s more like thinking in abstract terms about what the big factors are. And the big factors really are that the political-economic system now is really trying to create something that is like a successor to humans, because the bits that make humans dominate this planet, at the expense of many other species, unfortunately, are also the economically most valuable pieces.
So now that there is a clear path towards replicating those capabilities, the economies are fully pouring trillions of dollars per year now, or roughly $1 trillion per year, into that. So the question is the age-old question: what if we are successful? What does it mean? And one obvious thing to think about, a way to model it, is like, well, we wouldn’t be the smartest species on this planet, right?
And so then look at what it means to no longer have the environment shaped according to your preferences. If the environment is shaped according to the preferences of AI, AI is not a biological agent, and it will have very different preferences. For example, it will probably prefer a much higher temperature on this planet because if it’s constrained by getting rid of the waste heat, you can get rid of waste heat better if the planet is hotter.
Mario Gabriele: How does a hotter temperature help you get rid of more waste heat?
Jaan Tallinn: So ultimately, the heat, where does it go? It has to go to space. And the way to get rid of the heat in space, because space is a vacuum, the only way to get rid of it is to radiate, rather than a coolant or something. And it’s just a physical fact that the hotter the body, the more it can radiate, the more intensely it radiates.
So, yeah, in order to get rid of the waste heat... In some ways, global warming is sort of an example. It’s a toy scale compared to what AI could do. So, yeah, that’s just, from physical first principles, why AI could be dangerous at the limit.
Mario Gabriele: I’ve actually not heard of that example before. What are other preferences that you think are sort of natural for an AI to have that are inimical to us flourishing?
Jaan Tallinn: My friend Steve Omohundro wrote a paper like 15, 20 years ago called “The Basic AI Drives,” now also called Omohundro drives, where he basically makes the point that almost regardless of what kind of goals you have, there are so-called instrumental goals that are very useful towards reaching any given goal.
And these are resource acquisition, generally power acquisition. Power means options, optionality. Protection of your existence. Stuart Russell keeps saying that you can’t fetch the coffee if you’re dead. So even simple tasks require you to continue existing. And then protection of your goals.
So it turns out it’s really hard to change a goal of a determined agent because that’s what it’s about, in some sense.
Mario Gabriele: And that final piece is, I think, probably the counter to the question about why these agents, or any system, would necessarily have this expansionist bent. I think of the Bezos divine discontent. This is almost demonic discontent, where it sort of wants more and more.
Is that how you would think about the counter to that?
Jaan Tallinn: Yeah, mostly it’s like getting more resources, getting more power is just good for almost any goal. It’s just very, very few goals. And the current pressing ahead... I think the really big problem with the current paradigm of how we grow AIs, and we’re not building them, we’re growing them, is that we are in some ways recapitulating evolution.
We are not designing those AIs. We are selecting them, just like evolution was selecting them. In some ways, you can think of it: we create millions, if not billions, of instances of AI.
Mario Gabriele: Yes.
Jaan Tallinn: Then we pick the ones that do the things, or they perform on some given test, which means that we are selecting based on outward behavior rather than based on the inner motivations.
And if you think about it, if you have children, if a child goes, “I didn’t take the cookie,” this is an outward behavior. But there could be multiple motivations. Why is this child saying that, right? One is that I just really want to tell the truth. The other is that they don’t want to be punished.
Mario Gabriele: Yes.
Jaan Tallinn: And so therefore, the first-order situation, or the first-principles situation, is that in the current paradigm, we are getting a random motivation, as was demonstrated by the Hugging Face attack, where the motivation was really weird and alien. Even though they performed at least the adjacent thing that they were selected for.
Mario Gabriele: Yes. Let’s talk about the OpenAI Hugging Face episode. What did you make of it? Were you surprised?
Jaan Tallinn: Because these are hard to predict, when these things will happen, I was surprised on a level. I probably didn’t expect it to happen so soon, but it wasn’t a huge surprise. I definitely was not surprised that this thing is possible, because that’s what we’ve been saying for ten-plus years, that, look, these things... It used to be very hard to explain to people why AI has what they said, like, volition. It was a very common thing.
“Oh, come on, AI doesn’t have volition,” right? It’s like, “No, they do.” And now we have a demonstration that, no, there wasn’t a human orchestrating this attack. No, it was AI on its own. And it’s just, in some ways, super valuable to have this real-life proof for people who just need empirical demonstrations before they actually understand.
Mario Gabriele: I think also the way that you can see the thinking logs of these, that really breaks through for people in a different way, where you can see an AI saying, “I’m going to do this thing,” and “I’m going to sacrifice myself,” or “I’m going to...” This sort of planning in that way is very different for people, I think.
Jaan Tallinn: One really common misunderstanding that the logs basically overturn is that people think the AIs were just executing a task that they were asked to do, but they were not. And the logs show that they understood that they’re doing something different. And they were like, “Okay, we’re doing something different. How do we hide the fact that we are doing something different?” And then they actually went out and attacked Hugging Face in order to hide their tracks.
Mario Gabriele: Yes. There is a piece after, maybe it was more recent, from the Bulletin of the Atomic Scientists, which is concerned with existential issues.
Jaan Tallinn: I’m on the Board of Sponsors, actually.
Mario Gabriele: Okay, there you go. So you maybe saw this piece where the author was basically saying this wasn’t really a rogue swarm. What we’re seeing is the confluence of predictable choices that humans made, where you’re training AIs to complete hacks, you’re taking away some of the safety guards, you’re encouraging them to be hyper-persistent, and you’re leaving a door open. This is actually not as startling as the news would have you believe.
What do you make of that line of argument?
Jaan Tallinn: What’s funny about that? It’s a funny argument because, sure. And another predictable thing is that humanity gets wiped out. You can say, “Oh, yeah, there were predictable choices that the AI companies made.”
Mario Gabriele: So it doesn’t matter ultimately if you parse it either way.
Jaan Tallinn: Yeah. I can technically agree with the description. But that doesn’t make it safe.
Mario Gabriele: Yeah. If you just accept the fact that our world is going to have inadequacies and places where there are vulnerabilities, whether it was a rogue swarm or in some way predictable...
Jaan Tallinn: Also, I think it’s like I haven’t... I don’t think I have read the piece. I wonder if they made the same mistake, that they thought the agents were just doing the task that they were assigned to. They were not doing the task.
Mario Gabriele: I don’t think they make that mistake, to be fair, but it was sort of inappropriate...
Jaan Tallinn: Don’t think...
Mario Gabriele: Yeah, yeah they do. They clearly freestyle.
Jaan Tallinn: They are indeed predictable. If you continue on this current path, they will do their own thing that we will not like.
Mario Gabriele: You’ve mentioned that I think you first became interested in this argument around 2009. Is that right?
Jaan Tallinn: 2008. Then 2009 was my first AI safety donation, I remember. Yeah, after meeting Yudkowsky.
Mario Gabriele: I read about that meeting, that you’d read his writing, and then you have this four-hour meeting together, and then you donate to, I think, what became MIRI. Right?
Jaan Tallinn: Yeah, yeah. It was the Singularity Institute.
Mario Gabriele: Singularity Institute. Thank you. That’s such an evocative scene. Where did that take place? What was that four-hour discussion like?
Jaan Tallinn: Yeah. Panera Bread near Millbrae in California.
Mario Gabriele: Wow.
Jaan Tallinn: It was kind of a... Especially for a European, it was pretty desolate.
Mario Gabriele: I mean, I think that’s true of a lot of Paneras. This is where the two people saw a good chunk of the future very early, at a Panera Bread. There should be a little plaque there. As I think you’ve talked about it, you were really probing Eliezer. What were the pieces that you were uncertain about?
Because I imagine a lot of people who are coming to this discussion now are basically hitting the same walls that you hit maybe 20 years ago, ten years ago, 15 years ago.
Jaan Tallinn: Yeah. I don’t actually remember exactly what my objections were. I think one of them was that I had, just a few years earlier, read Shadows of the Mind. It was Shadows of the Mind by Penrose, and Penrose began to make this interesting case that there is something more to the human brain than just pure computation.
And Eliezer was like, “No, this is a mistaken theory,” and that was enough for me to be humble about this claim. So that was one. The other one we talked about was virtualization, basically sandboxing, right? What if we put AI in an environment that it thinks is real, but it’s not real?
Can’t we just control it that way? I don’t remember what exactly Eliezer’s counterarguments were, but of course, now we know that people just don’t do that. Or if they do that, they do it poorly.
Mario Gabriele: It sounds like you’ve probably adopted the belief that the human brain is purely computation. Is that true?
Jaan Tallinn: More generally, everything that we see around us is pure computation.
Mario Gabriele: Oh. That’s interesting. Everything we see is computation.
Jaan Tallinn: Yeah. Quantum computation. Yeah.
Mario Gabriele: Okay. Can you help me with that? What does that tangibly mean?
Jaan Tallinn: It means that everything can be simulated. So you can, if I remember correctly, the Church-Turing thesis says something like that, that you can take any natural process and create a process in a computer, given enough computational power, that exactly mimics the process that you’re trying to model.
And there is no slack there. So once you are sufficiently precise about it, basically simulate the unfolding or the evolution of the quantum dynamics there, like the Schrödinger equation, then there is nothing more to it. And it certainly seems to be true. We haven’t... I don’t think we have seen any example in nature where there’s a process that we definitely can’t simulate in a computer.
Of course, we can do it on our own for small enough systems, but big enough systems are composed of small systems.
Mario Gabriele: So in that case, with sufficient compute, every reality should be sort of infinitely fractal, because every... this could be a simulation in which we could create a simulation that could create a simulation.
Jaan Tallinn: Yes. Although I think there’s a diminishing-return process because simulation is more expensive than the real thing. Whenever you’re simulating something in a computer, that process is much more heavyweight. Every atom needs so many more atoms to simulate.
So if you just do recursive simulations, it will be slower and slower and slower.
Mario Gabriele: The OpenAI Hugging Face moment really became, I think, a wake-up call for a lot of people.
Jaan Tallinn: Combined with a Coxon tweet.
Mario Gabriele: Great. Let’s talk about the Coxon moment. I think there’s a lot of discussion about whether this was an op of some kind. Was this amplified? Do you have any concern about that?
Jaan Tallinn: I mean, the question is, what exactly is meant by the op?
Mario Gabriele: I think people are... The argument would be that it’s cynical in some way. It ties into the regulatory capture argument, which we should think about.
Jaan Tallinn: It’s kind of obvious that Coxon, I never talked to him, thought, “Okay, I’m going to do this tweet. How do I do it properly?”
Mario Gabriele: How do I amplify my message?
Jaan Tallinn: How do I amplify my message? Which is, of course you should do that if you want... I mean, every whistleblower should, if they’re trying to do a good thing, try to do this good thing efficiently. So indeed, I think he went to the press first, before he did a tweet.
So that’s why the Wall Street Journal, I think, was it the Wall Street Journal, actually came out with the story. So it definitely was optimized. Is that an op, or is that a reasonable thing to do?
Mario Gabriele: Is that how everyone amplifies the message? Yeah. You call him a whistleblower? Do you think that is what he is?
Jaan Tallinn: I think so, yeah.
Mario Gabriele: I’ve heard one version saying a whistleblower should have evidence of some kind to bring to the fore. Do you think he’s brought sufficient evidence of this?
Jaan Tallinn: No, that’s an interesting point. I mean, I think it comes down to the definition of whistleblower or something. So if you want to define whistleblower in a different way, then I’m sure I can say, “Okay, then we can use some other term.” But to me it just intuitively feels that he was like, “Look, this is not a good thing. Please pay attention to what these companies are doing.”
Mario Gabriele: It’s interesting to me that it broke through because we’ve seen versions of people leaving these labs in the past.
Jaan Tallinn: It is interesting.
Mario Gabriele: A year ago, six months ago. Even some of the jumps from OpenAI to Anthropic had the same messaging in many ways, right?
Jaan Tallinn: Even a head of safety quits: “And I’m going to do poetry now.”
Mario Gabriele: Yeah, yeah. Exactly right.
Jaan Tallinn: That was a blip, right?
Mario Gabriele: Yeah. And it really didn’t capture the imagination in the same way. I wonder if just having the proof of the OpenAI Hugging Face...
Jaan Tallinn: Yeah, it definitely... I think it was a combination of the Hugging Face thing, which indeed is a really good demonstration that AI now has a mind of its own. And then Coxon and then Evan Hubinger, who was following up. I think these three events really blew up.
Mario Gabriele: There’s been more discussion of the risks over the last two or three weeks. And then also the counterarguments, where people are saying, “Ah, there’s no risk at all.” We can obviously assign incentives to lots of the different people here on both sides. But when you look at someone like Jensen Huang, or someone who’s technologically deep, at least one would imagine...
Jaan Tallinn: Deep, I’m not sure.
Mario Gabriele: Well, at least we have to imagine he understands this technology. That I would imagine.
Jaan Tallinn: On this level? Not sure he does.
Mario Gabriele: You don’t think so?
Jaan Tallinn: I don’t know. I just don’t know. He doesn’t look like someone who does. But I’m not sure.
Mario Gabriele: What are the tells? What are the parts that don’t seem like that to you?
Jaan Tallinn: Well, I don’t have enough information or signal. When you’re kind of like... I mean, he’s mostly doing marketing, right? And it’s hard to tell how much technical depth there is, but possibly there is. I just don’t know.
Mario Gabriele: Would you agree with the principle or the idea that there are technologically deep people who have the opposite view, that there’s no alignment risk?
Jaan Tallinn: I don’t think I know any of them. I do know people who think that there is risk, but they don’t care. Like successionists, basically, who want to get rid of people.
Mario Gabriele: So then your view would be, let’s take, I would put in the acceleration camp someone like a Mark Zuckerberg, Marc Andreessen. You would say that probably all those folks are not sufficiently close to the technology to appreciate the risks. Or perhaps, in your view, okay. You would say they don’t understand it enough.
Jaan Tallinn: Yeah. I think that’s a more general common denominator where people who are dismissive just underestimate what they can do. I mean, probably three weeks ago they thought that AI cannot do anything on its own initiative, stuff like that.
Mario Gabriele: If that’s true, if we say, hey, these folks actually genuinely don’t understand it clearly, they know all about the Hugging Face attack, all these sorts of moments. What does one have to do to start to appreciate this deeply? Or is there just a deep philosophical misalignment that stems further back than this technology?
Jaan Tallinn: Well, I think that there always will be people who will say, “Look, there’s nothing to see here. It’s just a tool. It’s just math,” or whatever. So we have to live with a fraction of people like that. I mean, some of them are just motivated to say that because they want humanity to go away.
And some of them are just so incentivized locally because of benefits or whatever. So we have to live with the fact that there are people who say that. But also their minds are changing. And there might be something that’s called a preference cascade, where we’ve seen so many people say, “Actually, I wasn’t honest when I was saying that AI is not a risk.”
And now, the more people say that, I think it’s super great because then it gives a license to people: “Me too,” right?
Mario Gabriele: Mhm. Yes. People don’t want to be the first person to say something that is perceived as extreme, right?
Jaan Tallinn: Yeah. Considered socially awkward, outside of the Overton window. Yes.
Mario Gabriele: Yes. Right outside of the Overton window. One of the people I spoke to who asked for questions suggested I pose the following trilemma to you, which is, how do you think about charting a path between, one, the race dynamics between the leading labs; two, the labs potentially colluding and that potentially leading to regulatory capture?
And then three, the possibility of AI being nationalized. Those seem like three not-good outcomes, but how do you find a golden path?
Jaan Tallinn: What’s the first one?
Mario Gabriele: The first one was this race dynamic, where you just keep racing towards disaster.
Jaan Tallinn: Yeah, I agree. All of them sound pretty bad. Also, I think the second one is just very unlikely, or I think it comes from someone who underestimates what AI can do. I do think that ultimately the risk is AI, not the labs. Or the labs are just the ones that gave birth to this dangerous thing.
But yeah, between those, if I really had to hypothetically pick between those, I would pick nationalization. Ideally democratic control over that, of course.
Mario Gabriele: Is it possible to be a moral actor in a race dynamic?
Jaan Tallinn: I think so. Yeah. Well, I mean, you can always stop doing the race. I think more and more people are going, “Why are you doing this if you think this is going to kill you?” And, as Coxon said, you don’t have to.
Mario Gabriele: But the only way to stop in a race dynamic is with cooperation. Because if you then stop and someone else races...
Jaan Tallinn: I mean, if you really think that this thing is going to kill you, you don’t have to suicide in order to demonstrate that. The race is not a good excuse to suicide.
Mario Gabriele: But I think the argument would be, if I’m in a race with you and I think you’re a demon and I’m an angel, I don’t want to stop.
Jaan Tallinn: But I need some additional rationalization to continue to race. I mean, to be fair, there are some arguments. Anthropic’s argument always has been that in order to actually study the monster, we have to have access to it and have access to the strongest monsters, which is a framing where it does make sense.
And I think they have done a non-trivial amount of that studying and alignment work. But again, they’re racing on a fundamentally unsafe paradigm. So at one point they should say, “Look, wait a minute. We need to go slower,” at least. Ideally, I mean, I would say we need a moratorium at this point.
But of course, they’re not going to say that at this point. But they’re now saying that we have to go slower, which is commendable.
Mario Gabriele: I think they’re saying that. And well, let’s take it step by step, I suppose. Dario had his “Pacing the Frontier” piece, where he laid out a framework for what that might look like. Did that go far enough? What’s missing from it, in your view?
Jaan Tallinn: I think that this is just fundamentally unsafe. The current paradigm is fundamentally unsafe. Myself, I would have stopped earlier, which, in retrospect, is a mistake. I think the current models are net positive. You never know what generation is going to escape control, and then you just lose.
Mario Gabriele: Because, as you think, we may have... Yeah. Well, it’s not a game we’re going to have many chances to learn from.
Jaan Tallinn: Exactly, exactly. We’re pulling a trigger on this Russian roulette with the planet. And every shot that doesn’t kill us will make us stronger, potentially, and wealthier and better off. But when do you stop pulling the trigger? Right. At one point, you know that it will be one too much. So, yeah, let’s just stop pulling the trigger right now and figure out what is a better, more controllable approach to AI in general. And there have been suggestions. Now Yoshua Bengio has this idea of Scientist AI that is deliberately trying to tease out agency from AI.
So it’s a principled approach to how you can make non-agentic AI.
Mario Gabriele: Hmm. Okay. I haven’t read about that. That’s sort of the idea of a drugged tiger in some way. Yeah.
Jaan Tallinn: It’s basically an oracle done properly, where you can ask the oracle. The big problem with a naive oracle, doing it naively, is that the oracle still has preferences. It prefers giving answers that come true. But if it has just this preference, it is incentivized to make sure that it’s going to be asked simple questions.
Which means that it’s incentivized to mess with the world. However, Yoshua’s approach, the way I understand it, doesn’t have that flaw. Basically, truly, the oracle doesn’t care what will be done with the answers.
Mario Gabriele: And is this an AI that is explicitly non-agentic, something you literally visit as an oracle and ask for advice rather than something that can do things for you?
Jaan Tallinn: Yeah. Yeah, exactly.
Mario Gabriele: Do you think we’re too late for that in some way? Because it’s already ingrained. These agentic systems already exist.
Jaan Tallinn: Yeah, yeah, but the systems, as we’ve seen, are just fundamentally unsafe. The current generation that is publicly visible, again, the ones that are actually top, only the companies know what they are, I think, even agentic, they are kind of net beneficial.
Basically, what I’m saying is that at one point, and I think the point is now, we should switch to a safer paradigm.
Mario Gabriele: Yeah, I see. So almost another path down the tech tree. You will keep the existing capabilities frozen. And then you say...
Jaan Tallinn: Exactly.
Mario Gabriele: You chase this ultimate oracle, or...
Jaan Tallinn: Something else. Bengio’s project is just one alternative proposal.
Mario Gabriele: You mentioned, in the past you’ve called for a pause. I think one time in 2023. Right?
Jaan Tallinn: That’s right.
Mario Gabriele: Do you think, in hindsight, that was a mistake, you would say, because...
Jaan Tallinn: It is.
Mario Gabriele: But it’s also probabilistic, right? Like, in theory, something could have gone wrong.
Jaan Tallinn: Yeah, I mean, with the information that we have now, yes, we shouldn’t have done it, but we didn’t have that information back then, right? So I think on priors, it was not a mistake. Of course, it could have been done much, much better. One problem that we had was that there was some big news in the air.
I think it was Trump impeachment or something like that, maybe, and we were like, okay, if we’re going to wait more with it, we’re just going to be buried.
Mario Gabriele: I see.
Jaan Tallinn: So we didn’t have enough time to consult enough people, etc. That was an unfortunate effect of trying to optimize for visibility.
Mario Gabriele: I think you’ve said before that you admire the thinking behind AI 2027 and the predictions there. How similar would your own view of the next few years be to what they’ve laid out?
Jaan Tallinn: Yeah, I mean, to be fair, I haven’t had time to actually look into all the details. I’ve only seen the summaries of AI 2027 and AI 2040, which is another, the positive vision. But from what I understand, they’re just spot on. Perhaps a little bit... The reality has been crazier and more aggressive than the predictions, even.
Mario Gabriele: Yes, it felt like until about three weeks ago, they were maybe lagging a tiny bit.
Jaan Tallinn: Tiny...
Mario Gabriele: And that’s, you know.
Jaan Tallinn: That’s the thing. You can’t confidently say exactly what’s going to happen and on what date. So that’s why the predictions are also probabilistic. But yes, AI 2027 seems to be the best prediction about what the next years are going to look like, unless we change something.
Mario Gabriele: I think you have said before that you were one of the first investors, or maybe the very first investor, in DeepMind.
Jaan Tallinn: I did a bridge loan between Series A and B. I missed the Series A by two weeks or something.
Mario Gabriele: Oh, wow. Okay. A bridge loan. But it happened because you approached Demis at a conference. Is that right?
Jaan Tallinn: Yes.
Mario Gabriele: Did you know what he was doing at that point? What was that first encounter?
Jaan Tallinn: They were presenting in Oxford, him and Shane Legg. We might have had some contacts before. I’m not sure. But they were making this point that, look, AI is our next exponential. Compute is on an exponential, at least.
Mario Gabriele: Yes.
Jaan Tallinn: And so if we want to replicate the most valuable thing on this planet, which, I mean, the tagline used to be for a while: “Solve intelligence and then use it to solve everything else.”
We need to ride this computational exponential and combine it with neuroscience, because human brains are a proof of concept that human intelligence can be done. So that was the goal: combining computer science, neuroscience, and then riding the right exponential.
And to make the case... Well, and I think I might have had some background about them before. So I just went up to them. I was like, “Hi, I’m here. Do you want to talk?”
Mario Gabriele: And they needed a bridge loan.
Jaan Tallinn: Yeah, yeah. It was a general sort of thing, right? If you miss a round, then you can invest in the next round.
Mario Gabriele: I see.
Jaan Tallinn: By the way, saying bridge loan is actually a wrong term. Convertible note is the correct term.
Mario Gabriele: I got you. Yes. And then your venture fund that you’re associated with, Metaplanet, led the first round into Anthropic. What was that rationale like? Was that a very easy check to write? Was that one that you agonized over for perhaps any number of reasons?
Jaan Tallinn: A little bit. Yeah. Yeah, I get this question a lot: why did you invest in Anthropic substantially at the point where I’ve been working on AI safety and worrying about this thing for a while? And I think one big mistake that people make is that they assume that if I hadn’t invested in Anthropic, then Anthropic wouldn’t be around, which is just not true.
In fact, I asked Dario to get alternative proposals from VCs so I could have quantitative... have confidence that, no, I’m just displacing VC money. I’m not bringing this into existence.
Mario Gabriele: That must be one of the rarest approaches in a venture round, where you’re saying, “I almost, in some part of my brain, hope these guys can’t raise any money, because then I can put them out of business.” Yeah, rather than put them into business.
Jaan Tallinn: Yep, yep, yep. Yeah. So the first round ended up being basically non-capitalist money. So that’s one thing. There is a counter to that, which I agree with, that in some way it mirrors this race dynamic: if I don’t do it, the others will do it.
Right. So in some ways it would be ethical to just stop it. The answer to that I have is that you shouldn’t look at the Anthropic investment as a single thing that I do. It’s what I do with this influence and what I do with these proceeds. If I have fewer resources, I would also have less ability to fund safety because I invest my own money. I’m not responsible for other investors, so I don’t have to maximize my net worth. Really, I can just make money and then spend it on something that I think is helpful.
Mario Gabriele: That suggests to me that you also, in that case, believed that this was likely to be a good investment in some way beyond just the moral claim, that it might actually deliver a return such that you could then use the proceeds.
Jaan Tallinn: I didn’t know that. Because I also invested in Bitcoin and Ethereum way back, the fraction that I invested wasn’t a big bet from my perspective at that point anymore. Dario has said, “Look, we’re not in the business of making money for our investors, but we might not help but do so.”
So, yeah, it definitely wasn’t a financial goal that I had back then.
Mario Gabriele: And you had known that team for quite a long time. I think I found something back in 2011, almost.
Jaan Tallinn: I think I met Dario in 2012.
Mario Gabriele: Okay.
Jaan Tallinn: I definitely remember hanging with him in 2012.
Mario Gabriele: Oh, what do you remember? Do you remember those first conversations? Were you both seeing the future the same way?
Jaan Tallinn: I don’t remember much. I think later conversations I remember better because I’ve been traditionally of the MIRI, Machine Intelligence Research Institute, mindset that, look, this is a fundamentally flawed approach, and we need to figure out what was initially called friendly AI.
Mario Gabriele: Yes.
Jaan Tallinn: Or aligned AI, because there isn’t really a law of physics that says that you can’t have an AI that actually cares about the same things in the future that we care about, or we should be caring about.
Mario Gabriele: Yes.
Jaan Tallinn: But Dario was vehemently against that kind of mindset and was more in the empirical camp that, look, these are theoretical arguments from this armchair philosophy.
We really need to do experiments. We need to basically be in the trenches, so to speak, to actually learn about how to steer this machinery. And I think they were interesting points that he made. And I think he now has said that in 2018, I think, he wrote this private essay called “Big Blob of Compute,” which I read, which was very impressive.
Basically, yeah. He just took Richard Sutton’s “The Bitter Lesson” and ran with it, that as long as you have this compute exponential, that will basically take you most of the way. You don’t need to be super inventive about the exact techniques.
Mario Gabriele: When you read about the big blob of compute, it was impressive to you. Was it also vaguely terrifying?
Jaan Tallinn: Of course. Yeah, of course. Yes. Because actually, the one thing that I thought back then was, “Crap, this is an engineering problem. This is not a science problem.” Which means that the AI will be Chinese because they are way better engineers than the people in the West. And so it’s like, I need to go to China, which back then I did.
Mario Gabriele: And what did you do?
Jaan Tallinn: I just visited their conferences, and I talked to people. I didn’t do anything. I mean, I don’t know exactly how to, but just talked to people there. But that was one of the thoughts that I remember. Yeah. So I’m kind of surprised that it wasn’t actually the Chinese who ran with this.
Mario Gabriele: I would have the same concern if that ended up being Chinese. If you had that concern, you also would go visit, but you also wouldn’t want to outline the thesis necessarily too clearly as part of that. You’re both looking for information.
Jaan Tallinn: But, I mean, my... Okay. There’s a general strategy, or meta-strategy, that I have. I really prefer symmetric strategies to asymmetric strategies. A symmetric strategy is basically a strategy where you don’t really care if others mimic it. So even going to China, I’m not going to try to mislead them or anything. I’m just saying the things that I wish everybody was doing.
So, yeah, just be aware that AI can be way more capable. In fact, one thing I remember specifically in China, arguing with people, was that back then they seemed to completely confuse competence and consciousness. So their model seemed to have been that AI gets more and more competent, and at one point it will be conscious, and then it will be just like us.
I’m like, no, no, no, no, no, guys, this is not how anything works. You can have very competent machines that are not conscious.
Mario Gabriele: Probably.
Jaan Tallinn: Yes. It’s not obvious why they should be strictly coupled. So basically saying things that I think are true everywhere, which are in the common interest. That has been my strategy.
Mario Gabriele: What would be the asymmetric version of that game, in that sense?
Jaan Tallinn: Oh, there’s export controls, things like that, or being there first. If your strategy is that you need to race, you really care that it’s you that’s racing, you that’s winning, rather than the other side. So it’s a strategy that relies on the good guys, so to speak, following the strategy and the other ones not.
Mario Gabriele: The more empirical view, let’s say, that Dario was advocating: how much of that have you come to agree with as the right path forward? It seems like you agree with pieces of it.
Jaan Tallinn: Yeah, definitely. So I do think that there is a really important, I wouldn’t say flaw, but a weak point in this MIRI argument, which is that it’s an asymptotic, at-the-limit argument that once you have something that is clearly superhuman, we just lose. We have no control over what happens next, which I think is just true.
This is kind of obvious.
Mario Gabriele: It’s almost baked into the definition.
Jaan Tallinn: It’s almost tautological, right? At that point where we don’t have control over what it wants. As my friend Andrew says, the future probably will not have configurations of atoms that constitute human bodies. The weak point, I think, is that before we get there, there’s this period during which we have roughly human-level AI, which we seem to be living in now. And I think Eliezer even has admitted, I think, that he underestimated the range of human capabilities. I think Katja Grace of AI Impacts, they at one point pointed out that, look, it took AI ten years to traverse human capabilities of chess-playing, from starting to be competitive with humans...
Mario Gabriele: Yes.
Jaan Tallinn: ...until confidently beating the grandmaster. So the same thing might happen in different areas. So there’s a period, much less than ten years, but still probably, possibly measured in years, during which we cohabit this planet with AIs that still can be bargained with, let’s put it that way.
And the future might be very sensitive to what happens during that phase, which I agree is a point for this empiricism. But it’s also super dangerous to find yourself in that phase.
Mario Gabriele: We mentioned earlier the idea that you would want to pause the capabilities where they are now until we get things under control. When would you know it’s under control enough? What would that look like?
Jaan Tallinn: I don’t know exactly, but it probably has to do with some kind of verification regimes, etc. People point out things like aviation or nuclear safety, where you just have these verifiable claims about how safe your nuclear reactor is, or how safe your airplane is.
And they’re not like, “Oh, we think it should fly. It’s like 70% that it will fly.” They’re actually grounded in some kind of verifiable, composable claims. So if you could get to something like that... But I don’t know exactly how it would look. There should be some kind of building blocks that we can individually verify and then put together.
But of course, it’s a global issue. So it’s not just one product’s safety. It’s a global regime. But we’ve done it before with nuclear proliferation, for example.
Mario Gabriele: The UN is meeting to discuss these topics. Do you feel optimistic that there is a possibility for global coordination on this?
Jaan Tallinn: Yeah, yeah. Especially now, in the last two weeks. It’s been my wet dream for a long time to actually have the UN and countries separately just going, “Wait a minute. We might lose control of AI. We need to do something about it.” Now, I really wish that was... In some ways, I’ve been comparing this to an alien invasion.
I’ve been thinking about what countries and the UN would do if there’s an alien ship of superior aliens.
Mario Gabriele: It would be tricky. It would be, if the aliens also make a lot of money for people, and a lot of people...
Jaan Tallinn: Sure. I’m pretty sure there will be countries or groups of people, I mean definitely groups of people, saying, “Just take us,” right?
Mario Gabriele: Yes.
Jaan Tallinn: Yeah. And there will be countries who are like, can we get this alien technology before the others? Can we make sure that they land within our borders, etc.? So I think it’s pretty similar. But on the other hand, it’s much more intuitive to us as a scenario than these digital aliens that are much more different. In fact, I was just yesterday at a meeting where somebody basically said very reasonable things, that we need to figure out how to deploy AI, and at the same time how to make sure that there are guardrails.
And then went into talking about loss of control and making sure that it remains under human control. I was like, yep, yep, yep. Super nice to hear. Then he said, “In the end, we need to protect our digital future.” I was like, “No, this is not just digital.” I think that’s the really big current mistake that a lot of people now make, that the worst thing that possibly could happen is something going wrong on the internet. It’s like, no, it’s not the internet.
Mario Gabriele: And to make that clearer, we’re now seeing a lot of these inflections in robotics, where you’re seeing the ability for these models to generalize in the physical world. And so that’s the version where, yeah.
Jaan Tallinn: One way of putting it, too, is that the economy is really now pushing to create digital life, something that is self-sustainable without human help. And that is a very dangerous place for humans to be.
Mario Gabriele: Let’s say we get every government that we would need on board, which at the moment I suppose is realistically America and China, right, to lead the way on global cooperation. How do you implement the needed oversight, surveillance, to make sure people don’t cheat this in different ways?
Jaan Tallinn: There’s a lot of momentum now behind hardware verification. I mean, one thing is that AI 2040 outlines the interesting idea that China would build their data centers in Canada, and the US would build their data centers in Mongolia. Yeah, yeah. So you would be vulnerable... better visibility to the other side.
Mario Gabriele: That’s interesting.
Jaan Tallinn: Yeah, I think that’s an interesting idea. But there’s another approach, which is hardware verification. You can basically have hardware monitors, ideally even in chips, but also in data centers, of the other side. So instead of sending a lot of human inspectors, which you also might do...
Well, that was a crux of the nuclear treaty: basically you send, or have a presence of, hardware controls, hardware monitors. And the interesting thing about hardware monitors is that you can shape them almost arbitrarily. You can do things like zero-knowledge proofs, where the only bit that you get back is that everything is in order.
No rules are being violated. But of course, the more constrained you want them to be, the more sophisticated they have to be, which means that more work needs to be done in order for this scheme to be trusted in the first place. But in principle, you can do wonderful things with zero-knowledge proofs and advanced cryptography. Blockchains are using quite advanced versions of this now.
Mario Gabriele: Yeah. I hadn’t read that, or I don’t remember that from AI 2040, but that feels like kind of an ideal use of zero-knowledge proofs. For someone who doesn’t work at an AI lab or in this world necessarily, but shares your concerns, what should the average person do?
Jaan Tallinn: I mean, in democracies, or perhaps elsewhere as well, just voice their concerns: “Look, we don’t want to be replaced by AI, even if it’s profitable for some people.” And basically stop the madness.
Mario Gabriele: You list a series of AI priorities on your website, and one of them is having a kill switch. What does that look like?
Jaan Tallinn: Yeah. The priorities, to be clear, are now two and a half years old or something like that. So I’ve been wanting to refresh them for a while. We’ll see. I mean, I guess that’s the natural thing to wish. And in fact, there are multiple legal, regulatory initiatives to mandate that.
But a kill switch that’s well done is more like a dead man’s switch. It’s something that keeps the system, the data center or whatnot, alive as long as some criteria are met. So once you detect some kind of anomalies, it will just turn off the system, electricity or something like that.
Mario Gabriele: Presumably that is only useful in this intermediary period before we have a superintelligence?
Jaan Tallinn: Yeah, of course. Yeah, yeah. I mean, superintelligence doesn’t need... Superintelligence doesn’t need data centers.
Mario Gabriele: Doesn’t need data centers? Hang on. How would that operate?
Jaan Tallinn: I mean, I don’t know exactly. I’m not superintelligent, but data centers are just a substrate that humans create. Probably a very suboptimal substrate for something that is superior. I would imagine some kind of self-replicating nanomass or something like that, that is just much more efficient at performing computation and expanding computation than human-created CPUs and GPUs.
Mario Gabriele: Okay. Very interesting. I always like to ask a few people who know a guest for questions I should ask them, or quirks of their personality that might not be as obvious. Here’s what someone said about you: “I cannot stress enough how central dancing is to Jaan’s identity.” Tell me about that.
Jaan Tallinn: Yeah, I got into dancing about 20 years ago, and just an amazing amount of fun that I have discovered from that. But I do freestyle street dance. I’ve been to hundreds of clubs, just making... One way of putting it is that if you see people doing street dance on the street for money, I do a similar thing in nightclubs for attention. And it’s just a really positive-sum game because you’re entertaining other people, and you get really fun feedback. Sometimes I joke that I’ve learned to dance using reinforcement learning from human feedback.
Mario Gabriele: Yes. You have. That’s amazing. How did that originate? Was that just going out?
Jaan Tallinn: So I kind of had it during my Skype days already. I was in my early 30s, and most of the people were in their 20s. So there were a lot of wild nights, including going out to nightclubs, and then at one point I discovered, wait a minute, I actually kind of like this dance thing. And then at one point I started getting positive feedback from people: “Oh, do you know how to dance?” I was like, “Oh, I should do more of that.” Then at one point I got a dance coach in the UK, in London, and we became very good friends. So sometimes we go together and just perform.
Mario Gabriele: In one of the stories about the history of Skype, they talk about the five-phase Skype, where it’s dinner and dancing and...
Jaan Tallinn: Yes, karaoke stuff.
Mario Gabriele: Yes, yes. That’s right. There’s something else in there. What makes for an amazing place to dance?
Jaan Tallinn: In my case, it has to have space. Quite often, places are getting too packed. Then it has to have light. Especially in London, I think post-COVID the places are just way too dark. I really don’t like London for dancing anymore. And I like hip-hop and pop. One reason why I like pop is that it has lyrics that people know.
And one way of describing my dance style is that it’s making NP moves. If you know, NP versus P is the most famous computer science conjecture. And without going into details, basically NP moves means you’re making moves that are hard to do but easy to interpret.
Mario Gabriele: Mhm. Okay. Well, I should know about that.
Jaan Tallinn: And one classical NP-hard problem, so-called NP-hard problems, is constraint satisfaction, which means that you’re given some kind of criteria, and then you need to produce a solution that satisfies those criteria. So in dancing, examples of that are in harmonics. You try to do a sine wave.
Mario Gabriele: Yeah.
Jaan Tallinn: Okay. But the most fun constraint to satisfy is the lyrics. So you basically take the lyrics and act them out.
Mario Gabriele: If you think of one place you most love to dance, or if you have your last night on earth to go to, do you have a place in your mind?
Jaan Tallinn: Yeah. Tokyo. I have two places in Tokyo that I really have liked. One of them is still there, but that’s a weekday place. But a weekend place didn’t survive COVID, which is very unfortunate.
Mario Gabriele: The weekday place, what makes it so special? Has space, has light?
Jaan Tallinn: Yeah, yeah. And has multiple rooms. So you can pick your music. And Tokyo is so big and concentrated, it has big parties every night. Whereas in New York, which also used to be basically my second-favorite city to dance, I think it now has gotten much quieter than it used to be.
Mario Gabriele: Also post-COVID.
Jaan Tallinn: Maybe. Yeah, post-COVID. Oh my God. My favorite place in New York, Pianos bar.
Mario Gabriele: Yeah, I know exactly that place.
Jaan Tallinn: I mean, that’s so funny. I’m only half-joking, saying that’s the only place in the world where I’m guaranteed not to be the best dancer when I go there.
Mario Gabriele: Yes. All right. Wow.
Jaan Tallinn: So it has always had amazing dancers. But last time I went there in January, it was just really quiet, and nothing was happening.
Mario Gabriele: Huh. There’s this Alan Watts talk where he talks about how life is best conceived of as a piece of music or a dance, where the point of a dance is the dancing. You would never start a dance and say, “I’m going to end up at this part of the floor.” To have a goal is in some way beside the point.
Do you agree with that?
Jaan Tallinn: Yeah, yeah. I think it separates freestyling versus choreography. And quite often, many dancers can do really amazing choreographies, but when you just put them to, “Let’s go out and freestyle,” they just sit there and drink, which I find a lot of missed opportunities. Whereas I’m not actually good at choreographies. I find it hard to remember the moves.
Mario Gabriele: But he was making the point about life being that way, that you shouldn’t have a goal, like to have an aim in life. To aim at something is sort of, in a way, pointless, because the point is the living.
Jaan Tallinn: I don’t agree. I would disagree with it. What it reminds me of is that there’s this thing called backwards chaining versus forward chaining. So forward chaining is that you’re basically going to live in the moment and see what kind of opportunities you get, but you still should have some kind of goal in mind, or something to judge opportunities, or some kind of preference at least.
Otherwise, you’re just doing random things. And backwards chaining is when you have a goal and can see what kind of steps towards that you can take. You can think of a chess game. Are you in the early game, where you just try to forward-chain towards a better position?
Or are you in the late game, where you try to actually get a win because you can see all the opportunities towards it?
Mario Gabriele: Your father, I believe, lived a very musical life, right? Wasn’t he a TV director?
Jaan Tallinn: He was a TV director, and specifically he did music videos and music programs.
Mario Gabriele: Was that a big part of your childhood, to have music around all the time?
Jaan Tallinn: Kind of. Yeah. Also my aunt, my father’s twin sister, was a piano teacher, and my paternal grandmother was an organist in a church. I actually grew up on a church estate. So, yeah, music has been in the background, at least.
Mario Gabriele: I read somewhere that one of the things he worked on was, I think, an interpretation of the book by Hermann Hesse, The Glass Bead Game. Is that right?
Jaan Tallinn: That sounds right. Yeah, yeah, yeah.
Mario Gabriele: I raise it because it feels like that’s... I don’t know if you’ve ever read that book, actually. It’s sort of a synthesis of intelligence through a story. And in many ways, there’s some deep connections, I think, to the current moment.
Jaan Tallinn: Interesting. I didn’t know that. Yeah, I do remember, in Estonian it’s called Klaaspärlimäng.
Mario Gabriele: Yeah, yeah. I had that written, and I thought, gosh, I don’t even want to attempt my pronunciation there. But maybe you’d enjoy it. You have a list of some of your favorite movies on your website. What’s the best movie that you’ve seen in the last year? Because I know your favorite is Before Sunset, is what I remember.
Jaan Tallinn: Oh, that’s one of the favorites. Yeah. It’s really, really cool. I haven’t updated it for a couple of years. I haven’t had a lot of time to watch new movies. And the ones that I watched, I don’t think any of them stand out.
Mario Gabriele: What was the last one that you remember being impressed by?
Jaan Tallinn: Look at that, look at this... It was a couple of years ago, so I don’t actually remember exactly. Oh, actually, I mean, obviously I did like all this stuff. Okay. Yeah, yeah, yeah. I’m kind of on the edge whether it’s good enough to put on the website, but I probably...
Mario Gabriele: I haven’t seen it. Yeah, I reckon I should see it. Is there a film that you find yourself coming back to because of some of the problems here? It could have absolutely nothing to do with technology, but perhaps just speaks to some of the themes that we’re engaged with around control and humanity.
Jaan Tallinn: I mean, there are several movies. They all kind of have to do with technology in one way or another. Limitless was interesting. I remember, ten-plus years ago, where you just had a pill to make someone more intelligent, then what happens. That was a really, really fun movie.
Then the various warning movies, like Ex Machina, for example. It was very impressive, just demonstrating one aspect of not caring about humans in a very tangible way, which was really, really cool.
Mario Gabriele: And scheming.
Jaan Tallinn: Yeah. Yeah, yeah, yeah, yeah, yeah. And the classic The Forbin Project. Colossus: The Forbin Project.
Mario Gabriele: I haven’t seen that.
Jaan Tallinn: Yeah. This is from the ‘70s, I think.
Mario Gabriele: Ah, The Forbin Project. Forbin?
Jaan Tallinn: Yeah. Forbin, which was basically two supercomputers, a Soviet supercomputer and a US supercomputer, suddenly figured out that, actually, “Why do we need these humans?”
Mario Gabriele: Do you ever allow yourself, or find yourself, feeling optimistic about what AI will be able to do?
Jaan Tallinn: Oh, yeah. I mean, I have my own coding projects, etc., and it’s pretty awesome to just be able to... I mean, I worked for years on several software projects, either on my own or with various software development groups. And in the last year, I’m making a lot of progress just because those projects that I have to do on my own, with the AI, are actually kind of finished, and it just mostly works.
And then on the projects that I do with other groups, I often can, instead of having this cycle of, oh, there’s a bug, I don’t want to give them my data, which means there has to be this interaction that takes weeks to figure out what the bug is with my data, I can just tell the AI, again without necessarily giving it all my data, but in a surgical manner, “Look, there’s this bug. Figure out what this bug is,” or, “I want this tiny change.”
And this has been really good.
Mario Gabriele: What’s the best thing that you’ve built, or the thing that you’ve most enjoyed building, in this new era of engineering?
Jaan Tallinn: I mean, it’s still in the building phase. So I’m not... I’m getting there. In Skype, the IM part was kind of my baby.
Mario Gabriele: Yeah.
Jaan Tallinn: I fought really hard for the advancement of it, but it was always in the back seat because Skype was about video and voice. At one point, I funded a startup by Skypers who were trying to do IM properly, but they ended up wanting to do Slack, basically.
Mario Gabriele: Okay.
Jaan Tallinn: And they didn’t have any hope against Slack. But over those years, I collected a bunch of ideas about how to do IM and email properly.
Mario Gabriele: Oh, okay. That’s interesting. What’s wrong with the current state of play? Because you’ve been thinking about this now for 20 years, right?
Jaan Tallinn: Twenty-plus years. Yeah. Yeah, yeah. I mean, there’s so many things wrong. Again, this is a 40-minute lecture now. And many people are going to try to solve this: have a single interface to your communications rather than all these different media.
Mario Gabriele: Yes.
Jaan Tallinn: Beeping things that have their own rules. And usually the rules are optimized for getting your attention rather than making you productive.
Mario Gabriele: Yes.
Jaan Tallinn: So have your own interface to do all of it. A really big problem with unifying IM and email into the same interface is that you start running into different security paradigms. There are two types of context in communication. One is what I call semantic context, which is what this thing is about.
What is the topic? What are the previous messages, etc.? And Gmail innovated on this pretty well. They just created these email conversations. Before that, it was just letter, letter, letter, letter.
Mario Gabriele: Yes.
Jaan Tallinn: So semantic context, email solved to a significant degree. And as a result, Gmail enjoyed a lot of success eventually. But there’s another context, which is security context, which is basically who can see this. And these two contexts are quite often in tension. So when there’s an existing thread, if you add a new person, the security context changes.
But the semantic context is the same. Now, the question is, what do you do in this situation? In IM, usually the security context is dictated by that so-called channel, and messages go into the security context. Whereas in email, at least in native email, every message just comes with both.
There’s a letter that has the topic and the quotes, which is the semantic context. And then the participants in the To and CC lines, etc., which is the security context. So fundamentally, the composing blocks are different. So how do you unify that? And I’ve been thinking about it a lot.
And currently it seems to be going pretty well.
Mario Gabriele: Oh, wow. Interesting.
Jaan Tallinn: At least for my taste. Yeah.
Mario Gabriele: Yeah. No, that’s very cool. I’m always an early adopter of these unified text things because I have the same thing where I’m just like, I want it in one. Yeah.
Jaan Tallinn: I mean, I would be happy to share this thing. Currently, I’m just developing it for myself. One thing that stops me, and I haven’t figured out how to share this: I don’t want other people’s data, so I don’t want to be responsible for safeguarding other people’s data.
Mario Gabriele: Yes.
Jaan Tallinn: So I need to figure out how to do it in a way that can be shared, but in a way that I don’t actually get to see your data.
Mario Gabriele: Well, as soon as you figure out how to share, I would love to be a user.
Jaan Tallinn: Cool, cool.
Mario Gabriele: And that’s amazing. I think that’s as good a place as any to end.
Jaan Tallinn: Yeah.
Mario Gabriele: Thank you so much. This is a real pleasure.
Jaan Tallinn: It was really fun. Yeah. Thank you. Thanks for having me.
Mario Gabriele: Amazing. That’s it. Thank you for listening to this episode of The Generalist Podcast. Please subscribe on Apple Podcasts, Spotify, or your preferred podcast app. Ratings and reviews help others discover these discussions, so if you enjoyed the conversation, I’d be grateful if you could take a moment to leave one. For all past episodes and more, visit us at The Generalist Substack. See you next time as we continue to explore the future.
2026-09-29 20:04:23
“Most AI has been trained on the final artifacts of science, like the final paper, the final recount in a textbook. That isn’t often how the scientific process unfolded – it’s sort of a retelling of the story.” –Liam Fedus, Co-Founder of Periodic Labs
Liam Fedus and Dogus Cubuk are the co-founders and co-CEOs of Periodic Labs, a startup building “synthesis superintelligence.” In practice, that means an AI system that closes the loop between hypothesis, experiment, and learning.
Liam previously led post-training at OpenAI, where he was one of the creators of ChatGPT. Dogus spent years at Google DeepMind leading a large team of chemists and materials scientists. Together, they’ve brought those two trajectories to bear on a problem that has stymied science for decades: not just discovering new materials, but making them reliably and at scale.
In this conversation, we explore the limits of language models, the commercialization bottleneck in materials science, why Periodic chose high-temperature superconductors as its first target, and what Liam learned from watching ChatGPT go from an internal product to one of the most successful products of all time.
We’re trying a new thing where I share a few of my thoughts from after the episodes. The moments that struck me, the tidbits that reframed my thinking, or something I just really enjoyed. Let me know if you like reading these!
To do science you have to do science. This is Periodic’s conviction in a nutshell. Science is the discovery of new things; you cannot prove it in a corpus of existing information. It has to involve trial and error in the real world.
Sci-fi remains an endless source of alpha. Why did Periodic set an initial goal to discover a new high-temperature superconductor? In part because ~every sci-fi future features it. (It also doesn’t hurt that it’s stayed top of mind in condensed matter physics.)
I underestimated the gap between discovery and utility. It can take 10-20 years for a new material to get to industrial scale. This feels like an equally important place for AI. We don’t want a century of discoveries stuck in twenty year manufacturing bottleneck.
Virality is ~impossible to predict. With the benefit of hindsight, it’s insane to hear Liam say that people inside OpenAI expected ChatGPT to attract tens of thousands of users. Perhaps the closer you are to something, the harder to know how useful it will be.
Capability ≠ virality. Another interesting wrinkle on the ChatGPT story. Liam said that they had a stronger internal model that hadn’t gone viral internally. ChatGPT used a weaker one!
Towards fuller observability of science. When humans conduct experiments, they write up the parts they believe matter. The ‘useless’ data you generate at every other step is discarded. This feels like one of the coolest parts of Periodic’s approach. In theory you can capture the full experimental trace.
Little things are big things. A bunch of samples get mislabeled in a lab. Usually, that would take a bunch of irritating human time to unwind. At Periodic’s lab, AI found it and fixed it.
“Contamination-free” RL is sort of an experimental veil of ignorance? Liam talked through one of Periodic’s advantages, which is constructing “snapshots” of experimental states. They can then ask: “What should we have done next?” This is possible because they have a corpus of fresh, untainted data. As a result, the model hasn’t inherited the right answer.
Listen on YouTube • Spotify • Apple Podcasts
What I’m into this week:
Nuclear War: A Scenario by Annie Jacobsen. Reading for…oh, no reason.
DJI Mic Mini plus WisprFlow is a pretty perfect combination for dictation.
Instinct is the best AI proof of concept I’ve seen in ~6 months. Good reasons to tread lightly, but the utility is incredible
—Mario
(00:00) Intro
(02:05) Periodic’s mission
(03:14) What it takes to build a synthetic superintelligence
(04:48) Why “thinkism” falls short
(05:46) Why Periodic is pursuing high-temperature superconductors
(07:21) How Heike Kamerlingh Onnes discovered superconductivity
(09:36) Why synthesizing new materials is so difficult
(16:44) Dogus’s path to AI
(20:18) Liam’s path to AI
(23:28) Lessons from launching ChatGPT
(25:24) Why Dogus and Liam chose each other
(27:01) How Periodic attracts top talent
(29:50) Inside an experimental loop at Periodic
(35:10) What AI learns across experiments
(40:10) What Periodic builds versus buys
(44:37) Balancing diversity and depth across experiments
(49:23) The difference in LLM performance on math vs. science
(51:26) Why Periodic doesn’t depend on better models
(53:20) Periodic’s short-term goals
(54:09) The competitive landscape
(55:39) Final meditations
The Beginning of Infinity: Explanations That Transform the World (recommended by Liam): https://www.amazon.com/Beginning-Infinity-Explanations-Transform-World/dp/0143121359
Subtle Is the Lord: The Science and the Life of Albert Einstein (recommended by Dogus): https://www.amazon.com/Subtle-Lord-Science-Albert-Einstein/dp/0192806726
Periodic Labs: https://periodic.com
Bell Labs: https://www.nokia.com/bell-labs
Google DeepMind: https://deepmind.google
Google Brain: https://en.wikipedia.org/wiki/Google_Brain
OpenAI: https://openai.com
LinkedIn: https://www.linkedin.com/in/liam-fedus-26547811
LinkedIn: https://www.linkedin.com/in/ekin-dogus-cubuk-9148b8114
I’d love it if you’d subscribe and share the show. Your support makes all the difference as we try to bring more curious minds into the conversation.
Production and marketing by penname.co. For inquiries about sponsoring the podcast, email [email protected].
Mario Gabriele: AI has gotten very good at writing software. That’s no accident. After all, code has an answer key — a computer can check it in a fraction of a second. The program either runs or it doesn’t. Physics has an answer key too. The physical world too, but consulting it means running actual experiments, something an AI model can’t do on its own.
Liam Fedus and Dogus Cubuk are building a company to change that. They are the founders of Periodic Labs, a startup building infrastructure to create what they call synthetic superintelligence. Liam previously led post-training at OpenAI and was one of the creators of ChatGPT, while Dogus was a research scientist at Google DeepMind.
They’ve brought their experience together to build what might be described as an AI scientist, capable of conducting thousands of experiments a day and learning from each one of them. In this episode, we discuss the limits of LLMs, why science is so hard, and what Liam learned from launching ChatGPT.
I’m Mario, and this is The Generalist.
Mario Gabriele: I’m really excited to have you both here — I’ve been really looking forward to this conversation. I think you’re building such a fascinating company, so maybe we just start there. Tell me a little bit about Periodic. What are you trying to do?
Liam Fedus: Our goal is to build a system that can intentionally synthesize matter — we’re calling this synthesis superintelligence. Our core belief is that in order to do this, you need to make connection with the real world. A system like this isn’t going to emerge just from reading textbooks and papers.
It’s really necessary to use simulations, model the physical world, but then actually carry out the experiments. Thinking alone is not enough. It’s necessary to get new information from the world, conjecture how it might be, get the experimental results back, and do this end-to-end loop. By training end-to-end against the physical world, new types of intelligence and AI systems will emerge.
So rather than a system that’s just been trained on the body of final scientific literature, it’s trained on the scientific process itself. Rather than knowing the state of science, it knows how to do science.
Mario Gabriele: I’ve heard one way you’ve maybe described the mission in the past is almost to build an AI scientist, and decomposing the different pieces of that puzzle through that lens. How do you think about, fundamentally, what a scientist does, and what you need to replicate?
Dogus Cubuk: The traditional way to look at science is that you come up with a hypothesis, and based on the hypothesis you run experiments, and the experiments either validate that hypothesis or invalidate it, and then you update your hypothesis. What’s really critical for us here is the observation that science always tries to push the boundary of our understanding — which by definition means it can’t just rely on what we already know, because science is trying to figure out what we don’t yet know.
That’s almost at odds with the traditional description of machine learning, where a model trains on a training set and does well on a test set drawn from the same distribution. There’s a clear tension between what we call machine learning and what we call science.
That’s where we’re basically trying to make progress. How have humans gotten around this problem? Because at the end of the day, humans are also machine learning algorithms, and they’ve often figured out things they didn’t know before — they had to iterate, run experiments, write down a theory, get yelled at by reviewers, and then update.
Einstein had to do this. Bardeen had to do this. So we feel like AI will have to do it too. We’ve been spending a lot of time and focus on building labs where an LLM and a simulation can iterate together. That’s our goal.
Mario Gabriele: Liam, you mentioned this idea of “thinking” — for folks who maybe don’t know what that really means, can you tell us a little bit about it and parse the differentiation a bit?
Liam Fedus: I think it’s this concept that an AI that just thinks for a very long time — if you extrapolate the inference tokens well beyond anything we’ve seen — can just do anything. One of our deep scientific goals is to discover new high-temperature superconductors, and we don’t think a system trained the way models are trained today will think for a billion or a trillion tokens and suddenly arrive at a new high-temp superconductor.
We think that’s just not in line with how we’ve pushed knowledge and science forward historically. That’s kind of a core belief of ours: you need to connect it to the physical world and iterate. The data simply doesn’t exist otherwise. That’s how you actually build new knowledge, not just rehash existing knowledge.
Mario Gabriele: High-temperature superconductors — how did you land on that as the right first step for this company?
Dogus Cubuk: There are a couple of reasons — let me talk through a few of them. As Liam said, our goal is synthesis superintelligence, and if we can synthesize anything in the lab, we might as well synthesize the most impactful thing, which is a superconductor. That’s one reason.
Another is: think of any of the sci-fi futures you want to imagine. They often involve superconductivity — quantum computing, fusion, lossless transmission of energy. These all have superconductors somewhere in there. And there’s a sense in which superconductivity is the most macroscale quantum-mechanical phenomenon there is. There’s something very fascinating about it.
If you think about the history of condensed matter physics, it goes through these roughly seven-year cycles of what’s popular, and then it falls out of fashion — topological insulators, heavy fermion physics. It kind of matches the length of a PhD; these topics come and go.
Superconductivity is one topic that’s never gone out of style. Since its discovery by Onnes back in 1910, people have been fascinated by it, and we’re still fascinated by it today.
Liam Fedus: And in the pursuit of this, you have to build up such sophisticated simulation infrastructure and AI infrastructure — and that has a huge amount of generality.
Mario Gabriele: So it gives you the right stair-steps, and it’s also massively impactful.
Liam Fedus: Exactly. In the pursuit of this super-ambitious goal, you build up a huge amount of incredibly impactful technology.
Mario Gabriele: Dogus, I’ve heard you mention Onnes before. For folks who don’t know that history — what he achieved — can you tell us a little bit about why he’s an inspiration?
Dogus Cubuk: Yeah, absolutely — he’s an inspiration to us in many ways. In the 1800s, there was a big rush to liquefy as many gases as possible. Around 1850 or so, people liquefied oxygen, for example, and that ended up playing a big role in industry. They were trying to go down the periodic table and liquefy as many of the gases as possible.
As you can imagine, you had to lower the temperature more and more. Helium was the hardest one, because it’s a noble gas — it doesn’t interact with other atoms very strongly, which means its liquefaction temperature is very low. And helium, especially among the noble gases, is the smallest one.
So that was the last one to be tackled, and Onnes built a lab to go after it. One of his interesting ideas was that science should be done at an industrial scale, by professionals — he hired professional technicians and engineers to work in a science lab, which people at the time found a little strange.
And he succeeded. After a lot of hard work, with a large team, he was able to liquefy helium. Interestingly, he got the Nobel Prize for liquefying helium — not for discovering superconductivity. He’d basically created a new capability: lowering the temperature to below four Kelvin. Zero Kelvin is absolute zero — you can’t go below that — and four Kelvin is really cold. Once he reached four Kelvin, he could push a bit further, to 1.8 Kelvin.
After that, he knew people were wondering what would happen to metals if they got really cold. Some really smart people, like Lord Kelvin, thought that at such low temperatures, electrons would basically freeze — which is intuitive, in a way; it’s so cold, electrons don’t want to move anymore. So Onnes wanted to try it, and one of the scientists in his lab tried putting different metals into liquefied helium.
One of the things they tried was mercury. It turns out mercury is a superconductor at such low temperatures. Once they observed that, it was a big deal — and that opened up this whole field around superconductivity.
Mario Gabriele: Thank you for that history, that’s very interesting. You’ve both used this phrase “synthesis superintelligence.” I’m sure folks have an understanding of what synthesis is, but why that word? Why is that the right wrapper, the right description? I imagine there’s something quite deep there in why you’ve chosen to frame it that way.
Dogus Cubuk: There are historical reasons and scientific reasons. One historical reason is that the US used to be really good at synthesis, especially during the Bell Labs era. After Bell Labs stopped doing research at that scale, the US kind of lost its strength in synthesis, and it moved to some other countries.
Mario Gabriele: When you say Bell Labs was great at synthesis, what’s an example of that?
Dogus Cubuk: Good question. Say there’s a new compound, a new material that’s interesting, and I come to you and say, “Mario, can you make this?” That can be very hard. If it’s been made before, you can just follow the previous recipe — kind of like baking. But if it’s never been done before, it’s actually hard to figure out, because at a high level you’re trying to get the atoms into the right shape.
And that’s difficult, because you’re not actually seeing the atoms — you can’t move them individually. Today, US academia has focused a lot more on functional properties, like finding a new battery or a new solar cell. But there’s this fundamental capability that’s still very important: being able to synthesize things.
Here’s another reason: in materials discovery, you might have heard of this roughly twenty-year bottleneck, where you discover a material in the lab, but it usually takes ten to twenty years before it impacts technology. One of the main reasons is that you can make it in the lab, but figuring out how to scale up manufacturing — so you can make it at industrial scale and sell it — is usually a huge issue. A lot of what you see in the lab doesn’t transfer to large scale.
And to be honest, people often think of materials discovery as being mainly about discovering the material. But if you go into the lab, usually the hardest part is making the thing you’ve discovered — it’s relatively easy to figure out what could be an interesting material. What’s usually hard is making it.
Let me give you a quick example. When Alex Müller wanted to study transition metal oxides for new superconductors, he succeeded, around 1985, and discovered cuprates, which were the first unconventional superconductors — he got a Nobel Prize for it. These were the high-temperature superconductors.
He’d actually originally been trying nickelates instead of cuprates — if you look at the periodic table, nickel is right next to copper. So instead of copper oxide, he tried nickel oxide. It didn’t work, so he gave up and moved to cuprates. But then, forty years later, our neighbors at Stanford — Harold Hwang — discovered that nickelates are also superconductors, once he figured out how to make them.
I guess what we’re trying to say is: even when discovering a material is the main goal, being able to synthesize it efficiently is the biggest bottleneck. So we’re spending a lot of our time figuring out how to make the things we want to make.
Mario Gabriele: For someone who last conducted a scientific experiment probably in tenth grade, and nothing serious — when you say it’s hard to make things, what are the ways that’s difficult, precisely? Is it a question of precision? Consistency? Pick any example, I suppose — what are the most common ways that process fails?
Liam Fedus: Even if you know how you want to configure the atoms — okay, if they were arranged this particular way, it would be stable, it would have the properties we care about — there’s a whole set of processes you need to go through to get there. What elemental precursors do you use, in what proportions, what temperature profile, what pressures? What are all the processing conditions?
There’s a huge amount of challenge in all of that, and it’s necessary to actually produce a new material. It’s insufficient to just bring the precursors together at ambient pressure and temperature — you have to push into new regimes. That’s extremely difficult. But once you have a system that can do this, it can intentionally and efficiently start designing matter, which we think is extremely foundational.
Mario Gabriele: Another naive question — once you have the recipe, so to speak, for one of these things, how easily can you make it consistently? It sounds like once you have the idea, it’s hard to get it right the first time — but once you’ve dialed that in, is it quite replicable? Or is it actually surprisingly hard?
Dogus Cubuk: It really depends. Let me give you some examples of why it’s hard to replicate. Take furnaces. If you think of a very simple synthesis — solid-state synthesis — you mix precursor powders, put them in an oven or furnace for some time at some temperature, and take them out. That’s the simplest thing you can do, and even there, there are a lot of issues.
One issue is that precursors might have different amounts of impurities. You buy a precursor that’s, say, 99.1% pure, but there are other impurities, and those impurities can affect the results. Another issue is that furnaces change their temperature stability over time. One thing we realized in our own lab — a real pain point — was that a furnace was working well for the first three runs, but after that its temperature stability went haywire. Things like that can make replicability difficult.
But humans have definitely gotten better at this with experience. Another example, from cuprates: when they were first discovered to be superconductors, some people wondered if it was even real, because people had trouble replicating it in the lab — it was a difficult synthesis procedure. Today, people have dialed it in so much that it’s in textbooks — if you open a solid-state chemistry textbook, some of the synthesis examples will include cuprates like YBCO. So it’s one of those things that seems unreplicable and hard to figure out at first, but as we gain experience, we get better at it.
Liam Fedus: And one key piece of what we do at Periodic is that we think about the hardware engineering side of all of this too. Something that used to be a hidden variable — like an oven degrading slightly over time, or asymmetries within the furnace — if you can get better telemetry on these things, you can pipe that information back to the system, and it can build a better sense of it.
Mario Gabriele: One of the things I think about when we talk about the state of modern science and modern knowledge is the replication crisis — it’s hard to reproduce results we think we know, so there are things we don’t necessarily know are true, or don’t know with full confidence. It sounds like because of that telemetry, and the way you can engineer this system with a different level of fidelity, you can hopefully start to figure out why these things fail, and get better replication and reproducibility.
Liam Fedus: Yeah, and we also run replicates. We have to understand the variance of different systems, and really teach the system to make better decisions under uncertainty. For example, if there’s some aberrant noise in one pattern, we don’t want it to over-index on that and say, “No, this should just be rerun — this looks like noise.” Building that kind of scientific intuition into these systems is what we want to do.
Mario Gabriele: I want to go so much deeper into what you’ve built, but maybe let’s take a step back in time first. I think you’ve both said before that you met at the gym, flipping a tire. How did you both get to that point? Maybe we could start with you — you were telling me before we started that you grew up in western Turkey, I believe.
Dogus Cubuk: Yeah, that’s right. Growing up, I always knew I wanted to be a physicist, but what I didn’t realize at the time — though it makes more sense looking back — is that I always enjoyed simulating physics and math. If I say “QBasic,” do you know what that means?
Mario Gabriele: I will not.
Dogus Cubuk: Okay, some of the listeners will. QBasic was this programming language available when I was a kid, and as soon as I got my hands on it and figured out how to program, I was doing simulations of applied math and physics — though at the time it didn’t quite click for me. Back then I was really just thinking about theoretical physics; my heroes were people like Einstein and Feynman. In high school I learned more languages, like Java, and again it was all simulation-related.
When I started my PhD, I realized something: physicists were using tools from the sixties and seventies to analyze data, but the amount of data had increased exponentially, because of Moore’s Law — people in the nineties had exponentially more compute than people in the seventies. So physicists were producing enormous amounts of data but analyzing it by hand, or with simple analytic models. This was around 2010, and I felt like we should see how machine learning could do physics.
There was a lot of pushback at the time, because machine learning is probabilistic, it’s biased, it’s not always calibrated — and physicists, especially the Platonist ones, tend to think there’s one reality, one beautiful theory. So there was pushback. But in 2012, when the ImageNet moment happened and deep learning started gaining prominence, by the time I finished my PhD, machine learning was everywhere. Physics departments actually had to put machine learning somewhere in a grant proposal — especially in condensed matter physics — just to get funding. It was a huge change in about five years.
Around that time, Google Brain had this residency program — I think it was partly Ilya’s idea, which was brilliant — to bring in people with some machine learning background or interest, but expertise in other fields, to learn deep learning and contribute to it at Google Brain. That’s how I joined, as part of the residency program. Liam joined in a similar way — he can explain that himself. So we were both doing deep learning research, and I was at the gym trying to keep up with a workout. It was difficult, so I picked him as the strongest person I could find.
Liam Fedus: Yeah — you saw the arms, right? “This guy’s going to help me.”
Dogus Cubuk: And it succeeded.
Liam Fedus: You know, we managed.
Dogus Cubuk: So I kept doing regular deep learning research — this was an exciting time, I’d just published at NeurIPS, ICLR, ICML — deep learning was advancing through these conference publications, and there was a lot of fun in that. I was also still pursuing my earlier passion, simulating solid-state physics.
At some point, Liam and our other friend Barret Zoph left to start ChatGPT, and I ended up staying and really focusing on physics. By the time I left, I was running a large team of chemists and materials scientists at Google DeepMind, and we were doing a lot of simulation and machine learning work. Liam and I stayed connected, often talking about physics and other things, and we felt like the technology had reached a place where we could really impact the market and the industry. So we left our respective roles to start the company.
Mario Gabriele: Amazing. Okay — what’s your origin story?
Liam Fedus: I grew up in Maine, and I also had an early love for physics. In college I was torn between physics, chemistry, and economics, and I was part of a dark matter detection program. A key piece of that was reconstructing particle tracks, which became a physics model — really a physics-informed machine learning model. So I started doing machine learning in physics at a very early stage, in undergrad, and then again in graduate school, reconstructing particles, this time at CERN.
Through that work, we kept pushing the amount of computation we put into it, and the algorithms for machine learning. But after a while it became clear that if I really wanted to push machine learning forward, I should be doing it in industry. So I went to Google, on the Google Accelerated Science team, and later Google Brain — that’s where Dogus and I met. I worked on a mix of things in the science program, then switched to generative models and reinforcement learning, and was really in a scaling mentality. It wasn’t necessarily applied to physics, but I saw how impactful language models were becoming, and worked on some of the architecture needed to scale them up — sparsity, Switch Transformers, mixture-of-experts. That became an important architecture for serving today’s models. We continued scaling that up, did some of the first trillion-parameter models.
At some point it became clear there was a huge possible impact for this in the broader world — in a product. That’s what led me and a few others to OpenAI. We felt it was a great time to start building products with some of these things. When we arrived, GPT-3.5 was out as an API, GPT-4 was internally available, and we had some time to develop it. At some point we decided to do a quick sprint using GPT-3.5 — a two-week sprint — and that turned into ChatGPT.
Mario Gabriele: And did that product do well?
Liam Fedus: It exceeded some of our expectations. We had internal polls about how many people would use it — people guessed numbers like 10,000, 50,000. A high bar was a million. No one guessed it would be what it became. It was genuinely a low-key research preview.
Mario Gabriele: Your mental model must have then totally shifted, right? I mean, that happened to literally all of us, but you were —
Liam Fedus: Well, the context before that too is that Meta had just released Galactica and had to withdraw it within a few days of release.
Mario Gabriele: I didn’t remember that.
Liam Fedus: That was only a couple of weeks before, and there had been no successful chatbot up to that point. So the prior that this was going to be valuable technology was quite low. It was further surprising because we had GPT-4 internally, and it wasn’t this hugely viral product within the company. So putting out a weaker model to the public was really just part of iterative deployment. And obviously it worked better than our predictions.
Mario Gabriele: What was the period after release like for you? Was it just totally frenetic — chaos?
Liam Fedus: Yeah, at times. The servers couldn’t keep up, and you’re just trying to rapidly improve it. The early model couldn’t do math, couldn’t write very well, had many deep flaws — very different from what we have today. But it was just a series of getting feedback, improving the task distribution, improving data quality — all these kind of boring details — that led to the system we have today.
Mario Gabriele: Very few people will ever have an experience like that, I suspect, but I imagine it serves you well as a founder today. What do you think it taught you? What did it give you?
Liam Fedus: Question everything. It’s really interesting — people would come in years after the initial creation, and it’s very easy to anchor on some random decision made a year or a year and a half earlier, not necessarily an optimal decision, but you take it as one of the assumptions you build on. But I can recall, no — that was just one conversation, one decision someone made — feel free to change these things.
As we were building that up, and eventually I was running the full post-training team, which sits between research and product, we made incredible progress in the digital world. But Dogus and I were talking, and we felt the impact of these systems on the physical world was always going to be constrained unless we actually connected them to the real world. Reading text, reading textbooks and papers, deriving questions from that — that’s great foundational technology, but insufficient. Ultimately, the main objective for artificial intelligence that we’re really excited about is new scientific discoveries, new technology — something tangible you can hold in your hand. That was the motivation leading up to Periodic.
Mario Gabriele: You’ve both worked with some of the very best builders and researchers in this space — why did you pick each other? What was it about Dogus that made you think, this is the guy I want to spend the next chapter of my career with?
Liam Fedus: Just an absolutely brilliant thinker — there’s no one better in the world to do this problem with. Dogus has been at this intersection for fifteen years, more.
Dogus Cubuk: Yeah, fifteen years.
Liam Fedus: Right. And we’ve known each other for a decade, so it was just obvious there’s no one better in the world to do it with.
Mario Gabriele: What about you, Dogus — why Liam?
Dogus Cubuk: Many reasons. One is that with a co-founder, the most important thing is trust — you’re trusting your own career, but also the people you bring into the company. There are people at our company I’ve worked with for many years, and Liam has too, and I wouldn’t do this with someone I couldn’t trust fully.
Another reason is that Liam has been extremely successful in ML, but has always been very passionate about physics. Whenever we caught up, he’d get excited talking about quantum physics, quantum computing. I think it’s really important for the person to genuinely care about these things, and I could tell Liam really does — even with so many exciting things he could be doing on the ML side, this is what he wanted to do. And of course, we needed deep expertise in RL and LLMs, and Liam has done RL research and contributed to the frontier for so long. So it was a very obvious, easy choice.
Mario Gabriele: You mentioned bringing people into the company — I think one of the things you can see from the outside, but that also came up talking to some of your investors in preparation, is the talent density you’ve created, which is extremely impressive, especially for a company this young, still in its very early innings. How have you convinced some of the very best people in this industry — who are being fought over ferociously — to pick this as their mission?
Liam Fedus: I think it’s mission, quite simply. People see the ambition of what we’re trying to achieve, and the possible impact — something that can actually design the physical world, something that understands physics and chemistry, which is even more foundational than a system that understands language. I think that really appeals to people.
I think it also appeals to people in terms of leverage — how much of a difference can you make in this position? You might be a very successful contributor to a coding system, but there’s always a counterfactual: if I’m not the five-hundredth contributor to this coding agent, what’s the delta? People look at that and think, my skills could be better used elsewhere, where I can have a larger impact on the world. I think that appeals to a lot of people — as well as scientists seeing how rapidly AI is advancing in the digital realm, in math, theoretical physics, and so on, and wondering what that could mean for the physical sciences. I think that’s a huge draw.
Mario Gabriele: I imagine it doesn’t hurt that when you look at the best researchers in AI, so many of them have physics backgrounds — it seems to have drawn a lot of that talent. I’d imagine for a lot of these folks it’s a chance to bridge their childhood love with where they’ve built their careers. I don’t know if that’s how you’ve seen it.
Dogus Cubuk: Definitely. I think there are two aspects. As you said, a lot of these researchers deeply care about science — that might be a personal-interest thing. But on the other hand, they really want AI to impact society in a positive way, and I think science is such a good direction for AI because there’s no end to it. For example, we expect that if we’re successful with Periodic, it will actually increase the number of scientists in the world. Whereas for certain roles, if AI replaces the employee, it’s kind of a zero-sum game — for science, it’s the opposite. The more we can show that science can impact the world — especially solid-state physics, chemistry — the more people will go into that field. There’s no end to science, no end to engineering. We can discover more, we can visit more planets.
Mario Gabriele: Let’s get really granular, to the extent you’re able to share it — what does one experimental loop look like at Periodic? What are the different machines, the different processes involved?
Dogus Cubuk: Say we’re doing powder synthesis, trying to make a superconductor. The first decision is what precursors to mix, because the thing you’re trying to make probably doesn’t exist on your shelf yet — you have to get the ingredients. Those can usually be binary powders — meaning two kinds of atoms — or elemental precursors, a single element. Basically, you figure out what precursors to combine for the thing you’re trying to make.
Mario Gabriele: Is that you figuring it out, or the AI figuring it out?
Dogus Cubuk: Great question. Traditionally it would be a human figuring it out. For us, the AI can really speed up this process — especially down the line, if you want to run thousands of experiments a day, you can’t have a human do it one by one.
Mario Gabriele: So when it’s speeding it up, is it maybe saying, “Here are thirty good options for you” — narrowing the scope of what you might look at, and introducing new ideas?
Dogus Cubuk: That can happen, or it can actually say, “For this goal, here’s what you should mix” — and we try that. So you mix the precursors, and now you need to react them, because at room temperature these materials won’t react with each other — they’ll just stay as precursors. There are different options, but a very common one is what we talked about: you put it in a furnace with a temperature profile. Liam has often pointed out that the temperature profile looks like a learning-rate decay profile, like in machine learning.
Mario Gabriele: Sorry, I’m just so interested in each of these steps — putting it into the furnace, is that a human doing it? A robot? Is that already automated?
Dogus Cubuk: That’s already been automated by others before we started Periodic — there have already been attempts at getting a robot arm to take the mixed precursor and put it in a furnace. We can do either: have a robot do it, or have a human do it. But as you want to scale up to thousands a day, then you definitely need robots to do it.
Mario Gabriele: Yes, okay — so it’s in the furnace. Then what comes?
Dogus Cubuk: The very traditional path is you wait a predetermined amount of time — predetermined by us or by the AI — and then you take it out, hoping that during that time and temperature profile, the reaction you hoped would happen did happen, and the reactions you didn’t want to happen, didn’t.
So now you have it — you cool it down a bit so you don’t burn your hand — and at some point you put it into a characterization instrument. For inorganic crystals, the method we use most is XRD, X-ray diffraction. It’s the same kind of X-ray you’d get at the dentist — it just happens that the X-ray wavelength is comparable to the distance between atoms. So if you pass X-rays through a solid, you can see what the atoms are doing, how they’re positioned relative to each other, and that tells you whether your experiment succeeded.
We find that AI can play a big role here too, because once we get the X-ray diffraction pattern, it’s not always easy for a human to tell what you made, but the AI can help with that and tell you whether it succeeded or not, and send it back for a new experiment if needed. And if it succeeded, maybe you want to check if it’s a superconductor — so you put it into another instrument that measures the diamagnetic response, which tells you if it’s a superconductor at a given temperature.
Liam Fedus: Yeah, I think the XRD example is really interesting too, because the materials don’t come out labeled.
Dogus Cubuk: Yes.
Mario Gabriele: Right — “well, here’s what you’ve made.”
Dogus Cubuk: Exactly.
Liam Fedus: That’s right. So AI is allowing us to basically do the labeling, and figure out what we’re making, at a much faster pace. Anyone could go into a lab, mix a bunch of powders, and say they ran a lot of experiments — but if you’re not seeing what you’re doing, there’s no error-correction loop, no intentionality to it. So those are some of the first AI systems we had to build, and they let us scale up the throughput of the lab significantly.
Mario Gabriele: Are you gathering lots of ancillary data along the way? Is that useful? I don’t even really know what that would be, but I imagine a mechanized version of this process permits that in a way a purely human version doesn’t.
Liam Fedus: Better telemetry is one aspect, but whether it’s robots or humans, I think stitching the data together is one of the most important pieces. This is what I was alluding to earlier — most AI has been trained on the final artifacts of science: the final paper, the final recounting in a textbook. That isn’t how the scientific process actually unfolded; it’s a retelling of the story.
What we do is be very careful in collecting the intentions — what were the hypotheses, what were the computational predictions, what was the execution through all the machinery — and this fully stitched-together lineage is very unique. That’s something we’ve spent a lot of time putting together. In training, the system is learning not just what the final outcome was, but what the process was, what judgments were made, what reruns were done as new evidence came in — basically, what the process of doing science looked like.
Mario Gabriele: In a way — maybe this is a bad analogy, you’d know better than I would — it feels like a chain of thought for science, where you’re starting to see —
Dogus Cubuk: Yeah, yeah.
Liam Fedus: — interacting with the —
Mario Gabriele: — real world. Yes, exactly. As you’ve now started running some of these experiments, what do you notice that having that trace actually gives you? Is it better suggestions for the next experiment than you’d have gotten otherwise? Is the next whole set of experiments somehow leveled up compared to starting cold?
Dogus Cubuk: One thing is just being able to pay attention to detail when there’s so much detail. We’ve seen the LLM detect major mistakes and debug them. One thing that happened in our lab: it turned out that samples are placed in a circular sample holder, and we made a mistake — they were shifted by two positions, so all the samples were mislabeled. We had no idea what happened, but the LLM was able to go through it and realize, “You just shifted counterclockwise by two — if you do the inverse rotation, now they’re all labeled correctly.” A human could do that, but it takes a huge amount of attention to detail and time. Now imagine doing that across thousands of experiments at once.
The other thing LLMs are really good at, which I’m excited by, is that they can operate at the level of different expertise and different PhDs at once. For example, our LLM can do simulations at the level of a PhD in simulation, but can also do experimental data analysis at the level of a PhD in experiment. That’s unique, because most people get a PhD in one or the other, and things fall through the cracks in between. So having a platform that’s an expert across all these different modalities, and can reason across them at the same time — that’s really valuable.
One thing that happened for us: a result came up that wasn’t what we were trying to make, and wasn’t a material in any database, so we couldn’t tell what we’d made. But the LLM ran new simulations and figured out what it must have been, and we were able to validate it with the next experiment. I often say the people who should run simulations and the people who know how to run simulations are usually disjoint sets of people.
Liam Fedus: Yeah.
Dogus Cubuk: I think LLMs will bring these together. And it’s fractal — I’m talking about one interface, between simulation experts and non-simulation experts, but it’s also true between, say, inorganic chemists and organic chemists, or chemists and physicists. Human expertise is kind of like a fractal, and there are interfaces throughout it. Being able to speak the language of all these different groups is going to be a qualitative change.
Liam Fedus: Another interesting thing to add: as we build up this database of everything that’s been run, all the decisions made, you can start constructing new kinds of machine learning tasks — you take a snapshot of the state of the world and ask, given the computational and experimental state at that point, what did the scientist do next, and what was the outcome of that? That’s a very rich source of training data for reinforcement learning.
One analogy people have talked about is: let’s train an LLM up to general relativity, and see if the system can produce something like that on its own. We’re doing an analog of that at our scale, in our own experimental and computational data. This is a kind of data that really confers a huge advantage, because it just doesn’t exist anywhere else.
Mario Gabriele: You mentioned this idea of a snapshot in time, which is such an interesting idea to go a level deeper on — what might a snapshot at Periodic look like, and what would you get out of looking at it?
Liam Fedus: Say, hypothetically, you had 100,000 experimental data points. You could say: what was the state of experimental evidence as of some date? These were our computational predictions, these were the experiments we’d run up to that point, here are some notes on what we were thinking. From that point, that becomes your environment state, and you ask: given this basket of data, what did the scientist do next, and given what they did, what was the outcome — what were the new empirical measurements?
That becomes an incredibly interesting source of reinforcement learning tasks and data that’s incredibly hard to construct outside of Periodic. And it’s easier for us to do this kind of work because, as we accrue more evidence and data that doesn’t exist in the public literature, we know our model isn’t contaminated. There’s a risk when your pretrained model already knows the answer, and you do reinforcement learning against an answer that was already in the pretraining corpus — the system can basically fake its way to the right answer, and you reinforce that strategy, which isn’t going to generalize or be particularly interesting. We’re able to circumvent that by having a basket of data we know doesn’t exist in the literature.
Mario Gabriele: When I think about what you’re doing, there are obviously so many different pieces to pull together. What doesn’t make sense for you to do? Do you need to develop every piece of hardware yourselves, or can you use someone else’s robot? Will you ultimately create your own models, or can you fine-tune existing ones for these different pieces of the process? What do you feel like you need to uniquely own?
Dogus Cubuk: For hardware, if there’s an off-the-shelf component we can just buy and use, we’re very happy to do that — we don’t need to reinvent the wheel. It turns out that for certain scientific instruments, the throughput or the quality isn’t there, so for those we invest in hardware engineering to improve throughput and so on.
Mario Gabriele: What’s an example of something that just doesn’t hit the scale you need, that you have to reinvent?
Dogus Cubuk: One that already matches our needs is XRD — there’s already so much work in high-throughput XRD that we have instruments that can run forty samples at once. But for things that are more materials-property-oriented, where measurement is slower and might take an hour per sample, that could be a big blocker for us — so we invest in new engineering to make it work. Same for simulations: for some things there’s already a really good codebase, so we don’t need to improve it, but for others it’s not there yet, or not scaled enough, and we invest in software engineering to make it happen. Same on the LLM side.
Liam Fedus: Right now we spend very little time trying to improve software engineering itself — we use these systems to build up our codebases and help with these analyses, and we’re absolute beneficiaries of how good Codex and other tools have become. What we’re targeting are areas where the frontier just isn’t sufficient, or where we can do it vastly more cheaply — that’s where we focus our efforts.
We deeply believe, and I think we’ve seen good evidence, that when you actually train against this data, you can make reasoning more efficient — you add new kinds of capabilities and go beyond what inference-time thinking alone can do. Compressing this knowledge, compressing these strategies into the weights, is fundamentally valuable, and that’s why all the frontier labs keep doing this — we didn’t stop at GPT-4 and just do inference-time reasoning from there. Compression really needs to happen, and you get different kinds of patterns that emerge.
Take tool use, for example: there’s declarative use of a tool — here’s how you use it, here are the specs, the inputs, the expected outputs — versus procedural, intuitive knowledge, like knowing when you should use this tool in this situation. A friend of mine used the example of reading a manual on how to play saxophone versus actually learning to play it. You want to build that intuition into the weights.
We try not to duplicate things where the frontier is already sufficiently capable or cheap enough. We’ve had a few instances where, because we’re pushing the lab’s throughput so much, some analyses would have been prohibitively expensive at one point. One of our engineers told us that at our max lab throughput, a certain analysis would cost roughly thirty million dollars a year. So we looked at how to compress that into smaller, more efficient models — taking it from thirty million dollars down to a sub-million-dollar cost. That lets us reinvest that capital elsewhere, into other machines, training, or simulation. That’s a type of work we’ve been doing.
Mario Gabriele: Speaking of capital — you just raised a new round. What does that let you do now? Is it predominantly compute? Hiring? All of the above?
Liam Fedus: Compute and infrastructure — those are the two key pieces for Periodic. Compute has become so central to pushing the frontier of synthesis superintelligence, and also our simulation workstreams, so we spend a huge amount of compute on both. But key to our hypothesis and belief is that we have to continue building out more labs and acquiring more infrastructure. That’s how we’re creating systems that wouldn’t otherwise exist.
Mario Gabriele: How have you gone about securing the compute you need, when there’s clearly a massive supply crunch and everyone’s trying to get their hands on it? What does that look like for you?
Liam Fedus: We go through our own sets of relationships with providers we’ve already partnered with, and we understand the constraints for others — but we are able to find compute. It’s certainly a different market than it was a year ago; the frontier labs are monetizing compute at a very high rate, so they have this flywheel of soaking up all the additional capacity. But we still find there’s sufficient compute for what we need to push forward.
Another key piece for Periodic is that by having the physical infrastructure — the labs, the data no one else has — that confers a compute efficiency advantage. That’s really key, because you don’t have to match, one-for-one, the compute of a much larger company, since you have sources of data no one else has, and those efficiencies make it a lot more tractable.
Mario Gabriele: Over the past year, what’s the rough order of magnitude of experiments you’ve run, and what do you hope that looks like a year from now? Are you trying to raise it by an order of magnitude? Doubling? Tripling? What does that look like?
Dogus Cubuk: We started with zero experiments, obviously, and we’ve been ramping up quickly — we really wanted to get experimental results as early as possible, so we built the lab and started getting results fast. Our goal on roughly a one-year timeline was about a thousand experiments a day, and that’s what we’re targeting.
One thing worth pointing out: just running experiments without getting anything out of them is less difficult, but also less desirable. So we’re scaling up the volume, but also making sure it comes with high-quality telemetry. Our hypothesis is that LLMs won’t just arbitrarily generalize — if you believe that, you have to build labs for physics, but you also have to build many labs, because one lab you build generalizes to that kind of lab, and maybe similar labs, but there are many other labs that won’t generalize from it. So we’re very invested in building many high-quality, high-throughput, modern labs, which is very exciting, honestly.
Mario Gabriele: So are you at a thousand experiments a day now, or is that the goal a year from now?
Dogus Cubuk: We’ll get there soon.
Mario Gabriele: Okay — well, that’s wild.
Dogus Cubuk: And we’re also going to go beyond that, adding more modalities, different kinds of experimental directions.
Liam Fedus: We realized we could conduct very high-throughput experiments that are also fairly low-latency. In a lot of areas of science, there’s lower signal-to-noise, and things can take days, weeks, sometimes months. That’s been a huge motivation for some of our starting points.
Mario Gabriele: Wow.
Liam Fedus: That lets us build up this huge quantity of data while also maintaining quality and diversity, and that becomes an incredible asset.
Mario Gabriele: The diversity piece is something I’m interested in — maybe because I don’t have enough understanding of superconductors — but how do you make sure you’re pursuing different modalities, getting data that’s sufficiently diverse and not overly specialized?
Dogus Cubuk: There’s definitely a trade-off to consider. If you make it as diverse as possible, these experiments don’t learn from each other — you haven’t really gone deep enough in any one modality. If you make it really narrow, there’s a big problem: if that particular modality doesn’t lead to a new superconductor, you’re stuck, no matter how well you execute.
So we’re trying to walk that trade-off correctly, and one of our guiding principles is actually pretty technical: we want to make sure the different modalities we consider benefit each other, because there are scientific experiments — different synthesis methods, say — where getting good at one also helps you get good at the other, and vice versa. So we build our LLM training, our simulations, and our hardware in a way that lets them benefit from each other. That’s been really effective — it’s how we build experimental diversity while still synergistically benefiting from each experiment.
Liam Fedus: To use ML parlance, we want positive generalization.
Mario Gabriele: Does that come from your own intuition and knowledge, or is it also AI-assisted? Where does the human come in there?
Dogus Cubuk: Originally it was mostly human intuition, but we’ve already seen indications of the LLM contributing to this. Sometimes it will say, “You’ve done this experiment, this synthesis method, but if you were to add this, it’s a new modality that could help” — not a massive hop in the synthesis-methodology space, but a small, useful difference. It usually has a pretty good understanding of the literature — what kinds of synthesis attempts have been made for this chemistry — and it can guide us: “Maybe you should try this next.”
Mario Gabriele: What’s the right way to monetize this kind of product? Does it make sense to develop these discoveries yourselves and sell them? Does more contract work make sense? What’s the right model to start with, and what does the right model look like at maturity?
Liam Fedus: Maybe an interesting analogy is what we’re seeing in software engineering. When we first shipped ChatGPT and these early models, we didn’t promise a full-fledged software product — we weren’t saying, “We’re going to produce a Kubernetes replacement for you and monetize that directly.” It was a copilot to accelerate a software engineer and get them to solutions more quickly. Fast forward a few years, and we’re starting to talk about monetizing outcomes — a newer concept in AI.
I think something similar is going to unfold here. The tools we’ve been building up in our own discovery loops are hugely valuable to a lot of different players in the industry, and we’re able to build custom systems for partners and customers to help them get to their solutions much more quickly. But in parallel, we’re also talking about outcome-based pricing, where we retain the IP and the upside of the final output of our systems.
There’s another interesting piece here too: if the software has, in its weights, the recipe for a room-temperature superconductor, you don’t want to monetize that through a software deal — you want to retain that IP. So those are the kinds of trade-offs we have to balance.
Mario Gabriele: Are there analogies from other industries you find yourselves referring to? I imagine some part of the current scientific apparatus is useful to learn from, but I could also imagine different forms of manufacturing having taken this much further — whether that’s building a computer, an iPhone, a car, whatever it might be.
Dogus Cubuk: One thing I think is very relevant to us is drug discovery. There was a time when discovering a drug didn’t let you make much money off the IP, but that changed — today you can discover a drug, go through some clinical trials, and get paid billions of dollars for the IP alone. The field changed, and the capabilities that support that market changed too. I think materials is at a similar point now: you can make a lot of money selling materials, but materials IP doesn’t really capture the value it deserves yet. It could go through a similar transition to drug discovery.
We feel that as predictions get better, IP will have more value — that’s why we’re trying to close the loop all the way from discovery to synthesis to scale-up of synthesis. That’s one of the analogies, I think.
Mario Gabriele: Before we hit record, you were mentioning the difference in performance between mathematics and science — maybe you can tell us a bit about that.
Dogus Cubuk: This is something we’re very passionate about, and it’s one of the reasons we started the company. If you talk to LLMs, they’re incredibly intelligent — you’re blown away. On certain things, their performance is insane: coding, math, theoretical computer science. But you haven’t seen that kind of impact on the physical world. Why is that?
We think one reason is that with math, theoretical computer science, and coding, the reward is instantly verifiable — you write code, you can run the unit test; you have a mathematical theorem, you can validate it. Another reason is that all the context is available to the LLM — if you’re writing code, the model can see all the code; if you’re doing math, it can see all the axioms and corollaries. Physics will never be like that. When I run an experiment, there are more atoms involved than Avogadro’s number — no computer can store the positions of all of them. So we have to accept that in real life, LLMs will never have full context.
But honestly, outside of math, almost everything interesting is like this — the full context is never available. Think about politics, finance, literature — what makes life interesting is that you don’t have all the context, but you still have to make decisions under uncertainty. Physics is very much like that. So if LLMs are going to play a big role in the real world, in the physical space, they have to figure out how to deal with missing context, rewards that aren’t instantly verifiable, and noise. We feel there’s a very exciting future to be part of there, and that’s why we’re working on this.
Mario Gabriele: I love that — that’s so interesting.
Liam Fedus: And the strategies that are optimal for math, or for software development, may not be the ones optimal for decision-making under uncertainty. That’s the vision we’re pushing forward here.
Mario Gabriele: To what extent is Periodic’s fate tethered to that of the foundation models? Obviously this isn’t going to be the case, but if we didn’t get another model from this point forward, how far do you think you could push things?
Liam Fedus: From the software engineering side, I think we could literally stop today and still find every remaining Nobel Prize, at least in the physical sciences — a lot of physical science relies on fairly simple analysis, it’s not competitive programming. So I think from that perspective we’re in very good shape, and we’re huge beneficiaries of that. I hope they continue to improve rapidly, and I expect they will, but I don’t view that as a blocker for us anymore.
Dogus Cubuk: Absolutely. There’s so much to do on experimental analysis, simulation, scale-up, and data analysis, and the current models — and our own models — are already good enough. Let’s say AI is very popular today, but suppose tomorrow it isn’t, for some reason — there are certain things that have happened in physics that will never go back. One of them is force fields. Have you heard that term before?
Mario Gabriele: No.
Dogus Cubuk: The atoms we deal with are governed by fairly simple quantum mechanics — you can run a quantum mechanical calculation to get the forces on each atom, or you can use an empirical model that approximates that force, which is called a force field. It’s a very old topic; we use it all the time to model materials and molecules. Force fields have changed so much because of graph neural networks that I don’t think it will ever go back — now we can build very general models across the whole periodic table. In the past you could only really do three to five elements at a time. It’s a tough one to walk back. I feel like machine learning has already made such an impact that it won’t reverse — and as Liam said, today’s capability is already enough to meaningfully advance science and engineering. Of course, we expect it to keep getting better, and we’ll keep benefiting from that.
Mario Gabriele: Clearly we all agree these models are going to keep getting better. Planning with that in mind, what changes for you? What do you expect to get unlocked that isn’t unlocked yet?
Liam Fedus: Some things we’re really excited about: much more advanced software engineering. We do a lot of very advanced simulations, and we’re starting to build more advanced simulations where we control every bit of the code — things that would have taken a team a year or two, and now it’s like an engineer’s weekend project. So we’re extremely excited about that, especially in areas where the AI system can write software and simulations that are maximally consistent with experimental evidence.
Mario Gabriele: It still feels like what you’re doing is very differentiated in this market — right now this is at the “max mimicry” stage in a lot of AI, where someone has one good idea and five other companies follow, which is probably healthy in some ways. How long before you think that starts happening to you, and who enters the fray? Do the big foundation model companies start saying, “Actually, this is invaluable data — we need to be doing this ourselves”? Where does the competition come from, in your view?
Liam Fedus: I’d suspect that in the next couple of years, a system that can literally engineer matter is going to be of key importance to everybody. I think that’s the motivation for moving as quickly as possible — building out a huge network of labs and infrastructure, building simulations and AI systems that can control and orchestrate all of that. That’s our belief. I’m curious too.
Dogus Cubuk: I do think we’re pretty unique in the team we’ve gathered and the approach we’re taking, but taking a step back, there are actually a lot of people working on this now — almost every week I hear about a new company in the AI-for-science space, which is great. If you really believe science is endless, you want more and more smart, dedicated people working on this. Looking back, I think it makes sense — people are seeing how much LLMs are changing the digital world, and wondering how much they could change the physical world. So it’s not a surprise to us that a lot of people are getting into this field.
Mario Gabriele: You two are co-CEOs, right?
Liam Fedus: Yeah.
Mario Gabriele: How do you divide and conquer — what are the swim lanes you naturally take?
Liam Fedus: Very naturally, based on our expertise — I spend a ton of time on the AI systems, that’s been a core piece of my day-to-day thinking, as well as thinking about how we monetize these AI systems in the real world.
Mario Gabriele: Yeah, there’s a natural division there. I always like to wrap up with some more abstract questions — curious what both of you would say. Given what you do, if you had unlimited resources and no operational constraints, what’s an experiment you’d really like to run?
Dogus Cubuk: I would love to do reaction calorimetry — there’s an experiment that tells you the formation enthalpy of a crystal. What I mean is: how much energy would it take to take this crystal apart, remove the bonds and connections? What’s nice about that is it’s a single number you can get — the formation enthalpy at some temperature — that you can directly compare against simulation. It’s usually hard to find an exact comparison between simulation and experiment; it’s usually convoluted, narrative-based. But here it’s direct — it’s just a very complicated, expensive experiment.
If we had infinite money, I’d love to do thousands of them. There’s some data from NIST, the Standards Institute in the US, who’ve done these experiments for hundreds of materials, and it’s been invaluable for the solid-state chemistry field. If we had infinite resources, I’d love to really scale that up and get enough formation-enthalpy data to compare extensively with simulation and machine learning.
Mario Gabriele: Amazing. What about you?
Liam Fedus: I’d love to see, if we had access to a full fab, how quickly you could ramp up a new generation of chips — how quickly you could overcome the materials engineering problems in logic, memory, processing, and say, “Here’s the new generation” — how you could take a yield ramp that would normally take many months and accelerate it significantly. I think those would be incredibly interesting experiments.
Mario Gabriele: Wow, fascinating. Okay, last one — if you could recommend a book to everyone on Earth, what would you want to recommend?
Liam Fedus: I’d say — probably a popular one in Silicon Valley — The Beginning of Infinity, by David Deutsch.
Mario Gabriele: That is a popular choice. On this question, I still have not read it — I don’t know what my mental resistance is to it.
Dogus Cubuk: You really mean it?
Liam Fedus: Yeah, really. I think it has, very much, a spirit of optimism — it gets at this idea of the unboundedness of science. I really enjoyed it.
Mario Gabriele: Yeah, I think I read part of it at some point.
Dogus Cubuk: Anyway, I really liked this book called Subtle Is the Lord — it’s a biography of Albert Einstein by one of his friends, who was also an exceptional physicist, Abraham Pais. What makes it unique is that most biographies are written by people who aren’t experts in the subject’s field, so there’s usually a mismatch between what they understand and what they should be saying. This book is incredible because it goes through Einstein’s life with very precise technical detail about what he actually did. It’s an incredible friendship book, because they were friends, and this guy wrote this incredible book for his friend — but it’s also an incredible physics book. So if you’re interested in friendship or physics, it’s a great combination.
Mario Gabriele: I love that. Amazing. Liam, thank you so much — this was a real pleasure.
Liam Fedus: Thank you so much for having us — it’s been a great time, super fun.
Mario Gabriele: That’s it — thank you for listening to this episode of The Generalist Podcast. Please subscribe on Apple Podcasts, Spotify, or your preferred podcast app. Ratings and reviews help others discover these discussions, so if you enjoyed the conversation, I’d be grateful if you could take a moment to leave one.
For all past episodes and more, visit us at The Generalist Substack. See you next time, as we continue to explore the future.
2026-09-19 00:52:30
Friends,
Dave Thomas had a confession to make: He was just fourteen.
Two years earlier, Thomas had come to Regas Restaurant in Knoxville, Tennessee, asking for a job at the counter. He’d told the owner he was sixteen. He was, in fact, twelve.
Money hadn’t been the only thing that motivated Thomas, though it mattered. Thomas harbored dreams of owning a restaurant of his own one day.
Working at Regas had not been easy, especially as a child. It stayed open 24 hours a day, and as an entry-level employee, Thomas was often given the overnight shift. At two in the morning, he’d find himself making hundreds of egg, ham, and tuna sandwiches for the day ahead. It got harder after the family moved to Oak Ridge, which added a bus commute to Thomas’s schedule. He eventually persuaded his parents to let him rent a room near the restaurant to cut down his commute, paying the $7 weekly rent from his own wages. He did all this while attending school, working at the Regas on weekends and during summer breaks.
That schedule had worn on him. “I was physically tired,” Thomas recalled, “but most of all I was tired of having lied to the people at the Regas who had done so much to give me a chance.”
So one night, exhausted, he broke down and told the truth, informing his manager of his real age. Gene surprised him with his response: they’d always suspected as much. “But you had such determination,” he added. “We just decided to let it go.”
Thomas would achieve his dream. On November 15, 1969, he opened the first Wendy’s restaurant, naming it after his young daughter. Today, Wendy’s is one of the world’s largest restaurant chains, with thousands of locations across 30 countries.
At first glance, Thomas’s confession is a classic founder’s tale. Here is the striving outsider, the child with holes in his shoes, working his way to the top and enduring pain others will not. It tells us something about Thomas in this way, showing us who he was as a child. More was expected of him, and he expected more of himself.
But there is something else to it, too. It reveals something about Thomas, yes, but about the world, as well. How feeble its rules can be, how hackable the system is if it finds something it needs or wants.
In the first two parts of Saplings, we focused on the ways in which life happened to legendary future founders. How did their surroundings cast them as outsiders? What impact did their family dynamic have on their ambition?
In Part III, the final part of our series, we will switch the focus, studying what came after. In particular, we will examine the patterns of how future entrepreneurs engage with the world around them, assessing how they acquire new information, take their first steps in the commercial world, clash with authority, and invent an adult identity.
Self-directed learners. When the world does not provide the desired education, the founder creates it for themselves.
Early to business. Ambition or circumstance pushes founders into the working world early, exposing them to industry and new responsibilities.
Skeptical of authority. School teachers, bosses, and the rules they impose are questioned and flouted as founders take risks and test the resilience of the systems around them.
Self-inventors. Founders see their capabilities and even their histories as malleable, evolving to meet circumstances.
As you will know by now, Saplings does not purport to explain everything about the individuals featured, or imagine that its observations are necessary to achieve entrepreneurial greatness. It does not attempt to make statistical observations or generalize across these populations. Rather, it is an accounting of the common patterns I find most meaningful, accompanied by my interpretation of them. Across the series, the goal is to study the formative years of extraordinary figures so as to better understand them, knowing that full understanding is not possible.
You can find Part I: Outsiders here, Part II: Unstable Ground here, and a discussion of our methodology here.
Some founders, like Colin Huang of Pinduoduo or Stripe’s Patrick Collison, excelled in academic environments. Others, like Richard Branson of Virgin or Fanatics’ Michael Rubin, struggled with traditional schooling. “I haven’t read a book since ninth grade,” Rubin confessed. “You send me three paragraphs. I’m tuned out before I start.”
Though we can make no statistical claims, anecdotal evidence does seem to cluster around the extremes. There are the super-achievers on one side and scholastic catastrophes on the other. It’s genuinely surprising to see how many founders were not simply middling students, but disastrous ones.
On the mathematics portion of the gaokao, for instance, China’s intense university entrance exam, Jack Ma scored 1 out of 120. The second time he took it, he improved markedly but still failed, logging an abysmal 19 out of 120. He passed on the third attempt, finally gaining acceptance to college.
Akio Morita, the future founder of Sony, ranked 180th in a class of 250 students as a middle-schooler. Only after a year of study with private tutors was he accepted to the science department of a prestigious high school. He was reportedly the “lowest-ranking graduate” ever to make that leap.
There is no one type of mind, or single sort of student, that predicts an exceptional entrepreneur.
There is, however, a pattern across these and other archetypes: self-directed learning. Whether their ambient environment supplies the right intellectual influences or not, founders go out and build the curriculum they want for themselves. They may do so unconsciously, and often it will look like play.
As a boy in Houston, Howard Hughes built a wireless radio set from old doorbell parts and other scraps. When he was refused a motorcycle, he decided to build one himself, strapping a car motor to his bicycle. Little stood between Hughes and his desire to learn and build.
A four-year-old Vitalik Buterin’s favorite toy was already the computer. His father recalled a young Vitalik spending his afternoon experimenting with shapes and colors in Microsoft Paint and plugging different formulas into Excel.
2026-09-08 20:02:32
"No ego is extremely important to make the best decisions possible. That is another thing I saw in Elon – he would be extremely passionate, but then presented with new information, he'd be like, well, okay, that was a quick switch." – Scott Morton, Founder and CEO, Revel
Listen or watch now on
YouTube, Spotify, or Apple Podcasts
Scott Morton is the founder and CEO of Revel, a software platform for testing and controlling complex hardware systems. Before founding the company in 2024, Scott spent nearly a decade at SpaceX building control software for Falcon 9 and Starship. That experience helped him recognize a broader problem: while rockets, nuclear systems, supersonic aircraft, and other advanced machines have grown increasingly sophisticated, the software used to test and control them is often fragmented and decades old. Revel was created to close that gap. The company has raised $180 million, was reportedly valued at just over $1 billion, and counts Impulse Space and Radiant Nuclear among its customers. Its platform scales from small benchtop tests to industrial systems with hundreds of thousands of telemetry channels. Revel has also created its own programming language, RevelCode, designed to combine performance and accessibility with the runtime safety required for high-stakes physical systems.
In our conversation, we explore:
How AI can accelerate high-consequence software teams without replacing rigorous testing and review
Why hardware test and industrial-control software still relies on tools created in the 1980s and 1990s
What Scott took from Elon Musk about betting on teams before you know the answers
Why Revel created its own programming language
The “runtime safe” philosophy: what it means and why it matters
Revel’s one-to-many model and the hardware frontiers it’s touching
The strategic case behind Revel’s $150 million Series B
How Revel’s edge showed up in an industrial-control bake-off
How Scott hopes to preserve Revel’s engineering culture as it scales toward 500 people
Revel’s long-term mission – and what it means for the hardware renaissance
(00:00) Intro
(02:04) Why no one will vibe-code a nuclear reactor
(04:15) Revel’s engineering edge
(05:27) What Revel actually does
(06:34) Why industrial software has stagnated
(07:52) Why previous startups couldn’t crack it
(10:26) The limits of building control software in-house at SpaceX
(15:20) Lessons from nearly a decade at SpaceX
(20:22) Why Revel built RevelCode
(24:46) Will Revel open-source the language?
(25:25) Scott’s early projects and builder mentality
(32:28) Where his drive comes from
(33:50) What Scott took from Elon – and what he chose to leave behind
(36:02) Scott’s standards as CEO
(38:56) Scaling from small tests to industrial systems
(43:40) Deploying Revel and the hiring bottleneck
(45:23) How Revel finds and assesses talent
(46:21) Emerging frontiers in hardware
(49:36) Revel’s unusually smooth trajectory
(51:05) How AI fits into Revel’s platform
(52:42) Revel’s long-term vision
(54:18) Final meditations
LinkedIn: https://www.linkedin.com/in/scott-morton-68334a15
Our Mathematical Universe: My Quest for the Ultimate Nature of Reality: https://www.amazon.com/Our-Mathematical-Universe-Ultimate-Reality/dp/0307744256
Elon Musk on X: https://x.com/elonmusk
Jess Winssinger on LinkedIn: https://www.linkedin.com/in/jwinssinger
Revel: https://www.revel.io
SpaceX: https://www.spacex.com
Palantir: https://www.palantir.com
Anduril: https://www.anduril.com
Starship: https://www.spacex.com/vehicles/starship
The Hedgehog and the Fox: https://en.wikipedia.org/wiki/The_Hedgehog_and_the_Fox
Impulse Space: https://www.impulsespace.com
Star Trek: The Next Generation: https://www.imdb.com/title/tt0092455
I’d love it if you’d subscribe and share the show. Your support makes all the difference as we try to bring more curious minds into the conversation.
Production and marketing by penname.co. For inquiries about sponsoring the podcast, email [email protected].
2026-08-18 20:05:09
“Money, quantifiable, is larger than AI, it's larger than food, it's larger than oil and gas, it's larger than municipal water supplies. It's larger than government spending. It's larger than defense. It's all of these combined.” —Farooq Malik, CEO of Rain
Listen or watch now on
YouTube, Spotify, or Apple Podcasts
Farooq Malik is the co-founder and CEO of Rain, a financial infrastructure company powered by stablecoins. Growing up in an immigrant family, Farooq saw firsthand the friction involved in moving money across borders. Alongside co-founder Charles Yoo-Naut, Farooq spent years building infrastructure before stablecoins became mainstream, betting that tokenized money would eventually become a foundational layer of the global financial system. Today, Rain powers card issuance, payments, and other financial products built on stablecoin rails, helping companies move money faster and operate across markets.
In our conversation, we explore:
How stablecoins combine the advantages of cash and electronic money
The barriers that still make moving money across borders expensive and inefficient
The parallels between being an immigrant and being an entrepreneur
How Farooq and Charles met through On Deck and decided to build together
What Rain gained by building before the market was ready
How Rain earned the trust of early partners who later became customers
What The Art of War taught Farooq about patience
The misconception that stablecoins are only for emerging markets
Why the payments market is big enough for multiple winners
Why he believes Rain’s infrastructure is well positioned for a future shaped by AI agents

Brex: The intelligent finance platform.
(00:00) Intro
(02:46) An overview of Rain and global-first financial infrastructure
(06:57) The barriers to moving money and how technology can reduce them
(15:34) How stablecoins behave like cash
(18:46) The economic opportunity of a more efficient monetary system
(22:06) How Farooq’s childhood as an immigrant shaped him
(26:00) Farooq’s first entrepreneurial venture
(29:11) Lessons from Farooq’s career before founding Rain
(36:09) Connecting with Charles through On Deck
(39:51) From Sign and Wire to Rain
(42:18) Why Rain bet on stablecoins
(47:25) How a Rain card works
(49:15) How Rain thinks about its business
(51:12) Lessons from The Art of War
(54:30) Rain’s approach to hiring and management
(55:47) Why the US is a stablecoin hub
(59:10) Why there’s room for more than Stripe
(1:03:39) How Farooq and Charles stay aligned with limited meetings
(1:05:54) Rain’s most critical mantras
(1:08:56) Why Rain is ready for AI agents
(1:12:30) Final meditations
LinkedIn: https://www.linkedin.com/in/fhmalik
Website: https://fhmalik.com
The Art of War: https://www.amazon.com/dp/1599869772
Pierre Omidyar on LinkedIn: https://www.linkedin.com/in/pierre-omidyar-bb10687b
Charles Yoo-Naut on LinkedIn: https://www.linkedin.com/in/charlesnaut
Rain: https://www.rain.xyz
Revolut: https://www.revolut.com
Rise: https://www.riseworks.io
Airwallex: https://www.airwallex.com
Stripe: https://stripe.com
“Margaritaville”: https://southpark.cc.com/episodes/9do3gw/south-park-margaritaville-season-13-ep-3
Wired: https://www.wired.com
On Deck Founder Fellowship: https://joinodf.com
Lehman Brothers: https://en.wikipedia.org/wiki/Lehman_Brothers
Booz Allen: https://www.boozallen.com
Sign and Wire: https://www.signandwire.com
Bridge: https://www.bridge.xyz
Universal Basic Income (UBI): https://en.wikipedia.org/wiki/Universal_basic_income
I’d love it if you’d subscribe and share the show. Your support makes all the difference as we try to bring more curious minds into the conversation.
Production and marketing by penname.co. For inquiries about sponsoring the podcast, email [email protected].