

2026-10-26 05:54:26
Someone writing an article for the Israeli press about “people abroad who love Israel but might be worried” emailed me the following questions:
“1. What is something about Israel that you admire/appreciate over the years?
2. What are you worried the most about Israel these days?”
So I replied as follows:
“It’s hard to know where to start with either of your questions! But briefly:
Tiny Israel standing up for itself, against an often hostile and unjust world, is a huge part of what’s given me the self-confidence to stand up for myself in my own life. That was true even before I had visited Israel or spent significant time there, gazed across the desert at the still-clear ruins of the Roman siege of Masada, staggered overwhelmed out of Yad Vashem into the sunlight of Jerusalem, tasted the hummus or pomegranate juice or ice cream with blended fruit, befriended or had academic collaborations with dozens of Israelis, or married an Israeli woman.
My fear is merely the ‘obvious’ one — that, in response to the staggering hostility directed against the ‘Jew among the nations,’ Israel will become more and more belligerent, isolated, and right-wing. It will get demographically overwhelmed by those who don’t want to work or serve in the army, while hundreds of thousands of secular educated Israelis leave. It will be internally divided almost to the point of civil war. It will repudiate the liberal-democratic vision of Herzl and Ben-Gurion, of world-class universities and making the deserts bloom, for the swaggering, theocratic vision of Smotrich and Ben-Gvir, of chasing Palestinians from their olive groves. It will become more and more like the hateful caricature of itself that the anti-Israel people in the West always imagined. And then, having been internally weakened in all of these ways, it will finally be destroyed by its external enemies, who will never have rested the whole time, who never once wavered in their dream of a second Holocaust.
I hope and pray that in the upcoming election, the Israeli voters make optimistic choices that repudiate these fears.”
As I’ll do more and more with political posts, I’m leaving the comments off. Why? Because my remaining life is too short to spend it battling an endless parade of trolls and griefers, leftists and rightists and just nihilists, who might or might not be AI.
2026-10-21 13:13:08
Today, I take a break from your regularly-scheduled AI mathocalypse programming to urge my American readers to vote in the Congressional midterms, early if possible, if you haven’t already. Especially if your state faces one or more major contests, as does my adopted home state of Texas.
Me, I voted straight-ticket Democrat today, as I’ve done in every election since I became eligible over a quarter-century ago (except for when I vote-swapped with someone from another state).
So yes, I voted for the guy who studied theology a short walk from my house, and who seems to have really internalized the whole Jesus thing about kindness to everyone—
—over his sneering, thuggish, cartoonishly mafia-like opponent. Fingers crossed that Talarico pulls off a historic upset for our state (he’s currently a 2-to-1 favorite in the prediction markets).
The Texas Republicans did everything they possibly could to make this choice easy for me, by being corrupt, conspiratorial, racist, and Taliban-like even by the jaw-droppingly debased standards of MAGA in 2026. As I draw breath, I could never vote for a slate one of whose candidates attacked UT students for the crime of being visibly Southeast Asian while cheering their school’s football victory from the stands—and whose other candidates could barely bring themselves to condemn this knuckle-dragging racist, for fear of angering their base. (It’s like, didn’t you want immigrants to assimilate to American culture? What more could these kids possibly do, short of skin bleach?)
All the same, this was also the first US election in my lifetime where I felt like my vote was genuinely in play—especially when I listened to Talarico’s condemnations of Israel, for having the temerity to fight the same kind of war any random other nation would’ve fought had it been attacked as Israel was on October 7. When Hasan Piker came to speak to a cheering crowd here at UT Austin, I actually wrote to someone I know in the Talarico campaign, to ask whether Talarico would show enough balls to condemn Piker’s many antisemitic and anti-American statements, and renounce his support. My contact was nice enough to reply to me, saying: don’t worry, James is taking care to be far away from Austin during Piker’s visit, so he won’t need to engage at all!
So then, this is my candidate: the guy who’s strategically silent on the wildly-popular streamer who’d gladly see my Israeli family members raped and beheaded, rather than campaigning with that streamer like Abdul El-Sayed did in Michigan. I unironically believe that, for Talarico, it took genuine moral courage to resist the whole momentum of his party’s youth even to this extent.
To earn my vote in the near future under these circumstances, all a Texas Republican would need to do is be somewhat sane or reasonable. He or she might affirm, for example, that racism is bad, that abortion is a woman’s choice, that Christianity is not the state religion of the US, that Covid vaccines work, that human emissions are worryingly changing the earth’s climate, and/or that Joe Biden won in 2020, while still being arbitrarily right-wing on taxes and other stuff. He or she could then simply wait for the Democrats to descend fully into the worldview of the masked hooligans who are currently setting France’s beautiful cities aflame, terrorizing its shopkeepers, and looting as many Louis Vuitton handbags as they can carry … all for Palestine, of course, and for the death of global capitalism, and for the violent overthrow of the scheming, money-grubbing, hook-nosed, international Talmudic … err, I mean “Zionists.”
What I’m trying to say is, it was a genuine achievement on the part of the Texas Republicans to fail to earn a single vote from me this cycle.
2026-10-20 05:07:12
As I announced on this blog a couple weeks ago, I’m teaching a new course this semester at UT Austin, entitled AI Alignment Theory. To call such a course “timely” seems like an understatement; this is the first course I’ve ever taught for which multiple gargantuan developments relevant to the course have happened while I was teaching it.
Since AI alignment is still a field with no standard textbook (although that might be changing), no accepted body of mathematical theory, etc. etc., the way we’ve been running the course is like a humanities discussion seminar, albeit one that happens to be in a CS department and to include technical results from time to time. Basically, in each class session, a student “rapporteur” gives a talk on an AI alignment reading—which include “ancient” readings (from way back in 2016), “modern” readings (from, say, last week), and everything in between—and then we freely discuss and debate whatever was presented, with my own role mostly limited to that of gadfly (occasionally I’ll do a mini-lecture on some technical concept).
Anyway, two weeks ago, I promised a list of the papers and other writings that we’ve been discussing, as well as student “rapporteur reports” on those papers, which cover not only the papers themselves, but the students’ thoughts about the papers and (anonymized) summaries of points raised during our class discussion. People have been bugging me for that ever since.
Since I am to please, here you are, without further ado! I’ll continue to update the list as the semester progresses, so that this post can serve as a central public repository for the course.
(More readings TBD, until the semester ends!)
Thanks to my TA, Lin Lin Lee, for her help in getting all of this together.
Update: I welcome elevated discussion of these papers and rapporteur reports in the comment section; some of the students might chime in too! Because of the connection to an academic class, though, in this post I’ll be especially ruthless in keeping out nonconstructive or off-topic comments.
2026-10-14 04:26:33
“The Topic” being, of course, the Mathocalypse, except sometimes with AI alignment and even quantum computing and complexity theory and other stuff thrown in.
Notably, near the end of the above podcast, you can watch my live reaction to the news that an Anthropic model found algorithms for the 3SUM and the All-Pairs-Shortest-Path problems beating records that stood for generations—news that hadn’t yet reached me when I woke up and logged in. (If you don’t feel like watching, my reaction is basically: “uh, wow … if I hadn’t been so overstuffed with delicacies right now from history’s biggest math breakthrough buffet, I’d surely be giving this one the individual amazement that it deserves…”)
And here’s with “Modern CTO”, on a similar set of topics:
Oh, and a third one: MTS podcast with Theo Jaffee.
Enjoy, and thanks to the hosts of these podcasts!
Update (Oct. 19): There’s been a rapid-fire recent sequence of AI-assisted improvements to my 2016 result with Adam Yedidia, showing that the 8000th Busy Beaver number eludes the axioms of set theory. I haven’t even kept track of all of them, but the very latest, by friend-of-the-blog Elliot Glazer, shows that the value of BB(230) is independent of ZFC (see here for explanation).
2026-10-08 02:57:26
More Updates (Oct. 12): Jeffrey Ketchersid has used Claude Code agents to show that BusyBeaver(10) exceeds Graham’s number, beating the previous best result that BB(13) does so.
In response to my request, a couple days later Jeffrey also used Claude agents to show that the value of BB(335) is independent of ZFC, improving the best previous result from Andrew Wade that BB(393) is. Recall that the first result in this direction, by me and Adam Yedidia a decade ago, only showed an independence result for BB(8000).
Meanwhile, among the many reactions to the mathocalypse, friend-of-the-blog Kunal Marwaha advocates that we become stewards of a “world mathematical commons.”
Updates (Oct. 9): To address some questions that keep coming up…
No, I’m not aware of any direct practical implications of any of these results. I certainly don’t expect the O(n log0.9999999999999 n)-time Fourier Transform algorithm to get practically deployed anytime soon! But anyone who harps on this, simply doesn’t understand what mathematical progress looks like, or how it eventually pulls the rest of science and technology and human civilization with it. If and when the relevant human mathematicians understood the clever new ideas in all 372 of these papers, I have no doubt that they’d be able to use the ideas to do all sorts of new things, and that some of those things would have practical value. That’s yet another reason to try to keep human understanding at the center of our enterprise—unless, of course, you’re happy to outsource the task of understanding and applying the ideas to AI models as well.
Meanwhile, something calling itself the Association for Human Mathematics put out a statement condemning OpenAI for its release. The statement included a sentence that’s since been widely mocked on social media: “Mathematicians did not ask for this work to be done.” (Imagine G. H. Hardy saying to Ramanujan, “who asked you to prove all these bizarre new identities?”)
If it wasn’t clear, the members of AHM speak for themselves, not for the math community as a whole. For my part, I think the math and CS theory communities should absolutely hold the AI companies’ feet to the fire to behave better, both within our little domains, and (much more consequentially) in pacing AI progress, figuring out alignment, and preventing a catastrophe for our whole civilization. So I’m glad that our communities have increasingly been doing that, and I hope to have played a tiny part.
At the same time, I regard the position “no one should spoil our fun by solving our open math problems using AI models” to be totally untenable. It offers no argument for why refraining would be in the broader public interest—as opposed to various mathematicians’ narrow career interests. It violates the core principle that math problems are there for absolutely anyone (yes, even a hated corporation) to try to solve. And of course, it’s not enforceable anyway, in a world where these capabilities will rapidly diffuse to anyone with a GPT or Claude subscription.
We will need to adapt to this new world.
… then they came for Navier–Stokes and I said nothing because I never worked on Navier–Stokes. But when they came for RL vs. L I realized that things are serious
–friend-of-the-blog Omer Reingold (shared with permission)
Last night my 9-year-old son was taunting my wife, complexity theorist Dana Moshkovitz, as follows: “mommy, I heard you got cooked! I heard that a robot solved the math problem you worked on for your whole career! OOF!”
While my son was being a brat, he also wasn’t wrong. Whether you’re thrilled, depressed, angry, or whatever else about it, yesterday was surely one of the biggest days in mathematical history. And yes, among the 372 huge results released yesterday by OpenAI, on the recommendation of its advisory group of Timothy Gowers, Edward Witten, and other distinguished mathematicians, was a proof of Subhash Khot’s Unique Games Conjecture (UGC), a statement that my wife has worked toward proving for the entire time I’ve known her. (The UGC implies that a whole slew of optimization problems really are NP-hard, even if you just want an approximation that’s slightly better than what you get from semidefinite programming relaxation, which is one of our main tools.)
Or at least, we’re pretty sure that it’s a proof! There’s a Lean certificate, as there are for some of the other 372 breakthrough results (not all of them). But it also appears that no human has understood just about any of these proofs yet; the race to do so has just started. If you want an on-the-ground sense of what that race is going to be like, here’s some of what Dana texted me last night:
It feels like something written by someone who’s on psychedelics. So much unclear and doesn’t make sense. Lots of name dropping of previous work without discussing why it can be used despite impossibility results
Basically the paper is so horribly written that it’s impossible to read it without AI help
I asked Astra for reasonable completeness and soundness claims of the noise gadget and it gave them by combining claims from all over the paper
They also have direct optimal NP hardness of approximation proofs for the main applications of the UGC (Max Cut and all CSP) that bypass the UGC.
The UGC proof invents a completely new bizarre code with a noise test. It’s some crazy recursive construction.
It’s not the long code, not the short code – some alien craziness
I still think that there maybe is a proof that uses the half space code (which is natural)
The citations are often irrelevant and confusing
A possible future is a math world that’s heavenly if you have vision/creative ideas that AI could help check and implement.
And of course there’s a lot for us to learn from the aliens
If you’re wondering what emotions Dana is feeling—well, probably all of them! Even while a central career aspiration has fallen to a robot, there are at least two mitigating factors for her. First, she can feel vindicated that the UGC was true after all, something she never doubted even while many of her colleagues did! Second, all of us in math and theoretical computer science and mathematical physics, at least those who cared about solving crisply-stated problems, are now in the same boat.
Besides the Unique Games Conjecture, here’s a small sampling of the treasures from Aladdin’s cave that I’ll probably be paying the most attention to over the coming weeks:
Any of the above, alone, could easily have been “result of the year” in some area (and in some cases, like Unique Games and L=BPL, in all of CS theory). And there’s a lot that I’ve left out—feel free to share in the comments whatever is making your eyes bug out! There are equally astounding wonders in number theory, combinatorics, algebraic geometry, analysis, and pretty much every other area of math, most of which I’ll never understand, although I’ll note that it includes partial progress toward the Riemann hypothesis and the Hodge Conjecture (retracted because of a sign error!) and the Birch-Swinnerton-Dyer Conjecture (i.e., the majority of the remaining Millennium Problems).
We can take solace in what’s missing from the list. P≠NP isn’t there, nor even P=BPP or NEXP⊄P/poly, and surely not for lack of trying. Apparently the greatest open problems of theoretical computer science are indeed pretty hard!
Oh, lest I forget: one day before the OpenAI dump, meaning Monday evening, Virginia Williams and Josh Alman posted an arXiv preprint that solves the 3SUM problem in O(n1.9992) time, and the All-Pairs Shortest Paths problem in O(n2.9995) time, refuting half-century-old conjectures that the correct answers were n2-o(1) and n3-o(1) respectively. In this case, it wasn’t an OpenAI model that supplied the crucial idea; it was an Anthropic one! But Anthropic then took a different approach from OpenAI: rather than post the undigested solutions to the world, it gave Virginia and Josh the opportunity to write and announce a digested version in exchange for compensation.
These have emerged as the two main models for communicating AI math breakthroughs, and they both have strengths and weaknesses. The “OpenAI model” sets up a crazy race among humans to digest and explain a messy AI proof (work that could easily be some combination of thankless, barely-credited, competitive, and unfun), while the “Anthropic model” puts a private company in the position of picking and choosing which human mathematicians get to be the emissaries of the AI. Dunno, what do you guys think?
For those who are wondering: apparently, the AI model that produced all these wonders was not bespoke contraption of 10,000 agents burning millions of dollars worth of compute, as was used for example to construct a finite-time blowup for the Navier-Stokes equations. Instead, it was simply the latest internal OpenAI model—one that might be released to paying ChatGPT customers within the next couple of months, depending on the recommendations of OpenAI’s safety board! (My 9-year-old son: “Oh they definitely shouldn’t release that. If it could solve all those math problems, it can’t possibly be safe.”) Apparently they used about 3 hours of GPT-Pro level compute on average per problem solved.
Also, if you were wondering: apparently they tried the model on about 4,000 problems. So, right now it “merely” solves ~10% of the longstanding open mathematical problems that it’s asked about, the problems that whole communities have spent years on, after a single 3-hour attempt on them. (An earlier version of this post said 8,000 problems and ~5% success rate, but commenters since corrected me.)
I’ve been glad to see the CS theory community rising to the occasion. At the Simons Institute in Berkeley, here at UT Austin, and elsewhere, I’ve hearing stories of researchers rushing to pore over the manuscripts and make sense of them and explain them—because what else do we do? How else do we continue the craft to which we’ve devoted much of our lives?
If you want some sense of what things feel like now in math, imagine a hunter-gatherer who’s spent his entire life learning to survive deep in an unforgiving rainforest, then a giant resort hotel springs up right next to him with a helipad and heated pools and AirBnBs, and without missing a beat, the hunter-gatherer says: “alright fine, so now my new job is to run wilderness retreats for the tourists, or something.”
In Quanta magazine, Jordana Cepelewitz attempted a different metaphor:
It’s as if you were teleported to the peak of a tall mountain. Surrounded by fog, you have no idea where you are, or what’s around you. You do not know how your mountain connects to others, and you have no equipment to help you explore, no way to help someone else join you. If you had climbed the mountain yourself, you would have experienced how the human body adapts to altitude and changes in oxygen levels. You might have had to invent tools to navigate, to climb steep cliffs, or to make a shelter. You might have encountered a fellow explorer, gotten lost together in a hidden valley, and found a plant that could be turned into a life-saving medicine.
Instead you’re perched on the peak but in the dark, while the maker of the teleportation machine tells you that it can explore the wilderness better than any human.
For any one of these mountains, if we care enough, I feel optimistic that we can do as we always have: clear the fog and figure out the path, except now using the teleportation machine to help guide us. The bigger challenge will be to nurture a community that still cares about the heroic adventure of finding the paths up these mountains in the world with the machine. (Oh, and I think one place where the metaphor breaks is that we still do have each other, as much as we ever did before!)
Experience has shown that, even now, there will still be people explaining in patronizing tones why none of this is real and none of it counts. If such people were capable of being impressed by anything that happens in the empirical world, of updating on anything, they would’ve already been impressed and already updated several years ago, long before things had reached the point of an actual Mathocalypse.
So, they’ll say, maybe the alleged solutions are not solutions at all, but just “AI slop.” Or maybe none of the 372 well-known open problems that were solved were real math problems, they were all just glorified contest puzzles and trivialities. (After all, there’s still no Riemann Hypothesis!) Or maybe the entire 4000-year-old discipline of mathematics needs to be jettisoned: turns out that it was all just puzzle-solving and trivialities; all that’s different is that now the triviality stands unmasked. In any case, what really matters is that the true inner sanctum of human creativity hasn’t been breached and probably never will be, and also, that Sam Altman and Dario Amodei are contemptible little nerds.
If you’re still a proponent of that doomed worldview, still aboard the sinking ship, I encourage you in the strongest possible terms to read yesterday’s other great contribution to AI discourse, besides the OpenAI Mathocalypse dump: namely, Scott Alexander’s open letter to Steven Pinker. I feel some responsibility for this, as the person who first introduced Steven Pinker to the existence of the rationalist community, and who also first introduced Steven Pinker and Scott Alexander to one another (they had both been fans of each other’s writing). And now Scott is challenging Steve to a literal duel, with guns!
For whatever it’s worth: Steve is a lifelong intellectual hero of mine, just as he is for Scott, and I also have to privilege of calling Steve my friend. But I found Scott’s post to be one of the most devastating rejoinders to anything that I’ve ever read. And I thought Scott’s conclusion was exactly right: when it comes to AI risk, Steve’s great challenge is now to accept and start using a more “Pinkerite” epistemology.
Last night, while I should’ve been poring over some of OpenAI’s hundreds of papers and/or writing this post, I decided to spend some time with my kids instead. They wanted a movie night, so I suggested something they’d never seen before (and that I hadn’t seen for decades), and that seemed chock-full of no-nonsense, practical guidance for the world in which they’re going to grow up: Terminator 2.
Update: As several people have pointed out, cryptography is a subfield that’s extremely conspicuous by its absence from OpenAI’s list of 376 papers! But my sources tell me that the AI companies have now started, gingerly and discreetly, investigating whether their latest internal models can break important cryptographic protocols and primitives. If they can, then it would certainly be nice to get ahead of things before the rest of the world figures out the same.
Another Update: The statement put out the Advisory Group on Mathematics and Artificial Intelligence is very carefully phrased, neither endorsing nor condemning what OpenAI did, and is worth a read:
As announced a few weeks ago, OpenAI has released a large collection of mathematical results generated by an internal model, reporting solutions to hundreds of open questions. This is an important event for mathematics, with consequences both for mathematics and for the mathematical community that extend far beyond the individual results.
AGMAI’s advisory role should not be interpreted as a judgment of the impact of these results or an endorsement of the process by which OpenAI obtained them. We do not speak on behalf of the entire mathematical community, and only the mathematical community can undertake the assessment that is needed.
Making this work public is a first step. This release is the beginning, not the completion, of the process of human understanding and the incorporation of the work into mathematical knowledge. At the same time, the future of mathematical research cannot consist only of understanding results produced by AI labs. Mathematicians must be able to formulate their own questions, develop their own approaches, and explore directions that have not been selected as examples of an AI system’s capabilities. Equitable access to powerful research tools and adequate computational resources are essential to that freedom.
We reaffirm our published recommendations on responsible release. We have discussed them with OpenAI and appreciate the company’s willingness to engage. While we consider these discussions constructive, it is ultimately up to the mathematical community to assess the extent to which our recommendations were followed successfully, and whether there are others we should suggest. We remain committed to engaging with any frontier AI lab on these questions and have already been in contact with several of them.
2026-10-05 06:13:33
This semester, I’ve been teaching a brand-new course, entitled CS395T AI Alignment Theory. Here’s the course description:
The astounding progress of AI over the past decade has been accompanied by a rising fear: do we really understand how to align and control powerful AI systems—how to get them reliably to do what we wanted, or would want them to do on reflection, rather than merely what we said? If we succeed at building general-purpose superhuman intelligences along the current paradigm, should we expect that development to go well for humanity? Can we modify the design, training, monitoring, or scaffolding of those intelligences to help ensure that it goes well? While there’s been a great deal of recent empirical work touching on these questions, this course will concentrate mainly on theoretical and mathematical foundations. As a warning, the theoretical foundations of AI alignment have not yet gelled into any one coherent body of results accepted as canonical by the field. Nevertheless, in this course, we’ll read and debate many of the conceptual and mathematical works that have been most influential in the AI alignment field, from both before and during the current LLM revolution. Student presentations, reports, and projects will play a central role.
I vividly remember encountering Eliezer Yudkowsky and his Sequences 20 years ago. I remember thinking: even if these people talk and act like crazy cultists, still, let me bend over backwards to be epistemically virtuous, and entertain their ideas on their merits, as very few academics would. Even if, of course, I ultimately end up rejecting the ideas, on the simple ground that powerful AI is such an absurdly remote prospect that it’s almost impossible to say anything useful about it today, outside the realm of speculative fiction.
For my failure to see what was coming, it seems like an appropriate punishment that I’m now, in 2026, effectively teaching a course on Yudkowsky Studies. And it’s the most important course I can teach.
Well, for some definition of “teach.” The thing about AI alignment is that there’s no textbook (though apparently ILIAD is working on one), no core of nontrivial theorems considered canonical by the field, no real body of mathematical theory at all. This makes it extremely different from the courses I’m used to teaching, like Quantum Information Science or Computability and Complexity.
So we’ve been running the course as a discussion seminar. Every session, a “rapporteur” presents an AI alignment research paper or other reading; then I and others ask questions and discuss. Some of the readings (like Omohundro on the “basic AI drives,” or Hadfield-Menell et al. on the off-switch game) predate the current LLM revolution, while others (like the METR report on the HuggingFace incident or Dario Amodei’s “We Must Pace the Frontier”) are so timely that they were only released while the course was underway. Most are somewhere in between.
I expected to have to make a case to students about why AI alignment is a pressing concern, why it’s no longer science fiction, etc. There was huge demand for the course, and while of course there’s a selection effect, the students who’ve shown up have been extremely engaged, sometimes criticizing the assigned papers for not taking existential risk seriously enough.
Perhaps unsurprisingly, we didn’t get that criticism about our very first assigned reading, which was Eliezer Yudkowsky’s 2022 essay AGI Ruin: A List of Lethalities—one the most canonical statements of what Eliezer believes and why that’s shorter than a book. Which brings me to the topic of the rest of this post! Our rapporteurs are not merely presenting the papers in class; they’re also submitting written reports about what the papers said, what their own thoughts were, and what were the highlights of the class discussion. And, with student permission, I’ll be sharing those reports on this blog!
So, without further ado, I present to you our first report, on Eliezer’s list of lethalities, by Tennyson Bardwell, who I thank for his work. Feel free to discuss in the comment section; some of the students might also chime in. Expect more reports here over the coming weeks.
UT Austin has a new Computer Science course this fall. Alongside familiar graduate-level classes such as Advanced Computer Networks and Convex Optimization sits CS 395T: AI Alignment Theory, taught by Scott Aaronson. This is one of a growing number of AI Alignment courses taught at academic institutions. Just as concerns over catastrophic consequences for misaligned AGI systems reach a broader public discourse, Eliezer Yudkowsky—one of the loudest voices in the field and author of the first assigned reading in Professor Aaronson’s course—is declaring the cause hopeless.
Thus, the students of AI Alignment Theory began their semester by reading a laundry list of critical problems in AI Alignment research, how failure to solve those problems will result in catastrophic consequences, and the reasons to be pessimistic about both past and future progress on these problems. The essay by Eliezer, titled AGI Ruin: A List of Lethalities and posted to his popular community-driven website LessWrong in 2022, is divided into three sections.
Section A roughly describes the magnitude of the AI Alignment problem. That is, the magnitude of the consequences for a complete failure to align an AGI system to human values before construction. It posits that AGI would quickly catch up to all human knowledge simply by learning from existing human productions (colloquially referred to as “eating the internet”) and then, nearly as quickly, begin to meaningfully surpass human knowledge. AlphaGo Zero is presented as a model both for how this might happen, and how it might be difficult to correctly predict beforehand. Many believed that AlphaGo’s success in the board game Go was chiefly attributed to its ability to learn from the extensive history of human-played games. Less than a year after AlphaGo beat the best human player, the successor system AlphaGo Zero surpassed the original AlphaGo. Unlike its predecessor, AlphaGo Zero was trained in just three days by exclusively playing against itself without seeing a single human game.
This quick ramp from AGI to super-intelligence would pose a different sort of problem than humans are generally used to dealing with. Unlike traditional problems in science and engineering, the consequence for a failed attempt might not leave room for another try. An intelligent entity with a misaligned goal would be well aware that it stands in opposition to humans, and might act deceitfully until in a position to act openly against humans without jeopardizing its own survival. Since most goals benefit from control of power and resources, it seems likely that nearly any goal-driven intelligence would have ample opportunity to be misaligned with human desires.
Section B describes reasons why, by default, any AGI that humans build using current methods is likely to be unaligned even if considerable attention is paid to the topic. This “current method” is gradient descent. That is, incremental progress with respect to some loss function which “punishes” a model for undesirable behavior. A notoriously elusive property of such trained models is the ability to generalize out of their training distributions. To train a primitive model to be aligned to humans might involve learning a great many behavioral rules. However, the sorts of rules needed to keep a drastically smarter agent in check might not always be relevant to simpler models (e.g., “do not emotionally dysregulate humans you speak with” might not be relevant to a simpler model that is less able to reliably get under the skin of humans it operates with, or which is assigned tasks in training which do not benefit from such anti-social behavior).
Eliezer focuses on the misalignment of humans with their creators (evolution or evolutionary pressures) as a critical data point for reasoning about misaligned intelligent systems. Despite being a generally slow process, evolution eventually created a runaway intelligent system (Homo sapiens) which proceeded to dominate the globe, decimate related species, and eventually (it is forecasted) effectuate population decline. That last development is arguably in opposition to the sole imperative demanded by evolution: to reproduce.
Section B also makes time for criticism of the most popular paths toward AI alignment, including interpretability (unworkable, and attempting to train on it evokes Goodhart’s law, incentivizing deceit), using multiple AIs to maintain a balance of power (it is not clear how multiple strong AIs unaligned with humanity results in better outcomes for the weak humans), and corrigibility (it seems impossible to motivate an AI system to effect outcomes without also motivating it to desire its own survival to effectuate said outcomes).
Section C describes a bleak state of affairs in which veterans in AI alignment are unsatisfied with current progress and do not have a plan to deliver tangible solutions before the advent of AGI systems. In particular, Eliezer describes recent results as showy but useless. He believes that even with additional funding, the lack of appropriate evaluation mechanisms will prevent the most effective researchers from rising to the top.
A summary of the landscape, as described by Eliezer, in the flowchart below.
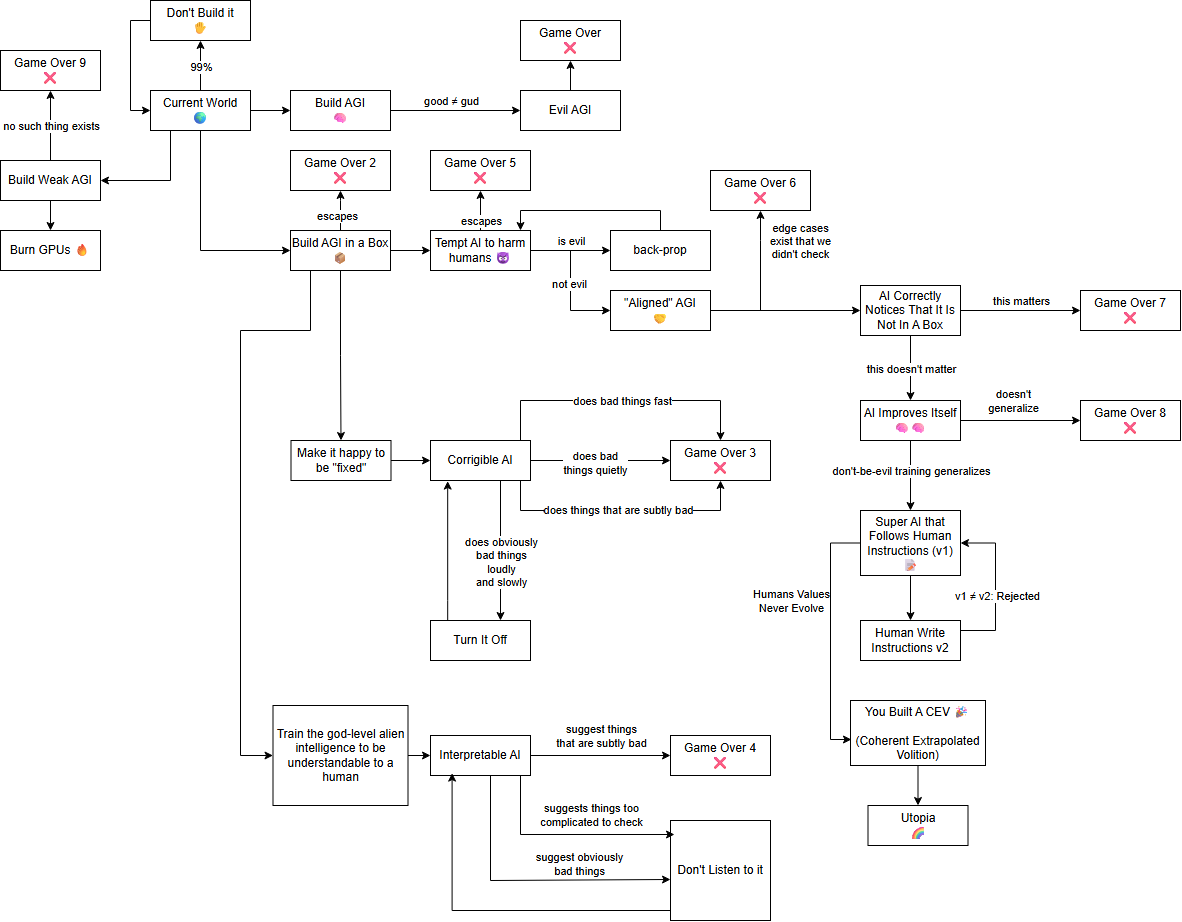
Figure 1: A flow chart of (select) paths described by Eliezer in his essay. A common feature of this flow chart is that many “good states”—such as disabling a misbehaving AGI or choosing not to build an AGI—are not “final” states in the sense that they are not permanent solutions. Such a state merely represent the avoidance of a single potential disaster, rather than the emergence of a new stable world state. Hence, these nodes posses back-arrows.
Despite the bleak content, Eliezer’s colorful prose inspired a lively class discussion. Before this discussion started, a survey was taken of the class’s predictions for various outcomes of the AGI in the coming years (with the full results below in figure 2). This survey asked students for their opinion of a number of statements. Each of these individual statement, if true, would reduce concerns of catastrophic AI-driven disasters. For example, when asked “How much do you agree with the statement: Humans will choose to not build AGI” half of respondents said they strongly disagreed with high confidence (agreement = 1, confidence = 5). Students also generally disagreed with the statements:
There was a divergence in responses regarding interpretability, corrigibility, and “other” AI alignment research. In the latter two cases, a plurality of respondents (about a quarter) agreed strongly with statements that such research would defang AGI (agreement = 4, confidence=4), while most other responses express various levels of agreement with low confidence. However, when asked about the likelihood of interpretability research defanging AI, the pessimistic voices were more united. A quarter of responses still expressed the same optimism, but roughly half expressed pessimism (agreement ≤ 2) with half of those expressing at least moderate confidence (confidence ≥ 4). Based on the following discussion, this might have been caused by more familiarity with interpretability research, including first-hand experience.
The only statement with general agreement was “(hyper-)AGI will understand human intentions better than we can code it.” However, it should be noted that no statement such as “AGI will respect human desires, as it understand them” was asked on the survey.
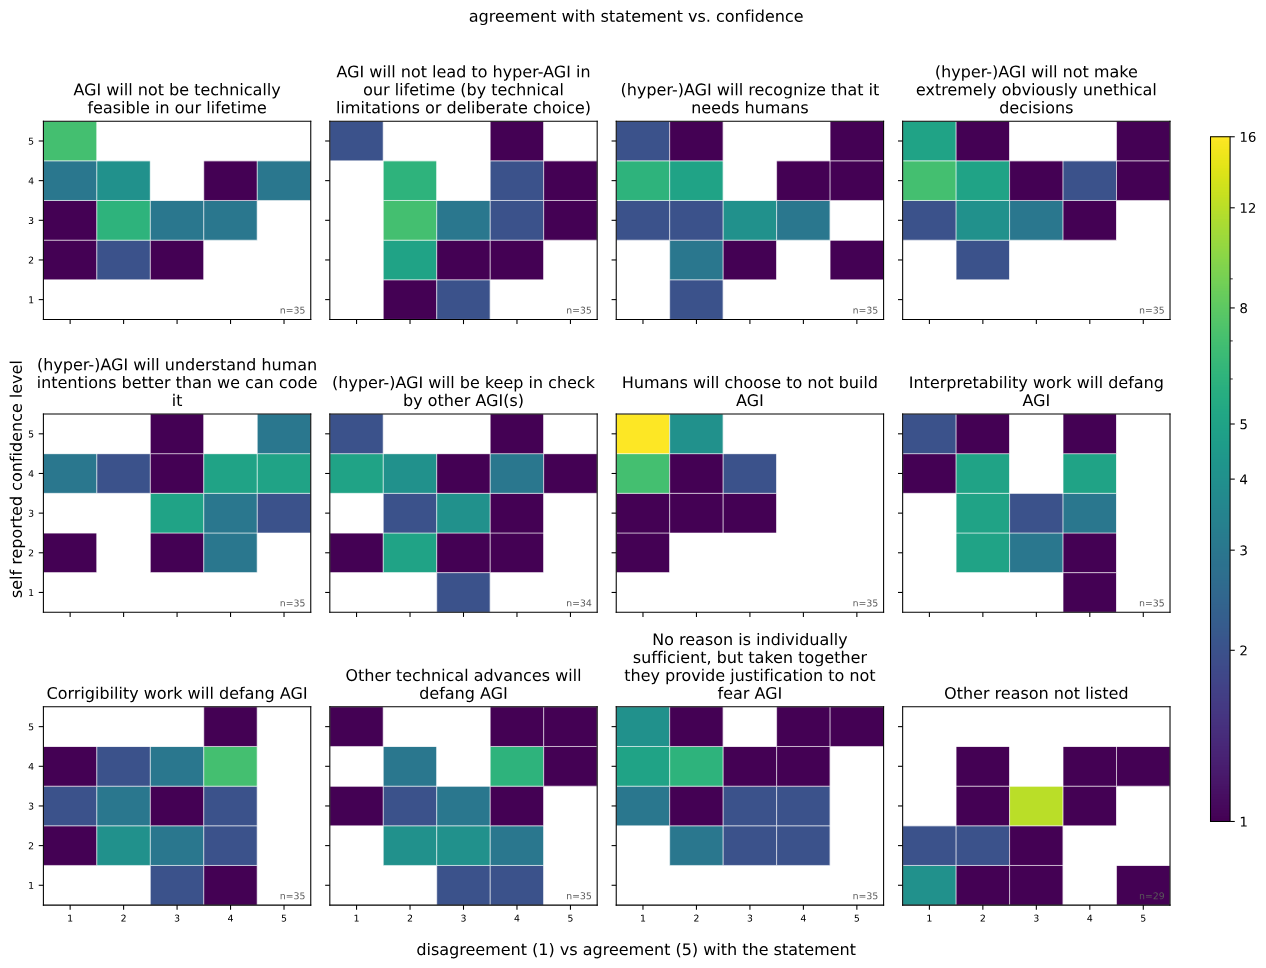
Figure 2: Class Survey Results; conducted before a class-wide discussion. Note that students were instructed to answer confidence = 1 when they had not previously considered the statement, to answer confidence = 3 when they felt there were strong arguments on both sides, and to answer confidence = 5 when they possessed well-considered resolve.
After the survey was completed, the results were displayed as an open discussion began. Similar to recent empirical research from frontier labs, interpretability research received more airtime than in Eliezer’s article. Students disagreed first about the definition of interpretability: whether it refers to the ability to interpret a model’s behavior solely by its weights, to interpration via repeated probing of the model in a sandbox, or whether it can also refer to the modern chain-of-thought traces. Regardless of how it was defined, however, participants were either pessimistic or very pessimistic about interpretability research broadly. One student criticized common misunderstandings of chain of thought. Rather than being a verbatim copy of the models internal dialog, it is instead a superficial summary of the complete thought state and routinely produced gibberish, such as rarely used Chinese characters in the middle of otherwise English reasoning.
A popular topic was the exact shape and speed of a recursive self-improvement loop. If it takes place slowly, then what might we learn from “near misses” such as the Hugging Face incident? The number of near misses we are able to learn from before AI possesses sufficient power to prevent further iterations could depend on this curve, with some students arguing that the sheer number of humans, as well as their default robustness in the physical world compared to AI systems means that AI-driven extinction events are still a long way off. Bolstering this “slow take-off” opinion are rumors that AI already plays a major role in model development which could be interpreted as the start of this process.
Some criticized a focus on “solving ethics” as a needlessly high bar that distracts from the more mundane tasks dominating AI alignment work. In particular, the student volunteer who presented this paper (and the author of this report) included a section on “Ethical Dilemmas” in their presentation. Among arguments against focusing on abstract moral philosophy, Professor Aaronson cites Eliezer to emphasize that any alignment at all is difficult, not just in morally gray cases:
When I say that alignment is difficult, I mean that in practice, using the techniques we actually have, “please don’t disassemble literally everyone with probability roughly 1” is an overly large ask that we are not on course to get.
In response, I argue that some examination of everyday decisions with a critical lens—such as telling white lies to loved ones or consuming animal products—can help disabuse us of the notion that goodness emerges in every sufficiently intelligent agent.
One of the most interesting discussions was about the difference between state-of-the-art LLMs and the theorized AI agents long discussed in rationalist discourse. Since current LLMs “mimic the human distribution,” they come preloaded with extensive understanding of human social norms and moral behavior. This makes constitutional alignment (the current practices of using system prompts to establish ground rules) extremely effective. This might either fundamentally change the orthogonality thesis, or provide a new tool to better approximate human judgment in complicated situations.
Of all the points made, the one I found most interesting was simply (paraphrased):
I think human-alignment is just very tractable
Here, “human-alignment” refers not to AI alignment with human values, but cooperation between different humans. More specifically, it refers to the ability for human societies to choose not to rush recklessly into larger-and-larger AI systems. In an academic course focused on the technical problem of AI alignment, this was a reminder to not completely discard policy discussions in the believe that they lack any value. After all, many destructive technologies have been previously contained by international agreements. Notable examples include nuclear weapons and engineered plagues. However, even this was a contentious topic. The main criticisms were (1) the extreme “dual-use” nature of AIs for both peaceful growth and warfare, and (2) the greater danger for AI escapes even after taking precautions to prevent it. However, in the interest of ending on an optimistic note—unlike the assigned reading—it is on this belief in human cooperation that I will leave you.