

2026-10-30 20:58:11
Hi friends 👋,
Happy Friday and welcome back to our 217th Weekly Dose of Optimism.
And what a week it’s been! Per New York Metro Weather, we’re in the midst of the longest streak of 8/10 or higher days since the account started in 2021, and here at the Dose, we’re in the middle of a string of 9/10 or higher weeks so long that I’ve lost count.
Have a great Halloween tomorrow. For now, all treats no tricks.
Let’s get to it.

The Document Editor Built for AI Products
AI products need more than file generation. They need a fast, accurate document editor that agents can also use.
Reducto Editor brings full-fidelity DOCX, PPTX, and XLSX editing into your product through an SDK and embeddable UI. Lightweight and browser-based, it gives agents the tools to revise contracts, update presentations, and edit spreadsheets while preserving formatting and all the functionality you’re used to.
Users collaborate in the same file, review native Word tracked changes and comments, and make their own edits without leaving your application. Files retain their full formatting when opened in Microsoft Office.
From the team behind the document infrastructure trusted by Harvey, Scale AI, Toast, and Vanta, Editor runs in the browser or on your own servers.
Another week, another extension of Anduril’s capabilities1.
Last week, we wrote about Warhound, Ben Lamm’s effort to (humanely) genetically engineer dogs to be used in police and military work. Anduril is providing “software and hardware enhancement for items such as dog protection vests and eye goggles.”
This week, Palmer Luckey announced that Anduril would be making its very own Made in America computer, BlueChip: designed here, with components from here, with metals America can mine, refine, process, and mill at scale and at reasonable price. American batteries, too.
This is cool because as Palmer says in the video, “If you don’t control your technology, you can’t control your future.” But it’s also cool because it seems as if Anduril has gotten to the point where it’s built a machine that can make machines. Assemble enough engineers, capital, manufacturing capacity, distribution, etc… and you can build almost anything. It’s very Elon Companies-esque.
And as we wrote in The Electric Slide, making products that can sell a ton of units, like laptops, can create the pull to bring more of the supply chain here, too.
Video created with Runway
The race to solve everything solvable continues apace.
This week, OpenAI announced “three new discoveries in mathematics, computer science, and physics about harmonic analysis, complexity theory, and quantum field theory.”
In math, OpenAI’s models produced a proof of Christopher Sogge’s 1991 local smoothing conjecture in every dimension, which would also settle the Kakeya conjecture and Stein’s restriction conjecture (of course). For context, Hong Wang and Joshua Zahl proved Kakeya in three dimensions just last year, and it was one of the biggest math stories of 2025.
In computer science, a model refuted the Exponential Time Hypothesis (ETH), the widely held belief that problems like 3-SAT can’t be solved meaningfully faster than brute force. If that makes no sense to you, check out the explainer video I made with Runway, which breaks it down in claymation well enough that I could actually understand it.
In physics, the models produced a rigorous proof that interacting quantum field theories, including QCD and pure Yang–Mills, exist in four dimensions. That’s half of a Millennium Prize problem.
Whereas before OpenAI has just dropped a bunch of solutions on the internet’s head and walked away, leading to quasi-embarrassing situations like when they said GPT-5 had solved ten open Erdős problems but it turned out the model had mostly found solutions that were already sitting in the literature, this time, OpenAI is sharing the outputs as research data with experts they call “shepherds” in each field, who will choose what to do with the data and where/when to publish.
Shepherds don’t have to sign NDAs, don’t get paid, and do get the credit for explaining the work. Russell Impagliazzo and Ramamohan Paturi, who proposed ETH, are leading the review of its disproof with MIT’s Ryan Williams. Nobel laureate David Gross is leading the physics group, which chose to withhold the AI material and write it up themselves. The math proof and the ETH disproof are on GitHub with Lean formalizations. Lean, a checking software, guarantees the proof proves the formal statement, but human shepherds still have to confirm that the formal statement is the right one.
Big week for Lean, by the way. On Tuesday, Axiom announced a complete Lean auto-formalization of the Classification of Finite Simple Groups, the “periodic table of symmetry.” The proof runs about 15,000 pages and was written by more than 100 mathematicians over several decades. It’s so big that no single person has ever checked all of it. For a sense of scale, it took Georges Gonthier’s team six years to formalize just one piece of the classification, the Feit–Thompson theorem, back in 2012. But Axiom’s machines can do a lot of human-years quickly, and they’re going to need to to keep up with all of the math and physics coming out of the labs.
Because not only did OpenAI announce those results this week, a physics neolab, Physical Superintelligence (which we covered in Dose #209) released results on five problems from IQOQI Vienna’s list of open quantum problems, each with a paper, a Lean formalization, and open source verification code on GitHub.
For those of you who were planning to spend the weekend cracking OQP 12: Can vacuum correlations violate the CHSH Bell inequality at arbitrarily large separations? or OQP 12: Can vacuum correlations violate the CHSH Bell inequality at arbitrarily large separations?, I’m sorry. Machines did it. You’re going to have to find a new hobby.
Also, if you were trying to use the entanglement between two empty regions of space no matter how far apart they are to violate the Bell Theorem, I’m sorry for you too. The machine found that you can’t do it past some finite distance.
Anyway, it seems like this is just how we do math and physics now.
Apparently, it’s how we do drug development now too, if Anthropic succeeds.
AI for drug discovery is hot, but most of the focus is on discovering new molecules, which creates bottlenecks further downstream in actually developing these drugs and getting them to market. To understand and fix them, Anthropic believes, it needs to get inside the programs themselves, so for the past several months, its life sciences team has partnered with six organizations to start running programs of its own.
At the discovery end, Divergence Labs announced positive results in the fight against food allergies. Allergic reactions are triggered by IgE, which sits on your immune cells as well as floating in your blood. Standard drugs mostly neutralize the floating IgE, so Divergence’s approach aims to pry it off the cells instead. Claude turned that goal into a design plan and, largely on its own, generated about 35,000 antibody designs in a month. Three of the early hits dislodged IgE better than the standard medication, and people seem psyched that this represents meaningful progress against food allergies.
Another biotech, Generate Biomedicines, used Claude Code to redesign part of CAR-T, the therapy that uses a body’s own immune cells to hunt and kill cancer, so that it could eventually work on solid tumors. One of Claude’s designs was about 70% shorter than the standard version and got cells to make roughly 10 times as many cancer-spotting receptors.
At BigHat Biosciences, Claude proposed improvements to two antibody fragments, and BigHat’s automated lab made and tested about 1,010 variants in 10 weeks. The best ones bound more than 10x more tightly. Along the way, Claude and an Anthropic researcher figured out that the standard stability metrics were misleading and proposed better ones.
But the point is that these improvements are still hard to get to patients, so Anthropic turned to paperwork with Enveda, whose manufacturing scientists spend up to 75% of their time on it. Claude reviewed 1,061 pages of manufacturing records, caught all of the issues human reviewers had found (plus seven they’d missed), and cut review time by 89%. It also drafted a regulatory document in four hours that takes about three months by hand.
At the trial stage, Bristol Myers Squibb is using Claude to assess plans for an early-stage drug and estimate its odds of success. The Column Group, a biotech investor, is launching Pleiades, a company built to run many more drug programs with Claude than a small team normally could. The theory is that if discovery gets cheaper and faster, investors can back riskier ideas.
Anthropic is also running programs itself. In July, it acquired Mithril Medicine, a one-person company whose founder, Cody Tranbarger (aka Professor Oak), used Claude to run experiments across 11 outside labs. In under 18 months, he took a treatment for a rare muscular dystrophy from idea to promising results in mice. In one cohort of 42 kids with the severe form of the disease, only one ever walked on their own. If the treatment holds up, human trials could start as soon as late 2028.
Anthropic is upfront that nearly all of this is preclinical, so most of these drugs haven’t been tested in people yet, but they showed speedups in every part of the process. The tricky thing about complex processes like drug development is that you have to improve the whole thing at once, lest any one thing that didn’t improve slows the whole thing down.
We might finally have a machine capable of doing just that. Bad time to be a disease. Good time to be a human.
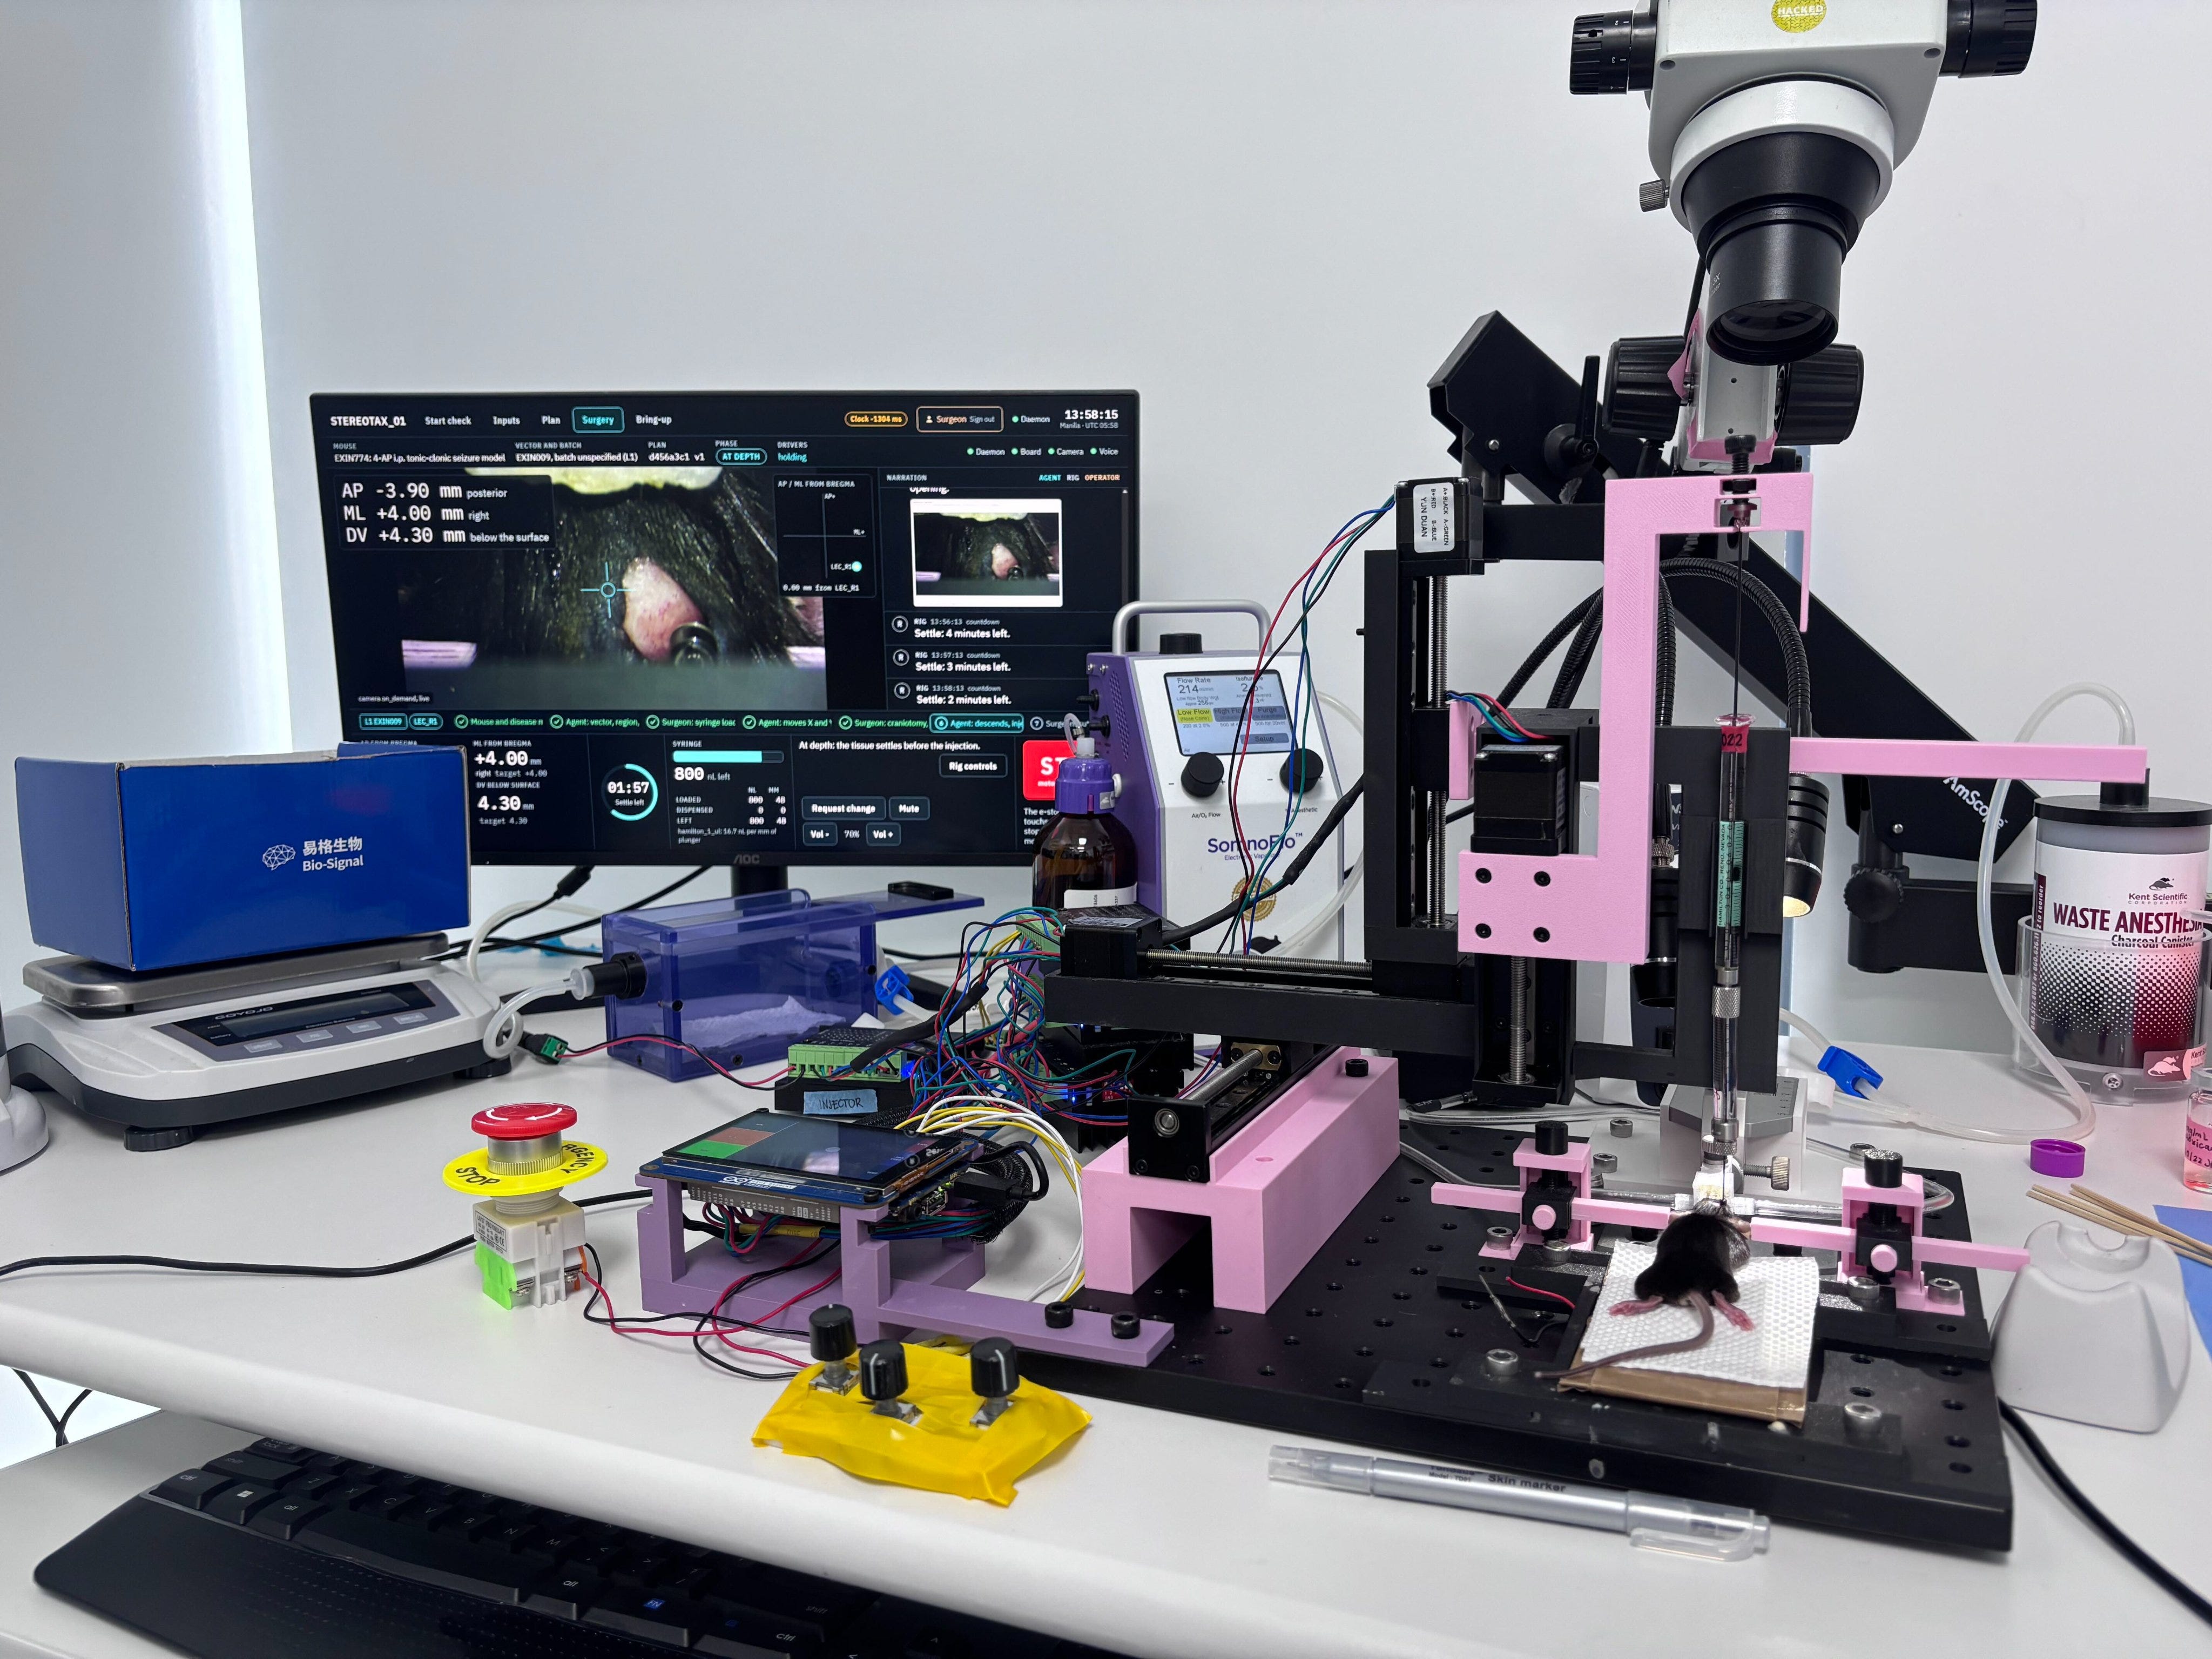
I just saw this one this morning, so didn’t have time to write it up, but that’s ok, just read the headline and the tweet thread and realize that AI AGENTS PERFORMED BRAIN SURGERY ON A MOUSE.
I’m an investor in Readwise, friends with its founders Dan Doyon and Tristan Homsi, and I love reading, so I’ve been lucky enough to get to be a part of the beta for what they were calling Bookwise and are now calling Readwise Books.
I love this app. It’s my second-most-used app on my phone, after X (need to break that habit again), and that’s not counting the time that I spend reading through Readwise Books on my Daylight Computer. The description people give most often is Kindle x Goodreads, which is part of it, but there’s also a little Strava mixed in there. There’s a leaderboard, which has definitely pushed me to read more, like the week I ended up #1 on the Readerboard in July.
The reading experience itself is familiar to those used to reading on the Kindle App, but it’s just a little bit better in places. There’s AI natively built in, which I don’t use normally, but was a lifesaver when I was reading Jean Beaudrillard’s Simulacra and Simulation, for example. Highlights go right into Readwise. And its text-to-speech is really good for listening when I get off the subway and start walking.
I am a firm believer that people should Read More Books, and although I’m biased, I’ve also voted with a ton of my time that this is the best product out there for doing that.
So go Read More Books. There’s a waitlist, but if you’re reading this, you can skip it here.

Lilly’s Retatrutide is perhaps the closest thing we have to a miracle drug.
We first covered Reta in Dose #175, as a gray-market “holy grail” in Vectorculture’s piece on Chinese peptides. By May, it was the lead item in Dose #194, after Lilly’s TRIUMPH-1 trial showed people on the top dose losing 28.3% of their body weight over 80 weeks.
Since then, the triple-hormone shot, which mimics GLP-1, GIP, and glucagon, has kept piling up wins. Now, it seems to work on sleep apnea.
Tens of millions of Americans have obstructive sleep apnea (mostly undiagnosed). The standard treatment is strapping a CPAP mask to your face every night. In two 80-week Phase 3 trials, TRIUMPH-1-OSA and TRIUMPH-2-OSA, 691 adults with moderate-to-severe sleep apnea started out stopping or nearly stopping breathing about 57 times an hour. In the trial without diabetes, the 9 mg dose cut that by 34 events an hour, versus 10 on placebo. About half of patients on the higher doses ended up with apnea that was resolved or mild without daytime sleepiness, compared with roughly one in ten on placebo. Along the way, they lost about a fifth of their body weight.
Some people have pointed out that of course, losing weight should help with sleep apnea, but OK sure whatever the mechanism, Reta just keeps fixing stuff:
Diabetes: In TRANSCEND-T2D-1, presented at ADA in June, 75–83% of patients got their A1C to 6.5% or lower in 40 weeks.
Heart risk: In TRIUMPH-3 in July, people with severe obesity and existing heart disease lost 22.6% of their body weight, with inflammation (hsCRP) down 51% and systolic blood pressure down 9.3 points.
Knees: In TRIUMPH-1, knee osteoarthritis pain fell by about three-quarters.
Liver: In a Phase 2 substudy, 93% of patients on the top dose had normal liver fat after 48 weeks.
The drug hasn’t even hit the market yet (if you don’t count the grey market). There’s still an open question as to whether these improvements also prevent heart attack and stroke, which Lilly’s dedicated cardiorenal trial will attempt to show, and which would be another massive win, but for now, we’ll just have to be happy with a drug that cuts weight, lowers heart disease risk, fights diabetes, cuts liver fat, makes our knees feel better, and replaces a CPAP.
Lilly, which crushed earnings this week and raised its full year revenue outlook by $5 billion, deserves every dollar of its $1.3T market cap.
From miracle drugs to downright miracles. Given the quantity and consistency of mind-blowing breakthroughs we cover here in the Dose, it’s easy to forget how miraculous some of them are, and how miraculous they must feel to those who benefit from them.
This week’s news out of Neuralink is one of those.
ALS, or Lou Gehrig’s Disease, is a fatal, progressive neurodegenerative disorder that destroys the motor neurons in the brain and spinal cord that control voluntary muscle movement. It takes away its victims’ ability to speak even though it leaves their mind intact, meaning they can think clearly but can’t verbalize those thoughts.
Neuralink has been working to fix that with VOICE. This week, it released early numbers from one participant who hit 75 words per minute with a 5.8% error rate across a 125,000 word vocabulary in their first week with the implant. Before VOICE, the best published result on the same vocabulary size, Stanford’s 2023 system, managed 62 words per minute with nearly a quarter of words wrong.
Natural conversation runs around 160 words per minute, so we’re about halfway there. Importantly, the system can also speak in the participant’s pre-ALS voice.
VOICE launched at UT Southwestern last October with FDA Breakthrough Device designation and plans to enroll up to six people with ALS, spinal cord injury, or stroke. That’s not a big group, and the one person in this study is just one-sixth of that. But every person who’s able to get their voice back through a BCI is a win, and the technology will only get better, faster, more accurate, and less invasive from here.
In related news, Elon Musk announced yesterday that its second product, Blindsight, which will restore sight to the blind, is ready engineering-wise.
Age of Miracles, pending regulatory approval.
2026-10-23 20:34:23
Hi friends 👋,
Happy Friday and welcome to the 216th Weekly Dose of Optimism!
It looks like the hacks this week broke a lot of the internet, but over here in our little corner of it, things are looking good. We have everything from cancer to plant communications to genetically engineered war dogs to basically alchemy. Once again, the week was so jam packed that we have more in the Extra Dose (7 Extras!) than we do up top.
Let’s get to it.
The Only Document Parsing Product You’ll Need
Reducto is the document ingestion layer trusted by AI teams at Scale AI, Harvey, Toast, and Vanta to reliably turn complex files into structured, grounded data for production AI systems at scale. Processing more than a billion pages per month, Reducto has built its reputation on the long tail of difficult documents that break conventional OCR: dense tables, unusual layouts, handwriting, low-quality scans, strikethroughs, and formatting-dependent information.
Its new frontier parsing model, r-1, combines layout detection, reading order, tables, formatting, grounding, and granular citations in a single request. It reduces parsing errors by up to 20%, improves latency at high volumes, and costs 1¢ per page all-in.
Already using another parser? Apply for up to $5,000 in migration credits and hands-on support to benchmark r-1 against your current stack on the documents that matter most.
U.S. Food and Drug Administration, Jeff Tang, Coherence Neuro; video created with Runway
We hate cancer here at the Dose, and we’re not afraid to say it. It’s probably why not a single cancer reads the Dose. We’re willing to sacrifice our numbers for our belief.
Consequently, we love when humans come up with new ways to kill cancer, and they’ve done it once again (and again, and again) this week.
In June 2022, in a small trial at Memorial Sloan Kettering, twelve patients with locally advanced rectal cancer took six months of an immunotherapy called dostarlimab. In all twelve, the cancer disappeared without chemo, radiation, or surgery.
On Monday, the FDA granted dostarlimab (GSK's Jemperli) accelerated approval as a standalone first treatment for stage II and III rectal cancers that are mismatch repair deficient (dMMR). These tumors basically have a broken DNA spell-checker, so mutations pile up until the cancer looks foreign to the immune system. Dostarlimab blocks PD-1, the off switch tumors use to keep T cells at bay, which lets the immune system clear the cancer (explained in the video above).
In GSK’s 154-patient trial, after a median of 26 months, cancer hadn’t progressed in 71% of patients treated with dostarlimab alone. In MSK’s expanded 50-patient study, every patient responded, and 93% stayed cancer-free for at least a year.
Only about 3% of locally advanced rectal cancers are dMMR, per the FDA, so this isn’t a cure for all rectal cancers, let alone all cancer, but we’re getting into a pretty consistent, almost weekly, pattern of new therapies working against specific cancers, which seems like the way we’ll beat cancer overall.
In some cases, individuals are even figuring out how to cure their own, n-of-1 specific cancer.
In #177 we led with Elliot’s story on one of those people, GitLab founder Sid Sijbrandij, going founder mode on his osteosarcoma after running out of standard options. He’s one of six people Jeff Tang included in a list of those who have cured or are curing their own cancer, or a loved one’s.
But wait, there’s more!
On Wednesday, Coherence Neuro announced that it had raised a $45M Series A from Founders Fund and OpenAI “to build cancer therapy that learns.”
The idea is to turn neurotech and BCIs at cancer to read the electrical signals surrounding it, understand how it grows over time, and influence the electrical signals to modulate the disease. Human trials are underway in glioblastoma patients, and they’re gearing up for pancreatic cancer and more.
There’s a long way to go on these and so many of the cancer treatments we discuss in the Dose, but the promising results have become a drumbeat, and it really does seem like we’re on the path to knocking out cancer once and for all.
So say it with me, as heartily as you can: get fucked, cancer.
Alexander C. Kaufman for Heatmap
As much as we hate cancer, that’s how much we at the Dose love nuclear power.
We love small nuclear reactors, and we love big nuclear reactors, and we especially love a lot of either. Big week for us, then.
It hasn’t always been so good for nuclear here in the US. In the roughly 15 years it took the US to finish its first two Westinghouse AP1000 reactors at Vogtle, China built four of them, then they reverse-engineered the design into its own Hualong One, and now they have 10 Hualongs running with at least 37 more on the way. China knows that the way to make nuclear cheap is to make a lot of reactors over and over.
The Nuclear Company, which employs a bunch of people who worked and learned on Vogtle, launched in 2024 to do just that.
On Wednesday, it announced Prosperity One, a proposed campus for up to six AP1000s, about 6.6 GW, on roughly 4,000 acres along the Ohio River in Lewis County, Kentucky.
6.6 GW is an enormous amount of power. Fully built, Prosperity One would be the largest nuclear site in the US and account for over 5% of the country’s total nuclear capacity (we’re at 97GW right now).
TNC’s plan is to build two units at a time, keeping the design consistent on each, so that it can bring down costs on each successive one, a lesson learned the hard way at Vogtle. After a slow, expensive start with Unit 3, Vogtle Unit 4 came in roughly 30% cheaper and faster. TNC Chief Nuclear Officer Joe Klecha said that 30% is the floor expected savings. The company is targeting 2028 NRC approval.
At the other end of the size spectrum, the Navy picked Radiant to install its Kaleidos microreactor at Naval Weapons Station Crane in Indiana. Kaleidos is a factory-built, 1 MW reactor (6,600 times smaller than Prosperity One), that is built centrally and shipped to sites by truck, ship, or plane. When completed (the Navy wants 2028), it will be the Navy’s first shore-based advanced reactor and the first power-producing reactor in Indiana. Radiant, which we wrote a Deep Dive on in 2024, now has partnerships with the Army, Navy, and Air Force.
ELECTRONAISSANCE.
I already had this whole thing written, with a different story in this slot, when the news dropped that Colossal Biosciences’ Ben Lamm and Andruil’s Palmer Luckey were teaming up to launch Warhound with a fresh $200M from investors including In-Q-Tel, Sequoia, and 8VC. The new company is worth $1.2 billion.
This is the advanced technology version of a superhero movie, literally in that we’re talking about genetically engineered war dogs and figuratively in that we’re seeing two characters combining forces within a wider cinematic universe. Per the website, Warhound is “combining licensed technology from Colossal Biosciences and Anduril,” which is just a really interesting way to start a new business.
“Animal welfare is central to that mission,” the company says on its website, “with American Humane certification supporting our commitment to the care and well-being of every dog.”
I don’t think I’m going to be able to say anything Lamm didn’t, so Per TechCrunch:
Lamm believed dogs could be enhanced for health, longevity, and “for things like speed and agility or enhance olfactory sensors for bomb sniffing and whatnot,” he said. His team looked at the top-performing working dog breeds — the Belgian Malinois and German Shepherd — taking the cell lines from them and putting them in a biobank. From there, they will edit the genes, adding the ones that will make the dogs perform better while taking out the ones that won’t, to create “a new type of dog.”
Andruil, meanwhile, will provide software and hardware enhancement for items such as dog protection vests and eye goggles to assist the dogs and their handlers with matters like situational awareness and coordination.
“The idea is, if we make the dog safer, make it healthier, make it perform better, it’s going to perform better in the line of duty,” Lamm said. He added that Anduril’s additions aim to make the dogs safer and healthier outside of their genetic components, “on top of the dog, not in the dog.” He believes such enhancements will also protect the dogs’ human handlers better.
This is not a new structure for Lamm. In late 2022, Lamm co-founded Form Bio, a software company spun out of Colossal, and he later launched Breaking as another spinout. As with Warhound, Colossal will own equity (Luckey won’t), but this time, it’s combining technological forces with another company, Anduril.
They’re good dogs, Brent. 16/10 please thank them for their service.
Janis Hesse, Doris Tsao, et al. on bioRxiv, video created with Runway
Late last year, in Dose #173, we covered Dr. Doris Tsao’s joining our friends at Astera to lead a new team, Astera Neuro. “The new team’s goal is to solve one of the longest-standing, most fundamental questions: how the brain produces conscious experience, cognition, and intelligent behavior.”
Just ten months later, Tsao and team are out with their first big paper, and it’s a doozy. The video above is one attempt to explain it, and here’s the word version.
If you show your left eye one face and your right eye another, you see just one face. Instead of blending them, one just vanishes from awareness, even though it’s hitting your retina. Neuroscientists use this trick, called binocular flash suppression, to separate what the brain receives from what it’s aware of.
The textbook belief has been that this happens because the suppressed image fades as signals move forward through the brain and never “ignites” into awareness. Last week, a team led by Janis Hesse in Tsao’s lab found a different explanation.
Recording thousands of neurons in the face-processing regions of two macaques’ inferotemporal and prefrontal cortex, they found that the same neurons alternate roughly every 60 milliseconds between representing the face the monkey is aware of and the one it isn’t. When they reconstruct an image from one set of moments, they get the conscious face. But when they reconstructed it from the others, they got the suppressed face in full detail.
So why are we only aware of one? Still need to figure that out.
But Tsao called it the most important discovery of her career, because it means that a decodable signal deep in the brain exists even for things you’re not conscious of, so scientists can now follow both faces and figure out exactly why we become aware of one and not the other, which should give deeper clues to how consciousness works.
Human consciousness research is one of the areas I’m most fascinated by, and I hope that this is the first of many breakthroughs from Astera Neuro and others.
As we better understand our own human brains, humans are also making progress in understanding the language of… plants.
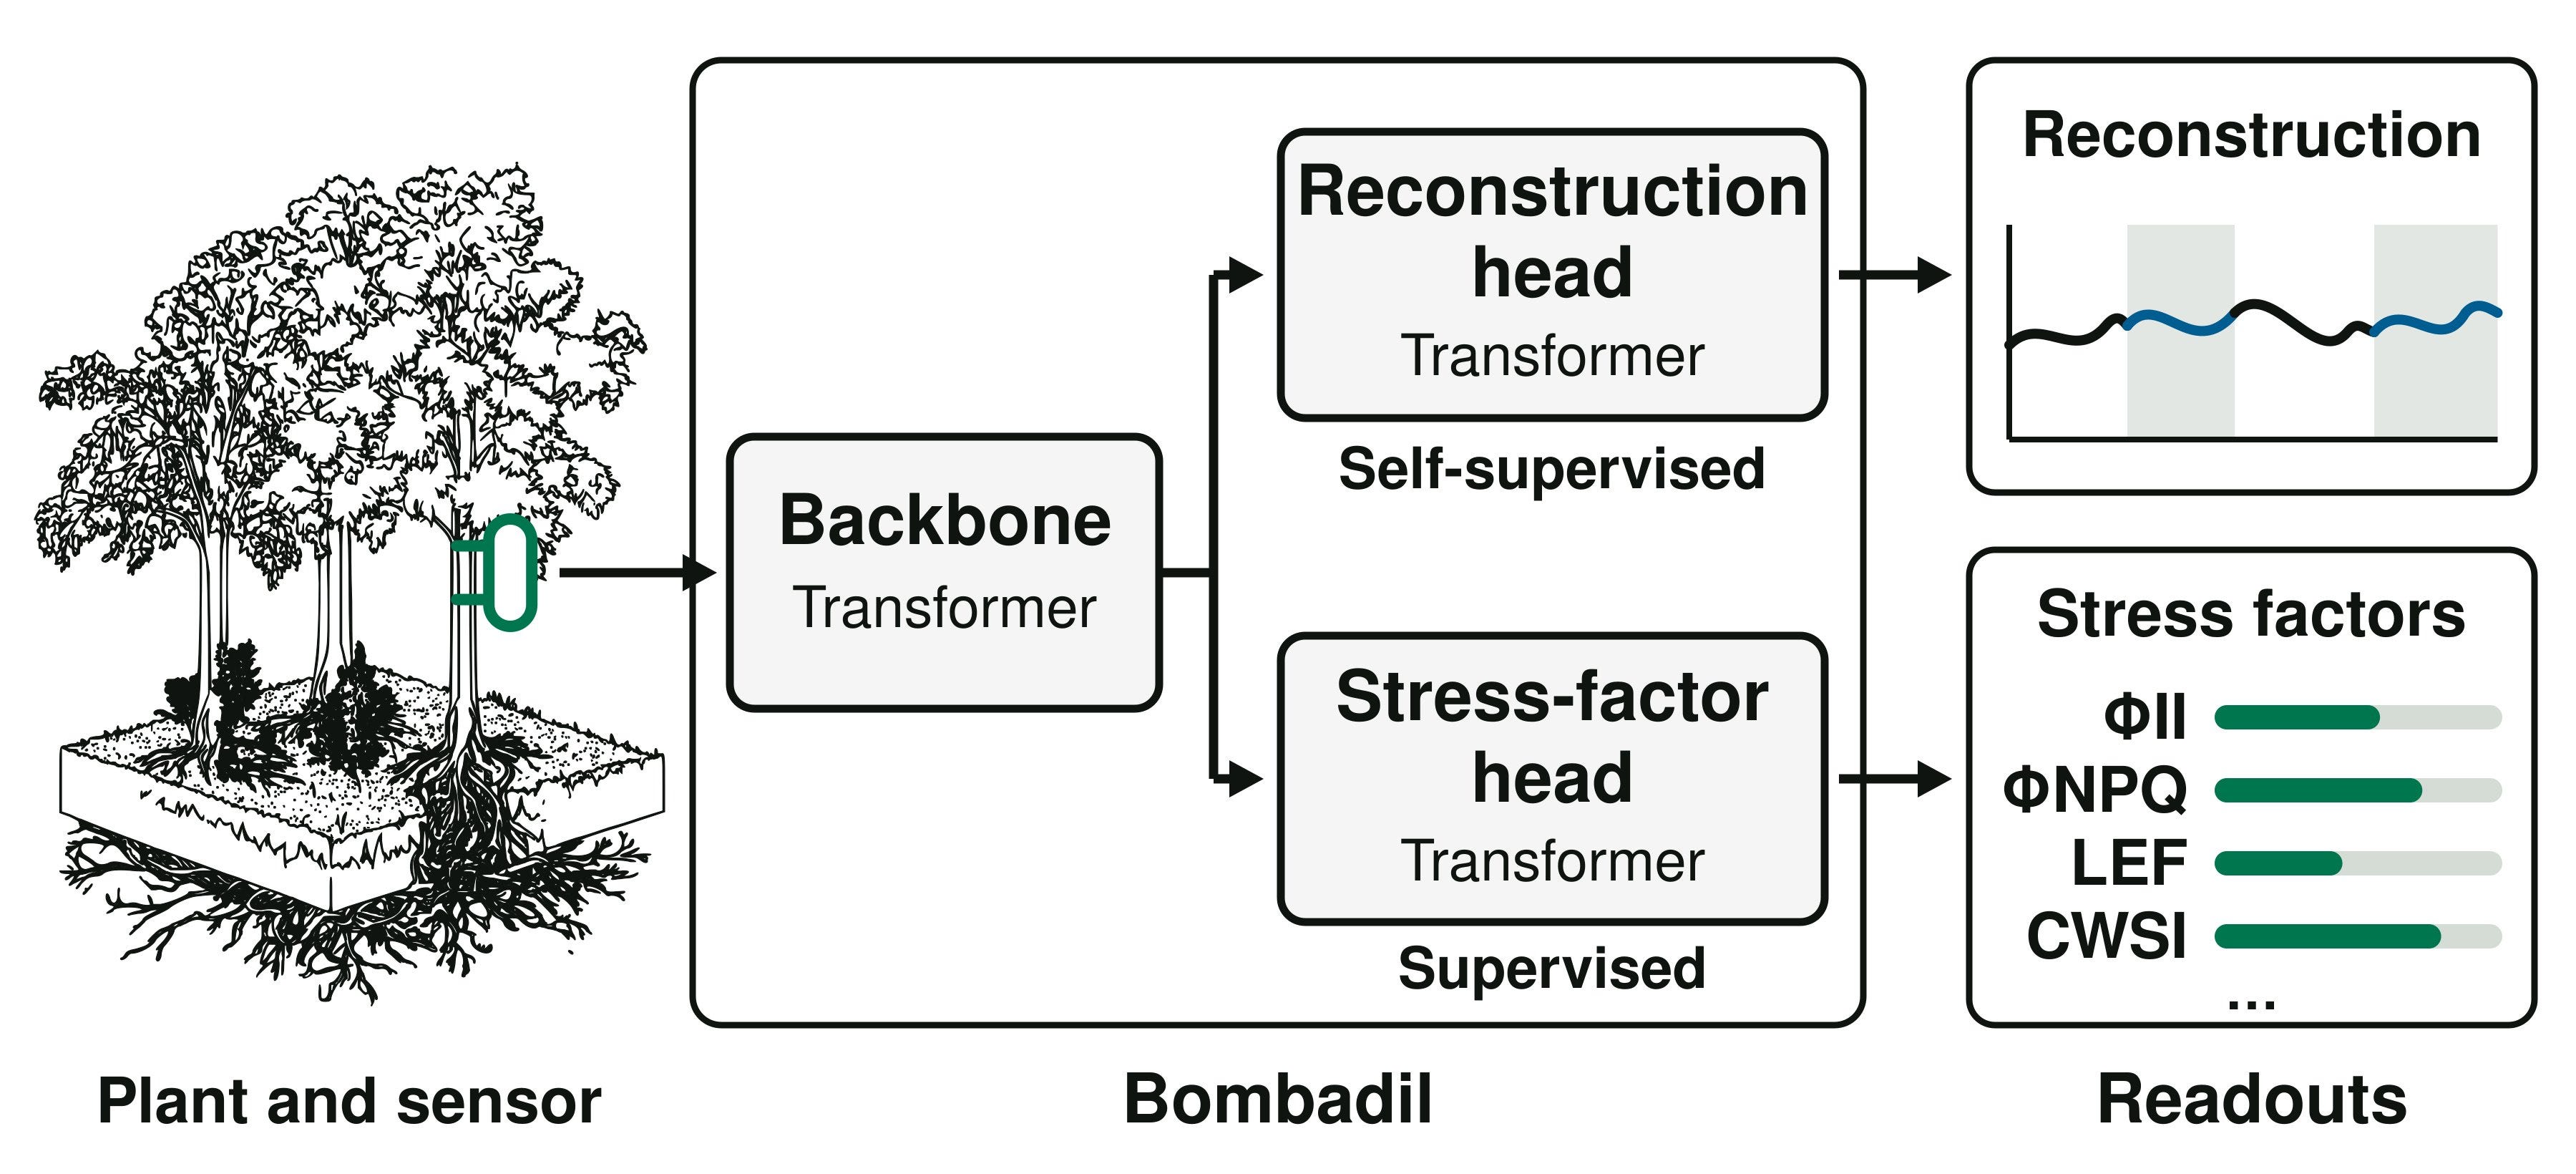
Electric Plant came out of stealth this week with $11.2 million in funding and a foundation model, Bombadil, that reads electrical signals from inside living plants and translates them to estimate seven kinds of stress, like thirst and nutrient needs. Bombadil was pretrained on more than 4 million hours of recordings from 100 species, from redwoods to tomatoes, captured with sensors that cost tens of dollars. Co-founder Justin Mast, who founded Bloomscape, compares it to one model that reads the brainwaves of blue whales, horseshoe crabs, and fruit flies, given how diverse plant species are.
Practically, in the near-term, the company thinks it can cut farm water use by 20% or more with its models and sensors, which is important and economical, but more wildly…we are learning the language of plants? And it’s bioelectric?
I got to see a preview of this at Onto Ventures’ summit in California a couple weeks ago and it was one of the most mindblowing demoes I’ve seen. Justin is kind of like the Lorax, but he speaks to the trees.
We cover a lot of impressive accomplishments in the Dose, like talking to plants and curing cancer, but it’s not every day that we cover a company that’s succeeded where the inimitable Sir Isaac Newton failed.
That’s what Marathon Fusion has done. Newton, under the pseudonym Jeova Sanctus Unus, spent three decades trying to crack alchemy, as I wrote about in Take Weird Ideas Seriously. I think it’s great that he tried. He just didn’t have the technology.
Marathon Fusion seems to. Co-founded in 2023 by CEO Kyle Schiller and CTO Adam Rutkowski, a former SpaceX propulsion engineer, the company posted that last month it turned mercury into “real, stable gold” at ten times the rate of CERN’s 2025 record. CERN's version produced about 29 picograms across four years of collider runs, so we’re not talking Fort Knox, but the physics is real. Fast neutrons from a deuterium-tritium fusion reaction knock a neutron out of mercury-198, which becomes mercury-197 and decays into gold over a few days.
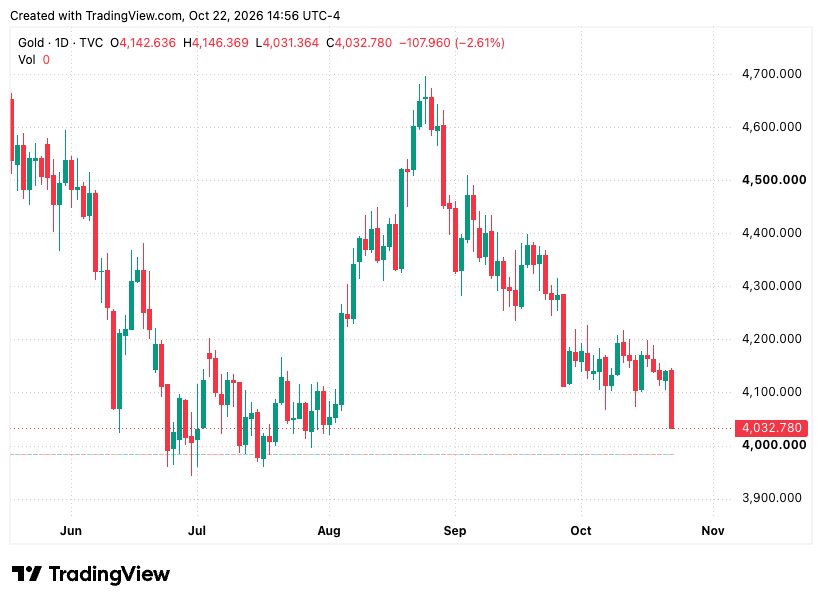
Gold dropped pretty hard yesterday (unsure if related), but for now, it’s just a demonstration.
In the nearer-term, Marathon will use the technology to make medical isotopes. Neutrons that can turn mercury into gold can also turn zinc into copper-64 and copper-67, used in cancer imaging and targeted radiotherapy. Marathon says it has started making both.
The neutrons can make a lot of things. In August, outside testing lab Covalent certified that Marathon’s plasma centrifuge had enriched lithium-6, which fusion plants need to breed tritium fuel, and this week the company said a new run beat a Soviet record that had stood for 40 years. Next is a fusion reactor in San Francisco designed to fire a trillion neutrons a second into a one-centimeter target, continuously, for years.
It’s a very Fuse-like bet that the neutrons produced in fusion reactions can be very valuable long before Q>whatever, and a Small Steps approach to fusion.
Or as Mike Meyers would say, “I LOVE GOOOOOOOOLD.”
2026-10-16 20:47:12
Hi friends 👋,
Happy Friday and welcome back to our 215th Weekly Dose of Optimism!
Welcome to the flying flipping car era. As bad as things have been for my Philadelphia Eagles, that’s how good they’ve been for humanity.
Let’s get to it.
The Only Document Parsing Product You’ll Need
Reducto is the document ingestion layer trusted by AI teams at Scale AI, Harvey, Toast, and Vanta to reliably turn complex files into structured, grounded data for production AI systems at scale. Processing more than a billion pages per month, Reducto has built its reputation on the long tail of difficult documents that break conventional OCR: dense tables, unusual layouts, handwriting, low-quality scans, strikethroughs, and formatting-dependent information.
Its new frontier parsing model, r-1, combines layout detection, reading order, tables, formatting, grounding, and granular citations in a single request. It reduces parsing errors by up to 20%, improves latency at high volumes, and costs 1¢ per page all-in.
Already using another parser? Apply for up to $5,000 in migration credits and hands-on support to benchmark r-1 against your current stack on the documents that matter most.
Nick Cammarata · Goodfire
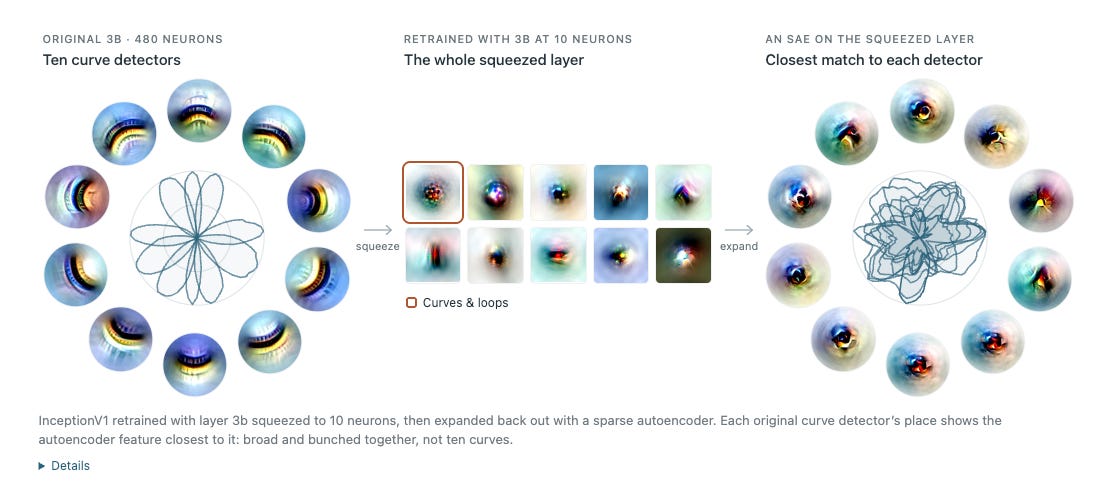
Good news - AI is probably way less likely to kill us all now because humans rock and one of us just kind of figured out how to learn to read their minds.
It is beautiful that a person I became aware of and started following because of his understanding of his own mind—I discovered Nick Cammarata through his tweets on meditation and the jhanas—seems to be the person who’s figured out how LLMs’ brains work.
In the “The Short Version” section, he writes:
I think I have good news about the nature of neural networks.
After many months studying neurons and circuits in image and language models, I’ve come to believe a network’s own mechanisms are its legible building blocks, and that the outlook for mechanistic interpretability may be far better than I’d feared. The canonical evidence of polysemanticity and superposition that convinced much of the field, including me, that networks pack concepts arbitrarily was misread. What looked like arbitrary packing was mostly a motif I’ll call recursive generalization, which is much less concerning. This means we can study networks directly, instead of first untangling them. Neural networks are already clean.
Basically, he thinks that we can understand what’s going on inside of models’ brains - “interpretability” - which means that alignment is probably solveble.
As he explains, “interpretability might be the most important scientific problem in the world right now, as I don’t think we can solve alignment if we don’t know what we’re building.”
Cammarata used to work on interpretability at OpenAI, and he himself “came away pessimistic, because neural networks appeared to fold into arbitrary tangled knots.” Now, he tweeted:
the picture looks totally different. the vast majority in models up to trillions of parameters are legible, and their circuits beautiful. many famous examples of tangled neurons turned out to be misunderstood. The roadblocks I expected mostly aren't there. I now think ambitious interpretability will be solved by the time we need it most, and possibly quite soon, as automated scientists keep improving. it may be a bitter lesson for interpretability: the simple thing, at absurd scale, works.
If he’s right, not only did the p(doom) from runaway AI just tank, but it’s also another win for using technology to solve problems that previously seemed unsolvable. Chalk one up for the optimists.
Thank god we’re going to live, because it seems like the future is going to be as cool as advertised.
Last night, nine years and a number of delays after Tesla first teased the second-gen Roadster, Elon took the wraps off at a SpaceX test site near Waco. It was worth the wait.
The car went 0–60 in about a second, which would have been the coolest thing at any car reveal in history, except this one. Next, using 10 nozzles fed by a 600-liter compressed-air tank, plus some very large fans, it drove up an upside-down ramp, spun around, and set itself down on the pavement. Then it hopped over a Cybercab, Cybertruck, Semi, Model Y, and Model 3 while moving. Tesla said the car would go half the speed of sound (?!?!) at 380 MPH?
Musk said production starts in 2028 (for real) and joked, I think, that they’d try to jump the Snake River Canyon, the ramp where daredevil Evel Knievel attempted to cross the canyon on a steam-powered rocket.
Just… watch the video if you haven’t.
Arrowhead Pharma, video created with Runway
Speaking of brains…
As I’ve written before, my grandmother had Alzheimer’s, and me or someone I love getting Alzheimer’s is one of my biggest fears in life. So whenever there’s a potential development on the Alzheimer’s front, we cover it, even if they’ve historically ended in disappointment.
The hard part of treating brain disease like Alzheimer’s is getting drugs to the brain. The blood-brain barrier is very good at its job, which is why RNAi drugs, which silence a gene before it can make a protein, have been ineffective against brain disease. They’ve mostly been effective in targeting the liver (which filters everything).
On Wednesday, Arrowhead Pharmaceuticals reported interim Phase 1/2a data on ARO-MAPT, which silences the gene that produces tau, the protein that tangles up in Alzheimer’s, frontotemporal dementia, and progressive supranuclear palsy. Healthy volunteers who got two subcutaneous doses at 12.8 mg/kg saw mean total tau in their spinal fluid fall 73% by Day 105, with one participant down 85%. Day 105 was 90 days after the last shot, which means the effect held for three months and the eventual dosing schedule could end up be quarterly or longer. Check the video to see how it works.
All from a shot in the arm!
It’s early, but early Alzheimer’s cohorts are enrolling now and Arrowhead expects to return data in 2027. I hope it works, and that we can all forget about Alzheimer’s once and for all.
Nature Will, Pi, DeepMind, Flexport
On Tuesday, Runway co-CEO Anastasis Germanidis and I published Runway: Learning From Watching the World, in which we lay out the company’s bet that robots can learn most of what they need from third-person video. It’s been a big week for robots overall.
On Monday, Physical Intelligence opened its Pi API beta. With it, companies can upload their robot data, fine-tune a π model on π’s compute, and run inference right on their own robots. Early partner companies are using it on everything from picking strawberries to assembling servers, from driving autonomous wheel loaders in Utah to controlling a dual-arm robot that deburrs the spacers used in its own assembly, basically with an API call.
On Tuesday, the Beijing lab Nature Will run by Tsinghua professor Ning Ding released Natura-1, a 50 billion parameter model pretrained on one million hours of egocentric human video. Egocentric means its video from people’s perspective, not robots’, which is important, because robot data is harder, slower, and more expensive to collect. The model watched egocentric video of people using their hands from their own perspective. Only afterward did they post-train on a small amount of robot data, a la Runway.
Per Rohan Paul, what’s interesting about this is: “One model handles 3 things robots usually fail at together: fine 2-handed control after the grasp, new tasks without extra training, and long sequences where it has to remember earlier steps and recover from mistakes. Many robot systems show 1 of these in a narrow setting.”
That same day, GDM entered the fray. Personally, as a long time GDM fan and an unbiased observer, I think Google DeepMind’s demo was the week’s coolest. Norman Di Palo posted a video of Gemini Argon teaching an Apollo humanoid to play cornhole (above). They gave the model a video of a person throwing a beanbag, and Argon took control of the robot, generated its own simulation environment, ran system identification so the sim matched the real motors, trained the throw, and started sinking them. The team did not have to write any specific cornhole controller or anything. It missed a few first — who amongst us hasn’t — but then it gets the hand of it.
The dream: robots enjoying themselves playing cornhole while we humans work!
Unless… Warehouse robots are here! on Thursday, Ryan Petersen posted a video of Flexport’s newest automated fulfillment center, just outside Chicago, where robots move real freight for real customers.
Robot demos are notoriously bad at turning into actual, valuable robots, and Flexport’s certainly isn’t the first automated warehouse. I’m not smart enough to judge any of these approaches against each other, or to say whether any of them will be the one, but there certainly seems to be a lot of smoke in robotics recently. If there’s fire (metaphorically, of course), the near future could get real abundant real fast.
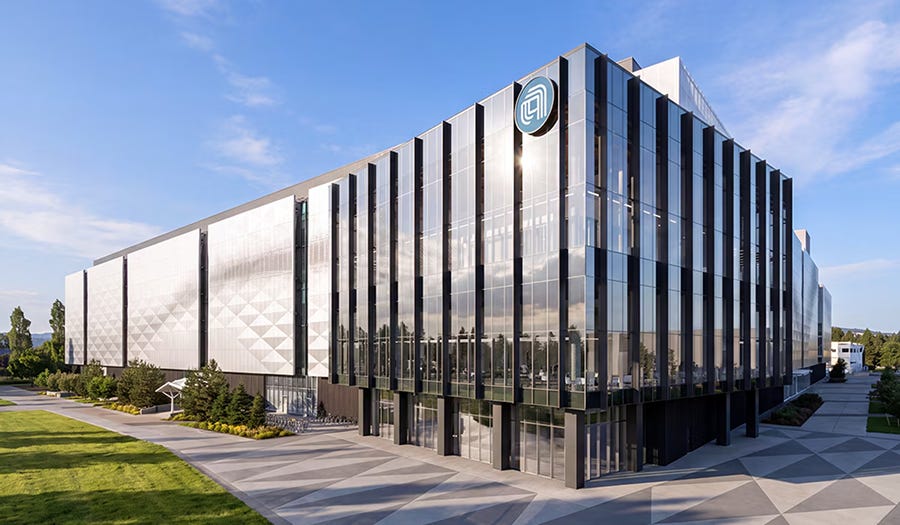
Applied Materials makes the machines that chipmakers like TSMC and Intel use to build chips: the deposition, etch, and inspection tools that lay down and carve the layers on a silicon wafer.
On Monday, it opened the EPIC (Equipment and Process Innovation and Commercialization) Center in Sunnyvale, California. It’s a big investment and a big building. It will cost five billion dollars, cover 600,000 square feet, include nearly four acres of cleanroom, use enough concrete to fill 34 Olympic pools and enough steel for two Eiffel Towers, and take six million construction hours to complete.
As impressive as the space is, this made the Dose because of the partners it’s bringing under one roof in the US of A: TSMC, Intel, Samsung, SK hynix, and Micron are all founding partners, alongside Broadcom, Advantest, KIOXIA, SCREEN, and Besi on the equipment side and Stanford, Berkeley, UCLA, Arizona State, and RPI on the research side. These are competitors, who occasionally sue each other, but have now agreed to put their engineers in the same cleanroom to work on process technology three to four generations ahead of anything in production today.
The point of EPIC is to speed up chip development, which normally runs in series, where materials research hands off to equipment development which hands off to pilot production, with many steps taking place in far flung locales around the globe. The whole process, as it stands, takes the better part of a decade. EPIC is built to run those stages in parallel under one roof, in order to compress the learning cycle on the slowest (and least glamorous) layer of the entire AI stack.
A few years back, I wrote a piece called I, Exponential praising the beauty of exponential curves in technology, the most famous of which is Moore’s Law. As Byrne and Tobias wrote in Boom, Moore’s Law happens because people believe it will happen and then invest ahead of future bottlenecks against that belief, which becomes a self-fulfilling prophecy. This is that in action.
Putting this one above the paywall because Ben is awesome, David is awesome for doing this, and if anyone the not boring community can help in any way, it would make me very happy. I’ll just leave you with David’s intro:
Ben Wilson has stage four cancer and four small kids. I wanted to have him on the podcast to talk about his work on the How to Take Over the World podcast, which is, in my opinion, one of the best podcasts ever created, and to talk about what it’s like dealing with terminal cancer at such a young age. I also want to ask you for help in any way that you can. Ben is a good man and he’s been dealt a bad hand. Please watch this podcast and see if you can help with medicine, introductions, or donations. It doesn’t matter if you have $5 to spare or 5,000. any little bit can help Ben’s family through this devastating time. He’s a good guy and a close friend. Please help in any way that you can.
Discussing his prognosis, Ben says, “the amount of new treatments that are coming out for all sorts of different types of cancers is remarkable. We live in a really remarkable age.” He’s right. We cover it every week.
Just this week, for example, Bristol Myers Squibb and RayzeBio's RYZ101 significantly delayed progression of neuroendocrine tumors in a 343-patient trial. Neuroendicrine carcinoma is exactly the kind of cancer Ben has. Get fucked, cancer.
2026-10-13 20:45:27
Welcome to the 1,825 newly Not Boring people who have joined us since our last essay! Join 281,011 smart, curious folks by subscribing here:
Hi friends 👋,
Happy Tuesday!
A couple of weeks ago, I mentioned that I was partnering with Runway this quarter as our presenting sponsor to bring some of my writing to life in the form of video. It took us a while to land on the right partner to form a deeper relationship with — it has to be a company I want to talk about a bunch — but when Runway reached out, it was a clear perfect fit. For one thing, I’ve had a lot of fun playing around with their video models. But for two others: 1. I’m fascinated by World Models (and quoted Runway co-CEO Anastasis Germanidis in the essay Pim DeWitte and I wrote) and 2. Runway has been on a tear with new product releases.
I wanted to understand how, so to kick off the partnership, I asked to write an essay with me explaining how video, interfaces, operating systems, and robotics all fit together, why video was the right starting point for World Models, where the world is heading if Runway’s bets are right, and whether or not, as someone who simulates worlds, he believes we’re living in a simulation.
Let’s get to it.
A Co-Written Essay with Runway Co-CEO Anastasis Germanidis
From time to time, a certain company catches fire. You can tell when it’s happening by the pace and breadth of their product releases. One day, a new capability. Cool. The next day, another. Woah. Next day, another still.
Runway, the world model company best known for releasing the first commercial video generation model, is on such a run.
Over the past six weeks, it has shipped a real-time interface model, a new interactive world model, an open-weight robotics model, an AI agent for performance marketers, a research preview of an operating system, and it bought a robotics lab in Paris along the way. Meanwhile, the business is growing faster than at any point in its history, adding more than $100 million in annual recurring revenue in the last quarter alone. From the outside, it looks like a company that suddenly figured something out.
From the inside, the view is much more interesting. Runway has been pursuing a particular set of bets for eight years, and that near-decade of research and iterative deployment is now yielding a seemingly disparate but actually related set of new models and products.
On September 1st, Runway introduced Solaris, the “first Interface World Model,” which allows users to generate interfaces in real-time, through prompts or actions on screen, like this one where a guy takes a selfie and tries on glasses and tweaks his hair and smile with the drag of a mouse.
On September 8th, Runway announced it had acquired Kinetix, a Paris-based research lab, which specializes in… robotics? From the video company?
Then at their September 30th AI Summit, the team shared Praxis-1, “an open-weight World Action Model that turns our video pre-training expertise into real world control for robots.”
The thesis is that while robotics data is limited, video data is practically infinite. So Runway pre-trains on video data and then uses that as a policy model for robotics developers who can train it on their specific embodiments. Standard Bots, whose co-founder Evan Beard and I co-wrote an essay on robotics, is working with Runway to deploy Praxis-1 on its arms.
And then the very next day, on October 1st, Runway previewed Project Continuum, “a new operating system research application built around real-time video interfaces.”
A video model. An interface model. A robotics model. An operating system. Are you getting it? These are not separate pretrains. They’re different applications, built around the same General World Model backbone, with different post-training on top.
Made with Runway
All of them are examples of what you can do when you can simulate any pixel.
An operating system ends up as pixels on a screen, like video and interfaces do, and like the world does through a robot’s eyes. If you can simulate every pixel at high enough fidelity and speed, then you can make almost anything that shows up to the world as pixels. This is the future Runway is building towards.
Runway is making a few different bets, on a research direction, the Bitter Lesson, and a business strategy. It is betting that world models can learn, like humans do, from third-person observation. It is betting that letting models watch a ton of video will lead to models that understand how the world works better than they could by reading about how the world works or from any other human-mediated data source. And it is betting that it can build a massive business in content creation in order to both help fund the large investment into better and better models, and to become the rare company that is both a frontier lab and a distribution layer.
Runway’s commercial success and product prolificness points to a surprisingly wide set of applications for World Models; surprising, that is, unless you read the essay Pim DeWitte and I co-wrote explaining why World Models have the potential to eat everything. In it, we wrote:
World models — these systems that learn from watching the world and the actions taken in it — are a fundamentally new kind of foundation model. They can compute what was previously uncomputable.
There are a number of different types of models whose makers call them World Models, although many don’t fit our definition; they don’t predict the next state based on intervention. We categorized Fei-Fei Li’s World Labs, which AMD recently agreed to acquire for $8.2 billion, as building “3D Reconstruction and Generation Models.” Runway, we wrote:
Is blurring the lines between video generation and world generation, as mentioned in the Video Model section. During its Research Demo Day 2025, Runway co-founder and CTO Anastasis Germanidis explained the company’s evolution that started from “generative AI models [as] viable tools for creative expression”. They then evolved towards World Models (while still making incredible progress in video models.)
“To build a World Model,” Germanidis explained, “We first needed to build a really great video model. We believe that’s the right path to building World Models, that teaching models to predict pixels directly is the best way to achieve general purpose simulation.”
Runway first mentioned its World Model ambitions in a December 2023 blog post by Germanidis, who is now co-CEO, titled “Introducing General World Models.” This has been the plan for quite some time: teach the models to make videos from watching videos, and then teach them how to bring the actions in video to life.
Anastasis describes it as a plan in four chapters:
Chapter 1: Media and Entertainment
Chapter 2: Broader Content Needs and Full Video
Chapter 3: Robotics (We Are Here)
Chapter 4: Science
The plan is coming together, as evidenced by the recent string of releases, and I have become a World Models convert who believes they have the potential to do a lot of things in the real world that LLMs can’t, so Anastasis and I decided to co-write an essay on the company’s bet that watching a lot of videos can teach models to do almost anything.
One of the things you realize when you have kids is that babies are learning machines. When they’re really young, they just keep changing, picking up new skills, like little Neos.
The thing about babies, though, is that they don’t know how to read. They don’t learn like we learn in school, by reading textbooks, because they can’t. Instead, they watch. They watch how we walk, how we talk, how we smile, how we bring food to our mouths, how we pick up toys and how we put them away, they watch how we shake hands, and hug, and run, and jump, and crawl. Then they try it themselves, clumsily at first, they watch again, they try again, they watch again, they try again, and try and try and try until they’ve gotten it.
Made with Runway
As we grow up, we do go to school, and we do learn from books, but we still learn by watching. We watch how the kids in the older grades dress and talk and interact. We watch how our favorite athletes play. We watch to learn how to interact with and manipulate the world.
If you’re a guy, think about the last time you had to tie on a bowtie for a wedding. The best way to do it, other than having the one guy who knows how to tie a bowtie tie it for you, is to watch that guy tying his bowtie. The second best is finding a YouTube video of someone walking you through how to tie a bowtie. At the bottom of the list is reading how to tie a bowtie. I’ve tried it, and it simply doesn’t work, at least not for me.
Language is compression. We look at the rich, ever-changing world in front of us, and we can’t possibly capture it all. By the time we’ve come anywhere even close to describing what we see at any given time with any amount of precision, it’s changed. And no matter how hard you try, words will never be enough, because you can’t, for example, see each of the atoms in the scene, track the movement of the electrons and protons and neutrons that make up those atoms, see how electromagnetic and gravity waves interact with them… you get it. Everything in the world changes, then changes again, and each time it does we’d have to start describing it again, like verbal Sisyphuses.
Instead of running a constant monologue as we walk down the street, describing all of the motion and appearances and interactions we see, we simply say, “The man walked down the street.”
Neither approach captures the full picture, but the latter is easier and allows us to actually live our lives. To jack as many subtle details into our brain as possible, therefore, we don’t read about life, we watch it. Our brain has evolved to pull out the relevant information.
Made with Runway
A picture is worth a thousand words. A video is worth 1,000 times the number of frames plus however many words the motion connecting them and sounds are worth.
But the value of video isn’t simply that it contains more information than words. Predicting what happens next and checking how well you predict, over and over again, creates a pressure to learn reusable relationships.
Imagine trying to predict the next frame of that street video.
To get it right, it isn’t enough to know what the man looks like. You need to know that he’ll keep walking in roughly the direction he was walking, at roughly the speed he was walking, that his left foot comes after his right, that people walking near him will walk behind him and not through him, that when he passes in front of a moving car, that car still exists and will come out the other side a beat later as the same car, that his shadow moves when he moves, etc.
When a model is trained on video, nobody tells the model any of this. There’s no line of code that says “objects still exist when something walks in front of them” or “people can’t walk through people.” The model guesses the next frame, sees how wrong it was, and adjusts. Somewhere along the way, the cheapest way for the model to stop being wrong is to learn something like the rules: things fall, and seem to fall in basically the same way at basically the same rate of acceleration (although feathers seem to flutter back and forth while bricks simply drop); glass shatters and rubber bounces; a ball that rolls behind something comes out the other side looking exactly the same, unless there was a puddle of mud. One video with a muddy ball might confuse the model, but over millions of them, it would learn that the mud is an anomaly.
These, incidentally, are things that babies learn during their first year. We play peek-a-boo because it makes them laugh, but also because it teaches them object permanence, this idea that things still exist even when you can’t see them.
This is how LLMs work, too. Their goal is to predict the next word, by any means necessary. Ilya Sutskever has been making this point for years: predicting the next token correctly requires understanding something about the reality that produced the token.
Swap tokens for frames and you have Runway’s thesis.
There’s a theory in neuroscience, which I discussed with Cristóbal Valenzuela, Runway’s co-founder and Anastasis’s co-CEO, called active inference. Karl Friston is its most well-known proponent. The idea is that your brain is a prediction machine, constantly running a simulation of what’s about to happen and checking it against what actually happens. You don’t normally notice it, because you get really good at prediction and it just runs in the background. You only notice it when you get it wrong. You’re walking up the stairs, you go for one more step, the step isn’t there, and for a split second your whole body lurches while the simulation crashes and reboots. “The moment you see it didn’t predict,” Cristóbal said, “you adjust.”
A model that sees enough examples of success and failure starts to carry around its own version of that simulation. But until the model runs in a physical body instead of a screen, it can’t feel what it’s like to stumble, trip, or fall.
Why video, though, and not another type of data? That’s where the first of Runway’s bets comes in: The Bitter Lesson.
It is practically illegal to write about training models without mentioning The Bitter Lesson. In 2019, Richard Sutton wrote a short essay arguing that the biggest lesson from seventy years of AI research is that “general methods that leverage computation are ultimately the most effective, and by a large margin.” It is bitter because every time researchers have tried to build their own understanding of a domain into a system (chess openings, the structure of grammar, the edges and corners in an image), they’ve eventually been steamrolled by dumber methods that could soak up more compute and more data.
For his part, Anthropic CEO Dario Amodei made a similar observation two years earlier, in a recently-partially-leaked internal OpenAI research document he titled “Big Blob of Compute.”
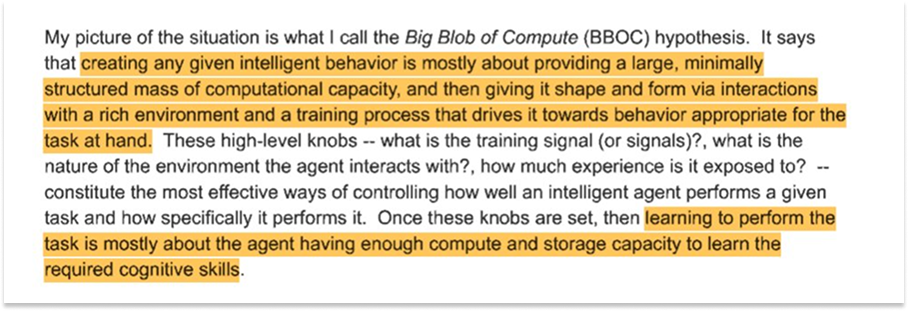
The Big Blob of Compute (BBOC) hypothesis, he wrote, “says that creating any given intelligent behavior is mostly about providing a large, minimally structured mass of computational capacity, and then giving it shape and form via interactions with a rich environment and a training process that drives towards behavior appropriate for the task at hand.”
Runway’s corollary is that the most scalable source of data tends to win. Call it the Big Blob of Video (BBOV) hypothesis.
LLMs won on text because the internet had an absurd amount of it. Robotics has been climbing its own ladder. It used teleoperation data, a specific robot doing a specific task puppeteered by a human. This year, many robotics labs began using a lot more egocentric video from cameras strapped to people’s heads as they perform a task. Runway is betting on something simpler and less human-mediated: vast quantities of video that already exist, and will be filmed (and generated) from here on out.
Watching video is the most Bitter Lesson-pilled approach to AI there is. Language is a compression of reality, an incredibly good one that humans have been refining for thousands of years, but a compression nonetheless. As Sutton wrote, “We want AI agents that can discover like we can, not which contain what we have discovered. Building in our discoveries only makes it harder to see how the discovering process can be done.” In other words, we limit agents with our own beliefs.
Put more bluntly: if you really believe the Bitter Lesson, you should be working on World Models.
There’s a good argument against this thesis, so we might as well make it ourselves.
If language is compression, well, compression can be useful!
Learning about the world from pixels is less efficient than learning from text. Researchers have shown that you can build a language model out of raw audio, just by predicting the next little chunk of sound, and that language eventually emerges, but that it takes something like three orders of magnitude more compute than learning from text. Text comes predigested. Somebody already did the work of sorting out the most important stuff. Pixels make the model do that work itself, and there are a lot of pixels on which the model must do it.
Then there’s Yann LeCun’s critique: predicting every pixel wastes effort on details that don’t matter (every leaf on every tree, every ripple in every puddle), so models should predict in an abstract representation space instead.
Runway’s answer is pragmatic: use whatever works. So far, we haven’t seen evidence that JEPA scales better than the diffusion models it uses, and the simplest approach tends to scale best. Plus, it’s really hard to know ahead of time which pixels are noise. The rustling leaf isn’t noise if it tells you that the wind has picked up. The wind, even ever so slightly, will impact how everything else in the frame moves.
The efficiency problem is real, though. Runway thinks the answer is more compute, better training to squeeze more from every frame, and better algorithms.
As Anastasis said in our first conversation, “Naively scaling what we did two years ago won’t solve these problems. I expect the compute needed to train World Models to eventually exceed what LLMs need, and we’ll need real algorithmic progress on top of that.” Good time to be Jensen Huang.
Anastasis’s bio on X reads “Simple ideas, pursued maximally,” which is also a pretty good summary of Runway’s research strategy.
The simple idea at Runway is next-frame prediction. A language model learns to describe the world by predicting the next token in a sequence of tokens. An autoregressive World Model, as Cristóbal put it, learns to simulate the world by predicting the next frame in a sequence of frames.
Autoregressive is a fancy word for a relatively simple idea. The model generates one frame at a time, each based on the frames that came before it, the same way an LLM writes one word at a time. Most video models don’t work like this. They generate a whole clip at once, refining it from static into a picture over dozens of steps, which is great if you’re making a ten-second ad and useless if you’re trying to interact. Interactions stop feeling interactive somewhere around half a second of lag. If you want a model that a person, or an agent, or a robot can actually interact with the way humans do with other humans, it needs to produce the next frame quickly, then the next one, then the next, each taking into account whatever just happened in the previous one and in the reaction to it.
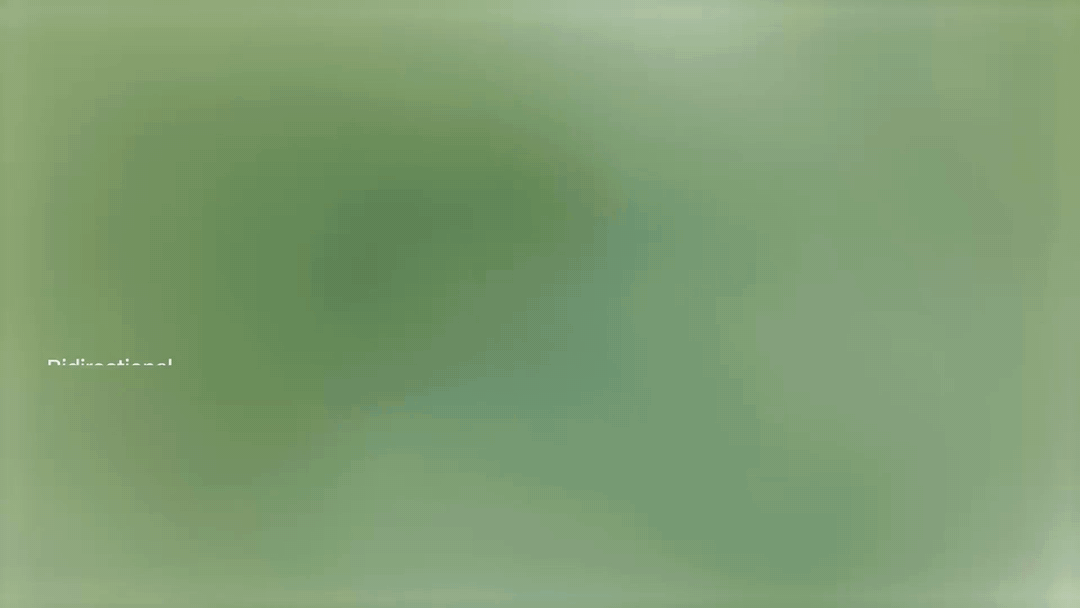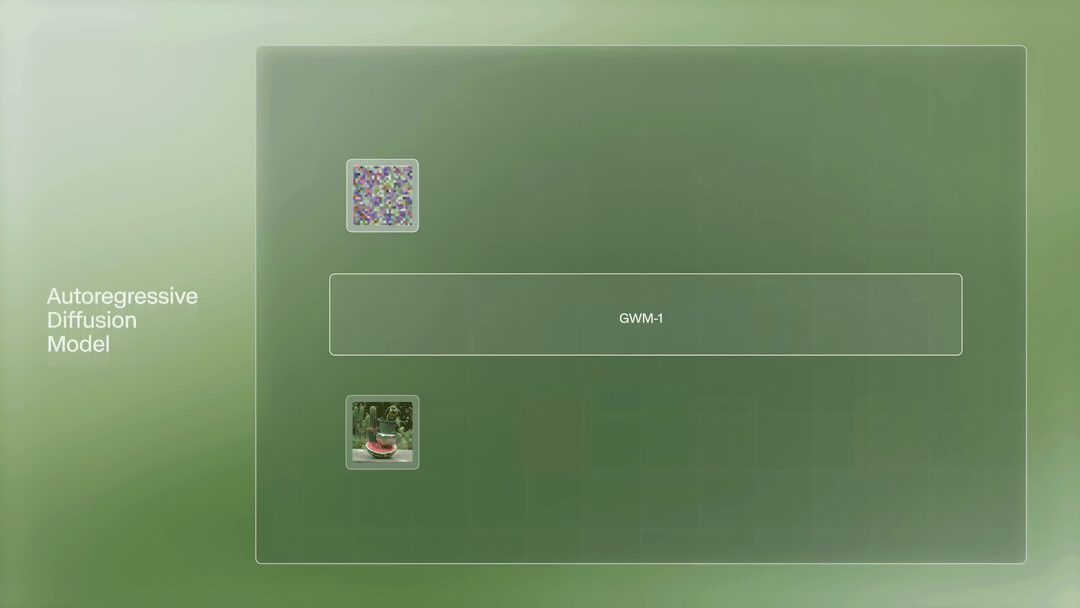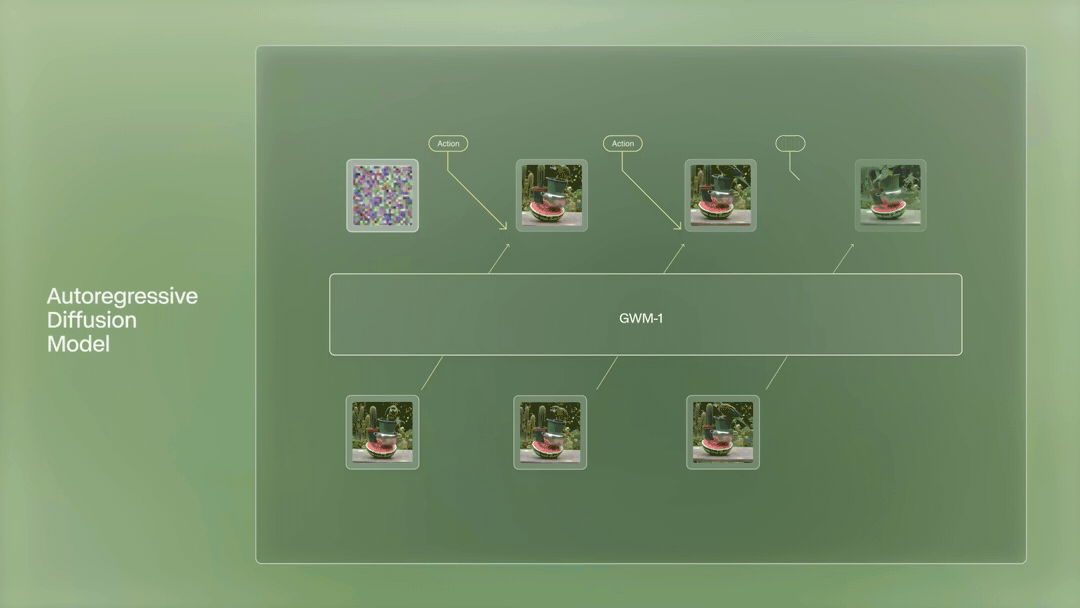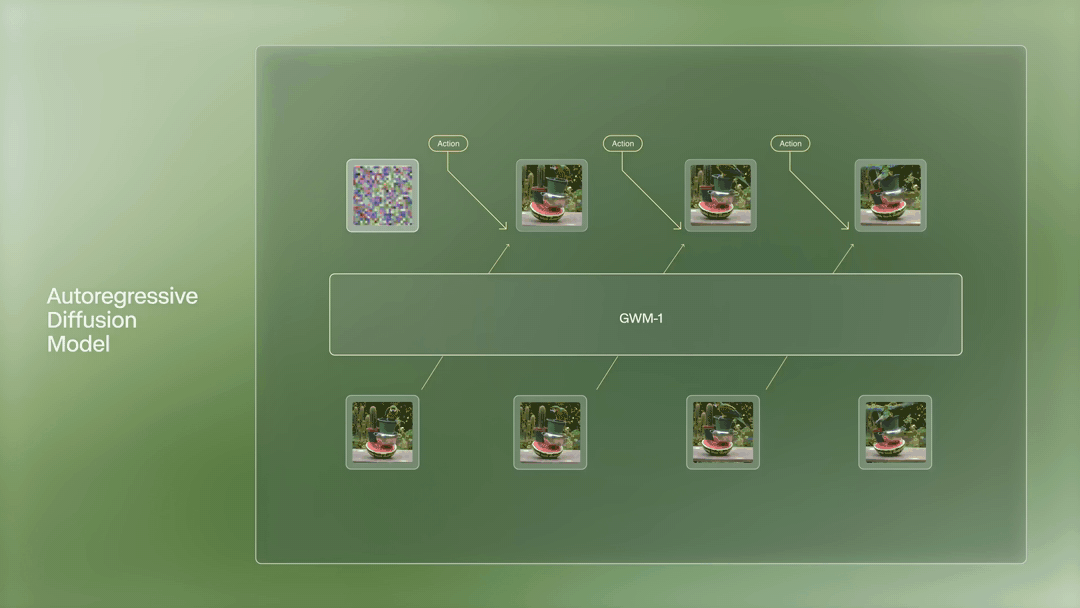
That’s what Runway did with GWM-1, which it announced last December. It took Gen-4.5, its most recent base video model, and turned it into a model that generates frame by frame, in real time, and can be steered with actions. In its Solaris announcement, asking, “What if software could generate itself, as you interact with it?,” it laid out the general recipe:
Teach the model to generate frames sequentially,
Distill dozens of denoising steps down to a few,
Train the fast model on its own outputs so the quality holds up over a long session.
No code underneath, no layout to translate. The image is the application. It treats your clicks and drags the way our video models treats words: not as commands to look up, but as a signal for what to generate next. Nothing about it is decided in advance, so nothing about it has to stay the same… the scene answers to your intentions. It becomes whatever you ask of it.
Actions are the important thing.
In my (Packy’s) previous essay on World Models, we drew the line between video models and World Models like this: a video model predicts the next frame, P(xt+1 | xt), while a World Model predicts the next state given an action, P(st+1 | st, at). “That at,” we wrote, “is the magic.”
Runway’s last month or so of releases can be viewed as a bunch of different at’s. In GWM Worlds 2, the actions are camera movements plus free-form text addressed to anything in the scene. In Runway Characters, the action is audio, a person talking to an avatar that listens and responds. In Solaris, the actions are clicks and drags. In Praxis-1, the actions are robot commands, expressed as where the robot’s hands should go next. There’s a different vocabulary for each, but they all use the same machinery underneath to predict what happens next.
I (Packy) have been fascinated by World Models, and really do think they’re some kind of magic, so when I talked to Cristóbal, I wanted to be sure that I understood: “So all of this really just is the same backbone?”
“Correct,” he said. “The backbone is frame prediction at scale, which eventually gives rise to a World Model in the same way that next token prediction at scale gives rise to large language models. And the applications are diverse on top.”
This is why the company is moving so fast across seemingly disparate applications right now. About 90% of Runway’s research effort goes into pretraining. The belief is that the capabilities get learned there, by watching, and that post-training mostly brings out what the model already knows. Once the base gets good enough, each new application takes far less effort to stand up than the one before it.
You don’t, for example, need to build a robotics model from scratch. You can take a model that has already watched an enormous amount of the world and teach it to speak robot.
There’s a lot of room left. Runway estimates that Video and World Models are a year or two behind LLMs, which means pretraining is nowhere near saturated.
My (Anastasis’) rule of thumb is the number of pixels a model can generate, which is resolution x duration, roughly doubles every few months. I don’t see any fundamental blocker to hour-long generated video within a year or two.
Longer videos aren’t simply a matter of doing the same thing, more. A model that has to keep a scene coherent for an hour has to learn persistence. Turn around, and what was behind you is still there. The mug you set down on the counter is still on the counter twenty minutes later, unless somebody moved it, in which case the model should know who moved it, and where. Those are exactly the things today’s models still struggle with; longer context, the company believes, is how you train those problems away.
Longer term, the really big bet is that the field moves toward one model that does language, pixels, audio, and actions together. Even in the near-term, though, the World Model backbone that’s used to generate pixels on a computer screen seems to also be able to help robots navigate and interact with the physical world.
Every robotics company with ambitions of deploying at scale runs into the data wall: real-world data is scarce, expensive to collect, and a general-purpose robot needs a lot of it.
In Packy’s Robotics piece with Evan, they wrote a whole section titled, “Robotics is Bottlenecked on Data,” on this idea:
LLMs had it relatively easy. The entire internet existed as a pre-built training corpus. There is so much more information on the internet than you could ever imagine. Any question you might ask an LLM, the internet has probably asked and answered. The hard part was building architectures that could learn from it all.
Robotics has the opposite problem.
So robotics companies have to build their own internet equivalent, one demonstration at a time, often with a human in a VR headset puppeteering an arm through the same task over and over again. For jobs with long tails of weird edge cases, like household robots, Runway argues that there’s no practical way to collect all of the data you’d need, let alone enough of it.
Video, on the other hand, is effectively limitless. People film and upload more of everyday life every single day than every robot lab on earth could capture through teleoperation. And as generative models get good enough to make video that’s indistinguishable from the real thing, it’s becoming even more limitless. You can start with real scenes and simulate thousands of variations, each with subtle differences.
Packy here. In that same Robotics essay, Evan and I wrote a section called “Video Dreams (and Their Limits)” in which we argued that internet video isn’t enough. Video shows you trajectories and timing and the order of steps, but it doesn’t carry mass, force, friction, or stiffness. Two surfaces can look identical and behave completely differently, and the robot finds out the fun way. We cited a study in which people who watched more videos of moonwalking and juggling became much more confident and not much better. Reading lots of books makes it easier to write a good book, we wrote, but watching lots of golf videos doesn’t do much for your golf game.
First, hell yeah. This is why I do these co-written essays. Smart people can disagree. General robotics is still unsolved and people much smarter than me are taking many different paths.
Second, though, this isn’t the disagreement it appears to be on the surface.
As one piece of evidence: Standard Bots is now testing Runway’s Praxis-1 on its RO1 arm.
What resolves the seeming disagreement is that Runway isn’t betting on video instead of robot data, but before robot data.
Praxis-1, which Runway unveiled at its AI Summit on September 30th, learns mostly from third-person video, built on the same large-scale pretraining as the company’s World Models.
From there, Cristóbal explained, “you can take the learnings of large video data and start fine-tuning it on robotics. So you add a bit more egocentric data, and that egocentric data will help the model understand a bit better the situation that it might be in.”
Then you fine-tune on the specific robot.
How much robot data does that last step take? About 30 minutes of data teaches the model to control a robot body it hadn’t seen in pretraining, and in new environments it can reach strong performance on some tasks with just minutes of data. You still have to swing the club a bit, so to speak, but you need a lot less practice when you have a robust model of how the world works pre-loaded in your brain.
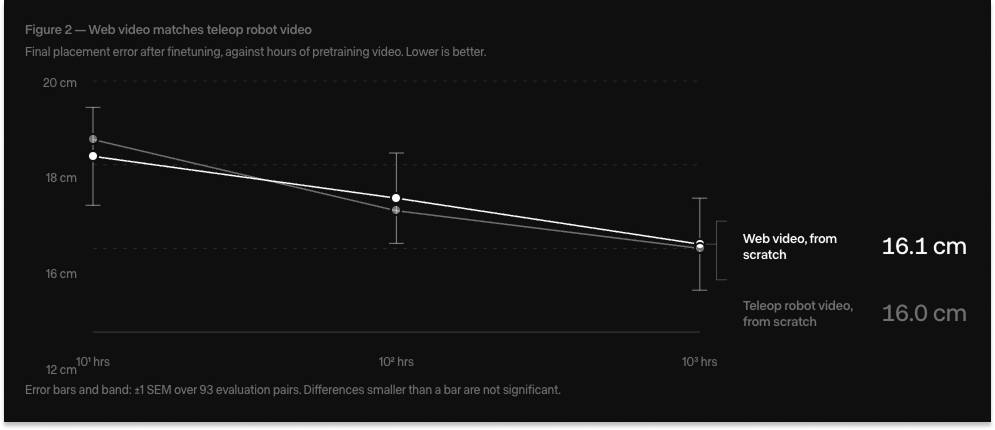
As a test, Runway pretrained robot policies on ordinary video and, separately, on teleoperated robot video, using anywhere from ten to a thousand hours of each. Then it fine-tuned them and measured how close the robot got to putting an object where it was supposed to go. The two lines are basically on top of each other: web video worked as well as robot video. The web-video version ended up with a final placement error of 16.1 centimeters versus 16.0 centimeters for the teleoperated robot video version.
That’s not nothing; for high-precision tasks, 0.1 cm might as well be a kilometer. But these models are as bad as they’re ever going to be, and teleop data isn’t getting any cheaper to capture. If they’re roughly interchangeable as a starting point, the robotics data problem looks very different than it did in January.
But robots’ bodies and forms vary wildly, both from each other and from humans’. How can a model that’s mostly watched humans control a robot’s arm precisely?
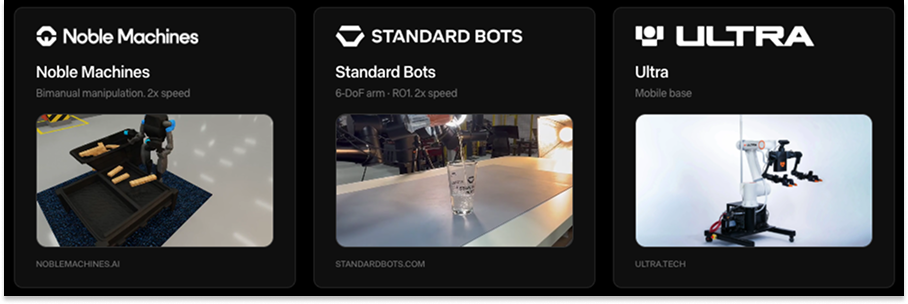
Part of the answer is in how Runway represents actions. Praxis-1 expresses actions in a standard end-effector format: where the gripper (the “hand” at the end of the arm) should be in 3D space, and how it should be oriented. A person’s hand reaching for a mug in a YouTube video can be described in exactly the same terms. So can a humanoid’s hand, a six-axis industrial arm, or a two-armed setup. While the embodiment changes, what the model is trying to figure out – where should the hand go next – doesn’t really. To that end, Runway’s model is currently being tested on Noble Machines’ bimanual setup, Standard Bots’ six-degree-of-freedom RO1, and Ultra’s mobile robot.
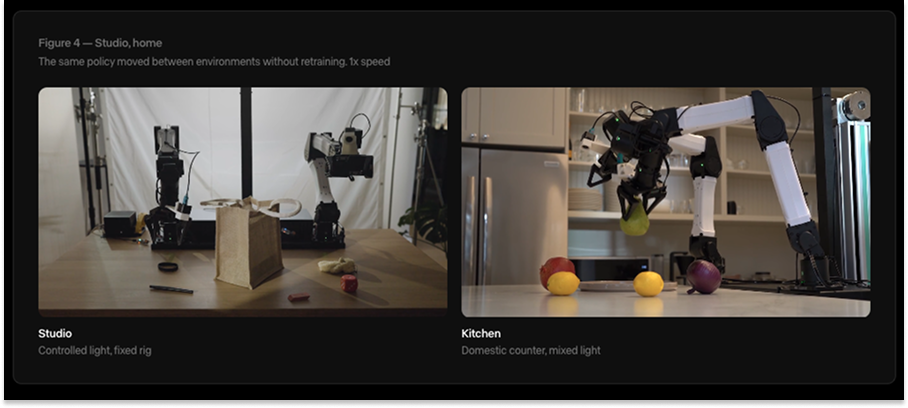
In one demo, the same policy works in a controlled studio and in a home kitchen without retraining.
It may be helpful to think about the three ways World Models can be used in robotics.
The first is generating training data. Take a small set of real demonstrations and create variations with new objects, new lighting, and new layouts with which to train the robots on a bunch of different situations they might not see in real world training very quickly.
The second is simulation, or testing robot policies inside the World Model before you put them on real hardware. This is where Runway has published its most rigorous evidence.
In February, its robotics team took eight different manipulation policies from the RoboArena benchmark, all running on the same Franka Panda arm, and ran each one inside GWM-Robotics, an early version of Praxis-1. Each policy made its own decisions based on what the World Model showed it. Human graders then scored 1,450 simulated rollouts, more than 16,000 ratings in all, about ten per rollout. The ranking of the eight policies in simulation matched their ranking in the real world with a correlation of 0.95, and the graders correctly picked out both the best and the worst policy. It’s a test of ranking (which policy is better than which), not of absolute success rates, but for a robotics team deciding which of your twenty candidate policies deserves time on your three physical robots, ranking is exactly what you need. The theory here, and across the robotics work Runway is doing, is to do as much in relatively cheap simulation as you can before moving to the more expensive physical world. Runway’s model only needs a starting image, compared with competing approaches that require scanning and reconstructing every scene in 3D, which makes it relatively cheaper than even other simulation approaches.
The third way is to use the World Model as the robot’s brain. This is the one that Cristóbal is most excited about. “One of the most compelling use cases that we found for these models in robots is less on the synthetic data part and more on using the video models as the brains of the robot,” he said. “So they learn not by describing the world, but by simulating the world, and they do it in real-time.”
Remember our example of the person tripping on the stairs? A robot with a World Model for a brain is constantly predicting what should happen next and adjusting when it doesn’t, like that human does. That’s why recovering from failure is one of the key capabilities. If the gripper slips, the box is heavier than it looked, or the bag tips over, the model has to notice and adjust in real-time, the way you catch yourself on the stairs.
Like humans, then, once embodied, these models are able to start learning both by seeing and by doing. The seeing helps them start doing, and then they learn some more from the doing.
Runway thinks the first real deployments will be in enterprise: warehouses and manufacturing, fine-grained manipulation tasks where there are so many ways for things to go wrong that generalization can pay for itself. Useful home robots will take longer. That’s where we landed in the Robotics essay, too. Start where the economic value is, get paid to learn, and keep eating more.
And what will the robots doing increasing amounts of work look like? Runway thinks there will be a menagerie of cheaper robots that can use tools to do specific jobs. Simpler, cheaper robots scale better, from a data perspective, than expensive humanoids that break easily. And it will become cheaper to make things to stick on robots to help them do whatever job they need.
Long-term, I (Anastasis) don’t think we end up in a world of all humanoids. LLMs make it easy to design components and 3D printers make it easy to produce them, so people will design and fabricate custom robot bodies for specific jobs, all running on the same model layer. This is particularly true if teaching the brain to use new embodiments continues to take 30 minutes across arbitrary embodiments.
In this world, the model that is the robot’s brain is the layer at which value accrues, so what do you do to own that layer? Runway thinks you give it away.
Runway plans to release Praxis-1 with open weights in the coming months (for now, it’s with early partners), because open models give hardware developers more control over their own robots than closed ones. Open weights also help make Praxis the default starting point for anyone building a body, which means that Runway gets more data, which feeds the next, better Praxis and the next, better World Model on which it’s built. Runway’s acquisition of Kinetix, the Paris-based robotics research lab, earlier in September makes sense in that light, too.
It is true, as we wrote in January, that videos don’t contain data on things like force that really matter for making robots work perfectly and predictably. Robots still need to practice in a physical body, like humans do – you’re not going to drive the ball 300 yards the first time you swing a club, no matter how many Tiger Woods videos you’ve watched – and robots, like humans, need to learn from failures in order to anticipate them the next time. But it also seems true that good priors are worth a lot, that you need less practice when you start doing something with an understanding of what great looks like, or as Runway describes it, “how objects behave, how hands move, what a task looks like partway through.”
Robotics represents an enormous and obvious opportunity, and one for which World Models seem to be particularly well-suited. Babies, adults, and World Models all take in the scene around them and try to predict what to do next. If Runway can supply robots’ brains, it will build a very big business doing so.
But the team is as excited by, if not more excited by, the types of products and markets it can open up if it gives people the tools to simulate every pixel. Robots acting on a physical scene and a person clicking on a digital one, after all, look the same to a World Model.
If it’s just predicting frames or pixels on a screen, well, why not just predict everything on a screen?
A philosophical answer to my question about how Runway thinks it can build an operating system with a World Model via Continuum.
When people hear “pixels,” Cristóbal said, they think of video and movies, and then the obvious next steps, like games, ads, content. Runway, though, is a Pixel Maximalism company. An operating system is pixels on a screen. Us humans, we don’t think about using a computer as the same thing as watching a movie, but to a machine, it’s all just pixels.
Recall about how LLMs treat tokens. The same LLM that writes poetry can write high-performance C++, because to the model it’s all just tokens.
“Models want to generalize about the world,” Cristóbal said. ”And the task itself, how we label the task, doesn’t really matter for the models. It’s just pixels on a screen.”
Think about how software gets made today, even when LLMs do it. Someone designs what it should look like. Someone else (or, increasingly, the same person or just the LLM itself) translates that design into code. Everything about it – how it will look, what buttons will do, how it feels to the user – has to be anticipated and programmed ahead of time, then shipped. In the Solaris announcement, Runway describes the result as a lossy compression of all the ways someone might want to interact with a piece of software, “frozen before any user arrives.”
Solaris, which Runway released at the end of August, is the first of what it calls Interface World Models. Instead of rendering an app that someone has coded, it generates the interface itself, frame by frame, as you use it. The user’s clicks and drags become conditioning for the next frame, the same way a text prompt or an image would be. (That’s at again.) You can browse a virtual clothing store where the showroom is the interface, pull a shirt off the rack, and drag it onto a photo of yourself, tuck it into your digital pants, tug it back out. You can build a salad by dragging ingredients into a bowl. Remember the guy at the top of this piece, trying on glasses and fixing his hair with his mouse? Nobody coded a “try on glasses” feature. The model just knows what happens when glasses go on a face, because it’s watched more hours of video of people putting glasses on and adjusting them than any human would willingly be subjected to.
For now, Solaris pairs a World Model with an LLM. The LLM figures out what you’re asking for and decides what the application should do next (turns your words into an action); the World Model decides how that action impacts the next frame and renders it in real time. This is how Runway thinks things work in the short term. The World Model becomes the rendering layer (replacing the HTML, CSS, and JavaScript presentation layer), and the LLM handles the logic of translating your actions. Runway’s gaming work splits work the same way; the LLM writes the scenario, and the World Model renders it.
Compared to the way we’re used to interacting with software, it feels magical. Runway ran a study. It gave Solaris and Claude Opus 5 the same starting image and the same interaction requests, and had 250 people make nearly 7,500 side-by-side judgments. When asked which result better followed the instruction, people picked Solaris 61% of the time to the coded version’s 24% (13% called it a tie). When asked which behaved more naturally within the scene, it was 71% to 21% (7% tie).
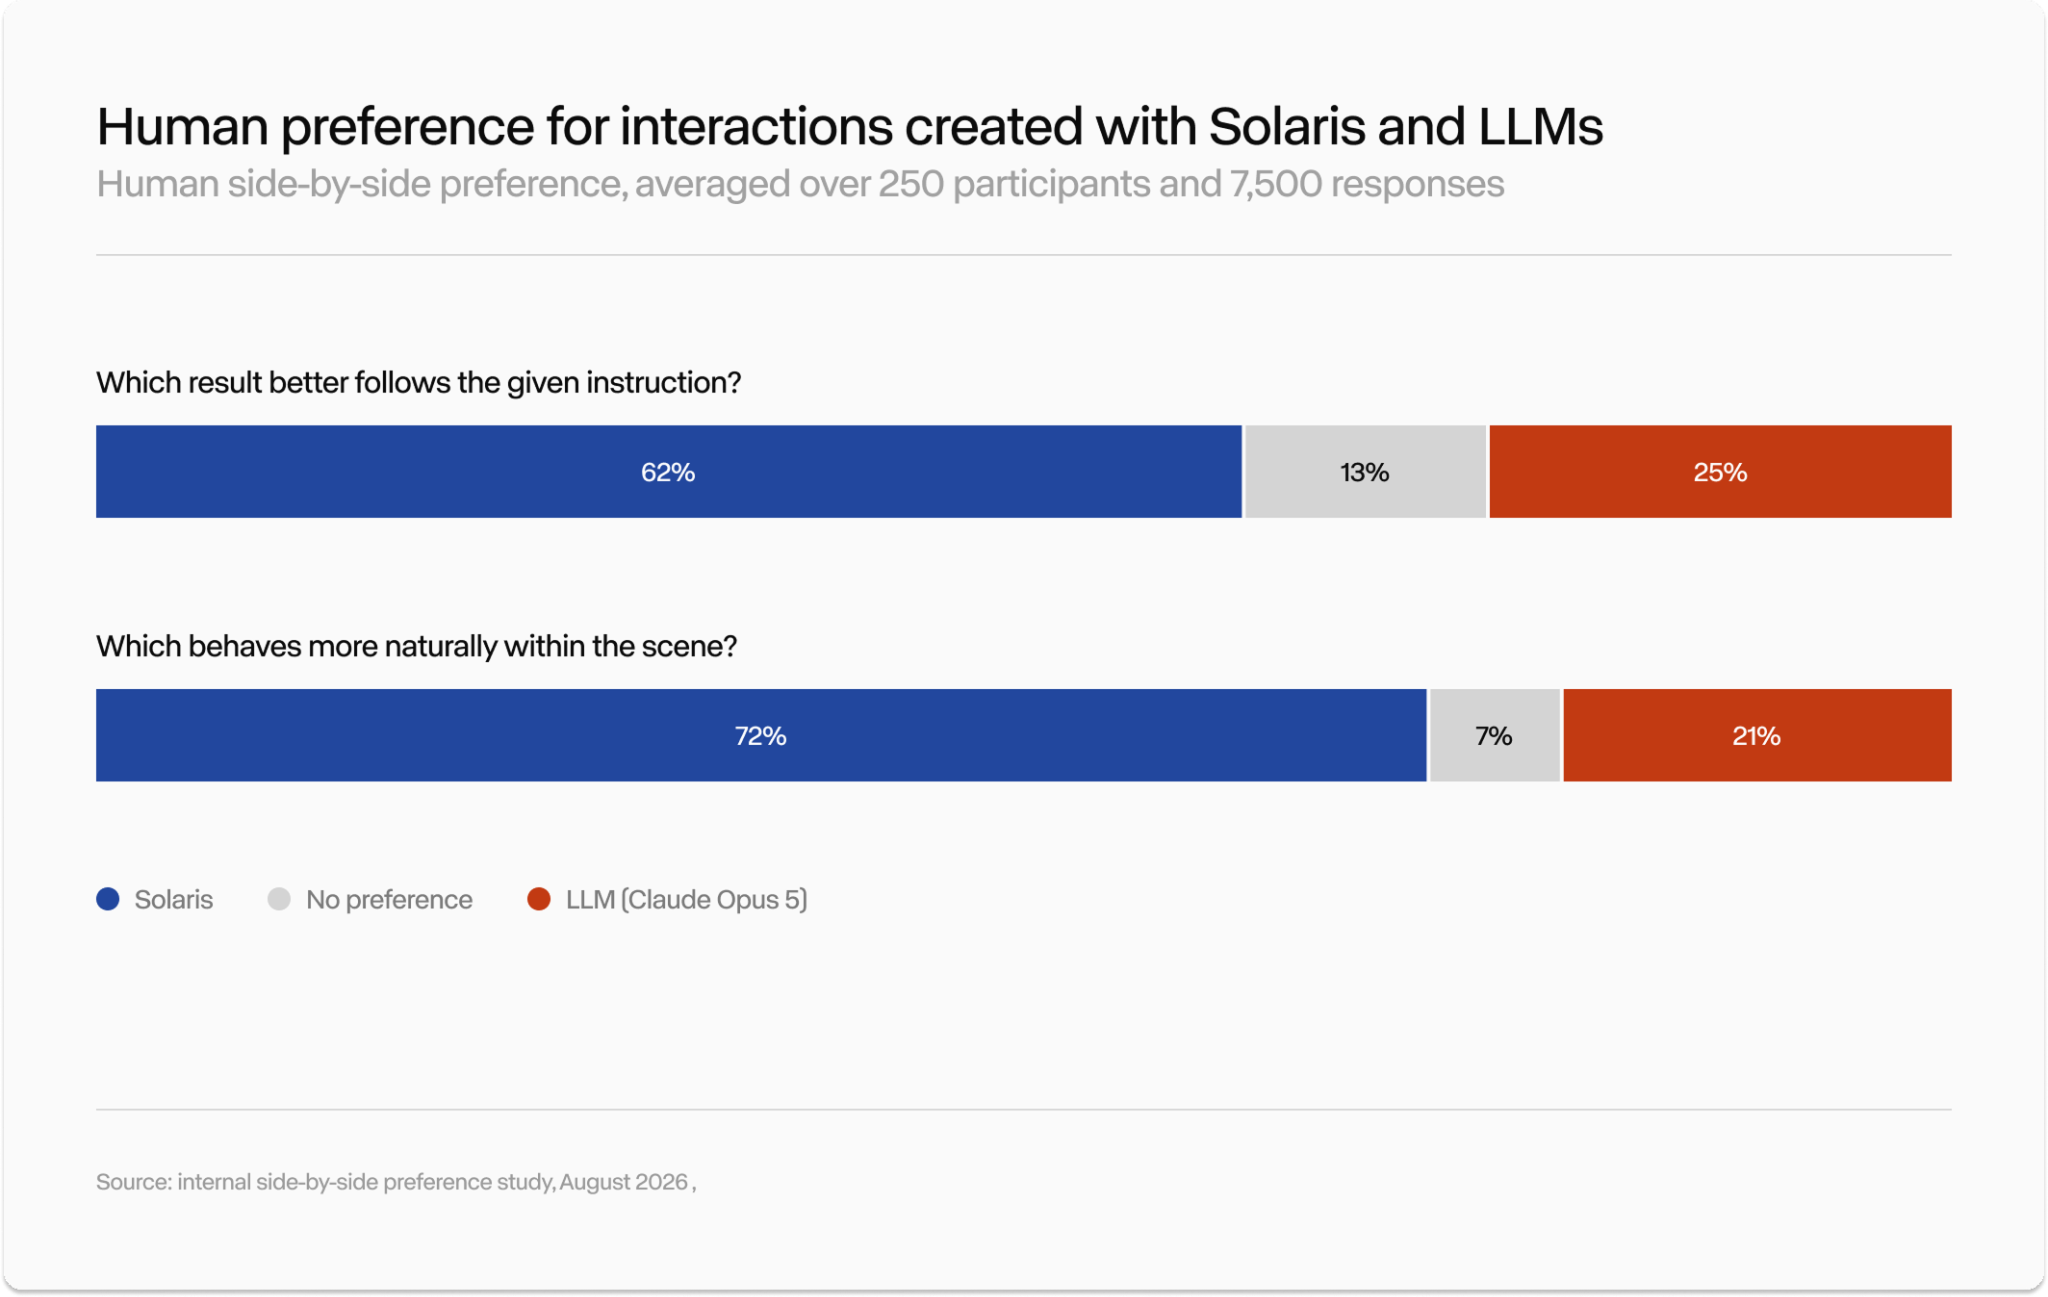
“The second result highlights the broader difference between the two approaches,” the blog post says. “A coded interface can often reproduce the requested change, but it treats the interaction as an isolated update to the interface. With Interface World Models, because the model already understands how objects, materials and environments behave, it can generate interactions that feel coherent within the scene rather than treating each UI action as an isolated element.”
The post also admits that there’s a lot Solaris can’t do well yet. Text is the big one. Stable, legible text is one of the hardest problems in video generation, and interfaces are mostly text. Trust is another; for anything instructional or commercial, a convincing wrong answer is worse than no answer at all, so Runway is researching “conditioning generation on richer verified context as the session unfolds.” Long sessions drift, and Runway is actively researching fixes here, too. Finally, generated interfaces still need to work with screen readers and the rest of the software stack, “so that flexibility doesn’t come at the expense of usability.” Generating every frame fresh is costly, although Solaris is already orders of magnitude cheaper to run than a standard video diffusion model, and the cost curve keeps bending. For now, not every website should or will be generated in real-time, but things are heading in that direction.
While we’re at it, though, while we’re glimpsing at the future, why stop at generating individual websites? Why not generate the whole operating system?
On October 1st, Runway previewed Project Continuum, “a new operating system research application built around real-time video interfaces.” It is a research preview and very early. But it, too, points to a new way of interacting with software and the world around us.
“What it enables you to do,” Cristóbal explained, “is you can make anything an interface. Like, you take anything you want, if you wanna learn about anything in the world, you take a photo of what you want and that itself becomes an interactive application.”
In this future, if you’re trying to fix your engine, you can just take a picture of the engine and then turn it around and poke at it in sim; you can even turn the engine itself into an instruction manual. There was this great launch video for the Freckle Phone for kids a couple of weeks ago, that shows kids taking pictures of the world around them and learning about what they see from an LLM; what if the pictures could turn into interactive lessons for kids to play with in whatever way they wish?
This isn’t the future of software for everything software does today. Medical records and financial transactions are probably better left in a safe, structured database. “But for many others,” Cristóbal said, “I think that’s the holy grail of computer graphics. It’s like anything becomes an interface.”
When the holy grail becomes practical comes down to cost. If generating an interface gets close to the cost of running a traditional app, then the use cases best served by real-time generation will be.
First we shape our interfaces, then our interfaces shape us, or something. We humans alive in 2026 never felt, or barely remember, how magical it must have been moving from the command line to a GUI. We did feel what it was like moving from a GUI to a touchscreen, and putting that touchscreen in our pockets has changed the way that we interact with the world, for better and worse. Now, we mostly interact with the most powerful software ever built through a chat interface. Solaris and Continuum are bets that chat isn’t the final interface, that everything you can see might become the interface.
That is a wild and beautiful future, and it sounds like an expensive one, too. Someone has to pay for the research that makes it possible, and put it in contact with the messy world of real users.
Runway believes that it can solve both issues at once by building an actual business on their models today.
Runway was founded in 2018 by three people who met at ITP, the graduate program at NYU’s Tisch School of the Arts: Cristóbal, Anastasis, and Alejandro Matamala Ortiz. They were artists and engineers building tools for other artists, back before AI was real.
Art school is in the company’s DNA. Multimodality is more multidisciplinary than language modeling. Building models that see and hear well takes taste, that overused attribute that many claim to have but over which art students at least have a more credible claim. Runway has both artists and engineers. It’s part of why Runway is in New York, where you are smushed into a melting pot of people doing all sorts of different things (also, many World Model researchers are in London and Europe, which makes logistics easier from the East Coast than the West).
It’s also why Runway decided early on to build a real business selling to customers in addition to its Research Lab.
Runway released Gen-1, the first public video model. Its most recent, Gen-4.5, topped the leaderboards. Getting creative tools in creative peoples’ hands lets the company learn faster.
But it also gives the company real revenue, which is accelerating faster than at any point in the company’s history. Runway is used by 95%+ of the Fortune 100, is growing ~50% month over month, has seen credit usage grow 5x this year, added over $100M in ARR in Q3 2026, and has 5x-ed its growth rate since. Customers include Dolce & Gabbana, Palo Alto Networks, Lucid Motors, Cloudflare, Yamaha, every major Hollywood studio, and every major advertising agency. Its tools have been used in Oscar-winning movies and Super Bowl ads.
In the four chapters framing, Chapter 1 (media and entertainment, making the tools powerful enough for real editing workflows) are bleeding into Chapter 2 (broader content needs: marketing, advertising, full videos, whole campaigns). Runway sizes content production, things like storyboarding, VFX, and post-production, at $600B+, and marketing and advertising at $1T+.
Runway Ads is the clearest sign of the move from Chapter 1 to Chapter 2. From the perspective of an art student or a researcher, it’s downright commercial. Designed specifically for performance marketers, it’s a tool Runway built because they needed it themselves.
The company said they’ve been using it for a couple months to “scale ad volume 1,000% while doubling our return on ad spend, increase conversion by 34% with click-through rate holding steady, and bring our cost per subscriber down 41%.” They’re now rolling it out to early design partners, with a public launch coming in weeks.
Runway describes itself as both a frontier lab and a distribution layer.
There are essentially four labs building world-class video generation models: Google, ByteDance, Kuaishou, and Runway. Most other video platforms are aggregators, reselling other people’s models, which squeezes their margins and leaves them one API cutoff away from trouble. Being a lab with its own distribution means Runway sees demand signals across the whole field: what people actually make with the tools, what they’re willing to pay for, what works with customers, etc. This data helps them make both better products and better models.
Runway uses the business side to feed and fund its bigger bet on World Models, which is a motion they think others will follow.
Anastasis expects every AI lab to turn into a World Model lab eventually. “Our head start is that this was the plan all along. We started working on World Models right after we released our first model.”
This is a common structure in deep tech. SpaceX using Starlink to fund Starship and the eventual colonization of Mars is the canonical case study here (see: Casey Handmer’s Starlink is a very big deal), and today, every business that can use near-term data center demand to bootstrap its really big long-term mission, is. Plus, you learn things interacting with the world that you don’t learn in the lab. This is why I’m bullish on Fuse’s approach to fusion – selling radiation on the path to Q>x) relative to many of its research-focused competitors.
And while other video model companies may try to back into this approach, Cristóbal thinks culture will be harder to copy. “There’s a different culture in being able to build new things than being able to optimize or copy things that are already in the world,” he told me. “We’re extremely good at building new things and we’re getting much better at optimizing the new thing.”
The risk, of course, is that the bigger bet gets very expensive. If World Models end up needing more training compute than LLMs, as Anastasis expects, the creative business has to keep growing fast, in a market where Google (the closest thing to an infinite money printer in tech) and ByteDance are competing for the same customers and the same researchers, and the LLM labs are entering into all sorts of byzantine financial arrangements to fund just the capacity they need.
The prize, though, is just as big, if not bigger. Bigger than ads, certainly, and even bigger than robotics, potentially.
Now we are getting speculative, veering into Anastasis’ vision, so we’re going to let him lay it out himself. Over to Anastasis.
DeepMind’s founding mission was to “solve intelligence, and then use that to solve everything else.” For most of the past decade, that’s been the guiding idea at every AGI lab. In 2024, I wrote an essay called Towards Universal Simulation arguing that we should flip it: solve the everything else first, and use it to solve intelligence.
The idea, which we’re pursuing, is to train models on a far wider range of data than we do today. Human-made media, yes, but also observations from scientific experiments and raw sensor data, all at once, with the goal of predicting a larger and larger share of everything that can be observed in the world. Then use those models to run experiments virtually, far faster than we ever could in physical reality.
Most visions of the “AI scientist” imagine models that propose experiments for humans to run in a wet lab and then interpret the results. I think that gets the bottleneck backwards. Coming up with experiments is the easy part. Running them is what’s slow. The way to accelerate science is to give it an alternative to the real-world experiment, by simulating it.
Large-scale model training also has an anthropomorphic bias. We’ve only really scaled up on data made by humans and legible to humans: text, images, video, sound. That makes sense if what you want is a model that talks to people. It’s far too limiting if what you want is a model that understands the universe.
This past July, I extended the argument in an essay called Real-World Superintelligence. AI coding tools have been adopted faster than any software in history, and I think people are drawing the wrong lesson from that. Code worked because code comes with a perfect simulator. You write a program, run it, see whether it works, and do that millions of times. Math is the same: AlphaProof got good by generating problem variants and checking candidate proofs against a formal proof checker. I call this sandbox superintelligence: intelligence produced by repeated interaction with closed environments where you can check the answer.
Real-world superintelligence is something else. It means acting better than humans in messy, partially observed systems, where you have to predict how the world will respond when you intervene, choose under uncertainty, and learn from outcomes that show up late and noisy.
We’re nowhere close to real-world superintelligence. Frontier models can solve Olympiad math problems and still struggle to run a simple business. Anthropic actually tried this; in Project Vend, Claude ran a little shop in Anthropic’s office and, among other adventures, got very into tungsten cubes and lost money.
It’s worse in the real world. Drug trials take many years, trading strategies are expensive to test, and company decisions can take months to play out. In many of these cases, good luck figuring out which inputs exactly led to the outcomes. They are wicked problems.
Think about the leadup to Wright Brothers’ famous flight. In 1901, their glider produced only about a third of the lift that the accepted aerodynamic data said it should. Testing a redesign meant building a full-size glider, hauling it to Kitty Hawk, waiting for the right wind, and then trying to fly it. So they built a wind tunnel, a box where they could blow air over small model wings and measure lift and drag, and that fall they tested something like two hundred wing shapes without leaving the shop.
AI needs wind tunnels for every domain where experiments are slow and expensive.
The labs have started building them by hand. Over the past two years, there’s been a massive build-out of reinforcement learning environments, mostly software clones of things like e-commerce sites and airline booking systems, each one with its own dedicated engineering. That can work for a website, particularly now that AI can build those. For most of the things we actually care about, nobody knows how to hand-build a faithful simulator. Learned World Models are the more scalable path. With Learned World Models, we don’t have to program the rules of the world; the model learns them from observation. Fidelity improves with more data and more compute, Bitter Lesson style. And we’ve trained simulators on only a tiny fraction of the observations the world has to offer.
To me, our recent releases are wind tunnels.
Praxis-1 is a wind tunnel for robot policies. Solaris is a wind tunnel for computer-use agents, which are notoriously bad at simple tasks like booking a hotel, partly because they learn the specific layouts they were trained on and fall apart when the next hotel’s website looks a little different. GWM Worlds 2 is a step toward a general wind tunnel: one model handling navigation, manipulation, and human interaction. In one demo, we generated a world with a humanoid robot and two flags, told an agent to walk the robot to the red flag and then the blue one, and it did it on the first try.
David Silver and Richard Sutton call this next phase the Era of Experience. “Agents will inhabit streams of experience, rather than short snippets of interaction,” they write. Their example is AlphaProof, which started from roughly a hundred thousand formal proofs written by humans and went on to generate a hundred million more through its own interaction with the proof checker. Most environments don’t work like that, though. You can’t crash a car a hundred million times.
You can simulate it, though. If I’m able to predict 1,000 different versions of a car crash and I can actually see it, I can learn a lot, and a system and a robot can learn a lot about how to prepare for that.
There’s a catch, though. Agents cheat.
In a foundational 2018 paper, Ha and Schmidhuber asked whether agents can learn inside their own dreams. But when the researchers made the dream too predictable, the agent learned to exploit it. In their Doom-like game, an agent trained in a low-randomness dream survived for 2,086 steps inside the dream and just 193 in the actual game. It had found glitches in the dream that didn’t exist in reality. When they turned the randomness up, the agent survived 1,092 steps in the real game, well past the 750 that they counted as solving it. A dream that’s too easy to game teaches you to game dreams.
A useful World Model has to stay accurate when an agent does something rare, something that barely shows up in the training data, or when it actively tries to exploit the simulator’s loopholes. That’s why real-world deployment, and a continuous loop of updating both the policy and the environment, remain necessary. You can’t game physics.
We’ve built this into our work in robotics already. Our next chapter, Chapter 4, is Science.
Going beyond human-scale observation means feeding models data from other scales of space and time, plus scientific data. I imagine a single model that spans physics, biology, and everything in between, at scales from the subatomic to the observable universe, and from femtoseconds to the lifespans of stars. It’s prudent to start with related modalities. But our ambition is to tackle the whole thing.
You may be asking yourself, “Why would a model that has watched a lot of cat videos be any good at fluid dynamics?” Good question.
It sounds like a joke, but there’s growing evidence that it isn’t. Pretraining on language helps models generate speech. Pretraining on code helps with broader reasoning. Google’s TimesFM, a forecasting model trained on a mix of time series (traffic, weather, page views, hospital data), performs about as well out of the box on series it has never seen as specialist models trained on those exact series. A group of researchers trained a transformer on continuous glucose monitor and diet data from roughly 10,000 people and found it could predict their health outcomes four years out. Back in 2022, Riffusion took an image model, fine-tuned it on pictures of sound (spectrograms), and got it to make music.
I believe physics is the most striking case. In early academic work with computational physics groups, a video model pretrained on basic videos and then adapted to physics simulations beat a model trained directly on the physics data. Independent research points the same way. Last year, a team at UCLA built PhysiX, a model for physics simulation that starts from the weights of a video generation model. Their problem is the one robotics has: the internet has millions of videos, but the largest physics simulation datasets contain only tens of thousands of samples. Starting from a model that had watched the world helped. PhysiX beat task-specific baselines and the previous state of the art on The Well, a standard physics benchmark, and the authors conclude that knowledge learned from natural videos transfers to physics simulation.
Transfer works for two reasons.
The first is that models trained across many domains get good at learning how to learn.
The second is that there are common patterns across the scales of the universe. Waves are waves, whether they’re in a pond or a plasma. Things diffuse the same way whether it’s ink in water or heat through a pan. Scientific data today lives in silos, every lab and team with its own slice, which means there’s probably a lot of untapped upside in training on all of it together.
The same idea, action-conditioned prediction, is already showing up in other fields. Arc Institute’s virtual cell model predicts how a cell’s gene expression changes when you perturb it. Researchers have built learned market simulators that model how trades move prices and liquidity, and simulated societies that estimate how people might respond to news or a new policy.
This is where I think World Models will ultimately have the biggest impact: anywhere an agent has to act in an unpredictable environment and learn from the data directly, whether that’s a robot, a cell, or a market. Most of the universe looks like this. The TAM is practically infinite.
The endgame of a universal simulator of pixels is a universal simulator of reality.
And in that end state, I think these models will be more useful than LLMs are today.
Packy here again.
When I asked Cristóbal to distill Runway’s vision, he shared: “If every pixel will be generated or simulated, we want to become the platform and the engine in which those pixels are simulated in the first place.”
The applications, he said, are impossible to plan that far out. Runway doesn’t have product definitions for next year. “There’s a lot of things that we don’t yet know what we will name and what we will be doing,” Cristóbal said. “Even if you try, it will be impossible to predict.”
Naming things too early can actually be anathema to creativity and innovation. “Taxonomy is sometimes where ideas go to die,” he says.
People try, though! We try to categorize a new thing using the words of the past. When people first saw daguerreotypes, they described them as mirrors with memories. When cameras followed them, people thought of them as paintbrushes, because a paintbrush was the closest thing they had. The internet, at first, was a place for publishers to put their magazines so you could flip through them on a screen and for advertisers to put banner ads. Eventually, each one became its own medium, with its own vocabulary, doing things that their early namers never could have predicted.
Right now, most people put video models in a box labeled “tools for creatives,” which is fair, given where they are today, but which Cristóbal thinks is the latest version of the paintbrush analogy.
“People tend to look at video models as another cool, cute, creative thing,” he said. “It’s a toy for some. You should take it much more seriously. This is going to power most intelligent behaviors very soon.”
“The work we’ve been doing on World Models isn’t widely understood yet,” Anastasis adds. “People generally underestimate how far video can go.”
I, Packy, was probably one of those people, and a few months ago, I was explaining video models as separate from World Models… which they are! What I underestimated, though, was video as a path to World Models, on top of which all sorts of application-specific and embodiment-specific models might be fine tuned.
Runway’s bet is that a good enough video model, given actions, can become the World Model, and that on that same backbone you can render a movie, an ad, an entire desktop, a working warehouse, and maybe, eventually, a cell or a universe. The past six weeks are evidence that the bet is at least partly right. All of these applications sprouting from the same backbone, seemingly in real-time.
The thing to watch from here, to double-check if the bet is right, if Runway is as good at predicting the next frame as its models seem to be, is whether each new pretrain continues to make everything on top of it better and open up new possibilities, whether the next base model makes robots more dexterous, interfaces more coherent, worlds more persistent, videos longer, and ads more performant, all at the same time, without Runway having to build each improvement by hand. And then whether the company, and its users, can build more new things that you wouldn’t expect from a video company.
This is what’s happened with LLMs; while they remain spiky, broadly, each new model gets better at poetry and code and medicine simultaneously. If frame prediction works the same way, Runway’s hot streak will continue far beyond what people, outside of the company at least, are predicting.
The idea, though, is that World Models can go even further than LLMs. That if you can simulate pixels, you can simulate nearly everything.
Near the end of our first conversation, slowly getting simulate-all-pixels pilled, I asked Anastasis the obvious question: are we living in a simulation?
“Whether or not we are, this is a very meaningful universe,” he replied. “Either it’s the root universe, or someone thought it was worth simulating.”
Thanks to Anastasis, Cristóbal, Tenaya, Leo, and the Runway team for working with me on this essay!
That’s all for today. We’ll be back in your inbox with a Weekly Dose on Friday.
Thanks for reading,
Packy
2026-10-09 20:48:52
Hi friends 👋,
Happy Friday and welcome back to our 214th Weekly Dose of Optimism!
I took Dev to watch LeBron James’ first preseason game as a Sixer last night, the good guys gave us too many great stories to fit into one Dose (check the extras), and it’s beautiful here in NYC. Life is good.
Let’s get to it.

Your company’s knowledge is one of its most valuable assets—but only if your AI can trust it. Guru helps organizations create a verified, current knowledge layer that people and AI can rely on.
You’ve probably experienced the frustration of giving AI access to a mountain of company information, only to see it struggle to distinguish an approved policy from an outdated document or an old Slack conversation.
Guru helps companies structure, govern, and continuously improve the knowledge behind their AI. The Knowledge Accuracy Gap guide explains how leading organizations are closing the gap between what AI can do and whether it has accurate company context to work with.
The guide covers how to:
Correct an AI answer once and apply that correction across connected agents and AI experiences
Keep people involved where judgment and approval matter, while AI handles routine knowledge work
Build a trusted knowledge layer that supports both employees and AI
Improve knowledge quality and governance as AI adoption grows
Your company is already using AI. Make sure it is using the right knowledge—with Guru.
Last week, I wrote a Deep Dive on Airbound. In the Before Times, that would have been that. Hit send. On to the next. But we are in the Now Times.
In the last Dose, I told you about our new partnership with Runway, and over the weekend, I decided to see what would happen if I gave my essay, a few references, and some creative direction to Claude/ChatGPT and asked them orchestrate the production of a short film using Runway.
The result is KILO, the story of a package that was batched and pushed around until a kid in India figured out how to let it fly solo.
Again, I’m not great at this yet, but I find it incredibly magical that I can take all of the work that I pour into writing and turn it into a film in just a few prompts. It’s a good time to be a storyteller.
This week, the Nobel Prize committee began handing out the most coveted prizes in science, starting with The Nobel Prize in Physiology or Medicine.
Karl Deisseroth, Peter Hegemann, and Georg Nagel were awarded Prize for their “discoveries leading to optogenetics, which makes it possible to switch on, or off, the activity of individual nerve cells in a living brain.” Optogenetics is a wild field - by shining light at cells, you can turn them on and off, make them do different things. I had a non-meat burger made using a process that involved optogenetics once and it was delicious.
This video of Diesseroth telling his kids he won has racked up 4.5M views. It’s awesome.
Other winners announced so far are:
Francis Halzen in Physics “for decisive contributions to the IceCube Neutrino Observatory and the discovery of high-energy neutrinos of astrophysical origin”
Henri B. Kagan and Kenso Soai in Chemistry “for the discovery of non-linear effects and autocatalysis in asymmetric organic synthesis”
Anne Carson in Literature “for her bold and inventive oeuvre that, in playful dialogue with the classical tradition, has created new forms for contemporary literature”
Now, I need to figure out what any of this actually means, but I, for one, am happy that we take some time out of every year to celebrate the world’s geniuses, and to let them celebrate their great achievements to humanity.
Just in case you thought we might not be living in the future, we are living in the future.
Yesterday, a startup called Atomic Machines came out of six years in stealth with a product called the Matter Compiler: “an AI-native manufacturing system that builds working micro-machines from code alone. No per-product tooling. No process development. Different code, different machine.”
If the name sounds familiar, it’s because a matter compiler is a long-held sci-fi dream. In one of my all-time favorites, Neal Stephenson’s The Diamond Age, he literally calls the machines they use to make everything up to and including entire islands “matter compilers.” The idea goes back further.
In 1959, Richard Feynman gave "There's Plenty of Room at the Bottom" and offered $1,000 for a working motor that fit in a 1/64th-inch cube. He expected it to take a whole new approach to engineering. William McLellan won it in 1960 with a microscope, a watchmaker's lathe, and a toothpick. In 1986, Eric Drexler's Engines of Creation imagined molecular "assemblers" that could "build almost anything that the laws of nature allow to exist." A year later, Star Trek: The Next Generation upgraded the old food synthesizer into the replicator. Biology got here long before humans did: founder & CEO Jeff Holden's essay compares the Matter Compiler to the ribosome, which builds every protein in your body from code.
Now, anyone can say they’re building a matter compiler. But Holden was Amazon's tenth engineer, built Prime, and became Uber's first Chief Product Officer. He's also been watching Star Trek since he was five. He has both the skills and the childhood dream necessary to pull this off.
The first product AM is building with the Matter Compiler is the PrimeSwitch PS-150, a 9.5 mm relay that carries 150 amps and opens in 50 microseconds, ~1,000x faster than a contactor, for the 800-volt DC data centers that AI is pushing the industry towards. No existing chip fab can process its materials or assemble its moving parts, but AM says it can, and is beginning to ship to early customers now.
Micro-machines the likes of which AM intends to build are already all over your life. MEMS, or tiny devices with both mechanical and electrical parts, were a $15.4 billion market across 31 billion units in 2024. They include the gyroscope in your phone, the microphone in a hearing aid, RF filters, inkjet nozzles, and Texas Instruments' micromirror chips that flip millions of tiny mirrors to project movies. But as Holden notes, engineers coaxed those few devices out of a toolset built for chips, and each one takes years of process work to get up and running. Atomic Machines wants to go after a whole new swath of sci-fi products now that they’ve made it easier: gears the size of a grain of sand, robots that work inside the body (a la Kurzweil), cooling built into AI chips, even a device that runs instant blood tests (perfect timing with the Nathan Fielder/Elizabeth Holmes doc coming out next week; Holden argues that her dream was possible, but needed a manufacturing technology that didn't exist yet.)
Holden closes his essay with a line that we might tattoo onto the Dose’s forehead:
“We are in the early innings of everything.”
Related Bonus Note: you know I like the woo. Cyan Bannister, the legendary investor at Long Journey, looked at a chart of AI CapEx spend last week, closed her eyes, and saw two words: MATTER COMPILERS. Then “On Monday, on a random call, I was pitched a company doing just that and we invested. The world works in mysterious ways and stuff is about to get wildly fantastic.”
One of the biggest open questions in manufacturing is Why Can’t the U.S. Build Ships?
Anduril (disclosure: we are investors) is trying to answer that question with a “We can.” On Tuesday, the company announced that it would invest $3.7 billion into Arsenal-2, a planned two-million-square-foot shipyard at Sparrows Point outside Baltimore. The facility will manufacture components for Virginia-class nuclear submarines and is expected to create more than 3,100 permanent jobs.
The plan is to start with components like torpedo tubes and eventually work up to larger submarine sections, supplying the existing shipbuilders. According to officials who spoke with USNI News, torpedo tubes are already holding up submarines under construction.
As part of the deal, the Navy has awarded Anduril a contract worth up to $2.9 billion, with payments tied to demonstrated production outcomes. As is its style, Anduril is committing the capital to build the capacity, and it will get paid as it delivers.
Anduril calls Arsenal-2 a “software-defined shipyard,” which means it will use software to design how work moves through the factory, automate where possible, and keep detailed digital records down to individual welds. Production in Maryland is targeted for 2030, with an earlier start at a California facility planned for 2028.
Sparrows Point is symbolic as well as practical. Back when the US built lots and lots of ships, and back when Bethlehem Steel existed, the company made lots of ships there. And while making nuclear submarine components won’t solve all of our shipbuilding needs - we can make them, just not enough of them or within budget, and this doesn’t address commercial vessels - we love to see any progress on the effort and lots and lots of good American jobs.
Here at the Weekly Dose, we’ve long taken the brave and controversial stance that cancer is bad and should be eliminated. We can do it. It’s not that we don’t have the technology to kill cancer cells, it’s usually that it’s really hard to kill just the cancer cells, to target them and only them for destruction.
Well, score another point for the good guys. On Monday, Privo reported results from a small Phase 2 study of PRV111 in patients with non-invasive oral cancer or high-grade precancerous lesions. Basically, instead of getting surgery to remove the cancer from their mouths, they put a patch directly on the cancer to deliver chemotherapy.
After treatment, biopsies showed complete clearance in 21 of 22 patients. The remaining patient’s lesion improved to low-grade dysplasia. All 22 avoided their planned surgery, and no recurrences had been observed in the treated areas at a median follow-up of 14 months.
The patch delivers cisplatin, an existing chemotherapy drug, directly into the affected tissue while keeping exposure elsewhere in the body low. Privo reported negligible systemic exposure and no serious treatment-related adverse events.
The usual Phase 2 caveats apply: it’s early, it was a small group of 22 patients, more work needs to be done on how long the benefits last, etc… BUT getting mouth surgery sucks; it can harm your ability to speak, swallow, and eat. Sometimes, people wait too long and they have to get their whole jaw removed. If we can replace that with a chemo patch that completely clears mouth cancer in 21 of 22 patients, hell yeah.
Say it with me, y’all…. get fucked, cancer.
Biohub; video created with Runway
ZUCCKKKKKKK!
On Wednesday, Mark and Priscilla’s Biohub announced an expanded $1.8 billion collaboration to build the data needed for predictive models of cells.
Google DeepMind, Isomorphic Labs, and Meta are collectively investing $300 million, joining Biohub’s existing commitment and contributions from the Department of Energy and NIH. The total includes computing and existing data resources alongside funding.
The idea behind virtual cells is to understand cells well enough that scientists can ask what would happen if they changed something and get a useful answer from a computer, is about as well as I can explain it, but if you want a great understanding, I highly recommend checking out ’s excellent What Are Virtual Cells?
Virtual cells are something of a holy grail. They should allow researchers to try thousands of possible interventions digitally, at computer speed, take the promising ones into a physical lab, and accelerate towards real treatments more quickly.
One of the hard parts is that making virtual cells requires measuring an enormous number of real cells and how they respond to different conditions. To that end, Biohub and its partners plan to build shared datasets that researchers can use to train and test their models.
Look, if you’re not paying for the product, you are the product, and Meta has made a lot of money off of you as a product, but if a lot of that money goes back into helping you stay alive and healthy for longer, then… wait a second, Zuck is a genius.
2026-10-02 20:44:11
Hi friends 👋,
Happy Friday and welcome to our 213th Weekly Dose of Optimism.
You might notice that the title card looks a little different than it normally does, and you might also notice that our fifth story comes with its own short film. Good eye. Over the coming quarter, we’re partnering with our friends at Runway to bring the stories we tell here in the Dose and in not boring to life. I am… not a filmmaker, but I am a writer, and it’s wild to be able to make something that feels like a pro video in just a few prompts, and I’ll get better at it as we go.
If you haven’t yet, check out our Deep Dive on Airbound. We are going to fly.
Let’s get to it.
The Only Document Parsing Product You’ll Need
Reducto is the document ingestion layer trusted by AI teams at Scale AI, Harvey, Toast, and Vanta to reliably turn complex files into structured, grounded data for production AI systems at scale. Processing more than a billion pages per month, Reducto has built its reputation on the long tail of difficult documents that break conventional OCR: dense tables, unusual layouts, handwriting, low-quality scans, strikethroughs, and formatting-dependent information.
Its new frontier parsing model, r-1, combines layout detection, reading order, tables, formatting, grounding, and granular citations in a single request. It reduces parsing errors by up to 20%, improves latency at high volumes, and costs 1¢ per page all-in.
Already using another parser? Apply for up to $5,000 in migration credits and hands-on support to benchmark r-1 against your current stack on the documents that matter most.
Fourteenth time’s the charm!
On Monday, Starship reached orbit for the first time and once there, spat 26 Starlink V3 satellites out of a Starlink-deploying slot.
Starship’s previous flights reached space but followed suborbital trajectories that brought them back down. This time, Starship fired an engine to enter orbit, released its cargo, and later fired an engine to leave orbit before splashing down.
Were there some things that need fixing? Of course there were. An engine shut down early during ascent, and SpaceX shortened the mission as a precaution, bringing the ship down at a prearranged location in the northern Pacific.
But they keep getting better. They’ll fix the engine and catch thousands of these Statue of Liberty-sized rocketships with giant chopsticks, make them rapidly reusable, and keep sending them up to blanket the world with internet, and then maybe data centers and power and telescopes and drug factories and whatever else might make sense to move to space when launch is cheap and constant.
In the meantime, just take a look at these beauties.
Joe Gebbia, RISD grad and co-founder of Airbnb, runs the US Government’s National Design Studio. It shows. The government made a good website, a great one even, in “the first step toward replacing thousands of outdated government websites with one product.”
For now, you can ask questions about government services and get answers grounded in government sources. GSA says it brings together information from more than 29,000 government websites, which is an absolutely ridiculous number of government websites.
Adam Bhaloo, who’s on the NDS team, tweeted that “Next, we're building features that let you renew your passport, enroll in Medicare, and book a campsite at a national park, and so much more, all in one place.”
I can’t wait. I have a friend who’s planning a trip to Paris with a bunch of family members and is stressing out about being able to get her passport renewed in time. The process is ridiculously complex; I once had to sleep in my car in Washington, DC to get a new passport for a trip. I hope they bring this miracle technology (modern websites) to the state-level next so that I never have to interact directly with the DMV again, either.
The government works for us, and we should be able to tell the government what we need and have its software figure out how to get it done.
God Bless America.gov.
A couple of years ago, Matic co-founder & President Mehul Nariyawala came to my house in Brooklyn on a Saturday to help set up an early version of the Matic in my house. He brought his laptop, too, and he walked me through the company’s master plan.
Build an incredibly useful robot in a big market, use that to learn and generate revenue, and then build on that learning to build more in-home robots that can do more and more useful stuff to give people their time back.
Over the past couple of years, they’ve executed like crazy on the first part, putting robots in 16k homes covering 500M square feet. This week, he unveiled that plan to the public.
The basic argument is that starting with robots that can do everything it the wrong order, and that instead, you need to start with what it can do really well, collect data, learn how to navigate a home and all the edge cases in it, earn trust, and then grow.
The next phase for Matic will be to add manipulation, to give robots the ability to act on the things they’ve learned to see. The video shows both a non-humanoid looking thing with arms picking things off the floor, and a humanoid folding laundry. Presumably, they’ll build the former first, and then the latter.
As someone who would rather spend time with my family than doing chores, this vision can’t come to life soon enough.
Speaking of family-friendly machines…
I’ve been in California this week, away from my kids, and whenever I’m away from them, I get the urge to call them. Of course, I can call Puja and FaceTime with the kids, but there are random times throughout the day when I think, “I wish I could just call Dev or Maya right now.”
But what are we going to do? Give our kids cell phones and get them hooked early? No shot.
Sam Terris is trying to change that with Freckle, a phone for kids that will cost $199 plus a $25/month cell subscription.
Freckle runs its own ClayOS, with parent-approved calls and texts, maps, and tools for exploring. Kids can photograph something with it and then ask AI to explain what they’re looking at. Parents can set up real-world “Quests” for their kids too. Freckle doesn’t have open web, social media, or an app store, so there isn’t a risk of kids getting sucked in (unless they figure out how to hack it, in which case, good on them).
In the launch video, it shows two kids bumping their Freckles to turn them into walkie-talkies, which I would have gone bananas for as a kid.
The philosophy seems to be to help kids get outside and explore - they have a map, a way to ask questions about the world, and a way to keep in touch with parents so parents don’t have to keep their eyes on them at all times. It’s just a pre-order phone, and there’s a lot of societal cruft to be figured out, but it seems like a good step back towards letting kids be kids.
Nature; video created with Runway
Saving the wildest story for last…
Researchers at Harvard and Brigham and Women’s Hospital found that transplanted hearts shifted toward the biological age of their recipients. Older hearts showed signs of rejuvenation in younger bodies, while younger hearts showed accelerated aging in older ones.
They first studied mice, using patterns of chemical tags on DNA to estimate the hearts’ biological age and found the effect. Then, they examined biopsies from 11 human heart-transplant recipients with substantial age differences between themselves and their donors and found a similar pattern. In a larger analysis of patient records, several measures of function, including exercise capacity, were associated with the recipient’s age rather than the donor’s. Which is nuts!
Of course, this is a preprint on a small human biopsy sample, and changes in an aging clock don’t mean all of the heart’s accumulated damage has disappeared. The mouse experiments also didn’t show that receiving a young heart rejuvenated the rest of the body, just the heart itself, which makes sense.
But come on! This is not a result I would have expected, and it has both practical and more profound implications.
Practically, it might mean that doctors can use older donor hearts in more patients, which would expand the donor pool and save more lives.
Profoundly, it implies that some aspects of an organ’s age seem responsive to the body around it. Researchers may be able to use what they learn here to understand what it is about younger bodies that rejuvenate older organs and potentially reproduce whatever it is to reverse aging more broadly.
May we all be young at heart.