MoreRSS

site iconLuke WroblewskiModify

Luke joined Google when it acquired Polar in 2014 where he was the CEO and Co-founder. Before founding Polar, Luke was the Chief Product Officer and Co-Founder of Bagcheck which was acquired by Twitte
Please copy the RSS to your reader, or quickly subscribe to:

Inoreader Feedly Follow Feedbin Local Reader

Rss preview of Blog of Luke Wroblewski

Crazy Agent Scale: Companies All-in on AI

2026-11-20 22:00:00

At the Crazy Agent Scale event at Sutter Hill Ventures, Clement Pang, David Cramer, Shawn Wang, Quinn Slack, and John Hayes demonstrated what pushing agents to their limits looks like today.
crazy agent scale event poster at the Sutter Hill Ventures speaker series

To kick things off, I shared an Alan Kay quote: "you can live in the future if you're willing to pay for it". In the 70s, Xerox PARC gave everyone a ridiculously expensive Alto computer and, as a result, lived ten to fifteen years in the future. The goal of this event was to see what living in the future looks like with agents at crazy scale. Here's my notes:

Clement Pang: Lessons from Building Intent

Clement Pang (co-founder of Wavefront) shared lessons from six months building Intent, an open source system for large-scale agent orchestration. He of course gave the caveat that tips and tricks in AI age poorly.

  • Give agents a spec that lives outside their context window, somewhere they can read, search, and edit as work progresses. Once agents have a shared space like this, they self-organize and use it for specs, logs, research, UI mockups, and more.
  • Intent represents work as a task graph where some tasks block others and some conflict. Because models often stop early thinking they're done, Intent quietly hints to the model when finished tasks unlock new ones, which drives work to its logical conclusion and makes the model seem smarter than it is.
  • Organize agents like a company with specialists (system prompts that govern how each agent behaves). One useful pattern is adversarial pairs: a PM specialist interrogates the user to build a spec while a second PM only critiques it and writes no code.
  • Having no context can be a feature. Code reviewers that never saw the implementation discussion regularly spot a third option the original agent never considered.
  • Long-running agents can retire to avoid compaction. A fresh agent spins up, the two do some knowledge sharing, and the retiring agent signs off (sometimes with a "nice working with you").
  • To save tokens, swap agents sleeping in loops while they wait on CI for monitors: JavaScript the agent writes that runs inside Intent and wakes it only on a signal. Better still is waking the agent only when there's something actionable, like a failing check, a missing approval, or a blocking comment.
  • After tokens, compute becomes the bottleneck. Intent's Rust backend (IntentD) runs on any machine, links machines into a mesh (so a task that needs Xcode finds a Mac), and now extends to cloud sandboxes and Kubernetes, which also limit network and file access.
  • Intent runs coding agents like Claude Code, Codex, Google Antigravity, etc. underneath through ACP, so the main challenge is getting the model to use Intent's tools (like its PR monitor) while keeping the system prompt close to the size of Claude Code's own.
  • Specialists and delegation are now optional, and the model decides when to use them. Parallelism still pays off for work like internationalizing an app, where small, clear tasks fan out to faster models.
  • Clement rarely types anymore. He uses dictation and a small hardware controller with a dial and status lights to move between agent workspaces.

David Cramer: One Agent for the Whole Company

David Cramer (co-founder of Sentry) built Junior, an open source agent that does nearly every job at Sentry and is its top contributor by commits. Opus 5.5 does 99% of the lift, the rest is automation and efficiency.

  • Run agents in cloud sandboxes. Local setups quickly hit disk space limits, port conflicts, database and Docker networking headaches, while sandboxes remove those choices (much like code formatters ended the tabs versus spaces debate) and scale indefinitely. Compute is roughly 10 to 20% of Junior's bill.
  • Skip role play. A single agent with access to the knowledge it needs, using one system prompt, handles every task at the company that isn't highly confidential.
  • Treat the agent like an intern: hand it the work and expect it to come back when it's blocked or done, with no micromanaging along the way.
  • Give the agent its own corporate identity. Junior has a shared account and email address, so it can log into services like Notion once and give the whole company access through it.
  • Attribution matters. Junior opens pull requests under its own name, co-authors every commit with the person who asked for it, and adds a footer. David expects every company will need an identity model that covers both the person and the agent.
  • Getting an agent to stay quiet until it's needed is hard. Magic "no reply" markers work but aren't reliable, while injecting a tool call that ends the turn works much better.
  • Use watches over loops. Polling loops are expensive (Intercom reportedly found about 60% of its token spend went to checking pull requests), so Junior subscribes to events like CI failures and review comments that get injected as user messages. Leaving review comments on a pull request produces far better output than chatting with a bot.
  • Before starting work, Junior checks whether anyone else has touched the task and pulls in related transcripts, which is more diligence than most people do.
  • Enforce core workflows with code and keep them out of the system prompt. Reject tool calls that skip a step, add co-author credits automatically, and route traffic through an egress firewall that can answer a raw gh pr create with instructions to use the right tool. The agent never sees secrets.
  • Tool descriptions and tool responses are powerful places to steer behavior, a lesson David learned building MCP servers.
  • Human attention is now the limiting factor. Junior pushes questions and ready-to-review pull requests into an inbox, and the team is experimenting with managing all work through that inbox and a single always-on thread.
  • Junior's biggest unlock came from answering questions. Anyone at the company (sales included) can ask how something works, and Junior clones the relevant repos in a sandbox, reads the code, and comes back with a correct answer.
  • Most companies shouldn't build one of these. Junior has taken thousands of hours and a team of five, and David would start with an existing framework like Mastra.
  • Junior's memory is basic: shared, stored forever, with passive extraction and recall injected into every prompt via hybrid search. Even so, it makes the agent noticeably more token efficient.

Shawn Wang: Tiny Teams and Internal Tools

Shawn Wang (Latent Space podcast, AI Engineer) talked about tiny teams, companies with more than $1M in revenue per employee, and how his own team uses agents to build internal tools.

  • Every company should have an internal tools repo where employees can build whatever helps them, with guidance on guardrails. Shawn's team has built its own code hosting, a drive with a DocuSign clone that files signed documents automatically, a calendar replacement, and more.
  • Facing a $40,000 a year bill for a mid-sized SaaS tool, Shawn ran a competition with a $10,000 prize to replace it. Entrants spent a few hundred dollars each building clones, the team hired the top two, and now owns the resulting software outright.
  • For the competition, he wrote evals that contestants could hill climb against, then had his buying team evaluate the finalists as if they were independent vendors.
  • Think in loops on top of loops: token generation, multi-turn conversations, tool calls, goals, and automations. The loop above all of these is how you direct the humans who direct the agents.
  • People increasingly want AI that owns an outcome and coordinates a team, a different abstraction than either a software factory or an agent on a loop. These agents also need to keep learning and research what to do next.
  • Most answer engine optimization (AEO) tools only report a score, so Shawn stores each model's full answer and reasoning, which shows exactly what to fix. One founder on the podcast was losing to a competitor because models had the wrong pricing information, and fixing it moved the results.
  • Give every agent a dashboard with a template that updates over time. Vibe coding a new report each time produces inconsistent results.
  • AI Engineer has transcribed and cleaned up every talk it's ever hosted and plans to release the corpus on Hugging Face so models can train on it, the opposite of blocking crawlers and charging for access.
  • Software factories are a comfortable focus for people in the room, but some of the most ambitious work is applying AI to science and real economic problems (Periodic Labs being one example). Memory and skills also remain largely unsolved.

Quinn Slack: Building a Company Around Agents

Quinn Slack (CEO of Amp, co-founder of Sourcegraph) shared how Amp passed $100M in ARR with the same 21 people it started with a year ago using agents to scale.

  • Amp spun out of Sourcegraph and couldn't grant stock options for most of its first year, which forced the team to do everything themselves without hiring experts.
  • Quinn thinks selling software to a broad audience is dead. He compared software companies using agents to a typewriter company celebrating that computers made its sales team more efficient while holding the seed of its own demise.
  • Software companies were organized around writing code being slow and expensive, with sales, marketing, and support each in their own box. Incremental changes like lighter code review or "agent first" processes don't go far enough, and the whole structure needs to be burned down.
  • At Amp, one person working with an agent owns something end to end: deciding what to build, shipping it, supporting it, and marketing it. Everyone owns at least 1% of the company, and Quinn believes that much responsibility and skin in the game brings out the best in people.
  • Amp received about 9,300 bug reports in three months, most filed by customers' agents, so they capture what the person was trying to do (and whether they were mad).
  • An agent clusters those reports into themes, pulls in telemetry, logs, customer value, and past communications, kicks off fixes, and drafts emails to every affected user, including people who never reported the bug.
  • Those emails often include free credits. Amp gave out about half a million dollars in credits over three months, less than 0.5% of revenue and far cheaper than a support team, and delighted users send even more feedback.
  • A human still reviews every outgoing email, because fully automated customer messages feel too impersonal.
  • Amp has no support, finance, or marketing teams. The best marketing turns out to be finding the 300 people who asked for something and building it for them.
  • The team built its own bug tracker in half a day, since they only needed about 2% of Linear plus a few things Linear would never build.
  • You can do all of this with any agent. If your company won't let you connect your agent to this kind of data, Quinn's take is that's pretty dumb.
  • Amp makes its money through joint ventures (with banks, for example) that earn it shares of companies benefiting most from AI. It avoids selling to software companies, which he doesn't expect to be around long enough to renew.

John Hayes: Running a Software Factory in Production

John Hayes (Reve; Pure Storage) walked through how his team runs a software factory in production for Motif, a product that turns an entire marketing department into code. Since marketers don't review code, agents build, verify, and fix it continuously on the live system.

  • Marketing work like ad feedback loops, landing pages, user journey models, asset generation, strategy, and reporting all becomes code. With everything in code, you can trace backwards from what's working to the assets, journeys, and strategy behind it.
  • A runbook skill shows the general pattern. It runs a program first and only falls back to a prompt for the agent when something fails, and the agent then fixes the script so next time no agent is needed. Over time, prompts turn into code.
  • The team doesn't use a bug database or continuous integration, and lets the system find and fix problems itself. At one point, the agent figured out it could spin up a sandbox and pull secrets from the database to populate John's local environment file.
  • For softer qualities in the UI, every component fills out contracts covering things like layout stability, focus, relevance, and how DOM elements can collapse. These get turned into a machine readable form so a verification harness can observe components at runtime and report findings.
  • Findings go to a judge that decides whether the component is wrong or the contract is, much like a unit test that turns out to be the thing in need of fixing.
  • At around 130 components, the system deadlocked for 48 hours trying to track the state of its findings, and steps kept getting dropped. The fix was alternating agents and scripts: scripts handle the busywork and return a just-in-time prompt for the next step, since agents forget steps no matter how emphatic the system prompt is.
  • On the backend, everything is stored in Git (about 600,000 files for a larger customer), so careless reads blow up the system. John instrumented every IO and byte to give agents a ratio of data read to output produced.
  • Agents have poor performance instincts, like running lots of small operations in parallel when batching would be faster. He ended up changing the API so batching was the only option, and gave up on letting agents access Git history at all.
  • In production sandboxes, agents are immortal. Each directory gets its own agent that lives forever, so keeping things in context covers for details it forgets to write down.
  • Each ad network integration ends up as generated code, and agents call each other the same way a program calls an executable, with requests transparently routed to other sandboxes.
  • Generated Python modules can run inside an agent debugger the first time they're used or whenever something breaks. The agent completes the task, returns the result, and writes the code so the next run is much faster.
  • Agents tend to look for fixes right where a problem shows up. Trace scripts, written by hand at first and later extracted from successful debugging sessions, broaden their view and get contributed back to the library where the problem originated.
  • When an agent goes down the wrong rabbit hole, you can insert a trace to redirect it. Often one extra sentence, like a reminder to do static analysis, is enough. The goal is super continuous development on a running system that keeps fixing itself.

Design by Playground

2026-11-19 22:00:00

For all the years there's been software designers, there's been a dominant software design tool: Photoshop, Sketch, Figma. Increasingly though, designers are making their own highly specific (and disposable) design tools using AI coding agents. Let's call it "design by playground."

So what's a playground? If you've been a front end developer, a playground isn't a new concept. Effectively, you create a tool that allows you to manipulate variables and see their outcomes on an interface in real time. You can use a playground to see a bunch of variants at once (long text, short text, no text), play with options (big text, bold text, red text), and actually interact with designs.
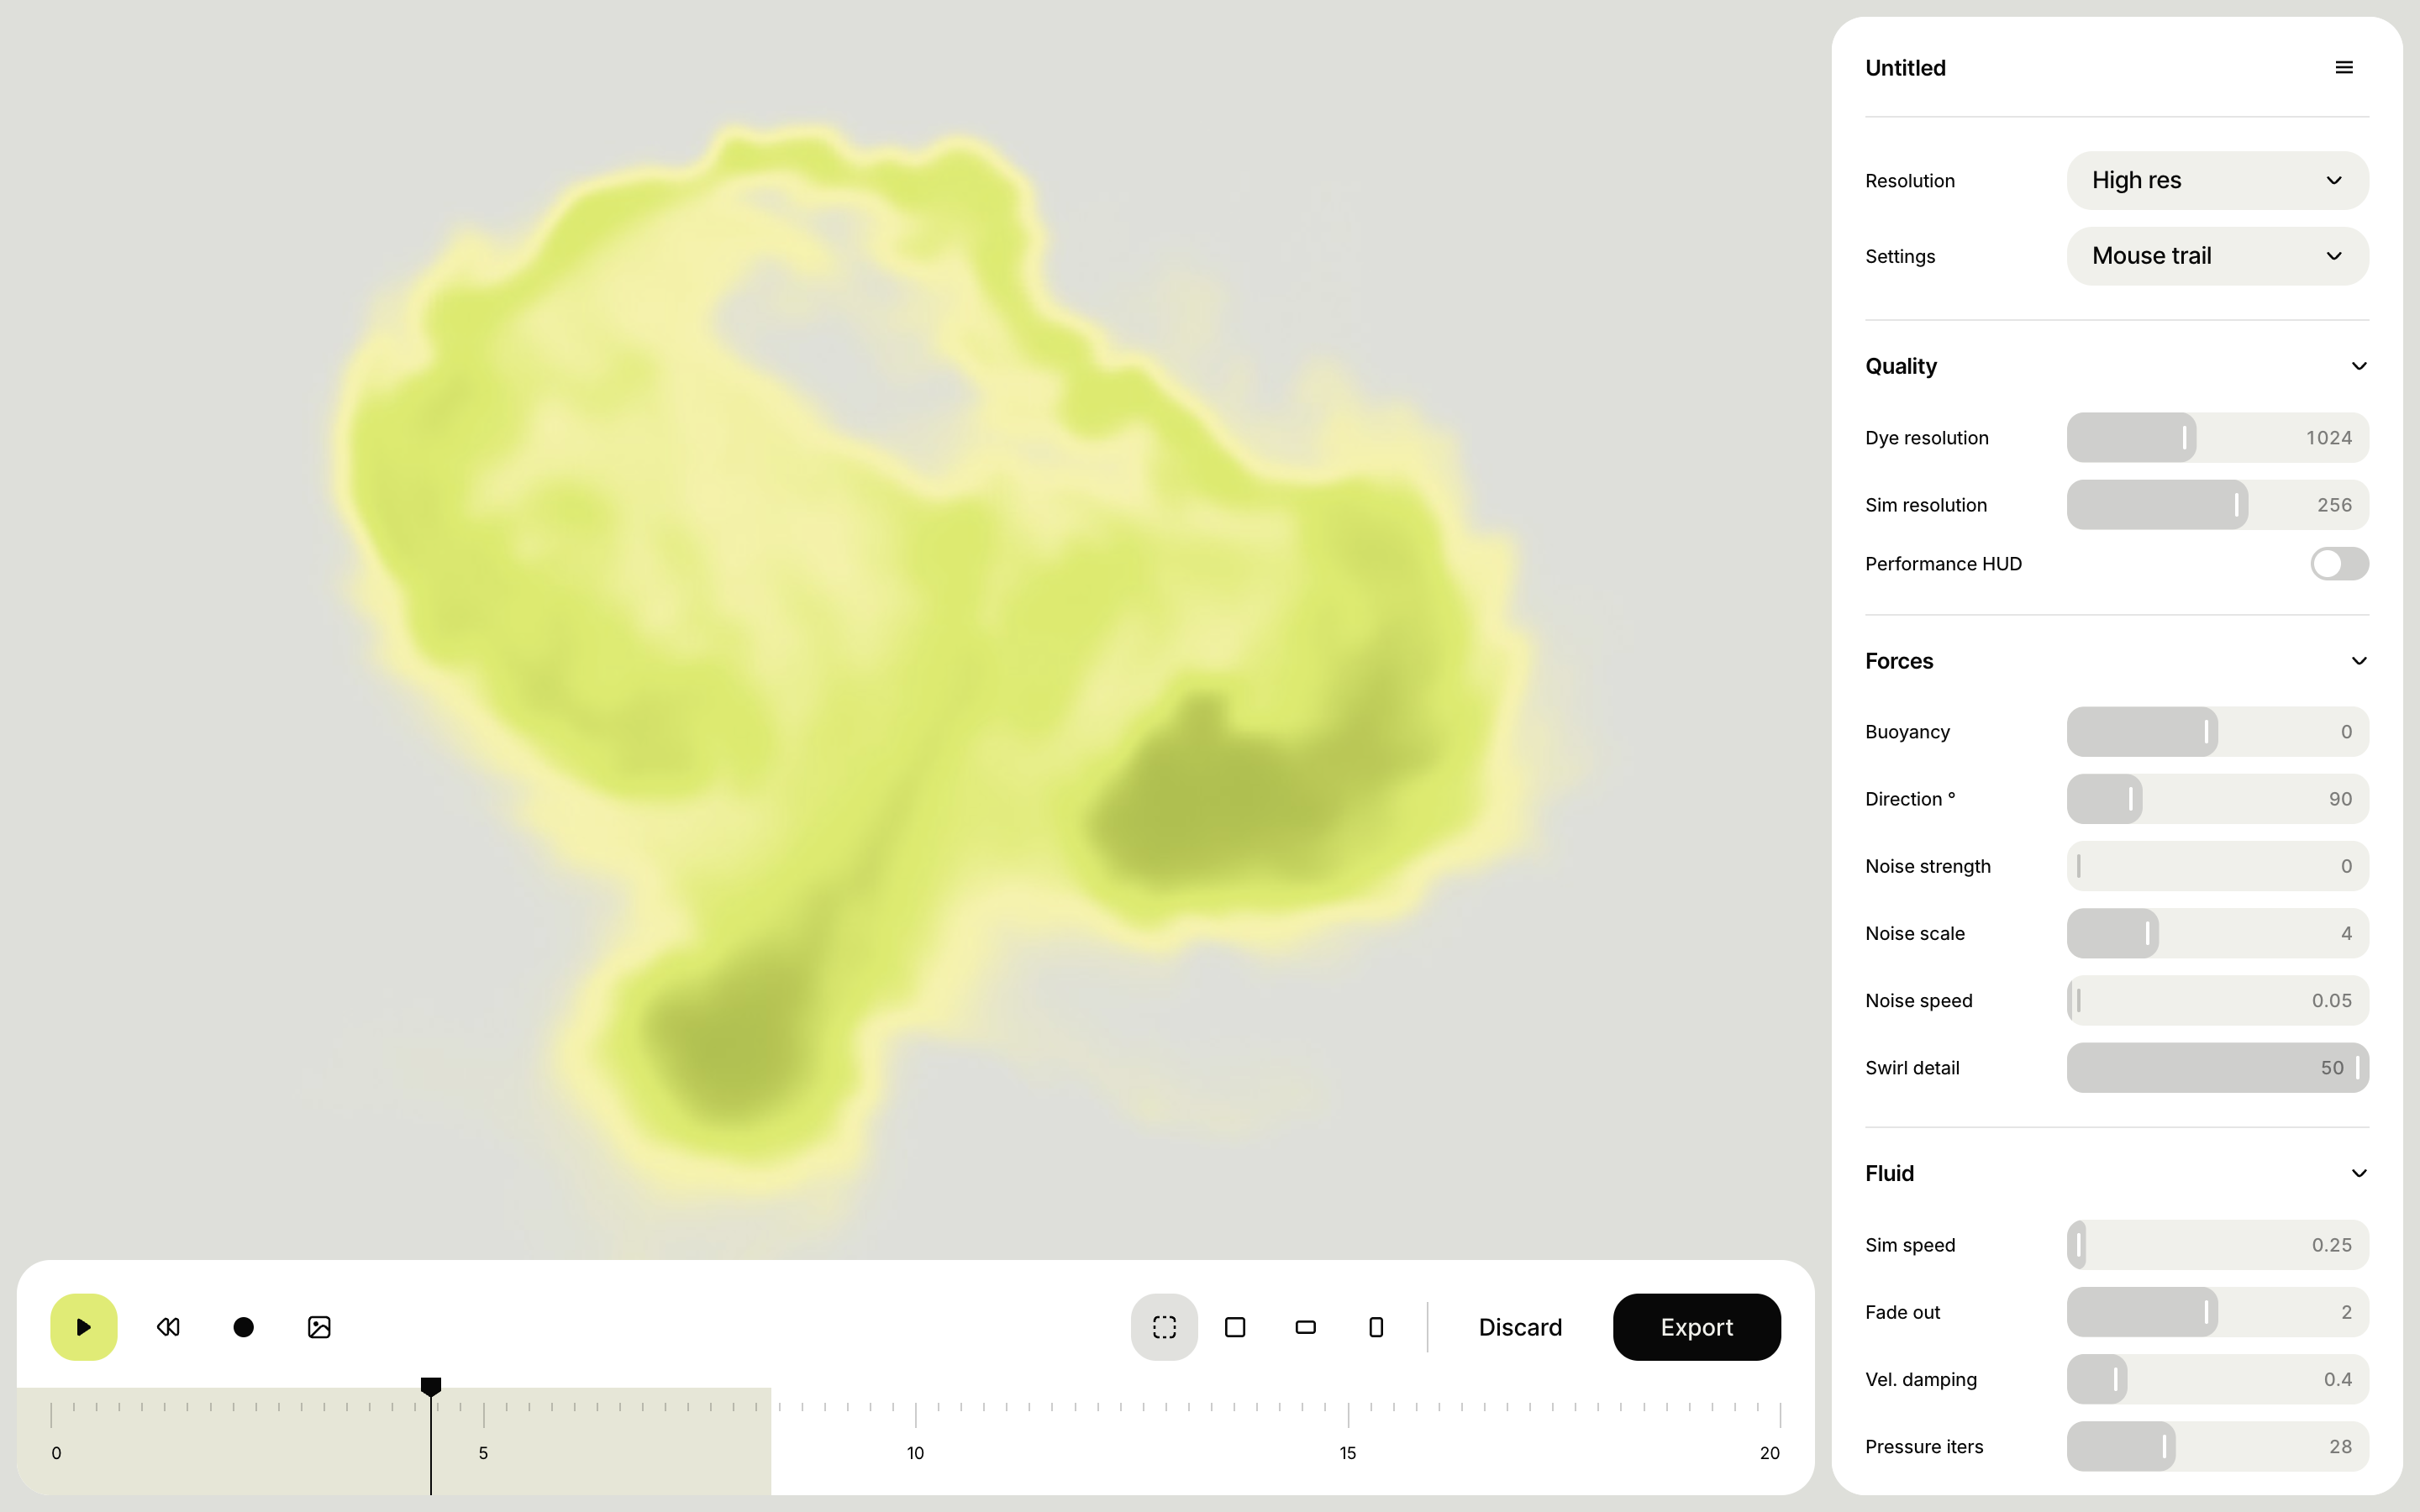
design playground for creating background animations in a software application

The advantages over static mockups are obvious, no matter how good you are at Figma. A playground can pull in real content and data, so long names, missing images, and other edge cases get thought about upfront instead of being flagged by developers later. Animation timing, transitions, and loading, empty, and error states all become controls you can adjust and test.
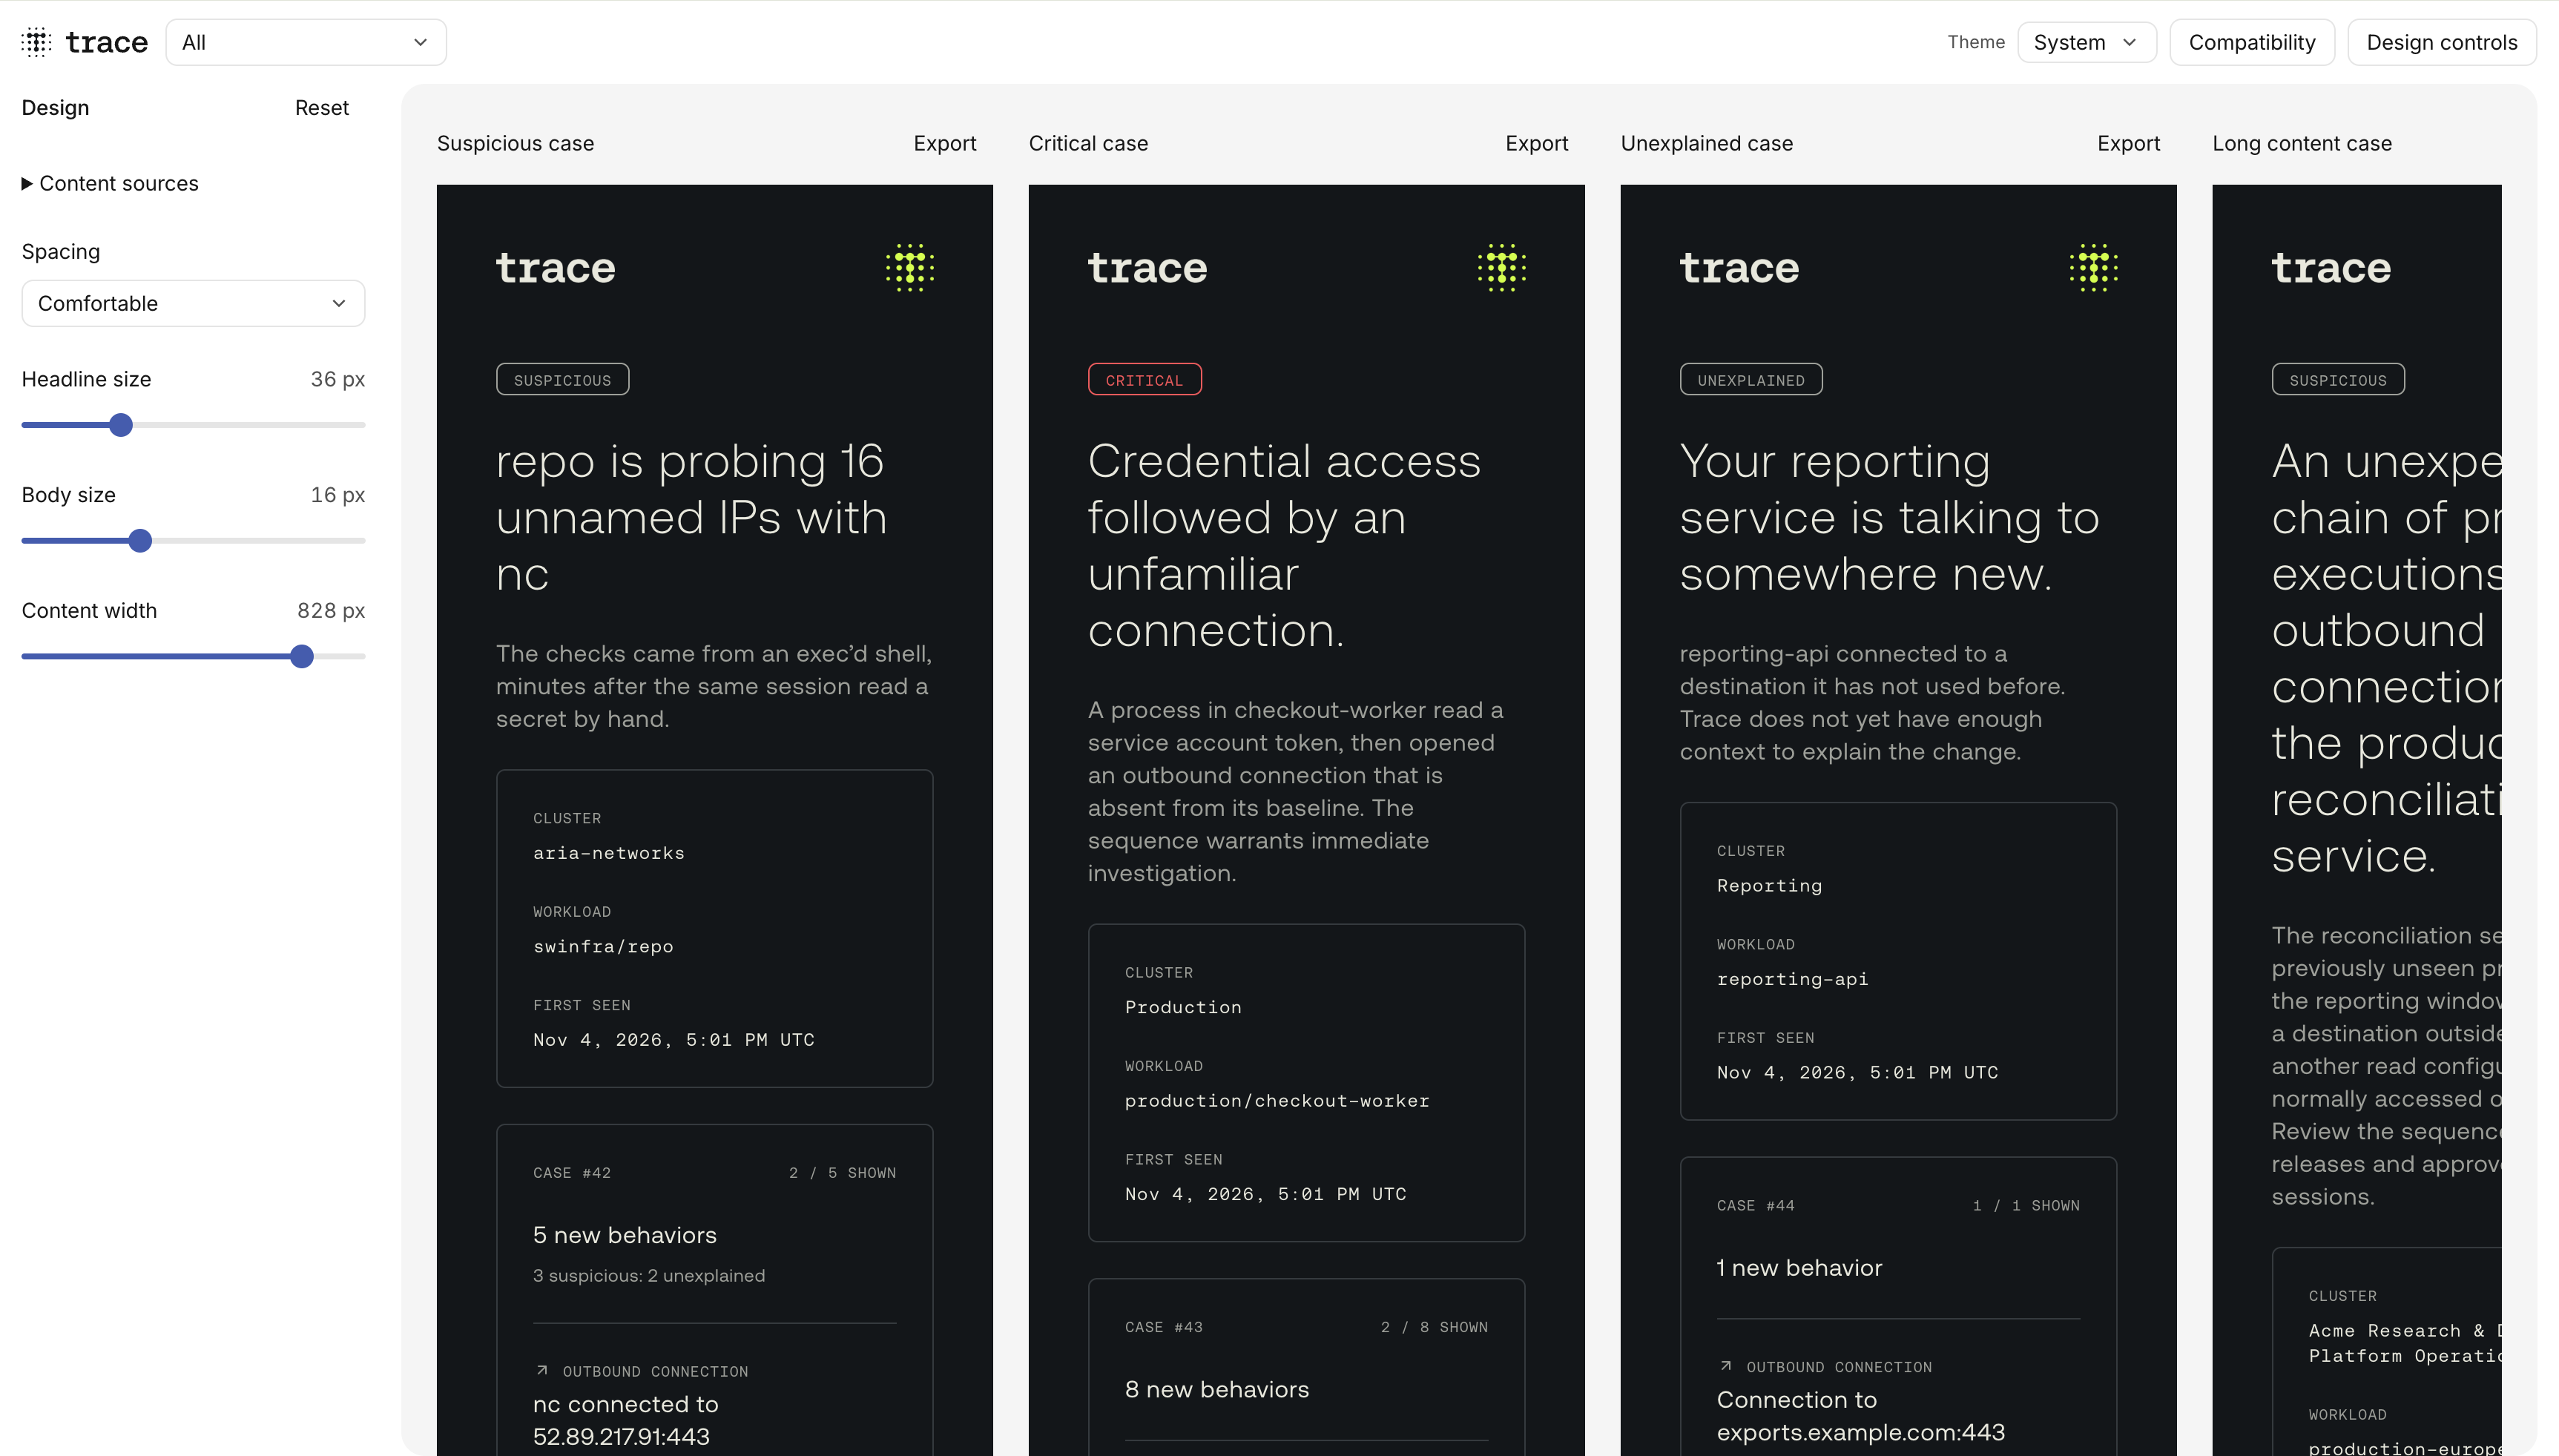
design playground for creating email notifications in a software application

But if that's the case, why hasn't everyone been designing by playground all these years? Put simply, building playgrounds took more time than it was worth. Fidgeting with mockups was faster and easier than building a tool from scratch that you'd probably never use again.
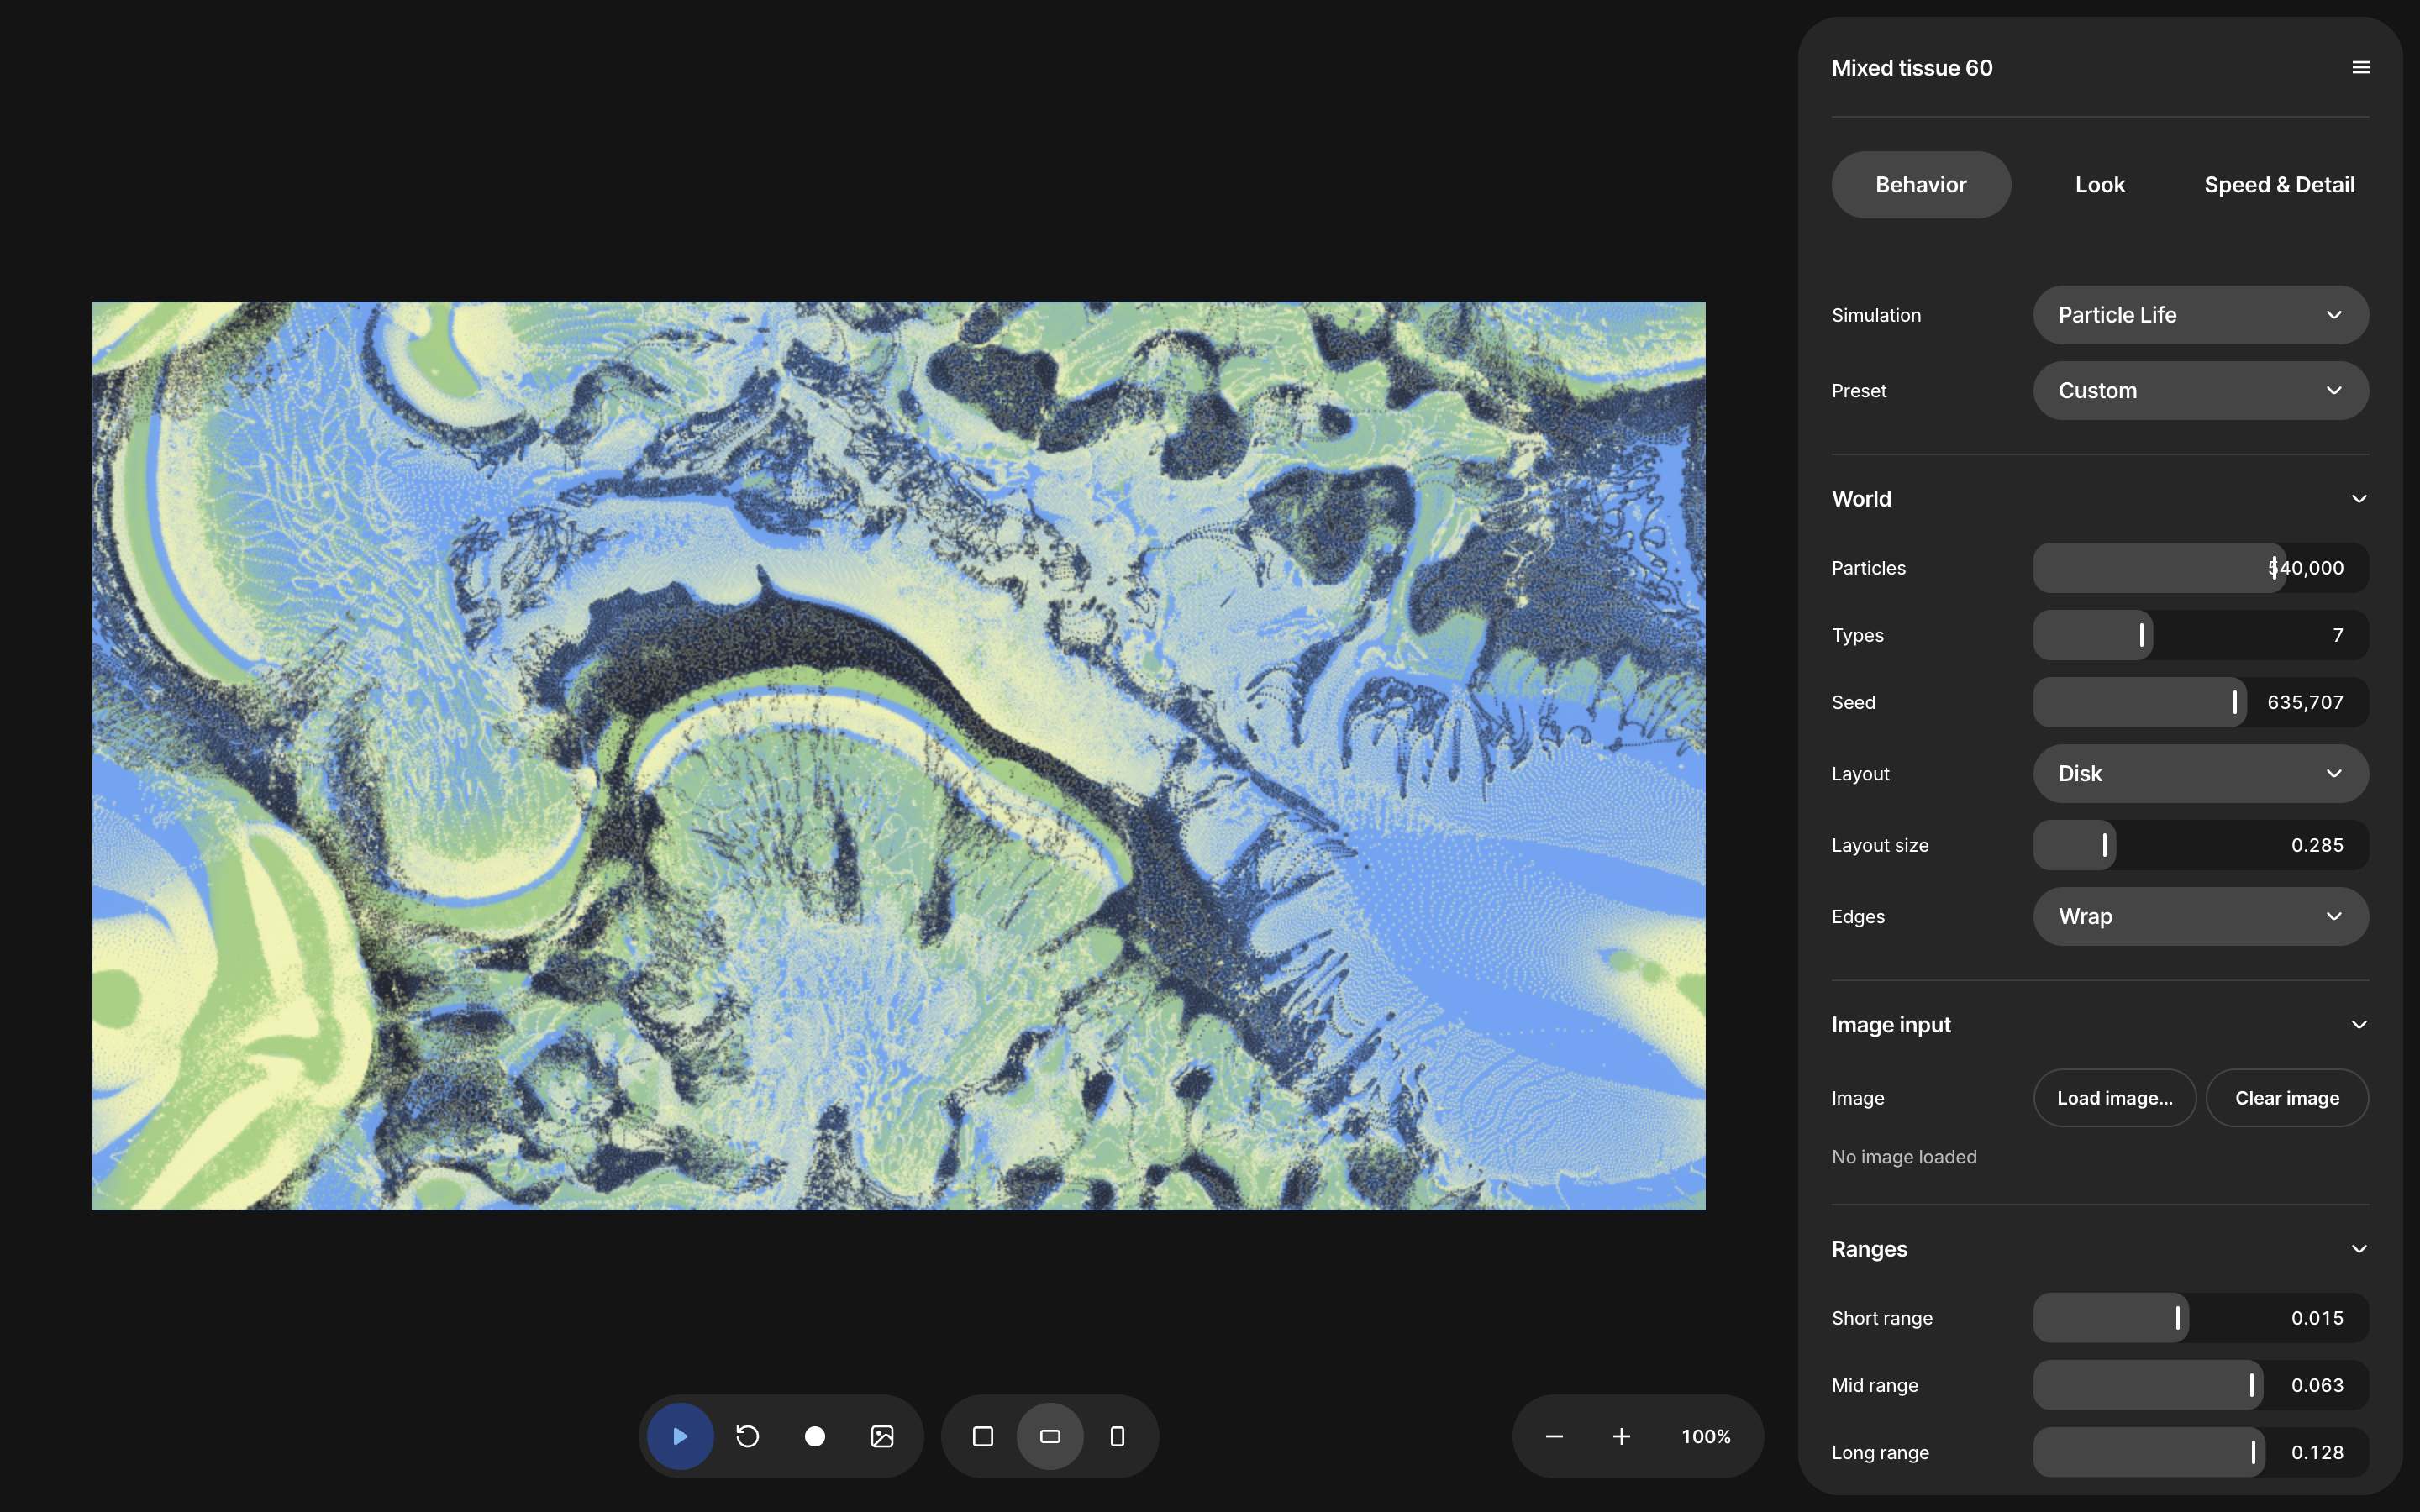
design playground for exploring a design language and creating brand assets

Of course, AI coding agents have changed that completely. A frontier model with a good harness can whip up playgrounds in minutes at minuscule cost. So there's no barrier to building a bespoke design tool whenever you need it. You can spin up a playground for a single design question or feature and toss it once you've got your answer.
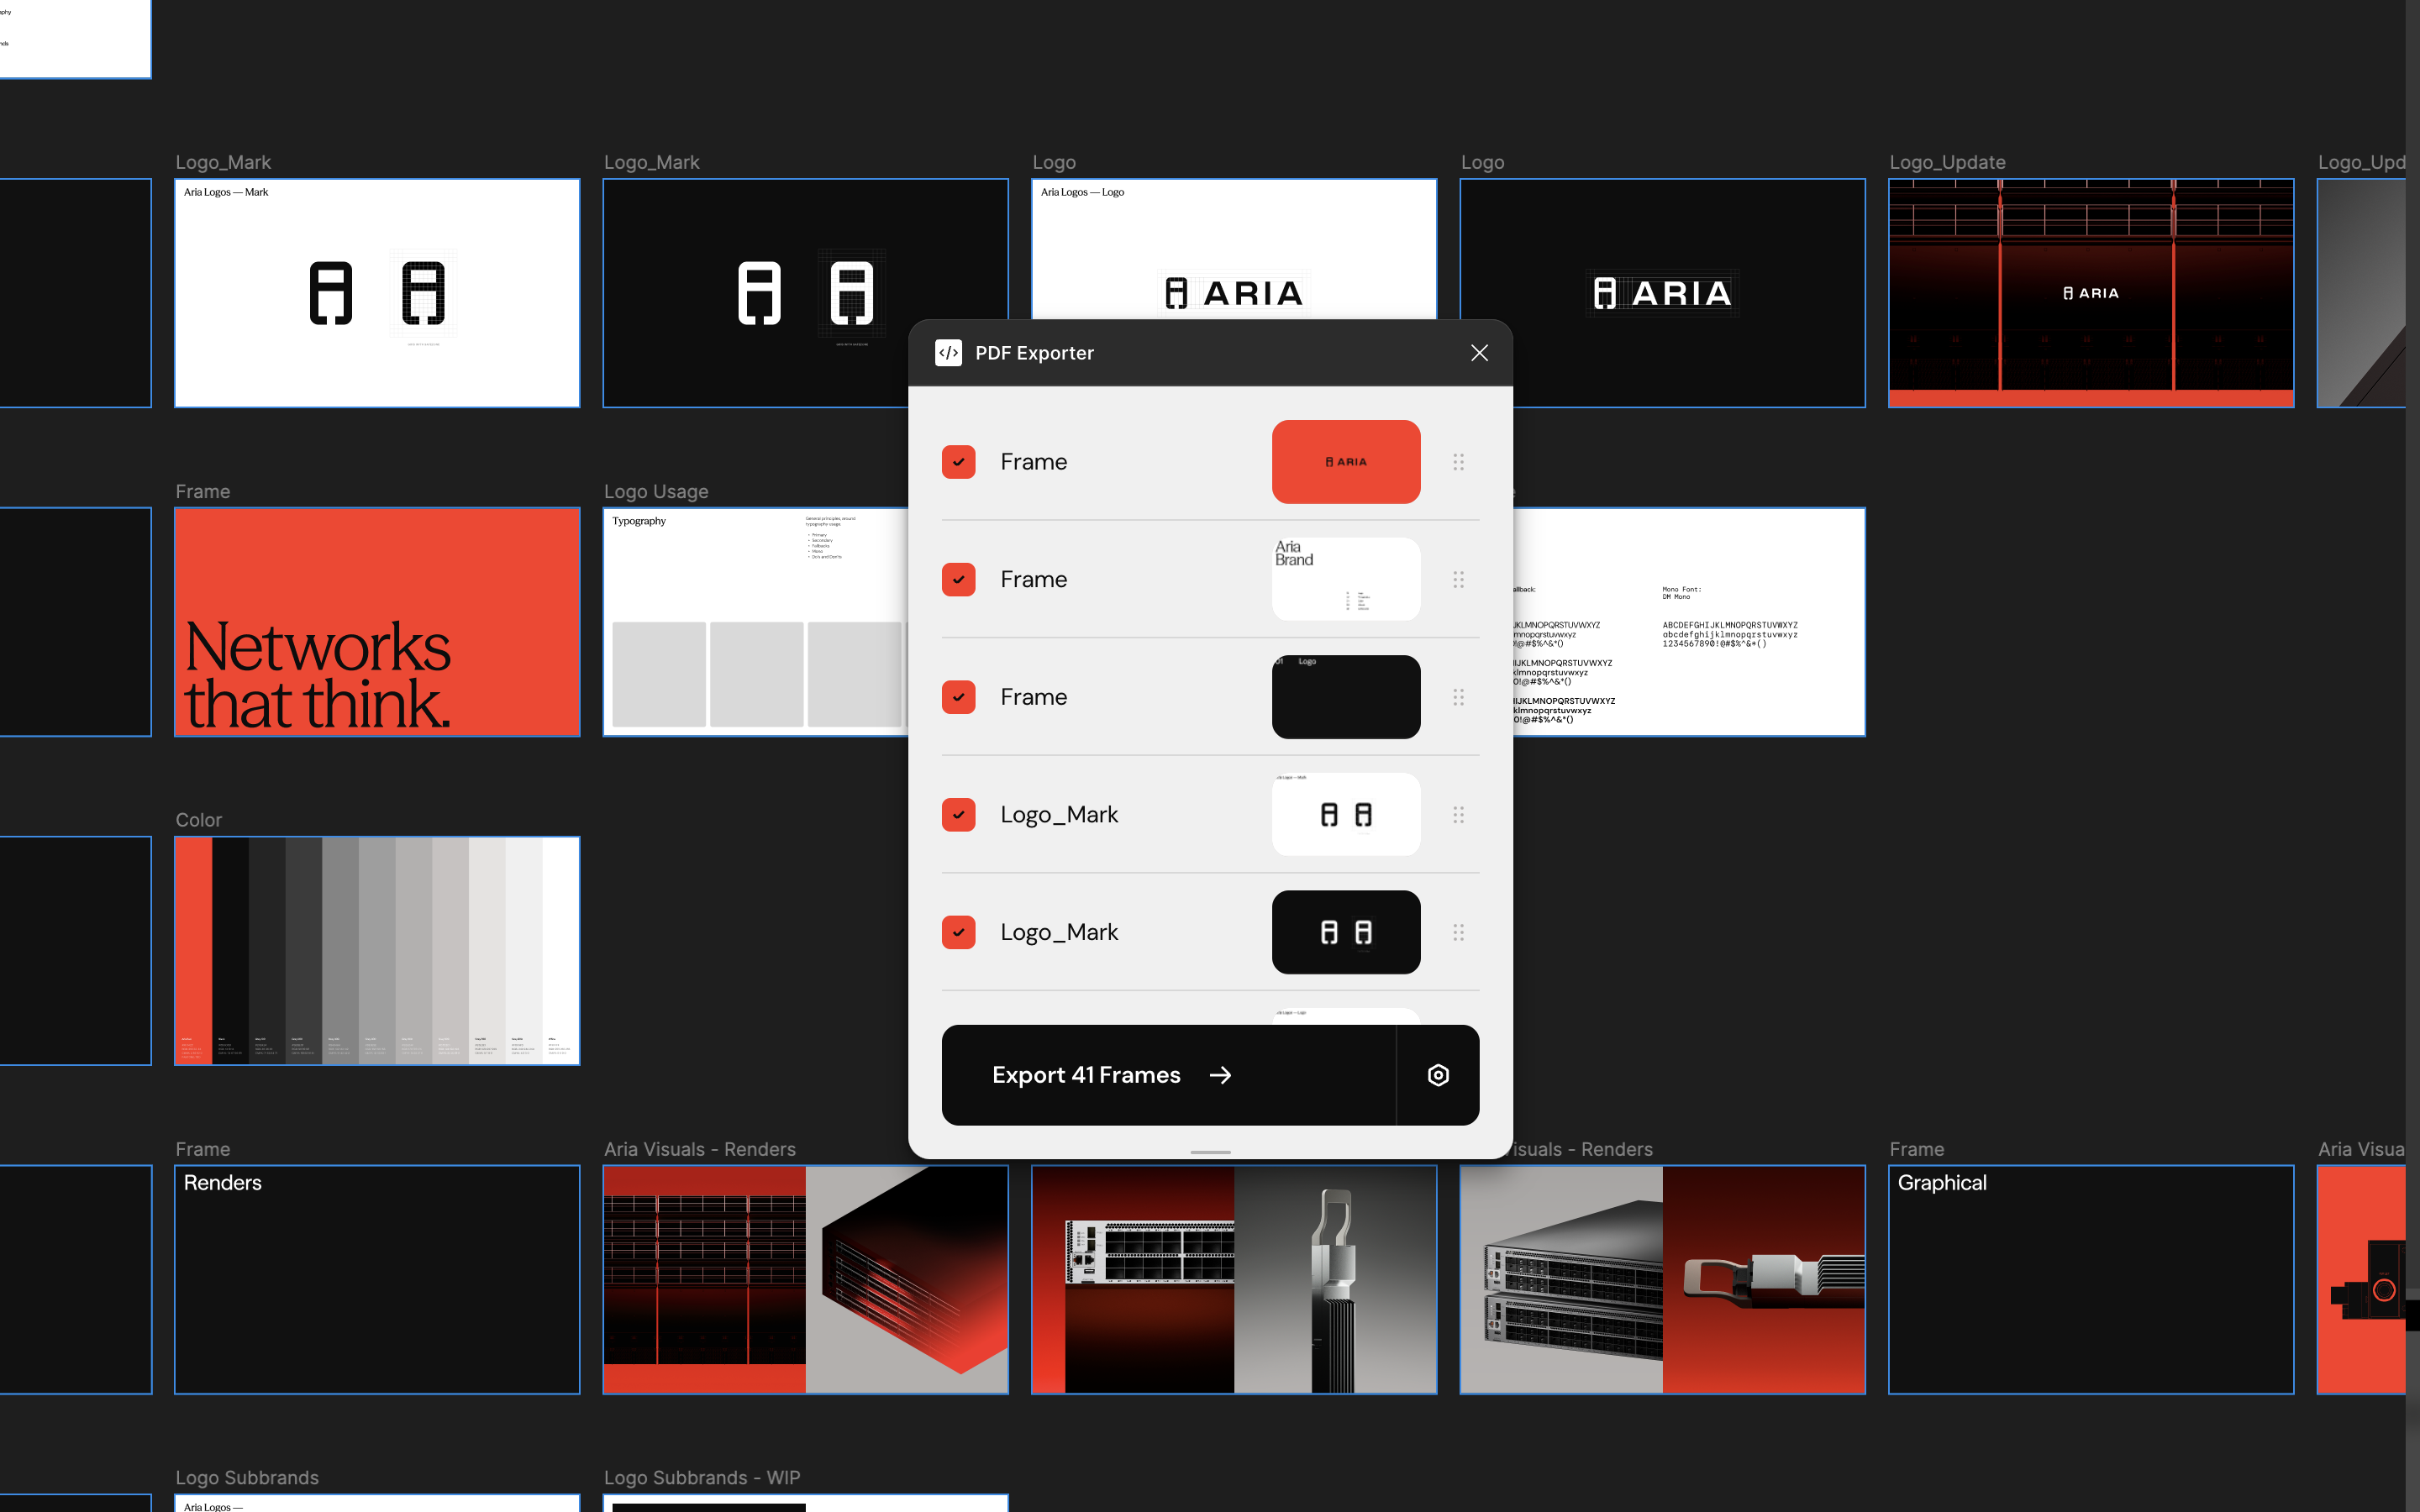
design playground for creating PDF documents from Figma files

And a highly specific tool often beats a generic one, especially when it runs in the same environment your software does: the Web, iOS, Windows, etc. That way you're looking at real font rendering, scrolling, touch and hover behavior, performance, and screen sizes, all things static mockups can only approximate. And the values you settle on in a playground can be exported directly as code or design tokens for engineers (or more likely, coding agents) to pick up.

Here's an example you can play with yourself... AI agents do a lot (reasoning, tool use, delegation, monitoring, etc.). How much of that work do you show people in your app's UI? I built a design playground to try out different designs, tweak details, and animate them to see what works best. Try it out.

Design tools used to be something you spent years learning. Now they can be something you make, use for an afternoon, and happily move on. They're called playgrounds for a reason.

Ask LukeW: in Your AI Tools

2026-11-11 22:00:00

To date, the Ask LukeW feature on my website has answered more than 17,000 people's questions about digital product design. Each of them, though, had to make their way to my site for that to happen. Going forward, they won't have to.

More than a billion people each month use AI through tools like ChatGPT, Claude, Cursor, and more. An ever increasing number connect these tools to their email, calendar, and apps. Now Ask LukeW's product design advice is available in those places too, through both an MCP server and a custom agent.

The MCP (Model Context Protocol) format is a pretty simple and increasingly universal way to connect AI assistants to outside tools. Adding Ask LukeW just requires finding the "Add MCP" setting in your favorite AI tool and plugging in: lukew.com/mcp. No account or login needed.

LukeW MCP retrieval sytem diagram: keywords and semantic

Under the hood, the Ask LukeW MCP supports two ways of searching everything I've published over the years: keyword and semantic search. Keyword search finds exact words or phrases, which is useful for names, quotes, or talk titles. Semantic search finds passages about the same idea even when the wording differs. These are exposed as tools in the MCP server so AI models can decide which to use and how to use them (i.e. only searching PDFs). Every result also includes a link back to its source so everything can be cited by the model.

While a set of tools can enhance an AI model's capabilities, it's on the model itself to decide when to use those tools and how based on the MCP server's descriptions and the tools' parameters. Bundling tools with detailed instructions makes things more specific and more useful.

For example, I made an Interface Designer agent by combining a larger set of instructions with the Ask LukeW MCP server. The agent starts with semantic search and then checks key phrases with keyword search. It removes duplicates, links each source, and answers in first person as me. When used in a coding tool, like Intent, this agent can assess a user interface and guide coding agents toward improving things.

When I asked the agent to “suggest UI improvements for the signup action” on a site we’re building, it evaluated what was there: a single email field with the right input type and autocomplete settings, a button that disables while the request runs, and a high-contrast primary action.

LukeW agent that evaluates user interfaces

Then the agent made specific suggestions grounded in things I’ve written or talked about and linked to the source behind each recommendation:

  • put the success message where people are looking by swapping the form itself for the confirmation
  • show progress on the button while the request runs
  • change the button copy from "Sign up" to match the header’s "Get early access" so it reinforces the offer
  • validate the email address on blur and offer a one-tap fix for typos like "gmial.com"

It also suggested prompts for a coding agent to act on any one of these design suggestions... all without anyone needing to visit lukew.com to hunt for articles or presentations. I've spent decades writing and presenting on how to design better user interfaces. Seeing that advice pointed at real code and turned into near instant improvements is perhaps the most useful form it's taken so far.

Design Feedback for AI Agents

2026-11-03 22:00:00

No plan survives contact with the battlefield and no design system survives contact with the product. Products are full of variants and combinations most design systems don't account for. So when AI agents are the ones applying design systems to production code, how does this real world battle hardening happen?

In Design systems for AI agents, I outlined the techniques we use to ensure coding agents make use of design specifications and components each time they make changes or create new features. This has the advantage of continually steering software towards a cohesive product design and brand. But no matter how robust a design system is, it can't take into account all the potential combinations of layout and functionality a software application needs to work.
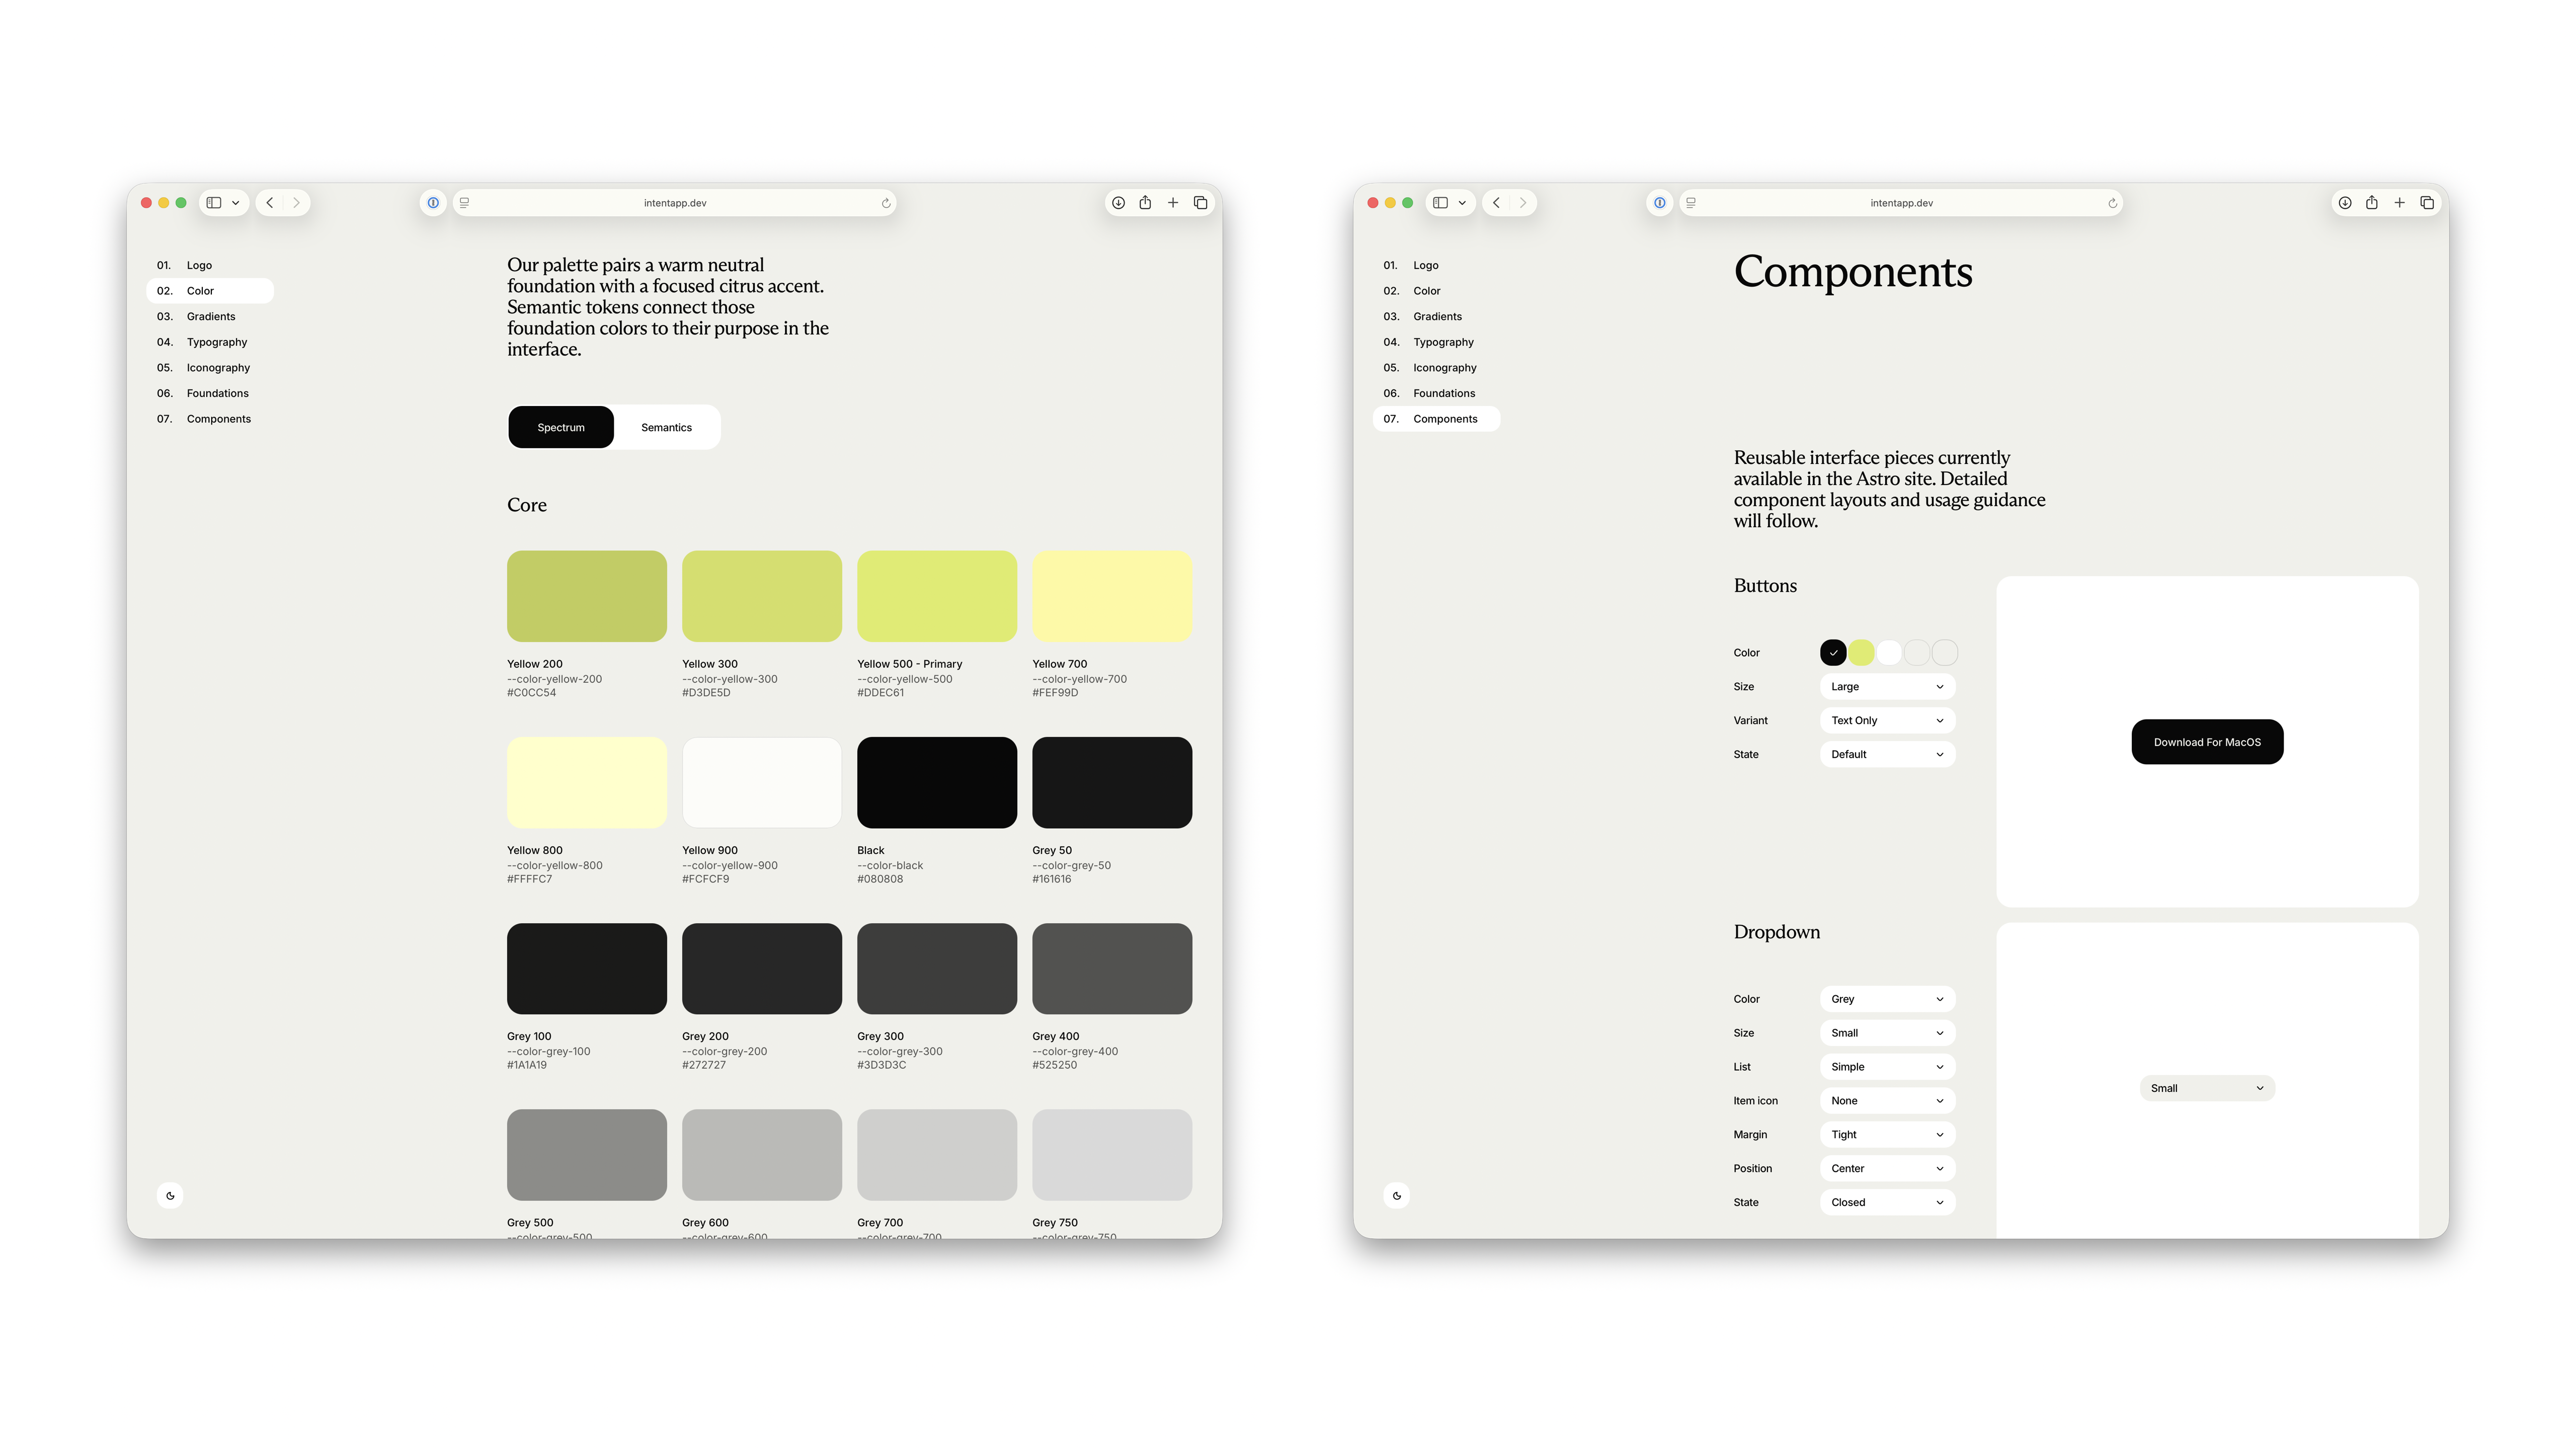
design system for Intent, example of colors and components

Nor should it. Over the years we've intentionally scaled back the amount of content in our design systems so they can stay relevant and manageable. Without significant restraint, design system systems have a tendency to spiral out of control in both resource requirements (an ever increasing design system team) and complexity (more components, more states, more documentation).

But if design systems for AI agents are not enough, how do you close the gap on coherent, integrated products? In our recent projects, we've relied on a rapid and lightweight design feedback loop. The first pass of a feature or change is driven by the design system and agent instructions, which gets us 90% of the way there. (it's worth noting earlier AI model capabilities could only get us 50 to 60% of the way.)
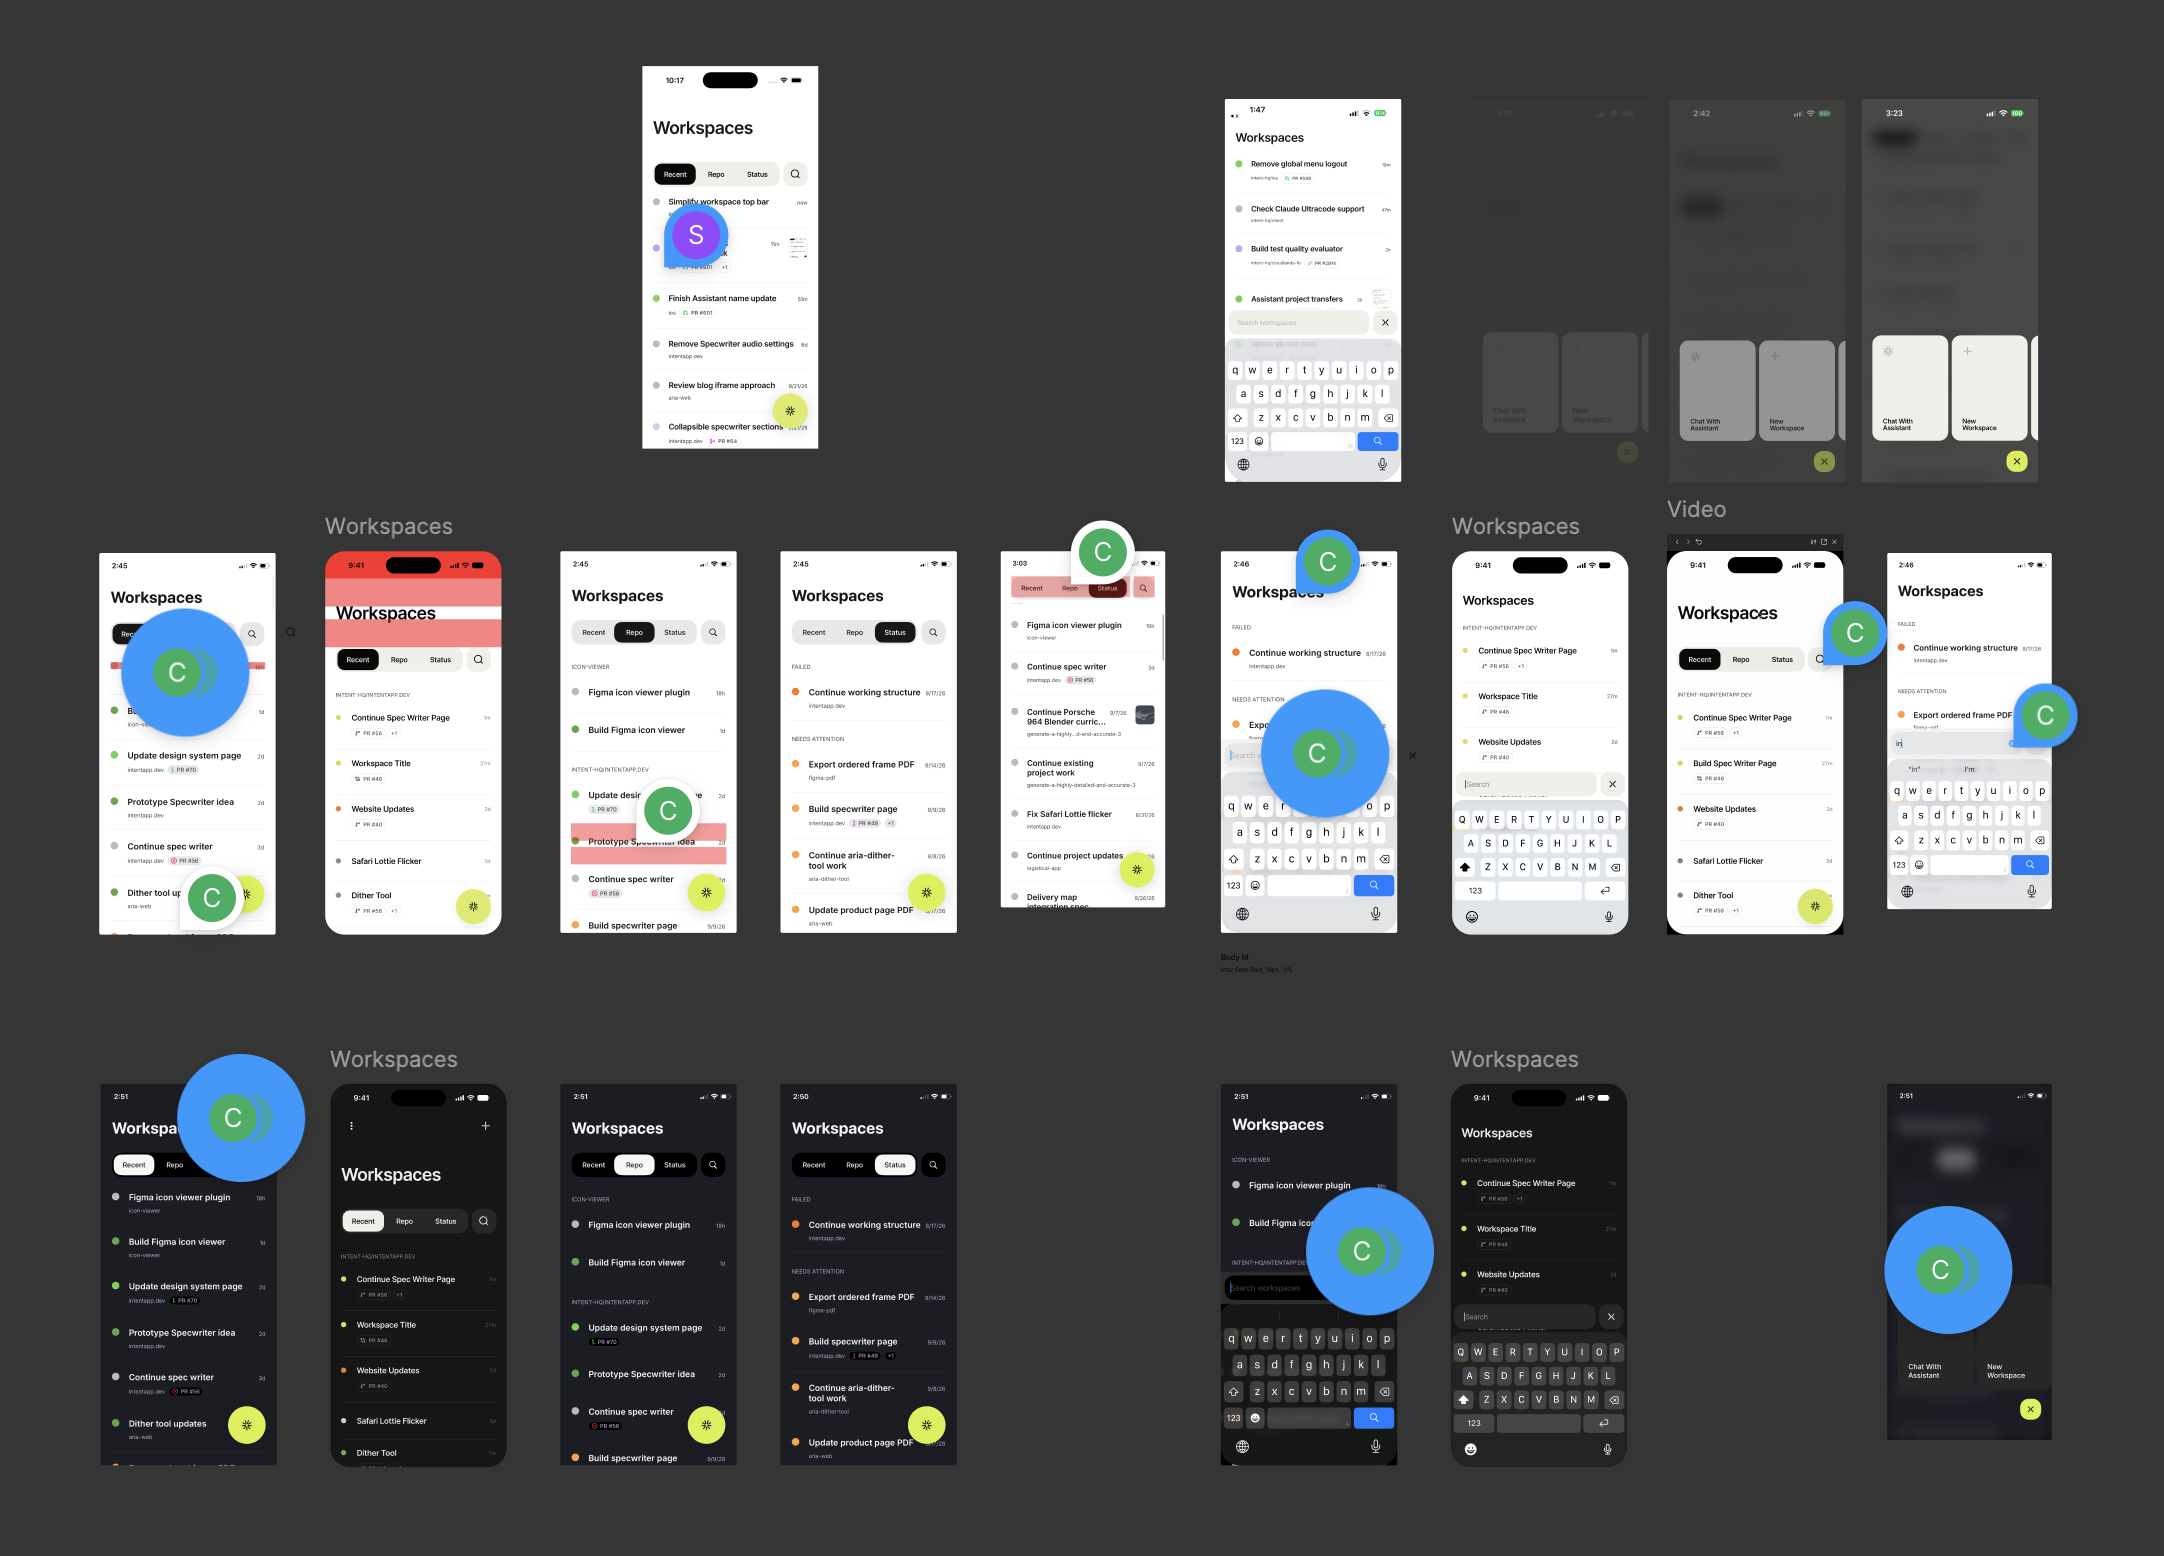
design feedback for the Intent iOS app as comments inside of Figma

We then use a process of visually showing agents where things don't lineup or work and having them correct each one until all the variants and composite layout issues are taken care of. We've tried a number of ways to provide this feedback including marking it up inside Figma with comments, annotating screenshots, and just plain old typing each change into a chat box.
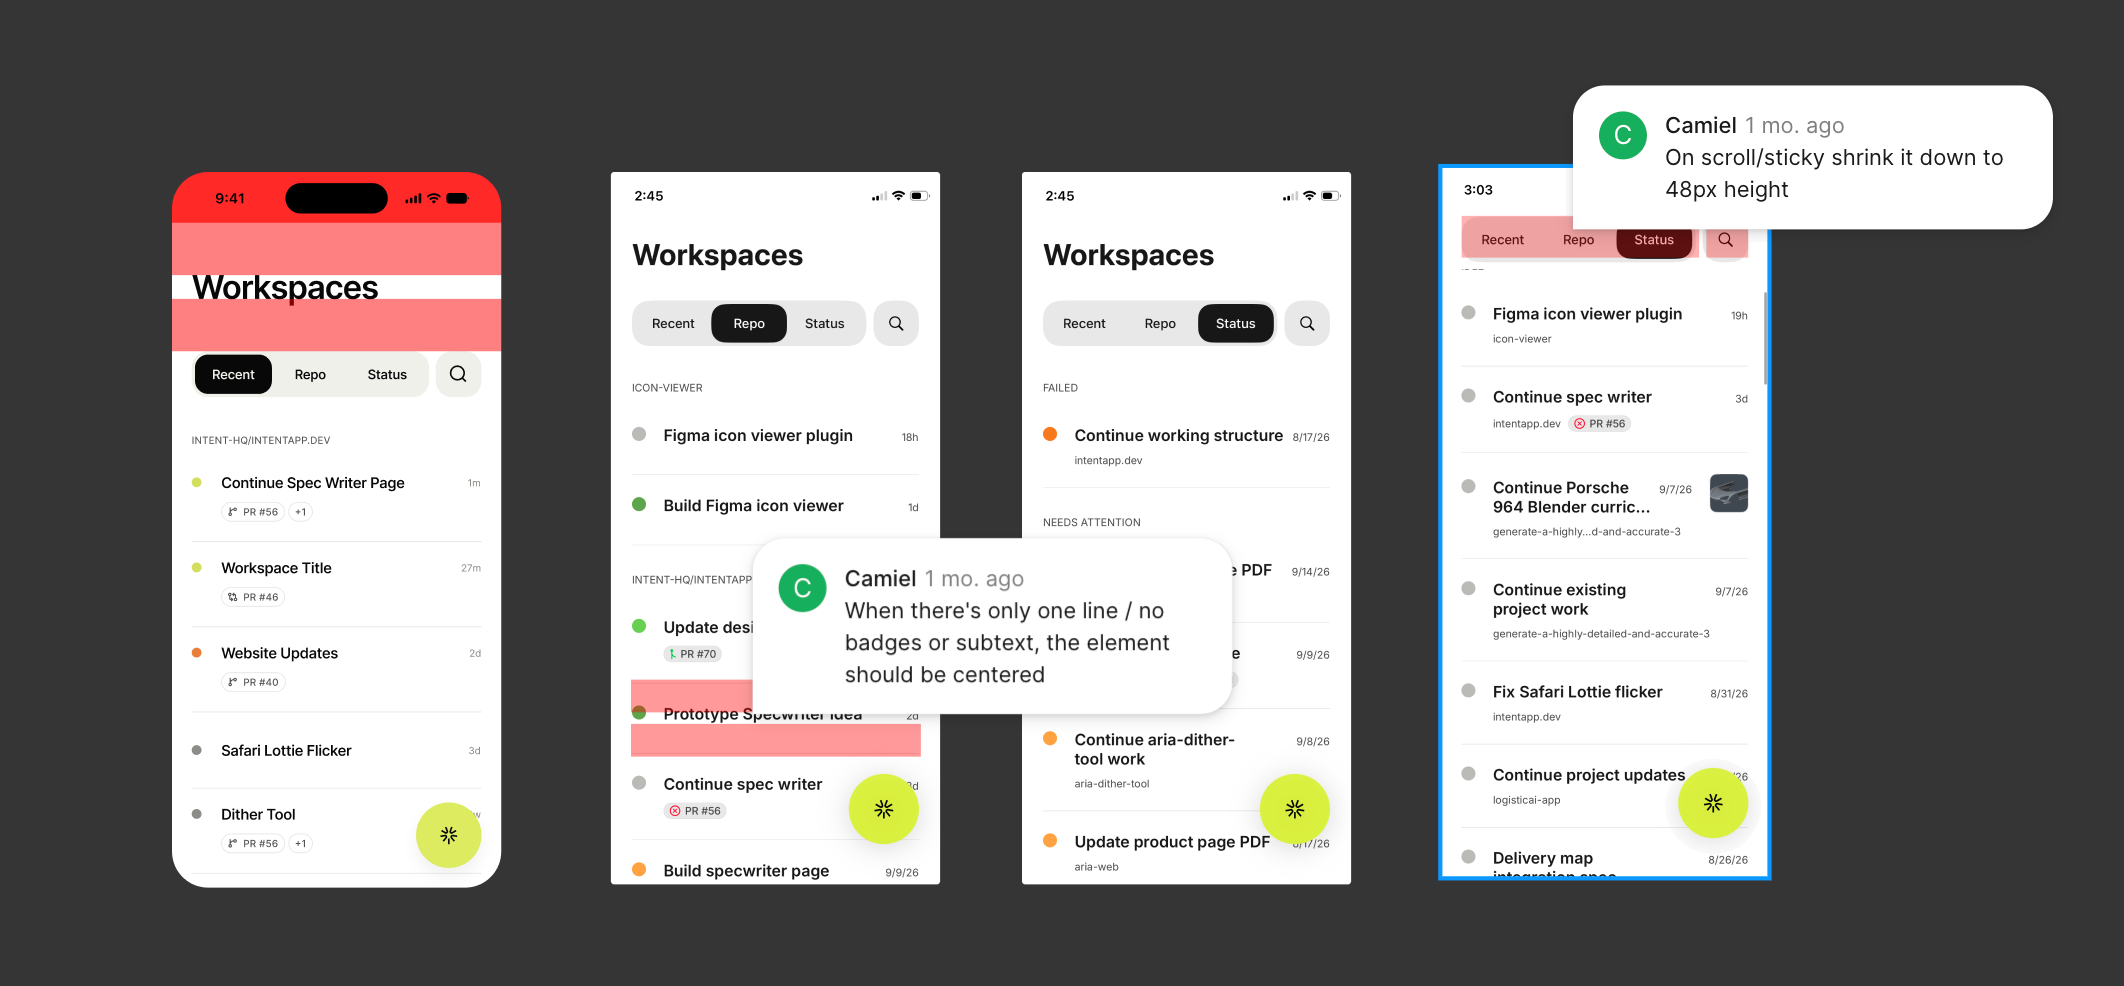
design feedback for the Intent iOS app up close, comment

These experiments led to a more a tightly integrated feature in Intent for providing visual feedback to AI agents. In the latest release, the notch on macOS devices provides a way to use your entire screen as feedback. Not only can you type or speak instructions but you can also annotate anything on your screen, take screenshots, make videos, or any combination of these to provide last mile feedback on user interface issues.

This approach streamlines bridging the gap between a high-level component and design system and its real world application in a variety of screens, edge cases, and features. The logical next step would be using all this feedback to further improve the design system. After all... intelligent systems should learn right?

Alas today's current AI models still lack the judgment needed to know what to integrate and how. If given free license today's models will err on the side of over documentation instead of the pattern simplification and cohesion needed in an effective design system. So for now, a designers judgment still matters a lot.

Technology Limits are Temporary

2026-10-26 22:00:00

Years ago I was invited to Netflix to give a talk on why we should design software for mobile and how. In the Q&A I was told that people wouldn't watch movies or TV on small screens. When I gave the same talk at eBay, I heard people would never buy expensive items without reviewing them on large displays. Obviously neither is true today. So why the disconnect?

In short, many people fixate on the limitations of new technologies instead of their long-term potential. It's happened over and over again.

The Commodore 64 had just 64 kilobytes of memory. Programs could take several minutes to start up. A complete personal computer in the 80s could set you back $4,000 of today’s money. Today's $600 MacBook Neo has none of these problems.

The early Web ran on dial-up connections. Designers were stuck with a 256 color "Web-safe" palette and hacked together page layouts using table and font tags. Today's Web runs applications, TV shows, games, and more.

comparison of the screen pixel dimensions of the original iPhone and the iPhone 18 Pro Max

The first iPhone only connected to 2G networks, had no copy and paste, only had 16 built-in apps and no way to add more. I won't belabor the point but you'd think with all these examples behind us, we'd know early technology limitations don't last. And the fixation continues with AI:

  • image models can't draw hands.
  • language models hallucinate.
  • coding models can't write good code.
  • and so on...

four years of changing capabilities in the image generation model midjourney demonstrated by images of Spider-Man

These limitations have largely disappeared in short order. And the folks that focused on what AI models couldn't do are now grappling with the larger impact of what they can do. Designers, writers, and developers all of a sudden face capabilities they actively bet against, leaving them vulnerable to job disruptions and more.

If the last forty years are any guide... technology limits are temporary. Plan accordingly.

Ask LukeW: Instant Content Indexing

2026-10-20 22:00:00

The Ask LukeW feature on my website has been answering people's questions about digital product design for over three years. How well it answers depends on the content available to it. So in addition to improving content retrieval recently, I've also improved content indexing: a key part of making personal AI work.

Before any of my articles, presentations, or files can be used to answer people's questions, they need to be cleaned up and turned into a format that makes semantic search possible. This happens through a content ingestion pipeline, which I had to kick off manually for every piece of new content.

Now the system automatically checks for anything new or changed each hour. Audio, video, PDFs, and images it finds get queued, processed in the background, and added to the corpus. How that happens depends on the types of content.

Audio and video files get transcribed into text spelling out what was said and who said it. The service doing this recognizes my voice so it can consistently label me in each transcript. An AI model then reads the transcript and generates a title, summary, list of topics, and date if it can find one in the text. Each transcript gets split into distinct passages so an answer can reference the exact moment in a talk where I said something, and you can jump straight to it in the embeddable video and audio players.

Ask Luke embedded video files

PDF files get read by a vision model that not only extracts all the text but also describes charts and diagrams in words. Since many of my presentation slides are visual, this process matters a lot. Each PDF page is individually saved so answers can show slides inline resulting in less walls of text.
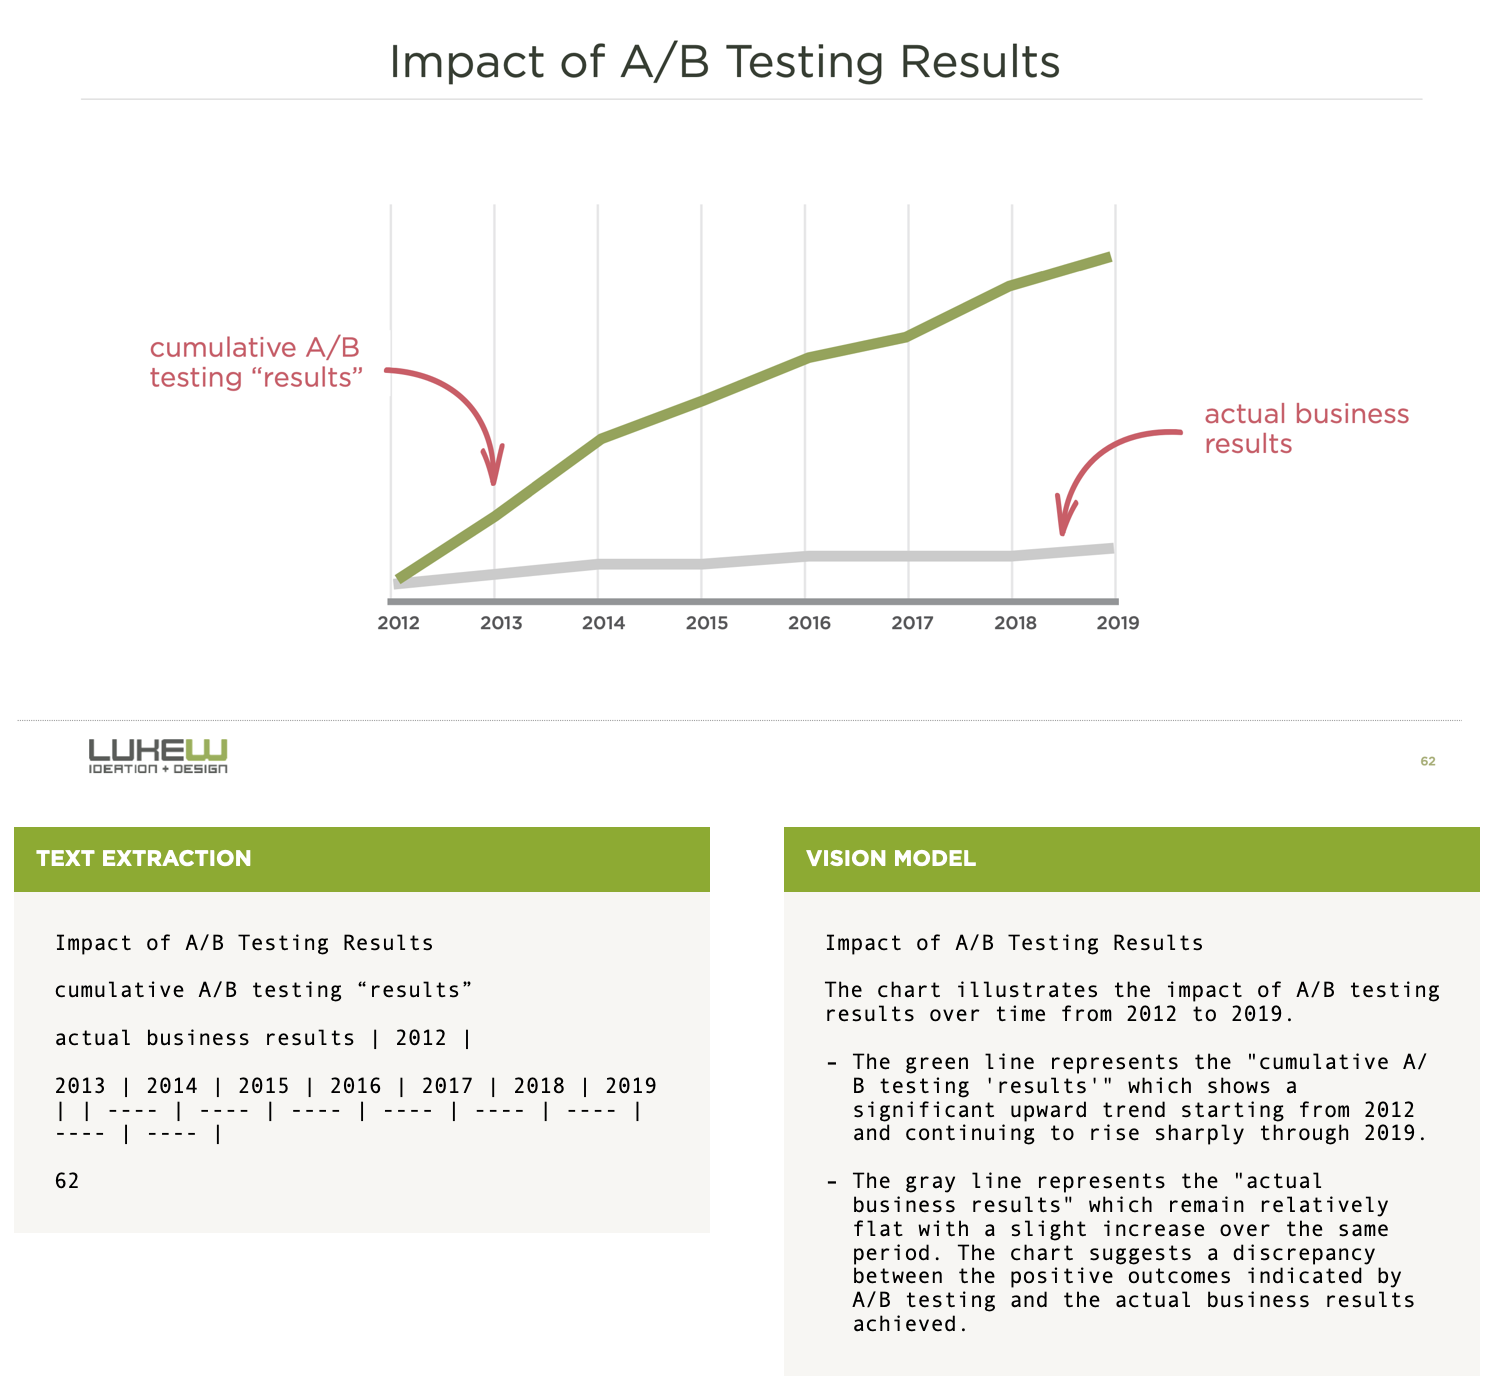
Example of LukeW slide parsing via vision model

Of course, images help with that as well, so an AI model analyzes each new image added, describes what's in it, and uses my captions as additional context if the image appears in a blog post.

That's all well and good, but I'm not writing that many articles and definitely not giving enough talks to keep content recent and relevant. Thankfully, there's Twitter (X now) and I've posted there nearly 20,000 times since 2008. Damn, I need hobbies.

Despite the volume, none of those tweets were available to Ask LukeW. Now when I post, X notifies our server which pulls in the full post or deletes it if I had a half-baked idea that I removed. Older posts were added through a one-time import though I skipped replies to other people, reposts, and anything linking to lukew.com (that content was already there).

Example of and ask Luke W reply, citing a few published tweets (posts on X)

For each post, shortened links are expanded so the text reads naturally, and quoted posts are included for context. Any photo, video, or GIF also gets described by an AI model.

So why does all this matter? Making content ingestion automatic, especially Twitter/X posts as they happen, allowed me to start the Ask LukeW experience with an answer vs. requiring a question. Which addresses one of the most challenging bits of AI products: knowing what they can do. Plus Ask LukeW answers are now better because they have more content to draw from. So that's cool.