


2026-11-10 22:21:08
OK, the shift from WordPress and Godaddy is happening. I managed to convert most of the old blog to static pages and you can see the result already at the old domain Wait-till-i.com
It’s a highly responsive and fully static site now, build with lots of dirty PHP conversion scripts and Jekyll. I did use GitHub pages at first, but the build took 10 minutes each time, and that’s not the idea of Github. You can see what the design looks like and how it behaves in the following screencast, click to see it on YouTube:
Here’s what’s done so far:

The most amazing thing so far is that the only thing I use JavaScript for is the search, which also means that it is almost instant.
Here are the main new-ish things I used to avoid having to use any script:
If you give several `detail` elements the same name, they become an accordion as the others get automatically closed when you expand one.
One
Lorem ipsum dolor sit amet…


Two
Lorem ipsum dolor sit amet…


Three
Lorem ipsum dolor sit amet…
And now we also have a way to “animate to auto” and other keywords using interpolate-size. Which means you can make the accordion open smoothly using the following:
:root {

interpolate-size: allow-keywords;

}
	details::details-content {

height: 0;

overflow: clip;

transition: height 0.4s ease,

content-visibility 0.4s allow-discrete;

}

	details[open]::details-content {

height: auto;

}
You can play with this on the accordion demo page:
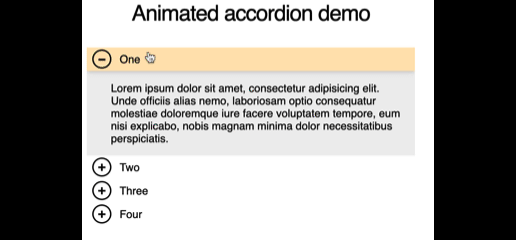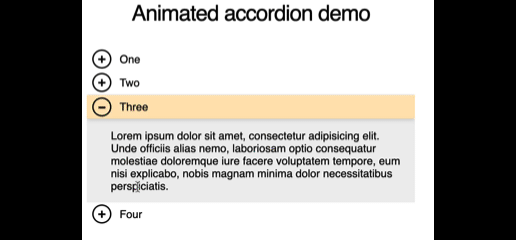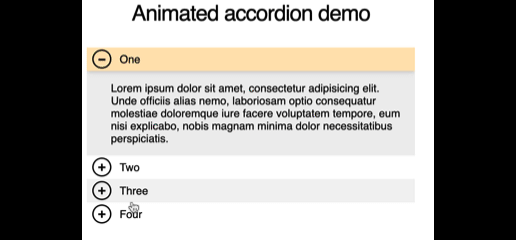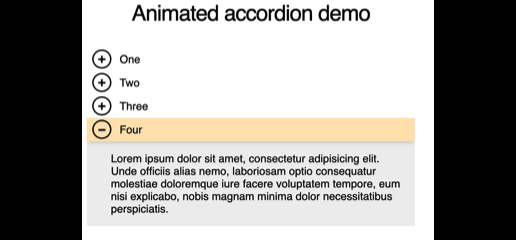
Currently (November 2026) this works only in Chromium browsers, but it is progressively enhanced, as other browsers snap to the expanded stage.
I found this explained by Theodore Lefevre on LinkedIn.
## Card layout using `grid` and hero highlight using `not(:hover)`
The layout of the different sections on the homepage uses CSS grid and is pretty straight forward:
.deck {

pointer-events: none;

}
	.deck:hover .card:not(:hover),

.deck:focus-within .card:not(:focus-within){

scale: 0.8;

opacity: 0.3;

}
	.card {

pointer-events: auto;

transition: scale 300ms, opacity 300ms;

}
	.card:hover, .card:focus-within {

background: skyblue;

border-color: cornflowerblue;

}
	.deck {

display: grid;

grid-template-columns: repeat(auto-fit, minmax(10em, 1fr));

gap: 3rem;

}
Highlighting the current section is done using `hover` and `focus-within` (to support keyboard users). Making the other cards less prominent uses `not(:hover)`, which in the past would have needed a class on the parent elenent or having to loop through the other cards.
.deck {

pointer-events: none;

}
	.deck:hover .card:not(:hover),

.deck:focus-within .card:not(:focus-within){

scale: 0.8;

opacity: 0.3;

}
	.card {

pointer-events: auto;

transition: scale 300ms, opacity 300ms;

}
	.card:hover, .card:focus-within {

background: skyblue;

border-color: cornflowerblue;

}
	.deck {

display: grid;

grid-template-columns: repeat(auto-fit, minmax(10em, 1fr));

gap: 3rem;

}
You can play with this [on the cards demo page](https://wait-till-i.com/demos/cards/) (make sure to resize the outer element):
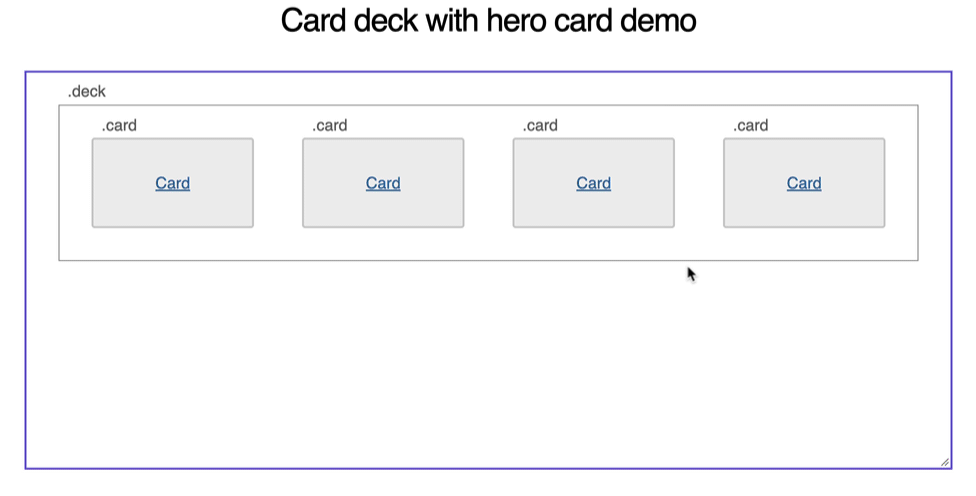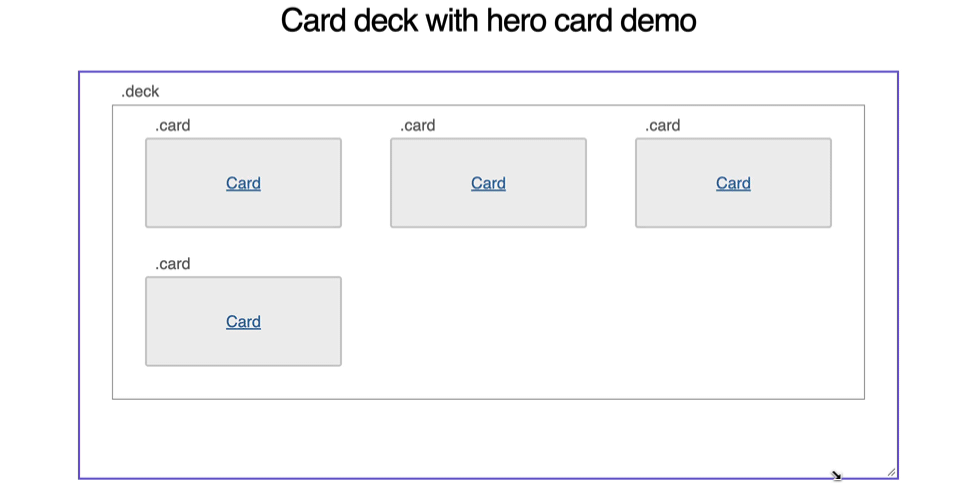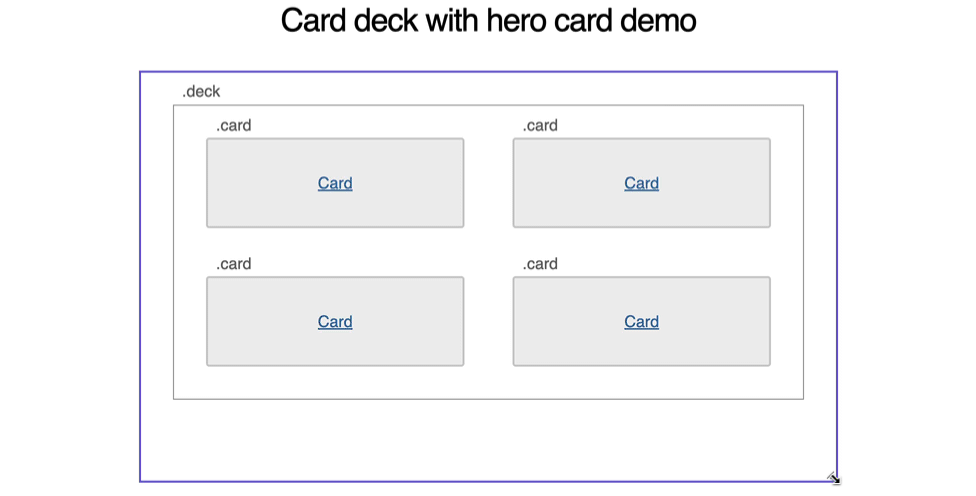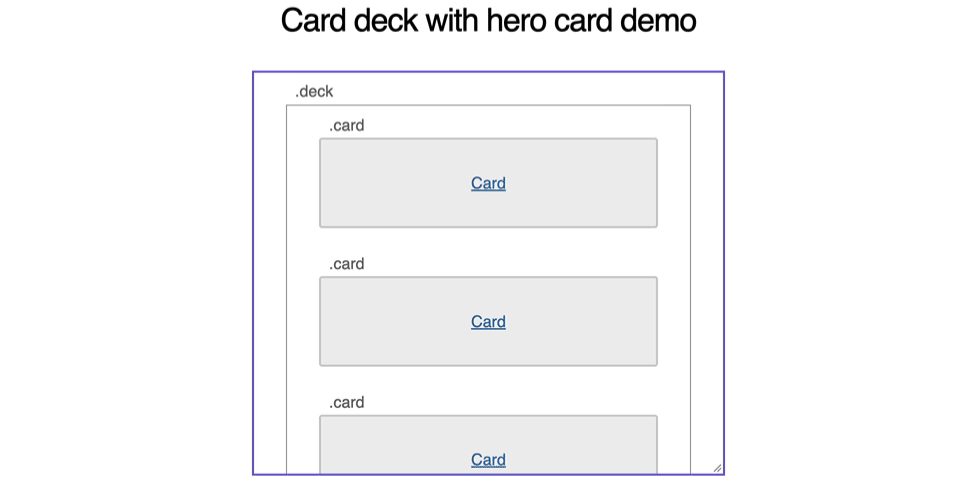
I found this [on CSS Tricks by Krzysztof Gonciarz](https://css-tricks.com/a-pure-css-gallery-focus-effect-with-not/).
The other thing that’s costing me a lot of time is cleaning up the markup of older posts. I’m writing a very messy PHP script to do that and I am almost done removing all the defunct embed codes from old Flash versions of YouTube and many other dead services.
I also moved to Jekyll to do all of this offline as building the page on GitHub Pages took 8 minutes at a time, which got me scarily close to the 10 minute timeout limit…
See you in part 3!
2026-10-29 00:24:35
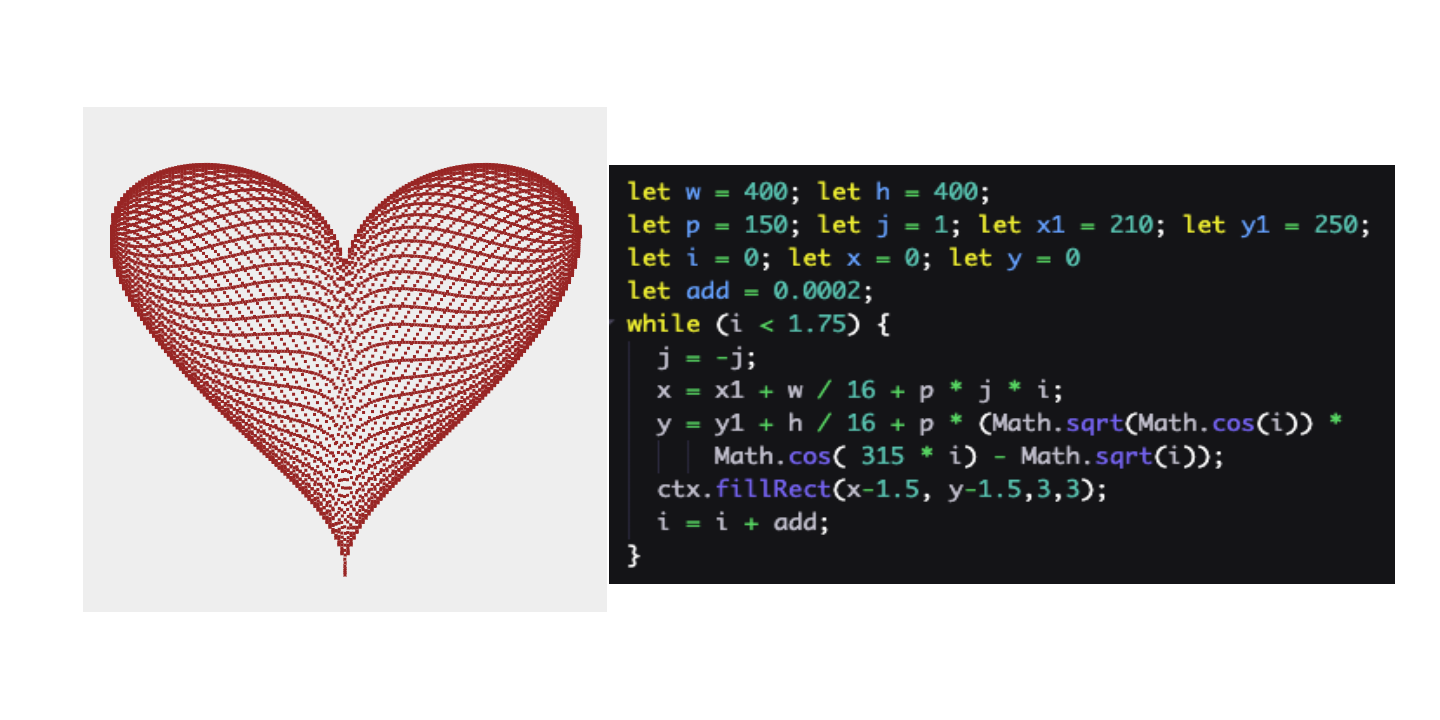
Math is beautiful – check it out on Codepen
At WeAreDevelopers, we love to code. We love the concept of creating something from nothing, finding a solution for a problem and create something people can get excited about.
That’s why we thought we’d give you a challenge to show what you can do with an HTML document containing some wisdom by Lao-Tzu about what several concepts become when love is missing.
We’ve used this to learn about some new(ish) things in CSS we hadn’t played with before and we encourage you to use this as an opportunity to try out something new.
There are no rules what you do with this and what tech you use.
You can submit your solution as a pull request here – simply create a folder with your name and code in the entries folder.
Show the world what adding some love can do.
2026-10-28 13:20:25
I’ve been a bit silent here lately. The reason is on the one hand life and issues with that but also problems with the hoster of this blog, specifically the SSL certificate. I’ve spent some fun hours on the phone with helpdesk and it’s still, well, complicated. That’s why I finally took the plunge and will change and move this blog, for the first time.
This blog uses WordPress and it was a great friend over the years. It also was hosted on MediaTemple, who were amazing people to work with and made it simple to buy domains, have them secured and keep the engine up-to-date. Then MediaTemple was bought by GoDaddy and I was forced to buy a new hosting package and out of a sudden getting the SSL for my domain became expensive and a pain in the lower backside. Unneccesarily so, as letsencrypt and others made buying your own certificates and installing them by hand redundant. That doesn’t stop GoDaddy though from charging you for every step on the way. WordPress also has its troubles and I don’t really use its features for anything, so I’m also out.
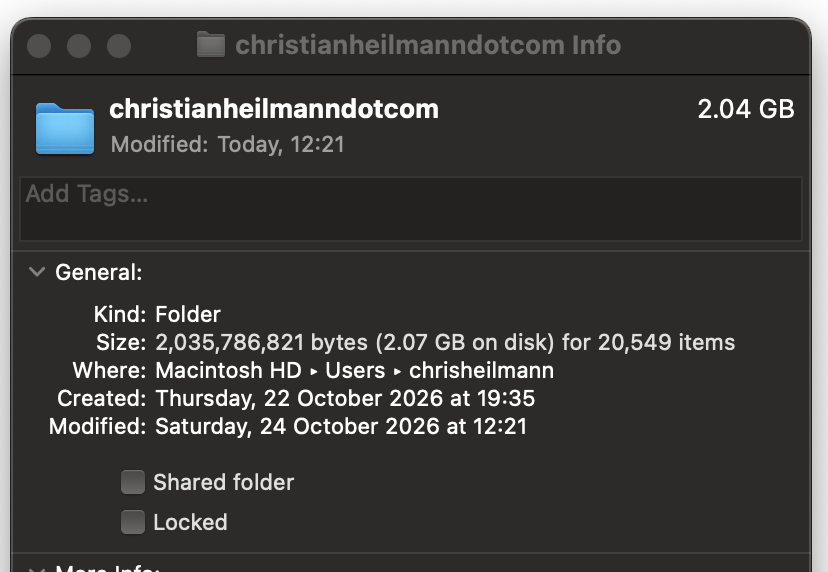
Lots of other people I admire and blog about the same things that I do kept changing their platform and wrote about that. Every time I considered to do the same, I wrote a post about a current tech topic instead. Now I face the interesting task to change this Frankensteinian something into an easy to maintain and independent product. Here’s what I have:
21 years of blogging with this stack:
So, bear with me while I make this all work. So far, I have converted 1850 blog posts to markdown, made sure to keep the original folder structure as not to break any links and started on a leaner, cleaner template to display both the old and the posts to come.
I’m moving off WordPress as I don’t use any of its functionality. I’ve turned off comments years ago as I drowned in spam. I never used the high fidelity editor, but the classic text box. And I don’t use any social media plugins or boosters.
What that leaves me with though is having to implement search and feed generation myself. And I am on a good path.
The next thing I then need to worry about is hosting, as I really want to say goodbye to GoDaddy. I currently work to convert the blog to Jekyll and will find a place for it. Any recommendations are welcome and I want to maintain it in the future on Git(Hub) as I am writing it in VS Code anyway.
Without further ado, here are the steps I took/I am taking:

Join me in Part 2, coming soon.
2026-10-09 22:05:42
After rocking San Jose with our World Congress, WeAreDevelopers’ next port of call is Bengaluru in India. See you there on the 25th of November for two days of excellent talks and workshops !
2026-10-06 23:52:53
Much like a lot of other people, I subscribe to quite a few of the newsletters of TLDR. As I re-use the things I found there in own publications, I did find the newsletters – ironically – not quite succinct enough to go through them quickly. I wanted to skip sponsored sections and other cruft, so, of course I wrote a PHP script to help me with that. Here it is and you can find it on GitHub.
$URLS = file_get_contents(‘tldrs.txt’);

$out = ‘’;

foreach (array_filter(explode(“n”, $URLS)) as $url) {

echo $url . “n”;

$html = file_get_contents($url);

$dom = new DOMDocument();

libxml_use_internal_errors(true);

$dom->loadHTML($html);

libxml_clear_errors();

$xpath = new DOMXPath($dom);

$links = $xpath->query(‘//a’);

foreach($links as $link) {

$content = $link->nodeValue;

if (strstr($content,’minute read’) ||

strstr($content,’GitHub Repo’)) {

$text = trim(

preg_replace(

“/ (d+ minute read)|(GitHub Repo)/”,

“”,$link->nodeValue)

);

$details = trim($link->parentNode->lastChild->previousSibling->nodeValue);

$link = $link->getAttribute(‘href’);

if (strpos($link, ‘links.tldrnewsletter.com’) !== 0) {

$link = exec(‘curl -Ls -o /dev/null -w %{url_effective} ’ . escapeshellarg($link));

}
	$out .= trim($text).” ” . $link . “n” . $details . “nn”;

}
	}

}
	file_put_contents(‘tldrs.txt’, $URLS . “n” . $out);

?>
The script takes a text file called “tldrs.txt” and loads the URLs on each of its lines. For example:
https://a.tldrnewsletter.com/web-version?ep=1&lc=12287b12-8315-11ee-beaa-736450d0f676&p=f7d1a838-be26-11f1-8893-bde744e2a96e&pt=campaign&t=1790939613&s=ca95811254756b8f90a40fb908f378eb263ee5efd26c4f4e75cf27afe12c4c75

https://a.tldrnewsletter.com/web-version?ep=1&lc=072c9ebe-8315-11ee-bfc9-3105a9c4cdee&p=a87ac9ce-be42-11f1-81e5-6329ebe08e36&pt=campaign&t=1790937594&s=593f4a56fb8e145a55f12d69fbe7ad37ae0b8f79db13cdb50873af64859a8d24

https://a.tldrnewsletter.com/web-version?ep=1&lc=122aee56-8315-11ee-88bc-f3604afdd80b&p=dacd0d30-bd87-11f1-bb10-f5a7490d358d&pt=campaign&t=1790861448&s=180e6f7bff6862c042d890cffd0d0b86c48161084c379294691dd212ee59c658

https://a.tldrnewsletter.com/web-version?ep=1&lc=122aee56-8315-11ee-88bc-f3604afdd80b&p=102bee2e-be55-11f1-a985-65716d1d02e4&pt=campaign&t=1790947629&s=6f9c6a5ccbd4e6b92b9ac81680b0f4a037611ae42219f5859937387a97f21526
It loads the URLs one by one, and checks which links contain either `minutes read` or `GitHub Repo`. It then loads these and extracts their URL, headline and description and adds the results to the `tldrs.txt` file.
Some of the links in the newsletters are hidden behind a redirect of `links.tldrnewsletter.com`. As I wanted the real URLs, I am using cURL to get the correct ones.
You can do this with the following command:
curl Ls -o /dev/null -w %{url_effective} https://linkto-unfold
Pretty sure noone but me needs this, but here we are.

